Compare commits
1
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Lysandre |
46d2d18c5c |
No files matched your search
@@ -27,9 +27,8 @@ jobs:
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[mecab,sklearn,tf-cpu,torch,testing]
|
||||
- run:
|
||||
command: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
no_output_timeout: 4h
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
- no_output_timeout: 4h
|
||||
|
||||
run_tests_torch:
|
||||
working_directory: ~/transformers
|
||||
@@ -137,7 +136,7 @@ workflows:
|
||||
run_slow_tests:
|
||||
triggers:
|
||||
- schedule:
|
||||
cron: "0 4 * * *"
|
||||
cron: "0 4 * * 1"
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
||||
@@ -1,25 +1,3 @@
|
||||
/* Our DOM objects */
|
||||
|
||||
.framework-selector {
|
||||
display: flex;
|
||||
flex-direction: row;
|
||||
justify-content: flex-end;
|
||||
}
|
||||
|
||||
.framework-selector > button {
|
||||
background-color: white;
|
||||
color: #6670FF;
|
||||
border: 1px solid #6670FF;
|
||||
padding: 5px;
|
||||
}
|
||||
|
||||
.framework-selector > button.selected{
|
||||
background-color: #6670FF;
|
||||
color: white;
|
||||
border: 1px solid #6670FF;
|
||||
padding: 5px;
|
||||
}
|
||||
|
||||
/* The literal code blocks */
|
||||
.rst-content tt.literal, .rst-content tt.literal, .rst-content code.literal {
|
||||
color: #6670FF;
|
||||
|
||||
@@ -68,74 +68,6 @@ function addHfMenu() {
|
||||
document.body.insertAdjacentHTML('afterbegin', div);
|
||||
}
|
||||
|
||||
function platformToggle() {
|
||||
const codeBlocks = Array.from(document.getElementsByClassName("highlight"));
|
||||
const pytorchIdentifier = "## PYTORCH CODE";
|
||||
const tensorflowIdentifier = "## TENSORFLOW CODE";
|
||||
const pytorchSpanIdentifier = `<span class="c1">${pytorchIdentifier}</span>`;
|
||||
const tensorflowSpanIdentifier = `<span class="c1">${tensorflowIdentifier}</span>`;
|
||||
|
||||
const getFrameworkSpans = filteredCodeBlock => {
|
||||
const spans = filteredCodeBlock.element.innerHTML;
|
||||
const pytorchSpanPosition = spans.indexOf(pytorchSpanIdentifier);
|
||||
const tensorflowSpanPosition = spans.indexOf(tensorflowSpanIdentifier);
|
||||
|
||||
let pytorchSpans;
|
||||
let tensorflowSpans;
|
||||
|
||||
if(pytorchSpanPosition < tensorflowSpanPosition){
|
||||
pytorchSpans = spans.slice(pytorchSpanPosition + pytorchSpanIdentifier.length + 1, tensorflowSpanPosition);
|
||||
tensorflowSpans = spans.slice(tensorflowSpanPosition + tensorflowSpanIdentifier.length + 1, spans.length);
|
||||
}else{
|
||||
tensorflowSpans = spans.slice(tensorflowSpanPosition + tensorflowSpanIdentifier.length + 1, pytorchSpanPosition);
|
||||
pytorchSpans = spans.slice(pytorchSpanPosition + pytorchSpanIdentifier.length + 1, spans.length);
|
||||
}
|
||||
|
||||
return {
|
||||
...filteredCodeBlock,
|
||||
pytorchSample: pytorchSpans ,
|
||||
tensorflowSample: tensorflowSpans
|
||||
}
|
||||
};
|
||||
|
||||
const createFrameworkButtons = sample => {
|
||||
const pytorchButton = document.createElement("button");
|
||||
pytorchButton.innerText = "PyTorch";
|
||||
|
||||
const tensorflowButton = document.createElement("button");
|
||||
tensorflowButton.innerText = "TensorFlow";
|
||||
|
||||
const selectorDiv = document.createElement("div");
|
||||
selectorDiv.classList.add("framework-selector");
|
||||
selectorDiv.appendChild(pytorchButton);
|
||||
selectorDiv.appendChild(tensorflowButton);
|
||||
sample.element.parentElement.prepend(selectorDiv);
|
||||
|
||||
// Init on PyTorch
|
||||
sample.element.innerHTML = sample.pytorchSample;
|
||||
pytorchButton.classList.add("selected");
|
||||
tensorflowButton.classList.remove("selected");
|
||||
|
||||
pytorchButton.addEventListener("click", () => {
|
||||
sample.element.innerHTML = sample.pytorchSample;
|
||||
pytorchButton.classList.add("selected");
|
||||
tensorflowButton.classList.remove("selected");
|
||||
});
|
||||
tensorflowButton.addEventListener("click", () => {
|
||||
sample.element.innerHTML = sample.tensorflowSample;
|
||||
tensorflowButton.classList.add("selected");
|
||||
pytorchButton.classList.remove("selected");
|
||||
});
|
||||
};
|
||||
|
||||
codeBlocks
|
||||
.map(element => {return {element: element.firstChild, innerText: element.innerText}})
|
||||
.filter(codeBlock => codeBlock.innerText.includes(pytorchIdentifier) && codeBlock.innerText.includes(tensorflowIdentifier))
|
||||
.map(getFrameworkSpans)
|
||||
.forEach(createFrameworkButtons);
|
||||
}
|
||||
|
||||
|
||||
/*!
|
||||
* github-buttons v2.2.10
|
||||
* (c) 2019 なつき
|
||||
@@ -153,7 +85,6 @@ function onLoad() {
|
||||
addGithubButton();
|
||||
parseGithubButtons();
|
||||
addHfMenu();
|
||||
platformToggle();
|
||||
}
|
||||
|
||||
window.addEventListener("load", onLoad);
|
||||

@@ -1 +1,47 @@
|
||||
<svg clip-rule="evenodd" fill-rule="evenodd" stroke-linejoin="round" stroke-miterlimit="2" viewBox="0 0 127 118" xmlns="http://www.w3.org/2000/svg" xmlns:xlink="http://www.w3.org/1999/xlink"><clipPath id="a"><path clip-rule="nonzero" d="m62 75.052c13.105 0 17.333-11.684 17.333-17.684 0-3.118-2.096-2.136-5.453-.474-3.103 1.536-7.282 3.653-11.88 3.653-9.573 0-17.333-9.179-17.333-3.179s4.228 17.684 17.333 17.684z"/></clipPath><path d="m125.057 93.44c1 2.88.76 5.947-.573 8.613-.96 1.947-2.333 3.454-4.013 4.8-2.027 1.6-4.547 2.96-7.587 4.267-3.627 1.547-8.053 3-10.08 3.533-5.187 1.347-10.173 2.2-15.227 2.24-7.226.067-13.453-1.64-17.88-6-2.293.28-4.613.44-6.946.44-2.214 0-4.4-.133-6.574-.4-4.44 4.334-10.64 6.027-17.84 5.96-5.053-.04-10.04-.893-15.24-2.24-2.013-.533-6.44-1.986-10.066-3.533-3.04-1.307-5.56-2.667-7.574-4.267-1.693-1.346-3.066-2.853-4.026-4.8-1.32-2.666-1.574-5.733-.56-8.613-.934-2.2-1.174-4.72-.44-7.507.333-1.266.88-2.44 1.573-3.48-.147-.546-.267-1.106-.347-1.72-.506-3.653.76-6.986 3.147-9.573 1.173-1.293 2.44-2.187 3.76-2.76-.973-4.133-1.48-8.387-1.48-12.733 0-30.747 24.92-55.667 55.667-55.667 10.56 0 20.44 2.933 28.866 8.053 1.52.934 3.014 1.934 4.44 3 .707.534 1.414 1.08 2.094 1.654.693.56 1.373 1.146 2.026 1.746 1.974 1.8 3.827 3.734 5.52 5.8.574.68 1.12 1.387 1.654 2.107 1.08 1.427 2.08 2.907 3 4.44 1.4 2.293 2.626 4.693 3.693 7.187.707 1.666 1.32 3.373 1.867 5.12.813 2.613 1.44 5.306 1.866 8.08.134.92.254 1.853.347 2.786.187 1.867.293 3.76.293 5.694 0 4.293-.506 8.506-1.453 12.573 1.467.573 2.853 1.507 4.147 2.92 2.386 2.587 3.653 5.933 3.146 9.587-.08.6-.2 1.16-.346 1.706.693 1.04 1.24 2.214 1.573 3.48.733 2.787.493 5.307-.427 7.507" fill="#fff" fill-rule="nonzero"/><circle cx="62.333" cy="55.667" fill="#ffd21e" r="46.333"/><g fill-rule="nonzero"><path d="m108.667 55.667c0-25.59-20.744-46.334-46.334-46.334-25.589 0-46.333 20.744-46.333 46.334 0 25.589 20.744 46.333 46.333 46.333 25.59 0 46.334-20.744 46.334-46.333zm-98 0c0-28.535 23.132-51.667 51.666-51.667 28.535 0 51.667 23.132 51.667 51.667 0 28.534-23.132 51.666-51.667 51.666-28.534 0-51.666-23.132-51.666-51.666z" fill="#ffac03"/><path d="m77.387 43.055c1.7.6 2.376 4.093 4.092 3.181 3.251-1.729 4.485-5.765 2.757-9.016-1.729-3.251-5.765-4.485-9.016-2.757-3.251 1.729-4.485 5.765-2.757 9.016.816 1.535 3.406-.96 4.924-.424z" fill="#3a3b45"/><path d="m45.978 43.055c-1.699.6-2.375 4.093-4.092 3.181-3.251-1.729-4.485-5.765-2.756-9.016 1.728-3.251 5.765-4.485 9.016-2.757 3.251 1.729 4.485 5.765 2.756 9.016-.815 1.535-3.405-.96-4.924-.424z" fill="#3a3b45"/><path d="m62 75.052c13.105 0 17.333-11.684 17.333-17.684 0-3.118-2.096-2.136-5.453-.474-3.103 1.536-7.282 3.653-11.88 3.653-9.573 0-17.333-9.179-17.333-3.179s4.228 17.684 17.333 17.684z" fill="#3a3b45"/></g><g clip-path="url(#a)"><path d="m62.333 88.667c6.387 0 11.564-5.178 11.564-11.564 0-4.975-3.141-9.216-7.548-10.848-.162-.06-.326-.116-.491-.169-1.111-.355-2.296 3.464-3.525 3.464-1.148 0-2.257-3.844-3.305-3.532-4.776 1.422-8.259 5.847-8.259 11.085 0 6.386 5.178 11.564 11.564 11.564z" fill="#ef4e4e" fill-rule="nonzero"/></g><circle cx="93.667" cy="45" fill="#ffd21e" r="4.333"/><circle cx="31.667" cy="45" fill="#ffd21e" r="4.333"/><path d="m22.749 64c-2.158 0-4.088.887-5.433 2.495-.832.996-1.701 2.601-1.772 5.005-.905-.26-1.776-.405-2.589-.405-2.067 0-3.934.792-5.254 2.23-1.696 1.847-2.449 4.116-2.121 6.387.156 1.081.517 2.051 1.057 2.948-1.138.921-1.977 2.204-2.382 3.747-.318 1.209-.643 3.728 1.056 6.322-.108.17-.21.346-.304.526-1.022 1.938-1.087 4.129-.186 6.169 1.367 3.092 4.763 5.528 11.358 8.143 4.102 1.626 7.856 2.666 7.889 2.676 5.424 1.406 10.329 2.121 14.576 2.121 7.805 0 13.393-2.391 16.609-7.105 5.176-7.592 4.436-14.536-2.261-21.23-3.707-3.704-6.171-9.165-6.684-10.364-1.035-3.549-3.771-7.494-8.319-7.494h-.001c-.383 0-.769.03-1.151.09-1.992.314-3.733 1.46-4.977 3.186-1.343-1.67-2.647-2.998-3.827-3.747-1.778-1.128-3.556-1.7-5.284-1.7m0 5.333c.68 0 1.511.29 2.427.871 2.844 1.804 8.332 11.237 10.341 14.907.674 1.229 1.824 1.749 2.86 1.749 2.056 0 3.662-2.044.188-4.641-5.222-3.908-3.39-10.296-.897-10.69.109-.017.217-.025.321-.025 2.267 0 3.267 3.907 3.267 3.907s2.931 7.36 7.965 12.39c5.035 5.032 5.295 9.071 1.626 14.452-2.503 3.67-7.294 4.778-12.203 4.778-5.092 0-10.312-1.192-13.237-1.951-.144-.037-17.935-5.063-15.682-9.34.379-.719 1.003-1.007 1.788-1.007 3.174 0 8.946 4.723 11.427 4.723.555 0 .945-.236 1.105-.812 1.058-3.793-16.076-5.388-14.632-10.883.255-.972.946-1.366 1.916-1.365 4.194 0 13.602 7.375 15.574 7.375.15 0 .258-.044.317-.138.988-1.594.447-2.708-6.517-6.922-6.964-4.216-11.852-6.752-9.072-9.779.32-.349.773-.504 1.324-.504 4.228.001 14.217 9.092 14.217 9.092s2.696 2.804 4.327 2.804c.374 0 .693-.148.909-.513 1.156-1.95-10.737-10.963-11.408-14.682-.455-2.52.319-3.796 1.749-3.796" fill="#ffac03" fill-rule="nonzero"/><path d="m50.846 102.253c3.67-5.381 3.41-9.42-1.625-14.452-5.035-5.03-7.965-12.39-7.965-12.39s-1.095-4.275-3.588-3.882c-2.494.394-4.324 6.782.898 10.69 5.223 3.906-1Line truncated
|
||||
<svg width="95px" height="88px" viewBox="0 0 95 88" version="1.1" xmlns="http://www.w3.org/2000/svg" xmlns:xlink="http://www.w3.org/1999/xlink">
|
||||
<!-- Generator: Sketch 43.2 (39069) - http://www.bohemiancoding.com/sketch -->
|
||||
<title>icon</title>
|
||||
<desc>Created with Sketch.</desc>
|
||||
<defs>
|
||||
<path d="M13,14.7890193 C22.8284801,14.7890193 26,6.02605902 26,1.5261751 C26,-0.812484109 24.4279133,-0.0763570998 21.9099482,1.17020987 C19.5830216,2.32219957 16.4482998,3.91011313 13,3.91011313 C5.82029825,3.91011313 0,-2.97370882 0,1.5261751 C0,6.02605902 3.17151989,14.7890193 13,14.7890193 Z" id="path-1"></path>
|
||||
</defs>
|
||||
<g id="Page-1" stroke="none" stroke-width="1" fill="none" fill-rule="evenodd">
|
||||
<g id="icon_desktop">
|
||||
<g id="icon">
|
||||
<g id="icon_desktop">
|
||||
<g id="Group-2">
|
||||
<g id="Group">
|
||||
<path d="M93.7930402,70.08 C94.5430402,72.24 94.3630402,74.54 93.3630402,76.54 C92.6430402,78 91.6130402,79.13 90.3530402,80.14 C88.8330402,81.34 86.9430402,82.36 84.6630402,83.34 C81.9430402,84.5 78.6230402,85.59 77.1030402,85.99 C73.2130402,87 69.4730402,87.64 65.6830402,87.67 C60.2630402,87.72 55.5930402,86.44 52.2730402,83.17 C50.5530402,83.38 48.8130402,83.5 47.0630402,83.5 C45.4030402,83.5 43.7630402,83.4 42.1330402,83.2 C38.8030402,86.45 34.1530402,87.72 28.7530402,87.67 C24.9630402,87.64 21.2230402,87 17.3230402,85.99 C15.8130402,85.59 12.4930402,84.5 9.77304019,83.34 C7.49304019,82.36 5.60304019,81.34 4.09304019,80.14 C2.82304019,79.13 1.79304019,78 1.07304019,76.54 C0.0830401858,74.54 -0.106959814,72.24 0.653040186,70.08 C-0.0469598142,68.43 -0.226959814,66.54 0.323040186,64.45 C0.573040186,63.5 0.983040186,62.62 1.50304019,61.84 C1.39304019,61.43 1.30304019,61.01 1.24304019,60.55 C0.863040186,57.81 1.81304019,55.31 3.60304019,53.37 C4.48304019,52.4 5.43304019,51.73 6.42304019,51.3 C5.69304019,48.2 5.31304019,45.01 5.31304019,41.75 C5.31304019,18.69 24.0030402,0 47.0630402,0 C54.9830402,0 62.3930402,2.2 68.7130402,6.04 C69.8530402,6.74 70.9730402,7.49 72.0430402,8.29 C72.5730402,8.69 73.1030402,9.1 73.6130402,9.53 C74.1330402,9.95 74.6430402,10.39 75.1330402,10.84 C76.6130402,12.19 78.0030402,13.64 79.2730402,15.19 C79.7030402,15.7 80.1130402,16.23 80.5130402,16.77 C81.3230402,17.84 82.0730402,18.95 82.7630402,20.1 C83.8130402,21.82 84.7330402,23.62 85.5330402,25.49 C86.0630402,26.74 86.5230402,28.02 86.9330402,29.33 C87.5430402,31.29 88.0130402,33.31 88.3330402,35.39 C88.4330402,36.08 88.5230402,36.78 88.5930402,37.48 C88.7330402,38.88 88.8130402,40.3 88.8130402,41.75 C88.8130402,44.97 88.4330402,48.13 87.7230402,51.18 C88.8230402,51.61 89.8630402,52.31 90.8330402,53.37 C92.6230402,55.31 93.5730402,57.82 93.1930402,60.56 C93.1330402,61.01 93.0430402,61.43 92.9330402,61.84 C93.4530402,62.62 93.8630402,63.5 94.1130402,64.45 C94.6630402,66.54 94.4830402,68.43 93.7930402,70.08" id="Fill-1" fill="#FFFFFF" fill-rule="nonzero"></path>
|
||||
<circle id="Oval" fill="#FFD21E" fill-rule="nonzero" cx="46.75" cy="41.75" r="34.75"></circle>
|
||||
<path d="M81.5,41.75 C81.5,22.5581049 65.9418951,7 46.75,7 C27.5581049,7 12,22.5581049 12,41.75 C12,60.9418951 27.5581049,76.5 46.75,76.5 C65.9418951,76.5 81.5,60.9418951 81.5,41.75 Z M8,41.75 C8,20.3489659 25.3489659,3 46.75,3 C68.1510341,3 85.5,20.3489659 85.5,41.75 C85.5,63.1510341 68.1510341,80.5 46.75,80.5 C25.3489659,80.5 8,63.1510341 8,41.75 Z" id="Oval" fill="#FFAC03" fill-rule="nonzero"></path>
|
||||
<path d="M57.1723547,31.7151181 C58.0863134,32.7107502 57.3040427,35.2620959 58.7620957,35.2620959 C61.5235194,35.2620959 63.7620957,33.0235196 63.7620957,30.2620959 C63.7620957,27.5006721 61.5235194,25.2620959 58.7620957,25.2620959 C56.0006719,25.2620959 53.7620957,27.5006721 53.7620957,30.2620959 C53.7620957,31.5654666 56.3553563,30.8251108 57.1723547,31.7151181 Z" id="Oval-2" fill="#3A3B45" fill-rule="nonzero" transform="translate(58.762096, 30.262096) rotate(-28.000000) translate(-58.762096, -30.262096) "></path>
|
||||
<path d="M32.1723553,31.7151181 C33.086314,32.7107502 32.3040433,35.2620959 33.7620963,35.2620959 C36.52352,35.2620959 38.7620963,33.0235196 38.7620963,30.2620959 C38.7620963,27.5006721 36.52352,25.2620959 33.7620963,25.2620959 C31.0006725,25.2620959 28.7620963,27.5006721 28.7620963,30.2620959 C28.7620963,31.5654666 31.3553569,30.8251108 32.1723553,31.7151181 Z" id="Oval-2" fill="#3A3B45" fill-rule="nonzero" transform="translate(33.762096, 30.262096) scale(-1, 1) rotate(-28.000000) translate(-33.762096, -30.262096) "></path>
|
||||
<g id="Oval-4" transform="translate(33.500000, 41.500000)">
|
||||
<g id="Mask" fill-rule="nonzero" fill="#3A3B45">
|
||||
<path d="M13,14.7890193 C22.8284801,14.7890193 26,6.02605902 26,1.5261751 C26,-0.812484109 24.4279133,-0.0763570998 21.9099482,1.17020987 C19.5830216,2.32219957 16.4482998,3.91011313 13,3.91011313 C5.82029825,3.91011313 0,-2.97370882 0,1.5261751 C0,6.02605902 3.17151989,14.7890193 13,14.7890193 Z" id="path-1"></path>
|
||||
</g>
|
||||
<g id="Clipped">
|
||||
<mask id="mask-2" fill="white">
|
||||
<use xlink:href="#path-1"></use>
|
||||
</mask>
|
||||
<g id="path-1"></g>
|
||||
<path d="M13.25,25 C18.0399291,25 21.9229338,21.1169953 21.9229338,16.3270662 C21.9229338,12.5962324 19.5672252,9.41560375 16.2620987,8.19147116 C16.1404592,8.14641904 16.0175337,8.10401696 15.8933923,8.06433503 C15.0599892,7.79793679 14.1717882,10.6623144 13.25,10.6623144 C12.3886883,10.6623144 11.5567012,7.77968641 10.7713426,8.01349068 C7.18916268,9.07991937 4.57706621,12.3984489 4.57706621,16.3270662 C4.57706621,21.1169953 8.46007093,25 13.25,25 Z" id="Shape" fill="#EF4E4E" fill-rule="nonzero" mask="url(#mask-2)"></path>
|
||||
</g>
|
||||
</g>
|
||||
<circle id="Oval-3" fill="#FFD21E" fill-rule="nonzero" style="mix-blend-mode: multiply;" cx="70.25" cy="33.75" r="3.25"></circle>
|
||||
<circle id="Oval-3" fill="#FFD21E" fill-rule="nonzero" style="mix-blend-mode: multiply;" cx="23.75" cy="33.75" r="3.25"></circle>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
<g id="Group-4" transform="translate(3.000000, 48.000000)" fill-rule="nonzero">
|
||||
<path d="M14.0619453,0 L14.0619453,0 C12.4429453,0 10.9959453,0.665 9.98694534,1.871 C9.36294534,2.618 8.71094534,3.822 8.65794534,5.625 C7.97894534,5.43 7.32594534,5.321 6.71594534,5.321 C5.16594534,5.321 3.76594534,5.915 2.77594534,6.994 C1.50394534,8.379 0.938945345,10.081 1.18494534,11.784 C1.30194534,12.595 1.57294534,13.322 1.97794534,13.995 C1.12394534,14.686 0.494945345,15.648 0.190945345,16.805 C-0.0470546551,17.712 -0.291054655,19.601 0.982945345,21.547 C0.901945345,21.674 0.825945345,21.806 0.754945345,21.941 C-0.0110546551,23.395 -0.0600546551,25.038 0.615945345,26.568 C1.64094534,28.887 4.18794534,30.714 9.13394534,32.675 C12.2109453,33.895 15.0259453,34.675 15.0509453,34.682 C19.1189453,35.737 22.7979453,36.273 25.9829453,36.273 C31.8369453,36.273 36.0279453,34.48 38.4399453,30.944 C42.3219453,25.25 41.7669453,20.042 36.7439453,15.022 C33.9639453,12.244 32.1159453,8.148 31.7309453,7.249 C30.9549453,4.587 28.9029453,1.628 25.4919453,1.628 L25.4909453,1.628 C25.2039453,1.628 24.9139453,1.651 24.6279453,1.696 C23.1339453,1.931 21.8279453,2.791 20.8949453,4.085 C19.8879453,2.833 18.9099453,1.837 18.0249453,1.275 C16.6909453,0.429 15.3579453,0 14.0619453,0 M14.0619453,4 C14.5719453,4 15.1949453,4.217 15.8819453,4.653 C18.0149453,6.006 22.1309453,13.081 23.6379453,15.833 C24.1429453,16.755 25.0059453,17.145 25.7829453,17.145 C27.3249453,17.145 28.5289453,15.612 25.9239453,13.664 C22.0069453,10.733 23.3809453,5.942 25.2509453,5.647 C25.3329453,5.634 25.4139453,5.628 25.4919453,5.628 C27.1919453,5.628 27.9419453,8.558 27.9419453,8.558 C27.9419453,8.558 30.1399453,14.078 33.9159453,17.851 C37.6919453,21.625 37.8869453,24.654 35.1349453,28.69 C33.2579453,31.442 29.6649453,32.273 25.9829453,32.273 C22.1639453,32.273 18.2489453,31.379 16.0549453,30.81 C15.9469453,30.782 2.60394534,27.013 4.29394534,23.805 C4.57794534,23.266 5.04594534,23.05 5.63494534,23.05 C8.01494534,23.05 12.3439453,26.592 14.2049453,26.592 C14.6209453,26.592 14.9139453,26.415 15.0339453,25.983 C15.8269453,23.138 2.97694534,21.942 4.05994534,17.821 C4.25094534,17.092 4.76894534,16.796 5.49694534,16.797 C8.64194534,16.797 15.6979453,22.328 17.1769453,22.328 C17.2899453,22.328 17.3709453,22.295 17.4149453,22.225 C18.1559453,21.029 17.7499453,20.194 12.5269453,17.033 C7.30394534,13.871 3.63794534,11.969 5.72294534,9.699 C5.96294534,9.437 6.30294534,9.321 6.71594534,9.321 C9.88694534,9.322 17.3789453,16.14 17.3789453,16.14 C17.3789453,16.14 19.4009453,18.243 20.6239453,18.243 C20.9049453,18.243 21.1439453,18.132 21.3059453,17.858 C22.1729453,16.396 13.2529453,9.636 12.7499453,6.847 C12.4089453,4.957 12.9889453,4 14.0619453,4" id="Fill-1" fill="#FFAC03"></path>
|
||||
<path d="M35.1348,28.6899 C37.8868,24.6539 37.6918,21.6249 33.9158,17.8509 C30.1398,14.0779 27.9418,8.5579 27.9418,8.5579 C27.9418,8.5579 27.1208,5.3519 25.2508,5.6469 C23.3808,5.9419 22.0078,10.7329 25.9248,13.6639 C29.8418,16.5939 25.1448,18.5849 23.6378,15.8329 C22.1308,13.0809 18.0158,6.0059 15.8818,4.6529 C13.7488,3.2999 12.2468,4.0579 12.7498,6.8469 C13.2528,9.6359 22.1738,16.3959 21.3058,17.8589 C20.4378,19.3209 17.3788,16.1399 17.3788,16.1399 C17.3788,16.1399 7.8068,7.4289 5.7228,9.6989 C3.6388,11.9689 7.3038,13.8709 12.5268,17.0329 C17.7508,20.1939 18.1558,21.0289 17.4148,22.2249 C16.6728,23.4209 5.1428,13.6999 4.0598,17.8209 C2.9778,21.9419 15.8268,23.1379 15.0338,25.9829 C14.2408,28.8289 5.9828,20.5979 4.2938,23.8049 C2.6038,27.0129 15.9468,30.7819 16.0548,30.8099 C20.3648,31.9279 31.3108,34.2969 35.1348,28.6899" id="Fill-4" fill="#FFD21E"></path>
|
||||
</g>
|
||||
<g id="Group-4" transform="translate(70.500000, 66.500000) scale(-1, 1) translate(-70.500000, -66.500000) translate(50.000000, 48.000000)" fill-rule="nonzero">
|
||||
<path d="M14.0619453,0 L14.0619453,0 C12.4429453,0 10.9959453,0.665 9.98694534,1.871 C9.36294534,2.618 8.71094534,3.822 8.65794534,5.625 C7.97894534,5.43 7.32594534,5.321 6.71594534,5.321 C5.16594534,5.321 3.76594534,5.915 2.77594534,6.994 C1.50394534,8.379 0.938945345,10.081 1.18494534,11.784 C1.30194534,12.595 1.57294534,13.322 1.97794534,13.995 C1.12394534,14.686 0.494945345,15.648 0.190945345,16.805 C-0.0470546551,17.712 -0.291054655,19.601 0.982945345,21.547 C0.901945345,21.674 0.825945345,21.806 0.754945345,21.941 C-0.0110546551,23.395 -0.0600546551,25.038 0.615945345,26.568 C1.64094534,28.887 4.18794534,30.714 9.13394534,32.675 C12.2109453,33.895 15.0259453,34.675 15.0509453,34.682 C19.1189453,35.737 22.7979453,36.273 25.9829453,36.273 C31.8369453,36.273 36.0279453,34.48 38.4399453,30.944 C42.3219453,25.25 41.7669453,20.042 36.7439453,15.022 C33.9639453,12.244 32.1159453,8.148 31.7309453,7.249 C30.9549453,4.587 28.9029453,1.628 25.4919453,1.628 L25.4909453,1.628 C25.2039453,1.628 24.9139453,1.651 24.6279453,1.696 C23.1339453,1.931 21.8279453,2.791 20.8949453,4.085 C19.8879453,2.833 18.9099453,1.837 18.0249453,1.275 C16.6909453,0.429 15.3579453,0 14.0619453,0 M14.0619453,4 C14.5719453,4 15.1949453,4.217 15.8819453,4.653 C18.0149453,6.006 22.1309453,13.081 23.6379453,15.833 C24.1429453,16.755 25.0059453,17.145 25.7829453,17.145 C27.3249453,17.145 28.5289453,15.612 25.9239453,13.664 C22.0069453,10.733 23.3809453,5.942 25.2509453,5.647 C25.3329453,5.634 25.4139453,5.628 25.4919453,5.628 C27.1919453,5.628 27.9419453,8.558 27.9419453,8.558 C27.9419453,8.558 30.1399453,14.078 33.9159453,17.851 C37.6919453,21.625 37.8869453,24.654 35.1349453,28.69 C33.2579453,31.442 29.6649453,32.273 25.9829453,32.273 C22.1639453,32.273 18.2489453,31.379 16.0549453,30.81 C15.9469453,30.782 2.60394534,27.013 4.29394534,23.805 C4.57794534,23.266 5.04594534,23.05 5.63494534,23.05 C8.01494534,23.05 12.3439453,26.592 14.2049453,26.592 C14.6209453,26.592 14.9139453,26.415 15.0339453,25.983 C15.8269453,23.138 2.97694534,21.942 4.05994534,17.821 C4.25094534,17.092 4.76894534,16.796 5.49694534,16.797 C8.64194534,16.797 15.6979453,22.328 17.1769453,22.328 C17.2899453,22.328 17.3709453,22.295 17.4149453,22.225 C18.1559453,21.029 17.7499453,20.194 12.5269453,17.033 C7.30394534,13.871 3.63794534,11.969 5.72294534,9.699 C5.96294534,9.437 6.30294534,9.321 6.71594534,9.321 C9.88694534,9.322 17.3789453,16.14 17.3789453,16.14 C17.3789453,16.14 19.4009453,18.243 20.6239453,18.243 C20.9049453,18.243 21.1439453,18.132 21.3059453,17.858 C22.1729453,16.396 13.2529453,9.636 12.7499453,6.847 C12.4089453,4.957 12.9889453,4 14.0619453,4" id="Fill-1" fill="#FFAC03"></path>
|
||||
<path d="M35.1348,28.6899 C37.8868,24.6539 37.6918,21.6249 33.9158,17.8509 C30.1398,14.0779 27.9418,8.5579 27.9418,8.5579 C27.9418,8.5579 27.1208,5.3519 25.2508,5.6469 C23.3808,5.9419 22.0078,10.7329 25.9248,13.6639 C29.8418,16.5939 25.1448,18.5849 23.6378,15.8329 C22.1308,13.0809 18.0158,6.0059 15.8818,4.6529 C13.7488,3.2999 12.2468,4.0579 12.7498,6.8469 C13.2528,9.6359 22.1738,16.3959 21.3058,17.8589 C20.4378,19.3209 17.3788,16.1399 17.3788,16.1399 C17.3788,16.1399 7.8068,7.4289 5.7228,9.6989 C3.6388,11.9689 7.3038,13.8709 12.5268,17.0329 C17.7508,20.1939 18.1558,21.0289 17.4148,22.2249 C16.6728,23.4209 5.1428,13.6999 4.0598,17.8209 C2.9778,21.9419 15.8268,23.1379 15.0338,25.9829 C14.2408,28.8289 5.9828,20.5979 4.2938,23.8049 C2.6038,27.0129 15.9468,30.7819 16.0548,30.8099 C20.3648,31.9279 31.3108,34.2969 35.1348,28.6899" id="Fill-4" fill="#FFD21E"></path>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
</svg>
|
||||
|
Before Width: | Height: | Size: 7.6 KiB After Width: | Height: | Size: 14 KiB |
+2
-8
@@ -20,13 +20,13 @@ sys.path.insert(0, os.path.abspath('../../src'))
|
||||
# -- Project information -----------------------------------------------------
|
||||
|
||||
project = u'transformers'
|
||||
copyright = u'2020, huggingface'
|
||||
copyright = u'2019, huggingface'
|
||||
author = u'huggingface'
|
||||
|
||||
# The short X.Y version
|
||||
version = u''
|
||||
# The full version, including alpha/beta/rc tags
|
||||
release = u'2.5.1'
|
||||
release = u'2.5.0'
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
@@ -105,12 +105,6 @@ html_static_path = ['_static']
|
||||
#
|
||||
# html_sidebars = {}
|
||||
|
||||
# This must be the name of an image file (path relative to the configuration
|
||||
# directory) that is the favicon of the docs. Modern browsers use this as
|
||||
# the icon for tabs, windows and bookmarks. It should be a Windows-style
|
||||
# icon file (.ico).
|
||||
html_favicon = 'favicon.ico'
|
||||
|
||||
|
||||
# -- Options for HTMLHelp output ---------------------------------------------
|
||||
|
||||
|
||||
Binary file not shown.
|
Before Width: | Height: | Size: 47 KiB |
@@ -61,7 +61,6 @@ The library currently contains PyTorch and Tensorflow implementations, pre-train
|
||||
quickstart
|
||||
glossary
|
||||
pretrained_models
|
||||
usage
|
||||
model_sharing
|
||||
examples
|
||||
notebooks
|
||||
|
||||
@@ -41,8 +41,7 @@ AlbertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.AlbertTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
AlbertModel
|
||||
|
||||
@@ -46,8 +46,7 @@ BertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BertTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
BertModel
|
||||
|
||||
@@ -33,8 +33,7 @@ CamembertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.CamembertTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
CamembertModel
|
||||
|
||||
@@ -43,7 +43,7 @@ CTRLTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.CTRLTokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
CTRLModel
|
||||
|
||||
@@ -47,7 +47,7 @@ OpenAIGPTTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.OpenAIGPTTokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
OpenAIGPTModel
|
||||
|
||||
@@ -5,7 +5,7 @@ Overview
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
OpenAI GPT-2 model was proposed in
|
||||
`Language Models are Unsupervised Multitask Learners <https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf>`_
|
||||
`Language Models are Unsupervised Multitask Learners`_
|
||||
by Alec Radford*, Jeffrey Wu*, Rewon Child, David Luan, Dario Amodei** and Ilya Sutskever**.
|
||||
It's a causal (unidirectional) transformer pre-trained using language modeling on a very large
|
||||
corpus of ~40 GB of text data.
|
||||
@@ -46,7 +46,7 @@ GPT2Tokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.GPT2Tokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
GPT2Model
|
||||
|
||||
@@ -39,8 +39,7 @@ RobertaTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.RobertaTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
RobertaModel
|
||||
|
||||
@@ -42,7 +42,7 @@ TransfoXLTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TransfoXLTokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
TransfoXLModel
|
||||
|
||||
@@ -41,8 +41,7 @@ XLMTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.XLMTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
XLMModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
@@ -39,8 +39,7 @@ XLMRobertaTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.XLMRobertaTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
XLMRobertaModel
|
||||
|
||||
@@ -44,8 +44,7 @@ XLNetTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.XLNetTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
XLNetModel
|
||||
|
||||
@@ -1,597 +0,0 @@
|
||||
Usage
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
This page shows the most frequent use-cases when using the library. The models available allow for many different
|
||||
configurations and a great versatility in use-cases. The most simple ones are presented here, showcasing usage
|
||||
for tasks such as question answering, sequence classification, named entity recognition and others.
|
||||
|
||||
These examples leverage auto-models, which are classes that will instantiate a model according to a given checkpoint,
|
||||
automatically selecting the correct model architecture. Please check the :class:`~transformers.AutoModel` documentation
|
||||
for more information.
|
||||
Feel free to modify the code to be more specific and adapt it to your specific use-case.
|
||||
|
||||
In order for a model to perform well on a task, it must be loaded from a checkpoint corresponding to that task. These
|
||||
checkpoints are usually pre-trained on a large corpus of data and fine-tuned on a specific task. This means the
|
||||
following:
|
||||
|
||||
- Not all models were fine-tuned on all tasks. If you want to fine-tune a model on a specific task, you can leverage
|
||||
one of the `run_$TASK.py` script in the
|
||||
`examples <https://github.com/huggingface/transformers/tree/master/examples>`_ directory.
|
||||
- Fine-tuned models were fine-tuned on a specific dataset. This dataset may or may not overlap with your use-case
|
||||
and domain. As mentioned previously, you may leverage the
|
||||
`examples <https://github.com/huggingface/transformers/tree/master/examples>`_ scripts to fine-tune your model, or you
|
||||
may create your own training script.
|
||||
|
||||
In order to do an inference on a task, several mechanisms are made available by the library:
|
||||
|
||||
- Pipelines: very easy-to-use abstractions, which require as little as two lines of code.
|
||||
- Using a model directly with a tokenizer (PyTorch/TensorFlow): the full inference using the model. Less abstraction,
|
||||
but much more powerful.
|
||||
|
||||
Both approaches are showcased here.
|
||||
|
||||
.. note::
|
||||
|
||||
All tasks presented here leverage pre-trained checkpoints that were fine-tuned on specific tasks. Loading a
|
||||
checkpoint that was not fine-tuned on a specific task would load only the base transformer layers and not the
|
||||
additional head that is used for the task, initializing the weights of that head randomly.
|
||||
|
||||
This would produce random output.
|
||||
|
||||
Sequence Classification
|
||||
--------------------------
|
||||
|
||||
Sequence classification is the task of classifying sequences according to a given number of classes. An example
|
||||
of sequence classification is the GLUE dataset, which is entirely based on that task. If you would like to fine-tune
|
||||
a model on a GLUE sequence classification task, you may leverage the
|
||||
`run_glue.py <https://github.com/huggingface/transformers/tree/master/examples/run_glue.py>`_ or
|
||||
`run_tf_glue.py <https://github.com/huggingface/transformers/tree/master/examples/run_tf_glue.py>`_ scripts.
|
||||
|
||||
Here is an example using the pipelines do to sentiment analysis: identifying if a sequence is positive or negative.
|
||||
It leverages a fine-tuned model on sst2, which is a GLUE task.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("sentiment-analysis")
|
||||
|
||||
print(nlp("I hate you"))
|
||||
print(nlp("I love you"))
|
||||
|
||||
This returns a label ("POSITIVE" or "NEGATIVE") alongside a score, as follows:
|
||||
|
||||
::
|
||||
|
||||
[{'label': 'NEGATIVE', 'score': 0.9991129}]
|
||||
[{'label': 'POSITIVE', 'score': 0.99986565}]
|
||||
|
||||
|
||||
Here is an example of doing a sequence classification using a model to determine if two sequences are paraphrases
|
||||
of each other. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a BERT model and loads it
|
||||
with the weights stored in the checkpoint.
|
||||
- Build a sequence from the two sentences, with the correct model-specific separators token type ids
|
||||
and attention masks (:func:`~transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`~transformers.PreTrainedTokenizer.encode_plus` take care of this)
|
||||
- Pass this sequence through the model so that it is classified in one of the two available classes: 0
|
||||
(not a paraphrase) and 1 (is a paraphrase)
|
||||
- Compute the softmax of the result to get probabilities over the classes
|
||||
- Print the results
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoTokenizer, AutoModelForSequenceClassification
|
||||
import torch
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
|
||||
classes = ["not paraphrase", "is paraphrase"]
|
||||
|
||||
sequence_0 = "The company HuggingFace is based in New York City"
|
||||
sequence_1 = "Apples are especially bad for your health"
|
||||
sequence_2 = "HuggingFace's headquarters are situated in Manhattan"
|
||||
|
||||
paraphrase = tokenizer.encode_plus(sequence_0, sequence_2, return_tensors="pt")
|
||||
not_paraphrase = tokenizer.encode_plus(sequence_0, sequence_1, return_tensors="pt")
|
||||
|
||||
paraphrase_classification_logits = model(**paraphrase)[0]
|
||||
not_paraphrase_classification_logits = model(**not_paraphrase)[0]
|
||||
|
||||
paraphrase_results = torch.softmax(paraphrase_classification_logits, dim=1).tolist()[0]
|
||||
not_paraphrase_results = torch.softmax(not_paraphrase_classification_logits, dim=1).tolist()[0]
|
||||
|
||||
print("Should be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(paraphrase_results[i] * 100)}%")
|
||||
|
||||
print("\nShould not be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(not_paraphrase_results[i] * 100)}%")
|
||||
## TENSORFLOW CODE
|
||||
from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
model = TFAutoModelForSequenceClassification.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
|
||||
classes = ["not paraphrase", "is paraphrase"]
|
||||
|
||||
sequence_0 = "The company HuggingFace is based in New York City"
|
||||
sequence_1 = "Apples are especially bad for your health"
|
||||
sequence_2 = "HuggingFace's headquarters are situated in Manhattan"
|
||||
|
||||
paraphrase = tokenizer.encode_plus(sequence_0, sequence_2, return_tensors="tf")
|
||||
not_paraphrase = tokenizer.encode_plus(sequence_0, sequence_1, return_tensors="tf")
|
||||
|
||||
paraphrase_classification_logits = model(paraphrase)[0]
|
||||
not_paraphrase_classification_logits = model(not_paraphrase)[0]
|
||||
|
||||
paraphrase_results = tf.nn.softmax(paraphrase_classification_logits, axis=1).numpy()[0]
|
||||
not_paraphrase_results = tf.nn.softmax(not_paraphrase_classification_logits, axis=1).numpy()[0]
|
||||
|
||||
print("Should be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(paraphrase_results[i] * 100)}%")
|
||||
|
||||
print("\nShould not be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(not_paraphrase_results[i] * 100)}%")
|
||||
|
||||
This outputs the following results:
|
||||
|
||||
::
|
||||
|
||||
Should be paraphrase
|
||||
not paraphrase: 10%
|
||||
is paraphrase: 90%
|
||||
|
||||
Should not be paraphrase
|
||||
not paraphrase: 94%
|
||||
is paraphrase: 6%
|
||||
|
||||
Extractive Question Answering
|
||||
----------------------------------------------------
|
||||
|
||||
Extractive Question Answering is the task of extracting an answer from a text given a question. An example of a
|
||||
question answering dataset is the SQuAD dataset, which is entirely based on that task. If you would like to fine-tune
|
||||
a model on a SQuAD task, you may leverage the `run_squad.py`.
|
||||
|
||||
Here is an example using the pipelines do to question answering: extracting an answer from a text given a question.
|
||||
It leverages a fine-tuned model on SQuAD.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("question-answering")
|
||||
|
||||
context = r"""
|
||||
Extractive Question Answering is the task of extracting an answer from a text given a question. An example of a
|
||||
question answering dataset is the SQuAD dataset, which is entirely based on that task. If you would like to fine-tune
|
||||
a model on a SQuAD task, you may leverage the `run_squad.py`.
|
||||
"""
|
||||
|
||||
print(nlp(question="What is extractive question answering?", context=context))
|
||||
print(nlp(question="What is a good example of a question answering dataset?", context=context))
|
||||
|
||||
This returns an answer extracted from the text, a confidence score, alongside "start" and "end" values which
|
||||
are the positions of the extracted answer in the text.
|
||||
|
||||
::
|
||||
|
||||
{'score': 0.622232091629833, 'start': 34, 'end': 96, 'answer': 'the task of extracting an answer from a text given a question.'}
|
||||
{'score': 0.5115299158662765, 'start': 147, 'end': 161, 'answer': 'SQuAD dataset,'}
|
||||
|
||||
|
||||
Here is an example of question answering using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a BERT model and loads it
|
||||
with the weights stored in the checkpoint.
|
||||
- Define a text and a few questions.
|
||||
- Iterate over the questions and build a sequence from the text and the current question, with the correct
|
||||
model-specific separators token type ids and attention masks
|
||||
- Pass this sequence through the model. This outputs a range of scores across the entire sequence tokens (question and
|
||||
text), for both the start and end positions.
|
||||
- Compute the softmax of the result to get probabilities over the tokens
|
||||
- Fetch the tokens from the identified start and stop values, convert those tokens to a string.
|
||||
- Print the results
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoTokenizer, AutoModelForQuestionAnswering
|
||||
import torch
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
model = AutoModelForQuestionAnswering.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
|
||||
text = r"""
|
||||
🤗 Transformers (formerly known as pytorch-transformers and pytorch-pretrained-bert) provides general-purpose
|
||||
architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet…) for Natural Language Understanding (NLU) and Natural
|
||||
Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between
|
||||
TensorFlow 2.0 and PyTorch.
|
||||
"""
|
||||
|
||||
questions = [
|
||||
"How many pretrained models are available in Transformers?",
|
||||
"What does Transformers provide?",
|
||||
"Transformers provides interoperability between which frameworks?",
|
||||
]
|
||||
|
||||
for question in questions:
|
||||
inputs = tokenizer.encode_plus(question, text, add_special_tokens=True, return_tensors="pt")
|
||||
input_ids = inputs["input_ids"].tolist()[0]
|
||||
|
||||
text_tokens = tokenizer.convert_ids_to_tokens(input_ids)
|
||||
answer_start_scores, answer_end_scores = model(**inputs)
|
||||
|
||||
answer_start = torch.argmax(
|
||||
answer_start_scores
|
||||
) # Get the most likely beginning of answer with the argmax of the score
|
||||
answer_end = torch.argmax(answer_end_scores) + 1 # Get the most likely end of answer with the argmax of the score
|
||||
|
||||
answer = tokenizer.convert_tokens_to_string(tokenizer.convert_ids_to_tokens(input_ids[answer_start:answer_end]))
|
||||
|
||||
print(f"Question: {question}")
|
||||
print(f"Answer: {answer}\n")
|
||||
## TENSORFLOW CODE
|
||||
from transformers import AutoTokenizer, TFAutoModelForQuestionAnswering
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
model = TFAutoModelForQuestionAnswering.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
|
||||
text = r"""
|
||||
🤗 Transformers (formerly known as pytorch-transformers and pytorch-pretrained-bert) provides general-purpose
|
||||
architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet…) for Natural Language Understanding (NLU) and Natural
|
||||
Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between
|
||||
TensorFlow 2.0 and PyTorch.
|
||||
"""
|
||||
|
||||
questions = [
|
||||
"How many pretrained models are available in Transformers?",
|
||||
"What does Transformers provide?",
|
||||
"Transformers provides interoperability between which frameworks?",
|
||||
]
|
||||
|
||||
for question in questions:
|
||||
inputs = tokenizer.encode_plus(question, text, add_special_tokens=True, return_tensors="tf")
|
||||
input_ids = inputs["input_ids"].numpy()[0]
|
||||
|
||||
text_tokens = tokenizer.convert_ids_to_tokens(input_ids)
|
||||
answer_start_scores, answer_end_scores = model(inputs)
|
||||
|
||||
answer_start = tf.argmax(
|
||||
answer_start_scores, axis=1
|
||||
).numpy()[0] # Get the most likely beginning of answer with the argmax of the score
|
||||
answer_end = (
|
||||
tf.argmax(answer_end_scores, axis=1) + 1
|
||||
).numpy()[0] # Get the most likely end of answer with the argmax of the score
|
||||
answer = tokenizer.convert_tokens_to_string(tokenizer.convert_ids_to_tokens(input_ids[answer_start:answer_end]))
|
||||
|
||||
print(f"Question: {question}")
|
||||
print(f"Answer: {answer}\n")
|
||||
|
||||
This outputs the questions followed by the predicted answers:
|
||||
|
||||
::
|
||||
|
||||
Question: How many pretrained models are available in Transformers?
|
||||
Answer: over 32 +
|
||||
|
||||
Question: What does Transformers provide?
|
||||
Answer: general - purpose architectures
|
||||
|
||||
Question: Transformers provides interoperability between which frameworks?
|
||||
Answer: tensorflow 2 . 0 and pytorch
|
||||
|
||||
|
||||
|
||||
Language Modeling
|
||||
----------------------------------------------------
|
||||
|
||||
Language modeling is the task of fitting a model to a corpus, which can be domain specific. All popular transformer
|
||||
based models are trained using a variant of language modeling, e.g. BERT with masked language modeling, GPT-2 with
|
||||
causal language modeling.
|
||||
|
||||
Language modeling can be useful outside of pre-training as well, for example to shift the model distribution to be
|
||||
domain-specific: using a language model trained over a very large corpus, and then fine-tuning it to a news dataset
|
||||
or on scientific papers e.g. `LysandreJik/arxiv-nlp <https://huggingface.co/lysandre/arxiv-nlp>`__.
|
||||
|
||||
Masked Language Modeling
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Masked language modeling is the task of masking tokens in a sequence with a masking token, and prompting the model to
|
||||
fill that mask with an appropriate token. This allows the model to attend to both the right context (tokens on the
|
||||
right of the mask) and the left context (tokens on the left of the mask). Such a training creates a strong basis
|
||||
for downstream tasks requiring bi-directional context such as SQuAD (question answering,
|
||||
see `Lewis, Lui, Goyal et al. <https://arxiv.org/abs/1910.13461>`__, part 4.2).
|
||||
|
||||
Here is an example of using pipelines to replace a mask from a sequence:
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("fill-mask")
|
||||
print(nlp(f"HuggingFace is creating a {nlp.tokenizer.mask_token} that the community uses to solve NLP tasks."))
|
||||
|
||||
This outputs the sequences with the mask filled, the confidence score as well as the token id in the tokenizer
|
||||
vocabulary:
|
||||
|
||||
::
|
||||
|
||||
[
|
||||
{'sequence': '<s> HuggingFace is creating a tool that the community uses to solve NLP tasks.</s>', 'score': 0.15627853572368622, 'token': 3944},
|
||||
{'sequence': '<s> HuggingFace is creating a framework that the community uses to solve NLP tasks.</s>', 'score': 0.11690319329500198, 'token': 7208},
|
||||
{'sequence': '<s> HuggingFace is creating a library that the community uses to solve NLP tasks.</s>', 'score': 0.058063216507434845, 'token': 5560},
|
||||
{'sequence': '<s> HuggingFace is creating a database that the community uses to solve NLP tasks.</s>', 'score': 0.04211743175983429, 'token': 8503},
|
||||
{'sequence': '<s> HuggingFace is creating a prototype that the community uses to solve NLP tasks.</s>', 'score': 0.024718601256608963, 'token': 17715}
|
||||
]
|
||||
|
||||
Here is an example doing masked language modeling using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a DistilBERT model and
|
||||
loads it with the weights stored in the checkpoint.
|
||||
- Define a sequence with a masked token, placing the :obj:`tokenizer.mask_token` instead of a word.
|
||||
- Encode that sequence into IDs and find the position of the masked token in that list of IDs.
|
||||
- Retrieve the predictions at the index of the mask token: this tensor has the same size as the vocabulary, and the
|
||||
values are the scores attributed to each token. The model gives higher score to tokens he deems probable in that
|
||||
context.
|
||||
- Retrieve the top 5 tokens using the PyTorch :obj:`topk` or TensorFlow :obj:`top_k` methods.
|
||||
- Replace the mask token by the tokens and print the results
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
import torch
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("distilbert-base-cased")
|
||||
model = AutoModelWithLMHead.from_pretrained("distilbert-base-cased")
|
||||
|
||||
sequence = f"Distilled models are smaller than the models they mimic. Using them instead of the large versions would help {tokenizer.mask_token} our carbon footprint."
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="pt")
|
||||
mask_token_index = torch.where(input == tokenizer.mask_token_id)[1]
|
||||
|
||||
token_logits = model(input)[0]
|
||||
mask_token_logits = token_logits[0, mask_token_index, :]
|
||||
|
||||
top_5_tokens = torch.topk(mask_token_logits, 5, dim=1).indices[0].tolist()
|
||||
|
||||
for token in top_5_tokens:
|
||||
print(sequence.replace(tokenizer.mask_token, tokenizer.decode([token])))
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelWithLMHead, AutoTokenizer
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("distilbert-base-cased")
|
||||
model = TFAutoModelWithLMHead.from_pretrained("distilbert-base-cased")
|
||||
|
||||
sequence = f"Distilled models are smaller than the models they mimic. Using them instead of the large versions would help {tokenizer.mask_token} our carbon footprint."
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="tf")
|
||||
mask_token_index = tf.where(input == tokenizer.mask_token_id)[0, 1]
|
||||
|
||||
token_logits = model(input)[0]
|
||||
mask_token_logits = token_logits[0, mask_token_index, :]
|
||||
|
||||
top_5_tokens = tf.math.top_k(mask_token_logits, 5).indices.numpy()
|
||||
|
||||
for token in top_5_tokens:
|
||||
print(sequence.replace(tokenizer.mask_token, tokenizer.decode([token])))
|
||||
|
||||
This prints five sequences, with the top 5 tokens predicted by the model:
|
||||
|
||||
::
|
||||
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help reduce our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help increase our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help decrease our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help offset our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help improve our carbon footprint.
|
||||
|
||||
|
||||
Causal Language Modeling
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Causal language modeling is the task of predicting the token following a sequence of tokens. In this situation, the
|
||||
model only attends to the left context (tokens on the left of the mask). Such a training is particularly interesting
|
||||
for generation tasks.
|
||||
|
||||
There is currently no pipeline to do causal language modeling/generation.
|
||||
|
||||
Here is an example using the tokenizer and model. leveraging the :func:`~transformers.PreTrainedModel.generate` method
|
||||
to generate the tokens following the initial sequence in PyTorch, and creating a simple loop in TensorFlow.
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("gpt2")
|
||||
model = AutoModelWithLMHead.from_pretrained("gpt2")
|
||||
|
||||
sequence = f"Hugging Face is based in DUMBO, New York City, and is"
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="pt")
|
||||
generated = model.generate(input, max_length=50)
|
||||
|
||||
resulting_string = tokenizer.decode(generated.tolist()[0])
|
||||
print(resulting_string)
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelWithLMHead, AutoTokenizer
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("gpt2")
|
||||
model = TFAutoModelWithLMHead.from_pretrained("gpt2")
|
||||
|
||||
sequence = f"Hugging Face is based in DUMBO, New York City, and is"
|
||||
generated = tokenizer.encode(sequence)
|
||||
|
||||
for i in range(50):
|
||||
predictions = model(tf.constant([generated]))[0]
|
||||
token = tf.argmax(predictions[0], axis=1)[-1].numpy()
|
||||
generated += [token]
|
||||
|
||||
resulting_string = tokenizer.decode(generated)
|
||||
print(resulting_string)
|
||||
|
||||
|
||||
This outputs a (hopefully) coherent string from the original sequence, as the
|
||||
:func:`~transformers.PreTrainedModel.generate` samples from a top_p/tok_k distribution:
|
||||
|
||||
::
|
||||
|
||||
Hugging Face is based in DUMBO, New York City, and is a live-action TV series based on the novel by John
|
||||
Carpenter, and its producers, David Kustlin and Steve Pichar. The film is directed by!
|
||||
|
||||
|
||||
Named Entity Recognition
|
||||
----------------------------------------------------
|
||||
|
||||
Named Entity Recognition (NER) is the task of classifying tokens according to a class, for example identifying a
|
||||
token as a person, an organisation or a location.
|
||||
An example of a named entity recognition dataset is the CoNLL-2003 dataset, which is entirely based on that task.
|
||||
If you would like to fine-tune a model on an NER task, you may leverage the `ner/run_ner.py` (PyTorch),
|
||||
`ner/run_pl_ner.py` (leveraging pytorch-lightning) or the `ner/run_tf_ner.py` (TensorFlow) scripts.
|
||||
|
||||
Here is an example using the pipelines do to named entity recognition, trying to identify tokens as belonging to one
|
||||
of 9 classes:
|
||||
|
||||
- O, Outside of a named entity
|
||||
- B-MIS, Beginning of a miscellaneous entity right after another miscellaneous entity
|
||||
- I-MIS, Miscellaneous entity
|
||||
- B-PER, Beginning of a person's name right after another person's name
|
||||
- I-PER, Person's name
|
||||
- B-ORG, Beginning of an organisation right after another organisation
|
||||
- I-ORG, Organisation
|
||||
- B-LOC, Beginning of a location right after another location
|
||||
- I-LOC, Location
|
||||
|
||||
It leverages a fine-tuned model on CoNLL-2003, fine-tuned by `@stefan-it <https://github.com/stefan-it>`__ from
|
||||
`dbmdz <https://github.com/dbmdz>`__.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("ner")
|
||||
|
||||
sequence = "Hugging Face Inc. is a company based in New York City. Its headquarters are in DUMBO, therefore very" \
|
||||
"close to the Manhattan Bridge which is visible from the window."
|
||||
|
||||
print(nlp(sequence))
|
||||
|
||||
This outputs a list of all words that have been identified as an entity from the 9 classes defined above. Here is the
|
||||
expected results:
|
||||
|
||||
::
|
||||
|
||||
[
|
||||
{'word': 'Hu', 'score': 0.9995632767677307, 'entity': 'I-ORG'},
|
||||
{'word': '##gging', 'score': 0.9915938973426819, 'entity': 'I-ORG'},
|
||||
{'word': 'Face', 'score': 0.9982671737670898, 'entity': 'I-ORG'},
|
||||
{'word': 'Inc', 'score': 0.9994403719902039, 'entity': 'I-ORG'},
|
||||
{'word': 'New', 'score': 0.9994346499443054, 'entity': 'I-LOC'},
|
||||
{'word': 'York', 'score': 0.9993270635604858, 'entity': 'I-LOC'},
|
||||
{'word': 'City', 'score': 0.9993864893913269, 'entity': 'I-LOC'},
|
||||
{'word': 'D', 'score': 0.9825621843338013, 'entity': 'I-LOC'},
|
||||
{'word': '##UM', 'score': 0.936983048915863, 'entity': 'I-LOC'},
|
||||
{'word': '##BO', 'score': 0.8987102508544922, 'entity': 'I-LOC'},
|
||||
{'word': 'Manhattan', 'score': 0.9758241176605225, 'entity': 'I-LOC'},
|
||||
{'word': 'Bridge', 'score': 0.990249514579773, 'entity': 'I-LOC'}
|
||||
]
|
||||
|
||||
Note how the words "Hugging Face" have been identified as an organisation, and "New York City", "DUMBO" and
|
||||
"Manhattan Bridge" have been identified as locations.
|
||||
|
||||
Here is an example doing named entity recognition using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a BERT model and
|
||||
loads it with the weights stored in the checkpoint.
|
||||
- Define the label list with which the model was trained on.
|
||||
- Define a sequence with known entities, such as "Hugging Face" as an organisation and "New York City" as a location.
|
||||
- Split words into tokens so that they can be mapped to the predictions. We use a small hack by firstly completely
|
||||
encoding and decoding the sequence, so that we're left with a string that contains the special tokens.
|
||||
- Encode that sequence into IDs (special tokens are added automatically).
|
||||
- Retrieve the predictions by passing the input to the model and getting the first output. This results in a
|
||||
distribution over the 9 possible classes for each token. We take the argmax to retrieve the most likely class
|
||||
for each token.
|
||||
- Zip together each token with its prediction and print it.
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelForTokenClassification, AutoTokenizer
|
||||
import torch
|
||||
|
||||
model = AutoModelForTokenClassification.from_pretrained("dbmdz/bert-large-cased-finetuned-conll03-english")
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
|
||||
|
||||
label_list = [
|
||||
"O", # Outside of a named entity
|
||||
"B-MISC", # Beginning of a miscellaneous entity right after another miscellaneous entity
|
||||
"I-MISC", # Miscellaneous entity
|
||||
"B-PER", # Beginning of a person's name right after another person's name
|
||||
"I-PER", # Person's name
|
||||
"B-ORG", # Beginning of an organisation right after another organisation
|
||||
"I-ORG", # Organisation
|
||||
"B-LOC", # Beginning of a location right after another location
|
||||
"I-LOC" # Location
|
||||
]
|
||||
|
||||
sequence = "Hugging Face Inc. is a company based in New York City. Its headquarters are in DUMBO, therefore very" \
|
||||
"close to the Manhattan Bridge."
|
||||
|
||||
# Bit of a hack to get the tokens with the special tokens
|
||||
tokens = tokenizer.tokenize(tokenizer.decode(tokenizer.encode(sequence)))
|
||||
inputs = tokenizer.encode(sequence, return_tensors="pt")
|
||||
|
||||
outputs = model(inputs)[0]
|
||||
predictions = torch.argmax(outputs, dim=2)
|
||||
|
||||
print([(token, label_list[prediction]) for token, prediction in zip(tokens, predictions[0].tolist())])
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelForTokenClassification, AutoTokenizer
|
||||
import tensorflow as tf
|
||||
|
||||
model = TFAutoModelForTokenClassification.from_pretrained("dbmdz/bert-large-cased-finetuned-conll03-english")
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
|
||||
|
||||
label_list = [
|
||||
"O", # Outside of a named entity
|
||||
"B-MISC", # Beginning of a miscellaneous entity right after another miscellaneous entity
|
||||
"I-MISC", # Miscellaneous entity
|
||||
"B-PER", # Beginning of a person's name right after another person's name
|
||||
"I-PER", # Person's name
|
||||
"B-ORG", # Beginning of an organisation right after another organisation
|
||||
"I-ORG", # Organisation
|
||||
"B-LOC", # Beginning of a location right after another location
|
||||
"I-LOC" # Location
|
||||
]
|
||||
|
||||
sequence = "Hugging Face Inc. is a company based in New York City. Its headquarters are in DUMBO, therefore very" \
|
||||
"close to the Manhattan Bridge."
|
||||
|
||||
# Bit of a hack to get the tokens with the special tokens
|
||||
tokens = tokenizer.tokenize(tokenizer.decode(tokenizer.encode(sequence)))
|
||||
inputs = tokenizer.encode(sequence, return_tensors="tf")
|
||||
|
||||
outputs = model(inputs)[0]
|
||||
predictions = tf.argmax(outputs, axis=2)
|
||||
|
||||
print([(token, label_list[prediction]) for token, prediction in zip(tokens, predictions[0].numpy())])
|
||||
|
||||
This outputs a list of each token mapped to their prediction. Differently from the pipeline, here every token has
|
||||
a prediction as we didn't remove the "0" class which means that no particular entity was found on that token. The
|
||||
following array should be the output:
|
||||
|
||||
::
|
||||
|
||||
[('[CLS]', 'O'), ('Hu', 'I-ORG'), ('##gging', 'I-ORG'), ('Face', 'I-ORG'), ('Inc', 'I-ORG'), ('.', 'O'), ('is', 'O'), ('a', 'O'), ('company', 'O'), ('based', 'O'), ('in', 'O'), ('New', 'I-LOC'), ('York', 'I-LOC'), ('City', 'I-LOC'), ('.', 'O'), ('Its', 'O'), ('headquarters', 'O'), ('are', 'O'), ('in', 'O'), ('D', 'I-LOC'), ('##UM', 'I-LOC'), ('##BO', 'I-LOC'), (',', 'O'), ('therefore', 'O'), ('very', 'O'), ('##c', 'O'), ('##lose', 'O'), ('to', 'O'), ('the', 'O'), ('Manhattan', 'I-LOC'), ('Bridge', 'I-LOC'), ('.', 'O'), ('[SEP]', 'O')]
|
||||
+1
-1
@@ -22,7 +22,7 @@ pip install -r ./examples/requirements.txt
|
||||
| [GLUE](#glue) | Examples running BERT/XLM/XLNet/RoBERTa on the 9 GLUE tasks. Examples feature distributed training as well as half-precision. |
|
||||
| [SQuAD](#squad) | Using BERT/RoBERTa/XLNet/XLM for question answering, examples with distributed training. |
|
||||
| [Multiple Choice](#multiple-choice) | Examples running BERT/XLNet/RoBERTa on the SWAG/RACE/ARC tasks. |
|
||||
| [Named Entity Recognition](https://github.com/huggingface/transformers/tree/master/examples/ner) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [Named Entity Recognition](#named-entity-recognition) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [XNLI](#xnli) | Examples running BERT/XLM on the XNLI benchmark. |
|
||||
| [Adversarial evaluation of model performances](#adversarial-evaluation-of-model-performances) | Testing a model with adversarial evaluation of natural language inference on the Heuristic Analysis for NLI Systems (HANS) dataset (McCoy et al., 2019.) |
|
||||
|
||||
|
||||
@@ -59,7 +59,7 @@ MODEL_CLASSES = {
|
||||
# Padding text to help Transformer-XL and XLNet with short prompts as proposed by Aman Rusia
|
||||
# in https://github.com/rusiaaman/XLNet-gen#methodology
|
||||
# and https://medium.com/@amanrusia/xlnet-speaks-comparison-to-gpt-2-ea1a4e9ba39e
|
||||
PADDING_TEXT = """In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
PADDING_TEXT = """ In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
(except for Alexei and Maria) are discovered.
|
||||
The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
|
||||
remainder of the story. 1883 Western Siberia,
|
||||
@@ -214,9 +214,7 @@ def main():
|
||||
if requires_preprocessing:
|
||||
prepare_input = PREPROCESSING_FUNCTIONS.get(args.model_type)
|
||||
preprocessed_prompt_text = prepare_input(args, model, tokenizer, prompt_text)
|
||||
encoded_prompt = tokenizer.encode(
|
||||
preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt", add_space_before_punct_symbol=True
|
||||
)
|
||||
encoded_prompt = tokenizer.encode(preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt")
|
||||
else:
|
||||
encoded_prompt = tokenizer.encode(prompt_text, add_special_tokens=False, return_tensors="pt")
|
||||
encoded_prompt = encoded_prompt.to(args.device)
|
||||
|
||||
@@ -1,80 +0,0 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# Spanish BERT (BETO) + POS
|
||||
|
||||
This model is a fine-tuned on [NER-C](https://www.kaggle.com/nltkdata/conll-corpora) Of the Spanish BERT cased [(BETO)](https://github.com/dccuchile/beto) for **POS** (Part of Speech tagging) downstream task.
|
||||
|
||||
## Details of the downstream task (POS) - Dataset
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora) with data augmentation techniques
|
||||
|
||||
I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
|
||||
| Dataset | # Examples |
|
||||
| ---------------------- | ----- |
|
||||
| Train | 340 K |
|
||||
| Dev | 50 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
```
|
||||
AO, AQ, CC, CS, DA, DD, DE, DI, DN, DP, DT, Faa, Fat, Fc, Fd, Fe, Fg, Fh, Fia, Fit, Fp, Fpa, Fpt, Fs, Ft, Fx, Fz, I, NC, NP, P0, PD, PI, PN, PP, PR, PT, PX, RG, RN, SP, VAI, VAM, VAN, VAP, VAS, VMG, VMI, VMM, VMN, VMP, VMS, VSG, VSI, VSM, VSN, VSP, VSS, Y and Z
|
||||
```
|
||||
|
||||
|
||||
## Metrics on evaluation set:
|
||||
|
||||
| Metric | # score |
|
||||
| :------------------------------------------------------------------------------------: | :-------: |
|
||||
| F1 | **90.06**
|
||||
| Precision | **89.46** |
|
||||
| Recall | **90.67** |
|
||||
|
||||
## Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp_pos = pipeline(
|
||||
"ner",
|
||||
model="mrm8488/bert-spanish-cased-finetuned-pos",
|
||||
tokenizer=(
|
||||
'mrm8488/bert-spanish-cased-finetuned-pos',
|
||||
{"use_fast": False}
|
||||
))
|
||||
|
||||
|
||||
text = 'Mis amigos están pensando en viajar a Londres este verano'
|
||||
|
||||
nlp_pos(text)
|
||||
|
||||
#Output:
|
||||
'''
|
||||
[{'entity': 'NC', 'score': 0.7792173624038696, 'word': '[CLS]'},
|
||||
{'entity': 'DP', 'score': 0.9996283650398254, 'word': 'Mis'},
|
||||
{'entity': 'NC', 'score': 0.9999253749847412, 'word': 'amigos'},
|
||||
{'entity': 'VMI', 'score': 0.9998560547828674, 'word': 'están'},
|
||||
{'entity': 'VMG', 'score': 0.9992249011993408, 'word': 'pensando'},
|
||||
{'entity': 'SP', 'score': 0.9999602437019348, 'word': 'en'},
|
||||
{'entity': 'VMN', 'score': 0.9998666048049927, 'word': 'viajar'},
|
||||
{'entity': 'SP', 'score': 0.9999545216560364, 'word': 'a'},
|
||||
{'entity': 'VMN', 'score': 0.8722310662269592, 'word': 'Londres'},
|
||||
{'entity': 'DD', 'score': 0.9995203614234924, 'word': 'este'},
|
||||
{'entity': 'NC', 'score': 0.9999248385429382, 'word': 'verano'},
|
||||
{'entity': 'NC', 'score': 0.8802427649497986, 'word': '[SEP]'}]
|
||||
'''
|
||||
```
|
||||
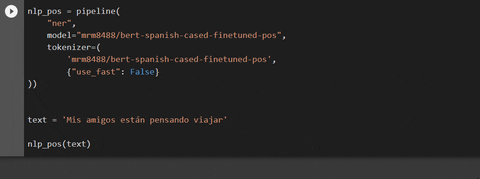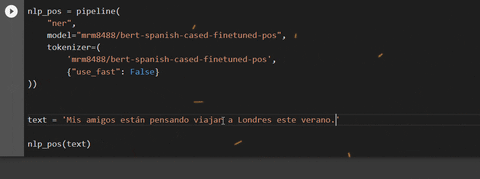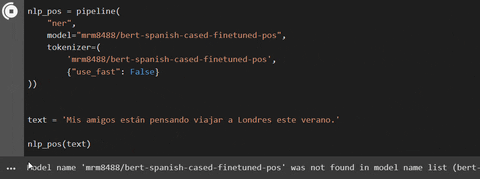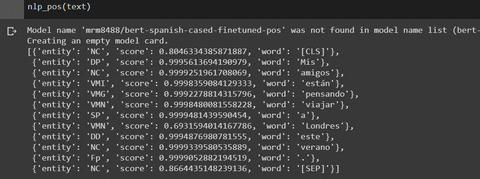
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -79,7 +79,7 @@ extras["dev"] = extras["testing"] + extras["quality"] + ["mecab-python3", "sciki
|
||||
|
||||
setup(
|
||||
name="transformers",
|
||||
version="2.5.1",
|
||||
version="2.5.0",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Sam Shleifer, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
author_email="thomas@huggingface.co",
|
||||
description="State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch",
|
||||
@@ -92,7 +92,7 @@ setup(
|
||||
packages=find_packages("src"),
|
||||
install_requires=[
|
||||
"numpy",
|
||||
"tokenizers == 0.5.2",
|
||||
"tokenizers == 0.5.0",
|
||||
# accessing files from S3 directly
|
||||
"boto3",
|
||||
# filesystem locks e.g. to prevent parallel downloads
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# There's no way to ignore "F401 '...' imported but unused" warnings in this
|
||||
# module, but to preserve other warnings. So, don't check this module at all.
|
||||
|
||||
__version__ = "2.5.1"
|
||||
__version__ = "2.5.0"
|
||||
|
||||
# Work around to update TensorFlow's absl.logging threshold which alters the
|
||||
# default Python logging output behavior when present.
|
||||
|
||||
@@ -109,12 +109,11 @@ class FlaubertConfig(XLMConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
|
||||
@@ -73,12 +73,11 @@ class GPT2Config(PretrainedConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.GPT2DoubleHeadsModel`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.GPT2DoubleHeadsModel`.
|
||||
|
||||
@@ -73,12 +73,11 @@ class OpenAIGPTConfig(PretrainedConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.OpenAIGPTDoubleHeadsModel`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.OpenAIGPTDoubleHeadsModel`.
|
||||
|
||||
@@ -198,7 +198,6 @@ class PretrainedConfig(object):
|
||||
force_download = kwargs.pop("force_download", False)
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
if pretrained_config_archive_map is None:
|
||||
pretrained_config_archive_map = cls.pretrained_config_archive_map
|
||||
@@ -220,7 +219,6 @@ class PretrainedConfig(object):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
# Load config dict
|
||||
if resolved_config_file is None:
|
||||
|
||||
@@ -108,12 +108,11 @@ class XLMConfig(PretrainedConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
|
||||
@@ -214,7 +214,6 @@ def cached_path(
|
||||
user_agent=None,
|
||||
extract_compressed_file=False,
|
||||
force_extract=False,
|
||||
local_files_only=False,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given something that might be a URL (or might be a local path),
|
||||
@@ -251,7 +250,6 @@ def cached_path(
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
user_agent=user_agent,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
elif os.path.exists(url_or_filename):
|
||||
# File, and it exists.
|
||||
@@ -380,14 +378,7 @@ def http_get(url, temp_file, proxies=None, resume_size=0, user_agent=None):
|
||||
|
||||
|
||||
def get_from_cache(
|
||||
url,
|
||||
cache_dir=None,
|
||||
force_download=False,
|
||||
proxies=None,
|
||||
etag_timeout=10,
|
||||
resume_download=False,
|
||||
user_agent=None,
|
||||
local_files_only=False,
|
||||
url, cache_dir=None, force_download=False, proxies=None, etag_timeout=10, resume_download=False, user_agent=None
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given a URL, look for the corresponding file in the local cache.
|
||||
@@ -404,19 +395,18 @@ def get_from_cache(
|
||||
|
||||
os.makedirs(cache_dir, exist_ok=True)
|
||||
|
||||
etag = None
|
||||
if not local_files_only:
|
||||
# Get eTag to add to filename, if it exists.
|
||||
if url.startswith("s3://"):
|
||||
etag = s3_etag(url, proxies=proxies)
|
||||
else:
|
||||
try:
|
||||
response = requests.head(url, allow_redirects=True, proxies=proxies, timeout=etag_timeout)
|
||||
if response.status_code == 200:
|
||||
etag = response.headers.get("ETag")
|
||||
except (EnvironmentError, requests.exceptions.Timeout):
|
||||
# etag is already None
|
||||
pass
|
||||
# Get eTag to add to filename, if it exists.
|
||||
if url.startswith("s3://"):
|
||||
etag = s3_etag(url, proxies=proxies)
|
||||
else:
|
||||
try:
|
||||
response = requests.head(url, allow_redirects=True, proxies=proxies, timeout=etag_timeout)
|
||||
if response.status_code != 200:
|
||||
etag = None
|
||||
else:
|
||||
etag = response.headers.get("ETag")
|
||||
except (EnvironmentError, requests.exceptions.Timeout):
|
||||
etag = None
|
||||
|
||||
filename = url_to_filename(url, etag)
|
||||
|
||||
@@ -437,15 +427,6 @@ def get_from_cache(
|
||||
if len(matching_files) > 0:
|
||||
return os.path.join(cache_dir, matching_files[-1])
|
||||
else:
|
||||
# If files cannot be found and local_files_only=True,
|
||||
# the models might've been found if local_files_only=False
|
||||
# Notify the user about that
|
||||
if local_files_only:
|
||||
raise ValueError(
|
||||
"Cannot find the requested files in the cached path and outgoing traffic has been"
|
||||
" disabled. To enable model look-ups and downloads online, set 'local_files_only'"
|
||||
" to False."
|
||||
)
|
||||
return None
|
||||
|
||||
# From now on, etag is not None.
|
||||
|
||||
@@ -1230,7 +1230,7 @@ class BertForMultipleChoice(BertPreTrainedModel):
|
||||
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
loss (:obj:`torch.FloatTensor`` of shape ``(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification loss.
|
||||
classification_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_choices)`):
|
||||
`num_choices` is the second dimension of the input tensors. (see `input_ids` above).
|
||||
@@ -1382,10 +1382,8 @@ class BertForTokenClassification(BertPreTrainedModel):
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -818,10 +818,8 @@ class DistilBertForTokenClassification(DistilBertPreTrainedModel):
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -542,16 +542,13 @@ class RobertaForTokenClassification(BertPreTrainedModel):
|
||||
logits = self.classifier(sequence_output)
|
||||
|
||||
outputs = (logits,) + outputs[2:] # add hidden states and attention if they are here
|
||||
|
||||
if labels is not None:
|
||||
loss_fct = CrossEntropyLoss()
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -668,39 +668,38 @@ class TFBertModel(TFBertPreTrainedModel):
|
||||
@add_start_docstrings_to_callable(BERT_INPUTS_DOCSTRING)
|
||||
def call(self, inputs, **kwargs):
|
||||
r"""
|
||||
Returns:
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
|
||||
last_hidden_state (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
pooler_output (:obj:`tf.Tensor` of shape :obj:`(batch_size, hidden_size)`):
|
||||
Last layer hidden-state of the first token of the sequence (classification token)
|
||||
further processed by a Linear layer and a Tanh activation function. The Linear
|
||||
layer weights are trained from the next sentence prediction (classification)
|
||||
objective during Bert pretraining. This output is usually *not* a good summary
|
||||
of the semantic content of the input, you're often better with averaging or pooling
|
||||
the sequence of hidden-states for the whole input sequence.
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when :obj:`config.output_hidden_states=True`):
|
||||
tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`:
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
|
||||
|
||||
Examples::
|
||||
|
||||
Examples::
|
||||
import tensorflow as tf
|
||||
from transformers import BertTokenizer, TFBertModel
|
||||
|
||||
import tensorflow as tf
|
||||
from transformers import BertTokenizer, TFBertModel
|
||||
|
||||
tokenizer = BertTokenizer.from_pretrained('bert-base-uncased')
|
||||
model = TFBertModel.from_pretrained('bert-base-uncased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
"""
|
||||
outputs = self.bert(inputs, **kwargs)
|
||||
return outputs
|
||||
|
||||
@@ -645,7 +645,7 @@ class TransfoXLModel(TransfoXLPreTrainedModel):
|
||||
else:
|
||||
return None
|
||||
|
||||
def _update_mems(self, hids, mems, mlen, qlen):
|
||||
def _update_mems(self, hids, mems, qlen, mlen):
|
||||
# does not deal with None
|
||||
if mems is None:
|
||||
return None
|
||||
|
||||
@@ -376,7 +376,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
output_loading_info = kwargs.pop("output_loading_info", False)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
# Load config if we don't provide a configuration
|
||||
if not isinstance(config, PretrainedConfig):
|
||||
@@ -389,7 +388,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
force_download=force_download,
|
||||
resume_download=resume_download,
|
||||
proxies=proxies,
|
||||
local_files_only=local_files_only,
|
||||
**kwargs,
|
||||
)
|
||||
else:
|
||||
@@ -437,7 +435,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
except EnvironmentError:
|
||||
if pretrained_model_name_or_path in cls.pretrained_model_archive_map:
|
||||
|
||||
@@ -512,7 +512,7 @@ class XLMModel(XLMPreTrainedModel):
|
||||
inputs_embeds = self.embeddings(input_ids)
|
||||
|
||||
tensor = inputs_embeds + self.position_embeddings(position_ids).expand_as(inputs_embeds)
|
||||
if langs is not None and self.use_lang_emb and self.n_langs > 1:
|
||||
if langs is not None and self.use_lang_emb:
|
||||
tensor = tensor + self.lang_embeddings(langs)
|
||||
if token_type_ids is not None:
|
||||
tensor = tensor + self.embeddings(token_type_ids)
|
||||
|
||||
@@ -702,9 +702,8 @@ class XLNetModel(XLNetPreTrainedModel):
|
||||
r"""
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLNetConfig`) and inputs:
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_predict, hidden_size)`):
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the last layer of the model.
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
mems (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks).
|
||||
Can be used (see `mems` input) to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -729,7 +728,7 @@ class XLNetModel(XLNetPreTrainedModel):
|
||||
tokenizer = XLNetTokenizer.from_pretrained('xlnet-large-cased')
|
||||
model = XLNetModel.from_pretrained('xlnet-large-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=False)).unsqueeze(0) # Batch size 1
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
@@ -978,21 +977,19 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
labels=None,
|
||||
):
|
||||
r"""
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, num_predict)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for masked language modeling.
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
The labels should correspond to the masked input words that should be predicted and depends on `target_mapping`. Note in order to perform standard auto-regressive language modeling a `<mask>` token has to be added to the `input_ids` (see `prepare_inputs_for_generation` fn and examples below)
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for language modeling.
|
||||
Note that the labels **are shifted** inside the model, i.e. you can set ``lm_labels = input_ids``
|
||||
Indices are selected in ``[-100, 0, ..., config.vocab_size]``
|
||||
All labels set to ``-100`` are ignored, the loss is only
|
||||
All labels set to ``-100`` are ignored (masked), the loss is only
|
||||
computed for labels in ``[0, ..., config.vocab_size]``
|
||||
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLNetConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when ``labels`` is provided)
|
||||
Language modeling loss.
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_predict, config.vocab_size)`):
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`):
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
mems (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks).
|
||||
Can be used (see `past` input) to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -1018,7 +1015,7 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
model = XLNetLMHeadModel.from_pretrained('xlnet-large-cased')
|
||||
|
||||
# We show how to setup inputs to predict a next token using a bi-directional context.
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=False)).unsqueeze(0) # We will predict the masked token
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=True)).unsqueeze(0) # We will predict the masked token
|
||||
perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
|
||||
perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token
|
||||
target_mapping = torch.zeros((1, 1, input_ids.shape[1]), dtype=torch.float) # Shape [1, 1, seq_length] => let's predict one token
|
||||
@@ -1027,18 +1024,6 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping)
|
||||
next_token_logits = outputs[0] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
|
||||
|
||||
# The same way can the XLNetLMHeadModel be used to be trained by standard auto-regressive language modeling.
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=False)).unsqueeze(0) # We will predict the masked token
|
||||
labels = torch.tensor(tokenizer.encode("cute", add_special_tokens=False)).unsqueeze(0)
|
||||
assert labels.shape[0] == 1, 'only one word will be predicted'
|
||||
perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
|
||||
perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token as is done in standard auto-regressive lm training
|
||||
target_mapping = torch.zeros((1, 1, input_ids.shape[1]), dtype=torch.float) # Shape [1, 1, seq_length] => let's predict one token
|
||||
target_mapping[0, 0, -1] = 1.0 # Our first (and only) prediction will be the last token of the sequence (the masked token)
|
||||
|
||||
outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping, labels=labels)
|
||||
loss, next_token_logits = outputs[:2] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
|
||||
|
||||
"""
|
||||
transformer_outputs = self.transformer(
|
||||
input_ids,
|
||||
@@ -1264,10 +1249,8 @@ class XLNetForTokenClassification(XLNetPreTrainedModel):
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -19,7 +19,6 @@ import logging
|
||||
import os
|
||||
import unicodedata
|
||||
from shutil import copyfile
|
||||
from typing import List, Optional
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
@@ -56,55 +55,9 @@ SPIECE_UNDERLINE = "▁"
|
||||
|
||||
class AlbertTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Constructs an ALBERT tokenizer. Based on `SentencePiece <https://github.com/google/sentencepiece>`__
|
||||
SentencePiece based tokenizer. Peculiarities:
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
`SentencePiece <https://github.com/google/sentencepiece>`__ file (generally has a .spm extension) that
|
||||
contains the vocabulary necessary to instantiate a tokenizer.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
remove_space (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to strip the text when tokenizing (removing excess spaces before and after the string).
|
||||
keep_accents (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Whether to keep accents when tokenizing.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "[CLS]"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "[SEP]"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "[SEP]"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "[CLS]"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "[MASK]"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
|
||||
Attributes:
|
||||
sp_model (:obj:`SentencePieceProcessor`):
|
||||
The `SentencePiece` processor that is used for every conversion (string, tokens and IDs).
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -232,28 +185,17 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return self.sp_model.IdToPiece(index)
|
||||
|
||||
def convert_tokens_to_string(self, tokens):
|
||||
"""Converts a sequence of tokens (strings for sub-words) in a single string."""
|
||||
out_string = "".join(tokens).replace(SPIECE_UNDERLINE, " ").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
An ALBERT sequence has the following format:
|
||||
|
||||
- single sequence: ``[CLS] X [SEP]``
|
||||
- pair of sequences: ``[CLS] A [SEP] B [SEP]``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: [CLS] X [SEP]
|
||||
pair of sequences: [CLS] A [SEP] B [SEP]
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -261,30 +203,27 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return cls + token_ids_0 + sep
|
||||
return cls + token_ids_0 + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
raise ValueError(
|
||||
"You should not supply a second sequence if the provided sequence of "
|
||||
"ids is already formatted with special tokens for the model."
|
||||
"ids is already formated with special tokens for the model."
|
||||
)
|
||||
return list(map(lambda x: 1 if x in [self.sep_token_id, self.cls_token_id] else 0, token_ids_0))
|
||||
|
||||
@@ -292,29 +231,14 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
An ALBERT sequence pair mask has the following format:
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence |
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0s).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -324,15 +248,8 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1]
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
""" Save the sentencepiece vocabulary (copy original file) and special tokens file
|
||||
to a directory.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
|
||||
@@ -157,7 +157,7 @@ class AutoTokenizer:
|
||||
A dictionary of proxy servers to use by protocol or endpoint, e.g.: {'http': 'foo.bar:3128', 'http://hostname': 'foo.bar:4012'}.
|
||||
The proxies are used on each request.
|
||||
|
||||
use_fast: (`optional`) boolean, default False:
|
||||
use_fast: (`optional`) boolean, default True:
|
||||
Indicate if transformers should try to load the fast version of the tokenizer (True) or use the Python one (False).
|
||||
|
||||
inputs: (`optional`) positional arguments: will be passed to the Tokenizer ``__init__`` method.
|
||||
@@ -183,7 +183,7 @@ class AutoTokenizer:
|
||||
if "bert-base-japanese" in pretrained_model_name_or_path:
|
||||
return BertJapaneseTokenizer.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
|
||||
use_fast = kwargs.pop("use_fast", False)
|
||||
use_fast = kwargs.pop("use_fast", True)
|
||||
for config_class, (tokenizer_class_py, tokenizer_class_fast) in TOKENIZER_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
if tokenizer_class_fast and use_fast:
|
||||
|
||||
@@ -19,7 +19,6 @@ import collections
|
||||
import logging
|
||||
import os
|
||||
import unicodedata
|
||||
from typing import List, Optional
|
||||
|
||||
from tokenizers import BertWordPieceTokenizer
|
||||
|
||||
@@ -118,41 +117,17 @@ def whitespace_tokenize(text):
|
||||
|
||||
class BertTokenizer(PreTrainedTokenizer):
|
||||
r"""
|
||||
Constructs a BERT tokenizer. Based on WordPiece.
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
Constructs a BertTokenizer.
|
||||
:class:`~transformers.BertTokenizer` runs end-to-end tokenization: punctuation splitting + wordpiece
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
File containing the vocabulary.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
do_basic_tokenize (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to do basic tokenization before WordPiece.
|
||||
never_split (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
List of tokens which will never be split during tokenization. Only has an effect when
|
||||
:obj:`do_basic_tokenize=True`
|
||||
unk_token (:obj:`string`, `optional`, defaults to "[UNK]"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "[SEP]"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "[PAD]"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "[CLS]"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "[MASK]"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
tokenize_chinese_chars (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to tokenize Chinese characters.
|
||||
This should likely be deactivated for Japanese:
|
||||
see: https://github.com/huggingface/transformers/issues/328
|
||||
vocab_file: Path to a one-wordpiece-per-line vocabulary file
|
||||
do_lower_case: Whether to lower case the input. Only has an effect when do_basic_tokenize=True
|
||||
do_basic_tokenize: Whether to do basic tokenization before wordpiece.
|
||||
max_len: An artificial maximum length to truncate tokenized sequences to; Effective maximum length is always the
|
||||
minimum of this value (if specified) and the underlying BERT model's sequence length.
|
||||
never_split: List of tokens which will never be split during tokenization. Only has an effect when
|
||||
do_basic_tokenize=True
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -174,6 +149,23 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
tokenize_chinese_chars=True,
|
||||
**kwargs
|
||||
):
|
||||
"""Constructs a BertTokenizer.
|
||||
|
||||
Args:
|
||||
**vocab_file**: Path to a one-wordpiece-per-line vocabulary file
|
||||
**do_lower_case**: (`optional`) boolean (default True)
|
||||
Whether to lower case the input
|
||||
Only has an effect when do_basic_tokenize=True
|
||||
**do_basic_tokenize**: (`optional`) boolean (default True)
|
||||
Whether to do basic tokenization before wordpiece.
|
||||
**never_split**: (`optional`) list of string
|
||||
List of tokens which will never be split during tokenization.
|
||||
Only has an effect when do_basic_tokenize=True
|
||||
**tokenize_chinese_chars**: (`optional`) boolean (default True)
|
||||
Whether to tokenize Chinese characters.
|
||||
This should likely be deactivated for Japanese:
|
||||
see: https://github.com/huggingface/pytorch-pretrained-BERT/issues/328
|
||||
"""
|
||||
super().__init__(
|
||||
unk_token=unk_token,
|
||||
sep_token=sep_token,
|
||||
@@ -229,25 +221,13 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
out_string = " ".join(tokens).replace(" ##", "").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A BERT sequence has the following format:
|
||||
|
||||
- single sequence: ``[CLS] X [SEP]``
|
||||
- pair of sequences: ``[CLS] A [SEP] B [SEP]``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: [CLS] X [SEP]
|
||||
pair of sequences: [CLS] A [SEP] B [SEP]
|
||||
"""
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
@@ -255,23 +235,20 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
@@ -286,29 +263,14 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
A BERT sequence pair mask has the following format:
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence |
|
||||
0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -317,16 +279,7 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1]
|
||||
|
||||
def save_vocabulary(self, vocab_path):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
vocab_path (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary to a directory or file."""
|
||||
index = 0
|
||||
if os.path.isdir(vocab_path):
|
||||
vocab_file = os.path.join(vocab_path, VOCAB_FILES_NAMES["vocab_file"])
|
||||
|
||||
@@ -18,7 +18,6 @@
|
||||
import logging
|
||||
import os
|
||||
from shutil import copyfile
|
||||
from typing import List, Optional
|
||||
|
||||
import sentencepiece as spm
|
||||
|
||||
@@ -54,50 +53,7 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
Adapted from RobertaTokenizer and XLNetTokenizer
|
||||
SentencePiece based tokenizer. Peculiarities:
|
||||
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<mask>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`["<s>NOTUSED", "</s>NOTUSED"]`):
|
||||
Additional special tokens used by the tokenizer.
|
||||
|
||||
Attributes:
|
||||
sp_model (:obj:`SentencePieceProcessor`):
|
||||
The `SentencePiece` processor that is used for every conversion (string, tokens and IDs).
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -141,50 +97,34 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
self.fairseq_tokens_to_ids["<mask>"] = len(self.sp_model) + len(self.fairseq_tokens_to_ids)
|
||||
self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()}
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A CamemBERT sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s></s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
A RoBERTa sequence has the following format:
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s></s> B </s>
|
||||
"""
|
||||
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
@@ -198,29 +138,14 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
A CamemBERT sequence pair mask has the following format:
|
||||
A RoBERTa sequence pair mask has the following format:
|
||||
0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | | second sequence |
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0s).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -275,15 +200,8 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
""" Save the sentencepiece vocabulary (copy original file) and special tokens file
|
||||
to a directory.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
|
||||
@@ -116,21 +116,8 @@ def get_pairs(word):
|
||||
|
||||
class CTRLTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Constructs a CTRL tokenizer. Peculiarities:
|
||||
|
||||
- Byte-Pair-Encoding
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
CTRL BPE tokenizer. Peculiarities:
|
||||
- Byte-Pair-Encoding
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -232,16 +219,7 @@ class CTRLTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
|
||||
@@ -58,11 +58,16 @@ PRETRAINED_INIT_CONFIGURATION = {
|
||||
class DistilBertTokenizer(BertTokenizer):
|
||||
r"""
|
||||
Constructs a DistilBertTokenizer.
|
||||
:class:`~transformers.DistilBertTokenizer` is identical to :class:`~transformers.BertTokenizer` and runs end-to-end
|
||||
tokenization: punctuation splitting + wordpiece.
|
||||
:class:`~transformers.DistilBertTokenizer` is identical to BertTokenizer and runs end-to-end tokenization: punctuation splitting + wordpiece
|
||||
|
||||
Refer to superclass :class:`~transformers.BertTokenizer` for usage examples and documentation concerning
|
||||
parameters.
|
||||
Args:
|
||||
vocab_file: Path to a one-wordpiece-per-line vocabulary file
|
||||
do_lower_case: Whether to lower case the input. Only has an effect when do_basic_tokenize=True
|
||||
do_basic_tokenize: Whether to do basic tokenization before wordpiece.
|
||||
max_len: An artificial maximum length to truncate tokenized sequences to; Effective maximum length is always the
|
||||
minimum of this value (if specified) and the underlying BERT model's sequence length.
|
||||
never_split: List of tokens which will never be split during tokenization. Only has an effect when
|
||||
do_basic_tokenize=True
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
|
||||
@@ -80,14 +80,14 @@ class FlaubertTokenizer(XLMTokenizer):
|
||||
"""
|
||||
BPE tokenizer for Flaubert
|
||||
|
||||
- Moses preprocessing & tokenization
|
||||
- Normalize all inputs text
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
- `do_lowercase` controle lower casing (automatically set for pretrained vocabularies)
|
||||
- Moses preprocessing & tokenization
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.XLMTokenizer`. Please check the superclass for usage examples
|
||||
and documentation regarding arguments.
|
||||
- Normalize all inputs text
|
||||
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
|
||||
- `do_lowercase` controle lower casing (automatically set for pretrained vocabularies)
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
|
||||
@@ -101,35 +101,11 @@ def get_pairs(word):
|
||||
class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
GPT-2 BPE tokenizer. Peculiarities:
|
||||
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer ``encode`` and ``decode`` method will not conserve
|
||||
the absence of a space at the beginning of a string:
|
||||
|
||||
::
|
||||
|
||||
tokenizer.decode(tokenizer.encode("Hello")) = " Hello"
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
errors (:obj:`str`, `optional`, defaults to "replace"):
|
||||
Paradigm to follow when decoding bytes to UTF-8. See `bytes.decode
|
||||
<https://docs.python.org/3/library/stdtypes.html#bytes.decode>`__ for more information.
|
||||
unk_token (:obj:`string`, `optional`, defaults to `<|endoftext|>`):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
bos_token (:obj:`string`, `optional`, defaults to `<|endoftext|>`):
|
||||
The beginning of sequence token.
|
||||
eos_token (:obj:`string`, `optional`, defaults to `<|endoftext|>`):
|
||||
The end of sequence token.
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding and tokenize methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer's ``encode``, ``decode``, and ``tokenize`` methods will not conserve
|
||||
the spaces at the beginning of a string: `tokenizer.decode(tokenizer.encode(" Hello")) = "Hello"`
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -243,16 +219,7 @@ class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
return text
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
|
||||
@@ -82,21 +82,8 @@ def text_standardize(text):
|
||||
class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
BPE tokenizer. Peculiarities:
|
||||
|
||||
- lower case all inputs
|
||||
- uses SpaCy tokenizer and ftfy for pre-BPE tokenization if they are installed, fallback to BERT's BasicTokenizer if not.
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
- lower case all inputs
|
||||
- uses SpaCy tokenizer and ftfy for pre-BPE tokenization if they are installed, fallback to BERT's BasicTokenizer if not.
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -214,16 +201,7 @@ class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
|
||||
@@ -16,7 +16,6 @@
|
||||
|
||||
|
||||
import logging
|
||||
from typing import List, Optional
|
||||
|
||||
from tokenizers.processors import RobertaProcessing
|
||||
|
||||
@@ -61,59 +60,12 @@ PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
|
||||
class RobertaTokenizer(GPT2Tokenizer):
|
||||
"""
|
||||
Constructs a RoBERTa BPE tokenizer, derived from the GPT-2 tokenizer. Peculiarities:
|
||||
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer ``encode`` and ``decode`` method will not conserve
|
||||
the absence of a space at the beginning of a string:
|
||||
|
||||
::
|
||||
|
||||
tokenizer.decode(tokenizer.encode("Hello")) = " Hello"
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
errors (:obj:`str`, `optional`, defaults to "replace"):
|
||||
Paradigm to follow when decoding bytes to UTF-8. See `bytes.decode
|
||||
<https://docs.python.org/3/library/stdtypes.html#bytes.decode>`__ for more information.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<mask>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
RoBERTa BPE tokenizer, derived from the GPT-2 tokenizer. Peculiarities:
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer ``encode`` and ``decode`` method will not conserve
|
||||
the absence of a space at the beginning of a string: `tokenizer.decode(tokenizer.encode("Hello")) = " Hello"`
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -150,25 +102,13 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
self.max_len_single_sentence = self.max_len - 2 # take into account special tokens
|
||||
self.max_len_sentences_pair = self.max_len - 4 # take into account special tokens
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A RoBERTa sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s></s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s></s> B </s>
|
||||
"""
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
@@ -176,23 +116,20 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
@@ -206,22 +143,12 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
RoBERTa does not make use of token type ids, therefore a list of zeros is returned.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of zeros.
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
|
||||
@@ -98,12 +98,6 @@ class T5Tokenizer(PreTrainedTokenizer):
|
||||
additional_special_tokens=additional_special_tokens,
|
||||
**kwargs,
|
||||
)
|
||||
self.max_len_single_sentence = (
|
||||
self.max_len
|
||||
) # no default special tokens - you can update this value if you add special tokens
|
||||
self.max_len_sentences_pair = (
|
||||
self.max_len
|
||||
) # no default special tokens - you can update this value if you add special tokens
|
||||
|
||||
try:
|
||||
import sentencepiece as spm
|
||||
|
||||
@@ -22,7 +22,6 @@ import glob
|
||||
import logging
|
||||
import os
|
||||
import pickle
|
||||
import re
|
||||
from collections import Counter, OrderedDict
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
@@ -45,7 +44,6 @@ if is_torch_available():
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
VOCAB_FILES_NAMES = {"pretrained_vocab_file": "vocab.bin", "vocab_file": "vocab.txt"}
|
||||
VOCAB_FILES_NAMES_FAST = {"pretrained_vocab_file": "vocab.json", "vocab_file": "vocab.json"}
|
||||
|
||||
PRETRAINED_VOCAB_FILES_MAP = {
|
||||
"pretrained_vocab_file": {
|
||||
@@ -72,9 +70,6 @@ CORPUS_NAME = "corpus.bin"
|
||||
class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Transformer-XL tokenizer adapted from Vocab class in https://github.com/kimiyoung/transformer-xl
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -119,36 +114,18 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
self.delimiter = delimiter
|
||||
self.vocab_file = vocab_file
|
||||
self.never_split = never_split
|
||||
self.punctuation_symbols = '!"#$%&()*+,-./\:;<=>?@[\\]^_`{|}~' # noqa: W605
|
||||
self.punction_without_space_before_pattern = re.compile(r"[^\s][{}]".format(self.punctuation_symbols))
|
||||
self.punctuation_with_space_around_pattern = self._compile_space_around_punctuation_pattern()
|
||||
|
||||
try:
|
||||
if pretrained_vocab_file is not None:
|
||||
# Hack because, honestly this tokenizer was not made to be used
|
||||
# in a library like ours, at all.
|
||||
vocab_dict = torch.load(pretrained_vocab_file)
|
||||
for key, value in vocab_dict.items():
|
||||
if key not in self.__dict__:
|
||||
self.__dict__[key] = value
|
||||
|
||||
if vocab_file is not None:
|
||||
self.build_vocab()
|
||||
except Exception:
|
||||
raise ValueError(
|
||||
"Unable to parse file {}. Unknown format. "
|
||||
"If you tried to load a model saved through TransfoXLTokenizerFast,"
|
||||
"please note they are not compatible.".format(pretrained_vocab_file)
|
||||
)
|
||||
if pretrained_vocab_file is not None:
|
||||
# Hack because, honestly this tokenizer was not made to be used
|
||||
# in a library like ours, at all.
|
||||
vocab_dict = torch.load(pretrained_vocab_file)
|
||||
for key, value in vocab_dict.items():
|
||||
if key not in self.__dict__:
|
||||
self.__dict__[key] = value
|
||||
|
||||
if vocab_file is not None:
|
||||
self.build_vocab()
|
||||
|
||||
def _compile_space_around_punctuation_pattern(self):
|
||||
look_ahead_for_special_token = "(?=[{}])".format(self.punctuation_symbols)
|
||||
look_ahead_to_match_all_except_space = "(?=[^\s])" # noqa: W605
|
||||
return re.compile(r"" + look_ahead_for_special_token + look_ahead_to_match_all_except_space)
|
||||
|
||||
def count_file(self, path, verbose=False, add_eos=False):
|
||||
if verbose:
|
||||
logger.info("counting file {} ...".format(path))
|
||||
@@ -192,22 +169,7 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
raise ValueError("No <unkown> token in vocabulary")
|
||||
|
||||
def save_vocabulary(self, vocab_path):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
vocab_path (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
|
||||
logger.warning(
|
||||
"Please note you will not be able to load the save vocabulary in"
|
||||
" Rust-based TransfoXLTokenizerFast as they don't share the same structure."
|
||||
)
|
||||
|
||||
"""Save the tokenizer vocabulary to a directory or file."""
|
||||
if os.path.isdir(vocab_path):
|
||||
vocab_file = os.path.join(vocab_path, VOCAB_FILES_NAMES["pretrained_vocab_file"])
|
||||
else:
|
||||
@@ -333,19 +295,6 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
else:
|
||||
return symbols
|
||||
|
||||
def prepare_for_tokenization(self, text, **kwargs):
|
||||
# add spaces before punctuation symbols as should be done in transfo-xl
|
||||
|
||||
if "add_space_before_punct_symbol" in kwargs and kwargs["add_space_before_punct_symbol"]:
|
||||
text = self.punctuation_with_space_around_pattern.sub(r" ", text)
|
||||
elif self.punction_without_space_before_pattern.search(text):
|
||||
# searches until the first occurence of a punctuation symbol without surrounding spaces
|
||||
logger.warning(
|
||||
"You might want to consider setting `add_space_before_punct_symbol=True` as an argument to the `tokenizer.encode()` to avoid tokenizing words with punctuation symbols to the `<unk>` token"
|
||||
)
|
||||
|
||||
return text
|
||||
|
||||
|
||||
class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
def __init__(
|
||||
@@ -360,15 +309,8 @@ class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
normalization: Optional[str] = None,
|
||||
):
|
||||
|
||||
try:
|
||||
tokenizer = WordLevel.from_files(vocab_file, unk_token=unk_token)
|
||||
tokenizer = Tokenizer(tokenizer)
|
||||
except Exception:
|
||||
raise ValueError(
|
||||
"Unable to parse file {}. Unknown format. "
|
||||
"If you tried to load a model saved through TransfoXLTokenizer,"
|
||||
"please note they are not compatible.".format(vocab_file)
|
||||
)
|
||||
tokenizer = WordLevel.from_files(vocab_file, unk_token=unk_token)
|
||||
tokenizer = Tokenizer(tokenizer)
|
||||
|
||||
# Create the correct normalization path
|
||||
normalizer = []
|
||||
@@ -415,7 +357,7 @@ class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
|
||||
class TransfoXLTokenizerFast(PreTrainedTokenizerFast):
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES_FAST
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP_FAST
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
@@ -455,14 +397,6 @@ class TransfoXLTokenizerFast(PreTrainedTokenizerFast):
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
def save_pretrained(self, save_directory):
|
||||
logger.warning(
|
||||
"Please note you will not be able to load the vocabulary in"
|
||||
" Python-based TransfoXLTokenizer as they don't share the same structure."
|
||||
)
|
||||
|
||||
return super().save_pretrained(save_directory)
|
||||
|
||||
|
||||
class LMOrderedIterator(object):
|
||||
def __init__(self, data, bsz, bptt, device="cpu", ext_len=None):
|
||||
|
||||
@@ -14,6 +14,7 @@
|
||||
# limitations under the License.
|
||||
"""Tokenization classes for OpenAI GPT."""
|
||||
|
||||
|
||||
import copy
|
||||
import itertools
|
||||
import json
|
||||
@@ -152,18 +153,6 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
padding_side = "right"
|
||||
|
||||
NO_PAD_TOKEN_FOR_BATCH_MSG = (
|
||||
"No padding token is set for this model, therefore no batch can be made with uneven "
|
||||
"sequences. Set a padding token or adjust the lengths of the sequences building the "
|
||||
"batch so that every sequence is of the same length."
|
||||
)
|
||||
|
||||
UNEVEN_SEQUENCES_FOR_BATCH_MSG = (
|
||||
"The sequences building the batch are not of the same size, no tensor "
|
||||
"can be built. Set `pad_to_max_length=True` to pad the smaller sequences"
|
||||
"up to the larger sequence's length."
|
||||
)
|
||||
|
||||
@property
|
||||
def bos_token(self):
|
||||
""" Beginning of sentence token (string). Log an error if used while not having been set. """
|
||||
@@ -395,7 +384,6 @@ class PreTrainedTokenizer(object):
|
||||
force_download = kwargs.pop("force_download", False)
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
s3_models = list(cls.max_model_input_sizes.keys())
|
||||
vocab_files = {}
|
||||
@@ -463,7 +451,6 @@ class PreTrainedTokenizer(object):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
except EnvironmentError:
|
||||
if pretrained_model_name_or_path in s3_models:
|
||||
@@ -1033,18 +1020,14 @@ class PreTrainedTokenizer(object):
|
||||
def batch_encode_plus(
|
||||
self,
|
||||
batch_text_or_text_pairs=None,
|
||||
add_special_tokens=True,
|
||||
add_special_tokens=False,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
pad_to_max_length=False,
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_masks=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_masks=False,
|
||||
return_offsets_mapping=False,
|
||||
return_input_lengths=False,
|
||||
return_attention_masks=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
"""
|
||||
@@ -1067,54 +1050,14 @@ class PreTrainedTokenizer(object):
|
||||
- 'only_first': Only truncate the first sequence
|
||||
- 'only_second': Only truncate the second sequence
|
||||
- 'do_not_truncate': Does not truncate (raise an error if the input sequence is longer than max_length)
|
||||
pad_to_max_length: if set to True, the returned sequences will be padded according to the model's padding side and
|
||||
padding index, up to their max length. If no max length is specified, the padding is done up to the model's max length.
|
||||
The tokenizer padding sides are handled by the class attribute `padding_side` which can be set to the following strings:
|
||||
- 'left': pads on the left of the sequences
|
||||
- 'right': pads on the right of the sequences
|
||||
Defaults to False: no padding.
|
||||
return_tensors: (optional) can be set to 'tf' or 'pt' to return respectively TensorFlow tf.constant
|
||||
or PyTorch torch.Tensor instead of a list of python integers.
|
||||
return_input_lengths: (optional) If set the resulting dictionary will include the length of each sample
|
||||
return_attention_masks: (optional) Set to True to return the attention mask (default False)
|
||||
return_offsets_mapping: (optional) Not available, should be set to False or it will throw NotImplementError
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
|
||||
Return:
|
||||
A Dictionary of shape::
|
||||
|
||||
{
|
||||
input_ids: list[List[int]],
|
||||
token_type_ids: list[List[int]] if return_token_type_ids is True (default)
|
||||
attention_mask: list[List[int]] if return_attention_mask is True (default)
|
||||
overflowing_tokens: list[List[int]] if a ``max_length`` is specified and return_overflowing_tokens is True
|
||||
num_truncated_tokens: List[int] if a ``max_length`` is specified and return_overflowing_tokens is True
|
||||
special_tokens_mask: list[List[int]] if ``add_special_tokens`` if set to ``True`` and return_special_tokens_mask is True
|
||||
}
|
||||
|
||||
With the fields:
|
||||
``input_ids``: list of token ids to be fed to a model
|
||||
``token_type_ids``: list of token type ids to be fed to a model
|
||||
``attention_mask``: list of indices specifying which tokens should be attended to by the model
|
||||
``overflowing_tokens``: list of overflowing tokens if a max length is specified.
|
||||
``num_truncated_tokens``: number of overflowing tokens a ``max_length`` is specified
|
||||
``special_tokens_mask``: if adding special tokens, this is a list of [0, 1], with 0 specifying special added
|
||||
tokens and 1 specifying sequence tokens.
|
||||
"""
|
||||
|
||||
def get_input_ids(text):
|
||||
if isinstance(text, str):
|
||||
tokens = self.tokenize(text, add_special_tokens=add_special_tokens, **kwargs)
|
||||
return self.convert_tokens_to_ids(tokens)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], str):
|
||||
return self.convert_tokens_to_ids(text)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], int):
|
||||
return text
|
||||
else:
|
||||
raise ValueError(
|
||||
"Input is not valid. Should be a string, a list/tuple of strings or a list/tuple of integers."
|
||||
)
|
||||
|
||||
if return_offsets_mapping:
|
||||
raise NotImplementedError(
|
||||
"return_offset_mapping is not available when using Python tokenizers."
|
||||
@@ -1124,47 +1067,21 @@ class PreTrainedTokenizer(object):
|
||||
"https://github.com/huggingface/transformers/pull/2674"
|
||||
)
|
||||
|
||||
input_ids = []
|
||||
batch_outputs = {}
|
||||
for ids_or_pair_ids in batch_text_or_text_pairs:
|
||||
if isinstance(ids_or_pair_ids, (list, tuple)):
|
||||
assert len(ids_or_pair_ids) == 2
|
||||
ids, pair_ids = ids_or_pair_ids
|
||||
else:
|
||||
ids, pair_ids = ids_or_pair_ids, None
|
||||
|
||||
first_ids = get_input_ids(ids)
|
||||
second_ids = get_input_ids(pair_ids) if pair_ids is not None else None
|
||||
input_ids.append((first_ids, second_ids))
|
||||
|
||||
if max_length is None and pad_to_max_length:
|
||||
|
||||
def total_sequence_length(input_pairs):
|
||||
first_ids, second_ids = input_pairs
|
||||
return len(first_ids) + (
|
||||
self.num_added_tokens()
|
||||
if second_ids is None
|
||||
else (len(second_ids) + self.num_added_tokens(pair=True))
|
||||
)
|
||||
|
||||
max_length = max([total_sequence_length(ids) for ids in input_ids])
|
||||
|
||||
batch_outputs = {}
|
||||
for first_ids, second_ids in input_ids:
|
||||
# Prepares a sequence of input id, or a pair of sequences of inputs ids so that it can be used by
|
||||
# the model. It adds special tokens, truncates sequences if overflowing while taking into account
|
||||
# the special tokens and manages a window stride for overflowing tokens
|
||||
outputs = self.prepare_for_model(
|
||||
first_ids,
|
||||
pair_ids=second_ids,
|
||||
max_length=max_length,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
outputs = self.encode_plus(
|
||||
ids,
|
||||
pair_ids,
|
||||
add_special_tokens=add_special_tokens,
|
||||
max_length=max_length,
|
||||
stride=stride,
|
||||
truncation_strategy=truncation_strategy,
|
||||
return_attention_mask=return_attention_masks,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_masks,
|
||||
return_tensors=None,
|
||||
)
|
||||
|
||||
# Append the non-padded length to the output
|
||||
@@ -1176,28 +1093,31 @@ class PreTrainedTokenizer(object):
|
||||
batch_outputs[key] = []
|
||||
batch_outputs[key].append(value)
|
||||
|
||||
# Compute longest sequence size
|
||||
max_seq_len = max(map(len, batch_outputs["input_ids"]))
|
||||
|
||||
if return_attention_masks:
|
||||
# Allow the model to not give any special attention to padded input
|
||||
batch_outputs["attention_mask"] = [[0] * len(v) for v in batch_outputs["input_ids"]]
|
||||
|
||||
if return_tensors is not None:
|
||||
|
||||
# Do the tensor conversion in batch
|
||||
for key, value in batch_outputs.items():
|
||||
|
||||
padded_value = value
|
||||
# verify that the tokenizer has a pad_token_id
|
||||
if key != "input_len" and self._pad_token is not None:
|
||||
# Padding handle
|
||||
padded_value = [
|
||||
v + [self.pad_token_id if key == "input_ids" else 1] * (max_seq_len - len(v))
|
||||
for v in padded_value
|
||||
]
|
||||
|
||||
if return_tensors == "tf" and is_tf_available():
|
||||
try:
|
||||
batch_outputs[key] = tf.constant(value)
|
||||
except ValueError:
|
||||
if None in [item for sequence in value for item in sequence]:
|
||||
raise ValueError(self.NO_PAD_TOKEN_FOR_BATCH_MSG)
|
||||
else:
|
||||
raise ValueError(self.UNEVEN_SEQUENCES_FOR_BATCH_MSG)
|
||||
batch_outputs[key] = tf.constant(padded_value)
|
||||
elif return_tensors == "pt" and is_torch_available():
|
||||
try:
|
||||
batch_outputs[key] = torch.tensor(value)
|
||||
except ValueError:
|
||||
raise ValueError(self.UNEVEN_SEQUENCES_FOR_BATCH_MSG)
|
||||
except RuntimeError:
|
||||
if None in [item for sequence in value for item in sequence]:
|
||||
raise ValueError(self.NO_PAD_TOKEN_FOR_BATCH_MSG)
|
||||
else:
|
||||
raise
|
||||
batch_outputs[key] = torch.tensor(padded_value)
|
||||
elif return_tensors is not None:
|
||||
logger.warning(
|
||||
"Unable to convert output to tensors format {}, PyTorch or TensorFlow is not available.".format(
|
||||
@@ -1205,6 +1125,13 @@ class PreTrainedTokenizer(object):
|
||||
)
|
||||
)
|
||||
|
||||
# encoder_attention_mask requires 1 for real token, 0 for padding, just invert value
|
||||
if return_attention_masks:
|
||||
if is_tf_available():
|
||||
batch_outputs["attention_mask"] = tf.abs(batch_outputs["attention_mask"] - 1)
|
||||
else:
|
||||
batch_outputs["attention_mask"] = torch.abs(batch_outputs["attention_mask"] - 1)
|
||||
|
||||
return batch_outputs
|
||||
|
||||
def prepare_for_model(
|
||||
@@ -1906,9 +1833,8 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
if os.path.isdir(save_directory):
|
||||
files = self._tokenizer.save(save_directory)
|
||||
folder, file = save_directory, self.vocab_files_names["vocab_file"]
|
||||
else:
|
||||
folder, file = os.path.split(os.path.abspath(save_directory))
|
||||
files = self._tokenizer.save(folder, name=file)
|
||||
|
||||
return tuple(files)
|
||||
return tuple(self._tokenizer.save(folder, file))
|
||||
@@ -21,7 +21,6 @@ import os
|
||||
import re
|
||||
import sys
|
||||
import unicodedata
|
||||
from typing import List, Optional
|
||||
|
||||
import sacremoses as sm
|
||||
|
||||
@@ -531,59 +530,20 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
BPE tokenizer for XLM
|
||||
|
||||
- Moses preprocessing & tokenization for most supported languages
|
||||
- Language specific tokenization for Chinese (Jieba), Japanese (KyTea) and Thai (PyThaiNLP)
|
||||
- (optionally) lower case & normalize all inputs text
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
- `lang2id` attribute maps the languages supported by the model with their ids if provided (automatically set for pretrained vocabularies)
|
||||
- `id2lang` attributes does reverse mapping if provided (automatically set for pretrained vocabularies)
|
||||
- Moses preprocessing & tokenization for most supported languages
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
- Language specific tokenization for Chinese (Jieba), Japanese (KyTea) and Thai (PyThaiNLP)
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
Vocabulary file.
|
||||
merges_file (:obj:`string`):
|
||||
Merges file.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
remove_space (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to strip the text when tokenizing (removing excess spaces before and after the string).
|
||||
keep_accents (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Whether to keep accents when tokenizing.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
- (optionally) lower case & normalize all inputs text
|
||||
|
||||
.. note::
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<special1>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`["<special0>","<special1>","<special2>","<special3>","<special4>","<special5>","<special6>","<special7>","<special8>","<special9>"]`):
|
||||
List of additional special tokens.
|
||||
lang2id (:obj:`Dict[str, int]`, `optional`, defaults to :obj:`None`):
|
||||
Dictionary mapping languages string identifiers to their IDs.
|
||||
id2lang (:obj:`Dict[int, str`, `optional`, defaults to :obj:`None`):
|
||||
Dictionary mapping language IDs to their string identifiers.
|
||||
do_lowercase_and_remove_accent (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase and remove accents when tokenizing.
|
||||
- `lang2id` attribute maps the languages supported by the model with their ids if provided (automatically set for pretrained vocabularies)
|
||||
|
||||
- `id2lang` attributes does reverse mapping if provided (automatically set for pretrained vocabularies)
|
||||
|
||||
- `do_lowercase_and_remove_accent` controle lower casing and accent (automatically set for pretrained vocabularies)
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -852,26 +812,13 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
out_string = "".join(tokens).replace("</w>", " ").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A XLM sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s> B </s>
|
||||
"""
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
@@ -879,23 +826,20 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
cls = [self.cls_token_id]
|
||||
return cls + token_ids_0 + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
@@ -910,29 +854,14 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
An XLM sequence pair mask has the following format:
|
||||
0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence |
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0s).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -941,16 +870,7 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1]
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
|
||||
@@ -18,7 +18,6 @@
|
||||
import logging
|
||||
import os
|
||||
from shutil import copyfile
|
||||
from typing import List, Optional
|
||||
|
||||
from transformers.tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
@@ -55,50 +54,7 @@ class XLMRobertaTokenizer(PreTrainedTokenizer):
|
||||
Adapted from RobertaTokenizer and XLNetTokenizer
|
||||
SentencePiece based tokenizer. Peculiarities:
|
||||
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<mask>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`["<s>NOTUSED", "</s>NOTUSED"]`):
|
||||
Additional special tokens used by the tokenizer.
|
||||
|
||||
Attributes:
|
||||
sp_model (:obj:`SentencePieceProcessor`):
|
||||
The `SentencePiece` processor that is used for every conversion (string, tokens and IDs).
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -176,52 +132,35 @@ class XLMRobertaTokenizer(PreTrainedTokenizer):
|
||||
self.sp_model = spm.SentencePieceProcessor()
|
||||
self.sp_model.Load(self.vocab_file)
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A XLM-R sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s></s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
A RoBERTa sequence has the following format:
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s></s> B </s>
|
||||
"""
|
||||
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
raise ValueError(
|
||||
@@ -234,24 +173,12 @@ class XLMRobertaTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
XLM-R does not make use of token type ids, therefore a list of zeros is returned.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of zeros.
|
||||
|
||||
RoBERTa does not make use of token type ids, therefore a list of zeros is returned.
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
|
||||
@@ -289,15 +216,8 @@ class XLMRobertaTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
""" Save the sentencepiece vocabulary (copy original file) and special tokens file
|
||||
to a directory.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
|
||||
@@ -19,7 +19,6 @@ import logging
|
||||
import os
|
||||
import unicodedata
|
||||
from shutil import copyfile
|
||||
from typing import List, Optional
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
@@ -52,57 +51,9 @@ SEG_ID_PAD = 4
|
||||
|
||||
class XLNetTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Constructs an XLNet tokenizer. Based on `SentencePiece <https://github.com/google/sentencepiece>`__
|
||||
SentencePiece based tokenizer. Peculiarities:
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
`SentencePiece <https://github.com/google/sentencepiece>`__ file (generally has a .spm extension) that
|
||||
contains the vocabulary necessary to instantiate a tokenizer.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
remove_space (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to strip the text when tokenizing (removing excess spaces before and after the string).
|
||||
keep_accents (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Whether to keep accents when tokenizing.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "<sep>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "<cls>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<mask>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`["<eop>", "<eod>"]`):
|
||||
Additional special tokens used by the tokenizer.
|
||||
|
||||
Attributes:
|
||||
sp_model (:obj:`SentencePieceProcessor`):
|
||||
The `SentencePiece` processor that is used for every conversion (string, tokens and IDs).
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -238,25 +189,13 @@ class XLNetTokenizer(PreTrainedTokenizer):
|
||||
out_string = "".join(tokens).replace(SPIECE_UNDERLINE, " ").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
An XLNet sequence has the following format:
|
||||
|
||||
- single sequence: ``X <sep> <cls>``
|
||||
- pair of sequences: ``A <sep> B <sep> <cls>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: X <sep> <cls>
|
||||
pair of sequences: A <sep> B <sep> <cls>
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -264,23 +203,20 @@ class XLNetTokenizer(PreTrainedTokenizer):
|
||||
return token_ids_0 + sep + cls
|
||||
return token_ids_0 + sep + token_ids_1 + sep + cls
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
@@ -295,9 +231,7 @@ class XLNetTokenizer(PreTrainedTokenizer):
|
||||
return ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1, 1]
|
||||
return ([0] * len(token_ids_0)) + [1, 1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
An XLNet sequence pair mask has the following format:
|
||||
@@ -305,16 +239,6 @@ class XLNetTokenizer(PreTrainedTokenizer):
|
||||
| first sequence | second sequence | CLS segment ID
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls_segment_id = [2]
|
||||
@@ -324,15 +248,8 @@ class XLNetTokenizer(PreTrainedTokenizer):
|
||||
return len(token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1] + cls_segment_id
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
""" Save the sentencepiece vocabulary (copy original file) and special tokens file
|
||||
to a directory.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
|
||||
@@ -641,7 +641,7 @@ global_rng = random.Random()
|
||||
|
||||
|
||||
def ids_tensor(shape, vocab_size, rng=None, name=None):
|
||||
# Creates a random int32 tensor of the shape within the vocab size
|
||||
"""Creates a random int32 tensor of the shape within the vocab size."""
|
||||
if rng is None:
|
||||
rng = global_rng
|
||||
|
||||
|
||||
@@ -23,7 +23,6 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import CTRLConfig, CTRLModel, CTRL_PRETRAINED_MODEL_ARCHIVE_MAP, CTRLLMHeadModel
|
||||
|
||||
|
||||
@@ -213,36 +212,3 @@ class CTRLModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(CTRL_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = CTRLModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
class CTRLModelLanguageGenerationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_lm_generate_ctrl(self):
|
||||
model = CTRLLMHeadModel.from_pretrained("ctrl")
|
||||
input_ids = torch.Tensor([[11859, 586, 20984, 8]]).long() # Legal My neighbor is
|
||||
expected_output_ids = [
|
||||
11859,
|
||||
586,
|
||||
20984,
|
||||
8,
|
||||
13391,
|
||||
3,
|
||||
980,
|
||||
8258,
|
||||
72,
|
||||
327,
|
||||
148,
|
||||
2,
|
||||
53,
|
||||
29,
|
||||
226,
|
||||
3,
|
||||
780,
|
||||
49,
|
||||
3,
|
||||
980,
|
||||
] # Legal My neighbor is refusing to pay rent after 2 years and we are having to force him to pay
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(input_ids)
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -24,7 +24,6 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
GPT2Config,
|
||||
GPT2Model,
|
||||
@@ -166,7 +165,7 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
"presents": presents,
|
||||
}
|
||||
self.parent.assertListEqual(
|
||||
list(result["sequence_output"].size()), [self.batch_size, self.seq_length, self.hidden_size],
|
||||
list(result["sequence_output"].size()), [self.batch_size, self.seq_length, self.hidden_size]
|
||||
)
|
||||
self.parent.assertEqual(len(result["presents"]), config.n_layer)
|
||||
|
||||
@@ -181,7 +180,7 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["lm_logits"].size()), [self.batch_size, self.seq_length, self.vocab_size],
|
||||
list(result["lm_logits"].size()), [self.batch_size, self.seq_length, self.vocab_size]
|
||||
)
|
||||
|
||||
def create_and_check_double_lm_head_model(
|
||||
@@ -209,8 +208,7 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["lm_logits"].size()),
|
||||
[self.batch_size, self.num_choices, self.seq_length, self.vocab_size],
|
||||
list(result["lm_logits"].size()), [self.batch_size, self.num_choices, self.seq_length, self.vocab_size]
|
||||
)
|
||||
self.parent.assertListEqual(list(result["mc_logits"].size()), [self.batch_size, self.num_choices])
|
||||
|
||||
@@ -229,11 +227,7 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
choice_labels,
|
||||
) = config_and_inputs
|
||||
|
||||
inputs_dict = {
|
||||
"input_ids": input_ids,
|
||||
"token_type_ids": token_type_ids,
|
||||
"head_mask": head_mask,
|
||||
}
|
||||
inputs_dict = {"input_ids": input_ids, "token_type_ids": token_type_ids, "head_mask": head_mask}
|
||||
|
||||
return config, inputs_dict
|
||||
|
||||
@@ -261,84 +255,3 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(GPT2_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = GPT2Model.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"bos_token_id": 50256, "eos_token_id": 50256}
|
||||
|
||||
|
||||
class GPT2ModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_gpt2(self):
|
||||
model = GPT2LMHeadModel.from_pretrained("gpt2")
|
||||
input_ids = torch.Tensor([[464, 3290, 318, 13779]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
464,
|
||||
3290,
|
||||
318,
|
||||
13779,
|
||||
1165,
|
||||
13,
|
||||
632,
|
||||
7832,
|
||||
284,
|
||||
6437,
|
||||
319,
|
||||
502,
|
||||
290,
|
||||
318,
|
||||
922,
|
||||
329,
|
||||
502,
|
||||
357,
|
||||
1169,
|
||||
3290,
|
||||
] # The dog is cute too. It likes to rub on me and is good for me (the dog
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
eos_token_ids=self.special_tokens["eos_token_id"],
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
|
||||
@slow
|
||||
def test_lm_generate_distilgpt2(self):
|
||||
model = GPT2LMHeadModel.from_pretrained("distilgpt2")
|
||||
input_ids = torch.Tensor([[464, 3290, 318, 13779]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
464,
|
||||
3290,
|
||||
318,
|
||||
13779,
|
||||
996,
|
||||
339,
|
||||
460,
|
||||
3360,
|
||||
655,
|
||||
2513,
|
||||
287,
|
||||
262,
|
||||
3952,
|
||||
13,
|
||||
632,
|
||||
318,
|
||||
407,
|
||||
845,
|
||||
3621,
|
||||
284,
|
||||
] # The dog is cute though he can sometimes just walk in the park. It is not very nice to
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
eos_token_ids=self.special_tokens["eos_token_id"],
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -24,7 +24,6 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
OpenAIGPTConfig,
|
||||
OpenAIGPTModel,
|
||||
@@ -209,36 +208,3 @@ class OpenAIGPTModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(OPENAI_GPT_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = OpenAIGPTModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
class OPENAIGPTModelLanguageGenerationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_lm_generate_openai_gpt(self):
|
||||
model = OpenAIGPTLMHeadModel.from_pretrained("openai-gpt")
|
||||
input_ids = torch.Tensor([[481, 2585, 544, 4957]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
481,
|
||||
2585,
|
||||
544,
|
||||
4957,
|
||||
669,
|
||||
512,
|
||||
761,
|
||||
5990,
|
||||
271,
|
||||
645,
|
||||
487,
|
||||
535,
|
||||
976,
|
||||
2479,
|
||||
240,
|
||||
487,
|
||||
804,
|
||||
1296,
|
||||
2891,
|
||||
512,
|
||||
] # the dog is cute when you're annoyed : if he's really stupid, he 'll stop fighting you
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(input_ids)
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -212,372 +212,3 @@ class TransfoXLModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(TRANSFO_XL_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = TransfoXLModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"eos_token_id": 0}
|
||||
|
||||
|
||||
class TransfoXLModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_transfo_xl_wt103(self):
|
||||
model = TransfoXLLMHeadModel.from_pretrained("transfo-xl-wt103")
|
||||
input_ids = torch.Tensor(
|
||||
[
|
||||
[
|
||||
33,
|
||||
1297,
|
||||
2,
|
||||
1,
|
||||
1009,
|
||||
4,
|
||||
1109,
|
||||
11739,
|
||||
4762,
|
||||
358,
|
||||
5,
|
||||
25,
|
||||
245,
|
||||
22,
|
||||
1706,
|
||||
17,
|
||||
20098,
|
||||
5,
|
||||
3215,
|
||||
21,
|
||||
37,
|
||||
1110,
|
||||
3,
|
||||
13,
|
||||
1041,
|
||||
4,
|
||||
24,
|
||||
603,
|
||||
490,
|
||||
2,
|
||||
71477,
|
||||
20098,
|
||||
104447,
|
||||
2,
|
||||
20961,
|
||||
1,
|
||||
2604,
|
||||
4,
|
||||
1,
|
||||
329,
|
||||
3,
|
||||
6224,
|
||||
831,
|
||||
16002,
|
||||
2,
|
||||
8,
|
||||
603,
|
||||
78967,
|
||||
29546,
|
||||
23,
|
||||
803,
|
||||
20,
|
||||
25,
|
||||
416,
|
||||
5,
|
||||
8,
|
||||
232,
|
||||
4,
|
||||
277,
|
||||
6,
|
||||
1855,
|
||||
4601,
|
||||
3,
|
||||
29546,
|
||||
54,
|
||||
8,
|
||||
3609,
|
||||
5,
|
||||
57211,
|
||||
49,
|
||||
4,
|
||||
1,
|
||||
277,
|
||||
18,
|
||||
8,
|
||||
1755,
|
||||
15691,
|
||||
3,
|
||||
341,
|
||||
25,
|
||||
416,
|
||||
693,
|
||||
42573,
|
||||
71,
|
||||
17,
|
||||
401,
|
||||
94,
|
||||
31,
|
||||
17919,
|
||||
2,
|
||||
29546,
|
||||
7873,
|
||||
18,
|
||||
1,
|
||||
435,
|
||||
23,
|
||||
11011,
|
||||
755,
|
||||
5,
|
||||
5167,
|
||||
3,
|
||||
7983,
|
||||
98,
|
||||
84,
|
||||
2,
|
||||
29546,
|
||||
3267,
|
||||
8,
|
||||
3609,
|
||||
4,
|
||||
1,
|
||||
4865,
|
||||
1075,
|
||||
2,
|
||||
6087,
|
||||
71,
|
||||
6,
|
||||
346,
|
||||
8,
|
||||
5854,
|
||||
3,
|
||||
29546,
|
||||
824,
|
||||
1400,
|
||||
1868,
|
||||
2,
|
||||
19,
|
||||
160,
|
||||
2,
|
||||
311,
|
||||
8,
|
||||
5496,
|
||||
2,
|
||||
20920,
|
||||
17,
|
||||
25,
|
||||
15097,
|
||||
3,
|
||||
24,
|
||||
24,
|
||||
0,
|
||||
]
|
||||
]
|
||||
).long()
|
||||
# In 1991 , the remains of Russian Tsar Nicholas II and his family
|
||||
# ( except for Alexei and Maria ) are discovered .
|
||||
# The voice of Nicholas's young son , Tsarevich Alexei Nikolaevich , narrates the
|
||||
# remainder of the story . 1883 Western Siberia ,
|
||||
# a young Grigori Rasputin is asked by his father and a group of men to perform magic .
|
||||
# Rasputin has a vision and denounces one of the men as a horse thief . Although his
|
||||
# father initially slaps him for making such an accusation , Rasputin watches as the
|
||||
# man is chased outside and beaten . Twenty years later , Rasputin sees a vision of
|
||||
# the Virgin Mary , prompting him to become a priest . Rasputin quickly becomes famous ,
|
||||
# with people , even a bishop , begging for his blessing . <eod> </s> <eos>
|
||||
|
||||
expected_output_ids = [
|
||||
33,
|
||||
1297,
|
||||
2,
|
||||
1,
|
||||
1009,
|
||||
4,
|
||||
1109,
|
||||
11739,
|
||||
4762,
|
||||
358,
|
||||
5,
|
||||
25,
|
||||
245,
|
||||
22,
|
||||
1706,
|
||||
17,
|
||||
20098,
|
||||
5,
|
||||
3215,
|
||||
21,
|
||||
37,
|
||||
1110,
|
||||
3,
|
||||
13,
|
||||
1041,
|
||||
4,
|
||||
24,
|
||||
603,
|
||||
490,
|
||||
2,
|
||||
71477,
|
||||
20098,
|
||||
104447,
|
||||
2,
|
||||
20961,
|
||||
1,
|
||||
2604,
|
||||
4,
|
||||
1,
|
||||
329,
|
||||
3,
|
||||
6224,
|
||||
831,
|
||||
16002,
|
||||
2,
|
||||
8,
|
||||
603,
|
||||
78967,
|
||||
29546,
|
||||
23,
|
||||
803,
|
||||
20,
|
||||
25,
|
||||
416,
|
||||
5,
|
||||
8,
|
||||
232,
|
||||
4,
|
||||
277,
|
||||
6,
|
||||
1855,
|
||||
4601,
|
||||
3,
|
||||
29546,
|
||||
54,
|
||||
8,
|
||||
3609,
|
||||
5,
|
||||
57211,
|
||||
49,
|
||||
4,
|
||||
1,
|
||||
277,
|
||||
18,
|
||||
8,
|
||||
1755,
|
||||
15691,
|
||||
3,
|
||||
341,
|
||||
25,
|
||||
416,
|
||||
693,
|
||||
42573,
|
||||
71,
|
||||
17,
|
||||
401,
|
||||
94,
|
||||
31,
|
||||
17919,
|
||||
2,
|
||||
29546,
|
||||
7873,
|
||||
18,
|
||||
1,
|
||||
435,
|
||||
23,
|
||||
11011,
|
||||
755,
|
||||
5,
|
||||
5167,
|
||||
3,
|
||||
7983,
|
||||
98,
|
||||
84,
|
||||
2,
|
||||
29546,
|
||||
3267,
|
||||
8,
|
||||
3609,
|
||||
4,
|
||||
1,
|
||||
4865,
|
||||
1075,
|
||||
2,
|
||||
6087,
|
||||
71,
|
||||
6,
|
||||
346,
|
||||
8,
|
||||
5854,
|
||||
3,
|
||||
29546,
|
||||
824,
|
||||
1400,
|
||||
1868,
|
||||
2,
|
||||
19,
|
||||
160,
|
||||
2,
|
||||
311,
|
||||
8,
|
||||
5496,
|
||||
2,
|
||||
20920,
|
||||
17,
|
||||
25,
|
||||
15097,
|
||||
3,
|
||||
24,
|
||||
24,
|
||||
0,
|
||||
29546,
|
||||
40,
|
||||
1092,
|
||||
18,
|
||||
8,
|
||||
5854,
|
||||
7,
|
||||
1143,
|
||||
2,
|
||||
7,
|
||||
1,
|
||||
159,
|
||||
99,
|
||||
16,
|
||||
1,
|
||||
1009,
|
||||
4,
|
||||
1109,
|
||||
11739,
|
||||
4762,
|
||||
358,
|
||||
5,
|
||||
25,
|
||||
245,
|
||||
28,
|
||||
1110,
|
||||
3,
|
||||
57,
|
||||
629,
|
||||
38,
|
||||
3493,
|
||||
47,
|
||||
1094,
|
||||
7,
|
||||
1297,
|
||||
3,
|
||||
0,
|
||||
]
|
||||
# In 1991, the remains of Russian Tsar Nicholas II and his family (
|
||||
# except for Alexei and Maria ) are discovered. The voice of young son,
|
||||
# Tsarevich Alexei Nikolaevich, narrates the remainder of the story.
|
||||
# 1883 Western Siberia, a young Grigori Rasputin is asked by his father
|
||||
# and a group of men to perform magic. Rasputin has a vision and
|
||||
# denounces one of the men as a horse thief. Although his father initially
|
||||
# slaps him for making such an accusation, Rasputin watches as the man
|
||||
# is chased outside and beaten. Twenty years later, Rasputin sees a vision
|
||||
# of the Virgin Mary, prompting him to become a priest.
|
||||
# Rasputin quickly becomes famous, with people, even a bishop, begging for
|
||||
# his blessing. Rasputin first appears as a priest in 1996, in the same year
|
||||
# that the remains of Russian Tsar Nicholas II and his family were discovered. H
|
||||
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(input_ids, eos_token_ids=self.special_tokens["eos_token_id"], max_length=200)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -24,7 +24,6 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
XLMConfig,
|
||||
XLMModel,
|
||||
@@ -397,48 +396,3 @@ class XLMModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(XLM_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = XLMModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"bos_token_id": 0, "pad_token_id": 2}
|
||||
|
||||
|
||||
class XLMModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_xlm_mlm_en_2048(self):
|
||||
model = XLMWithLMHeadModel.from_pretrained("xlm-mlm-en-2048")
|
||||
input_ids = torch.Tensor([[1, 14, 2232, 26, 1]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
1,
|
||||
14,
|
||||
2232,
|
||||
26,
|
||||
1,
|
||||
567,
|
||||
26,
|
||||
32,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
] # The dog is nothing is it!!!!!!!!!!!! TODO (PVP): this sentence (and others I tried) does not make much sense, there seems to be a problem with xlm language generation.
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
pad_token_id=self.special_tokens["pad_token_id"],
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -1,68 +0,0 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
|
||||
import unittest
|
||||
|
||||
from transformers import is_torch_available
|
||||
|
||||
from .utils import slow
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import XLMRobertaModel
|
||||
|
||||
|
||||
class XLMRobertaModelIntegrationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_xlm_roberta_base(self):
|
||||
model = XLMRobertaModel.from_pretrained("xlm-roberta-base")
|
||||
input_ids = torch.tensor([0, 581, 10269, 83, 99942, 136, 60742, 23, 70, 80583, 18276, 2]).unsqueeze(
|
||||
0
|
||||
) # The dog is cute and lives in the garden house
|
||||
|
||||
expected_output_shape = torch.Size((1, 12, 768)) # batch_size, sequence_length, embedding_vector_dim
|
||||
expected_output_values_last_dim = torch.tensor(
|
||||
[-0.0101, 0.1218, -0.0803, 0.0801, 0.1327, 0.0776, -0.1215, 0.2383, 0.3338, 0.3106, 0.0300, 0.0252]
|
||||
).unsqueeze(0)
|
||||
# xlmr = torch.hub.load('pytorch/fairseq', 'xlmr.base')
|
||||
# xlmr.eval()
|
||||
# expected_output_values_last_dim = xlmr.extract_features(input_ids[0])[:, :, -1]
|
||||
|
||||
output = model(input_ids)[0].detach()
|
||||
self.assertEqual(output.shape, expected_output_shape)
|
||||
# compare the actual values for a slice of last dim
|
||||
self.assertTrue(torch.allclose(output[:, :, -1], expected_output_values_last_dim, atol=1e-3))
|
||||
|
||||
@slow
|
||||
def test_xlm_roberta_large(self):
|
||||
model = XLMRobertaModel.from_pretrained("xlm-roberta-large")
|
||||
input_ids = torch.tensor([0, 581, 10269, 83, 99942, 136, 60742, 23, 70, 80583, 18276, 2]).unsqueeze(
|
||||
0
|
||||
) # The dog is cute and lives in the garden house
|
||||
|
||||
expected_output_shape = torch.Size((1, 12, 1024)) # batch_size, sequence_length, embedding_vector_dim
|
||||
expected_output_values_last_dim = torch.tensor(
|
||||
[-0.0699, -0.0318, 0.0705, -0.1241, 0.0999, -0.0520, 0.1004, -0.1838, -0.4704, 0.1437, 0.0821, 0.0126]
|
||||
).unsqueeze(0)
|
||||
# xlmr = torch.hub.load('pytorch/fairseq', 'xlmr.large')
|
||||
# xlmr.eval()
|
||||
# expected_output_values_last_dim = xlmr.extract_features(input_ids[0])[:, :, -1]
|
||||
|
||||
output = model(input_ids)[0].detach()
|
||||
self.assertEqual(output.shape, expected_output_shape)
|
||||
# compare the actual values for a slice of last dim
|
||||
self.assertTrue(torch.allclose(output[:, :, -1], expected_output_values_last_dim, atol=1e-3))
|
||||
@@ -511,418 +511,3 @@ class XLNetModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(XLNET_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = XLNetModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"bos_token_id": 1, "pad_token_id": 5, "eos_token_id": 2}
|
||||
|
||||
|
||||
class XLNetModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_xlnet_base_cased(self):
|
||||
model = XLNetLMHeadModel.from_pretrained("xlnet-base-cased")
|
||||
input_ids = torch.Tensor(
|
||||
[
|
||||
[
|
||||
67,
|
||||
2840,
|
||||
19,
|
||||
18,
|
||||
1484,
|
||||
20,
|
||||
965,
|
||||
29077,
|
||||
8719,
|
||||
1273,
|
||||
21,
|
||||
45,
|
||||
273,
|
||||
17,
|
||||
10,
|
||||
15048,
|
||||
28,
|
||||
27511,
|
||||
21,
|
||||
4185,
|
||||
11,
|
||||
41,
|
||||
2444,
|
||||
9,
|
||||
32,
|
||||
1025,
|
||||
20,
|
||||
8719,
|
||||
26,
|
||||
23,
|
||||
673,
|
||||
966,
|
||||
19,
|
||||
29077,
|
||||
20643,
|
||||
27511,
|
||||
20822,
|
||||
20643,
|
||||
19,
|
||||
17,
|
||||
6616,
|
||||
17511,
|
||||
18,
|
||||
8978,
|
||||
20,
|
||||
18,
|
||||
777,
|
||||
9,
|
||||
19233,
|
||||
1527,
|
||||
17669,
|
||||
19,
|
||||
24,
|
||||
673,
|
||||
17,
|
||||
28756,
|
||||
150,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
27,
|
||||
442,
|
||||
37,
|
||||
45,
|
||||
668,
|
||||
21,
|
||||
24,
|
||||
256,
|
||||
20,
|
||||
416,
|
||||
22,
|
||||
2771,
|
||||
4901,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
51,
|
||||
24,
|
||||
3004,
|
||||
21,
|
||||
28142,
|
||||
23,
|
||||
65,
|
||||
20,
|
||||
18,
|
||||
416,
|
||||
34,
|
||||
24,
|
||||
2958,
|
||||
22947,
|
||||
9,
|
||||
1177,
|
||||
45,
|
||||
668,
|
||||
3097,
|
||||
13768,
|
||||
23,
|
||||
103,
|
||||
28,
|
||||
441,
|
||||
148,
|
||||
48,
|
||||
20522,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
12860,
|
||||
34,
|
||||
18,
|
||||
326,
|
||||
27,
|
||||
17492,
|
||||
684,
|
||||
21,
|
||||
6709,
|
||||
9,
|
||||
8585,
|
||||
123,
|
||||
266,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
6872,
|
||||
24,
|
||||
3004,
|
||||
20,
|
||||
18,
|
||||
9225,
|
||||
2198,
|
||||
19,
|
||||
12717,
|
||||
103,
|
||||
22,
|
||||
401,
|
||||
24,
|
||||
6348,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
1068,
|
||||
2768,
|
||||
2286,
|
||||
19,
|
||||
33,
|
||||
104,
|
||||
19,
|
||||
176,
|
||||
24,
|
||||
9313,
|
||||
19,
|
||||
20086,
|
||||
28,
|
||||
45,
|
||||
10292,
|
||||
9,
|
||||
4,
|
||||
3,
|
||||
]
|
||||
]
|
||||
).long()
|
||||
# In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
# (except for Alexei and Maria) are discovered.
|
||||
# The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
|
||||
# remainder of the story. 1883 Western Siberia,
|
||||
# a young Grigori Rasputin is asked by his father and a group of men to perform magic.
|
||||
# Rasputin has a vision and denounces one of the men as a horse thief. Although his
|
||||
# father initially slaps him for making such an accusation, Rasputin watches as the
|
||||
# man is chased outside and beaten. Twenty years later, Rasputin sees a vision of
|
||||
# the Virgin Mary, prompting him to become a priest. Rasputin quickly becomes famous,
|
||||
# with people, even a bishop, begging for his blessing. """
|
||||
|
||||
expected_output_ids = [
|
||||
67,
|
||||
2840,
|
||||
19,
|
||||
18,
|
||||
1484,
|
||||
20,
|
||||
965,
|
||||
29077,
|
||||
8719,
|
||||
1273,
|
||||
21,
|
||||
45,
|
||||
273,
|
||||
17,
|
||||
10,
|
||||
15048,
|
||||
28,
|
||||
27511,
|
||||
21,
|
||||
4185,
|
||||
11,
|
||||
41,
|
||||
2444,
|
||||
9,
|
||||
32,
|
||||
1025,
|
||||
20,
|
||||
8719,
|
||||
26,
|
||||
23,
|
||||
673,
|
||||
966,
|
||||
19,
|
||||
29077,
|
||||
20643,
|
||||
27511,
|
||||
20822,
|
||||
20643,
|
||||
19,
|
||||
17,
|
||||
6616,
|
||||
17511,
|
||||
18,
|
||||
8978,
|
||||
20,
|
||||
18,
|
||||
777,
|
||||
9,
|
||||
19233,
|
||||
1527,
|
||||
17669,
|
||||
19,
|
||||
24,
|
||||
673,
|
||||
17,
|
||||
28756,
|
||||
150,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
27,
|
||||
442,
|
||||
37,
|
||||
45,
|
||||
668,
|
||||
21,
|
||||
24,
|
||||
256,
|
||||
20,
|
||||
416,
|
||||
22,
|
||||
2771,
|
||||
4901,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
51,
|
||||
24,
|
||||
3004,
|
||||
21,
|
||||
28142,
|
||||
23,
|
||||
65,
|
||||
20,
|
||||
18,
|
||||
416,
|
||||
34,
|
||||
24,
|
||||
2958,
|
||||
22947,
|
||||
9,
|
||||
1177,
|
||||
45,
|
||||
668,
|
||||
3097,
|
||||
13768,
|
||||
23,
|
||||
103,
|
||||
28,
|
||||
441,
|
||||
148,
|
||||
48,
|
||||
20522,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
12860,
|
||||
34,
|
||||
18,
|
||||
326,
|
||||
27,
|
||||
17492,
|
||||
684,
|
||||
21,
|
||||
6709,
|
||||
9,
|
||||
8585,
|
||||
123,
|
||||
266,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
6872,
|
||||
24,
|
||||
3004,
|
||||
20,
|
||||
18,
|
||||
9225,
|
||||
2198,
|
||||
19,
|
||||
12717,
|
||||
103,
|
||||
22,
|
||||
401,
|
||||
24,
|
||||
6348,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
1068,
|
||||
2768,
|
||||
2286,
|
||||
19,
|
||||
33,
|
||||
104,
|
||||
19,
|
||||
176,
|
||||
24,
|
||||
9313,
|
||||
19,
|
||||
20086,
|
||||
28,
|
||||
45,
|
||||
10292,
|
||||
9,
|
||||
4,
|
||||
3,
|
||||
1722,
|
||||
19,
|
||||
24,
|
||||
6348,
|
||||
61,
|
||||
977,
|
||||
176,
|
||||
1772,
|
||||
33,
|
||||
45,
|
||||
970,
|
||||
19,
|
||||
4185,
|
||||
19,
|
||||
27,
|
||||
442,
|
||||
22,
|
||||
2771,
|
||||
4901,
|
||||
25,
|
||||
18,
|
||||
2059,
|
||||
20,
|
||||
24,
|
||||
303,
|
||||
1775,
|
||||
691,
|
||||
9,
|
||||
1147,
|
||||
19,
|
||||
634,
|
||||
19,
|
||||
43,
|
||||
51,
|
||||
54,
|
||||
6157,
|
||||
2999,
|
||||
33,
|
||||
4185,
|
||||
]
|
||||
# In 1991, the remains of Russian Tsar Nicholas II and his family (except for Alexei and Maria)
|
||||
# are discovered. The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich,
|
||||
# narrates the remainder of the story. 1883 Western Siberia, a young Grigori Rasputin
|
||||
# is asked by his father and a group of men to perform magic. Rasputin has a vision and
|
||||
# denounces one of the men as a horse thief. Although his father initially slaps
|
||||
# him for making such an accusation, Rasputin watches as the man is chased outside and beaten.
|
||||
# Twenty years later, Rasputin sees a vision of the Virgin Mary, prompting him to become a priest.
|
||||
# Rasputin quickly becomes famous, with people, even a bishop, begging for his blessing.
|
||||
# 1990, a priest who cannot even walk with his wife, Maria, is asked to perform magic
|
||||
# in the presence of a local religious leader.
|
||||
# Since, however, he has had difficulty walking with Maria
|
||||
|
||||
torch.manual_seed(0)
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
pad_token_id=self.special_tokens["pad_token_id"],
|
||||
eos_token_ids=self.special_tokens["eos_token_id"],
|
||||
max_length=200,
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -101,5 +101,5 @@ class AutoTokenizerTest(unittest.TestCase):
|
||||
self.assertFalse(issubclass(child_model_fast, parent_model_fast))
|
||||
|
||||
def test_from_pretrained_use_fast_toggle(self):
|
||||
self.assertIsInstance(AutoTokenizer.from_pretrained("bert-base-cased"), BertTokenizer)
|
||||
self.assertIsInstance(AutoTokenizer.from_pretrained("bert-base-cased", use_fast=True), BertTokenizerFast)
|
||||
self.assertIsInstance(AutoTokenizer.from_pretrained("bert-base-cased"), BertTokenizerFast)
|
||||
self.assertIsInstance(AutoTokenizer.from_pretrained("bert-base-cased", use_fast=False), BertTokenizer)
|
||||
@@ -19,8 +19,6 @@ import pickle
|
||||
import shutil
|
||||
import tempfile
|
||||
|
||||
from tests.utils import require_tf, require_torch
|
||||
|
||||
|
||||
class TokenizerTesterMixin:
|
||||
|
||||
@@ -42,15 +40,6 @@ class TokenizerTesterMixin:
|
||||
def get_input_output_texts(self):
|
||||
raise NotImplementedError
|
||||
|
||||
@staticmethod
|
||||
def convert_batch_encode_plus_format_to_encode_plus(batch_encode_plus_sequences):
|
||||
# Switch from batch_encode_plus format: {'input_ids': [[...], [...]], ...}
|
||||
# to the concatenated encode_plus format: [{'input_ids': [...], ...}, {'input_ids': [...], ...}]
|
||||
return [
|
||||
{value: batch_encode_plus_sequences[value][i] for value in batch_encode_plus_sequences.keys()}
|
||||
for i in range(len(batch_encode_plus_sequences))
|
||||
]
|
||||
|
||||
def test_tokenizers_common_properties(self):
|
||||
tokenizer = self.get_tokenizer()
|
||||
attributes_list = [
|
||||
@@ -546,8 +535,11 @@ class TokenizerTesterMixin:
|
||||
# we're loading an S3 configuration from a pre-trained identifier, and we have no way of testing those today.
|
||||
|
||||
tokenizer = self.get_tokenizer(random_argument=True)
|
||||
print(tokenizer.init_kwargs)
|
||||
assert tokenizer.init_kwargs["random_argument"] is True
|
||||
new_tokenizer = self.get_tokenizer(random_argument=False)
|
||||
print(tokenizer.init_kwargs)
|
||||
print(new_tokenizer.init_kwargs)
|
||||
assert tokenizer.init_kwargs["random_argument"] is True
|
||||
assert new_tokenizer.init_kwargs["random_argument"] is False
|
||||
|
||||
@@ -570,101 +562,3 @@ class TokenizerTesterMixin:
|
||||
for word, ind in vocab.items():
|
||||
self.assertEqual(tokenizer.convert_tokens_to_ids(word), ind)
|
||||
self.assertEqual(tokenizer.convert_ids_to_tokens(ind), word)
|
||||
|
||||
def test_batch_encode_plus_batch_sequence_length(self):
|
||||
# Tests that all encoded values have the correct size
|
||||
tokenizer = self.get_tokenizer()
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
encoded_sequences = [tokenizer.encode_plus(sequence, pad_to_max_length=False) for sequence in sequences]
|
||||
encoded_sequences_batch = tokenizer.batch_encode_plus(sequences)
|
||||
self.assertListEqual(
|
||||
encoded_sequences, self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch)
|
||||
)
|
||||
|
||||
maximum_length = len(max([encoded_sequence["input_ids"] for encoded_sequence in encoded_sequences], key=len))
|
||||
|
||||
encoded_sequences_padded = [
|
||||
tokenizer.encode_plus(sequence, pad_to_max_length=True, max_length=maximum_length)
|
||||
for sequence in sequences
|
||||
]
|
||||
encoded_sequences_batch_padded = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True)
|
||||
self.assertListEqual(
|
||||
encoded_sequences_padded,
|
||||
self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch_padded),
|
||||
)
|
||||
|
||||
def test_batch_encode_plus_padding(self):
|
||||
# Test that padded sequences are equivalent between batch_encode_plus and encode_plus
|
||||
|
||||
# Right padding tests
|
||||
tokenizer = self.get_tokenizer()
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
max_length = 100
|
||||
encoded_sequences = [
|
||||
tokenizer.encode_plus(sequence, pad_to_max_length=True, max_length=max_length) for sequence in sequences
|
||||
]
|
||||
encoded_sequences_batch = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, max_length=max_length)
|
||||
self.assertListEqual(
|
||||
encoded_sequences, self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch)
|
||||
)
|
||||
|
||||
# Left padding tests
|
||||
tokenizer = self.get_tokenizer()
|
||||
tokenizer.padding_side = "left"
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
max_length = 100
|
||||
encoded_sequences = [
|
||||
tokenizer.encode_plus(sequence, pad_to_max_length=True, max_length=max_length) for sequence in sequences
|
||||
]
|
||||
encoded_sequences_batch = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, max_length=max_length)
|
||||
self.assertListEqual(
|
||||
encoded_sequences, self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch)
|
||||
)
|
||||
|
||||
@require_torch
|
||||
@require_tf
|
||||
def test_batch_encode_plus_tensors(self):
|
||||
tokenizer = self.get_tokenizer()
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
# A Tensor cannot be build by sequences which are not the same size
|
||||
self.assertRaises(ValueError, tokenizer.batch_encode_plus, sequences, return_tensors="pt")
|
||||
self.assertRaises(ValueError, tokenizer.batch_encode_plus, sequences, return_tensors="tf")
|
||||
|
||||
if tokenizer.pad_token_id is None:
|
||||
self.assertRaises(
|
||||
ValueError, tokenizer.batch_encode_plus, sequences, pad_to_max_length=True, return_tensors="pt"
|
||||
)
|
||||
self.assertRaises(
|
||||
ValueError, tokenizer.batch_encode_plus, sequences, pad_to_max_length=True, return_tensors="tf"
|
||||
)
|
||||
else:
|
||||
pytorch_tensor = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, return_tensors="pt")
|
||||
tensorflow_tensor = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, return_tensors="tf")
|
||||
encoded_sequences = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True)
|
||||
|
||||
for key in encoded_sequences.keys():
|
||||
pytorch_value = pytorch_tensor[key].tolist()
|
||||
tensorflow_value = tensorflow_tensor[key].numpy().tolist()
|
||||
encoded_value = encoded_sequences[key]
|
||||
|
||||
self.assertEqual(pytorch_value, tensorflow_value, encoded_value)
|
||||
@@ -258,20 +258,6 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
output_p = tokenizer_p.build_inputs_with_special_tokens(input_simple, input_pair)
|
||||
self.assertEqual(output_p, output_r)
|
||||
|
||||
def assert_save_pretrained(self, tokenizer_r, tokenizer_p):
|
||||
|
||||
# Checks it save with the same files
|
||||
self.assertSequenceEqual(tokenizer_r.save_vocabulary("."), tokenizer_p.save_vocabulary("."))
|
||||
|
||||
# Checks everything loads correctly in the same way
|
||||
tokenizer_rp, tokenizer_pp = tokenizer_r.from_pretrained("."), tokenizer_p.from_pretrained(".")
|
||||
|
||||
# Check special tokens are set accordingly on Rust and Python
|
||||
for key in tokenizer_pp.special_tokens_map:
|
||||
self.assertTrue(hasattr(tokenizer_rp, key))
|
||||
# self.assertEqual(getattr(tokenizer_rp, key), getattr(tokenizer_pp, key))
|
||||
# self.assertEqual(getattr(tokenizer_rp, key + "_id"), getattr(tokenizer_pp, key + "_id"))
|
||||
|
||||
def test_bert(self):
|
||||
for tokenizer_name in BertTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = BertTokenizer.from_pretrained(tokenizer_name)
|
||||
@@ -308,7 +294,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assert_padding(tokenizer_r, tokenizer_p)
|
||||
@@ -349,26 +335,12 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
# Check alignment for build_inputs_with_special_tokens
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assertRaises(ValueError, self.assert_padding, tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
# TransfoXL tokenizers comes in a special format which is not compatible at all
|
||||
# with rust tokenizers. We ensure the errors detection at correctly raised
|
||||
tokenizer_r_files = tokenizer_r.save_pretrained(".")
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_r_files, ["./vocab.json", "./special_tokens_map.json", "./added_tokens.json"]
|
||||
)
|
||||
|
||||
# Check loading Python-tokenizer save through Rust doesnt work (and the opposite)
|
||||
self.assertRaises(ValueError, tokenizer_p.from_pretrained, *tokenizer_r_files)
|
||||
self.assertRaises(ValueError, tokenizer_r.from_pretrained, *tokenizer_p.save_pretrained("."))
|
||||
|
||||
# Check loading works for Python to Python and Rust to Rust
|
||||
# Issue: https://github.com/huggingface/transformers/issues/3000
|
||||
# self.assertIsNotNone(tokenizer_p.__class__.from_pretrained('./'))
|
||||
self.assertIsNotNone(tokenizer_r.__class__.from_pretrained("./"))
|
||||
|
||||
def test_distilbert(self):
|
||||
for tokenizer_name in DistilBertTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = DistilBertTokenizer.from_pretrained(tokenizer_name)
|
||||
@@ -406,7 +378,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assert_padding(tokenizer_r, tokenizer_p)
|
||||
@@ -447,7 +419,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assertRaises(ValueError, self.assert_padding, tokenizer_r, tokenizer_p)
|
||||
@@ -488,7 +460,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
# TODO: Re-enable this test as soon as Roberta align with the python tokenizer.
|
||||
@@ -529,10 +501,12 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
# Check alignment for build_inputs_with_special_tokens
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assertRaises(ValueError, self.assert_padding, tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -1,111 +0,0 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
|
||||
import unittest
|
||||
|
||||
from transformers.tokenization_xlm_roberta import XLMRobertaTokenizer
|
||||
|
||||
from .utils import slow
|
||||
|
||||
|
||||
class XLMRobertaTokenizationIntegrationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_tokenization_base_easy_symbols(self):
|
||||
tokenizer = XLMRobertaTokenizer.from_pretrained("xlm-roberta-base")
|
||||
|
||||
symbols = "Hello World!"
|
||||
original_tokenizer_encodings = [0, 35378, 6661, 38, 2]
|
||||
# xlmr = torch.hub.load('pytorch/fairseq', 'xlmr.base') # xlmr.large has same tokenizer
|
||||
# xlmr.eval()
|
||||
# xlmr.encode(symbols)
|
||||
|
||||
self.assertListEqual(original_tokenizer_encodings, tokenizer.encode(symbols))
|
||||
|
||||
@slow
|
||||
def test_tokenization_base_hard_symbols(self):
|
||||
tokenizer = XLMRobertaTokenizer.from_pretrained("xlm-roberta-base")
|
||||
|
||||
symbols = 'This is a very long text with a lot of weird characters, such as: . , ~ ? ( ) " [ ] ! : - . Also we will add words that should not exsist and be tokenized to <unk>, such as saoneuhaoesuth'
|
||||
original_tokenizer_encodings = [
|
||||
0,
|
||||
3293,
|
||||
83,
|
||||
10,
|
||||
4552,
|
||||
4989,
|
||||
7986,
|
||||
678,
|
||||
10,
|
||||
5915,
|
||||
111,
|
||||
179459,
|
||||
124850,
|
||||
4,
|
||||
6044,
|
||||
237,
|
||||
12,
|
||||
6,
|
||||
5,
|
||||
6,
|
||||
4,
|
||||
6780,
|
||||
705,
|
||||
15,
|
||||
1388,
|
||||
44,
|
||||
378,
|
||||
10114,
|
||||
711,
|
||||
152,
|
||||
20,
|
||||
6,
|
||||
5,
|
||||
22376,
|
||||
642,
|
||||
1221,
|
||||
15190,
|
||||
34153,
|
||||
450,
|
||||
5608,
|
||||
959,
|
||||
1119,
|
||||
57702,
|
||||
136,
|
||||
186,
|
||||
47,
|
||||
1098,
|
||||
29367,
|
||||
47,
|
||||
4426,
|
||||
3678,
|
||||
2740,
|
||||
4,
|
||||
6044,
|
||||
237,
|
||||
6284,
|
||||
50901,
|
||||
528,
|
||||
31,
|
||||
90,
|
||||
34,
|
||||
927,
|
||||
2,
|
||||
]
|
||||
# xlmr = torch.hub.load('pytorch/fairseq', 'xlmr.base') # xlmr.large has same tokenizer
|
||||
# xlmr.eval()
|
||||
# xlmr.encode(symbols)
|
||||
|
||||
self.assertListEqual(original_tokenizer_encodings, tokenizer.encode(symbols))
|
||||
Reference in new issue
Block a user