Compare commits
128
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Lysandre |
6626e9cf74 | ||
|
Lysandre
|
81d4fb79dd | ||
|
Sam Shleifer
|
3aca02efb3 | ||
|
Lysandre Debut
|
5164ea91a7 | ||
|
Patrick von Platen
|
49debe62fd | ||
|
Patrick von Platen
|
847d370301 | ||
|
Lysandre
|
eb3e6cb04f | ||
|
Patrick von Platen
|
3e624c64ca | ||
|
Param bhavsar
|
b29fed790b | ||
|
Julien Chaumond
|
e03129ad44 | ||
|
Julien Chaumond
|
08a70fb392 | ||
|
Lysandre Debut
|
0ae91c80aa | ||
|
voidful
|
d6df9a8ffe | ||
|
Manuel Romero
|
c52716d46c | ||
|
Aleksei Lymar
|
73a0c25376 | ||
|
Sam Shleifer
|
ed37f9fa4f | ||
|
Thomas Wolf
|
0416d437fb | ||
|
Funtowicz Morgan
|
db9279dedb | ||
|
Sam Shleifer
|
e58b3ec5df | ||
|
Thomas Wolf
|
6ffe03a0a1 | ||
|
Thomas Wolf
|
3e5da38dae | ||
|
Thomas Wolf
|
9499a3778e | ||
|
patrickvonplaten
|
9362eb4a07 | ||
|
Patrick von Platen
|
c8035e11e8 | ||
|
patrickvonplaten
|
58fc8f97a3 | ||
|
Sam Shleifer
|
857e0a0d3b | ||
|
Lysandre Debut
|
fa2aa699da | ||
|
Lysandre Debut
|
146c521235 | ||
|
Lysandre Debut
|
b623ddc000 | ||
|
Lysandre Debut
|
0001d05686 | ||
|
Thomas Wolf
|
1741d740f2 | ||
|
Thomas Wolf
|
bbabbc1613 | ||
|
sshleifer
|
14d40584b2 | ||
|
sshleifer
|
1360dacaa3 | ||
|
sshleifer
|
810079de1f | ||
|
sshleifer
|
c203509d5b | ||
|
sshleifer
|
c36fdc88d4 | ||
|
Morgan Funtowicz
|
7ac47bfe69 | ||
|
Morgan Funtowicz
|
be02176a4b | ||
|
Julien Chaumond
|
8a2d9bc9ef | ||
|
Morgan Funtowicz
|
012cbdb0f5 | ||
|
Tom Hosking
|
31acb8dc52 | ||
|
Tom Hosking
|
06a6cb6f36 | ||
|
Patrick von Platen
|
e33ed12c3b | ||
|
Patrick von Platen
|
4220fd52b9 | ||
|
Patrick von Platen
|
c47394b0c9 | ||
|
Gunnlaugur Thor Briem
|
4c91a3af94 | ||
|
Gunnlaugur Thor Briem
|
4be01e5cbf | ||
|
Gunnlaugur Thor Briem
|
a355f4f0fc | ||
|
Gunnlaugur Thor Briem
|
d262a5d48e | ||
|
Morgan Funtowicz
|
30624f7056 | ||
|
Julien Chaumond
|
3f067f4409 | ||
|
Julien Chaumond
|
f564f93c84 | ||
|
Julien Chaumond
|
ff9e79ba3a | ||
|
Lysandre
|
07a79db505 | ||
|
Gunnlaugur Thor Briem
|
4f338ed407 | ||
|
Gunnlaugur Thor Briem
|
6fe1cc0874 | ||
|
Thomas Wolf
|
bdd3d0c76d | ||
|
Julien Chaumond
|
c440030e99 | ||
|
Thomas Wolf
|
3b7f95a506 | ||
|
Morgan Funtowicz
|
1bca97ec7f | ||
|
Manuel Romero
|
189113d891 | ||
|
Julien Chaumond
|
76111a3d3a | ||
|
Julien Chaumond
|
a43c388abb | ||
|
Manuel Romero
|
ec60e0ae7a | ||
|
Wissam Antoun
|
6a143bf282 | ||
|
Patrick von Platen
|
932eab943d | ||
|
Julien Chaumond
|
256cbbc4a2 | ||
|
Patrick von Platen
|
006097f8ad | ||
|
Gunnlaugur Thor Briem
|
18f4b9274f | ||
|
Funtowicz MorganandMOI Anthony
|
71c8711970 | ||
|
Patrick von Platen
|
7a89a3e493 | ||
|
Patrick von Platen
|
c4c4c9998a | ||
|
patrickvonplaten
|
2529b2d37e | ||
|
patrickvonplaten
|
61fef6e957 | ||
|
Patrick von Platen
|
34de670dbe | ||
|
Patrick von Platen
|
6701fb7859 | ||
|
Gunnlaugur Thor Briem
|
b1116fd673 | ||
|
Gunnlaugur Thor Briem
|
96c4990165 | ||
|
Gunnlaugur Thor Briem
|
470753bcf5 | ||
|
Gunnlaugur Thor Briem
|
0c716ede8c | ||
|
Sam Shleifer
|
e9e6efdc45 | ||
|
Julien Chaumond
|
f631e01d2c | ||
|
Sam Shleifer
|
5b396457e5 | ||
|
Sam Shleifer
|
5c5af879b6 | ||
|
Gunnlaugur Thor Briem
|
b8da16f390 | ||
|
Gunnlaugur Thor Briem
|
ba28170717 | ||
|
Julien Chaumond
|
a088d75e51 | ||
|
Patrick von Platen
|
4134100363 | ||
|
ali safaya
|
b31f715019 | ||
|
Davide Fiocco
|
c0c7ec3458 | ||
|
Julien Chaumond
|
eec5ec8071 | ||
|
Felix MIKAELIAN
|
6b1558bad8 | ||
|
Julien Chaumond
|
f169957d0c | ||
|
Lysandre Debut
|
d3eb7d23a4 | ||
|
Manuel Romero
|
2c7749784c | ||
|
Julien Chaumond
|
0e56b37e80 | ||
|
Patrick von Platen
|
2fdc7f6ce8 | ||
|
|
13afb71208 | ||
|
Patrick von Platen
|
c0135194eb | ||
|
Sam Shleifer
|
b54ef78d0c | ||
|
Victor SANH
|
6b1ff25084 | ||
|
Julien Chaumond
|
298bed16a8 | ||
|
VictorSanh
|
852e032ca6 | ||
|
VictorSanh
|
b5509abb36 | ||
|
Julien Chaumond
|
d6ef587a10 | ||
|
Julien Chaumond
|
e36bd94345 | ||
|
srush
|
908fa43b54 | ||
|
Lysandre Debut
|
8bcb37bfb8 | ||
|
Sam Shleifer
|
6a37588041 | ||
|
Cola
|
f4ff44a6d9 | ||
|
Martin Malmsten
|
f71157529e | ||
|
Martin Malmsten
|
aceb6a0907 | ||
|
Martin Malmsten
|
d762d4289c | ||
|
Martin Malmsten
|
9495d38b0d | ||
|
Julien Chaumond
|
b370cc7e99 | ||
|
Julien Chaumond
|
f5516805c2 | ||
|
Andrew Walker
|
5bc99e7f33 | ||
|
Patrick von Platen
|
fdd61b1992 | ||
|
Julien ChaumondandSam Shleifer
|
9cda3620b6 | ||
|
Sam Shleifer
|
9df74b8bc4 | ||
|
Lysandre Debut
|
bb7c468520 | ||
|
Patrick von Platen
|
f5b50c6b8e | ||
|
Patrick von Platen
|
ec16142ee5 | ||
|
Patrick von Platen
|
e645dcbb70 | ||
|
Martin Malmsten
|
105dcb4162 | ||
|
Martin Malmsten
|
33eb8a165d | ||
|
Martin Malmsten
|
869b66f6b3 |
@@ -14,22 +14,6 @@ jobs:
|
||||
- run: sudo pip install codecov pytest-cov
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/ --cov
|
||||
- run: codecov
|
||||
run_all_tests_torch_and_tf:
|
||||
working_directory: ~/transformers
|
||||
docker:
|
||||
- image: circleci/python:3.5
|
||||
environment:
|
||||
OMP_NUM_THREADS: 1
|
||||
RUN_SLOW: yes
|
||||
RUN_CUSTOM_TOKENIZERS: yes
|
||||
resource_class: xlarge
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[mecab,sklearn,tf-cpu,torch,testing]
|
||||
- run:
|
||||
command: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
no_output_timeout: 4h
|
||||
|
||||
run_tests_torch:
|
||||
working_directory: ~/transformers
|
||||
@@ -134,13 +118,3 @@ workflows:
|
||||
- run_tests_torch
|
||||
- run_tests_tf
|
||||
- deploy_doc: *workflow_filters
|
||||
run_slow_tests:
|
||||
triggers:
|
||||
- schedule:
|
||||
cron: "0 4 * * *"
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
- master
|
||||
jobs:
|
||||
- run_all_tests_torch_and_tf
|
||||
|
||||
@@ -0,0 +1,19 @@
|
||||
name: GitHub-hosted runner
|
||||
|
||||
on: push
|
||||
|
||||
jobs:
|
||||
check_code_quality:
|
||||
runs-on: ubuntu-18.04
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v1
|
||||
with:
|
||||
python-version: 3.7
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
pip install .[tf,torch,quality]
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,49 @@
|
||||
name: Self-hosted runner (push)
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- master
|
||||
pull_request:
|
||||
|
||||
|
||||
jobs:
|
||||
run_tests_torch_and_tf_gpu:
|
||||
runs-on: self-hosted
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- name: Python version
|
||||
run: |
|
||||
which python
|
||||
python --version
|
||||
pip --version
|
||||
- name: Current dir
|
||||
run: pwd
|
||||
- run: nvidia-smi
|
||||
- name: Create new python env (on self-hosted runners we have to handle isolation ourselves)
|
||||
run: |
|
||||
python -m venv .env
|
||||
source .env/bin/activate
|
||||
which python
|
||||
python --version
|
||||
pip --version
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install .[sklearn,tf,torch,testing]
|
||||
|
||||
- name: Are GPUs recognized by our DL frameworks
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -c "import torch; print(torch.cuda.is_available())"
|
||||
python -c "import tensorflow as tf; print(tf.test.is_built_with_cuda(), tf.config.list_physical_devices('GPU'))"
|
||||
|
||||
- name: Run all non-slow tests on GPU
|
||||
env:
|
||||
TF_FORCE_GPU_ALLOW_GROWTH: "true"
|
||||
# TF_GPU_MEMORY_LIMIT: 4096
|
||||
OMP_NUM_THREADS: 1
|
||||
USE_CUDA: yes
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -m pytest -n 2 --dist=loadfile -s -v ./tests/
|
||||
@@ -0,0 +1,51 @@
|
||||
name: Self-hosted runner (scheduled)
|
||||
|
||||
on:
|
||||
push:
|
||||
branches:
|
||||
- ci_*
|
||||
repository_dispatch:
|
||||
schedule:
|
||||
- cron: "0 0 * * *"
|
||||
|
||||
jobs:
|
||||
run_all_tests_torch_and_tf_gpu:
|
||||
runs-on: self-hosted
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- name: Python version
|
||||
run: |
|
||||
which python
|
||||
python --version
|
||||
pip --version
|
||||
- name: Current dir
|
||||
run: pwd
|
||||
- run: nvidia-smi
|
||||
- name: Create new python env (on self-hosted runners we have to handle isolation ourselves)
|
||||
run: |
|
||||
python -m venv .env
|
||||
source .env/bin/activate
|
||||
which python
|
||||
python --version
|
||||
pip --version
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install .[sklearn,tf,torch,testing]
|
||||
|
||||
- name: Are GPUs recognized by our DL frameworks
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -c "import torch; print(torch.cuda.is_available())"
|
||||
python -c "import tensorflow as tf; print(tf.test.is_built_with_cuda(), tf.config.list_physical_devices('GPU'))"
|
||||
|
||||
- name: Run all tests on GPU
|
||||
env:
|
||||
TF_FORCE_GPU_ALLOW_GROWTH: "true"
|
||||
OMP_NUM_THREADS: 1
|
||||
RUN_SLOW: yes
|
||||
USE_CUDA: yes
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -m pytest -n 1 --dist=loadfile -s -v ./tests/
|
||||
|
||||
@@ -1,7 +0,0 @@
|
||||
FROM pytorch/pytorch:latest
|
||||
|
||||
RUN git clone https://github.com/NVIDIA/apex.git && cd apex && python setup.py install --cuda_ext --cpp_ext
|
||||
|
||||
RUN pip install transformers
|
||||
|
||||
WORKDIR /workspace
|
||||
@@ -0,0 +1,26 @@
|
||||
FROM ubuntu:18.04
|
||||
LABEL maintainer="Hugging Face"
|
||||
LABEL repository="transformers"
|
||||
|
||||
RUN apt update && \
|
||||
apt install -y bash \
|
||||
build-essential \
|
||||
git \
|
||||
curl \
|
||||
ca-certificates \
|
||||
python3 \
|
||||
python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
||||
python3 -m pip install --no-cache-dir \
|
||||
jupyter \
|
||||
tensorflow-cpu \
|
||||
torch
|
||||
|
||||
WORKDIR /workspace
|
||||
COPY . transformers/
|
||||
RUN cd transformers/ && \
|
||||
python3 -m pip install --no-cache-dir .
|
||||
|
||||
CMD ["/bin/bash"]
|
||||
@@ -0,0 +1,26 @@
|
||||
FROM nvidia/cuda:10.1-cudnn7-runtime-ubuntu18.04
|
||||
LABEL maintainer="Hugging Face"
|
||||
LABEL repository="transformers"
|
||||
|
||||
RUN apt update && \
|
||||
apt install -y bash \
|
||||
build-essential \
|
||||
git \
|
||||
curl \
|
||||
ca-certificates \
|
||||
python3 \
|
||||
python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
||||
python3 -m pip install --no-cache-dir \
|
||||
jupyter \
|
||||
tensorflow \
|
||||
torch
|
||||
|
||||
WORKDIR /workspace
|
||||
COPY . transformers/
|
||||
RUN cd transformers/ && \
|
||||
python3 -m pip install --no-cache-dir .
|
||||
|
||||
CMD ["/bin/bash"]
|
||||
@@ -0,0 +1,25 @@
|
||||
FROM ubuntu:18.04
|
||||
LABEL maintainer="Hugging Face"
|
||||
LABEL repository="transformers"
|
||||
|
||||
RUN apt update && \
|
||||
apt install -y bash \
|
||||
build-essential \
|
||||
git \
|
||||
curl \
|
||||
ca-certificates \
|
||||
python3 \
|
||||
python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
||||
python3 -m pip install --no-cache-dir \
|
||||
jupyter \
|
||||
torch
|
||||
|
||||
WORKDIR /workspace
|
||||
COPY . transformers/
|
||||
RUN cd transformers/ && \
|
||||
python3 -m pip install --no-cache-dir .
|
||||
|
||||
CMD ["/bin/bash"]
|
||||
@@ -0,0 +1,25 @@
|
||||
FROM nvidia/cuda:10.1-cudnn7-runtime-ubuntu18.04
|
||||
LABEL maintainer="Hugging Face"
|
||||
LABEL repository="transformers"
|
||||
|
||||
RUN apt update && \
|
||||
apt install -y bash \
|
||||
build-essential \
|
||||
git \
|
||||
curl \
|
||||
ca-certificates \
|
||||
python3 \
|
||||
python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
||||
python3 -m pip install --no-cache-dir \
|
||||
mkl \
|
||||
torch
|
||||
|
||||
WORKDIR /workspace
|
||||
COPY . transformers/
|
||||
RUN cd transformers/ && \
|
||||
python3 -m pip install --no-cache-dir .
|
||||
|
||||
CMD ["/bin/bash"]
|
||||
@@ -0,0 +1,25 @@
|
||||
FROM ubuntu:18.04
|
||||
LABEL maintainer="Hugging Face"
|
||||
LABEL repository="transformers"
|
||||
|
||||
RUN apt update && \
|
||||
apt install -y bash \
|
||||
build-essential \
|
||||
git \
|
||||
curl \
|
||||
ca-certificates \
|
||||
python3 \
|
||||
python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
||||
python3 -m pip install --no-cache-dir \
|
||||
mkl \
|
||||
tensorflow-cpu
|
||||
|
||||
WORKDIR /workspace
|
||||
COPY . transformers/
|
||||
RUN cd transformers/ && \
|
||||
python3 -m pip install --no-cache-dir .
|
||||
|
||||
CMD ["/bin/bash"]
|
||||
@@ -0,0 +1,25 @@
|
||||
FROM nvidia/cuda:10.1-cudnn7-runtime-ubuntu18.04
|
||||
LABEL maintainer="Hugging Face"
|
||||
LABEL repository="transformers"
|
||||
|
||||
RUN apt update && \
|
||||
apt install -y bash \
|
||||
build-essential \
|
||||
git \
|
||||
curl \
|
||||
ca-certificates \
|
||||
python3 \
|
||||
python3-pip && \
|
||||
rm -rf /var/lib/apt/lists
|
||||
|
||||
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
||||
python3 -m pip install --no-cache-dir \
|
||||
mkl \
|
||||
tensorflow
|
||||
|
||||
WORKDIR /workspace
|
||||
COPY . transformers/
|
||||
RUN cd transformers/ && \
|
||||
python3 -m pip install --no-cache-dir .
|
||||
|
||||
CMD ["/bin/bash"]
|
||||
@@ -80,6 +80,7 @@ The library currently contains PyTorch and Tensorflow implementations, pre-train
|
||||
main_classes/configuration
|
||||
main_classes/model
|
||||
main_classes/tokenizer
|
||||
main_classes/pipelines
|
||||
main_classes/optimizer_schedules
|
||||
main_classes/processors
|
||||
|
||||
|
||||
@@ -0,0 +1,63 @@
|
||||
Pipelines
|
||||
----------------------------------------------------
|
||||
|
||||
The pipelines are a great and easy way to use models for inference. These pipelines are objects that abstract most
|
||||
of the complex code from the library, offering a simple API dedicated to several tasks, including Named Entity
|
||||
Recognition, Masked Language Modeling, Sentiment Analysis, Feature Extraction and Question Answering.
|
||||
|
||||
There are two categories of pipeline abstractions to be aware about:
|
||||
|
||||
- The :class:`~transformers.pipeline` which is the most powerful object encapsulating all other pipelines
|
||||
- The other task-specific pipelines, such as :class:`~transformers.NerPipeline`
|
||||
or :class:`~transformers.QuestionAnsweringPipeline`
|
||||
|
||||
The pipeline abstraction
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
The `pipeline` abstraction is a wrapper around all the other available pipelines. It is instantiated as any
|
||||
other pipeline but requires an additional argument which is the `task`.
|
||||
|
||||
.. autoclass:: transformers.pipeline
|
||||
:members:
|
||||
|
||||
|
||||
The task specific pipelines
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Parent class: Pipeline
|
||||
=========================================
|
||||
|
||||
.. autoclass:: transformers.Pipeline
|
||||
:members: predict, transform, save_pretrained
|
||||
|
||||
NerPipeline
|
||||
==========================================
|
||||
|
||||
.. autoclass:: transformers.NerPipeline
|
||||
|
||||
TokenClassificationPipeline
|
||||
==========================================
|
||||
|
||||
This class is an alias of the :class:`~transformers.NerPipeline` defined above. Please refer to that pipeline for
|
||||
documentation and usage examples.
|
||||
|
||||
FillMaskPipeline
|
||||
==========================================
|
||||
|
||||
.. autoclass:: transformers.FillMaskPipeline
|
||||
|
||||
FeatureExtractionPipeline
|
||||
==========================================
|
||||
|
||||
.. autoclass:: transformers.FeatureExtractionPipeline
|
||||
|
||||
TextClassificationPipeline
|
||||
==========================================
|
||||
|
||||
.. autoclass:: transformers.TextClassificationPipeline
|
||||
|
||||
QuestionAnsweringPipeline
|
||||
==========================================
|
||||
|
||||
.. autoclass:: transformers.QuestionAnsweringPipeline
|
||||
|
||||
@@ -4,33 +4,42 @@ Bart
|
||||
file a `Github Issue <https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title>`__ and assign
|
||||
@sshleifer
|
||||
|
||||
The Bart model was `proposed <https://arxiv.org/abs/1910.13461>`_ by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov, Luke Zettlemoyer on 29 Oct, 2019.
|
||||
It is a sequence to sequence model where both encoder and decoder are transformers. The paper also introduces a novel pretraining objective, and demonstrates excellent summarization results.
|
||||
The authors released their code `here <https://github.com/pytorch/fairseq/tree/master/examples/bart>`_
|
||||
Paper
|
||||
~~~~~
|
||||
The Bart model was `proposed <https://arxiv.org/abs/1910.13461>`_ by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer on 29 Oct, 2019.
|
||||
According to the abstract,
|
||||
|
||||
**Abstract:**
|
||||
- Bart uses a standard seq2seq/machine translation architecture with a bidirectional encoder (like BERT) and a left-to-right decoder (like GPT).
|
||||
- The pretraining task involves randomly shuffling the order of the original sentences and a novel in-filling scheme, where spans of text are replaced with a single mask token.
|
||||
- BART is particularly effective when fine tuned for text generation but also works well for comprehension tasks. It matches the performance of RoBERTa with comparable training resources on GLUE and SQuAD, achieves new state-of-the-art results on a range of abstractive dialogue, question answering, and summarization tasks, with gains of up to 6 ROUGE.
|
||||
|
||||
*We present BART, a denoising autoencoder for pretraining sequence-to-sequence models. BART is trained by (1) corrupting text with an arbitrary noising function, and (2) learning a model to reconstruct the original text. It uses a standard Tranformer-based neural machine translation architecture which, despite its simplicity, can be seen as generalizing BERT (due to the bidirectional encoder), GPT (with the left-to-right decoder), and many other more recent pretraining schemes. We evaluate a number of noising approaches, finding the best performance by both randomly shuffling the order of the original sentences and using a novel in-filling scheme, where spans of text are replaced with a single mask token. BART is particularly effective when fine tuned for text generation but also works well for comprehension tasks. It matches the performance of RoBERTa with comparable training resources on GLUE and SQuAD, achieves new state-of-the-art results on a range of abstractive dialogue, question answering, and summarization tasks, with gains of up to 6 ROUGE. BART also provides a 1.1 BLEU increase over a back-translation system for machine translation, with only target language pretraining. We also report ablation experiments that replicate other pretraining schemes within the BART framework, to better measure which factors most influence end-task performance.*
|
||||
`BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension`
|
||||
The Authors' code can be found `here <https://github.com/pytorch/fairseq/tree/master/examples/bart>`_
|
||||
|
||||
|
||||
Implementation Notes
|
||||
~~~~~~~~~~~~~~~~~~~~
|
||||
- Bart doesn't use :obj:`token_type_ids` for sequence classification. Use BartTokenizer.encode to get the proper splitting.
|
||||
- The forward pass of ``BartModel`` will create decoder inputs (using the helper function ``transformers.modeling_bart._prepare_bart_decoder_inputs``) if they are not passed. This is different than some other modeling APIs.
|
||||
- Model predictions are intended to be identical to the original implementation. This only works, however, if the string you pass to ``fairseq.encode`` starts with a space.
|
||||
- ``BartForConditionalGeneration.generate`` should be used for conditional generation tasks like summarization, see the example in that docstrings
|
||||
- Models that load the ``"bart-large-cnn"`` weights will not have a ``mask_token_id``, or be able to perform mask filling tasks.
|
||||
|
||||
|
||||
Notes:
|
||||
- Bart doesn't use :obj:`token_type_ids`, for sequence classification just use BartTokenizer.encode to get the proper splitting.
|
||||
- Inputs to the decoder are created by BartModel.forward if they are not passed. This is different than some other model APIs.
|
||||
- Model predictions are intended to be identical to the original implementation. This only works, however, if the string you pass to fairseq.encode starts with a space.
|
||||
|
||||
BartModel
|
||||
~~~~~~~~~~~~~~~~~~~~
|
||||
~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartModel
|
||||
:members: forward
|
||||
|
||||
.. autofunction:: transformers.modeling_bart._prepare_bart_decoder_inputs
|
||||
|
||||
BartForMaskedLM
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartForMaskedLM
|
||||
:members: forward
|
||||
BartForConditionalGeneration
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartForConditionalGeneration
|
||||
:members: generate, forward
|
||||
|
||||
|
||||
BartForSequenceClassification
|
||||
@@ -45,8 +54,3 @@ BartConfig
|
||||
.. autoclass:: transformers.BartConfig
|
||||
:members:
|
||||
|
||||
Automatic Creation of Decoder Inputs
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
This is enabled by default
|
||||
|
||||
.. autofunction:: transformers.modeling_bart._prepare_bart_decoder_inputs
|
||||
|
||||
@@ -47,6 +47,7 @@ The different languages this model/tokenizer handles, as well as the ids of thes
|
||||
|
||||
.. code-block::
|
||||
|
||||
# Continuation of the previous script
|
||||
print(tokenizer.lang2id) # {'en': 0, 'fr': 1}
|
||||
|
||||
|
||||
@@ -54,6 +55,7 @@ These ids should be used when passing a language parameter during a model pass.
|
||||
|
||||
.. code-block::
|
||||
|
||||
# Continuation of the previous script
|
||||
input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size of 1
|
||||
|
||||
|
||||
@@ -62,6 +64,7 @@ filled with the appropriate language ids, of the same size as input_ids. For eng
|
||||
|
||||
.. code-block::
|
||||
|
||||
# Continuation of the previous script
|
||||
language_id = tokenizer.lang2id['en'] # 0
|
||||
langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
|
||||
|
||||
@@ -73,6 +76,7 @@ You can then feed it all as input to your model:
|
||||
|
||||
.. code-block::
|
||||
|
||||
# Continuation of the previous script
|
||||
outputs = model(input_ids, langs=langs)
|
||||
|
||||
|
||||
|
||||
@@ -280,7 +280,10 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | | (see `details <https://github.com/pytorch/fairseq/tree/master/examples/bart>`_) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``bart-large-mnli`` | | Adds a 2 layer classification head with 1 million parameters |
|
||||
| | | | bart-large base architecture with a classification head |
|
||||
| | | | bart-large base architecture with a classification head, finetuned on MNLI |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``bart-large-cnn`` | | 12-layer, 1024-hidden, 16-heads, 406M parameters (same as base) |
|
||||
| | | | bart-large base architecture finetuned on cnn summarization task |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
|
||||
|
||||
|
||||
@@ -220,96 +220,3 @@ print(sequence)
|
||||
```
|
||||
|
||||
The model only requires a single token as input as all the previous tokens' key/value pairs are contained in the `past`.
|
||||
|
||||
### Model2Model example
|
||||
|
||||
Encoder-decoder architectures require two tokenized inputs: one for the encoder and the other one for the decoder. Let's assume that we want to use `Model2Model` for generative question answering, and start by tokenizing the question and answer that will be fed to the model.
|
||||
|
||||
```python
|
||||
import torch
|
||||
from transformers import BertTokenizer, Model2Model
|
||||
|
||||
# OPTIONAL: if you want to have more information on what's happening under the hood, activate the logger as follows
|
||||
import logging
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
|
||||
# Load pre-trained model tokenizer (vocabulary)
|
||||
tokenizer = BertTokenizer.from_pretrained('bert-base-uncased')
|
||||
|
||||
# Encode the input to the encoder (the question)
|
||||
question = "Who was Jim Henson?"
|
||||
encoded_question = tokenizer.encode(question)
|
||||
|
||||
# Encode the input to the decoder (the answer)
|
||||
answer = "Jim Henson was a puppeteer"
|
||||
encoded_answer = tokenizer.encode(answer)
|
||||
|
||||
# Convert inputs to PyTorch tensors
|
||||
question_tensor = torch.tensor([encoded_question])
|
||||
answer_tensor = torch.tensor([encoded_answer])
|
||||
```
|
||||
|
||||
Let's see how we can use `Model2Model` to get the value of the loss associated with this (question, answer) pair:
|
||||
|
||||
```python
|
||||
# In order to compute the loss we need to provide language model
|
||||
# labels (the token ids that the model should have produced) to
|
||||
# the decoder.
|
||||
lm_labels = encoded_answer
|
||||
labels_tensor = torch.tensor([lm_labels])
|
||||
|
||||
# Load pre-trained model (weights)
|
||||
model = Model2Model.from_pretrained('bert-base-uncased')
|
||||
|
||||
# Set the model in evaluation mode to deactivate the DropOut modules
|
||||
# This is IMPORTANT to have reproducible results during evaluation!
|
||||
model.eval()
|
||||
|
||||
# If you have a GPU, put everything on cuda
|
||||
question_tensor = question_tensor.to('cuda')
|
||||
answer_tensor = answer_tensor.to('cuda')
|
||||
labels_tensor = labels_tensor.to('cuda')
|
||||
model.to('cuda')
|
||||
|
||||
# Predict hidden states features for each layer
|
||||
with torch.no_grad():
|
||||
# See the models docstrings for the detail of the inputs
|
||||
outputs = model(question_tensor, answer_tensor, decoder_lm_labels=labels_tensor)
|
||||
# Transformers models always output tuples.
|
||||
# See the models docstrings for the detail of all the outputs
|
||||
# In our case, the first element is the value of the LM loss
|
||||
lm_loss = outputs[0]
|
||||
```
|
||||
|
||||
This loss can be used to fine-tune `Model2Model` on the question answering task. Assuming that we fine-tuned the model, let us now see how to generate an answer:
|
||||
|
||||
```python
|
||||
# Let's re-use the previous question
|
||||
question = "Who was Jim Henson?"
|
||||
encoded_question = tokenizer.encode(question)
|
||||
question_tensor = torch.tensor([encoded_question])
|
||||
|
||||
# This time we try to generate the answer, so we start with an empty sequence
|
||||
answer = "[CLS]"
|
||||
encoded_answer = tokenizer.encode(answer, add_special_tokens=False)
|
||||
answer_tensor = torch.tensor([encoded_answer])
|
||||
|
||||
# Load pre-trained model (weights)
|
||||
model = Model2Model.from_pretrained('fine-tuned-weights')
|
||||
model.eval()
|
||||
|
||||
# If you have a GPU, put everything on cuda
|
||||
question_tensor = question_tensor.to('cuda')
|
||||
answer_tensor = answer_tensor.to('cuda')
|
||||
model.to('cuda')
|
||||
|
||||
# Predict all tokens
|
||||
with torch.no_grad():
|
||||
outputs = model(question_tensor, answer_tensor)
|
||||
predictions = outputs[0]
|
||||
|
||||
# confirm we were able to predict 'jim'
|
||||
predicted_index = torch.argmax(predictions[0, -1]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
assert predicted_token == 'jim'
|
||||
```
|
||||
|
||||
+1
-1
@@ -379,7 +379,7 @@ export SQUAD_DIR=/path/to/SQUAD
|
||||
|
||||
python run_squad.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path bert-base-cased \
|
||||
--model_name_or_path bert-base-uncased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
|
||||
@@ -622,7 +622,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -10,14 +10,14 @@ This folder contains the original code used to train Distil* as well as examples
|
||||
|
||||
**October 23, 2019 - Update** We release **DistilRoBERTa**: 95% of `RoBERTa-base`'s performance on GLUE, twice as fast as RoBERTa while being 35% smaller.
|
||||
|
||||
**October 3, 2019 - Update** We release our [NeurIPS workshop paper](https://arxiv.org/abs/1910.01108) explaining our approach on **DistilBERT**. It includes updated results and further experiments. We applied the same method to GPT2 and release the weights of **DistilGPT2**. DistilGPT2 is two times faster and 33% smaller than GPT2. **The paper superseeds our [previous blogpost](https://medium.com/huggingface/distilbert-8cf3380435b5) with a different distillation loss and better performances. Please use the paper as a reference when comparing/reporting results on DistilBERT.**
|
||||
**October 3, 2019 - Update** We release our [NeurIPS workshop paper](https://arxiv.org/abs/1910.01108) explaining our approach on **DistilBERT**. It includes updated results and further experiments. We applied the same method to GPT2 and release the weights of **DistilGPT2**. DistilGPT2 is two times faster and 33% smaller than GPT2. **The paper supersedes our [previous blogpost](https://medium.com/huggingface/distilbert-8cf3380435b5) with a different distillation loss and better performances. Please use the paper as a reference when comparing/reporting results on DistilBERT.**
|
||||
|
||||
**September 19, 2019 - Update:** We fixed bugs in the code and released an upadted version of the weights trained with a modification of the distillation loss. DistilBERT now reaches 99% of `BERT-base`'s performance on GLUE, and 86.9 F1 score on SQuAD v1.1 dev set (compared to 88.5 for `BERT-base`). We will publish a formal write-up of our approach in the near future!
|
||||
|
||||
|
||||
## What is Distil*
|
||||
|
||||
Distil* is a class of compressed models that started with DistilBERT. DistilBERT stands for Distillated-BERT. DistilBERT is a small, fast, cheap and light Transformer model based on Bert architecture. It has 40% less parameters than `bert-base-uncased`, runs 60% faster while preserving 99% of BERT's performances as measured on the GLUE language understanding benchmark. DistilBERT is trained using knowledge distillation, a technique to compress a large model called the teacher into a smaller model called the student. By distillating Bert, we obtain a smaller Transformer model that bears a lot of similarities with the original BERT model while being lighter, smaller and faster to run. DistilBERT is thus an interesting option to put large-scaled trained Transformer model into production.
|
||||
Distil* is a class of compressed models that started with DistilBERT. DistilBERT stands for Distillated-BERT. DistilBERT is a small, fast, cheap and light Transformer model based on Bert architecture. It has 40% less parameters than `bert-base-uncased`, runs 60% faster while preserving 97% of BERT's performances as measured on the GLUE language understanding benchmark. DistilBERT is trained using knowledge distillation, a technique to compress a large model called the teacher into a smaller model called the student. By distillating Bert, we obtain a smaller Transformer model that bears a lot of similarities with the original BERT model while being lighter, smaller and faster to run. DistilBERT is thus an interesting option to put large-scaled trained Transformer model into production.
|
||||
|
||||
We have applied the same method to other Transformer architectures and released the weights:
|
||||
- GPT2: on the [WikiText-103](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/) benchmark, GPT2 reaches a perplexity on the test set of 16.3 compared to 21.1 for **DistilGPT2** (after fine-tuning on the train set).
|
||||
@@ -31,15 +31,15 @@ Here are the results on the dev sets of GLUE:
|
||||
|
||||
| Model | Macro-score | CoLA | MNLI | MRPC | QNLI | QQP | RTE | SST-2| STS-B| WNLI |
|
||||
| :---: | :---: | :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---: |
|
||||
| BERT-base-uncased | **74.9** | 49.2 | 80.8 | 87.4 | 87.5 | 86.4 | 61.7 | 92.0 | 83.8 | 45.1 |
|
||||
| DistilBERT-base-uncased | **74.3** | 43.6 | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 | 56.3 |
|
||||
| BERT-base-uncased | **79.5** | 56.3 | 84.7 | 88.6 | 91.8 | 89.6 | 69.3 | 92.7 | 89.0 | 53.5 |
|
||||
| DistilBERT-base-uncased | **77.0** | 51.3 | 82.1 | 87.5 | 89.2 | 88.5 | 59.9 | 91.3 | 86.9 | 56.3 |
|
||||
| BERT-base-cased | **78.2** | 58.2 | 83.9 | 87.8 | 91.0 | 89.2 | 66.1 | 91.7 | 89.2 | 46.5 |
|
||||
| DistilBERT-base-cased | **75.9** | 47.2 | 81.5 | 85.6 | 88.2 | 87.8 | 60.6 | 90.4 | 85.5 | 56.3 |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| RoBERTa-base (reported) | **83.2**/**86.4**<sup>2</sup> | 63.6 | 87.6 | 90.2 | 92.8 | 91.9 | 78.7 | 94.8 | 91.2 | 57.7<sup>3</sup> |
|
||||
| DistilRoBERTa<sup>1</sup> | **79.0**/**82.3**<sup>2</sup> | 59.3 | 84.0 | 86.6 | 90.8 | 89.4 | 67.9 | 92.5 | 88.3 | 52.1 |
|
||||
|
||||
<sup>1</sup> We did not use the MNLI checkpoint for fine-tuning but directy perform transfer learning on the pre-trained DistilRoBERTa.
|
||||
<sup>1</sup> We did not use the MNLI checkpoint for fine-tuning but directly perform transfer learning on the pre-trained DistilRoBERTa.
|
||||
|
||||
<sup>2</sup> Macro-score computed without WNLI.
|
||||
|
||||
@@ -65,9 +65,9 @@ This part of the library has only be tested with Python3.6+. There are few speci
|
||||
Transformers includes five pre-trained Distil* models, currently only provided for English and German (we are investigating the possibility to train and release a multilingual version of DistilBERT):
|
||||
|
||||
- `distilbert-base-uncased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-uncased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 66M parameters.
|
||||
- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 79.8 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 82.3 F1 score).
|
||||
- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knowledge distillation on SQuAD 1.0. This model reaches a F1 score of 86.9 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 88.5 F1 score).
|
||||
- `distilbert-base-cased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-cased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 65M parameters.
|
||||
- `distilbert-base-cased-distilled-squad`: A finetuned version of `distilbert-base-cased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 87.1 on the dev set (for comparison, Bert `bert-base-cased` version reaches a 88.7 F1 score).
|
||||
- `distilbert-base-cased-distilled-squad`: A finetuned version of `distilbert-base-cased` finetuned using (a second step of) knowledge distillation on SQuAD 1.0. This model reaches a F1 score of 87.1 on the dev set (for comparison, Bert `bert-base-cased` version reaches a 88.7 F1 score).
|
||||
- `distilbert-base-german-cased`: DistilBERT German language model pretrained on 1/2 of the data used to pretrain Bert using distillation with the supervision of the `bert-base-german-dbmdz-cased` version of German DBMDZ Bert. For NER tasks the model reaches a F1 score of 83.49 on the CoNLL-2003 test set (for comparison, `bert-base-german-dbmdz-cased` reaches a 84.52 F1 score), and a F1 score of 85.23 on the GermEval 2014 test set (`bert-base-german-dbmdz-cased` reaches a 86.89 F1 score).
|
||||
- `distilgpt2`: DistilGPT2 English language model pretrained with the supervision of `gpt2` (the smallest version of GPT2) on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset. The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 124M parameters for GPT2). On average, DistilGPT2 is two times faster than GPT2.
|
||||
- `distilroberta-base`: DistilRoBERTa English language model pretrained with the supervision of `roberta-base` solely on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset (it is ~4 times less training data than the teacher RoBERTa). The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 125M parameters for RoBERTa-base). On average DistilRoBERTa is twice as fast as Roberta-base.
|
||||
@@ -111,7 +111,7 @@ python scripts/binarized_data.py \
|
||||
--dump_file data/binarized_text
|
||||
```
|
||||
|
||||
Our implementation of masked language modeling loss follows [XLM](https://github.com/facebookresearch/XLM)'s one and smoothes the probability of masking with a factor that put more emphasis on rare words. Thus we count the occurences of each tokens in the data:
|
||||
Our implementation of masked language modeling loss follows [XLM](https://github.com/facebookresearch/XLM)'s one and smoothes the probability of masking with a factor that put more emphasis on rare words. Thus we count the occurrences of each tokens in the data:
|
||||
|
||||
```bash
|
||||
python scripts/token_counts.py \
|
||||
|
||||
@@ -39,6 +39,9 @@ from transformers import (
|
||||
DistilBertConfig,
|
||||
DistilBertForQuestionAnswering,
|
||||
DistilBertTokenizer,
|
||||
RobertaConfig,
|
||||
RobertaForQuestionAnswering,
|
||||
RobertaTokenizer,
|
||||
XLMConfig,
|
||||
XLMForQuestionAnswering,
|
||||
XLMTokenizer,
|
||||
@@ -73,6 +76,7 @@ MODEL_CLASSES = {
|
||||
"xlnet": (XLNetConfig, XLNetForQuestionAnswering, XLNetTokenizer),
|
||||
"xlm": (XLMConfig, XLMForQuestionAnswering, XLMTokenizer),
|
||||
"distilbert": (DistilBertConfig, DistilBertForQuestionAnswering, DistilBertTokenizer),
|
||||
"roberta": (RobertaConfig, RobertaForQuestionAnswering, RobertaTokenizer),
|
||||
}
|
||||
|
||||
|
||||
@@ -716,7 +720,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -520,7 +520,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -492,7 +492,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
+19
-5
@@ -33,6 +33,9 @@ from tqdm import tqdm, trange
|
||||
from transformers import (
|
||||
WEIGHTS_NAME,
|
||||
AdamW,
|
||||
AlbertConfig,
|
||||
AlbertForTokenClassification,
|
||||
AlbertTokenizer,
|
||||
BertConfig,
|
||||
BertForTokenClassification,
|
||||
BertTokenizer,
|
||||
@@ -70,6 +73,7 @@ ALL_MODELS = sum(
|
||||
)
|
||||
|
||||
MODEL_CLASSES = {
|
||||
"albert": (AlbertConfig, AlbertForTokenClassification, AlbertTokenizer),
|
||||
"bert": (BertConfig, BertForTokenClassification, BertTokenizer),
|
||||
"roberta": (RobertaConfig, RobertaForTokenClassification, RobertaTokenizer),
|
||||
"distilbert": (DistilBertConfig, DistilBertForTokenClassification, DistilBertTokenizer),
|
||||
@@ -77,6 +81,8 @@ MODEL_CLASSES = {
|
||||
"xlmroberta": (XLMRobertaConfig, XLMRobertaForTokenClassification, XLMRobertaTokenizer),
|
||||
}
|
||||
|
||||
TOKENIZER_ARGS = ["do_lower_case", "strip_accents", "keep_accents", "use_fast"]
|
||||
|
||||
|
||||
def set_seed(args):
|
||||
random.seed(args.seed)
|
||||
@@ -462,7 +468,13 @@ def main():
|
||||
parser.add_argument(
|
||||
"--do_lower_case", action="store_true", help="Set this flag if you are using an uncased model."
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--keep_accents", action="store_const", const=True, help="Set this flag if model is trained with accents."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--strip_accents", action="store_const", const=True, help="Set this flag if model is trained without accents."
|
||||
)
|
||||
parser.add_argument("--use_fast", action="store_const", const=True, help="Set this flag to use fast tokenization.")
|
||||
parser.add_argument("--per_gpu_train_batch_size", default=8, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument(
|
||||
"--per_gpu_eval_batch_size", default=8, type=int, help="Batch size per GPU/CPU for evaluation."
|
||||
@@ -545,7 +557,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
@@ -590,10 +602,12 @@ def main():
|
||||
label2id={label: i for i, label in enumerate(labels)},
|
||||
cache_dir=args.cache_dir if args.cache_dir else None,
|
||||
)
|
||||
tokenizer_args = {k: v for k, v in vars(args).items() if v is not None and k in TOKENIZER_ARGS}
|
||||
logger.info("Tokenizer arguments: %s", tokenizer_args)
|
||||
tokenizer = tokenizer_class.from_pretrained(
|
||||
args.tokenizer_name if args.tokenizer_name else args.model_name_or_path,
|
||||
do_lower_case=args.do_lower_case,
|
||||
cache_dir=args.cache_dir if args.cache_dir else None,
|
||||
**tokenizer_args,
|
||||
)
|
||||
model = model_class.from_pretrained(
|
||||
args.model_name_or_path,
|
||||
@@ -636,7 +650,7 @@ def main():
|
||||
# Evaluation
|
||||
results = {}
|
||||
if args.do_eval and args.local_rank in [-1, 0]:
|
||||
tokenizer = tokenizer_class.from_pretrained(args.output_dir, do_lower_case=args.do_lower_case)
|
||||
tokenizer = tokenizer_class.from_pretrained(args.output_dir, **tokenizer_args)
|
||||
checkpoints = [args.output_dir]
|
||||
if args.eval_all_checkpoints:
|
||||
checkpoints = list(
|
||||
@@ -658,7 +672,7 @@ def main():
|
||||
writer.write("{} = {}\n".format(key, str(results[key])))
|
||||
|
||||
if args.do_predict and args.local_rank in [-1, 0]:
|
||||
tokenizer = tokenizer_class.from_pretrained(args.output_dir, do_lower_case=args.do_lower_case)
|
||||
tokenizer = tokenizer_class.from_pretrained(args.output_dir, **tokenizer_args)
|
||||
model = model_class.from_pretrained(args.output_dir)
|
||||
model.to(args.device)
|
||||
result, predictions = evaluate(args, model, tokenizer, labels, pad_token_label_id, mode="test")
|
||||
|
||||
+15
-1
@@ -1,6 +1,20 @@
|
||||
# Require pytorch-lightning=0.6
|
||||
# Install newest ptl.
|
||||
pip install -U git+http://github.com/PyTorchLightning/pytorch-lightning/
|
||||
|
||||
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-train.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-dev.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-test.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
|
||||
wget "https://raw.githubusercontent.com/stefan-it/fine-tuned-berts-seq/master/scripts/preprocess.py"
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
python3 preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
|
||||
python3 preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
|
||||
python3 preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
|
||||
cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
|
||||
+54
-70
@@ -7,8 +7,7 @@ import numpy as np
|
||||
import torch
|
||||
from seqeval.metrics import f1_score, precision_score, recall_score
|
||||
from torch.nn import CrossEntropyLoss
|
||||
from torch.utils.data import DataLoader, RandomSampler, SequentialSampler, TensorDataset
|
||||
from torch.utils.data.distributed import DistributedSampler
|
||||
from torch.utils.data import DataLoader, TensorDataset
|
||||
|
||||
from transformer_base import BaseTransformer, add_generic_args, generic_train
|
||||
from utils_ner import convert_examples_to_features, get_labels, read_examples_from_file
|
||||
@@ -25,13 +24,14 @@ class NERTransformer(BaseTransformer):
|
||||
def __init__(self, hparams):
|
||||
self.labels = get_labels(hparams.labels)
|
||||
num_labels = len(self.labels)
|
||||
self.pad_token_label_id = CrossEntropyLoss().ignore_index
|
||||
super(NERTransformer, self).__init__(hparams, num_labels)
|
||||
|
||||
def forward(self, **inputs):
|
||||
return self.model(**inputs)
|
||||
|
||||
def training_step(self, batch, batch_num):
|
||||
"Compute loss"
|
||||
"Compute loss and log."
|
||||
inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
|
||||
if self.hparams.model_type != "distilbert":
|
||||
inputs["token_type_ids"] = (
|
||||
@@ -40,25 +40,61 @@ class NERTransformer(BaseTransformer):
|
||||
|
||||
outputs = self.forward(**inputs)
|
||||
loss = outputs[0]
|
||||
|
||||
tensorboard_logs = {"loss": loss, "rate": self.lr_scheduler.get_last_lr()[-1]}
|
||||
return {"loss": loss, "log": tensorboard_logs}
|
||||
|
||||
def _feature_file(self, mode):
|
||||
return os.path.join(
|
||||
self.hparams.data_dir,
|
||||
"cached_{}_{}_{}".format(
|
||||
mode,
|
||||
list(filter(None, self.hparams.model_name_or_path.split("/"))).pop(),
|
||||
str(self.hparams.max_seq_length),
|
||||
),
|
||||
)
|
||||
|
||||
def prepare_data(self):
|
||||
"Called to initialize data. Use the call to construct features"
|
||||
args = self.hparams
|
||||
for mode in ["train", "dev", "test"]:
|
||||
cached_features_file = self._feature_file(mode)
|
||||
if not os.path.exists(cached_features_file):
|
||||
logger.info("Creating features from dataset file at %s", args.data_dir)
|
||||
examples = read_examples_from_file(args.data_dir, mode)
|
||||
features = convert_examples_to_features(
|
||||
examples,
|
||||
self.labels,
|
||||
args.max_seq_length,
|
||||
self.tokenizer,
|
||||
cls_token_at_end=bool(args.model_type in ["xlnet"]),
|
||||
cls_token=self.tokenizer.cls_token,
|
||||
cls_token_segment_id=2 if args.model_type in ["xlnet"] else 0,
|
||||
sep_token=self.tokenizer.sep_token,
|
||||
sep_token_extra=bool(args.model_type in ["roberta"]),
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]),
|
||||
pad_token=self.tokenizer.convert_tokens_to_ids([self.tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token_label_id=self.pad_token_label_id,
|
||||
)
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
torch.save(features, cached_features_file)
|
||||
|
||||
def load_dataset(self, mode, batch_size):
|
||||
labels = get_labels(self.hparams.labels)
|
||||
self.pad_token_label_id = CrossEntropyLoss().ignore_index
|
||||
dataset = self.load_and_cache_examples(labels, self.pad_token_label_id, mode)
|
||||
if mode == "train":
|
||||
if self.hparams.n_gpu > 1:
|
||||
sampler = DistributedSampler(dataset)
|
||||
else:
|
||||
sampler = RandomSampler(dataset)
|
||||
else:
|
||||
sampler = SequentialSampler(dataset)
|
||||
dataloader = DataLoader(dataset, sampler=sampler, batch_size=batch_size)
|
||||
return dataloader
|
||||
"Load datasets. Called after prepare data."
|
||||
cached_features_file = self._feature_file(mode)
|
||||
logger.info("Loading features from cached file %s", cached_features_file)
|
||||
features = torch.load(cached_features_file)
|
||||
all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
|
||||
all_input_mask = torch.tensor([f.input_mask for f in features], dtype=torch.long)
|
||||
all_segment_ids = torch.tensor([f.segment_ids for f in features], dtype=torch.long)
|
||||
all_label_ids = torch.tensor([f.label_ids for f in features], dtype=torch.long)
|
||||
return DataLoader(
|
||||
TensorDataset(all_input_ids, all_input_mask, all_segment_ids, all_label_ids), batch_size=batch_size
|
||||
)
|
||||
|
||||
def validation_step(self, batch, batch_nb):
|
||||
"Compute validation"
|
||||
|
||||
inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
|
||||
if self.hparams.model_type != "distilbert":
|
||||
inputs["token_type_ids"] = (
|
||||
@@ -68,11 +104,10 @@ class NERTransformer(BaseTransformer):
|
||||
tmp_eval_loss, logits = outputs[:2]
|
||||
preds = logits.detach().cpu().numpy()
|
||||
out_label_ids = inputs["labels"].detach().cpu().numpy()
|
||||
|
||||
return {"val_loss": tmp_eval_loss, "pred": preds, "target": out_label_ids}
|
||||
return {"val_loss": tmp_eval_loss.detach().cpu(), "pred": preds, "target": out_label_ids}
|
||||
|
||||
def _eval_end(self, outputs):
|
||||
"Task specific validation"
|
||||
"Evaluation called for both Val and Test"
|
||||
val_loss_mean = torch.stack([x["val_loss"] for x in outputs]).mean()
|
||||
preds = np.concatenate([x["pred"] for x in outputs], axis=0)
|
||||
preds = np.argmax(preds, axis=2)
|
||||
@@ -96,7 +131,6 @@ class NERTransformer(BaseTransformer):
|
||||
}
|
||||
|
||||
if self.is_logger():
|
||||
logger.info(self.proc_rank)
|
||||
logger.info("***** Eval results *****")
|
||||
for key in sorted(results.keys()):
|
||||
logger.info(" %s = %s", key, str(results[key]))
|
||||
@@ -140,56 +174,6 @@ class NERTransformer(BaseTransformer):
|
||||
)
|
||||
return ret
|
||||
|
||||
def load_and_cache_examples(self, labels, pad_token_label_id, mode):
|
||||
args = self.hparams
|
||||
tokenizer = self.tokenizer
|
||||
if self.proc_rank not in [-1, 0] and mode == "train":
|
||||
torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
|
||||
|
||||
# Load data features from cache or dataset file
|
||||
cached_features_file = os.path.join(
|
||||
args.data_dir,
|
||||
"cached_{}_{}_{}".format(
|
||||
mode, list(filter(None, args.model_name_or_path.split("/"))).pop(), str(args.max_seq_length)
|
||||
),
|
||||
)
|
||||
if os.path.exists(cached_features_file) and not args.overwrite_cache:
|
||||
logger.info("Loading features from cached file %s", cached_features_file)
|
||||
features = torch.load(cached_features_file)
|
||||
else:
|
||||
logger.info("Creating features from dataset file at %s", args.data_dir)
|
||||
examples = read_examples_from_file(args.data_dir, mode)
|
||||
features = convert_examples_to_features(
|
||||
examples,
|
||||
labels,
|
||||
args.max_seq_length,
|
||||
tokenizer,
|
||||
cls_token_at_end=bool(args.model_type in ["xlnet"]),
|
||||
cls_token=tokenizer.cls_token,
|
||||
cls_token_segment_id=2 if args.model_type in ["xlnet"] else 0,
|
||||
sep_token=tokenizer.sep_token,
|
||||
sep_token_extra=bool(args.model_type in ["roberta"]),
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]),
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token_label_id=pad_token_label_id,
|
||||
)
|
||||
if self.proc_rank in [-1, 0]:
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
torch.save(features, cached_features_file)
|
||||
|
||||
if self.proc_rank == 0 and mode == "train":
|
||||
torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
|
||||
|
||||
# Convert to Tensors and build dataset
|
||||
all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
|
||||
all_input_mask = torch.tensor([f.input_mask for f in features], dtype=torch.long)
|
||||
all_segment_ids = torch.tensor([f.segment_ids for f in features], dtype=torch.long)
|
||||
all_label_ids = torch.tensor([f.label_ids for f in features], dtype=torch.long)
|
||||
|
||||
dataset = TensorDataset(all_input_ids, all_input_mask, all_segment_ids, all_label_ids)
|
||||
return dataset
|
||||
|
||||
@staticmethod
|
||||
def add_model_specific_args(parser, root_dir):
|
||||
# Add NER specific options
|
||||
|
||||
@@ -1,3 +1,4 @@
|
||||
import logging
|
||||
import os
|
||||
import random
|
||||
|
||||
@@ -26,6 +27,9 @@ from transformers import (
|
||||
)
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
ALL_MODELS = sum(
|
||||
(
|
||||
tuple(conf.pretrained_config_archive_map.keys())
|
||||
@@ -77,20 +81,14 @@ class BaseTransformer(pl.LightningModule):
|
||||
cache_dir=self.hparams.cache_dir if self.hparams.cache_dir else None,
|
||||
)
|
||||
self.config, self.tokenizer, self.model = config, tokenizer, model
|
||||
self.proc_rank = -1
|
||||
|
||||
def is_logger(self):
|
||||
return self.proc_rank <= 0
|
||||
return self.trainer.proc_rank <= 0
|
||||
|
||||
def configure_optimizers(self):
|
||||
"Prepare optimizer and schedule (linear warmup and decay)"
|
||||
model = self.model
|
||||
|
||||
t_total = (
|
||||
len(self.train_dataloader())
|
||||
// self.hparams.gradient_accumulation_steps
|
||||
* float(self.hparams.num_train_epochs)
|
||||
)
|
||||
model = self.model
|
||||
no_decay = ["bias", "LayerNorm.weight"]
|
||||
optimizer_grouped_parameters = [
|
||||
{
|
||||
@@ -103,18 +101,16 @@ class BaseTransformer(pl.LightningModule):
|
||||
},
|
||||
]
|
||||
optimizer = AdamW(optimizer_grouped_parameters, lr=self.hparams.learning_rate, eps=self.hparams.adam_epsilon)
|
||||
scheduler = get_linear_schedule_with_warmup(
|
||||
optimizer, num_warmup_steps=self.hparams.warmup_steps, num_training_steps=t_total
|
||||
)
|
||||
self.lr_scheduler = scheduler
|
||||
self.opt = optimizer
|
||||
return [optimizer]
|
||||
|
||||
def optimizer_step(self, epoch, batch_idx, optimizer, optimizer_idx, second_order_closure=None):
|
||||
|
||||
# Step each time.
|
||||
optimizer.step()
|
||||
self.lr_scheduler.step()
|
||||
if self.trainer.use_tpu:
|
||||
xm.optimizer_step(optimizer)
|
||||
else:
|
||||
optimizer.step()
|
||||
optimizer.zero_grad()
|
||||
self.lr_scheduler.step()
|
||||
|
||||
def get_tqdm_dict(self):
|
||||
tqdm_dict = {"loss": "{:.3f}".format(self.trainer.avg_loss), "lr": self.lr_scheduler.get_last_lr()[-1]}
|
||||
@@ -127,22 +123,27 @@ class BaseTransformer(pl.LightningModule):
|
||||
def test_end(self, outputs):
|
||||
return self.validation_end(outputs)
|
||||
|
||||
@pl.data_loader
|
||||
def train_dataloader(self):
|
||||
return self.load_dataset("train", self.hparams.train_batch_size)
|
||||
train_batch_size = self.hparams.train_batch_size
|
||||
dataloader = self.load_dataset("train", train_batch_size)
|
||||
|
||||
t_total = (
|
||||
(len(dataloader.dataset) // (train_batch_size * max(1, self.hparams.n_gpu)))
|
||||
// self.hparams.gradient_accumulation_steps
|
||||
* float(self.hparams.num_train_epochs)
|
||||
)
|
||||
scheduler = get_linear_schedule_with_warmup(
|
||||
self.opt, num_warmup_steps=self.hparams.warmup_steps, num_training_steps=t_total
|
||||
)
|
||||
self.lr_scheduler = scheduler
|
||||
return dataloader
|
||||
|
||||
@pl.data_loader
|
||||
def val_dataloader(self):
|
||||
return self.load_dataset("dev", self.hparams.eval_batch_size)
|
||||
|
||||
@pl.data_loader
|
||||
def test_dataloader(self):
|
||||
return self.load_dataset("test", self.hparams.eval_batch_size)
|
||||
|
||||
def init_ddp_connection(self, proc_rank, world_size):
|
||||
self.proc_rank = proc_rank
|
||||
super(BaseTransformer, self).init_ddp_connection(proc_rank, world_size)
|
||||
|
||||
@staticmethod
|
||||
def add_model_specific_args(parser, root_dir):
|
||||
parser.add_argument(
|
||||
@@ -213,6 +214,7 @@ def add_generic_args(parser, root_dir):
|
||||
)
|
||||
|
||||
parser.add_argument("--n_gpu", type=int, default=1)
|
||||
parser.add_argument("--n_tpu_cores", type=int, default=0)
|
||||
parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
|
||||
parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
|
||||
parser.add_argument("--do_predict", action="store_true", help="Whether to run predictions on the test set.")
|
||||
@@ -252,13 +254,22 @@ def generic_train(model, args):
|
||||
accumulate_grad_batches=args.gradient_accumulation_steps,
|
||||
gpus=args.n_gpu,
|
||||
max_epochs=args.num_train_epochs,
|
||||
early_stop_callback=False,
|
||||
gradient_clip_val=args.max_grad_norm,
|
||||
checkpoint_callback=checkpoint_callback,
|
||||
)
|
||||
|
||||
if args.fp16:
|
||||
train_params["use_amp"] = args.fp16
|
||||
train_params["amp_level"] = args.fp16_opt_level
|
||||
|
||||
if args.n_tpu_cores > 0:
|
||||
global xm
|
||||
import torch_xla.core.xla_model as xm
|
||||
|
||||
train_params["num_tpu_cores"] = args.n_tpu_cores
|
||||
train_params["gpus"] = 0
|
||||
|
||||
if args.n_gpu > 1:
|
||||
train_params["distributed_backend"] = "ddp"
|
||||
|
||||
|
||||
@@ -338,7 +338,7 @@ def main():
|
||||
# Setup devices and distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
args.device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else:
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
args.device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -189,7 +189,7 @@ def main():
|
||||
args = parser.parse_args()
|
||||
|
||||
args.device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
|
||||
set_seed(args)
|
||||
|
||||
|
||||
@@ -183,8 +183,11 @@ def train(args, train_dataset, model, tokenizer):
|
||||
steps_trained_in_current_epoch = 0
|
||||
# Check if continuing training from a checkpoint
|
||||
if os.path.exists(args.model_name_or_path):
|
||||
# set global_step to gobal_step of last saved checkpoint from model path
|
||||
global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
|
||||
# set global_step to global_step of last saved checkpoint from model path
|
||||
try:
|
||||
global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
|
||||
except ValueError:
|
||||
global_step = 0
|
||||
epochs_trained = global_step // (len(train_dataloader) // args.gradient_accumulation_steps)
|
||||
steps_trained_in_current_epoch = global_step % (len(train_dataloader) // args.gradient_accumulation_steps)
|
||||
|
||||
@@ -575,7 +578,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -663,7 +663,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -535,7 +535,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -725,7 +725,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -530,7 +530,7 @@ def main():
|
||||
# Setup CUDA, GPU & distributed training
|
||||
if args.local_rank == -1 or args.no_cuda:
|
||||
device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
args.n_gpu = torch.cuda.device_count()
|
||||
args.n_gpu = 0 if args.no_cuda else torch.cuda.device_count()
|
||||
else: # Initializes the distributed backend which will take care of sychronizing nodes/GPUs
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
device = torch.device("cuda", args.local_rank)
|
||||
|
||||
@@ -0,0 +1,45 @@
|
||||
### Get the CNN/Daily Mail Data
|
||||
To be able to reproduce the authors' results on the CNN/Daily Mail dataset you first need to download both CNN and Daily Mail datasets [from Kyunghyun Cho's website](https://cs.nyu.edu/~kcho/DMQA/) (the links next to "Stories") in the same folder. Then uncompress the archives by running:
|
||||
|
||||
```bash
|
||||
tar -xvf cnn_stories.tgz && tar -xvf dailymail_stories.tgz
|
||||
```
|
||||
this should make a directory called cnn_dm/ with files like `test.source`.
|
||||
To use your own data, copy that files format. Each article to be summarized is on its own line.
|
||||
|
||||
### Usage
|
||||
To create summaries for each article in dataset, run:
|
||||
```bash
|
||||
python evaluate_cnn.py <path_to_test.source> cnn_test_summaries.txt
|
||||
```
|
||||
the default batch size, 8, fits in 16GB GPU memory, but may need to be adjusted to fit your system.
|
||||
|
||||
### Where is the code?
|
||||
The core model is in `src/transformers/modeling_bart.py`. This directory only contains examples.
|
||||
|
||||
### (WIP) Rouge Scores
|
||||
|
||||
### Stanford CoreNLP Setup
|
||||
```
|
||||
ptb_tokenize () {
|
||||
cat $1 | java edu.stanford.nlp.process.PTBTokenizer -ioFileList -preserveLines > $2
|
||||
}
|
||||
|
||||
sudo apt install openjdk-8-jre-headless
|
||||
sudo apt-get install ant
|
||||
wget http://nlp.stanford.edu/software/stanford-corenlp-full-2018-10-05.zip
|
||||
unzip stanford-corenlp-full-2018-10-05.zip
|
||||
cd stanford-corenlp-full-2018-10-05
|
||||
export CLASSPATH=stanford-corenlp-3.9.2.jar:stanford-corenlp-3.9.2-models.jar
|
||||
```
|
||||
### Rouge Setup
|
||||
Install `files2rouge` following the instructions at [here](https://github.com/pltrdy/files2rouge).
|
||||
I also needed to run `sudo apt-get install libxml-parser-perl`
|
||||
|
||||
```python
|
||||
from files2rouge import files2rouge
|
||||
from files2rouge import settings
|
||||
files2rouge.run(<path_to_tokenized_hypo>,
|
||||
<path_to_tokenized_target>,
|
||||
saveto='rouge_output.txt')
|
||||
```
|
||||
@@ -0,0 +1,60 @@
|
||||
import argparse
|
||||
from pathlib import Path
|
||||
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
|
||||
from transformers import BartForConditionalGeneration, BartTokenizer
|
||||
|
||||
|
||||
DEFAULT_DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
|
||||
|
||||
def chunks(lst, n):
|
||||
"""Yield successive n-sized chunks from lst."""
|
||||
for i in range(0, len(lst), n):
|
||||
yield lst[i : i + n]
|
||||
|
||||
|
||||
def generate_summaries(lns, out_file, batch_size=8, device=DEFAULT_DEVICE):
|
||||
fout = Path(out_file).open("w")
|
||||
model = BartForConditionalGeneration.from_pretrained("bart-large-cnn", output_past=True,).to(device)
|
||||
tokenizer = BartTokenizer.from_pretrained("bart-large")
|
||||
for batch in tqdm(list(chunks(lns, batch_size))):
|
||||
dct = tokenizer.batch_encode_plus(batch, max_length=1024, return_tensors="pt", pad_to_max_length=True)
|
||||
summaries = model.generate(
|
||||
input_ids=dct["input_ids"].to(device),
|
||||
attention_mask=dct["attention_mask"].to(device),
|
||||
num_beams=4,
|
||||
length_penalty=2.0,
|
||||
max_length=140,
|
||||
min_len=55,
|
||||
no_repeat_ngram_size=3,
|
||||
)
|
||||
dec = [tokenizer.decode(g, skip_special_tokens=True, clean_up_tokenization_spaces=False) for g in summaries]
|
||||
for hypothesis in dec:
|
||||
fout.write(hypothesis + "\n")
|
||||
fout.flush()
|
||||
|
||||
|
||||
def _run_generate():
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument(
|
||||
"source_path", type=str, help="like cnn_dm/test.source",
|
||||
)
|
||||
parser.add_argument(
|
||||
"output_path", type=str, help="where to save summaries",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device", type=str, required=False, default=DEFAULT_DEVICE, help="cuda, cuda:1, cpu etc.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--bs", type=int, default=8, required=False, help="batch size: how many to summarize at a time",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
lns = [" " + x.rstrip() for x in open(args.source_path).readlines()]
|
||||
generate_summaries(lns, args.output_path, batch_size=args.bs, device=args.device)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
_run_generate()
|
||||
@@ -0,0 +1,28 @@
|
||||
import logging
|
||||
import sys
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
from .evaluate_cnn import _run_generate
|
||||
|
||||
|
||||
articles = [" New York (CNN)When Liana Barrientos was 23 years old, she got married in Westchester County."]
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
|
||||
logger = logging.getLogger()
|
||||
|
||||
|
||||
class TestBartExamples(unittest.TestCase):
|
||||
def test_bart_cnn_cli(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
tmp = Path(tempfile.gettempdir()) / "utest_generations.hypo"
|
||||
with tmp.open("w") as f:
|
||||
f.write("\n".join(articles))
|
||||
testargs = ["evaluate_cnn.py", str(tmp), "output.txt"]
|
||||
with patch.object(sys, "argv", testargs):
|
||||
_run_generate()
|
||||
self.assertTrue(Path("output.txt").exists())
|
||||
@@ -15,7 +15,7 @@ pip install nltk py-rouge
|
||||
cd examples/summarization
|
||||
```
|
||||
|
||||
## Reproduce the authors' results on ROUGE
|
||||
## Reproduce the authors' ROUGE score
|
||||
|
||||
To be able to reproduce the authors' results on the CNN/Daily Mail dataset you first need to download both CNN and Daily Mail datasets [from Kyunghyun Cho's website](https://cs.nyu.edu/~kcho/DMQA/) (the links next to "Stories") in the same folder. Then uncompress the archives by running:
|
||||
|
||||
+6
-5
@@ -11,12 +11,13 @@ from tqdm import tqdm
|
||||
|
||||
from modeling_bertabs import BertAbs, build_predictor
|
||||
from transformers import BertTokenizer
|
||||
from utils_summarization import (
|
||||
SummarizationDataset,
|
||||
|
||||
from .utils_summarization import (
|
||||
CNNDMDataset,
|
||||
build_mask,
|
||||
compute_token_type_ids,
|
||||
encode_for_summarization,
|
||||
fit_to_block_size,
|
||||
truncate_or_pad,
|
||||
)
|
||||
|
||||
|
||||
@@ -194,7 +195,7 @@ def build_data_iterator(args, tokenizer):
|
||||
|
||||
|
||||
def load_and_cache_examples(args, tokenizer):
|
||||
dataset = SummarizationDataset(args.documents_dir)
|
||||
dataset = CNNDMDataset(args.documents_dir)
|
||||
return dataset
|
||||
|
||||
|
||||
@@ -211,7 +212,7 @@ def collate(data, tokenizer, block_size, device):
|
||||
|
||||
encoded_text = [encode_for_summarization(story, summary, tokenizer) for _, story, summary in data]
|
||||
encoded_stories = torch.tensor(
|
||||
[fit_to_block_size(story, block_size, tokenizer.pad_token_id) for story, _ in encoded_text]
|
||||
[truncate_or_pad(story, block_size, tokenizer.pad_token_id) for story, _ in encoded_text]
|
||||
)
|
||||
encoder_token_type_ids = compute_token_type_ids(encoded_stories, tokenizer.cls_token_id)
|
||||
encoder_mask = build_mask(encoded_stories, tokenizer.pad_token_id)
|
||||
+4
-4
@@ -17,7 +17,7 @@ import unittest
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from utils_summarization import build_mask, compute_token_type_ids, fit_to_block_size, process_story
|
||||
from .utils_summarization import build_mask, compute_token_type_ids, process_story, truncate_or_pad
|
||||
|
||||
|
||||
class SummarizationDataProcessingTest(unittest.TestCase):
|
||||
@@ -28,19 +28,19 @@ class SummarizationDataProcessingTest(unittest.TestCase):
|
||||
""" Pad the sequence with 0 if the sequence is smaller than the block size."""
|
||||
sequence = [1, 2, 3, 4]
|
||||
expected_output = [1, 2, 3, 4, 0, 0, 0, 0, 0, 0]
|
||||
self.assertEqual(fit_to_block_size(sequence, self.block_size, 0), expected_output)
|
||||
self.assertEqual(truncate_or_pad(sequence, self.block_size, 0), expected_output)
|
||||
|
||||
def test_fit_to_block_sequence_fit_exactly(self):
|
||||
""" Do nothing if the sequence is the right size. """
|
||||
sequence = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
|
||||
expected_output = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
|
||||
self.assertEqual(fit_to_block_size(sequence, self.block_size, 0), expected_output)
|
||||
self.assertEqual(truncate_or_pad(sequence, self.block_size, 0), expected_output)
|
||||
|
||||
def test_fit_to_block_sequence_too_big(self):
|
||||
""" Truncate the sequence if it is too long. """
|
||||
sequence = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13]
|
||||
expected_output = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
|
||||
self.assertEqual(fit_to_block_size(sequence, self.block_size, 0), expected_output)
|
||||
self.assertEqual(truncate_or_pad(sequence, self.block_size, 0), expected_output)
|
||||
|
||||
def test_process_story_no_highlights(self):
|
||||
""" Processing a story with no highlights returns an empty list for the summary.
|
||||
+4
-4
@@ -10,7 +10,7 @@ from torch.utils.data import Dataset
|
||||
# ------------
|
||||
|
||||
|
||||
class SummarizationDataset(Dataset):
|
||||
class CNNDMDataset(Dataset):
|
||||
""" Abstracts the dataset used to train seq2seq models.
|
||||
|
||||
The class will process the documents that are located in the specified
|
||||
@@ -62,11 +62,11 @@ class SummarizationDataset(Dataset):
|
||||
def process_story(raw_story):
|
||||
""" Extract the story and summary from a story file.
|
||||
|
||||
Attributes:
|
||||
Arguments:
|
||||
raw_story (str): content of the story file as an utf-8 encoded string.
|
||||
|
||||
Raises:
|
||||
IndexError: If the stoy is empty or contains no highlights.
|
||||
IndexError: If the story is empty or contains no highlights.
|
||||
"""
|
||||
nonempty_lines = list(filter(lambda x: len(x) != 0, [line.strip() for line in raw_story.split("\n")]))
|
||||
|
||||
@@ -107,7 +107,7 @@ def _add_missing_period(line):
|
||||
# --------------------------
|
||||
|
||||
|
||||
def fit_to_block_size(sequence, block_size, pad_token_id):
|
||||
def truncate_or_pad(sequence, block_size, pad_token_id):
|
||||
""" Adapt the source and target sequences' lengths to the block size.
|
||||
If the sequence is shorter we append padding token to the right of the sequence.
|
||||
"""
|
||||
@@ -0,0 +1,14 @@
|
||||
---
|
||||
language:
|
||||
- bulgarian
|
||||
- czech
|
||||
- polish
|
||||
- russian
|
||||
---
|
||||
|
||||
# bert-base-bg-cs-pl-ru-cased
|
||||
|
||||
SlavicBERT\[1\] \(Slavic \(bg, cs, pl, ru\), cased, 12‑layer, 768‑hidden, 12‑heads, 180M parameters\) was trained on Russian News and four Wikipedias: Bulgarian, Czech, Polish, and Russian. Subtoken vocabulary was built using this data. Multilingual BERT was used as an initialization for SlavicBERT.
|
||||
|
||||
|
||||
\[1\]: Arkhipov M., Trofimova M., Kuratov Y., Sorokin A. \(2019\). [Tuning Multilingual Transformers for Language-Specific Named Entity Recognition](https://www.aclweb.org/anthology/W19-3712/). ACL anthology W19-3712.
|
||||
@@ -0,0 +1,17 @@
|
||||
---
|
||||
language:
|
||||
- english
|
||||
---
|
||||
|
||||
# bert-base-cased-conversational
|
||||
|
||||
Conversational BERT \(English, cased, 12‑layer, 768‑hidden, 12‑heads, 110M parameters\) was trained on the English part of Twitter, Reddit, DailyDialogues\[1\], OpenSubtitles\[2\], Debates\[3\], Blogs\[4\], Facebook News Comments. We used this training data to build the vocabulary of English subtokens and took English cased version of BERT‑base as an initialization for English Conversational BERT.
|
||||
|
||||
|
||||
\[1\]: Yanran Li, Hui Su, Xiaoyu Shen, Wenjie Li, Ziqiang Cao, and Shuzi Niu. DailyDialog: A Manually Labelled Multi-turn Dialogue Dataset. IJCNLP 2017.
|
||||
|
||||
\[2\]: P. Lison and J. Tiedemann, 2016, OpenSubtitles2016: Extracting Large Parallel Corpora from Movie and TV Subtitles. In Proceedings of the 10th International Conference on Language Resources and Evaluation \(LREC 2016\)
|
||||
|
||||
\[3\]: Justine Zhang, Ravi Kumar, Sujith Ravi, Cristian Danescu-Niculescu-Mizil. Proceedings of NAACL, 2016.
|
||||
|
||||
\[4\]: J. Schler, M. Koppel, S. Argamon and J. Pennebaker \(2006\). Effects of Age and Gender on Blogging in Proceedings of 2006 AAAI Spring Symposium on Computational Approaches for Analyzing Weblogs.
|
||||
@@ -0,0 +1,15 @@
|
||||
---
|
||||
language:
|
||||
- multilingual
|
||||
---
|
||||
|
||||
# bert-base-multilingual-cased-sentence
|
||||
|
||||
Sentence Multilingual BERT \(101 languages, cased, 12‑layer, 768‑hidden, 12‑heads, 180M parameters\) is a representation‑based sentence encoder for 101 languages of Multilingual BERT. It is initialized with Multilingual BERT and then fine‑tuned on english MultiNLI\[1\] and on dev set of multilingual XNLI\[2\]. Sentence representations are mean pooled token embeddings in the same manner as in Sentence‑BERT\[3\].
|
||||
|
||||
|
||||
\[1\]: Williams A., Nangia N. & Bowman S. \(2017\) A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference. arXiv preprint [arXiv:1704.05426](https://arxiv.org/abs/1704.05426)
|
||||
|
||||
\[2\]: Williams A., Bowman S. \(2018\) XNLI: Evaluating Cross-lingual Sentence Representations. arXiv preprint [arXiv:1809.05053](https://arxiv.org/abs/1809.05053)
|
||||
|
||||
\[3\]: N. Reimers, I. Gurevych \(2019\) Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks. arXiv preprint [arXiv:1908.10084](https://arxiv.org/abs/1908.10084)
|
||||
@@ -0,0 +1,13 @@
|
||||
---
|
||||
language:
|
||||
- russian
|
||||
---
|
||||
|
||||
# rubert-base-cased-conversational
|
||||
|
||||
Conversational RuBERT \(Russian, cased, 12‑layer, 768‑hidden, 12‑heads, 180M parameters\) was trained on OpenSubtitles\[1\], [Dirty](https://d3.ru/), [Pikabu](https://pikabu.ru/), and a Social Media segment of Taiga corpus\[2\]. We assembled a new vocabulary for Conversational RuBERT model on this data and initialized the model with [RuBERT](../rubert-base-cased).
|
||||
|
||||
|
||||
\[1\]: P. Lison and J. Tiedemann, 2016, OpenSubtitles2016: Extracting Large Parallel Corpora from Movie and TV Subtitles. In Proceedings of the 10th International Conference on Language Resources and Evaluation \(LREC 2016\)
|
||||
|
||||
\[2\]: Shavrina T., Shapovalova O. \(2017\) TO THE METHODOLOGY OF CORPUS CONSTRUCTION FOR MACHINE LEARNING: «TAIGA» SYNTAX TREE CORPUS AND PARSER. in proc. of “CORPORA2017”, international conference , Saint-Petersbourg, 2017.
|
||||
@@ -0,0 +1,15 @@
|
||||
---
|
||||
language:
|
||||
- russian
|
||||
---
|
||||
|
||||
# rubert-base-cased-sentence
|
||||
|
||||
Sentence RuBERT \(Russian, cased, 12-layer, 768-hidden, 12-heads, 180M parameters\) is a representation‑based sentence encoder for Russian. It is initialized with RuBERT and fine‑tuned on SNLI\[1\] google-translated to russian and on russian part of XNLI dev set\[2\]. Sentence representations are mean pooled token embeddings in the same manner as in Sentence‑BERT\[3\].
|
||||
|
||||
|
||||
\[1\]: S. R. Bowman, G. Angeli, C. Potts, and C. D. Manning. \(2015\) A large annotated corpus for learning natural language inference. arXiv preprint [arXiv:1508.05326](https://arxiv.org/abs/1508.05326)
|
||||
|
||||
\[2\]: Williams A., Bowman S. \(2018\) XNLI: Evaluating Cross-lingual Sentence Representations. arXiv preprint [arXiv:1809.05053](https://arxiv.org/abs/1809.05053)
|
||||
|
||||
\[3\]: N. Reimers, I. Gurevych \(2019\) Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks. arXiv preprint [arXiv:1908.10084](https://arxiv.org/abs/1908.10084)
|
||||
@@ -0,0 +1,11 @@
|
||||
---
|
||||
language:
|
||||
- russian
|
||||
---
|
||||
|
||||
# rubert-base-cased
|
||||
|
||||
RuBERT \(Russian, cased, 12‑layer, 768‑hidden, 12‑heads, 180M parameters\) was trained on the Russian part of Wikipedia and news data. We used this training data to build a vocabulary of Russian subtokens and took a multilingual version of BERT‑base as an initialization for RuBERT\[1\].
|
||||
|
||||
|
||||
\[1\]: Kuratov, Y., Arkhipov, M. \(2019\). Adaptation of Deep Bidirectional Multilingual Transformers for Russian Language. arXiv preprint [arXiv:1905.07213](https://arxiv.org/abs/1905.07213).
|
||||
@@ -0,0 +1,48 @@
|
||||
---
|
||||
language: arabic
|
||||
---
|
||||
|
||||
# Arabic BERT Model
|
||||
|
||||
Pretrained BERT base language model for Arabic
|
||||
|
||||
## Pretraining Corpus
|
||||
|
||||
`arabic-bert-base` model was pretrained on ~8.2 Billion words:
|
||||
|
||||
- Arabic version of [OSCAR](https://traces1.inria.fr/oscar/) - filtered from [Common Crawl](http://commoncrawl.org/)
|
||||
- Recent dump of Arabic [Wikipedia](https://dumps.wikimedia.org/backup-index.html)
|
||||
|
||||
and other Arabic resources which sum up to ~95GB of text.
|
||||
|
||||
__Notes on training data:__
|
||||
|
||||
- Our final version of corpus contains some non-Arabic words inlines, which we did not remove from sentences since that would affect some tasks like NER.
|
||||
- Although non-Arabic characters were lowered as a preprocessing step, since Arabic characters does not have upper or lower case, there is no cased and uncased version of the model.
|
||||
- The corpus and vocabulary set are not restricted to Modern Standard Arabic, they contain some dialectical Arabic too.
|
||||
|
||||
## Pretraining details
|
||||
|
||||
- This model was trained using Google BERT's github [repository](https://github.com/google-research/bert) on a single TPU v3-8 provided for free from [TFRC](https://www.tensorflow.org/tfrc).
|
||||
- Our pretraining procedure follows training settings of bert with some changes: trained for 3M training steps with batchsize of 128, instead of 1M with batchsize of 256.
|
||||
|
||||
## Load Pretrained Model
|
||||
|
||||
You can use this model by installing `torch` or `tensorflow` and Huggingface library `transformers`. And you can use it directly by initializing it like this:
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("asafaya/bert-base-arabic")
|
||||
model = AutoModel.from_pretrained("asafaya/bert-base-arabic")
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
For further details on the models performance or any other queries, please refer to [Arabic-BERT](https://github.com/alisafaya/Arabic-BERT)
|
||||
|
||||
## Acknowledgement
|
||||
|
||||
Thanks to Google for providing free TPU for the training process and for Huggingface for hosting this model on their servers 😊
|
||||
|
||||
|
||||
@@ -0,0 +1,93 @@
|
||||
---
|
||||
language: arabic
|
||||
---
|
||||
|
||||
# AraBERT : Pre-training BERT for Arabic Language Understanding
|
||||
|
||||
**AraBERT** is an Arabic pretrained lanaguage model based on [Google's BERT architechture](https://github.com/google-research/bert). AraBERT uses the same BERT-Base config.
|
||||
|
||||
There are two version off the model AraBERTv0.1 and AraBERTv1, with the difference being that AraBERTv1 uses pre-segmented text where prefixes and suffixes were splitted using the [Farasa Segmenter](http://alt.qcri.org/farasa/segmenter.html).
|
||||
|
||||
The model was trained on ~70M sentences or ~23GB of Arabic text with ~3B words. The training corpora are a collection of publically available large scale raw arabic text ([Arabic Wikidumps](https://archive.org/details/arwiki-20190201), [The 1.5B words Arabic Corpus](https://www.semanticscholar.org/paper/1.5-billion-words-Arabic-Corpus-El-Khair/f3eeef4afb81223df96575adadf808fe7fe440b4), [The OSIAN Corpus](https://www.aclweb.org/anthology/W19-4619), Assafir news articles, and 4 other manually crawled news websites (Al-Akhbar, Annahar, AL-Ahram, AL-Wafd) from [the Wayback Machine](http://web.archive.org/))
|
||||
|
||||
We evalaute both AraBERT models on different downstream tasks and compare it to [mBERT]((https://github.com/google-research/bert/blob/master/multilingual.md)), and other state of the art models (*To the extent of our knowledge*). The Tasks were Sentiment Analysis on 6 different datasets ([HARD](https://github.com/elnagara/HARD-Arabic-Dataset), [ASTD-Balanced](https://www.aclweb.org/anthology/D15-1299), [ArsenTD-Lev](https://staff.aub.edu.lb/~we07/Publications/ArSentD-LEV_Sentiment_Corpus.pdf), [LABR](https://github.com/mohamedadaly/LABR), [ArSaS](http://lrec-conf.org/workshops/lrec2018/W30/pdf/22_W30.pdf)), Named Entity Recognition with the [ANERcorp](http://curtis.ml.cmu.edu/w/courses/index.php/ANERcorp), and Arabic Question Answering on [Arabic-SQuAD and ARCD](https://github.com/husseinmozannar/SOQAL)
|
||||
|
||||
## Results (Acc.)
|
||||
Task | prev. SOTA | mBERT | AraBERTv0.1 | AraBERTv1
|
||||
---|:---:|:---:|:---:|:---:
|
||||
HARD |95.7 [ElJundi et.al.](https://www.aclweb.org/anthology/W19-4608/)|95.7|96.2|96.1
|
||||
ASTD |86.5 [ElJundi et.al.](https://www.aclweb.org/anthology/W19-4608/)| 80.1|92.2|92.6
|
||||
ArsenTD-Lev|52.4 [ElJundi et.al.](https://www.aclweb.org/anthology/W19-4608/)|51|58.9|59.4
|
||||
AJGT|93 [Dahou et.al.](https://dl.acm.org/doi/fullHtml/10.1145/3314941)| 83.6|94.1|93.8
|
||||
LABR|87.5 [Dahou et.al.](https://dl.acm.org/doi/fullHtml/10.1145/3314941)|83|85.9|86.7
|
||||
ANERcorp|81.7 (BiLSTM-CRF)|78.4|84.2|81.9
|
||||
ARCD|mBERT|EM:34.2 F1: 61.3|EM:30.1 F1:61.2|EM:30.6 F1: 62.7
|
||||
|
||||
*We would be extremly thankful if everyone can contibute to the Results table by adding more scores on different datasets*
|
||||
|
||||
## How to use
|
||||
|
||||
You can easily use AraBERT since it is almost fully compatible with existing codebases (You can use this repo instead of the official BERT one, the only difference is in the ```tokenization.py``` file where we modify the _is_punctuation function to make it compatible with the "+" symbol and the "[" and "]" characters)
|
||||
|
||||
To use HuggingFace's Transformer repository you only need to provide a lost of token that forces the model to not split them, also make sure that the text is pre-segmented:
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer
|
||||
from preprocess_arabert import never_split_tokens
|
||||
|
||||
arabert_tokenizer = AutoTokenizer.from_pretrained(
|
||||
"aubmindlab/bert-base-arabert",
|
||||
do_lower_case=False,
|
||||
do_basic_tokenize=True,
|
||||
never_split=never_split_tokens)
|
||||
arabert_model = AutoModel.from_pretrained("aubmindlab/bert-base-arabert")
|
||||
|
||||
arabert_tokenizer.tokenize("و+ لن نبالغ إذا قل +نا إن هاتف أو كمبيوتر ال+ مكتب في زمن +نا هذا ضروري")
|
||||
|
||||
>>> ['و+', 'لن', 'نبال', '##غ', 'إذا', 'قل', '+نا', 'إن', 'هاتف', 'أو', 'كمبيوتر', 'ال+', 'مكتب', 'في', 'زمن', '+نا', 'هذا', 'ضروري']
|
||||
```
|
||||
|
||||
**AraBERTv0.1 is compatible with all existing libraries, since it needs no pre-segmentation.**
|
||||
```python
|
||||
from transformers import AutoTokenizer
|
||||
from preprocess_arabert import never_split_tokens
|
||||
|
||||
arabert_tokenizer = AutoTokenizer.from_pretrained("aubmindlab/bert-base-arabertv01",do_lower_case=False)
|
||||
arabert_model = AutoModel.from_pretrained("aubmindlab/bert-base-arabertv01")
|
||||
|
||||
arabert_tokenizer.tokenize("ولن نبالغ إذا قلنا إن هاتف أو كمبيوتر المكتب في زمننا هذا ضروري")
|
||||
|
||||
>>> ['ولن', 'ن', '##بالغ', 'إذا', 'قلنا', 'إن', 'هاتف', 'أو', 'كمبيوتر', 'المكتب', 'في', 'زمن', '##ن', '##ا', 'هذا', 'ضروري']
|
||||
```
|
||||
|
||||
|
||||
The ```araBERT_(initial_Demo_TF)_.ipynb``` Notebook is a small demo using the AJGT dataset using TensorFlow (GPU and TPU compatible).
|
||||
|
||||
## Model Weights and Vocab Download
|
||||
Models | AraBERTv0.1 | AraBERTv1
|
||||
---|:---:|:---:
|
||||
TensorFlow|[Drive Link](https://drive.google.com/open?id=1-kVmTUZZ4DP2rzeHNjTPkY8OjnQCpomO) | [Drive Link](https://drive.google.com/open?id=1-d7-9ljKgDJP5mx73uBtio-TuUZCqZnt)
|
||||
PyTorch| [Drive_Link](https://drive.google.com/open?id=1-_3te42mQCPD8SxwZ3l-VBL7yaJH-IOv)| [Drive_Link](https://drive.google.com/open?id=1-69s6Pxqbi63HOQ1M9wTcr-Ovc6PWLLo)
|
||||
|
||||
**You can find the PyTorch models in HuggingFace's Transformer Library under the ```aubmindlab``` username**
|
||||
|
||||
## If you used this model please cite us as:
|
||||
```
|
||||
@misc{antoun2020arabert,
|
||||
title={AraBERT: Transformer-based Model for Arabic Language Understanding},
|
||||
author={Wissam Antoun and Fady Baly and Hazem Hajj},
|
||||
year={2020},
|
||||
eprint={2003.00104},
|
||||
archivePrefix={arXiv},
|
||||
primaryClass={cs.CL}
|
||||
}
|
||||
```
|
||||
## Acknowledgments
|
||||
Thanks to TensorFlow Research Cloud (TFRC) for the free access to Cloud TPUs, couldn't have done it without this program, and to the [AUB MIND Lab](https://sites.aub.edu.lb/mindlab/) Members for the continous support. Also thanks to [Yakshof](https://www.yakshof.com/#/) and Assafir for data and storage access.
|
||||
|
||||
## Contacts
|
||||
**Wissam Antoun**: [Linkedin](https://www.linkedin.com/in/giulio-ravasio-3a81a9110/) | [Twitter](https://twitter.com/wissam_antoun) | [Github](https://github.com/WissamAntoun) | <wfa07@mail.aub.edu> | <wissam.antoun@gmail.com>
|
||||
|
||||
**Fady Baly**: [Linkedin](https://www.linkedin.com/in/fadybaly/) | [Twitter](https://twitter.com/BalyFady) | [Github](https://github.com/fadybaly) | <fgb06@mail.aub.edu> | <baly.fady@gmail.com>
|
||||
|
||||
***We are looking for sponsors to train BERT-Large and other Transformer models, the sponsor only needs to cover to data storage and compute cost of the generating the pretraining data***
|
||||
@@ -0,0 +1 @@
|
||||
Slavic BERT from https://github.com/deepmipt/Slavic-BERT-NER http://files.deeppavlov.ai/deeppavlov_data/bg_cs_pl_ru_cased_L-12_H-768_A-12.tar.gz
|
||||
@@ -0,0 +1,49 @@
|
||||
---
|
||||
language: french
|
||||
---
|
||||
|
||||
# camembert-base-fquad
|
||||
|
||||
## Description
|
||||
|
||||
A baseline model for question-answering in french ([CamemBERT](https://camembert-model.fr/) model fine-tuned on [FQuAD](https://fquad.illuin.tech/))
|
||||
|
||||
## Training hyperparameters
|
||||
|
||||
```shell
|
||||
python3 ./examples/run_squad.py \
|
||||
--model_type camembert \
|
||||
--model_name_or_path camembert-base \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file train.json \
|
||||
--predict_file valid.json \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir output \
|
||||
--per_gpu_eval_batch_size=3 \
|
||||
--per_gpu_train_batch_size=3 \
|
||||
--save_steps 10000
|
||||
```
|
||||
|
||||
## Evaluation results
|
||||
|
||||
```shell
|
||||
{"f1": 77.24515316052342, "exact_match": 52.82308657465496}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline('question-answering', model='fmikaelian/camembert-base-fquad', tokenizer='fmikaelian/camembert-base-fquad')
|
||||
|
||||
nlp({
|
||||
'question': "Qui est Claude Monet?",
|
||||
'context': "Claude Monet, né le 14 novembre 1840 à Paris et mort le 5 décembre 1926 à Giverny, est un peintre français et l’un des fondateurs de l'impressionnisme."
|
||||
})
|
||||
```
|
||||
@@ -0,0 +1,49 @@
|
||||
---
|
||||
language: french
|
||||
---
|
||||
|
||||
# camembert-base-squad
|
||||
|
||||
## Description
|
||||
|
||||
A baseline model for question-answering in french ([CamemBERT](https://camembert-model.fr/) model fine-tuned on [french-translated SQuAD 1.1 dataset](https://github.com/Alikabbadj/French-SQuAD))
|
||||
|
||||
## Training hyperparameters
|
||||
|
||||
```shell
|
||||
python3 ./examples/run_squad.py \
|
||||
--model_type camembert \
|
||||
--model_name_or_path camembert-base \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file SQuAD-v1.1-train_fr_ss999_awstart2_net.json \
|
||||
--predict_file SQuAD-v1.1-dev_fr_ss999_awstart2_net.json \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir output3 \
|
||||
--per_gpu_eval_batch_size=3 \
|
||||
--per_gpu_train_batch_size=3 \
|
||||
--save_steps 10000
|
||||
```
|
||||
|
||||
## Evaluation results
|
||||
|
||||
```shell
|
||||
{"f1": 79.8570684959745, "exact_match": 59.21327108373895}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline('question-answering', model='fmikaelian/camembert-base-squad', tokenizer='fmikaelian/camembert-base-squad')
|
||||
|
||||
nlp({
|
||||
'question': "Qui est Claude Monet?",
|
||||
'context': "Claude Monet, né le 14 novembre 1840 à Paris et mort le 5 décembre 1926 à Giverny, est un peintre français et l’un des fondateurs de l'impressionnisme."
|
||||
})
|
||||
```
|
||||
@@ -0,0 +1,12 @@
|
||||
# GPT-2 (medium) Taboo
|
||||
|
||||
## What is it?
|
||||
A fine-tuned GPT-2 version for Taboo cards generation.
|
||||
|
||||
## Training setting
|
||||
|
||||
The model was trained on ~900 Taboo cards in the following format for 100 epochs:
|
||||
```
|
||||
Describe the word Glitch without using the words Problem, Unexpected, Technology, Minor, Outage.
|
||||
````
|
||||
|
||||
@@ -0,0 +1,139 @@
|
||||
---
|
||||
language: multilingual
|
||||
thumbnail:
|
||||
---
|
||||
|
||||
# BERT (base-multilingual-cased) fine-tuned on XQuAD
|
||||
|
||||
This model was created by [Google](https://github.com/google-research/bert/blob/master/multilingual.md) and fine-tuned on [XQuAD](https://github.com/deepmind/xquad) for multilingual (`11 different languages`) **Q&A** downstream task.
|
||||
|
||||
## Details of the language model('bert-base-multilingual-cased')
|
||||
|
||||
[Language model](https://github.com/google-research/bert/blob/master/multilingual.md)
|
||||
|
||||
| Languages | Heads | Layers | Hidden | Params |
|
||||
| --------- | ----- | ------ | ------ | ------ |
|
||||
| 104 | 12 | 12 | 768 | 100 M |
|
||||
|
||||
## Details of the downstream task (multilingual Q&A) - Dataset
|
||||
|
||||
Deepmind [XQuAD](https://github.com/deepmind/xquad)
|
||||
|
||||
Languages covered:
|
||||
|
||||
- Arabic: `ar`
|
||||
- German: `de`
|
||||
- Greek: `el`
|
||||
- English: `en`
|
||||
- Spanish: `es`
|
||||
- Hindi: `hi`
|
||||
- Russian: `ru`
|
||||
- Thai: `th`
|
||||
- Turkish: `tr`
|
||||
- Vietnamese: `vi`
|
||||
- Chinese: `zh`
|
||||
|
||||
As the dataset is based on SQuAD v1.1, there are no unanswerable questions in the data. We chose this
|
||||
setting so that models can focus on cross-lingual transfer.
|
||||
|
||||
We show the average number of tokens per paragraph, question, and answer for each language in the
|
||||
table below. The statistics were obtained using [Jieba](https://github.com/fxsjy/jieba) for Chinese
|
||||
and the [Moses tokenizer](https://github.com/moses-smt/mosesdecoder/blob/master/scripts/tokenizer/tokenizer.perl)
|
||||
for the other languages.
|
||||
|
||||
| | en | es | de | el | ru | tr | ar | vi | th | zh | hi |
|
||||
| --------- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: |
|
||||
| Paragraph | 142.4 | 160.7 | 139.5 | 149.6 | 133.9 | 126.5 | 128.2 | 191.2 | 158.7 | 147.6 | 232.4 |
|
||||
| Question | 11.5 | 13.4 | 11.0 | 11.7 | 10.0 | 9.8 | 10.7 | 14.8 | 11.5 | 10.5 | 18.7 |
|
||||
| Answer | 3.1 | 3.6 | 3.0 | 3.3 | 3.1 | 3.1 | 3.1 | 4.5 | 4.1 | 3.5 | 5.6 |
|
||||
|
||||
Citation:
|
||||
|
||||
<details>
|
||||
|
||||
```bibtex
|
||||
@article{Artetxe:etal:2019,
|
||||
author = {Mikel Artetxe and Sebastian Ruder and Dani Yogatama},
|
||||
title = {On the cross-lingual transferability of monolingual representations},
|
||||
journal = {CoRR},
|
||||
volume = {abs/1910.11856},
|
||||
year = {2019},
|
||||
archivePrefix = {arXiv},
|
||||
eprint = {1910.11856}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
I used `Data augmentation techniques` and splited the dataset in order to have a train and test set. The test set was created in a way that contains the same number of samples for each language. Finally, I got:
|
||||
|
||||
| Dataset | # samples |
|
||||
| ----------- | --------- |
|
||||
| XQUAD train | 50 K |
|
||||
| XQUAD test | 8 K |
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM.
|
||||
The script for fine tuning can be found [here](https://github.com/huggingface/transformers/blob/master/examples/distillation/run_squad_w_distillation.py)
|
||||
|
||||
## Results:
|
||||
|
||||
| Metric | # Value |
|
||||
| --------- | ----------- |
|
||||
| **Exact** | **91.43** |
|
||||
| **F1** | **94.14** |
|
||||
|
||||
|
||||
|
||||
## Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
qa_pipeline = pipeline(
|
||||
"question-answering",
|
||||
model="mrm8488/bert-multi-cased-finetuned-xquadv1",
|
||||
tokenizer="mrm8488/bert-multi-cased-finetuned-xquadv1"
|
||||
)
|
||||
|
||||
|
||||
# context: Coronavirus is seeding panic in the West because it expands so fast.
|
||||
|
||||
# question: Where is seeding panic Coronavirus?
|
||||
qa_pipeline({
|
||||
'context': "कोरोनावायरस पश्चिम में आतंक बो रहा है क्योंकि यह इतनी तेजी से फैलता है।",
|
||||
'question': "कोरोनावायरस घबराहट कहां है?"
|
||||
|
||||
})
|
||||
# output: {'answer': 'पश्चिम', 'end': 18, 'score': 0.7037217439689059, 'start': 12}
|
||||
|
||||
qa_pipeline({
|
||||
'context': "Manuel Romero has been working hardly in the repository hugginface/transformers lately",
|
||||
'question': "Who has been working hard for hugginface/transformers lately?"
|
||||
|
||||
})
|
||||
# output: {'answer': 'Manuel Romero', 'end': 13, 'score': 0.7254485993702389, 'start': 0}
|
||||
|
||||
qa_pipeline({
|
||||
'context': "Manuel Romero a travaillé à peine dans le référentiel hugginface / transformers ces derniers temps",
|
||||
'question': "Pour quel référentiel a travaillé Manuel Romero récemment?"
|
||||
|
||||
})
|
||||
#output: {'answer': 'hugginface / transformers', 'end': 79, 'score': 0.6482061613915384, 'start': 54}
|
||||
```
|
||||
|
||||
|
||||
Try it on a Colab:
|
||||
|
||||
<a href="https://colab.research.google.com/github/mrm8488/shared_colab_notebooks/blob/master/Try_mrm8488_xquad_finetuned_model.ipynb" target="_parent"><img src="https://camo.githubusercontent.com/52feade06f2fecbf006889a904d221e6a730c194/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open In Colab" data-canonical-src="https://colab.research.google.com/assets/colab-badge.svg"></a>
|
||||
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -0,0 +1,142 @@
|
||||
---
|
||||
language: multilingual
|
||||
thumbnail:
|
||||
---
|
||||
|
||||
# BERT (base-multilingual-uncased) fine-tuned on XQuAD
|
||||
|
||||
This model was created by [Google](https://github.com/google-research/bert/blob/master/multilingual.md) and fine-tuned on [XQuAD](https://github.com/deepmind/xquad) for multilingual (`11 different languages`) **Q&A** downstream task.
|
||||
|
||||
## Details of the language model('bert-base-multilingual-uncased')
|
||||
|
||||
[Language model](https://github.com/google-research/bert/blob/master/multilingual.md)
|
||||
|
||||
| Languages | Heads | Layers | Hidden | Params |
|
||||
| --------- | ----- | ------ | ------ | ------ |
|
||||
| 102 | 12 | 12 | 768 | 100 M |
|
||||
|
||||
## Details of the downstream task (multilingual Q&A) - Dataset
|
||||
|
||||
Deepmind [XQuAD](https://github.com/deepmind/xquad)
|
||||
|
||||
Languages covered:
|
||||
|
||||
- Arabic: `ar`
|
||||
- German: `de`
|
||||
- Greek: `el`
|
||||
- English: `en`
|
||||
- Spanish: `es`
|
||||
- Hindi: `hi`
|
||||
- Russian: `ru`
|
||||
- Thai: `th`
|
||||
- Turkish: `tr`
|
||||
- Vietnamese: `vi`
|
||||
- Chinese: `zh`
|
||||
|
||||
As the dataset is based on SQuAD v1.1, there are no unanswerable questions in the data. We chose this
|
||||
setting so that models can focus on cross-lingual transfer.
|
||||
|
||||
We show the average number of tokens per paragraph, question, and answer for each language in the
|
||||
table below. The statistics were obtained using [Jieba](https://github.com/fxsjy/jieba) for Chinese
|
||||
and the [Moses tokenizer](https://github.com/moses-smt/mosesdecoder/blob/master/scripts/tokenizer/tokenizer.perl)
|
||||
for the other languages.
|
||||
|
||||
| | en | es | de | el | ru | tr | ar | vi | th | zh | hi |
|
||||
| --------- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: |
|
||||
| Paragraph | 142.4 | 160.7 | 139.5 | 149.6 | 133.9 | 126.5 | 128.2 | 191.2 | 158.7 | 147.6 | 232.4 |
|
||||
| Question | 11.5 | 13.4 | 11.0 | 11.7 | 10.0 | 9.8 | 10.7 | 14.8 | 11.5 | 10.5 | 18.7 |
|
||||
| Answer | 3.1 | 3.6 | 3.0 | 3.3 | 3.1 | 3.1 | 3.1 | 4.5 | 4.1 | 3.5 | 5.6 |
|
||||
|
||||
Citation:
|
||||
|
||||
<details>
|
||||
|
||||
```bibtex
|
||||
@article{Artetxe:etal:2019,
|
||||
author = {Mikel Artetxe and Sebastian Ruder and Dani Yogatama},
|
||||
title = {On the cross-lingual transferability of monolingual representations},
|
||||
journal = {CoRR},
|
||||
volume = {abs/1910.11856},
|
||||
year = {2019},
|
||||
archivePrefix = {arXiv},
|
||||
eprint = {1910.11856}
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
I used `Data augmentation techniques` to obtain more samples and splited the dataset in order to have a train and test set. The test set was created in a way that contains the same number of samples for each language. Finally, I got:
|
||||
|
||||
| Dataset | # samples |
|
||||
| ----------- | --------- |
|
||||
| XQUAD train | 50 K |
|
||||
| XQUAD test | 8 K |
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM.
|
||||
The script for fine tuning can be found [here](https://github.com/huggingface/transformers/blob/master/examples/distillation/run_squad_w_distillation.py)
|
||||
|
||||
## Results:
|
||||
|
||||
| Metric | # Value |
|
||||
| --------- | ----------- |
|
||||
| **Exact** | **93.03** |
|
||||
| **F1** | **94.62** |
|
||||
|
||||
## Comparison:
|
||||
|
||||
| Model | Exact | F1 score |
|
||||
| --------- | ----------- | ------- |
|
||||
| [bert-multi-cased-finetuned-xquadv1](https://huggingface.co/mrm8488/bert-multi-cased-finetuned-xquadv1) | 91.43 | 94.14 |
|
||||
|bert-multi-uncased-finetuned-xquadv1 | **93.03** | **94.62**
|
||||
|
||||
## Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
qa_pipeline = pipeline(
|
||||
"question-answering",
|
||||
model="mrm8488/bert-multi-uncased-finetuned-xquadv1",
|
||||
tokenizer="bert-multi-uncased-finetuned-xquadv1"
|
||||
)
|
||||
|
||||
|
||||
# context: Coronavirus is seeding panic in the West because it expands so fast.
|
||||
|
||||
# question: Where is seeding panic Coronavirus?
|
||||
qa_pipeline({
|
||||
'context': "कोरोनावायरस पश्चिम में आतंक बो रहा है क्योंकि यह इतनी तेजी से फैलता है।",
|
||||
'question': "कोरोनावायरस घबराहट कहां है?"
|
||||
|
||||
})
|
||||
# output: {'answer': 'पश्चिम', 'end': 18, 'score': 0.7037217439689059, 'start': 12}
|
||||
|
||||
qa_pipeline({
|
||||
'context': "Manuel Romero has been working hardly in the repository hugginface/transformers lately",
|
||||
'question': "Who has been working hard for hugginface/transformers lately?"
|
||||
|
||||
})
|
||||
# output: {'answer': 'Manuel Romero', 'end': 13, 'score': 0.7254485993702389, 'start': 0}
|
||||
|
||||
qa_pipeline({
|
||||
'context': "Manuel Romero a travaillé à peine dans le référentiel hugginface / transformers ces derniers temps",
|
||||
'question': "Pour quel référentiel a travaillé Manuel Romero récemment?"
|
||||
|
||||
})
|
||||
#output: {'answer': 'hugginface / transformers', 'end': 79, 'score': 0.6482061613915384, 'start': 54}
|
||||
```
|
||||

|
||||
|
||||
Try it on a Colab:
|
||||
|
||||
<a href="https://colab.research.google.com/github/mrm8488/shared_colab_notebooks/blob/master/Try_mrm8488_xquad_finetuned_uncased_model.ipynb" target="_parent"><img src="https://camo.githubusercontent.com/52feade06f2fecbf006889a904d221e6a730c194/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open In Colab" data-canonical-src="https://colab.research.google.com/assets/colab-badge.svg"></a>
|
||||
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -19,22 +19,29 @@ I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
| Dev | 2.2 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
```bash
|
||||
!export NER_DIR='/content/ner_dataset'
|
||||
!python /content/transformers/examples/run_ner.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--data_dir '/content/ner_dataset' \
|
||||
--num_train_epochs 15.0 \
|
||||
--max_seq_length 384 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
- Labels covered:
|
||||
|
||||
```
|
||||
B-LOC
|
||||
B-MISC
|
||||
B-ORG
|
||||
B-PER
|
||||
I-LOC
|
||||
I-MISC
|
||||
I-ORG
|
||||
I-PER
|
||||
O
|
||||
```
|
||||
|
||||
## Metrics on evaluation set:
|
||||
|
||||
| Metric | # score |
|
||||
| :------------------------------------------------------------------------------------: | :-------: |
|
||||
| F1 | **90.17**
|
||||
| Precision | **89.86** |
|
||||
| Recall | **90.47** |
|
||||
|
||||
## Comparison:
|
||||
|
||||
@@ -44,13 +51,24 @@ I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
| [bert-spanish-cased-finetuned-ner (this one)](https://huggingface.co/mrm8488/bert-spanish-cased-finetuned-ner) | **89.65** |
|
||||
| Best Multilingual BERT | 87.38 |
|
||||
|
||||
```
|
||||
***** All metrics on Eval results *****
|
||||
## Model in action
|
||||
|
||||
f1 = 0.8965040489828165
|
||||
loss = 0.11504213575173258
|
||||
precision = 0.893679858239811
|
||||
recall = 0.8993461462254805
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp_ner = pipeline(
|
||||
"ner",
|
||||
model="mrm8488/bert-spanish-cased-finetuned-ner",
|
||||
tokenizer=(
|
||||
'mrm8488/bert-spanish-cased-finetuned-ner',
|
||||
{"use_fast": False}
|
||||
))
|
||||
|
||||
nlp_ner(text)
|
||||
|
||||
#Output: [{'entity': 'B-LOC', 'score': 0.9998720288276672, 'word': 'Londres'}]
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
@@ -0,0 +1,62 @@
|
||||
---
|
||||
language: english
|
||||
thumbnail:
|
||||
---
|
||||
|
||||
# [BERT](https://huggingface.co/deepset/bert-base-cased-squad2) fine tuned on [QNLI](https://github.com/rhythmcao/QNLI)+ compression ([BERT-of-Theseus](https://github.com/JetRunner/BERT-of-Theseus))
|
||||
|
||||
I used a [Bert model fine tuned on **SQUAD v2**](https://huggingface.co/deepset/bert-base-cased-squad2) and then I fine tuned it on **QNLI** using **compression** (with a constant replacing rate) as proposed in **BERT-of-Theseus**
|
||||
|
||||
## Details of the downstream task (QNLI):
|
||||
|
||||
### Getting the dataset
|
||||
```bash
|
||||
wget https://raw.githubusercontent.com/rhythmcao/QNLI/master/data/QNLI/train.tsv
|
||||
wget https://raw.githubusercontent.com/rhythmcao/QNLI/master/data/QNLI/test.tsv
|
||||
wget https://raw.githubusercontent.com/rhythmcao/QNLI/master/data/QNLI/dev.tsv
|
||||
|
||||
mkdir QNLI_dataset
|
||||
mv *.tsv QNLI_dataset
|
||||
```
|
||||
|
||||
### Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||
|
||||
```bash
|
||||
!python /content/BERT-of-Theseus/run_glue.py \
|
||||
--model_name_or_path deepset/bert-base-cased-squad2 \
|
||||
--task_name qnli \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--data_dir /content/QNLI_dataset \
|
||||
--max_seq_length 128 \
|
||||
--per_gpu_train_batch_size 32 \
|
||||
--per_gpu_eval_batch_size 32 \
|
||||
--learning_rate 2e-5 \
|
||||
--save_steps 2000 \
|
||||
--num_train_epochs 50 \
|
||||
--output_dir /content/ouput_dir \
|
||||
--evaluate_during_training \
|
||||
--replacing_rate 0.7 \
|
||||
--steps_for_replacing 2500
|
||||
```
|
||||
|
||||
## Metrics:
|
||||
|
||||
| Model | Accuracy |
|
||||
|-----------------|------|
|
||||
| BERT-base | 91.2 |
|
||||
| BERT-of-Theseus | 88.8 |
|
||||
| [bert-uncased-finetuned-qnli](https://huggingface.co/mrm8488/bert-uncased-finetuned-qnli) | 87.2
|
||||
| DistillBERT | 85.3 |
|
||||
|
||||
|
||||
|
||||
|
||||
> [See all my models](https://huggingface.co/models?search=mrm8488)
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
language:
|
||||
- chinese
|
||||
---
|
||||
|
||||
# albert_chinese_base
|
||||
|
||||
This a albert_chinese_base model from [Google's github](https://github.com/google-research/ALBERT)
|
||||
converted by huggingface's [script](https://github.com/huggingface/transformers/blob/master/src/transformers/convert_albert_original_tf_checkpoint_to_pytorch.py)
|
||||
|
||||
## Attention (注意)
|
||||
|
||||
Since sentencepiece is not used in albert_chinese_base model
|
||||
you have to call BertTokenizer instead of AlbertTokenizer !!!
|
||||
we can eval it using an example on MaskedLM
|
||||
|
||||
由於 albert_chinese_base 模型沒有用 sentencepiece
|
||||
用AlbertTokenizer會載不進詞表,因此需要改用BertTokenizer !!!
|
||||
我們可以跑MaskedLM預測來驗證這個做法是否正確
|
||||
|
||||
## Justify (驗證有效性)
|
||||
[colab trial](https://colab.research.google.com/drive/1Wjz48Uws6-VuSHv_-DcWLilv77-AaYgj)
|
||||
```python
|
||||
from transformers import *
|
||||
import torch
|
||||
from torch.nn.functional import softmax
|
||||
|
||||
pretrained = 'voidful/albert_chinese_base'
|
||||
tokenizer = BertTokenizer.from_pretrained(pretrained)
|
||||
model = AlbertForMaskedLM.from_pretrained(pretrained)
|
||||
|
||||
inputtext = "今天[MASK]情很好"
|
||||
|
||||
maskpos = tokenizer.encode(inputtext, add_special_tokens=True).index(103)
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode(inputtext, add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
logit_prob = softmax(prediction_scores[0, maskpos]).data.tolist()
|
||||
predicted_index = torch.argmax(prediction_scores[0, maskpos]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
print(predicted_token,logit_prob[predicted_index])
|
||||
```
|
||||
Result: `感 0.36333346366882324`
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
language:
|
||||
- chinese
|
||||
---
|
||||
|
||||
# albert_chinese_large
|
||||
|
||||
This a albert_chinese_large model from [Google's github](https://github.com/google-research/ALBERT)
|
||||
converted by huggingface's [script](https://github.com/huggingface/transformers/blob/master/src/transformers/convert_albert_original_tf_checkpoint_to_pytorch.py)
|
||||
|
||||
## Attention (注意)
|
||||
|
||||
Since sentencepiece is not used in albert_chinese_large model
|
||||
you have to call BertTokenizer instead of AlbertTokenizer !!!
|
||||
we can eval it using an example on MaskedLM
|
||||
|
||||
由於 albert_chinese_large 模型沒有用 sentencepiece
|
||||
用AlbertTokenizer會載不進詞表,因此需要改用BertTokenizer !!!
|
||||
我們可以跑MaskedLM預測來驗證這個做法是否正確
|
||||
|
||||
## Justify (驗證有效性)
|
||||
[colab trial](https://colab.research.google.com/drive/1Wjz48Uws6-VuSHv_-DcWLilv77-AaYgj)
|
||||
```python
|
||||
from transformers import *
|
||||
import torch
|
||||
from torch.nn.functional import softmax
|
||||
|
||||
pretrained = 'voidful/albert_chinese_large'
|
||||
tokenizer = BertTokenizer.from_pretrained(pretrained)
|
||||
model = AlbertForMaskedLM.from_pretrained(pretrained)
|
||||
|
||||
inputtext = "今天[MASK]情很好"
|
||||
|
||||
maskpos = tokenizer.encode(inputtext, add_special_tokens=True).index(103)
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode(inputtext, add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
logit_prob = softmax(prediction_scores[0, maskpos]).data.tolist()
|
||||
predicted_index = torch.argmax(prediction_scores[0, maskpos]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
print(predicted_token,logit_prob[predicted_index])
|
||||
```
|
||||
Result: `心 0.9422469735145569`
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
language:
|
||||
- chinese
|
||||
---
|
||||
|
||||
# albert_chinese_small
|
||||
|
||||
This a albert_chinese_small model from [brightmart/albert_zh project](https://github.com/brightmart/albert_zh), albert_small_google_zh model
|
||||
converted by huggingface's [script](https://github.com/huggingface/transformers/blob/master/src/transformers/convert_albert_original_tf_checkpoint_to_pytorch.py)
|
||||
|
||||
## Attention (注意)
|
||||
|
||||
Since sentencepiece is not used in albert_chinese_small model
|
||||
you have to call BertTokenizer instead of AlbertTokenizer !!!
|
||||
we can eval it using an example on MaskedLM
|
||||
|
||||
由於 albert_chinese_small 模型沒有用 sentencepiece
|
||||
用AlbertTokenizer會載不進詞表,因此需要改用BertTokenizer !!!
|
||||
我們可以跑MaskedLM預測來驗證這個做法是否正確
|
||||
|
||||
## Justify (驗證有效性)
|
||||
[colab trial](https://colab.research.google.com/drive/1Wjz48Uws6-VuSHv_-DcWLilv77-AaYgj)
|
||||
```python
|
||||
from transformers import *
|
||||
import torch
|
||||
from torch.nn.functional import softmax
|
||||
|
||||
pretrained = 'voidful/albert_chinese_small'
|
||||
tokenizer = BertTokenizer.from_pretrained(pretrained)
|
||||
model = AlbertForMaskedLM.from_pretrained(pretrained)
|
||||
|
||||
inputtext = "今天[MASK]情很好"
|
||||
|
||||
maskpos = tokenizer.encode(inputtext, add_special_tokens=True).index(103)
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode(inputtext, add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
logit_prob = softmax(prediction_scores[0, maskpos]).data.tolist()
|
||||
predicted_index = torch.argmax(prediction_scores[0, maskpos]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
print(predicted_token,logit_prob[predicted_index])
|
||||
```
|
||||
Result: `感 0.6390823125839233`
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
language:
|
||||
- chinese
|
||||
---
|
||||
|
||||
# albert_chinese_tiny
|
||||
|
||||
This a albert_chinese_tiny model from [brightmart/albert_zh project](https://github.com/brightmart/albert_zh), albert_tiny_google_zh model
|
||||
converted by huggingface's [script](https://github.com/huggingface/transformers/blob/master/src/transformers/convert_albert_original_tf_checkpoint_to_pytorch.py)
|
||||
|
||||
## Attention (注意)
|
||||
|
||||
Since sentencepiece is not used in albert_chinese_tiny model
|
||||
you have to call BertTokenizer instead of AlbertTokenizer !!!
|
||||
we can eval it using an example on MaskedLM
|
||||
|
||||
由於 albert_chinese_tiny 模型沒有用 sentencepiece
|
||||
用AlbertTokenizer會載不進詞表,因此需要改用BertTokenizer !!!
|
||||
我們可以跑MaskedLM預測來驗證這個做法是否正確
|
||||
|
||||
## Justify (驗證有效性)
|
||||
[colab trial](https://colab.research.google.com/drive/1Wjz48Uws6-VuSHv_-DcWLilv77-AaYgj)
|
||||
```python
|
||||
from transformers import *
|
||||
import torch
|
||||
from torch.nn.functional import softmax
|
||||
|
||||
pretrained = 'voidful/albert_chinese_tiny'
|
||||
tokenizer = BertTokenizer.from_pretrained(pretrained)
|
||||
model = AlbertForMaskedLM.from_pretrained(pretrained)
|
||||
|
||||
inputtext = "今天[MASK]情很好"
|
||||
|
||||
maskpos = tokenizer.encode(inputtext, add_special_tokens=True).index(103)
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode(inputtext, add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
logit_prob = softmax(prediction_scores[0, maskpos]).data.tolist()
|
||||
predicted_index = torch.argmax(prediction_scores[0, maskpos]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
print(predicted_token,logit_prob[predicted_index])
|
||||
```
|
||||
Result: `感 0.40312355756759644`
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
language:
|
||||
- chinese
|
||||
---
|
||||
|
||||
# albert_chinese_xlarge
|
||||
|
||||
This a albert_chinese_xlarge model from [Google's github](https://github.com/google-research/ALBERT)
|
||||
converted by huggingface's [script](https://github.com/huggingface/transformers/blob/master/src/transformers/convert_albert_original_tf_checkpoint_to_pytorch.py)
|
||||
|
||||
## Attention (注意)
|
||||
|
||||
Since sentencepiece is not used in albert_chinese_xlarge model
|
||||
you have to call BertTokenizer instead of AlbertTokenizer !!!
|
||||
we can eval it using an example on MaskedLM
|
||||
|
||||
由於 albert_chinese_xlarge 模型沒有用 sentencepiece
|
||||
用AlbertTokenizer會載不進詞表,因此需要改用BertTokenizer !!!
|
||||
我們可以跑MaskedLM預測來驗證這個做法是否正確
|
||||
|
||||
## Justify (驗證有效性)
|
||||
[colab trial](https://colab.research.google.com/drive/1Wjz48Uws6-VuSHv_-DcWLilv77-AaYgj)
|
||||
```python
|
||||
from transformers import *
|
||||
import torch
|
||||
from torch.nn.functional import softmax
|
||||
|
||||
pretrained = 'voidful/albert_chinese_xlarge'
|
||||
tokenizer = BertTokenizer.from_pretrained(pretrained)
|
||||
model = AlbertForMaskedLM.from_pretrained(pretrained)
|
||||
|
||||
inputtext = "今天[MASK]情很好"
|
||||
|
||||
maskpos = tokenizer.encode(inputtext, add_special_tokens=True).index(103)
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode(inputtext, add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
logit_prob = softmax(prediction_scores[0, maskpos]).data.tolist()
|
||||
predicted_index = torch.argmax(prediction_scores[0, maskpos]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
print(predicted_token,logit_prob[predicted_index])
|
||||
```
|
||||
Result: `心 0.9942440390586853`
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
language:
|
||||
- chinese
|
||||
---
|
||||
|
||||
# albert_chinese_xxlarge
|
||||
|
||||
This a albert_chinese_xxlarge model from [Google's github](https://github.com/google-research/ALBERT)
|
||||
converted by huggingface's [script](https://github.com/huggingface/transformers/blob/master/src/transformers/convert_albert_original_tf_checkpoint_to_pytorch.py)
|
||||
|
||||
## Attention (注意)
|
||||
|
||||
Since sentencepiece is not used in albert_chinese_xxlarge model
|
||||
you have to call BertTokenizer instead of AlbertTokenizer !!!
|
||||
we can eval it using an example on MaskedLM
|
||||
|
||||
由於 albert_chinese_xxlarge 模型沒有用 sentencepiece
|
||||
用AlbertTokenizer會載不進詞表,因此需要改用BertTokenizer !!!
|
||||
我們可以跑MaskedLM預測來驗證這個做法是否正確
|
||||
|
||||
## Justify (驗證有效性)
|
||||
[colab trial](https://colab.research.google.com/drive/1Wjz48Uws6-VuSHv_-DcWLilv77-AaYgj)
|
||||
```python
|
||||
from transformers import *
|
||||
import torch
|
||||
from torch.nn.functional import softmax
|
||||
|
||||
pretrained = 'voidful/albert_chinese_xxlarge'
|
||||
tokenizer = BertTokenizer.from_pretrained(pretrained)
|
||||
model = AlbertForMaskedLM.from_pretrained(pretrained)
|
||||
|
||||
inputtext = "今天[MASK]情很好"
|
||||
|
||||
maskpos = tokenizer.encode(inputtext, add_special_tokens=True).index(103)
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode(inputtext, add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
logit_prob = softmax(prediction_scores[0, maskpos]).data.tolist()
|
||||
predicted_index = torch.argmax(prediction_scores[0, maskpos]).item()
|
||||
predicted_token = tokenizer.convert_ids_to_tokens([predicted_index])[0]
|
||||
print(predicted_token,logit_prob[predicted_index])
|
||||
```
|
||||
Result: `心 0.995713472366333`
|
||||
@@ -0,0 +1,370 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## Tokenization doesn't have to be slow !\n",
|
||||
"\n",
|
||||
"### Introduction\n",
|
||||
"\n",
|
||||
"Before going deep into any Machine Learning or Deep Learning Natural Language Processing models, every practitioner\n",
|
||||
"should find a way to map raw input strings to a representation understandable by a trainable model.\n",
|
||||
"\n",
|
||||
"One very simple approach would be to split inputs over every space and assign an identifier to each word. This approach\n",
|
||||
"would look similar to the code below in python\n",
|
||||
"\n",
|
||||
"```python\n",
|
||||
"s = \"very long corpus...\"\n",
|
||||
"words = s.split(\" \") # Split over space\n",
|
||||
"vocabulary = dict(enumerate(set(words))) # Map storing the word to it's corresponding id\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"This approach might work well if your vocabulary remains small as it would store every word (or **token**) present in your original\n",
|
||||
"input. Moreover, word variations like \"cat\" and \"cats\" would not share the same identifiers even if their meaning is \n",
|
||||
"quite close.\n",
|
||||
"\n",
|
||||
"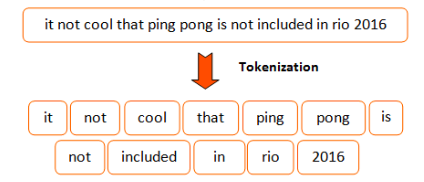\n",
|
||||
"\n",
|
||||
"### Subtoken Tokenization\n",
|
||||
"\n",
|
||||
"To overcome the issues described above, recent works have been done on tokenization, leveraging \"subtoken\" tokenization.\n",
|
||||
"**Subtokens** extends the previous splitting strategy to furthermore explode a word into grammatically logicial sub-components learned\n",
|
||||
"from the data.\n",
|
||||
"\n",
|
||||
"Taking our previous example of the words __cat__ and __cats__, a sub-tokenization of the word __cats__ would be [cat, ##s]. Where the prefix _\"##\"_ indicates a subtoken of the initial input. \n",
|
||||
"Such training algorithms might extract sub-tokens such as _\"##ing\"_, _\"##ed\"_ over English corpus.\n",
|
||||
"\n",
|
||||
"As you might think of, this kind of sub-tokens construction leveraging compositions of _\"pieces\"_ overall reduces the size\n",
|
||||
"of the vocabulary you have to carry to train a Machine Learning model. On the other side, as one token might be exploded\n",
|
||||
"into multiple subtokens, the input of your model might increase and become an issue on model with non-linear complexity over the input sequence's length. \n",
|
||||
" \n",
|
||||
"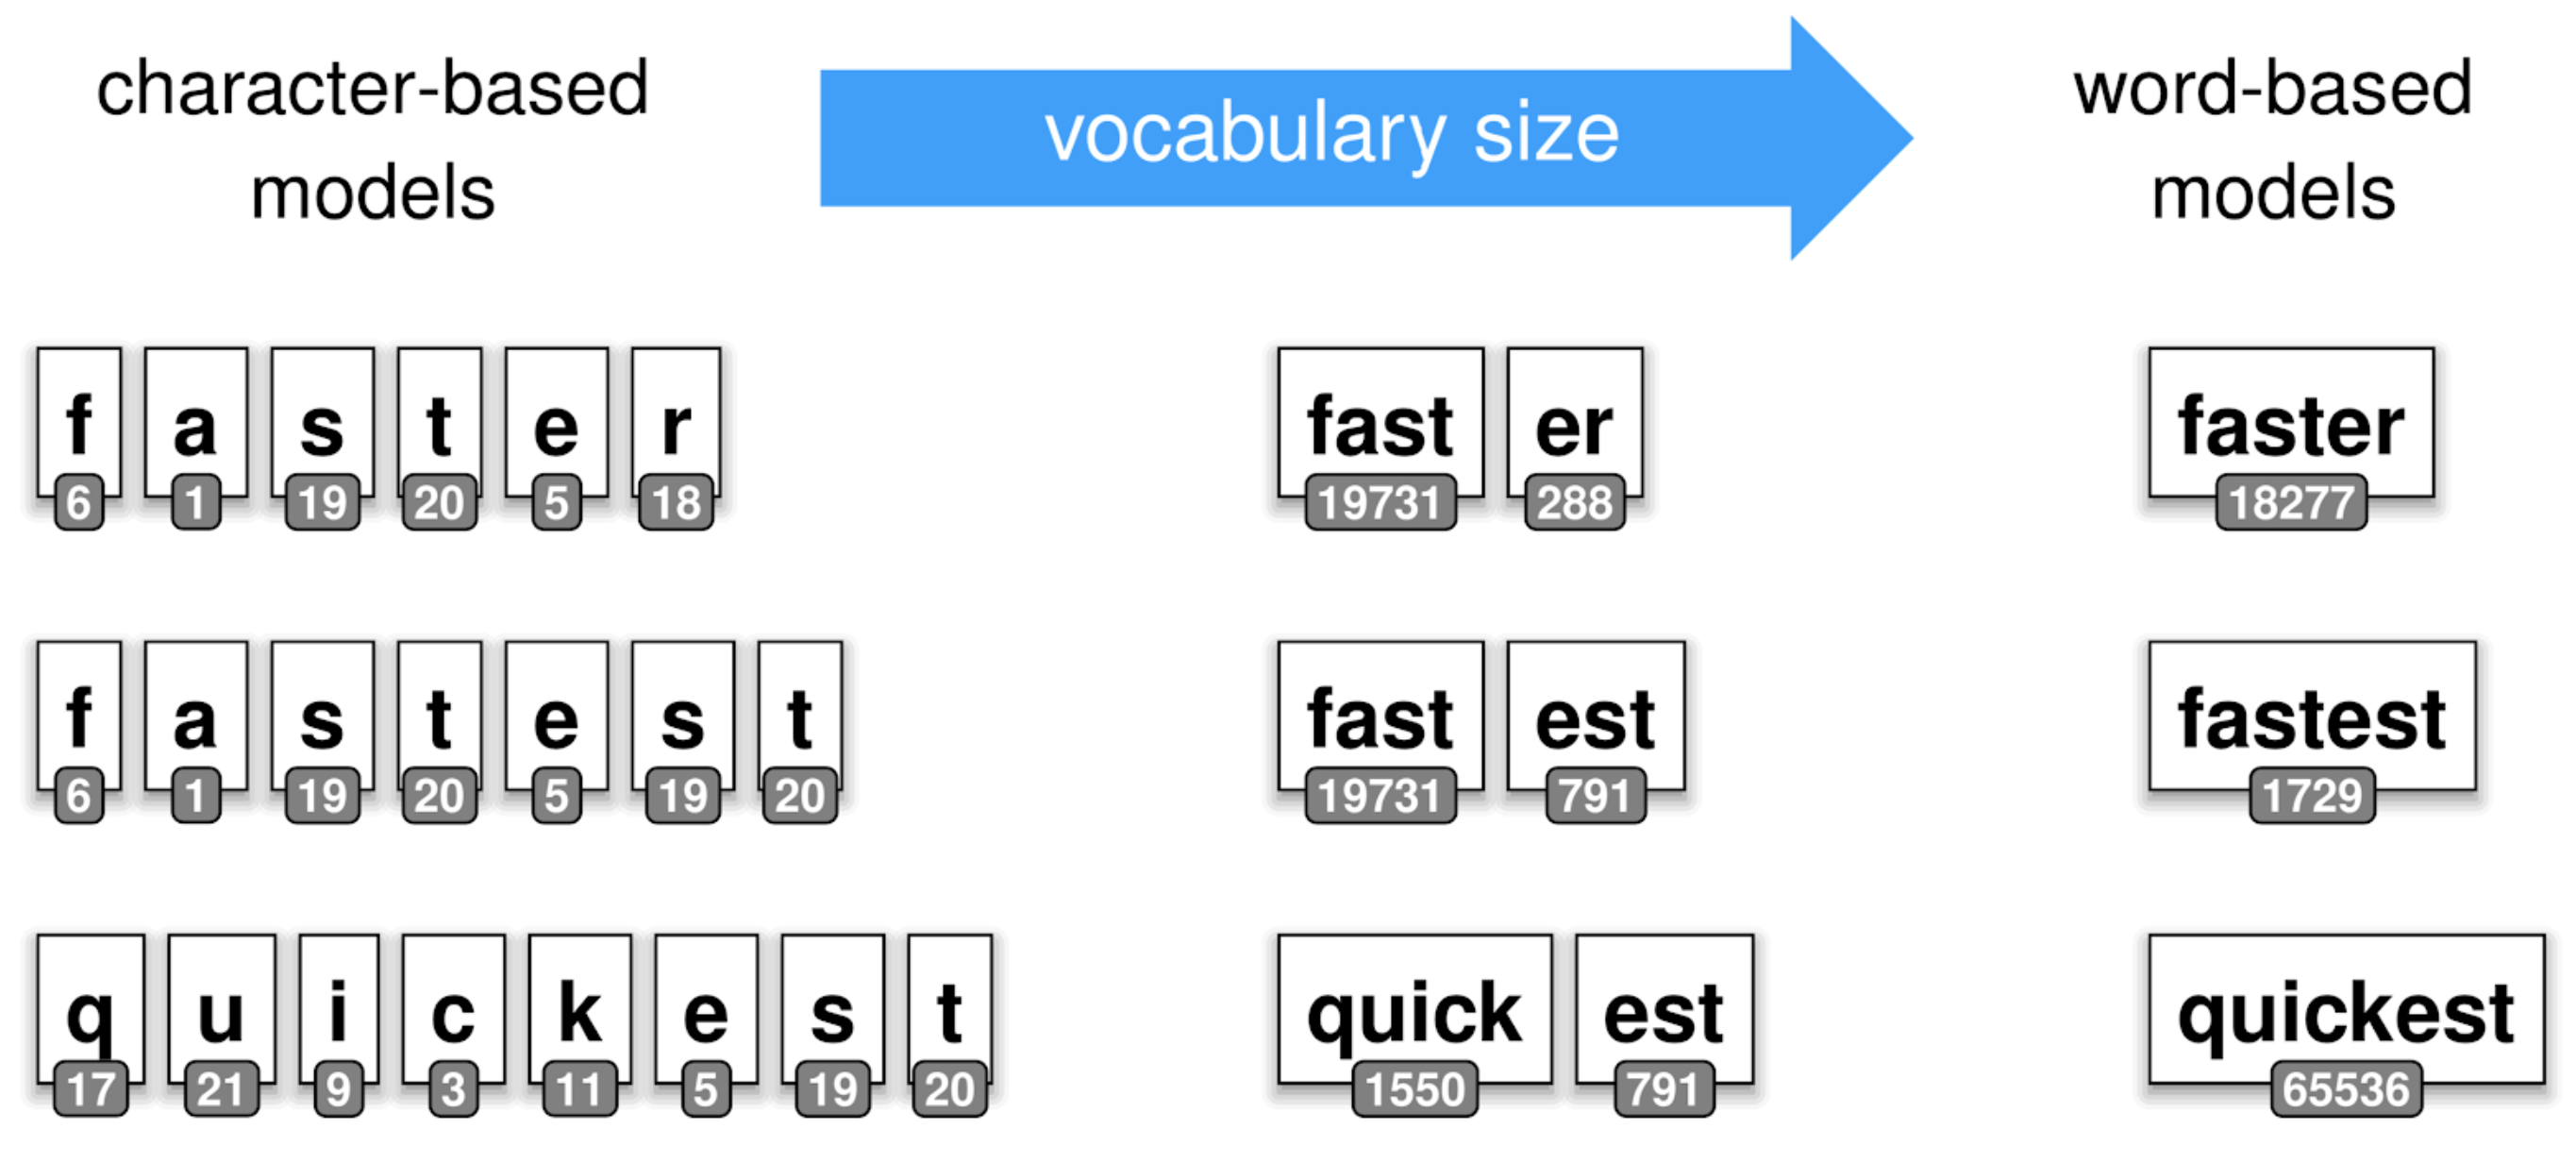\n",
|
||||
" \n",
|
||||
"Among all the tokenization algorithms, we can highlight a few subtokens algorithms used in Transformers-based SoTA models : \n",
|
||||
"\n",
|
||||
"- [Byte Pair Encoding (BPE) - Neural Machine Translation of Rare Words with Subword Units (Sennrich et al., 2015)](https://arxiv.org/abs/1508.07909)\n",
|
||||
"- [Word Piece - Japanese and Korean voice search (Schuster, M., and Nakajima, K., 2015)](https://research.google/pubs/pub37842/)\n",
|
||||
"- [Unigram Language Model - Subword Regularization: Improving Neural Network Translation Models with Multiple Subword Candidates (Kudo, T., 2018)](https://arxiv.org/abs/1804.10959)\n",
|
||||
"- [Sentence Piece - A simple and language independent subword tokenizer and detokenizer for Neural Text Processing (Taku Kudo and John Richardson, 2018)](https://arxiv.org/abs/1808.06226)\n",
|
||||
"\n",
|
||||
"Going through all of them is out of the scope of this notebook, so we will just highlight how you can use them.\n",
|
||||
"\n",
|
||||
"### @huggingface/tokenizers library \n",
|
||||
"Along with the transformers library, we @huggingface provide a blazing fast tokenization library\n",
|
||||
"able to train, tokenize and decode dozens of Gb/s of text on a common multi-core machine.\n",
|
||||
"\n",
|
||||
"The library is written in Rust allowing us to take full advantage of multi-core parallel computations in a native and memory-aware way, on-top of which \n",
|
||||
"we provide bindings for Python and NodeJS (more bindings may be added in the future). \n",
|
||||
"\n",
|
||||
"We designed the library so that it provides all the required blocks to create end-to-end tokenizers in an interchangeable way. In that sense, we provide\n",
|
||||
"these various components: \n",
|
||||
"\n",
|
||||
"- **Normalizer**: Executes all the initial transformations over the initial input string. For example when you need to\n",
|
||||
"lowercase some text, maybe strip it, or even apply one of the common unicode normalization process, you will add a Normalizer. \n",
|
||||
"- **PreTokenizer**: In charge of splitting the initial input string. That's the component that decides where and how to\n",
|
||||
"pre-segment the origin string. The simplest example would be like we saw before, to simply split on spaces.\n",
|
||||
"- **Model**: Handles all the sub-token discovery and generation, this part is trainable and really dependant\n",
|
||||
" of your input data.\n",
|
||||
"- **Post-Processor**: Provides advanced construction features to be compatible with some of the Transformers-based SoTA\n",
|
||||
"models. For instance, for BERT it would wrap the tokenized sentence around [CLS] and [SEP] tokens.\n",
|
||||
"- **Decoder**: In charge of mapping back a tokenized input to the original string. The decoder is usually chosen according\n",
|
||||
"to the `PreTokenizer` we used previously.\n",
|
||||
"- **Trainer**: Provides training capabilities to each model.\n",
|
||||
"\n",
|
||||
"For each of the components above we provide multiple implementations:\n",
|
||||
"\n",
|
||||
"- **Normalizer**: Lowercase, Unicode (NFD, NFKD, NFC, NFKC), Bert, Strip, ...\n",
|
||||
"- **PreTokenizer**: ByteLevel, WhitespaceSplit, CharDelimiterSplit, Metaspace, ...\n",
|
||||
"- **Model**: WordLevel, BPE, WordPiece\n",
|
||||
"- **Post-Processor**: BertProcessor, ...\n",
|
||||
"- **Decoder**: WordLevel, BPE, WordPiece, ...\n",
|
||||
"\n",
|
||||
"All of these building blocks can be combined to create working tokenization pipelines. \n",
|
||||
"In the next section we will go over our first pipeline."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Alright, now we are ready to implement our first tokenization pipeline through `tokenizers`. \n",
|
||||
"\n",
|
||||
"For this, we will train a Byte-Pair Encoding (BPE) tokenizer on a quite small input for the purpose of this notebook.\n",
|
||||
"We will work with [the file from Peter Norving](https://www.google.com/url?sa=t&rct=j&q=&esrc=s&source=web&cd=1&cad=rja&uact=8&ved=2ahUKEwjYp9Ppru_nAhUBzIUKHfbUAG8QFjAAegQIBhAB&url=https%3A%2F%2Fnorvig.com%2Fbig.txt&usg=AOvVaw2ed9iwhcP1RKUiEROs15Dz).\n",
|
||||
"This file contains around 130.000 lines of raw text that will be processed by the library to generate a working tokenizer.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install tokenizers"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"BIG_FILE_URL = 'https://raw.githubusercontent.com/dscape/spell/master/test/resources/big.txt'\n",
|
||||
"\n",
|
||||
"# Let's download the file and save it somewhere\n",
|
||||
"from requests import get\n",
|
||||
"with open('big.txt', 'wb') as big_f:\n",
|
||||
" response = get(BIG_FILE_URL, )\n",
|
||||
" \n",
|
||||
" if response.status_code == 200:\n",
|
||||
" big_f.write(response.content)\n",
|
||||
" else:\n",
|
||||
" print(\"Unable to get the file: {}\".format(response.reason))\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
" \n",
|
||||
"Now that we have our training data we need to create the overall pipeline for the tokenizer\n",
|
||||
" "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# For the user's convenience `tokenizers` provides some very high-level classes encapsulating\n",
|
||||
"# the overall pipeline for various well-known tokenization algorithm. \n",
|
||||
"# Everything described below can be replaced by the ByteLevelBPETokenizer class. \n",
|
||||
"\n",
|
||||
"from tokenizers import Tokenizer\n",
|
||||
"from tokenizers.decoders import ByteLevel as ByteLevelDecoder\n",
|
||||
"from tokenizers.models import BPE\n",
|
||||
"from tokenizers.normalizers import Lowercase, NFKC, Sequence\n",
|
||||
"from tokenizers.pre_tokenizers import ByteLevel\n",
|
||||
"\n",
|
||||
"# First we create an empty Byte-Pair Encoding model (i.e. not trained model)\n",
|
||||
"tokenizer = Tokenizer(BPE.empty())\n",
|
||||
"\n",
|
||||
"# Then we enable lower-casing and unicode-normalization\n",
|
||||
"# The Sequence normalizer allows us to combine multiple Normalizer that will be\n",
|
||||
"# executed in order.\n",
|
||||
"tokenizer.normalizer = Sequence([\n",
|
||||
" NFKC(),\n",
|
||||
" Lowercase()\n",
|
||||
"])\n",
|
||||
"\n",
|
||||
"# Our tokenizer also needs a pre-tokenizer responsible for converting the input to a ByteLevel representation.\n",
|
||||
"tokenizer.pre_tokenizer = ByteLevel()\n",
|
||||
"\n",
|
||||
"# And finally, let's plug a decoder so we can recover from a tokenized input to the original one\n",
|
||||
"tokenizer.decoder = ByteLevelDecoder()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"The overall pipeline is now ready to be trained on the corpus we downloaded earlier in this notebook."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 11,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Trained vocab size: 25000\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"from tokenizers.trainers import BpeTrainer\n",
|
||||
"\n",
|
||||
"# We initialize our trainer, giving him the details about the vocabulary we want to generate\n",
|
||||
"trainer = BpeTrainer(vocab_size=25000, show_progress=True, initial_alphabet=ByteLevel.alphabet())\n",
|
||||
"tokenizer.train(trainer, [\"big.txt\"])\n",
|
||||
"\n",
|
||||
"print(\"Trained vocab size: {}\".format(tokenizer.get_vocab_size()))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Et voilà ! You trained your very first tokenizer from scratch using `tokenizers`. Of course, this \n",
|
||||
"covers only the basics, and you may want to have a look at the `add_special_tokens` or `special_tokens` parameters\n",
|
||||
"on the `Trainer` class, but the overall process should be very similar.\n",
|
||||
"\n",
|
||||
"We can save the content of the model to reuse it later."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 12,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"['./vocab.json', './merges.txt']"
|
||||
]
|
||||
},
|
||||
"execution_count": 12,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# You will see the generated files in the output.\n",
|
||||
"tokenizer.model.save('.')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Now, let load the trained model and start using out newly trained tokenizer"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 13,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Encoded string: ['Ġthis', 'Ġis', 'Ġa', 'Ġsimple', 'Ġin', 'put', 'Ġto', 'Ġbe', 'Ġtoken', 'ized']\n",
|
||||
"Decoded string: this is a simple input to be tokenized\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Let's tokenizer a simple input\n",
|
||||
"tokenizer.model = BPE.from_files('vocab.json', 'merges.txt')\n",
|
||||
"encoding = tokenizer.encode(\"This is a simple input to be tokenized\")\n",
|
||||
"\n",
|
||||
"print(\"Encoded string: {}\".format(encoding.tokens))\n",
|
||||
"\n",
|
||||
"decoded = tokenizer.decode(encoding.ids)\n",
|
||||
"print(\"Decoded string: {}\".format(decoded))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"The Encoding structure exposes multiple properties which are useful when working with transformers models\n",
|
||||
"\n",
|
||||
"- normalized_str: The input string after normalization (lower-casing, unicode, stripping, etc.)\n",
|
||||
"- original_str: The input string as it was provided\n",
|
||||
"- tokens: The generated tokens with their string representation\n",
|
||||
"- input_ids: The generated tokens with their integer representation\n",
|
||||
"- attention_mask: If your input has been padded by the tokenizer, then this would be a vector of 1 for any non padded token and 0 for padded ones.\n",
|
||||
"- special_token_mask: If your input contains special tokens such as [CLS], [SEP], [MASK], [PAD], then this would be a vector with 1 in places where a special token has been added.\n",
|
||||
"- type_ids: If your was made of multiple \"parts\" such as (question, context), then this would be a vector with for each token the segment it belongs to.\n",
|
||||
"- overflowing: If your has been truncated into multiple subparts because of a length limit (for BERT for example the sequence length is limited to 512), this will contain all the remaining overflowing parts."
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.7.6"
|
||||
},
|
||||
"pycharm": {
|
||||
"stem_cell": {
|
||||
"cell_type": "raw",
|
||||
"metadata": {
|
||||
"collapsed": false
|
||||
},
|
||||
"source": []
|
||||
}
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 1
|
||||
}
|
||||
@@ -0,0 +1,594 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"collapsed": true,
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## Introduction\n",
|
||||
"The transformers library is an open-source, community-based repository to train, use and share models based on \n",
|
||||
"the Transformer architecture [(Vaswani & al., 2017)](https://arxiv.org/abs/1706.03762) such as Bert [(Devlin & al., 2018)](https://arxiv.org/abs/1810.04805),\n",
|
||||
"Roberta [(Liu & al., 2019)](https://arxiv.org/abs/1907.11692), GPT2 [(Radford & al., 2019)](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf),\n",
|
||||
"XLNet [(Yang & al., 2019)](https://arxiv.org/abs/1906.08237), etc. \n",
|
||||
"\n",
|
||||
"Along with the models, the library contains multiple variations of each of them for a large variety of \n",
|
||||
"downstream-tasks like **Named Entity Recognition (NER)**, **Sentiment Analysis**, \n",
|
||||
"**Language Modeling**, **Question Answering** and so on.\n",
|
||||
"\n",
|
||||
"## Before Transformer\n",
|
||||
"\n",
|
||||
"Back to 2017, most of the people using Neural Networks when working on Natural Language Processing were relying on \n",
|
||||
"sequential processing of the input through [Recurrent Neural Network (RNN)](https://en.wikipedia.org/wiki/Recurrent_neural_network).\n",
|
||||
"\n",
|
||||
"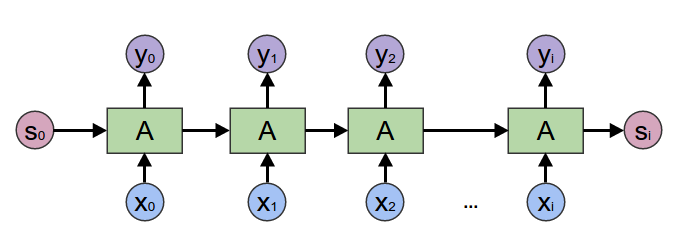 \n",
|
||||
"\n",
|
||||
"RNNs were performing well on large variety of tasks involving sequential dependency over the input sequence. \n",
|
||||
"However, this sequentially-dependent process had issues modeling very long range dependencies and \n",
|
||||
"was not well suited for the kind of hardware we're currently leveraging due to bad parallelization capabilities. \n",
|
||||
"\n",
|
||||
"Some extensions were provided by the academic community, such as Bidirectional RNN ([Schuster & Paliwal., 1997](https://www.researchgate.net/publication/3316656_Bidirectional_recurrent_neural_networks), [Graves & al., 2005](https://mediatum.ub.tum.de/doc/1290195/file.pdf)), \n",
|
||||
"which can be seen as a concatenation of two sequential process, one going forward, the other one going backward over the sequence input.\n",
|
||||
"\n",
|
||||
"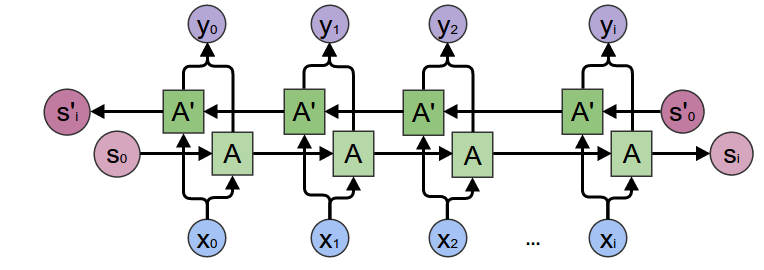\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"And also, the Attention mechanism, which introduced a good improvement over \"raw\" RNNs by giving \n",
|
||||
"a learned, weighted-importance to each element in the sequence, allowing the model to focus on important elements.\n",
|
||||
"\n",
|
||||
" \n",
|
||||
"\n",
|
||||
"## Then comes the Transformer \n",
|
||||
"\n",
|
||||
"The Transformers era originally started from the work of [(Vaswani & al., 2017)](https://arxiv.org/abs/1706.03762) who\n",
|
||||
"demonstrated its superiority over [Recurrent Neural Network (RNN)](https://en.wikipedia.org/wiki/Recurrent_neural_network)\n",
|
||||
"on translation tasks but it quickly extended to almost all the tasks RNNs were State-of-the-Art at that time.\n",
|
||||
"\n",
|
||||
"One advantage of Transformer over its RNN counterpart was its non sequential attention model. Remember, the RNNs had to\n",
|
||||
"iterate over each element of the input sequence one-by-one and carry an \"updatable-state\" between each hop. With Transformer, the model is able to look at every position in the sequence, at the same time, in one operation.\n",
|
||||
"\n",
|
||||
"For a deep-dive into the Transformer architecture, [The Annotated Transformer](https://nlp.seas.harvard.edu/2018/04/03/attention.html#encoder-and-decoder-stacks) \n",
|
||||
"will drive you along all the details of the paper.\n",
|
||||
"\n",
|
||||
""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## Getting started with transformers\n",
|
||||
"\n",
|
||||
"For the rest of this notebook, we will use the [BERT (Devlin & al., 2018)](https://arxiv.org/abs/1810.04805) architecture, as it's the most simple and there are plenty of content about it\n",
|
||||
"over the internet, it will be easy to dig more over this architecture if you want to.\n",
|
||||
"\n",
|
||||
"The transformers library allows you to benefits from large, pretrained language models without requiring a huge and costly computational\n",
|
||||
"infrastructure. Most of the State-of-the-Art models are provided directly by their author and made available in the library \n",
|
||||
"in PyTorch and TensorFlow in a transparent and interchangeable way. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
},
|
||||
"scrolled": true
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Requirement already satisfied: transformers in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (2.5.1)\n",
|
||||
"Requirement already satisfied: filelock in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (3.0.12)\n",
|
||||
"Requirement already satisfied: sentencepiece in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (0.1.83)\n",
|
||||
"Requirement already satisfied: boto3 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (1.12.0)\n",
|
||||
"Requirement already satisfied: requests in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (2.22.0)\n",
|
||||
"Requirement already satisfied: numpy in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (1.18.1)\n",
|
||||
"Requirement already satisfied: sacremoses in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (0.0.35)\n",
|
||||
"Requirement already satisfied: tokenizers==0.5.2 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (0.5.2)\n",
|
||||
"Requirement already satisfied: regex!=2019.12.17 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (2020.1.8)\n",
|
||||
"Requirement already satisfied: tqdm>=4.27 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from transformers) (4.42.1)\n",
|
||||
"Requirement already satisfied: s3transfer<0.4.0,>=0.3.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from boto3->transformers) (0.3.3)\n",
|
||||
"Requirement already satisfied: botocore<1.16.0,>=1.15.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from boto3->transformers) (1.15.0)\n",
|
||||
"Requirement already satisfied: jmespath<1.0.0,>=0.7.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from boto3->transformers) (0.9.4)\n",
|
||||
"Requirement already satisfied: certifi>=2017.4.17 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests->transformers) (2019.11.28)\n",
|
||||
"Requirement already satisfied: idna<2.9,>=2.5 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests->transformers) (2.8)\n",
|
||||
"Requirement already satisfied: urllib3!=1.25.0,!=1.25.1,<1.26,>=1.21.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests->transformers) (1.25.8)\n",
|
||||
"Requirement already satisfied: chardet<3.1.0,>=3.0.2 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests->transformers) (3.0.4)\n",
|
||||
"Requirement already satisfied: joblib in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from sacremoses->transformers) (0.14.0)\n",
|
||||
"Requirement already satisfied: click in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from sacremoses->transformers) (7.0)\n",
|
||||
"Requirement already satisfied: six in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from sacremoses->transformers) (1.14.0)\n",
|
||||
"Requirement already satisfied: docutils<0.16,>=0.10 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from botocore<1.16.0,>=1.15.0->boto3->transformers) (0.15.2)\n",
|
||||
"Requirement already satisfied: python-dateutil<3.0.0,>=2.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from botocore<1.16.0,>=1.15.0->boto3->transformers) (2.8.1)\n",
|
||||
"Requirement already satisfied: tensorflow==2.1.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (2.1.0)\n",
|
||||
"Requirement already satisfied: termcolor>=1.1.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.1.0)\n",
|
||||
"Requirement already satisfied: keras-preprocessing>=1.1.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.1.0)\n",
|
||||
"Requirement already satisfied: opt-einsum>=2.3.2 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (3.1.0)\n",
|
||||
"Requirement already satisfied: protobuf>=3.8.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (3.11.4)\n",
|
||||
"Requirement already satisfied: numpy<2.0,>=1.16.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.18.1)\n",
|
||||
"Requirement already satisfied: tensorboard<2.2.0,>=2.1.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (2.1.0)\n",
|
||||
"Requirement already satisfied: keras-applications>=1.0.8 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.0.8)\n",
|
||||
"Requirement already satisfied: wrapt>=1.11.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.11.2)\n",
|
||||
"Requirement already satisfied: six>=1.12.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.14.0)\n",
|
||||
"Requirement already satisfied: tensorflow-estimator<2.2.0,>=2.1.0rc0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (2.1.0)\n",
|
||||
"Requirement already satisfied: scipy==1.4.1; python_version >= \"3\" in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.4.1)\n",
|
||||
"Requirement already satisfied: google-pasta>=0.1.6 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (0.1.8)\n",
|
||||
"Requirement already satisfied: wheel>=0.26; python_version >= \"3\" in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (0.34.2)\n",
|
||||
"Requirement already satisfied: grpcio>=1.8.6 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (1.16.1)\n",
|
||||
"Requirement already satisfied: absl-py>=0.7.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (0.9.0)\n",
|
||||
"Requirement already satisfied: gast==0.2.2 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (0.2.2)\n",
|
||||
"Requirement already satisfied: astor>=0.6.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorflow==2.1.0) (0.8.0)\n",
|
||||
"Requirement already satisfied: setuptools in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from protobuf>=3.8.0->tensorflow==2.1.0) (45.2.0.post20200210)\n",
|
||||
"Requirement already satisfied: google-auth<2,>=1.6.3 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (1.11.2)\n",
|
||||
"Requirement already satisfied: google-auth-oauthlib<0.5,>=0.4.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (0.4.1)\n",
|
||||
"Requirement already satisfied: markdown>=2.6.8 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (3.1.1)\n",
|
||||
"Requirement already satisfied: werkzeug>=0.11.15 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (1.0.0)\n",
|
||||
"Requirement already satisfied: requests<3,>=2.21.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (2.22.0)\n",
|
||||
"Requirement already satisfied: h5py in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from keras-applications>=1.0.8->tensorflow==2.1.0) (2.10.0)\n",
|
||||
"Requirement already satisfied: rsa<4.1,>=3.1.4 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from google-auth<2,>=1.6.3->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (4.0)\n",
|
||||
"Requirement already satisfied: cachetools<5.0,>=2.0.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from google-auth<2,>=1.6.3->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (4.0.0)\n",
|
||||
"Requirement already satisfied: pyasn1-modules>=0.2.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from google-auth<2,>=1.6.3->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (0.2.8)\n",
|
||||
"Requirement already satisfied: requests-oauthlib>=0.7.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from google-auth-oauthlib<0.5,>=0.4.1->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (1.3.0)\n",
|
||||
"Requirement already satisfied: idna<2.9,>=2.5 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests<3,>=2.21.0->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (2.8)\n",
|
||||
"Requirement already satisfied: certifi>=2017.4.17 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests<3,>=2.21.0->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (2019.11.28)\n",
|
||||
"Requirement already satisfied: chardet<3.1.0,>=3.0.2 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests<3,>=2.21.0->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (3.0.4)\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Requirement already satisfied: urllib3!=1.25.0,!=1.25.1,<1.26,>=1.21.1 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests<3,>=2.21.0->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (1.25.8)\r\n",
|
||||
"Requirement already satisfied: pyasn1>=0.1.3 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from rsa<4.1,>=3.1.4->google-auth<2,>=1.6.3->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (0.4.8)\r\n",
|
||||
"Requirement already satisfied: oauthlib>=3.0.0 in /usr/local/Caskroom/miniconda/base/envs/huggingface/lib/python3.7/site-packages (from requests-oauthlib>=0.7.0->google-auth-oauthlib<0.5,>=0.4.1->tensorboard<2.2.0,>=2.1.0->tensorflow==2.1.0) (3.1.0)\r\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"!pip install transformers\n",
|
||||
"!pip install tensorflow==2.1.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"<torch.autograd.grad_mode.set_grad_enabled at 0x102c0ce10>"
|
||||
]
|
||||
},
|
||||
"execution_count": 2,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import torch\n",
|
||||
"from transformers import AutoModel, AutoTokenizer, BertTokenizer\n",
|
||||
"\n",
|
||||
"torch.set_grad_enabled(False)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 3,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Store the model we want to use\n",
|
||||
"MODEL_NAME = \"bert-base-cased\"\n",
|
||||
"\n",
|
||||
"# We need to create the model and tokenizer\n",
|
||||
"model = AutoModel.from_pretrained(MODEL_NAME)\n",
|
||||
"tokenizer = AutoTokenizer.from_pretrained(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"With only the above two lines of code, you're ready to use a BERT pre-trained model. \n",
|
||||
"The tokenizers will allow us to map a raw textual input to a sequence of integers representing our textual input\n",
|
||||
"in a way the model can manipulate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 4,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Tokens: ['This', 'is', 'an', 'input', 'example']\n",
|
||||
"Tokens id: [1188, 1110, 1126, 7758, 1859]\n",
|
||||
"Tokens PyTorch: tensor([[ 101, 1188, 1110, 1126, 7758, 1859, 102]])\n",
|
||||
"Token wise output: torch.Size([1, 7, 768]), Pooled output: torch.Size([1, 768])\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Tokens comes from a process that splits the input into sub-entities with interesting linguistic properties. \n",
|
||||
"tokens = tokenizer.tokenize(\"This is an input example\")\n",
|
||||
"print(\"Tokens: {}\".format(tokens))\n",
|
||||
"\n",
|
||||
"# This is not sufficient for the model, as it requires integers as input, \n",
|
||||
"# not a problem, let's convert tokens to ids.\n",
|
||||
"tokens_ids = tokenizer.convert_tokens_to_ids(tokens)\n",
|
||||
"print(\"Tokens id: {}\".format(tokens_ids))\n",
|
||||
"\n",
|
||||
"# Add the required special tokens\n",
|
||||
"tokens_ids = tokenizer.build_inputs_with_special_tokens(tokens_ids)\n",
|
||||
"\n",
|
||||
"# We need to convert to a Deep Learning framework specific format, let's use PyTorch for now.\n",
|
||||
"tokens_pt = torch.tensor([tokens_ids])\n",
|
||||
"print(\"Tokens PyTorch: {}\".format(tokens_pt))\n",
|
||||
"\n",
|
||||
"# Now we're ready to go through BERT with out input\n",
|
||||
"outputs, pooled = model(tokens_pt)\n",
|
||||
"print(\"Token wise output: {}, Pooled output: {}\".format(outputs.shape, pooled.shape))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"As you can see, BERT outputs two tensors:\n",
|
||||
" - One with the generated representation for every token in the input `(1, NB_TOKENS, REPRESENTATION_SIZE)`\n",
|
||||
" - One with an aggregated representation for the whole input `(1, REPRESENTATION_SIZE)`\n",
|
||||
" \n",
|
||||
"The first, token-based, representation can be leveraged if your task requires to keep the sequence representation and you\n",
|
||||
"want to operate at a token-level. This is particularly useful for Named Entity Recognition and Question-Answering.\n",
|
||||
"\n",
|
||||
"The second, aggregated, representation is especially useful if you need to extract the overall context of the sequence and don't\n",
|
||||
"require a fine-grained token-leven. This is the case for Sentiment-Analysis of the sequence or Information Retrieval."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"The code you saw in the previous section introduced all the steps required to do simple model invocation.\n",
|
||||
"For more day-to-day usage, transformers provides you higher-level methods which will makes your NLP journey easier\n",
|
||||
"Let's improve our previous example"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 5,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"input_ids:\n",
|
||||
"\ttensor([[ 101, 1188, 1110, 1126, 7758, 1859, 102]])\n",
|
||||
"token_type_ids:\n",
|
||||
"\ttensor([[0, 0, 0, 0, 0, 0, 0]])\n",
|
||||
"attention_mask:\n",
|
||||
"\ttensor([[1, 1, 1, 1, 1, 1, 1]])\n",
|
||||
"Difference with previous code: (0.0, 0.0)\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# tokens = tokenizer.tokenize(\"This is an input example\")\n",
|
||||
"# tokens_ids = tokenizer.convert_tokens_to_ids(tokens)\n",
|
||||
"# tokens_pt = torch.tensor([tokens_ids])\n",
|
||||
"\n",
|
||||
"# This code can be factored into one-line as follow\n",
|
||||
"tokens_pt2 = tokenizer.encode_plus(\"This is an input example\", return_tensors=\"pt\")\n",
|
||||
"\n",
|
||||
"for key, value in tokens_pt2.items():\n",
|
||||
" print(\"{}:\\n\\t{}\".format(key, value))\n",
|
||||
"\n",
|
||||
"outputs2, pooled2 = model(**tokens_pt2)\n",
|
||||
"print(\"Difference with previous code: ({}, {})\".format((outputs2 - outputs).sum(), (pooled2 - pooled).sum()))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"As you can see above, the methode `encode_plus` provides a convenient way to generate all the required parameters\n",
|
||||
"that will go through the model. \n",
|
||||
"\n",
|
||||
"Moreover, you might have noticed it generated some additional tensors: \n",
|
||||
"\n",
|
||||
"- token_type_ids: This tensor will map every tokens to their corresponding segment (see below).\n",
|
||||
"- attention_mask: This tensor is used to \"mask\" padded values in a batch of sequence with different lengths (see below)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 6,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Single segment token (str): ['[CLS]', 'This', 'is', 'a', 'sample', 'input', '[SEP]']\n",
|
||||
"Single segment token (int): [101, 1188, 1110, 170, 6876, 7758, 102]\n",
|
||||
"Single segment type : [0, 0, 0, 0, 0, 0, 0]\n",
|
||||
"\n",
|
||||
"Multi segment token (str): ['[CLS]', 'This', 'is', 'segment', 'A', '[SEP]', 'This', 'is', 'segment', 'B', '[SEP]']\n",
|
||||
"Multi segment token (int): [101, 1188, 1110, 6441, 138, 102, 1188, 1110, 6441, 139, 102]\n",
|
||||
"Multi segment type : [0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1]\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Single segment input\n",
|
||||
"single_seg_input = tokenizer.encode_plus(\"This is a sample input\")\n",
|
||||
"\n",
|
||||
"# Multiple segment input\n",
|
||||
"multi_seg_input = tokenizer.encode_plus(\"This is segment A\", \"This is segment B\")\n",
|
||||
"\n",
|
||||
"print(\"Single segment token (str): {}\".format(tokenizer.convert_ids_to_tokens(single_seg_input['input_ids'])))\n",
|
||||
"print(\"Single segment token (int): {}\".format(single_seg_input['input_ids']))\n",
|
||||
"print(\"Single segment type : {}\".format(single_seg_input['token_type_ids']))\n",
|
||||
"\n",
|
||||
"# Segments are concatened in the input to the model, with \n",
|
||||
"print()\n",
|
||||
"print(\"Multi segment token (str): {}\".format(tokenizer.convert_ids_to_tokens(multi_seg_input['input_ids'])))\n",
|
||||
"print(\"Multi segment token (int): {}\".format(multi_seg_input['input_ids']))\n",
|
||||
"print(\"Multi segment type : {}\".format(multi_seg_input['token_type_ids']))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 7,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Tokens (int) : [101, 1188, 1110, 170, 6876, 102, 0, 0]\n",
|
||||
"Tokens (str) : ['[CLS]', 'This', 'is', 'a', 'sample', '[SEP]', '[PAD]', '[PAD]']\n",
|
||||
"Tokens (attn_mask): [1, 1, 1, 1, 1, 1, 0, 0]\n",
|
||||
"\n",
|
||||
"Tokens (int) : [101, 1188, 1110, 1330, 2039, 6876, 3087, 102]\n",
|
||||
"Tokens (str) : ['[CLS]', 'This', 'is', 'another', 'longer', 'sample', 'text', '[SEP]']\n",
|
||||
"Tokens (attn_mask): [1, 1, 1, 1, 1, 1, 1, 1]\n",
|
||||
"\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Padding highlight\n",
|
||||
"tokens = tokenizer.batch_encode_plus(\n",
|
||||
" [\"This is a sample\", \"This is another longer sample text\"], \n",
|
||||
" pad_to_max_length=True # First sentence will have some PADDED tokens to match second sequence length\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"for i in range(2):\n",
|
||||
" print(\"Tokens (int) : {}\".format(tokens['input_ids'][i]))\n",
|
||||
" print(\"Tokens (str) : {}\".format([tokenizer.convert_ids_to_tokens(s) for s in tokens['input_ids'][i]]))\n",
|
||||
" print(\"Tokens (attn_mask): {}\".format(tokens['attention_mask'][i]))\n",
|
||||
" print()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Frameworks interoperability\n",
|
||||
"\n",
|
||||
"One of the most powerfull feature of transformers is its ability to seamlessly move from PyTorch to Tensorflow\n",
|
||||
"without pain for the user.\n",
|
||||
"\n",
|
||||
"We provide some convenient methods to load TensorFlow pretrained weight insinde a PyTorch model and opposite."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from transformers import TFBertModel, BertModel\n",
|
||||
"\n",
|
||||
"# Let's load a BERT model for TensorFlow and PyTorch\n",
|
||||
"model_tf = TFBertModel.from_pretrained('bert-base-cased')\n",
|
||||
"model_pt = BertModel.from_pretrained('bert-base-cased')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# transformers generates a ready to use dictionary with all the required parameters for the specific framework.\n",
|
||||
"input_tf = tokenizer.encode_plus(\"This is a sample input\", return_tensors=\"tf\")\n",
|
||||
"input_pt = tokenizer.encode_plus(\"This is a sample input\", return_tensors=\"pt\")\n",
|
||||
"\n",
|
||||
"# Let's compare the outputs\n",
|
||||
"output_tf, output_pt = model_tf(input_tf), model_pt(**input_pt)\n",
|
||||
"\n",
|
||||
"# Models outputs 2 values (The value for each tokens, the pooled representation of the input sentence)\n",
|
||||
"# Here we compare the output differences between PyTorch and TensorFlow.\n",
|
||||
"for name, o_tf, o_pt in zip([\"output\", \"pooled\"], output_tf, output_pt):\n",
|
||||
" print(\"{} differences: {}\".format(name, (o_tf.numpy() - o_pt.numpy()).sum()))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## Want it lighter? Faster? Let's talk distillation! \n",
|
||||
"\n",
|
||||
"One of the main concerns when using these Transformer based models is the computational power they require. All over this notebook we are using BERT model as it can be run on common machines but that's not the case for all of the models.\n",
|
||||
"\n",
|
||||
"For example, Google released a few months ago **T5** an Encoder/Decoder architecture based on Transformer and available in `transformers` with no more than 11 billions parameters. Microsoft also recently entered the game with **Turing-NLG** using 17 billions parameters. This kind of model requires tens of gigabytes to store the weights and a tremendous compute infrastructure to run such models which makes it impracticable for the common man !\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"With the goal of making Transformer-based NLP accessible to everyone we @huggingface developed models that take advantage of a training process called **Distillation** which allows us to drastically reduce the resources needed to run such models with almost zero drop in performances.\n",
|
||||
"\n",
|
||||
"Going over the whole Distillation process is out of the scope of this notebook, but if you want more information on the subject you may refer to [this Medium article written by my colleague Victor SANH, author of DistilBERT paper](https://medium.com/huggingface/distilbert-8cf3380435b5), you might also want to directly have a look at the paper [(Sanh & al., 2019)](https://arxiv.org/abs/1910.01108)\n",
|
||||
"\n",
|
||||
"Of course, in `transformers` we have distilled some models and made them available directly in the library ! "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from transformers import DistilBertModel\n",
|
||||
"\n",
|
||||
"bert_distil = DistilBertModel.from_pretrained('distilbert-base-cased')\n",
|
||||
"input_pt = tokenizer.encode_plus(\n",
|
||||
" 'This is a sample input to demonstrate performance of distiled models especially inference time', \n",
|
||||
" return_tensors=\"pt\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"%time _ = bert_distil(input_pt['input_ids'])\n",
|
||||
"%time _ = model_pt(input_pt['input_ids'])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Community provided models\n",
|
||||
"\n",
|
||||
"Last but not least, earlier in this notebook we introduced Hugging Face `transformers` as a repository for the NLP community to exchange pretrained models. We wanted to highlight this features and all the possibilities it offers for the end-user.\n",
|
||||
"\n",
|
||||
"To leverage community pretrained models, just provide the organisation name and name of the model to `from_pretrained` and it will do all the magic for you ! \n",
|
||||
"\n",
|
||||
"\n",
|
||||
"We currently have more 50 models provided by the community and more are added every day, don't hesitate to give it a try !"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Let's load German BERT from the Bavarian State Library\n",
|
||||
"de_bert = BertModel.from_pretrained(\"dbmdz/bert-base-german-cased\")\n",
|
||||
"de_tokenizer = BertTokenizer.from_pretrained(\"dbmdz/bert-base-german-cased\")\n",
|
||||
"\n",
|
||||
"de_input = de_tokenizer.encode_plus(\n",
|
||||
" \"Hugging Face ist einen französische Firma Mitarbeitern in New-York.\",\n",
|
||||
" return_tensors=\"pt\"\n",
|
||||
")\n",
|
||||
"output_de, pooled_de = de_bert(**de_input)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.7.6"
|
||||
},
|
||||
"pycharm": {
|
||||
"stem_cell": {
|
||||
"cell_type": "raw",
|
||||
"metadata": {
|
||||
"collapsed": false
|
||||
},
|
||||
"source": []
|
||||
}
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 1
|
||||
}
|
||||
@@ -0,0 +1,511 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## How can I leverage State-of-the-Art Natural Language Models with only one line of code ?"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Newly introduced in transformers v2.3.0, **pipelines** provides a high-level, easy to use,\n",
|
||||
"API for doing inference over a variety of downstream-tasks, including: \n",
|
||||
"\n",
|
||||
"- Sentence Classification (Sentiment Analysis): Indicate if the overall sentence is either positive or negative. _(Binary Classification task or Logitic Regression task)_\n",
|
||||
"- Token Classification (Named Entity Recognition, Part-of-Speech tagging): For each sub-entities _(**tokens**)_ in the input, assign them a label _(Classification task)_.\n",
|
||||
"- Question-Answering: Provided a tuple (question, context) the model should find the span of text in **content** answering the **question**.\n",
|
||||
"- Mask-Filling: Suggests possible word(s) to fill the masked input with respect to the provided **context**.\n",
|
||||
"- Feature Extraction: Maps the input to a higher, multi-dimensional space learned from the data.\n",
|
||||
"\n",
|
||||
"Pipelines encapsulate the overall process of every NLP process:\n",
|
||||
" \n",
|
||||
" 1. Tokenization: Split the initial input into multiple sub-entities with ... properties (i.e. tokens).\n",
|
||||
" 2. Inference: Maps every tokens into a more meaningful representation. \n",
|
||||
" 3. Decoding: Use the above representation to generate and/or extract the final output for the underlying task.\n",
|
||||
"\n",
|
||||
"The overall API is exposed to the end-user through the `pipeline()` method with the following \n",
|
||||
"structure:\n",
|
||||
"\n",
|
||||
"```python\n",
|
||||
"from transformers import pipeline\n",
|
||||
"\n",
|
||||
"# Using default model and tokenizer for the task\n",
|
||||
"pipeline(\"<task-name>\")\n",
|
||||
"\n",
|
||||
"# Using a user-specified model\n",
|
||||
"pipeline(\"<task-name>\", model=\"<model_name>\")\n",
|
||||
"\n",
|
||||
"# Using custom model/tokenizer as str\n",
|
||||
"pipeline('<task-name>', model='<model name>', tokenizer='<tokenizer_name>')\n",
|
||||
"```"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install transformers"
|
||||
],
|
||||
"metadata": {
|
||||
"collapsed": false,
|
||||
"pycharm": {
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 6,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code \n"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from __future__ import print_function\n",
|
||||
"import ipywidgets as widgets\n",
|
||||
"from transformers import pipeline"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## 1. Sentence Classification - Sentiment Analysis"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 8,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "HBox(children=(FloatProgress(value=0.0, description='Downloading', max=230.0, style=ProgressStyle(description_…",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "c9db53f30b9446c0af03268633a966c0"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"\n"
|
||||
],
|
||||
"output_type": "stream"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "[{'label': 'POSITIVE', 'score': 0.9997656}]"
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "execute_result",
|
||||
"execution_count": 8
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"nlp_sentence_classif = pipeline('sentiment-analysis')\n",
|
||||
"nlp_sentence_classif('Such a nice weather outside !')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"## 2. Token Classification - Named Entity Recognition"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 9,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "HBox(children=(FloatProgress(value=0.0, description='Downloading', max=230.0, style=ProgressStyle(description_…",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "1e300789e22644f1aed66a5ed60e75c4"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"\n"
|
||||
],
|
||||
"output_type": "stream"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "[{'word': 'Hu', 'score': 0.9970937967300415, 'entity': 'I-ORG'},\n {'word': '##gging', 'score': 0.9345750212669373, 'entity': 'I-ORG'},\n {'word': 'Face', 'score': 0.9787060022354126, 'entity': 'I-ORG'},\n {'word': 'French', 'score': 0.9981995820999146, 'entity': 'I-MISC'},\n {'word': 'New', 'score': 0.9983047246932983, 'entity': 'I-LOC'},\n {'word': '-', 'score': 0.8913455009460449, 'entity': 'I-LOC'},\n {'word': 'York', 'score': 0.9979523420333862, 'entity': 'I-LOC'}]"
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "execute_result",
|
||||
"execution_count": 9
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"nlp_token_class = pipeline('ner')\n",
|
||||
"nlp_token_class('Hugging Face is a French company based in New-York.')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## 3. Question Answering"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "HBox(children=(FloatProgress(value=0.0, description='Downloading', max=230.0, style=ProgressStyle(description_…",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "82aca58f1ea24b4cb37f16402e8a5923"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"\n"
|
||||
],
|
||||
"output_type": "stream"
|
||||
},
|
||||
{
|
||||
"name": "stderr",
|
||||
"text": [
|
||||
"convert squad examples to features: 100%|██████████| 1/1 [00:00<00:00, 225.51it/s]\n",
|
||||
"add example index and unique id: 100%|██████████| 1/1 [00:00<00:00, 2158.67it/s]\n"
|
||||
],
|
||||
"output_type": "stream"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "{'score': 0.9632966867654424, 'start': 42, 'end': 50, 'answer': 'New-York.'}"
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "execute_result",
|
||||
"execution_count": 10
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"nlp_qa = pipeline('question-answering')\n",
|
||||
"nlp_qa(context='Hugging Face is a French company based in New-York.', question='Where is based Hugging Face ?')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## 4. Text Generation - Mask Filling"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 11,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "HBox(children=(FloatProgress(value=0.0, description='Downloading', max=230.0, style=ProgressStyle(description_…",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "49df2227b4fa4eb28dcdcfc3d9261d0f"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"\n"
|
||||
],
|
||||
"output_type": "stream"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "[{'sequence': '<s> Hugging Face is a French company based in Paris</s>',\n 'score': 0.23106691241264343,\n 'token': 2201},\n {'sequence': '<s> Hugging Face is a French company based in Lyon</s>',\n 'score': 0.0819825753569603,\n 'token': 12790},\n {'sequence': '<s> Hugging Face is a French company based in Geneva</s>',\n 'score': 0.04769463092088699,\n 'token': 11559},\n {'sequence': '<s> Hugging Face is a French company based in Brussels</s>',\n 'score': 0.047622501850128174,\n 'token': 6497},\n {'sequence': '<s> Hugging Face is a French company based in France</s>',\n 'score': 0.04130595177412033,\n 'token': 1470}]"
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "execute_result",
|
||||
"execution_count": 11
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"nlp_fill = pipeline('fill-mask')\n",
|
||||
"nlp_fill('Hugging Face is a French company based in <mask>')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## 5. Projection - Features Extraction "
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 12,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "HBox(children=(FloatProgress(value=0.0, description='Downloading', max=230.0, style=ProgressStyle(description_…",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "2af4cfb19e3243dda014d0f56b48f4b2"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"name": "stdout",
|
||||
"text": [
|
||||
"\n"
|
||||
],
|
||||
"output_type": "stream"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "(1, 12, 768)"
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "execute_result",
|
||||
"execution_count": 12
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"import numpy as np\n",
|
||||
"nlp_features = pipeline('feature-extraction')\n",
|
||||
"output = nlp_features('Hugging Face is a French company based in Paris')\n",
|
||||
"np.array(output).shape # (Samples, Tokens, Vector Size)\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"name": "#%% md\n"
|
||||
}
|
||||
},
|
||||
"source": [
|
||||
"Alright ! Now you have a nice picture of what is possible through transformers' pipelines, and there is more\n",
|
||||
"to come in future releases. \n",
|
||||
"\n",
|
||||
"In the meantime, you can try the different pipelines with your own inputs"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 13,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% code\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "Dropdown(description='Task:', index=1, options=('sentiment-analysis', 'ner', 'fill_mask'), value='ner')",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "10bac065d46f4e4d9a8498dcc8104ecd"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "Text(value='', description='Your input:', placeholder='Enter something')",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "2c5f1411f7a94714bc00f01b0e3b27b2"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"task = widgets.Dropdown(\n",
|
||||
" options=['sentiment-analysis', 'ner', 'fill_mask'],\n",
|
||||
" value='ner',\n",
|
||||
" description='Task:',\n",
|
||||
" disabled=False\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"input = widgets.Text(\n",
|
||||
" value='',\n",
|
||||
" placeholder='Enter something',\n",
|
||||
" description='Your input:',\n",
|
||||
" disabled=False\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"def forward(_):\n",
|
||||
" if len(input.value) > 0: \n",
|
||||
" if task.value == 'ner':\n",
|
||||
" output = nlp_token_class(input.value)\n",
|
||||
" elif task.value == 'sentiment-analysis':\n",
|
||||
" output = nlp_sentence_classif(input.value)\n",
|
||||
" else:\n",
|
||||
" if input.value.find('<mask>') == -1:\n",
|
||||
" output = nlp_fill(input.value + ' <mask>')\n",
|
||||
" else:\n",
|
||||
" output = nlp_fill(input.value) \n",
|
||||
" print(output)\n",
|
||||
"\n",
|
||||
"input.on_submit(forward)\n",
|
||||
"display(task, input)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 14,
|
||||
"metadata": {
|
||||
"pycharm": {
|
||||
"is_executing": false,
|
||||
"name": "#%% Question Answering\n"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": "Textarea(value='Einstein is famous for the general theory of relativity', description='Context:', placeholder=…",
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"version_major": 2,
|
||||
"version_minor": 0,
|
||||
"model_id": "019fde2343634e94b6f32d04f6350ec1"
|
||||
}
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"context = widgets.Textarea(\n",
|
||||
" value='Einstein is famous for the general theory of relativity',\n",
|
||||
" placeholder='Enter something',\n",
|
||||
" description='Context:',\n",
|
||||
" disabled=False\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"query = widgets.Text(\n",
|
||||
" value='Why is Einstein famous for ?',\n",
|
||||
" placeholder='Enter something',\n",
|
||||
" description='Question:',\n",
|
||||
" disabled=False\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"def forward(_):\n",
|
||||
" if len(context.value) > 0 and len(query.value) > 0: \n",
|
||||
" output = nlp_qa(question=query.value, context=context.value) \n",
|
||||
" print(output)\n",
|
||||
"\n",
|
||||
"query.on_submit(forward)\n",
|
||||
"display(context, query)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.7.6"
|
||||
},
|
||||
"pycharm": {
|
||||
"stem_cell": {
|
||||
"cell_type": "raw",
|
||||
"source": [],
|
||||
"metadata": {
|
||||
"collapsed": false
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 1
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,17 @@
|
||||
# Transformers Notebooks
|
||||
|
||||
You can find here a list of the official notebooks provided by Hugging Face.
|
||||
|
||||
Also, we would like to list here interesting content created by the community.
|
||||
If you wrote some notebook(s) leveraging transformers and would like be listed here, please open a
|
||||
Pull Request and we'll review it so it can be included here.
|
||||
|
||||
|
||||
## Hugging Face's notebooks :hugs:
|
||||
|
||||
| Notebook | Description | |
|
||||
|:----------|:-------------:|------:|
|
||||
| [Getting Started Tokenizers](01-training-tokenizers.ipynb) | How to train and use your very own tokenizer |[](https://colab.research.google.com/github/huggingface/transformers/blob/master/notebooks/01-training-tokenizers.ipynb) |
|
||||
| [Getting Started Transformers](02-transformers.ipynb) | How to easily start using transformers | [](https://colab.research.google.com/github/huggingface/transformers/blob/master/notebooks/02-transformers.ipynb) |
|
||||
| [How to use Pipelines](03-pipelines.ipynb) | Simple and efficient way to use State-of-the-Art models on downstream tasks through transformers | [](https://colab.research.google.com/github/huggingface/transformers/blob/master/notebooks/03-pipelines.ipynb) |
|
||||
| [How to train a language model](https://github.com/huggingface/blog/blob/master/notebooks/01_how_to_train.ipynb)| Highlight all the steps to effectively train Transformer model on custom data | [](https://colab.research.google.com/github/huggingface/blog/blob/master/notebooks/01_how_to_train.ipynb)|
|
||||
@@ -64,7 +64,7 @@ if stale_egg_info.exists():
|
||||
extras = {}
|
||||
|
||||
extras["mecab"] = ["mecab-python3"]
|
||||
extras["sklearn"] = ["scikit-learn"]
|
||||
extras["sklearn"] = ["scikit-learn==0.22.1"]
|
||||
extras["tf"] = ["tensorflow"]
|
||||
extras["tf-cpu"] = ["tensorflow-cpu"]
|
||||
extras["torch"] = ["torch"]
|
||||
|
||||
@@ -136,7 +136,7 @@ if is_sklearn_available():
|
||||
|
||||
# Modeling
|
||||
if is_torch_available():
|
||||
from .modeling_utils import PreTrainedModel, prune_layer, Conv1D
|
||||
from .modeling_utils import PreTrainedModel, prune_layer, Conv1D, top_k_top_p_filtering
|
||||
from .modeling_auto import (
|
||||
AutoModel,
|
||||
AutoModelForPreTraining,
|
||||
@@ -206,7 +206,11 @@ if is_torch_available():
|
||||
XLMForQuestionAnsweringSimple,
|
||||
XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_bart import BartForSequenceClassification, BartModel, BartForMaskedLM
|
||||
from .modeling_bart import (
|
||||
BartForSequenceClassification,
|
||||
BartModel,
|
||||
BartForConditionalGeneration,
|
||||
)
|
||||
from .modeling_roberta import (
|
||||
RobertaForMaskedLM,
|
||||
RobertaModel,
|
||||
@@ -241,7 +245,7 @@ if is_torch_available():
|
||||
CamembertForTokenClassification,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_encoder_decoder import PreTrainedEncoderDecoder, Model2Model
|
||||
from .modeling_encoder_decoder import PreTrainedEncoderDecoder
|
||||
from .modeling_t5 import (
|
||||
T5PreTrainedModel,
|
||||
T5Model,
|
||||
@@ -255,6 +259,7 @@ if is_torch_available():
|
||||
AlbertForMaskedLM,
|
||||
AlbertForSequenceClassification,
|
||||
AlbertForQuestionAnswering,
|
||||
AlbertForTokenClassification,
|
||||
load_tf_weights_in_albert,
|
||||
ALBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
@@ -290,7 +295,13 @@ if is_torch_available():
|
||||
|
||||
# TensorFlow
|
||||
if is_tf_available():
|
||||
from .modeling_tf_utils import TFPreTrainedModel, TFSharedEmbeddings, TFSequenceSummary, shape_list
|
||||
from .modeling_tf_utils import (
|
||||
TFPreTrainedModel,
|
||||
TFSharedEmbeddings,
|
||||
TFSequenceSummary,
|
||||
shape_list,
|
||||
tf_top_k_top_p_filtering,
|
||||
)
|
||||
from .modeling_tf_auto import (
|
||||
TFAutoModel,
|
||||
TFAutoModelForPreTraining,
|
||||
|
||||
@@ -22,11 +22,10 @@ from .configuration_utils import PretrainedConfig
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_bart_large_url = "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large/config.json"
|
||||
BART_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"bart-large": _bart_large_url,
|
||||
"bart-large-mnli": _bart_large_url, # fine as same
|
||||
"bart-cnn": None, # not done
|
||||
"bart-large": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large/config.json",
|
||||
"bart-large-mnli": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-mnli/config.json",
|
||||
"bart-large-cnn": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-cnn/config.json",
|
||||
}
|
||||
|
||||
|
||||
@@ -59,6 +58,7 @@ class BartConfig(PretrainedConfig):
|
||||
classifier_dropout=0.0,
|
||||
output_past=False,
|
||||
num_labels=3,
|
||||
bos_token_id=0,
|
||||
**common_kwargs
|
||||
):
|
||||
r"""
|
||||
@@ -67,12 +67,16 @@ class BartConfig(PretrainedConfig):
|
||||
config = BartConfig.from_pretrained('bart-large')
|
||||
model = BartModel(config)
|
||||
"""
|
||||
super().__init__(num_labels=num_labels, output_past=output_past, pad_token_id=pad_token_id, **common_kwargs)
|
||||
|
||||
super().__init__(
|
||||
num_labels=num_labels,
|
||||
output_past=output_past,
|
||||
pad_token_id=pad_token_id,
|
||||
bos_token_id=bos_token_id,
|
||||
**common_kwargs,
|
||||
)
|
||||
self.vocab_size = vocab_size
|
||||
self.d_model = d_model # encoder_embed_dim and decoder_embed_dim
|
||||
self.eos_token_id = eos_token_id
|
||||
|
||||
self.encoder_ffn_dim = encoder_ffn_dim
|
||||
self.encoder_layers = self.num_hidden_layers = encoder_layers
|
||||
self.encoder_attention_heads = encoder_attention_heads
|
||||
|
||||
@@ -135,6 +135,8 @@ class GPT2Config(PretrainedConfig):
|
||||
summary_activation=None,
|
||||
summary_proj_to_labels=True,
|
||||
summary_first_dropout=0.1,
|
||||
bos_token_id=50256,
|
||||
eos_token_id=50256,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
@@ -156,6 +158,9 @@ class GPT2Config(PretrainedConfig):
|
||||
self.summary_first_dropout = summary_first_dropout
|
||||
self.summary_proj_to_labels = summary_proj_to_labels
|
||||
|
||||
self.bos_token_id = bos_token_id
|
||||
self.eos_token_ids = [eos_token_id]
|
||||
|
||||
@property
|
||||
def max_position_embeddings(self):
|
||||
return self.n_positions
|
||||
|
||||
@@ -149,6 +149,7 @@ class TransfoXLConfig(PretrainedConfig):
|
||||
proj_init_std=0.01,
|
||||
init_std=0.02,
|
||||
layer_norm_epsilon=1e-5,
|
||||
eos_token_id=0,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
@@ -186,6 +187,8 @@ class TransfoXLConfig(PretrainedConfig):
|
||||
self.init_std = init_std
|
||||
self.layer_norm_epsilon = layer_norm_epsilon
|
||||
|
||||
self.eos_token_ids = [eos_token_id]
|
||||
|
||||
@property
|
||||
def max_position_embeddings(self):
|
||||
return self.tgt_len + self.ext_len + self.mem_len
|
||||
|
||||
@@ -70,6 +70,7 @@ class PretrainedConfig(object):
|
||||
# Parameters for sequence generation
|
||||
self.max_length = kwargs.pop("max_length", 20)
|
||||
self.do_sample = kwargs.pop("do_sample", False)
|
||||
self.early_stopping = kwargs.pop("early_stopping", False)
|
||||
self.num_beams = kwargs.pop("num_beams", 1)
|
||||
self.temperature = kwargs.pop("temperature", 1.0)
|
||||
self.top_k = kwargs.pop("top_k", 50)
|
||||
@@ -98,6 +99,18 @@ class PretrainedConfig(object):
|
||||
logger.error("Can't set {} with value {} for {}".format(key, value, self))
|
||||
raise err
|
||||
|
||||
@property
|
||||
def num_labels(self):
|
||||
return self._num_labels
|
||||
|
||||
@num_labels.setter
|
||||
def num_labels(self, num_labels):
|
||||
self._num_labels = num_labels
|
||||
self.id2label = {i: "LABEL_{}".format(i) for i in range(self.num_labels)}
|
||||
self.id2label = dict((int(key), value) for key, value in self.id2label.items())
|
||||
self.label2id = dict(zip(self.id2label.values(), self.id2label.keys()))
|
||||
self.label2id = dict((key, int(value)) for key, value in self.label2id.items())
|
||||
|
||||
def save_pretrained(self, save_directory):
|
||||
"""
|
||||
Save a configuration object to the directory `save_directory`, so that it
|
||||
|
||||
@@ -194,6 +194,8 @@ class XLMConfig(PretrainedConfig):
|
||||
end_n_top=5,
|
||||
mask_token_id=0,
|
||||
lang_id=0,
|
||||
bos_token_id=0,
|
||||
pad_token_id=2,
|
||||
**kwargs
|
||||
):
|
||||
"""Constructs XLMConfig.
|
||||
@@ -234,6 +236,9 @@ class XLMConfig(PretrainedConfig):
|
||||
if "n_words" in kwargs:
|
||||
self.n_words = kwargs["n_words"]
|
||||
|
||||
self.bos_token_id = bos_token_id
|
||||
self.pad_token_id = pad_token_id
|
||||
|
||||
@property
|
||||
def n_words(self): # For backward compatibility
|
||||
return self.vocab_size
|
||||
|
||||
@@ -155,6 +155,9 @@ class XLNetConfig(PretrainedConfig):
|
||||
summary_last_dropout=0.1,
|
||||
start_n_top=5,
|
||||
end_n_top=5,
|
||||
bos_token_id=1,
|
||||
pad_token_id=5,
|
||||
eos_token_id=2,
|
||||
**kwargs
|
||||
):
|
||||
"""Constructs XLNetConfig.
|
||||
@@ -188,6 +191,10 @@ class XLNetConfig(PretrainedConfig):
|
||||
self.start_n_top = start_n_top
|
||||
self.end_n_top = end_n_top
|
||||
|
||||
self.bos_token_id = bos_token_id
|
||||
self.pad_token_id = pad_token_id
|
||||
self.eos_token_ids = [eos_token_id]
|
||||
|
||||
@property
|
||||
def max_position_embeddings(self):
|
||||
return -1
|
||||
|
||||
@@ -23,9 +23,17 @@ import fairseq
|
||||
import torch
|
||||
from packaging import version
|
||||
|
||||
from transformers import BartConfig, BartForSequenceClassification, BartModel, BartTokenizer
|
||||
from transformers import (
|
||||
BartConfig,
|
||||
BartForConditionalGeneration,
|
||||
BartForSequenceClassification,
|
||||
BartModel,
|
||||
BartTokenizer,
|
||||
)
|
||||
|
||||
|
||||
FAIRSEQ_MODELS = ["bart.large", "bart.large.mnli", "bart.large.cnn"]
|
||||
|
||||
if version.parse(fairseq.__version__) < version.parse("0.9.0"):
|
||||
raise Exception("requires fairseq >= 0.9.0")
|
||||
|
||||
@@ -33,7 +41,7 @@ if version.parse(fairseq.__version__) < version.parse("0.9.0"):
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
SAMPLE_TEXT = "Hello world! cécé herlolip"
|
||||
SAMPLE_TEXT = " Hello world! cécé herlolip"
|
||||
|
||||
rename_keys = [
|
||||
("model.classification_heads.mnli.dense.weight", "classification_head.dense.weight"),
|
||||
@@ -41,7 +49,7 @@ rename_keys = [
|
||||
("model.classification_heads.mnli.out_proj.weight", "classification_head.out_proj.weight"),
|
||||
("model.classification_heads.mnli.out_proj.bias", "classification_head.out_proj.bias"),
|
||||
]
|
||||
IGNORE_KEYS = ["encoder.version", "decoder.version", "model.encoder.version", "model.decoder.version"]
|
||||
IGNORE_KEYS = ["encoder.version", "decoder.version", "model.encoder.version", "model.decoder.version", "_float_tensor"]
|
||||
|
||||
|
||||
def rename_key(dct, old, new):
|
||||
@@ -53,36 +61,45 @@ def convert_bart_checkpoint(checkpoint_path, pytorch_dump_folder_path):
|
||||
"""
|
||||
Copy/paste/tweak model's weights to our BERT structure.
|
||||
"""
|
||||
b2 = torch.hub.load("pytorch/fairseq", checkpoint_path)
|
||||
b2.eval() # disable dropout
|
||||
b2.model.upgrade_state_dict(b2.model.state_dict())
|
||||
config = BartConfig()
|
||||
tokens = b2.encode(SAMPLE_TEXT).unsqueeze(0)
|
||||
tokens2 = BartTokenizer.from_pretrained("bart-large").encode(SAMPLE_TEXT).unsqueeze(0)
|
||||
bart = torch.hub.load("pytorch/fairseq", checkpoint_path)
|
||||
bart.eval() # disable dropout
|
||||
bart.model.upgrade_state_dict(bart.model.state_dict())
|
||||
hf_model_name = checkpoint_path.replace(".", "-")
|
||||
config = BartConfig.from_pretrained(hf_model_name)
|
||||
tokens = bart.encode(SAMPLE_TEXT).unsqueeze(0)
|
||||
tokens2 = BartTokenizer.from_pretrained(hf_model_name).encode(SAMPLE_TEXT, return_tensors="pt").unsqueeze(0)
|
||||
assert torch.eq(tokens, tokens2).all()
|
||||
|
||||
# assert their_output.size() == (1, 11, 1024)
|
||||
|
||||
if checkpoint_path == "bart.large":
|
||||
state_dict = b2.model.state_dict()
|
||||
if checkpoint_path in ["bart.large", "bart.large.cnn"]:
|
||||
state_dict = bart.model.state_dict()
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
state_dict["shared.weight"] = state_dict["decoder.embed_tokens.weight"]
|
||||
model = BartModel(config)
|
||||
their_output = b2.extract_features(tokens)
|
||||
|
||||
their_output = bart.extract_features(tokens)
|
||||
else: # MNLI Case
|
||||
state_dict = b2.state_dict()
|
||||
state_dict = bart.state_dict()
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
state_dict["model.shared.weight"] = state_dict["model.decoder.embed_tokens.weight"]
|
||||
for src, dest in rename_keys:
|
||||
rename_key(state_dict, src, dest)
|
||||
state_dict.pop("_float_tensor", None)
|
||||
model = BartForSequenceClassification(config)
|
||||
their_output = b2.predict("mnli", tokens, return_logits=True)
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
their_output = bart.predict("mnli", tokens, return_logits=True)
|
||||
|
||||
# Load state dict
|
||||
model.load_state_dict(state_dict)
|
||||
model.eval()
|
||||
our_outputs = model.forward(tokens)[0]
|
||||
# Check results
|
||||
|
||||
if checkpoint_path == "bart.large.cnn":
|
||||
model = BartForConditionalGeneration(config, base_model=model)
|
||||
assert "lm_head.weight" in model.state_dict()
|
||||
assert model.lm_head.out_features == config.max_position_embeddings
|
||||
model.eval()
|
||||
our_outputs = model.model(tokens)[0]
|
||||
else:
|
||||
our_outputs = model(tokens)[0]
|
||||
assert their_output.shape == our_outputs.shape
|
||||
assert (their_output == our_outputs).all().item()
|
||||
Path(pytorch_dump_folder_path).mkdir(exist_ok=True)
|
||||
@@ -92,7 +109,8 @@ def convert_bart_checkpoint(checkpoint_path, pytorch_dump_folder_path):
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
# Required parameters
|
||||
parser.add_argument("fairseq_path", choices=["bart.large", "bart.large.mnli"], type=str, help="")
|
||||
parser.add_argument("fairseq_path", choices=FAIRSEQ_MODELS, type=str, help="")
|
||||
|
||||
parser.add_argument("pytorch_dump_folder_path", default=None, type=str, help="Path to the output PyTorch model.")
|
||||
args = parser.parse_args()
|
||||
convert_bart_checkpoint(
|
||||
|
||||
@@ -46,7 +46,9 @@ logger = logging.getLogger(__name__)
|
||||
SAMPLE_TEXT = "Hello world! cécé herlolip"
|
||||
|
||||
|
||||
def convert_roberta_checkpoint_to_pytorch(roberta_checkpoint_path, pytorch_dump_folder_path, classification_head):
|
||||
def convert_roberta_checkpoint_to_pytorch(
|
||||
roberta_checkpoint_path: str, pytorch_dump_folder_path: str, classification_head: bool
|
||||
):
|
||||
"""
|
||||
Copy/paste/tweak roberta's weights to our BERT structure.
|
||||
"""
|
||||
|
||||
@@ -17,7 +17,7 @@
|
||||
import io
|
||||
import os
|
||||
from os.path import expanduser
|
||||
from typing import List
|
||||
from typing import Dict, List, Optional
|
||||
|
||||
import requests
|
||||
from tqdm import tqdm
|
||||
@@ -27,6 +27,10 @@ ENDPOINT = "https://huggingface.co"
|
||||
|
||||
|
||||
class S3Obj:
|
||||
"""
|
||||
Data structure that represents a file belonging to the current user.
|
||||
"""
|
||||
|
||||
def __init__(self, filename: str, LastModified: str, ETag: str, Size: int, **kwargs):
|
||||
self.filename = filename
|
||||
self.LastModified = LastModified
|
||||
@@ -41,6 +45,50 @@ class PresignedUrl:
|
||||
self.type = type # mime-type to send to S3.
|
||||
|
||||
|
||||
class S3Object:
|
||||
"""
|
||||
Data structure that represents a public file accessible on our S3.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
key: str, # S3 object key
|
||||
etag: str,
|
||||
lastModified: str,
|
||||
size: int,
|
||||
rfilename: str, # filename relative to config.json
|
||||
**kwargs
|
||||
):
|
||||
self.key = key
|
||||
self.etag = etag
|
||||
self.lastModified = lastModified
|
||||
self.size = size
|
||||
self.rfilename = rfilename
|
||||
|
||||
|
||||
class ModelInfo:
|
||||
"""
|
||||
Info about a public model accessible from our S3.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
modelId: str, # id of model
|
||||
key: str, # S3 object key of config.json
|
||||
author: Optional[str] = None,
|
||||
downloads: Optional[int] = None,
|
||||
tags: List[str] = [],
|
||||
siblings: List[Dict] = [], # list of files that constitute the model
|
||||
**kwargs
|
||||
):
|
||||
self.modelId = modelId
|
||||
self.key = key
|
||||
self.author = author
|
||||
self.downloads = downloads
|
||||
self.tags = tags
|
||||
self.siblings = [S3Object(**x) for x in siblings]
|
||||
|
||||
|
||||
class HfApi:
|
||||
def __init__(self, endpoint=None):
|
||||
self.endpoint = endpoint if endpoint is not None else ENDPOINT
|
||||
@@ -129,6 +177,16 @@ class HfApi:
|
||||
r = requests.delete(path, headers={"authorization": "Bearer {}".format(token)}, json={"filename": filename})
|
||||
r.raise_for_status()
|
||||
|
||||
def model_list(self) -> List[ModelInfo]:
|
||||
"""
|
||||
Get the public list of all the models on huggingface, including the community models
|
||||
"""
|
||||
path = "{}/api/models".format(self.endpoint)
|
||||
r = requests.get(path)
|
||||
r.raise_for_status()
|
||||
d = r.json()
|
||||
return [ModelInfo(**x) for x in d]
|
||||
|
||||
|
||||
class TqdmProgressFileReader:
|
||||
"""
|
||||
|
||||
@@ -788,6 +788,103 @@ class AlbertForSequenceClassification(AlbertPreTrainedModel):
|
||||
return outputs # (loss), logits, (hidden_states), (attentions)
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""Albert Model with a token classification head on top (a linear layer on top of
|
||||
the hidden-states output) e.g. for Named-Entity-Recognition (NER) tasks. """,
|
||||
ALBERT_START_DOCSTRING,
|
||||
)
|
||||
class AlbertForTokenClassification(AlbertPreTrainedModel):
|
||||
def __init__(self, config):
|
||||
super().__init__(config)
|
||||
self.num_labels = config.num_labels
|
||||
|
||||
self.albert = AlbertModel(config)
|
||||
self.dropout = nn.Dropout(config.hidden_dropout_prob)
|
||||
self.classifier = nn.Linear(config.hidden_size, self.config.num_labels)
|
||||
|
||||
self.init_weights()
|
||||
|
||||
@add_start_docstrings_to_callable(ALBERT_INPUTS_DOCSTRING)
|
||||
def forward(
|
||||
self,
|
||||
input_ids=None,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
inputs_embeds=None,
|
||||
labels=None,
|
||||
):
|
||||
r"""
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for computing the token classification loss.
|
||||
Indices should be in ``[0, ..., config.num_labels - 1]``.
|
||||
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.AlbertConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when ``labels`` is provided) :
|
||||
Classification loss.
|
||||
scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.num_labels)`)
|
||||
Classification scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
|
||||
Examples::
|
||||
|
||||
from transformers import AlbertTokenizer, AlbertForTokenClassification
|
||||
import torch
|
||||
|
||||
tokenizer = AlbertTokenizer.from_pretrained('albert-base-v2')
|
||||
model = AlbertForTokenClassification.from_pretrained('albert-base-v2')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
labels = torch.tensor([1] * input_ids.size(1)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, labels=labels)
|
||||
|
||||
loss, scores = outputs[:2]
|
||||
|
||||
"""
|
||||
|
||||
outputs = self.albert(
|
||||
input_ids,
|
||||
attention_mask=attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
position_ids=position_ids,
|
||||
head_mask=head_mask,
|
||||
inputs_embeds=inputs_embeds,
|
||||
)
|
||||
|
||||
sequence_output = outputs[0]
|
||||
|
||||
sequence_output = self.dropout(sequence_output)
|
||||
logits = self.classifier(sequence_output)
|
||||
|
||||
outputs = (logits,) + outputs[2:] # add hidden states and attention if they are here
|
||||
|
||||
if labels is not None:
|
||||
loss_fct = CrossEntropyLoss()
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
outputs = (loss,) + outputs
|
||||
|
||||
return outputs # (loss), logits, (hidden_states), (attentions)
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""Albert Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear layers on top of
|
||||
the hidden-states output to compute `span start logits` and `span end logits`). """,
|
||||
|
||||
@@ -42,9 +42,15 @@ from .modeling_albert import (
|
||||
AlbertForMaskedLM,
|
||||
AlbertForQuestionAnswering,
|
||||
AlbertForSequenceClassification,
|
||||
AlbertForTokenClassification,
|
||||
AlbertModel,
|
||||
)
|
||||
from .modeling_bart import BART_PRETRAINED_MODEL_ARCHIVE_MAP, BartForMaskedLM, BartForSequenceClassification, BartModel
|
||||
from .modeling_bart import (
|
||||
BART_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
BartForConditionalGeneration,
|
||||
BartForSequenceClassification,
|
||||
BartModel,
|
||||
)
|
||||
from .modeling_bert import (
|
||||
BERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
BertForMaskedLM,
|
||||
@@ -72,7 +78,7 @@ from .modeling_distilbert import (
|
||||
)
|
||||
from .modeling_flaubert import (
|
||||
FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
FlaubertForQuestionAnswering,
|
||||
FlaubertForQuestionAnsweringSimple,
|
||||
FlaubertForSequenceClassification,
|
||||
FlaubertModel,
|
||||
FlaubertWithLMHeadModel,
|
||||
@@ -91,7 +97,7 @@ from .modeling_t5 import T5_PRETRAINED_MODEL_ARCHIVE_MAP, T5Model, T5WithLMHeadM
|
||||
from .modeling_transfo_xl import TRANSFO_XL_PRETRAINED_MODEL_ARCHIVE_MAP, TransfoXLLMHeadModel, TransfoXLModel
|
||||
from .modeling_xlm import (
|
||||
XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLMForQuestionAnswering,
|
||||
XLMForQuestionAnsweringSimple,
|
||||
XLMForSequenceClassification,
|
||||
XLMModel,
|
||||
XLMWithLMHeadModel,
|
||||
@@ -105,7 +111,7 @@ from .modeling_xlm_roberta import (
|
||||
)
|
||||
from .modeling_xlnet import (
|
||||
XLNET_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLNetForQuestionAnswering,
|
||||
XLNetForQuestionAnsweringSimple,
|
||||
XLNetForSequenceClassification,
|
||||
XLNetForTokenClassification,
|
||||
XLNetLMHeadModel,
|
||||
@@ -165,7 +171,7 @@ MODEL_FOR_PRETRAINING_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertForMaskedLM),
|
||||
(CamembertConfig, CamembertForMaskedLM),
|
||||
(XLMRobertaConfig, XLMRobertaForMaskedLM),
|
||||
(BartConfig, BartForMaskedLM),
|
||||
(BartConfig, BartForConditionalGeneration),
|
||||
(RobertaConfig, RobertaForMaskedLM),
|
||||
(BertConfig, BertForPreTraining),
|
||||
(OpenAIGPTConfig, OpenAIGPTLMHeadModel),
|
||||
@@ -185,7 +191,7 @@ MODEL_WITH_LM_HEAD_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertForMaskedLM),
|
||||
(CamembertConfig, CamembertForMaskedLM),
|
||||
(XLMRobertaConfig, XLMRobertaForMaskedLM),
|
||||
(BartConfig, BartForMaskedLM),
|
||||
(BartConfig, BartForConditionalGeneration),
|
||||
(RobertaConfig, RobertaForMaskedLM),
|
||||
(BertConfig, BertForMaskedLM),
|
||||
(OpenAIGPTConfig, OpenAIGPTLMHeadModel),
|
||||
@@ -219,9 +225,9 @@ MODEL_FOR_QUESTION_ANSWERING_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertForQuestionAnswering),
|
||||
(RobertaConfig, RobertaForQuestionAnswering),
|
||||
(BertConfig, BertForQuestionAnswering),
|
||||
(XLNetConfig, XLNetForQuestionAnswering),
|
||||
(FlaubertConfig, FlaubertForQuestionAnswering),
|
||||
(XLMConfig, XLMForQuestionAnswering),
|
||||
(XLNetConfig, XLNetForQuestionAnsweringSimple),
|
||||
(FlaubertConfig, FlaubertForQuestionAnsweringSimple),
|
||||
(XLMConfig, XLMForQuestionAnsweringSimple),
|
||||
]
|
||||
)
|
||||
|
||||
@@ -233,6 +239,7 @@ MODEL_FOR_TOKEN_CLASSIFICATION_MAPPING = OrderedDict(
|
||||
(RobertaConfig, RobertaForTokenClassification),
|
||||
(BertConfig, BertForTokenClassification),
|
||||
(XLNetConfig, XLNetForTokenClassification),
|
||||
(AlbertConfig, AlbertForTokenClassification),
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
+423
-120
@@ -13,8 +13,8 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""PyTorch BART model, ported from the fairseq repo."""
|
||||
|
||||
import logging
|
||||
import math
|
||||
import random
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
|
||||
@@ -24,7 +24,7 @@ from torch import Tensor, nn
|
||||
|
||||
from .configuration_bart import BartConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PreTrainedModel, create_position_ids_from_input_ids
|
||||
from .modeling_utils import BeamHypotheses, PreTrainedModel, create_position_ids_from_input_ids
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -33,6 +33,7 @@ logger = logging.getLogger(__name__)
|
||||
BART_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"bart-large": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large/pytorch_model.bin",
|
||||
"bart-large-mnli": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-mnli/pytorch_model.bin",
|
||||
"bart-large-cnn": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-cnn/pytorch_model.bin",
|
||||
}
|
||||
|
||||
BART_START_DOCSTRING = r"""
|
||||
@@ -64,7 +65,7 @@ BART_INPUTS_DOCSTRING = r"""
|
||||
If you want to change padding behavior, you should read :func:`~transformers.modeling_bart._prepare_decoder_inputs` and modify.
|
||||
See diagram 1 in the paper for more info on the default strategy
|
||||
"""
|
||||
LARGE_NEGATIVE = -1e4
|
||||
LARGE_NEGATIVE = -1e8
|
||||
|
||||
|
||||
def _prepare_bart_decoder_inputs(
|
||||
@@ -86,7 +87,7 @@ def _prepare_bart_decoder_inputs(
|
||||
causal_lm_mask = None
|
||||
new_shape = (bsz, tgt_len, tgt_len)
|
||||
# make it broadcastable so can just be added to the attention coefficients
|
||||
decoder_attn_mask = _combine_masks(decoder_padding_mask, causal_lm_mask, new_shape)
|
||||
decoder_attn_mask = _combine_masks(decoder_padding_mask, causal_lm_mask, new_shape).to(device=input_ids.device)
|
||||
assert decoder_attn_mask is None or decoder_attn_mask.shape == (bsz, 1, tgt_len, tgt_len)
|
||||
return decoder_input_ids, decoder_attn_mask
|
||||
|
||||
@@ -143,18 +144,18 @@ def _check_shapes(shape_1, shape2):
|
||||
raise AssertionError("shape mismatch: {} != {}".format(shape_1, shape2))
|
||||
|
||||
|
||||
def _combine_masks(key_padding_mask, attn_mask, targ_size):
|
||||
def _combine_masks(key_padding_mask, causal_lm_mask, targ_size):
|
||||
# targ_size = (bsz, tgt_len, src_len)
|
||||
a = torch.zeros(targ_size)
|
||||
b = torch.zeros(targ_size)
|
||||
if key_padding_mask is not None: # (bsz, tgt_len) -> targ_size
|
||||
_check_shapes(key_padding_mask.shape, targ_size[:2])
|
||||
reshaped = key_padding_mask.unsqueeze(2).expand(*targ_size)
|
||||
a[reshaped] = 1e-8
|
||||
a[reshaped] = LARGE_NEGATIVE
|
||||
|
||||
if attn_mask is not None: # (tgt_len, src_len) -> targ_size
|
||||
_check_shapes(attn_mask.shape, targ_size[-2:])
|
||||
b = attn_mask.unsqueeze(0).expand(*targ_size)
|
||||
if causal_lm_mask is not None: # (tgt_len, src_len) -> targ_size
|
||||
_check_shapes(causal_lm_mask.shape, targ_size[-2:])
|
||||
b = causal_lm_mask.unsqueeze(0).expand(*targ_size)
|
||||
return (a + b).unsqueeze(1).clamp(LARGE_NEGATIVE,)
|
||||
|
||||
|
||||
@@ -207,7 +208,7 @@ class EncoderLayer(nn.Module):
|
||||
encoded output of shape `(seq_len, batch, embed_dim)`
|
||||
"""
|
||||
residual = x
|
||||
x, attn_weights = self.self_attn.forward(
|
||||
x, attn_weights = self.self_attn(
|
||||
query=x, key=x, value=x, key_padding_mask=encoder_padding_mask, need_weights=self.output_attentions,
|
||||
)
|
||||
x = F.dropout(x, p=self.dropout, training=self.training)
|
||||
@@ -270,6 +271,12 @@ class BartEncoder(nn.Module):
|
||||
- **all_attentions** (List[Tensor]): Attention weights for each layer.
|
||||
During training might not be of length n_layers because of layer dropout.
|
||||
"""
|
||||
# check attention mask and invert
|
||||
if attention_mask is not None:
|
||||
assert attention_mask.dim() == 2
|
||||
|
||||
attention_mask = (1.0 - attention_mask.long()) * -10000.0
|
||||
assert attention_mask.max() <= 0
|
||||
inputs_embeds = self.embed_tokens(input_ids)
|
||||
embed_pos = self.embed_positions(input_ids)
|
||||
x = inputs_embeds + embed_pos
|
||||
@@ -291,7 +298,7 @@ class BartEncoder(nn.Module):
|
||||
if self.training and (dropout_probability < self.layerdrop): # skip the layer
|
||||
attn = None
|
||||
else:
|
||||
x, attn = encoder_layer.forward(x, attention_mask)
|
||||
x, attn = encoder_layer(x, attention_mask)
|
||||
|
||||
if self.output_attentions:
|
||||
all_attentions.append(attn)
|
||||
@@ -332,7 +339,7 @@ class DecoderLayer(nn.Module):
|
||||
x,
|
||||
encoder_hidden_states,
|
||||
encoder_attn_mask=None,
|
||||
decoder_cached_states=None,
|
||||
layer_state=None,
|
||||
attention_mask=None,
|
||||
need_attn_weights=False,
|
||||
):
|
||||
@@ -348,43 +355,28 @@ class DecoderLayer(nn.Module):
|
||||
Returns:
|
||||
encoded output of shape `(seq_len, batch, embed_dim)`
|
||||
"""
|
||||
if decoder_cached_states is None:
|
||||
prev_self_attn_state, prev_attn_state = (None, None)
|
||||
else:
|
||||
assert len(decoder_cached_states) == 3
|
||||
prev_self_attn_state, prev_attn_state = (
|
||||
decoder_cached_states["self"],
|
||||
decoder_cached_states["encoder_decoder"],
|
||||
)
|
||||
|
||||
residual = x
|
||||
if prev_self_attn_state is not None:
|
||||
saved_state = prev_self_attn_state
|
||||
decoder_cached_states["self"] = saved_state
|
||||
y = x # TODO(SS): figure out why fairseq did this, then hopefully delete it
|
||||
|
||||
x, self_attn_weights = self.self_attn.forward(
|
||||
query=x,
|
||||
key=y,
|
||||
value=y,
|
||||
decoder_cached_states=decoder_cached_states,
|
||||
need_weights=need_attn_weights,
|
||||
attn_mask=attention_mask,
|
||||
if layer_state is None:
|
||||
layer_state = {}
|
||||
# next line mutates layer state
|
||||
x, self_attn_weights = self.self_attn(
|
||||
query=x, key=y, value=y, layer_state=layer_state, need_weights=need_attn_weights, attn_mask=attention_mask,
|
||||
)
|
||||
x = F.dropout(x, p=self.dropout, training=self.training)
|
||||
x = residual + x
|
||||
x = self.self_attn_layer_norm(x)
|
||||
residual = x
|
||||
assert self.encoder_attn.cache_key != self.self_attn.cache_key
|
||||
if prev_attn_state is not None:
|
||||
saved_state = prev_attn_state
|
||||
decoder_cached_states["encoder_decoder"] = saved_state
|
||||
x, encoder_attn_weights = self.encoder_attn.forward(
|
||||
|
||||
x, encoder_attn_weights = self.encoder_attn(
|
||||
query=x,
|
||||
key=encoder_hidden_states, # could be None
|
||||
value=encoder_hidden_states,
|
||||
key_padding_mask=encoder_attn_mask,
|
||||
decoder_cached_states=decoder_cached_states,
|
||||
layer_state=layer_state, # mutates layer state
|
||||
static_kv=True,
|
||||
need_weights=False, # not returning it so why compute it
|
||||
)
|
||||
@@ -403,15 +395,8 @@ class DecoderLayer(nn.Module):
|
||||
return (
|
||||
x,
|
||||
self_attn_weights,
|
||||
decoder_cached_states,
|
||||
) # just self_attn weights for now, following t5, decoder_cached_states = cache for decoding
|
||||
|
||||
def _past_to_dict(self, prev_attn_state):
|
||||
prev_key, prev_value = prev_attn_state[:2]
|
||||
saved_state = {"prev_key": prev_key, "prev_value": prev_value}
|
||||
if len(prev_attn_state) >= 3:
|
||||
saved_state["prev_key_padding_mask"] = prev_attn_state[2]
|
||||
return saved_state
|
||||
layer_state,
|
||||
) # just self_attn weights for now, following t5, layer_state = cache for decoding
|
||||
|
||||
|
||||
class BartDecoder(nn.Module):
|
||||
@@ -440,6 +425,7 @@ class BartDecoder(nn.Module):
|
||||
[DecoderLayer(config) for _ in range(config.decoder_layers)]
|
||||
) # type: List[DecoderLayer]
|
||||
self.layernorm_embedding = LayerNorm(config.d_model)
|
||||
self.generation_mode = False
|
||||
|
||||
def forward(
|
||||
self,
|
||||
@@ -468,12 +454,23 @@ class BartDecoder(nn.Module):
|
||||
- hidden states
|
||||
- attentions
|
||||
"""
|
||||
# embed positions
|
||||
positions = self.embed_positions(input_ids)
|
||||
x = self.embed_tokens(input_ids)
|
||||
# check attention mask and invert
|
||||
if encoder_padding_mask is not None:
|
||||
assert encoder_padding_mask.dim() == 2
|
||||
|
||||
if positions is not None:
|
||||
x += positions
|
||||
encoder_padding_mask = (1.0 - encoder_padding_mask.long()) * -10000.0
|
||||
assert encoder_padding_mask.max() <= 0
|
||||
|
||||
# embed positions
|
||||
positions = self.embed_positions(input_ids, generation_mode=self.generation_mode)
|
||||
|
||||
if self.generation_mode:
|
||||
input_ids = input_ids[:, -1:]
|
||||
positions = positions[:, -1:] # happens after we embed them
|
||||
assert input_ids.ne(self.padding_idx).any()
|
||||
|
||||
x = self.embed_tokens(input_ids)
|
||||
x += positions
|
||||
|
||||
x = self.layernorm_embedding(x)
|
||||
x = F.dropout(x, p=self.dropout, training=self.training)
|
||||
@@ -489,17 +486,19 @@ class BartDecoder(nn.Module):
|
||||
dropout_probability = random.uniform(0, 1)
|
||||
if self.training and (dropout_probability < self.layerdrop):
|
||||
continue
|
||||
|
||||
layer_state = decoder_cached_states[i] if decoder_cached_states is not None else None
|
||||
x, layer_self_attn, layer_past = decoder_layer.forward(
|
||||
x, layer_self_attn, layer_past = decoder_layer(
|
||||
x,
|
||||
encoder_hidden_states,
|
||||
encoder_padding_mask,
|
||||
decoder_cached_states=layer_state,
|
||||
layer_state=layer_state,
|
||||
attention_mask=combined_mask,
|
||||
need_attn_weights=self.output_attentions,
|
||||
)
|
||||
|
||||
if self.output_past:
|
||||
next_decoder_cache.append(layer_past)
|
||||
next_decoder_cache.append(layer_past.copy())
|
||||
if self.output_hidden_states:
|
||||
all_hidden_states += (x,)
|
||||
if self.output_attentions:
|
||||
@@ -509,7 +508,22 @@ class BartDecoder(nn.Module):
|
||||
all_hidden_states = [hidden_state.transpose(0, 1) for hidden_state in all_hidden_states]
|
||||
x = x.transpose(0, 1)
|
||||
|
||||
return x, next_decoder_cache, all_hidden_states, list(all_self_attns)
|
||||
if self.output_past:
|
||||
next_cache = ((encoder_hidden_states, encoder_padding_mask), next_decoder_cache)
|
||||
else:
|
||||
next_cache = None
|
||||
return x, next_cache, all_hidden_states, list(all_self_attns)
|
||||
|
||||
|
||||
def reorder_attn_buffer(input_buffer, new_order):
|
||||
"""Reorder buffered internal state (for incremental generation)."""
|
||||
# input_buffer = self._get_input_buffer(incremental_state)
|
||||
for k in input_buffer.keys():
|
||||
input_buffer_k = input_buffer[k]
|
||||
if input_buffer_k is not None:
|
||||
input_buffer[k] = input_buffer_k.index_select(0, new_order)
|
||||
# incremental_state = self._set_input_buffer(incremental_state, input_buffer)
|
||||
return input_buffer
|
||||
|
||||
|
||||
class SelfAttention(nn.Module):
|
||||
@@ -557,7 +571,7 @@ class SelfAttention(nn.Module):
|
||||
key: Optional[Tensor],
|
||||
value: Optional[Tensor],
|
||||
key_padding_mask: Optional[Tensor] = None,
|
||||
decoder_cached_states: Optional[Dict[str, Dict[str, Optional[Tensor]]]] = None,
|
||||
layer_state: Optional[Dict[str, Dict[str, Optional[Tensor]]]] = None,
|
||||
need_weights: bool = False,
|
||||
static_kv: bool = False,
|
||||
attn_mask: Optional[Tensor] = None,
|
||||
@@ -579,8 +593,8 @@ class SelfAttention(nn.Module):
|
||||
assert embed_dim == self.embed_dim
|
||||
assert list(query.size()) == [tgt_len, bsz, embed_dim]
|
||||
# get here for encoder decoder cause of static_kv
|
||||
if decoder_cached_states is not None: # get the last k,v and mask for reuse
|
||||
saved_state = decoder_cached_states.get(self.cache_key, {})
|
||||
if layer_state is not None: # get the last k,v and mask for reuse
|
||||
saved_state = layer_state.get(self.cache_key, {})
|
||||
if "prev_key" in saved_state:
|
||||
# previous time steps are cached - no need to recompute key and value if they are static
|
||||
if static_kv:
|
||||
@@ -588,6 +602,7 @@ class SelfAttention(nn.Module):
|
||||
key = value = None
|
||||
else:
|
||||
saved_state = None
|
||||
layer_state = {}
|
||||
|
||||
q = self.q_proj(query) * self.scaling
|
||||
if self.encoder_decoder_attention:
|
||||
@@ -608,17 +623,16 @@ class SelfAttention(nn.Module):
|
||||
v = self._shape(v, -1, bsz)
|
||||
|
||||
if saved_state is not None:
|
||||
k, v, key_padding_mask, new_state = self._use_and_update_saved_state(
|
||||
k, v, saved_state, key_padding_mask, static_kv, bsz
|
||||
)
|
||||
saved_state.update(
|
||||
{
|
||||
"prev_key": k.view(bsz, self.num_heads, -1, self.head_dim),
|
||||
"prev_value": v.view(bsz, self.num_heads, -1, self.head_dim),
|
||||
"prev_key_padding_mask": key_padding_mask,
|
||||
}
|
||||
)
|
||||
decoder_cached_states[self.cache_key] = saved_state # Update cache
|
||||
k, v, key_padding_mask = self._use_saved_state(k, v, saved_state, key_padding_mask, static_kv, bsz)
|
||||
# assert self.cache_key != 'encoder_decoder' or key_padding_mask is None
|
||||
|
||||
# Update cache
|
||||
layer_state[self.cache_key] = {
|
||||
"prev_key": k.view(bsz, self.num_heads, -1, self.head_dim),
|
||||
"prev_value": v.view(bsz, self.num_heads, -1, self.head_dim),
|
||||
"prev_key_padding_mask": key_padding_mask if not static_kv else None,
|
||||
}
|
||||
|
||||
assert k is not None
|
||||
src_len = k.size(1)
|
||||
attn_weights = torch.bmm(q, k.transpose(1, 2))
|
||||
@@ -632,16 +646,16 @@ class SelfAttention(nn.Module):
|
||||
# This is part of a workaround to get around fork/join parallelism not supporting Optional types.
|
||||
if key_padding_mask is not None and key_padding_mask.dim() == 0:
|
||||
key_padding_mask = None
|
||||
assert key_padding_mask is None or key_padding_mask.size()[:2] == (bsz, src_len)
|
||||
assert key_padding_mask is None or key_padding_mask.size()[:2] == (bsz, src_len,)
|
||||
|
||||
if key_padding_mask is not None: # don't attend to padding symbols
|
||||
attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
|
||||
reshaped = key_padding_mask.unsqueeze(1).unsqueeze(2).to(torch.bool)
|
||||
attn_weights = attn_weights.masked_fill(reshaped, float("-inf"))
|
||||
attn_weights = attn_weights.view(bsz * self.num_heads, tgt_len, src_len)
|
||||
attn_weights_float = F.softmax(attn_weights, dim=-1, dtype=torch.float32)
|
||||
attn_weights = attn_weights_float.type_as(attn_weights)
|
||||
attn_probs = F.dropout(attn_weights_float, p=self.dropout, training=self.training,)
|
||||
attn_weights = F.softmax(attn_weights, dim=-1)
|
||||
attn_probs = F.dropout(attn_weights, p=self.dropout, training=self.training,)
|
||||
|
||||
assert v is not None
|
||||
attn_output = torch.bmm(attn_probs, v)
|
||||
assert attn_output.size() == (bsz * self.num_heads, tgt_len, self.head_dim)
|
||||
@@ -650,7 +664,7 @@ class SelfAttention(nn.Module):
|
||||
attn_weights = attn_weights.view(bsz, self.num_heads, tgt_len, src_len)
|
||||
return attn_output, attn_weights
|
||||
|
||||
def _use_and_update_saved_state(self, k, v, saved_state, key_padding_mask, static_kv, bsz):
|
||||
def _use_saved_state(self, k, v, saved_state, key_padding_mask, static_kv, bsz):
|
||||
# saved states are stored with shape (bsz, num_heads, seq_len, head_dim)
|
||||
if "prev_key" in saved_state:
|
||||
_prev_key = saved_state["prev_key"]
|
||||
@@ -675,7 +689,7 @@ class SelfAttention(nn.Module):
|
||||
key_padding_mask = self._cat_prev_key_padding_mask(
|
||||
key_padding_mask, prev_key_padding_mask, bsz, k.size(1), static_kv
|
||||
)
|
||||
return k, v, key_padding_mask, saved_state
|
||||
return k, v, key_padding_mask
|
||||
|
||||
@staticmethod
|
||||
def _cat_prev_key_padding_mask(
|
||||
@@ -693,10 +707,9 @@ class SelfAttention(nn.Module):
|
||||
# During incremental decoding, as the padding token enters and
|
||||
# leaves the frame, there will be a time when prev or current is None
|
||||
elif prev_key_padding_mask is not None:
|
||||
|
||||
filler = torch.zeros(batch_size, src_len - prev_key_padding_mask.size(1))
|
||||
if prev_key_padding_mask.is_cuda:
|
||||
filler = filler.cuda()
|
||||
filler = filler.to(prev_key_padding_mask.device)
|
||||
new_key_padding_mask = torch.cat([prev_key_padding_mask.float(), filler.float()], dim=1)
|
||||
elif key_padding_mask is not None:
|
||||
filler = torch.zeros(batch_size, src_len - key_padding_mask.size(1))
|
||||
@@ -747,9 +760,13 @@ class LearnedPositionalEmbedding(nn.Embedding):
|
||||
num_embeddings += padding_idx + 1 # WHY?
|
||||
super().__init__(num_embeddings, embedding_dim, padding_idx=padding_idx)
|
||||
|
||||
def forward(self, input):
|
||||
def forward(self, input, generation_mode=False):
|
||||
"""Input is expected to be of size [bsz x seqlen]."""
|
||||
positions = create_position_ids_from_input_ids(input, self.padding_idx)
|
||||
if generation_mode: # the position is our current step in the decoded sequence
|
||||
pos = int(self.padding_idx + input.size(1))
|
||||
positions = input.data.new(1, 1).fill_(pos)
|
||||
else:
|
||||
positions = create_position_ids_from_input_ids(input, self.padding_idx)
|
||||
return super().forward(positions)
|
||||
|
||||
|
||||
@@ -774,21 +791,6 @@ def _filter_out_falsey_values(tup) -> Tuple:
|
||||
return tuple(x for x in tup if isinstance(x, torch.Tensor) or x)
|
||||
|
||||
|
||||
RET_DOCSTRING = r"""
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
"""
|
||||
# Public API
|
||||
|
||||
|
||||
@@ -819,28 +821,22 @@ class BartModel(PretrainedBartModel):
|
||||
decoder_attention_mask=None,
|
||||
decoder_cached_states=None,
|
||||
):
|
||||
if attention_mask is not None:
|
||||
assert attention_mask.dim() == 2
|
||||
|
||||
attention_mask = (1.0 - attention_mask.long()) * -10000.0
|
||||
assert attention_mask.max() <= 0
|
||||
|
||||
# make masks if user doesn't supply
|
||||
decoder_input_ids, decoder_attn_mask = _prepare_bart_decoder_inputs(
|
||||
self.config, input_ids, decoder_input_ids=decoder_input_ids, decoder_attn_mask=decoder_attention_mask,
|
||||
)
|
||||
|
||||
if not self.decoder.generation_mode:
|
||||
decoder_input_ids, decoder_attention_mask = _prepare_bart_decoder_inputs(
|
||||
self.config, input_ids, decoder_input_ids=decoder_input_ids, decoder_attn_mask=decoder_attention_mask,
|
||||
)
|
||||
assert decoder_input_ids is not None
|
||||
if encoder_outputs is None:
|
||||
# TODO(SS): make this caching more usable when overwrite generate
|
||||
encoder_outputs = self.encoder.forward(input_ids=input_ids, attention_mask=attention_mask)
|
||||
encoder_outputs = self.encoder(input_ids=input_ids, attention_mask=attention_mask)
|
||||
assert isinstance(encoder_outputs, tuple)
|
||||
# dec_features, decoder_cached_states, dec_hidden, dec_attn
|
||||
decoder_outputs = self.decoder.forward(
|
||||
# decoder outputs consists of (dec_features, layer_state, dec_hidden, dec_attn)
|
||||
decoder_outputs = self.decoder(
|
||||
decoder_input_ids,
|
||||
encoder_outputs[0],
|
||||
attention_mask,
|
||||
decoder_attn_mask,
|
||||
decoder_attention_mask,
|
||||
decoder_cached_states=decoder_cached_states,
|
||||
)
|
||||
# Attention and hidden_states will be [] or None if they aren't needed
|
||||
@@ -856,20 +852,25 @@ class BartModel(PretrainedBartModel):
|
||||
self.shared = value
|
||||
|
||||
def get_output_embeddings(self):
|
||||
return _make_linear_from_emb(self.shared)
|
||||
return _make_linear_from_emb(self.shared) # make it on the fly
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"The bare BART Model with a language modeling head", BART_START_DOCSTRING,
|
||||
"The BART Model with a language modeling head. Can be used for summarization.", BART_START_DOCSTRING,
|
||||
)
|
||||
class BartForMaskedLM(PretrainedBartModel):
|
||||
class BartForConditionalGeneration(PretrainedBartModel):
|
||||
base_model_prefix = "model"
|
||||
|
||||
def __init__(self, config: BartConfig):
|
||||
super().__init__(config)
|
||||
self.model = BartModel(config)
|
||||
# if base_model is None:
|
||||
base_model = BartModel(config)
|
||||
self.model = base_model
|
||||
self.lm_head = _make_linear_from_emb(self.model.shared)
|
||||
|
||||
def tie_weights(self):
|
||||
pass # hack to prevent changing lm_head.out_features. The input and output embeddings are still the same.
|
||||
|
||||
@add_start_docstrings_to_callable(BART_INPUTS_DOCSTRING)
|
||||
def forward(
|
||||
self,
|
||||
@@ -910,13 +911,20 @@ class BartForMaskedLM(PretrainedBartModel):
|
||||
|
||||
Examples::
|
||||
|
||||
# Mask filling only works for bart-large
|
||||
from transformers import BartTokenizer, BartForConditionalGeneration
|
||||
tokenizer = BartTokenizer.from_pretrained('bart-large')
|
||||
model = BartForMaskedLM.from_pretrained('bart-large')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids=input_ids, lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
TXT = "My friends are <mask> but they eat too many carbs."
|
||||
model = BartForConditionalGeneration.from_pretrained('bart-large')
|
||||
input_ids = tokenizer.batch_encode_plus([TXT], return_tensors='pt')['input_ids']
|
||||
logits = model(input_ids)[0]
|
||||
masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item()
|
||||
probs = logits[0, masked_index].softmax(dim=0)
|
||||
values, predictions = probs.topk(5)
|
||||
tokenizer.decode(predictions).split()
|
||||
# ['good', 'great', 'all', 'really', 'very']
|
||||
"""
|
||||
outputs = self.model.forward(
|
||||
outputs = self.model(
|
||||
input_ids,
|
||||
attention_mask=attention_mask,
|
||||
decoder_input_ids=decoder_input_ids,
|
||||
@@ -924,7 +932,7 @@ class BartForMaskedLM(PretrainedBartModel):
|
||||
decoder_attention_mask=decoder_attention_mask,
|
||||
decoder_cached_states=decoder_cached_states,
|
||||
)
|
||||
lm_logits = self.lm_head.forward(outputs[0])
|
||||
lm_logits = self.lm_head(outputs[0])
|
||||
outputs = (lm_logits,) + outputs[1:] # Add hidden states and attention if they are here
|
||||
if lm_labels is not None:
|
||||
loss_fct = nn.CrossEntropyLoss()
|
||||
@@ -935,12 +943,307 @@ class BartForMaskedLM(PretrainedBartModel):
|
||||
return outputs
|
||||
|
||||
@staticmethod
|
||||
def prepare_inputs_for_generation(input_ids, past, **kwargs):
|
||||
return {"input_ids": input_ids, "decoder_cached_states": past, "decoder_input_ids": input_ids[:, -1:]}
|
||||
def prepare_inputs_for_generation(input_ids, past, decoder_input_ids, attention_mask):
|
||||
if past is None: # first step
|
||||
encoder_outputs, decoder_cached_states = None, None
|
||||
else:
|
||||
encoder_outputs, decoder_cached_states = past
|
||||
return {
|
||||
"input_ids": input_ids, # ignored after first pass
|
||||
"decoder_cached_states": decoder_cached_states,
|
||||
"decoder_input_ids": decoder_input_ids,
|
||||
"encoder_outputs": encoder_outputs,
|
||||
"attention_mask": attention_mask,
|
||||
# "decoder_attention_mask": decoder_attention_mask,
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def _reorder_cache(past, beam_idx):
|
||||
((enc_out, enc_mask), decoder_cached_states) = past
|
||||
reordered_past = []
|
||||
for layer_past in decoder_cached_states:
|
||||
# get the correct batch idx from decoder layer's batch dim for cross and self-attn
|
||||
layer_past_new = {
|
||||
attn_key: reorder_attn_buffer(attn_cache, beam_idx) for attn_key, attn_cache in layer_past.items()
|
||||
}
|
||||
# reordered_layer_past = [layer_past[:, i].unsqueeze(1).clone().detach() for i in beam_idx]
|
||||
# reordered_layer_past = torch.cat(reordered_layer_past, dim=1)
|
||||
reordered_past.append(layer_past_new)
|
||||
new_enc_out = enc_out if enc_out is None else enc_out.index_select(1, beam_idx)
|
||||
new_enc_mask = enc_mask if enc_mask is None else enc_mask.index_select(0, beam_idx)
|
||||
|
||||
past = ((new_enc_out, new_enc_mask), reordered_past)
|
||||
return past
|
||||
|
||||
def get_output_embeddings(self):
|
||||
return self.lm_head
|
||||
|
||||
@torch.no_grad()
|
||||
def generate(
|
||||
self,
|
||||
input_ids,
|
||||
attention_mask=None,
|
||||
max_length=20,
|
||||
num_beams=1,
|
||||
repetition_penalty=1.0,
|
||||
length_penalty=1.0,
|
||||
num_return_sequences=1,
|
||||
min_len=0,
|
||||
no_repeat_ngram_size=0,
|
||||
):
|
||||
r""" Generates summaries using the lm-head and greedy beam search
|
||||
|
||||
Adapted in part from Facebook's `XLM beam search code`_ and `Fairseq beam search code`_.
|
||||
|
||||
.. _`XLM beam search code`:
|
||||
https://github.com/facebookresearch/XLM/blob/9e6f6814d17be4fe5b15f2e6c43eb2b2d76daeb4/src/model/transformer.py#L529
|
||||
.. _`Fairseq beam search code`:
|
||||
https://github.com/pytorch/fairseq/blob/master/fairseq/sequence_generator.py
|
||||
|
||||
|
||||
Parameters:
|
||||
|
||||
input_ids: (`optional`) `torch.LongTensor` of shape `(batch_size, sequence_length)`
|
||||
The sequence used as a prompt for the generation. If `None` the method initializes
|
||||
it as an empty `torch.LongTensor` of shape `(1,)`.
|
||||
|
||||
max_length: (`optional`) int
|
||||
The max length of the sequence to be generated. Does not include tokens in input_ids.
|
||||
|
||||
num_beams: (`optional`) int
|
||||
Number of beams for beam search. Must be between 1 and infinity. 1 means no beam search. Default to 1.
|
||||
|
||||
repetition_penalty: (`optional`) float
|
||||
The parameter for repetition penalty. Between 1.0 and infinity. 1.0 means no penalty. Default to 1.0.
|
||||
|
||||
length_penalty: (`optional`) float
|
||||
Exponential penalty to the length. Default to 1.
|
||||
|
||||
num_return_sequences: (`optional`) int
|
||||
The number of independently computed returned sequences for each element in the batch. Default to 1.
|
||||
|
||||
min_len: (`optional`) int
|
||||
|
||||
Returns:
|
||||
`torch.LongTensor` of shape `(batch_size * num_return_sequences, sequence_length)`
|
||||
sequence_length is <= max_length (examples can finish early)
|
||||
|
||||
Examples::
|
||||
from transformers import BartTokenizer, BartForConditionalGeneration, BartConfig
|
||||
# see ``examples/summarization/bart/evaluate_cnn.py`` for a longer example
|
||||
model = BartForConditionalGeneration.from_pretrained('bart-large-cnn')
|
||||
tokenizer = BartTokenizer.from_pretrained('bart-large-cnn')
|
||||
ARTICLE_TO_SUMMARIZE = "My friends are cool but they eat too many carbs."
|
||||
inputs = tokenizer.batch_encode_plus([ARTICLE_TO_SUMMARIZE], max_length=1024, return_tensors='pt')
|
||||
# Generate Summary
|
||||
summary_ids = model.generate(inputs['input_ids'], attention_mask=inputs['attention_mask'], num_beams=4, max_length=5)
|
||||
print([tokenizer.decode(g, skip_special_tokens=True, clean_up_tokenization_spaces=False) for g in summary_ids])
|
||||
"""
|
||||
bos_token_id = self.config.bos_token_id
|
||||
pad_token_id = self.config.pad_token_id
|
||||
eos_token_id = self.config.eos_token_id
|
||||
batch_size, cur_len = input_ids.shape
|
||||
assert input_ids is not None
|
||||
assert self.config.output_past, "Generating with bart requires instantiating a config with output_past=True"
|
||||
assert isinstance(max_length, int) and max_length > 0, "`max_length` should be a strictly positive integer."
|
||||
assert isinstance(num_beams, int) and num_beams > 0, "`num_beams` should be a strictly positive integer."
|
||||
assert repetition_penalty >= 1.0, "`repetition_penalty` should be >= 1."
|
||||
assert isinstance(pad_token_id, int)
|
||||
assert bos_token_id == 0, "configurable bos_token_id not yet supported"
|
||||
assert length_penalty > 0, "`length_penalty` should be strictly positive."
|
||||
assert (
|
||||
isinstance(num_return_sequences, int) and num_return_sequences > 0
|
||||
), "`num_return_sequences` should be a positive integer."
|
||||
|
||||
# current position and vocab size
|
||||
cur_len = input_ids.shape[1]
|
||||
vocab_size = self.config.vocab_size
|
||||
|
||||
if num_return_sequences != 1:
|
||||
# Expand input to num return sequences
|
||||
input_ids = input_ids.unsqueeze(1).expand(batch_size, num_return_sequences, cur_len)
|
||||
input_ids = input_ids.contiguous().view(
|
||||
batch_size * num_return_sequences, cur_len
|
||||
) # shape: (batch_size * num_return_sequences, cur_len)
|
||||
batch_size *= num_return_sequences
|
||||
|
||||
# Below here somewhat similar to PretrainedModel._generate_beam_search
|
||||
# Expand input to num beams
|
||||
input_ids = input_ids.unsqueeze(1).expand(batch_size, num_beams, cur_len)
|
||||
|
||||
input_ids = input_ids.contiguous().view(batch_size * num_beams, cur_len) # (batch_size * num_beams, cur_len)
|
||||
if attention_mask is not None:
|
||||
attention_mask = (
|
||||
attention_mask.unsqueeze(1)
|
||||
.expand(batch_size, num_beams, cur_len)
|
||||
.contiguous()
|
||||
.view(batch_size * num_beams, cur_len)
|
||||
) # RESHAPE
|
||||
|
||||
# generated hypotheses
|
||||
finalized_hyps = [ # they end in EOS and we wont work on them more!
|
||||
BeamHypotheses(num_beams, max_length, length_penalty, early_stopping=True) for _ in range(batch_size)
|
||||
]
|
||||
|
||||
# scores for each sentence in the beam
|
||||
beam_scores = torch.zeros((batch_size, num_beams), dtype=torch.float, device=input_ids.device)
|
||||
beam_scores[:, 1:] = -1e9 # avoid ties in first step
|
||||
beam_scores = beam_scores.view(-1) # shape (batch_size * num_beams,)
|
||||
|
||||
# decoder tokens
|
||||
prev_output_tokens = input_ids.new(batch_size * num_beams, 1).long().fill_(-1)
|
||||
prev_output_tokens[:, 0] = 2 # HARDCODED EOS, which will be removed at the end.
|
||||
decoder_cache = None
|
||||
done = [False for _ in range(batch_size)] # done sentences
|
||||
|
||||
self.model.decoder.generation_mode = True # tells decoder not to use causal mask
|
||||
for step in range(max_length + 1):
|
||||
decoder_input_ids = prev_output_tokens.clone()
|
||||
model_inputs = self.prepare_inputs_for_generation(
|
||||
input_ids, decoder_cache, decoder_input_ids, attention_mask,
|
||||
)
|
||||
outputs = self(**model_inputs)
|
||||
lprobs = F.log_softmax(outputs[0][:, -1, :], dim=-1)
|
||||
|
||||
lprobs[lprobs != lprobs] = -math.inf # block nans
|
||||
lprobs[:, pad_token_id] = -math.inf
|
||||
# TODO(SS): fairseq also takes out <unk> every step, and has unk at slot 3
|
||||
|
||||
if step == 0: # Force BOS to be chosen
|
||||
lprobs[:, bos_token_id + 1 :] = -math.inf
|
||||
elif step < min_len: # Prevent EOS from being chosen
|
||||
lprobs[:, eos_token_id] = -math.inf
|
||||
elif step == max_length: # FORCE EOS to be chosen
|
||||
lprobs[:, :eos_token_id] = -math.inf
|
||||
lprobs[:, eos_token_id + 1 :] = -math.inf
|
||||
assert self._do_output_past(outputs)
|
||||
decoder_cache = outputs[1]
|
||||
if repetition_penalty != 1.0:
|
||||
self.enforce_repetition_penalty_(lprobs, batch_size, num_beams, prev_output_tokens, repetition_penalty)
|
||||
num_hypos = batch_size * num_beams
|
||||
if no_repeat_ngram_size > 0: # copied from fairseq
|
||||
# for each sentence, calculate a list of banned tokens to prevent repetitively generating the same ngrams
|
||||
banned_tokens = self.calc_banned_tokens(prev_output_tokens, num_hypos, no_repeat_ngram_size, step)
|
||||
# then set their probabilities tof -inf
|
||||
for idx in range(num_hypos):
|
||||
lprobs[idx, banned_tokens[idx]] = -math.inf
|
||||
assert lprobs.size() == (batch_size * num_beams, vocab_size)
|
||||
_scores = lprobs + beam_scores[:, None].expand_as(lprobs) # (batch_size * num_beams, vocab_size)
|
||||
|
||||
# re-organize to group the beam together (we are keeping top hypothesis across beams)
|
||||
_scores = _scores.view(batch_size, num_beams * vocab_size) # (batch_size, num_beams * vocab_size)
|
||||
# Take the best 2 x beam_size predictions for each example, we'll choose the first beam_size of these which don't predict eos to continue with.
|
||||
next_scores, next_words = torch.topk(_scores, 2 * num_beams)
|
||||
assert next_scores.size() == next_words.size() == (batch_size, 2 * num_beams)
|
||||
|
||||
# list of (batch_size * num_beams)
|
||||
next_batch_beam = [] # Tuple(next score, next word, current position in the batch)
|
||||
for batch_idx in range(batch_size):
|
||||
# if we are done with this sentence (because we can't improve)
|
||||
if done[batch_idx]: # then pad all associated hypotheses
|
||||
assert (
|
||||
len(finalized_hyps[batch_idx]) >= num_beams
|
||||
), "Example can only be done if at least {} beams have been generated".format(num_beams)
|
||||
next_batch_beam.extend([(0, pad_token_id, 0)] * num_beams) # pad the batch
|
||||
continue
|
||||
|
||||
# Otherwise generate some next word choices
|
||||
next_sent_beam = []
|
||||
# add next words for this sentence
|
||||
for i, (idx, score) in enumerate(zip(next_words[batch_idx], next_scores[batch_idx])):
|
||||
beam_id = idx // vocab_size
|
||||
word_id = idx % vocab_size
|
||||
assert prev_output_tokens.shape[1] == (step + 1)
|
||||
if word_id.item() == eos_token_id:
|
||||
if i >= num_beams:
|
||||
continue
|
||||
finalized_hyps[batch_idx].add(
|
||||
prev_output_tokens[batch_idx * num_beams + beam_id].clone(), score.item(),
|
||||
)
|
||||
else:
|
||||
next_sent_beam.append((score, word_id, batch_idx * num_beams + beam_id))
|
||||
|
||||
if len(next_sent_beam) == num_beams: # TODO(SS): can we delete this?
|
||||
break
|
||||
# Check if were done so that we can save a pad step if all(done)
|
||||
done[batch_idx] = done[batch_idx] or finalized_hyps[batch_idx].is_done(
|
||||
next_scores[batch_idx].max().item(), cur_len=step + 1,
|
||||
)
|
||||
assert len(next_sent_beam) == num_beams, "Beam should always be full"
|
||||
next_batch_beam.extend(next_sent_beam)
|
||||
assert len(next_batch_beam) == num_beams * (batch_idx + 1)
|
||||
|
||||
if all(done):
|
||||
break
|
||||
|
||||
# sanity check / prepare next batch
|
||||
assert len(next_batch_beam) == batch_size * num_beams
|
||||
beam_scores = beam_scores.new([x[0] for x in next_batch_beam])
|
||||
beam_words = input_ids.new([x[1] for x in next_batch_beam])
|
||||
beam_idx = input_ids.new([x[2] for x in next_batch_beam])
|
||||
# re-order decoder inputs to [beam_idx]
|
||||
prev_output_tokens = prev_output_tokens[beam_idx]
|
||||
prev_output_tokens = torch.cat([prev_output_tokens, beam_words.unsqueeze(1)], dim=-1)
|
||||
|
||||
# re-order internal states
|
||||
decoder_cache = self._reorder_cache(decoder_cache, beam_idx)
|
||||
|
||||
for batch_idx in range(batch_size):
|
||||
# Add all open beam hypothesis to generated_hyps
|
||||
if done[batch_idx]:
|
||||
continue
|
||||
offset = batch_idx * num_beams
|
||||
for i in range(num_beams):
|
||||
score = beam_scores[offset + i]
|
||||
final_tokens = prev_output_tokens[offset + i]
|
||||
finalized_hyps[batch_idx].add(final_tokens, score.item())
|
||||
|
||||
# select the best hypotheses
|
||||
sent_lengths = input_ids.new(batch_size)
|
||||
best = []
|
||||
for i, hypotheses in enumerate(finalized_hyps):
|
||||
best_hyp = max(hypotheses.beams, key=lambda x: x[0])[1]
|
||||
sent_lengths[i] = len(best_hyp)
|
||||
best.append(best_hyp)
|
||||
|
||||
# shorter batches are filled with pad_token
|
||||
if sent_lengths.min().item() != sent_lengths.max().item():
|
||||
# TODO(SS): decoded = torch.rnn.utils.pad_sequence(best, batch_first=True, padding_value=pad_token_id)
|
||||
sent_max_len = min(sent_lengths.max().item() + 1, max_length + 1) # TODO(SS): same as step?
|
||||
decoded = input_ids.new(batch_size, sent_max_len).fill_(pad_token_id)
|
||||
# fill with hypothesis and eos_token_id if necessary
|
||||
for i, hypo in enumerate(best):
|
||||
decoded[i, : sent_lengths[i]] = hypo
|
||||
if sent_lengths[i] < max_length:
|
||||
decoded[i, sent_lengths[i]] = eos_token_id
|
||||
else:
|
||||
assert (len(hypo) == max_length for hypo in best)
|
||||
decoded = torch.stack(best).type(torch.long).to(next(self.parameters()).device)
|
||||
return decoded[:, 1:] # get rid of starting EOS
|
||||
|
||||
@staticmethod
|
||||
def calc_banned_tokens(prev_output_tokens, num_hypos, no_repeat_ngram_size, step):
|
||||
"""Copied from fairseq for no_repeat_ngram in beam_search"""
|
||||
# TODO(SS): this can go on parent if there is demand
|
||||
if step + 2 < no_repeat_ngram_size:
|
||||
return [
|
||||
[] for _ in range(num_hypos)
|
||||
] # no banned tokens if we haven't generated no_repeat_ngram_size tokens yet
|
||||
gen_ngrams = [{} for _ in range(num_hypos)]
|
||||
for idx in range(num_hypos):
|
||||
gen_tokens = prev_output_tokens[idx].tolist()
|
||||
for ngram in zip(*[gen_tokens[i:] for i in range(no_repeat_ngram_size)]):
|
||||
k = tuple(ngram[:-1])
|
||||
gen_ngrams[idx][k] = gen_ngrams[idx].get(k, []) + [ngram[-1]]
|
||||
|
||||
def _get_generated_ngrams(hypo_idx):
|
||||
"""Before decoding the next token, prevent decoding of ngrams that have already appeared"""
|
||||
ngram_index = tuple(prev_output_tokens[hypo_idx, step + 2 - no_repeat_ngram_size : step + 1].tolist())
|
||||
return gen_ngrams[hypo_idx].get(ngram_index, [])
|
||||
|
||||
banned_tokens = [_get_generated_ngrams(hypo_idx) for hypo_idx in range(num_hypos)]
|
||||
return banned_tokens
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""Bart model with a sequence classification/head on top (a linear layer on top of the pooled output) e.g. for GLUE tasks. """,
|
||||
@@ -1002,7 +1305,7 @@ class BartForSequenceClassification(PretrainedBartModel):
|
||||
loss, logits = outputs[:2]
|
||||
|
||||
"""
|
||||
outputs = self.model.forward(
|
||||
outputs = self.model(
|
||||
input_ids,
|
||||
attention_mask=attention_mask,
|
||||
decoder_input_ids=decoder_input_ids,
|
||||
@@ -1018,7 +1321,7 @@ class BartForSequenceClassification(PretrainedBartModel):
|
||||
# Prepend logits
|
||||
outputs = (logits,) + outputs[1:] # Add hidden states and attention if they are here
|
||||
if labels is not None: # prepend loss to output,
|
||||
loss = F.cross_entropy(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
loss = F.cross_entropy(logits.view(-1, self.config.num_labels), labels.view(-1))
|
||||
outputs = (loss,) + outputs
|
||||
|
||||
return outputs
|
||||
|
||||
@@ -454,14 +454,12 @@ class CTRLLMHeadModel(CTRLPreTrainedModel):
|
||||
def get_output_embeddings(self):
|
||||
return self.lm_head
|
||||
|
||||
def prepare_inputs_for_generation(self, input_ids, **kwargs):
|
||||
def prepare_inputs_for_generation(self, input_ids, past, **kwargs):
|
||||
# only last token for inputs_ids if past is defined in kwargs
|
||||
if "past" in kwargs and kwargs["past"]:
|
||||
if past:
|
||||
input_ids = input_ids[:, -1].unsqueeze(-1)
|
||||
|
||||
inputs = {"input_ids": input_ids}
|
||||
inputs.update(kwargs)
|
||||
return inputs
|
||||
return {"input_ids": input_ids, "past": past}
|
||||
|
||||
@add_start_docstrings_to_callable(CTRL_INPUTS_DOCSTRING)
|
||||
def forward(
|
||||
|
||||
@@ -234,62 +234,3 @@ class PreTrainedEncoderDecoder(nn.Module):
|
||||
decoder_outputs = self.decoder(decoder_input_ids, **kwargs_decoder)
|
||||
|
||||
return decoder_outputs + encoder_outputs
|
||||
|
||||
|
||||
class Model2Model(PreTrainedEncoderDecoder):
|
||||
r"""
|
||||
:class:`~transformers.Model2Model` instantiates a Seq2Seq2 model
|
||||
where both of the encoder and decoder are of the same family. If the
|
||||
name of or that path to a pretrained model is specified the encoder and
|
||||
the decoder will be initialized with the pretrained weight (the
|
||||
cross-attention will be intialized randomly if its weights are not
|
||||
present).
|
||||
|
||||
It is possible to override this behavior and initialize, say, the decoder randomly
|
||||
by creating it beforehand as follows
|
||||
|
||||
config = BertConfig.from_pretrained()
|
||||
decoder = BertForMaskedLM(config)
|
||||
model = Model2Model.from_pretrained('bert-base-uncased', decoder_model=decoder)
|
||||
"""
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
self.tie_weights()
|
||||
|
||||
def tie_weights(self):
|
||||
""" Tying the encoder and decoders' embeddings together.
|
||||
|
||||
We need for each to get down to the embedding weights. However the
|
||||
different model classes are inconsistent to that respect:
|
||||
- BertModel: embeddings.word_embeddings
|
||||
- RoBERTa: embeddings.word_embeddings
|
||||
- XLMModel: embeddings
|
||||
- GPT2: wte
|
||||
- BertForMaskedLM: bert.embeddings.word_embeddings
|
||||
- RobertaForMaskedLM: roberta.embeddings.word_embeddings
|
||||
|
||||
argument of the XEmbedding layer for each model, but it is "blocked"
|
||||
by a model-specific keyword (bert, )...
|
||||
"""
|
||||
# self._tie_or_clone_weights(self.encoder, self.decoder)
|
||||
pass
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(cls, pretrained_model_name_or_path, *args, **kwargs):
|
||||
|
||||
if (
|
||||
"bert" not in pretrained_model_name_or_path
|
||||
or "roberta" in pretrained_model_name_or_path
|
||||
or "distilbert" in pretrained_model_name_or_path
|
||||
):
|
||||
raise ValueError("Only the Bert model is currently supported.")
|
||||
|
||||
model = super().from_pretrained(
|
||||
encoder_pretrained_model_name_or_path=pretrained_model_name_or_path,
|
||||
decoder_pretrained_model_name_or_path=pretrained_model_name_or_path,
|
||||
*args,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
return model
|
||||
|
||||
@@ -148,9 +148,12 @@ class FlaubertModel(XLMModel):
|
||||
|
||||
Examples::
|
||||
|
||||
from transformers import FlaubertTokenizer, FlaubertModel
|
||||
import torch
|
||||
|
||||
tokenizer = FlaubertTokenizer.from_pretrained('flaubert-base-cased')
|
||||
model = FlaubertModel.from_pretrained('flaubert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Le chat manges une pomme.", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
input_ids = torch.tensor(tokenizer.encode("Le chat mange une pomme.", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
|
||||
|
||||
@@ -276,14 +276,17 @@ GPT2_START_DOCSTRING = r"""
|
||||
|
||||
GPT2_INPUTS_DOCSTRING = r"""
|
||||
Args:
|
||||
input_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`):
|
||||
input_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, input_ids_length)`):
|
||||
`input_ids_length` = `sequence_length if `past` is None else 1
|
||||
Indices of input sequence tokens in the vocabulary.
|
||||
If using `past` as an input make sure that `input_ids` are those of the last position.
|
||||
|
||||
Indices can be obtained using :class:`transformers.GPT2Tokenizer`.
|
||||
See :func:`transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`transformers.PreTrainedTokenizer.encode_plus` for details.
|
||||
|
||||
`What are input IDs? <../glossary.html#input-ids>`__
|
||||
|
||||
past (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks) as computed by the model
|
||||
(see `past` output below). Can be used to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -294,10 +297,12 @@ GPT2_INPUTS_DOCSTRING = r"""
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
|
||||
`What are attention masks? <../glossary.html#attention-mask>`__
|
||||
token_type_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
token_type_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, input_ids_length)`, `optional`, defaults to :obj:`None`):
|
||||
`input_ids_length` = `sequence_length if `past` is None else 1
|
||||
Segment token indices to indicate first and second portions of the inputs.
|
||||
Indices are selected in ``[0, 1]``: ``0`` corresponds to a `sentence A` token, ``1``
|
||||
corresponds to a `sentence B` token
|
||||
If using `past` as an input make sure that `token_type_ids` correspond to the `input_ids` of the last position.
|
||||
|
||||
`What are token type IDs? <../glossary.html#token-type-ids>`_
|
||||
position_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
@@ -419,7 +424,8 @@ class GPT2Model(GPT2PreTrainedModel):
|
||||
|
||||
# Attention mask.
|
||||
if attention_mask is not None:
|
||||
attention_mask = attention_mask.view(-1, input_shape[-1])
|
||||
batch_size = input_ids.shape[0]
|
||||
attention_mask = attention_mask.view(batch_size, -1)
|
||||
# We create a 3D attention mask from a 2D tensor mask.
|
||||
# Sizes are [batch_size, 1, 1, to_seq_length]
|
||||
# So we can broadcast to [batch_size, num_heads, from_seq_length, to_seq_length]
|
||||
@@ -519,14 +525,12 @@ class GPT2LMHeadModel(GPT2PreTrainedModel):
|
||||
def get_output_embeddings(self):
|
||||
return self.lm_head
|
||||
|
||||
def prepare_inputs_for_generation(self, input_ids, **kwargs):
|
||||
def prepare_inputs_for_generation(self, input_ids, past, **kwargs):
|
||||
# only last token for inputs_ids if past is defined in kwargs
|
||||
if "past" in kwargs and kwargs["past"]:
|
||||
if past:
|
||||
input_ids = input_ids[:, -1].unsqueeze(-1)
|
||||
|
||||
inputs = {"input_ids": input_ids}
|
||||
inputs.update(kwargs)
|
||||
return inputs
|
||||
return {"input_ids": input_ids, "past": past}
|
||||
|
||||
@add_start_docstrings_to_callable(GPT2_INPUTS_DOCSTRING)
|
||||
def forward(
|
||||
|
||||
@@ -23,7 +23,7 @@ import tensorflow as tf
|
||||
from .configuration_albert import AlbertConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_tf_bert import ACT2FN, TFBertSelfAttention
|
||||
from .modeling_tf_utils import TFPreTrainedModel, get_initializer, shape_list
|
||||
from .modeling_tf_utils import TFPreTrainedModel, get_initializer, keras_serializable, shape_list
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -478,9 +478,12 @@ class TFAlbertMLMHead(tf.keras.layers.Layer):
|
||||
return hidden_states
|
||||
|
||||
|
||||
@keras_serializable
|
||||
class TFAlbertMainLayer(tf.keras.layers.Layer):
|
||||
config_class = AlbertConfig
|
||||
|
||||
def __init__(self, config, **kwargs):
|
||||
super().__init__(config, **kwargs)
|
||||
super().__init__(**kwargs)
|
||||
self.num_hidden_layers = config.num_hidden_layers
|
||||
|
||||
self.embeddings = TFAlbertEmbeddings(config, name="embeddings")
|
||||
|
||||
@@ -23,7 +23,7 @@ import tensorflow as tf
|
||||
|
||||
from .configuration_bert import BertConfig
|
||||
from .file_utils import MULTIPLE_CHOICE_DUMMY_INPUTS, add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_tf_utils import TFPreTrainedModel, get_initializer, shape_list
|
||||
from .modeling_tf_utils import TFPreTrainedModel, get_initializer, keras_serializable, shape_list
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -471,7 +471,10 @@ class TFBertNSPHead(tf.keras.layers.Layer):
|
||||
return seq_relationship_score
|
||||
|
||||
|
||||
@keras_serializable
|
||||
class TFBertMainLayer(tf.keras.layers.Layer):
|
||||
config_class = BertConfig
|
||||
|
||||
def __init__(self, config, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.num_hidden_layers = config.num_hidden_layers
|
||||
|
||||
@@ -23,7 +23,7 @@ import tensorflow as tf
|
||||
|
||||
from .configuration_ctrl import CTRLConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_tf_utils import TFPreTrainedModel, TFSharedEmbeddings, shape_list
|
||||
from .modeling_tf_utils import TFPreTrainedModel, TFSharedEmbeddings, keras_serializable, shape_list
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -104,10 +104,10 @@ class TFMultiHeadAttention(tf.keras.layers.Layer):
|
||||
k = self.split_into_heads(k, batch_size)
|
||||
v = self.split_into_heads(v, batch_size)
|
||||
if layer_past is not None:
|
||||
past_key, past_value = tf.unstack(layer_past, axis=1)
|
||||
k = tf.concat((past_key, k), dim=-2)
|
||||
v = tf.concat((past_value, v), dim=-2)
|
||||
present = tf.stack((k, v), axis=1)
|
||||
past_key, past_value = tf.unstack(layer_past, axis=0)
|
||||
k = tf.concat((past_key, k), axis=-2)
|
||||
v = tf.concat((past_value, v), axis=-2)
|
||||
present = tf.stack((k, v), axis=0)
|
||||
|
||||
output = scaled_dot_product_attention(q, k, v, mask, attention_mask, head_mask)
|
||||
scaled_attention = tf.transpose(output[0], perm=[0, 2, 1, 3])
|
||||
@@ -164,7 +164,10 @@ class TFEncoderLayer(tf.keras.layers.Layer):
|
||||
return outputs
|
||||
|
||||
|
||||
@keras_serializable
|
||||
class TFCTRLMainLayer(tf.keras.layers.Layer):
|
||||
config_class = CTRLConfig
|
||||
|
||||
def __init__(self, config, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.output_hidden_states = config.output_hidden_states
|
||||
@@ -505,6 +508,13 @@ class TFCTRLLMHeadModel(TFCTRLPreTrainedModel):
|
||||
def get_output_embeddings(self):
|
||||
return self.lm_head.input_embeddings
|
||||
|
||||
def prepare_inputs_for_generation(self, inputs, past, **kwargs):
|
||||
# only last token for inputs_ids if past is defined in kwargs
|
||||
if past:
|
||||
inputs = tf.expand_dims(inputs[:, -1], -1)
|
||||
|
||||
return {"inputs": inputs, "past": past}
|
||||
|
||||
@add_start_docstrings_to_callable(CTRL_INPUTS_DOCSTRING)
|
||||
def call(self, inputs, **kwargs):
|
||||
r"""
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user