Compare commits
2
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 sshleifer |
4c62bdc466 | ||
|
sshleifer
|
6e0680ace3 |
No files matched your search
@@ -27,10 +27,7 @@ jobs:
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[mecab,sklearn,tf-cpu,torch,testing]
|
||||
- run:
|
||||
command: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
no_output_timeout: 4h
|
||||
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
run_tests_torch:
|
||||
working_directory: ~/transformers
|
||||
docker:
|
||||
@@ -137,7 +134,7 @@ workflows:
|
||||
run_slow_tests:
|
||||
triggers:
|
||||
- schedule:
|
||||
cron: "0 4 * * *"
|
||||
cron: "0 4 * * 1"
|
||||
filters:
|
||||
branches:
|
||||
only:
|
||||
|
||||
+1
-2
@@ -25,5 +25,4 @@ deploy_doc "fc9faa8" v2.0.0
|
||||
deploy_doc "3ddce1d" v2.1.1
|
||||
deploy_doc "3616209" v2.2.0
|
||||
deploy_doc "d0f8b9a" v2.3.0
|
||||
deploy_doc "6664ea9" v2.4.0
|
||||
deploy_doc "fb560dc" v2.5.0
|
||||
deploy_doc "6664ea9" v2.4.0
|
||||
@@ -139,9 +139,3 @@ serialization_dir
|
||||
# emacs
|
||||
*.*~
|
||||
debug.env
|
||||
|
||||
# vim
|
||||
.*.swp
|
||||
|
||||
#ctags
|
||||
tags
|
||||
@@ -62,7 +62,7 @@ Choose the right framework for every part of a model's lifetime
|
||||
| [Quick tour: Share your models ](#Quick-tour-of-model-sharing) | Upload and share your fine-tuned models with the community |
|
||||
| [Migrating from pytorch-transformers to transformers](#Migrating-from-pytorch-transformers-to-transformers) | Migrating your code from pytorch-transformers to transformers |
|
||||
| [Migrating from pytorch-pretrained-bert to pytorch-transformers](#Migrating-from-pytorch-pretrained-bert-to-transformers) | Migrating your code from pytorch-pretrained-bert to transformers |
|
||||
| [Documentation][(v2.5.0)](https://huggingface.co/transformers/v2.5.0)[(v2.4.0/v2.4.1)](https://huggingface.co/transformers/v2.4.0)[(v2.3.0)](https://huggingface.co/transformers/v2.3.0)[(v2.2.0/v2.2.1/v2.2.2)](https://huggingface.co/transformers/v2.2.0) [(v2.1.1)](https://huggingface.co/transformers/v2.1.1) [(v2.0.0)](https://huggingface.co/transformers/v2.0.0) [(v1.2.0)](https://huggingface.co/transformers/v1.2.0) [(v1.1.0)](https://huggingface.co/transformers/v1.1.0) [(v1.0.0)](https://huggingface.co/transformers/v1.0.0) [(master)](https://huggingface.co/transformers) | Full API documentation and more |
|
||||
| [Documentation][(v2.4.0)](https://huggingface.co/transformers/v2.4.0)[(v2.3.0)](https://huggingface.co/transformers/v2.3.0)[(v2.2.0/v2.2.1/v2.2.2)](https://huggingface.co/transformers/v2.2.0) [(v2.1.1)](https://huggingface.co/transformers/v2.1.1) [(v2.0.0)](https://huggingface.co/transformers/v2.0.0) [(v1.2.0)](https://huggingface.co/transformers/v1.2.0) [(v1.1.0)](https://huggingface.co/transformers/v1.1.0) [(v1.0.0)](https://huggingface.co/transformers/v1.0.0) [(master)](https://huggingface.co/transformers) | Full API documentation and more |
|
||||
|
||||
## Installation
|
||||
|
||||
@@ -678,7 +678,7 @@ for batch in train_data:
|
||||
## Citation
|
||||
|
||||
We now have a paper you can cite for the 🤗 Transformers library:
|
||||
```bibtex
|
||||
```
|
||||
@article{Wolf2019HuggingFacesTS,
|
||||
title={HuggingFace's Transformers: State-of-the-art Natural Language Processing},
|
||||
author={Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and R'emi Louf and Morgan Funtowicz and Jamie Brew},
|
||||
|
||||
@@ -1,25 +1,3 @@
|
||||
/* Our DOM objects */
|
||||
|
||||
.framework-selector {
|
||||
display: flex;
|
||||
flex-direction: row;
|
||||
justify-content: flex-end;
|
||||
}
|
||||
|
||||
.framework-selector > button {
|
||||
background-color: white;
|
||||
color: #6670FF;
|
||||
border: 1px solid #6670FF;
|
||||
padding: 5px;
|
||||
}
|
||||
|
||||
.framework-selector > button.selected{
|
||||
background-color: #6670FF;
|
||||
color: white;
|
||||
border: 1px solid #6670FF;
|
||||
padding: 5px;
|
||||
}
|
||||
|
||||
/* The literal code blocks */
|
||||
.rst-content tt.literal, .rst-content tt.literal, .rst-content code.literal {
|
||||
color: #6670FF;
|
||||
|
||||
@@ -68,74 +68,6 @@ function addHfMenu() {
|
||||
document.body.insertAdjacentHTML('afterbegin', div);
|
||||
}
|
||||
|
||||
function platformToggle() {
|
||||
const codeBlocks = Array.from(document.getElementsByClassName("highlight"));
|
||||
const pytorchIdentifier = "## PYTORCH CODE";
|
||||
const tensorflowIdentifier = "## TENSORFLOW CODE";
|
||||
const pytorchSpanIdentifier = `<span class="c1">${pytorchIdentifier}</span>`;
|
||||
const tensorflowSpanIdentifier = `<span class="c1">${tensorflowIdentifier}</span>`;
|
||||
|
||||
const getFrameworkSpans = filteredCodeBlock => {
|
||||
const spans = filteredCodeBlock.element.innerHTML;
|
||||
const pytorchSpanPosition = spans.indexOf(pytorchSpanIdentifier);
|
||||
const tensorflowSpanPosition = spans.indexOf(tensorflowSpanIdentifier);
|
||||
|
||||
let pytorchSpans;
|
||||
let tensorflowSpans;
|
||||
|
||||
if(pytorchSpanPosition < tensorflowSpanPosition){
|
||||
pytorchSpans = spans.slice(pytorchSpanPosition + pytorchSpanIdentifier.length + 1, tensorflowSpanPosition);
|
||||
tensorflowSpans = spans.slice(tensorflowSpanPosition + tensorflowSpanIdentifier.length + 1, spans.length);
|
||||
}else{
|
||||
tensorflowSpans = spans.slice(tensorflowSpanPosition + tensorflowSpanIdentifier.length + 1, pytorchSpanPosition);
|
||||
pytorchSpans = spans.slice(pytorchSpanPosition + pytorchSpanIdentifier.length + 1, spans.length);
|
||||
}
|
||||
|
||||
return {
|
||||
...filteredCodeBlock,
|
||||
pytorchSample: pytorchSpans ,
|
||||
tensorflowSample: tensorflowSpans
|
||||
}
|
||||
};
|
||||
|
||||
const createFrameworkButtons = sample => {
|
||||
const pytorchButton = document.createElement("button");
|
||||
pytorchButton.innerText = "PyTorch";
|
||||
|
||||
const tensorflowButton = document.createElement("button");
|
||||
tensorflowButton.innerText = "TensorFlow";
|
||||
|
||||
const selectorDiv = document.createElement("div");
|
||||
selectorDiv.classList.add("framework-selector");
|
||||
selectorDiv.appendChild(pytorchButton);
|
||||
selectorDiv.appendChild(tensorflowButton);
|
||||
sample.element.parentElement.prepend(selectorDiv);
|
||||
|
||||
// Init on PyTorch
|
||||
sample.element.innerHTML = sample.pytorchSample;
|
||||
pytorchButton.classList.add("selected");
|
||||
tensorflowButton.classList.remove("selected");
|
||||
|
||||
pytorchButton.addEventListener("click", () => {
|
||||
sample.element.innerHTML = sample.pytorchSample;
|
||||
pytorchButton.classList.add("selected");
|
||||
tensorflowButton.classList.remove("selected");
|
||||
});
|
||||
tensorflowButton.addEventListener("click", () => {
|
||||
sample.element.innerHTML = sample.tensorflowSample;
|
||||
tensorflowButton.classList.add("selected");
|
||||
pytorchButton.classList.remove("selected");
|
||||
});
|
||||
};
|
||||
|
||||
codeBlocks
|
||||
.map(element => {return {element: element.firstChild, innerText: element.innerText}})
|
||||
.filter(codeBlock => codeBlock.innerText.includes(pytorchIdentifier) && codeBlock.innerText.includes(tensorflowIdentifier))
|
||||
.map(getFrameworkSpans)
|
||||
.forEach(createFrameworkButtons);
|
||||
}
|
||||
|
||||
|
||||
/*!
|
||||
* github-buttons v2.2.10
|
||||
* (c) 2019 なつき
|
||||
@@ -153,7 +85,6 @@ function onLoad() {
|
||||
addGithubButton();
|
||||
parseGithubButtons();
|
||||
addHfMenu();
|
||||
platformToggle();
|
||||
}
|
||||
|
||||
window.addEventListener("load", onLoad);
|
||||

@@ -1 +1,47 @@
|
||||
<svg clip-rule="evenodd" fill-rule="evenodd" stroke-linejoin="round" stroke-miterlimit="2" viewBox="0 0 127 118" xmlns="http://www.w3.org/2000/svg" xmlns:xlink="http://www.w3.org/1999/xlink"><clipPath id="a"><path clip-rule="nonzero" d="m62 75.052c13.105 0 17.333-11.684 17.333-17.684 0-3.118-2.096-2.136-5.453-.474-3.103 1.536-7.282 3.653-11.88 3.653-9.573 0-17.333-9.179-17.333-3.179s4.228 17.684 17.333 17.684z"/></clipPath><path d="m125.057 93.44c1 2.88.76 5.947-.573 8.613-.96 1.947-2.333 3.454-4.013 4.8-2.027 1.6-4.547 2.96-7.587 4.267-3.627 1.547-8.053 3-10.08 3.533-5.187 1.347-10.173 2.2-15.227 2.24-7.226.067-13.453-1.64-17.88-6-2.293.28-4.613.44-6.946.44-2.214 0-4.4-.133-6.574-.4-4.44 4.334-10.64 6.027-17.84 5.96-5.053-.04-10.04-.893-15.24-2.24-2.013-.533-6.44-1.986-10.066-3.533-3.04-1.307-5.56-2.667-7.574-4.267-1.693-1.346-3.066-2.853-4.026-4.8-1.32-2.666-1.574-5.733-.56-8.613-.934-2.2-1.174-4.72-.44-7.507.333-1.266.88-2.44 1.573-3.48-.147-.546-.267-1.106-.347-1.72-.506-3.653.76-6.986 3.147-9.573 1.173-1.293 2.44-2.187 3.76-2.76-.973-4.133-1.48-8.387-1.48-12.733 0-30.747 24.92-55.667 55.667-55.667 10.56 0 20.44 2.933 28.866 8.053 1.52.934 3.014 1.934 4.44 3 .707.534 1.414 1.08 2.094 1.654.693.56 1.373 1.146 2.026 1.746 1.974 1.8 3.827 3.734 5.52 5.8.574.68 1.12 1.387 1.654 2.107 1.08 1.427 2.08 2.907 3 4.44 1.4 2.293 2.626 4.693 3.693 7.187.707 1.666 1.32 3.373 1.867 5.12.813 2.613 1.44 5.306 1.866 8.08.134.92.254 1.853.347 2.786.187 1.867.293 3.76.293 5.694 0 4.293-.506 8.506-1.453 12.573 1.467.573 2.853 1.507 4.147 2.92 2.386 2.587 3.653 5.933 3.146 9.587-.08.6-.2 1.16-.346 1.706.693 1.04 1.24 2.214 1.573 3.48.733 2.787.493 5.307-.427 7.507" fill="#fff" fill-rule="nonzero"/><circle cx="62.333" cy="55.667" fill="#ffd21e" r="46.333"/><g fill-rule="nonzero"><path d="m108.667 55.667c0-25.59-20.744-46.334-46.334-46.334-25.589 0-46.333 20.744-46.333 46.334 0 25.589 20.744 46.333 46.333 46.333 25.59 0 46.334-20.744 46.334-46.333zm-98 0c0-28.535 23.132-51.667 51.666-51.667 28.535 0 51.667 23.132 51.667 51.667 0 28.534-23.132 51.666-51.667 51.666-28.534 0-51.666-23.132-51.666-51.666z" fill="#ffac03"/><path d="m77.387 43.055c1.7.6 2.376 4.093 4.092 3.181 3.251-1.729 4.485-5.765 2.757-9.016-1.729-3.251-5.765-4.485-9.016-2.757-3.251 1.729-4.485 5.765-2.757 9.016.816 1.535 3.406-.96 4.924-.424z" fill="#3a3b45"/><path d="m45.978 43.055c-1.699.6-2.375 4.093-4.092 3.181-3.251-1.729-4.485-5.765-2.756-9.016 1.728-3.251 5.765-4.485 9.016-2.757 3.251 1.729 4.485 5.765 2.756 9.016-.815 1.535-3.405-.96-4.924-.424z" fill="#3a3b45"/><path d="m62 75.052c13.105 0 17.333-11.684 17.333-17.684 0-3.118-2.096-2.136-5.453-.474-3.103 1.536-7.282 3.653-11.88 3.653-9.573 0-17.333-9.179-17.333-3.179s4.228 17.684 17.333 17.684z" fill="#3a3b45"/></g><g clip-path="url(#a)"><path d="m62.333 88.667c6.387 0 11.564-5.178 11.564-11.564 0-4.975-3.141-9.216-7.548-10.848-.162-.06-.326-.116-.491-.169-1.111-.355-2.296 3.464-3.525 3.464-1.148 0-2.257-3.844-3.305-3.532-4.776 1.422-8.259 5.847-8.259 11.085 0 6.386 5.178 11.564 11.564 11.564z" fill="#ef4e4e" fill-rule="nonzero"/></g><circle cx="93.667" cy="45" fill="#ffd21e" r="4.333"/><circle cx="31.667" cy="45" fill="#ffd21e" r="4.333"/><path d="m22.749 64c-2.158 0-4.088.887-5.433 2.495-.832.996-1.701 2.601-1.772 5.005-.905-.26-1.776-.405-2.589-.405-2.067 0-3.934.792-5.254 2.23-1.696 1.847-2.449 4.116-2.121 6.387.156 1.081.517 2.051 1.057 2.948-1.138.921-1.977 2.204-2.382 3.747-.318 1.209-.643 3.728 1.056 6.322-.108.17-.21.346-.304.526-1.022 1.938-1.087 4.129-.186 6.169 1.367 3.092 4.763 5.528 11.358 8.143 4.102 1.626 7.856 2.666 7.889 2.676 5.424 1.406 10.329 2.121 14.576 2.121 7.805 0 13.393-2.391 16.609-7.105 5.176-7.592 4.436-14.536-2.261-21.23-3.707-3.704-6.171-9.165-6.684-10.364-1.035-3.549-3.771-7.494-8.319-7.494h-.001c-.383 0-.769.03-1.151.09-1.992.314-3.733 1.46-4.977 3.186-1.343-1.67-2.647-2.998-3.827-3.747-1.778-1.128-3.556-1.7-5.284-1.7m0 5.333c.68 0 1.511.29 2.427.871 2.844 1.804 8.332 11.237 10.341 14.907.674 1.229 1.824 1.749 2.86 1.749 2.056 0 3.662-2.044.188-4.641-5.222-3.908-3.39-10.296-.897-10.69.109-.017.217-.025.321-.025 2.267 0 3.267 3.907 3.267 3.907s2.931 7.36 7.965 12.39c5.035 5.032 5.295 9.071 1.626 14.452-2.503 3.67-7.294 4.778-12.203 4.778-5.092 0-10.312-1.192-13.237-1.951-.144-.037-17.935-5.063-15.682-9.34.379-.719 1.003-1.007 1.788-1.007 3.174 0 8.946 4.723 11.427 4.723.555 0 .945-.236 1.105-.812 1.058-3.793-16.076-5.388-14.632-10.883.255-.972.946-1.366 1.916-1.365 4.194 0 13.602 7.375 15.574 7.375.15 0 .258-.044.317-.138.988-1.594.447-2.708-6.517-6.922-6.964-4.216-11.852-6.752-9.072-9.779.32-.349.773-.504 1.324-.504 4.228.001 14.217 9.092 14.217 9.092s2.696 2.804 4.327 2.804c.374 0 .693-.148.909-.513 1.156-1.95-10.737-10.963-11.408-14.682-.455-2.52.319-3.796 1.749-3.796" fill="#ffac03" fill-rule="nonzero"/><path d="m50.846 102.253c3.67-5.381 3.41-9.42-1.625-14.452-5.035-5.03-7.965-12.39-7.965-12.39s-1.095-4.275-3.588-3.882c-2.494.394-4.324 6.782.898 10.69 5.223 3.906-1Line truncated
|
||||
<svg width="95px" height="88px" viewBox="0 0 95 88" version="1.1" xmlns="http://www.w3.org/2000/svg" xmlns:xlink="http://www.w3.org/1999/xlink">
|
||||
<!-- Generator: Sketch 43.2 (39069) - http://www.bohemiancoding.com/sketch -->
|
||||
<title>icon</title>
|
||||
<desc>Created with Sketch.</desc>
|
||||
<defs>
|
||||
<path d="M13,14.7890193 C22.8284801,14.7890193 26,6.02605902 26,1.5261751 C26,-0.812484109 24.4279133,-0.0763570998 21.9099482,1.17020987 C19.5830216,2.32219957 16.4482998,3.91011313 13,3.91011313 C5.82029825,3.91011313 0,-2.97370882 0,1.5261751 C0,6.02605902 3.17151989,14.7890193 13,14.7890193 Z" id="path-1"></path>
|
||||
</defs>
|
||||
<g id="Page-1" stroke="none" stroke-width="1" fill="none" fill-rule="evenodd">
|
||||
<g id="icon_desktop">
|
||||
<g id="icon">
|
||||
<g id="icon_desktop">
|
||||
<g id="Group-2">
|
||||
<g id="Group">
|
||||
<path d="M93.7930402,70.08 C94.5430402,72.24 94.3630402,74.54 93.3630402,76.54 C92.6430402,78 91.6130402,79.13 90.3530402,80.14 C88.8330402,81.34 86.9430402,82.36 84.6630402,83.34 C81.9430402,84.5 78.6230402,85.59 77.1030402,85.99 C73.2130402,87 69.4730402,87.64 65.6830402,87.67 C60.2630402,87.72 55.5930402,86.44 52.2730402,83.17 C50.5530402,83.38 48.8130402,83.5 47.0630402,83.5 C45.4030402,83.5 43.7630402,83.4 42.1330402,83.2 C38.8030402,86.45 34.1530402,87.72 28.7530402,87.67 C24.9630402,87.64 21.2230402,87 17.3230402,85.99 C15.8130402,85.59 12.4930402,84.5 9.77304019,83.34 C7.49304019,82.36 5.60304019,81.34 4.09304019,80.14 C2.82304019,79.13 1.79304019,78 1.07304019,76.54 C0.0830401858,74.54 -0.106959814,72.24 0.653040186,70.08 C-0.0469598142,68.43 -0.226959814,66.54 0.323040186,64.45 C0.573040186,63.5 0.983040186,62.62 1.50304019,61.84 C1.39304019,61.43 1.30304019,61.01 1.24304019,60.55 C0.863040186,57.81 1.81304019,55.31 3.60304019,53.37 C4.48304019,52.4 5.43304019,51.73 6.42304019,51.3 C5.69304019,48.2 5.31304019,45.01 5.31304019,41.75 C5.31304019,18.69 24.0030402,0 47.0630402,0 C54.9830402,0 62.3930402,2.2 68.7130402,6.04 C69.8530402,6.74 70.9730402,7.49 72.0430402,8.29 C72.5730402,8.69 73.1030402,9.1 73.6130402,9.53 C74.1330402,9.95 74.6430402,10.39 75.1330402,10.84 C76.6130402,12.19 78.0030402,13.64 79.2730402,15.19 C79.7030402,15.7 80.1130402,16.23 80.5130402,16.77 C81.3230402,17.84 82.0730402,18.95 82.7630402,20.1 C83.8130402,21.82 84.7330402,23.62 85.5330402,25.49 C86.0630402,26.74 86.5230402,28.02 86.9330402,29.33 C87.5430402,31.29 88.0130402,33.31 88.3330402,35.39 C88.4330402,36.08 88.5230402,36.78 88.5930402,37.48 C88.7330402,38.88 88.8130402,40.3 88.8130402,41.75 C88.8130402,44.97 88.4330402,48.13 87.7230402,51.18 C88.8230402,51.61 89.8630402,52.31 90.8330402,53.37 C92.6230402,55.31 93.5730402,57.82 93.1930402,60.56 C93.1330402,61.01 93.0430402,61.43 92.9330402,61.84 C93.4530402,62.62 93.8630402,63.5 94.1130402,64.45 C94.6630402,66.54 94.4830402,68.43 93.7930402,70.08" id="Fill-1" fill="#FFFFFF" fill-rule="nonzero"></path>
|
||||
<circle id="Oval" fill="#FFD21E" fill-rule="nonzero" cx="46.75" cy="41.75" r="34.75"></circle>
|
||||
<path d="M81.5,41.75 C81.5,22.5581049 65.9418951,7 46.75,7 C27.5581049,7 12,22.5581049 12,41.75 C12,60.9418951 27.5581049,76.5 46.75,76.5 C65.9418951,76.5 81.5,60.9418951 81.5,41.75 Z M8,41.75 C8,20.3489659 25.3489659,3 46.75,3 C68.1510341,3 85.5,20.3489659 85.5,41.75 C85.5,63.1510341 68.1510341,80.5 46.75,80.5 C25.3489659,80.5 8,63.1510341 8,41.75 Z" id="Oval" fill="#FFAC03" fill-rule="nonzero"></path>
|
||||
<path d="M57.1723547,31.7151181 C58.0863134,32.7107502 57.3040427,35.2620959 58.7620957,35.2620959 C61.5235194,35.2620959 63.7620957,33.0235196 63.7620957,30.2620959 C63.7620957,27.5006721 61.5235194,25.2620959 58.7620957,25.2620959 C56.0006719,25.2620959 53.7620957,27.5006721 53.7620957,30.2620959 C53.7620957,31.5654666 56.3553563,30.8251108 57.1723547,31.7151181 Z" id="Oval-2" fill="#3A3B45" fill-rule="nonzero" transform="translate(58.762096, 30.262096) rotate(-28.000000) translate(-58.762096, -30.262096) "></path>
|
||||
<path d="M32.1723553,31.7151181 C33.086314,32.7107502 32.3040433,35.2620959 33.7620963,35.2620959 C36.52352,35.2620959 38.7620963,33.0235196 38.7620963,30.2620959 C38.7620963,27.5006721 36.52352,25.2620959 33.7620963,25.2620959 C31.0006725,25.2620959 28.7620963,27.5006721 28.7620963,30.2620959 C28.7620963,31.5654666 31.3553569,30.8251108 32.1723553,31.7151181 Z" id="Oval-2" fill="#3A3B45" fill-rule="nonzero" transform="translate(33.762096, 30.262096) scale(-1, 1) rotate(-28.000000) translate(-33.762096, -30.262096) "></path>
|
||||
<g id="Oval-4" transform="translate(33.500000, 41.500000)">
|
||||
<g id="Mask" fill-rule="nonzero" fill="#3A3B45">
|
||||
<path d="M13,14.7890193 C22.8284801,14.7890193 26,6.02605902 26,1.5261751 C26,-0.812484109 24.4279133,-0.0763570998 21.9099482,1.17020987 C19.5830216,2.32219957 16.4482998,3.91011313 13,3.91011313 C5.82029825,3.91011313 0,-2.97370882 0,1.5261751 C0,6.02605902 3.17151989,14.7890193 13,14.7890193 Z" id="path-1"></path>
|
||||
</g>
|
||||
<g id="Clipped">
|
||||
<mask id="mask-2" fill="white">
|
||||
<use xlink:href="#path-1"></use>
|
||||
</mask>
|
||||
<g id="path-1"></g>
|
||||
<path d="M13.25,25 C18.0399291,25 21.9229338,21.1169953 21.9229338,16.3270662 C21.9229338,12.5962324 19.5672252,9.41560375 16.2620987,8.19147116 C16.1404592,8.14641904 16.0175337,8.10401696 15.8933923,8.06433503 C15.0599892,7.79793679 14.1717882,10.6623144 13.25,10.6623144 C12.3886883,10.6623144 11.5567012,7.77968641 10.7713426,8.01349068 C7.18916268,9.07991937 4.57706621,12.3984489 4.57706621,16.3270662 C4.57706621,21.1169953 8.46007093,25 13.25,25 Z" id="Shape" fill="#EF4E4E" fill-rule="nonzero" mask="url(#mask-2)"></path>
|
||||
</g>
|
||||
</g>
|
||||
<circle id="Oval-3" fill="#FFD21E" fill-rule="nonzero" style="mix-blend-mode: multiply;" cx="70.25" cy="33.75" r="3.25"></circle>
|
||||
<circle id="Oval-3" fill="#FFD21E" fill-rule="nonzero" style="mix-blend-mode: multiply;" cx="23.75" cy="33.75" r="3.25"></circle>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
<g id="Group-4" transform="translate(3.000000, 48.000000)" fill-rule="nonzero">
|
||||
<path d="M14.0619453,0 L14.0619453,0 C12.4429453,0 10.9959453,0.665 9.98694534,1.871 C9.36294534,2.618 8.71094534,3.822 8.65794534,5.625 C7.97894534,5.43 7.32594534,5.321 6.71594534,5.321 C5.16594534,5.321 3.76594534,5.915 2.77594534,6.994 C1.50394534,8.379 0.938945345,10.081 1.18494534,11.784 C1.30194534,12.595 1.57294534,13.322 1.97794534,13.995 C1.12394534,14.686 0.494945345,15.648 0.190945345,16.805 C-0.0470546551,17.712 -0.291054655,19.601 0.982945345,21.547 C0.901945345,21.674 0.825945345,21.806 0.754945345,21.941 C-0.0110546551,23.395 -0.0600546551,25.038 0.615945345,26.568 C1.64094534,28.887 4.18794534,30.714 9.13394534,32.675 C12.2109453,33.895 15.0259453,34.675 15.0509453,34.682 C19.1189453,35.737 22.7979453,36.273 25.9829453,36.273 C31.8369453,36.273 36.0279453,34.48 38.4399453,30.944 C42.3219453,25.25 41.7669453,20.042 36.7439453,15.022 C33.9639453,12.244 32.1159453,8.148 31.7309453,7.249 C30.9549453,4.587 28.9029453,1.628 25.4919453,1.628 L25.4909453,1.628 C25.2039453,1.628 24.9139453,1.651 24.6279453,1.696 C23.1339453,1.931 21.8279453,2.791 20.8949453,4.085 C19.8879453,2.833 18.9099453,1.837 18.0249453,1.275 C16.6909453,0.429 15.3579453,0 14.0619453,0 M14.0619453,4 C14.5719453,4 15.1949453,4.217 15.8819453,4.653 C18.0149453,6.006 22.1309453,13.081 23.6379453,15.833 C24.1429453,16.755 25.0059453,17.145 25.7829453,17.145 C27.3249453,17.145 28.5289453,15.612 25.9239453,13.664 C22.0069453,10.733 23.3809453,5.942 25.2509453,5.647 C25.3329453,5.634 25.4139453,5.628 25.4919453,5.628 C27.1919453,5.628 27.9419453,8.558 27.9419453,8.558 C27.9419453,8.558 30.1399453,14.078 33.9159453,17.851 C37.6919453,21.625 37.8869453,24.654 35.1349453,28.69 C33.2579453,31.442 29.6649453,32.273 25.9829453,32.273 C22.1639453,32.273 18.2489453,31.379 16.0549453,30.81 C15.9469453,30.782 2.60394534,27.013 4.29394534,23.805 C4.57794534,23.266 5.04594534,23.05 5.63494534,23.05 C8.01494534,23.05 12.3439453,26.592 14.2049453,26.592 C14.6209453,26.592 14.9139453,26.415 15.0339453,25.983 C15.8269453,23.138 2.97694534,21.942 4.05994534,17.821 C4.25094534,17.092 4.76894534,16.796 5.49694534,16.797 C8.64194534,16.797 15.6979453,22.328 17.1769453,22.328 C17.2899453,22.328 17.3709453,22.295 17.4149453,22.225 C18.1559453,21.029 17.7499453,20.194 12.5269453,17.033 C7.30394534,13.871 3.63794534,11.969 5.72294534,9.699 C5.96294534,9.437 6.30294534,9.321 6.71594534,9.321 C9.88694534,9.322 17.3789453,16.14 17.3789453,16.14 C17.3789453,16.14 19.4009453,18.243 20.6239453,18.243 C20.9049453,18.243 21.1439453,18.132 21.3059453,17.858 C22.1729453,16.396 13.2529453,9.636 12.7499453,6.847 C12.4089453,4.957 12.9889453,4 14.0619453,4" id="Fill-1" fill="#FFAC03"></path>
|
||||
<path d="M35.1348,28.6899 C37.8868,24.6539 37.6918,21.6249 33.9158,17.8509 C30.1398,14.0779 27.9418,8.5579 27.9418,8.5579 C27.9418,8.5579 27.1208,5.3519 25.2508,5.6469 C23.3808,5.9419 22.0078,10.7329 25.9248,13.6639 C29.8418,16.5939 25.1448,18.5849 23.6378,15.8329 C22.1308,13.0809 18.0158,6.0059 15.8818,4.6529 C13.7488,3.2999 12.2468,4.0579 12.7498,6.8469 C13.2528,9.6359 22.1738,16.3959 21.3058,17.8589 C20.4378,19.3209 17.3788,16.1399 17.3788,16.1399 C17.3788,16.1399 7.8068,7.4289 5.7228,9.6989 C3.6388,11.9689 7.3038,13.8709 12.5268,17.0329 C17.7508,20.1939 18.1558,21.0289 17.4148,22.2249 C16.6728,23.4209 5.1428,13.6999 4.0598,17.8209 C2.9778,21.9419 15.8268,23.1379 15.0338,25.9829 C14.2408,28.8289 5.9828,20.5979 4.2938,23.8049 C2.6038,27.0129 15.9468,30.7819 16.0548,30.8099 C20.3648,31.9279 31.3108,34.2969 35.1348,28.6899" id="Fill-4" fill="#FFD21E"></path>
|
||||
</g>
|
||||
<g id="Group-4" transform="translate(70.500000, 66.500000) scale(-1, 1) translate(-70.500000, -66.500000) translate(50.000000, 48.000000)" fill-rule="nonzero">
|
||||
<path d="M14.0619453,0 L14.0619453,0 C12.4429453,0 10.9959453,0.665 9.98694534,1.871 C9.36294534,2.618 8.71094534,3.822 8.65794534,5.625 C7.97894534,5.43 7.32594534,5.321 6.71594534,5.321 C5.16594534,5.321 3.76594534,5.915 2.77594534,6.994 C1.50394534,8.379 0.938945345,10.081 1.18494534,11.784 C1.30194534,12.595 1.57294534,13.322 1.97794534,13.995 C1.12394534,14.686 0.494945345,15.648 0.190945345,16.805 C-0.0470546551,17.712 -0.291054655,19.601 0.982945345,21.547 C0.901945345,21.674 0.825945345,21.806 0.754945345,21.941 C-0.0110546551,23.395 -0.0600546551,25.038 0.615945345,26.568 C1.64094534,28.887 4.18794534,30.714 9.13394534,32.675 C12.2109453,33.895 15.0259453,34.675 15.0509453,34.682 C19.1189453,35.737 22.7979453,36.273 25.9829453,36.273 C31.8369453,36.273 36.0279453,34.48 38.4399453,30.944 C42.3219453,25.25 41.7669453,20.042 36.7439453,15.022 C33.9639453,12.244 32.1159453,8.148 31.7309453,7.249 C30.9549453,4.587 28.9029453,1.628 25.4919453,1.628 L25.4909453,1.628 C25.2039453,1.628 24.9139453,1.651 24.6279453,1.696 C23.1339453,1.931 21.8279453,2.791 20.8949453,4.085 C19.8879453,2.833 18.9099453,1.837 18.0249453,1.275 C16.6909453,0.429 15.3579453,0 14.0619453,0 M14.0619453,4 C14.5719453,4 15.1949453,4.217 15.8819453,4.653 C18.0149453,6.006 22.1309453,13.081 23.6379453,15.833 C24.1429453,16.755 25.0059453,17.145 25.7829453,17.145 C27.3249453,17.145 28.5289453,15.612 25.9239453,13.664 C22.0069453,10.733 23.3809453,5.942 25.2509453,5.647 C25.3329453,5.634 25.4139453,5.628 25.4919453,5.628 C27.1919453,5.628 27.9419453,8.558 27.9419453,8.558 C27.9419453,8.558 30.1399453,14.078 33.9159453,17.851 C37.6919453,21.625 37.8869453,24.654 35.1349453,28.69 C33.2579453,31.442 29.6649453,32.273 25.9829453,32.273 C22.1639453,32.273 18.2489453,31.379 16.0549453,30.81 C15.9469453,30.782 2.60394534,27.013 4.29394534,23.805 C4.57794534,23.266 5.04594534,23.05 5.63494534,23.05 C8.01494534,23.05 12.3439453,26.592 14.2049453,26.592 C14.6209453,26.592 14.9139453,26.415 15.0339453,25.983 C15.8269453,23.138 2.97694534,21.942 4.05994534,17.821 C4.25094534,17.092 4.76894534,16.796 5.49694534,16.797 C8.64194534,16.797 15.6979453,22.328 17.1769453,22.328 C17.2899453,22.328 17.3709453,22.295 17.4149453,22.225 C18.1559453,21.029 17.7499453,20.194 12.5269453,17.033 C7.30394534,13.871 3.63794534,11.969 5.72294534,9.699 C5.96294534,9.437 6.30294534,9.321 6.71594534,9.321 C9.88694534,9.322 17.3789453,16.14 17.3789453,16.14 C17.3789453,16.14 19.4009453,18.243 20.6239453,18.243 C20.9049453,18.243 21.1439453,18.132 21.3059453,17.858 C22.1729453,16.396 13.2529453,9.636 12.7499453,6.847 C12.4089453,4.957 12.9889453,4 14.0619453,4" id="Fill-1" fill="#FFAC03"></path>
|
||||
<path d="M35.1348,28.6899 C37.8868,24.6539 37.6918,21.6249 33.9158,17.8509 C30.1398,14.0779 27.9418,8.5579 27.9418,8.5579 C27.9418,8.5579 27.1208,5.3519 25.2508,5.6469 C23.3808,5.9419 22.0078,10.7329 25.9248,13.6639 C29.8418,16.5939 25.1448,18.5849 23.6378,15.8329 C22.1308,13.0809 18.0158,6.0059 15.8818,4.6529 C13.7488,3.2999 12.2468,4.0579 12.7498,6.8469 C13.2528,9.6359 22.1738,16.3959 21.3058,17.8589 C20.4378,19.3209 17.3788,16.1399 17.3788,16.1399 C17.3788,16.1399 7.8068,7.4289 5.7228,9.6989 C3.6388,11.9689 7.3038,13.8709 12.5268,17.0329 C17.7508,20.1939 18.1558,21.0289 17.4148,22.2249 C16.6728,23.4209 5.1428,13.6999 4.0598,17.8209 C2.9778,21.9419 15.8268,23.1379 15.0338,25.9829 C14.2408,28.8289 5.9828,20.5979 4.2938,23.8049 C2.6038,27.0129 15.9468,30.7819 16.0548,30.8099 C20.3648,31.9279 31.3108,34.2969 35.1348,28.6899" id="Fill-4" fill="#FFD21E"></path>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
</g>
|
||||
</svg>
|
||||
|
Before Width: | Height: | Size: 7.6 KiB After Width: | Height: | Size: 14 KiB |
+2
-8
@@ -20,13 +20,13 @@ sys.path.insert(0, os.path.abspath('../../src'))
|
||||
# -- Project information -----------------------------------------------------
|
||||
|
||||
project = u'transformers'
|
||||
copyright = u'2020, huggingface'
|
||||
copyright = u'2019, huggingface'
|
||||
author = u'huggingface'
|
||||
|
||||
# The short X.Y version
|
||||
version = u''
|
||||
# The full version, including alpha/beta/rc tags
|
||||
release = u'2.5.1'
|
||||
release = u'2.4.1'
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
@@ -105,12 +105,6 @@ html_static_path = ['_static']
|
||||
#
|
||||
# html_sidebars = {}
|
||||
|
||||
# This must be the name of an image file (path relative to the configuration
|
||||
# directory) that is the favicon of the docs. Modern browsers use this as
|
||||
# the icon for tabs, windows and bookmarks. It should be a Windows-style
|
||||
# icon file (.ico).
|
||||
html_favicon = 'favicon.ico'
|
||||
|
||||
|
||||
# -- Options for HTMLHelp output ---------------------------------------------
|
||||
|
||||
|
||||
Binary file not shown.
|
Before Width: | Height: | Size: 47 KiB |
@@ -61,7 +61,6 @@ The library currently contains PyTorch and Tensorflow implementations, pre-train
|
||||
quickstart
|
||||
glossary
|
||||
pretrained_models
|
||||
usage
|
||||
model_sharing
|
||||
examples
|
||||
notebooks
|
||||
@@ -100,5 +99,4 @@ The library currently contains PyTorch and Tensorflow implementations, pre-train
|
||||
model_doc/camembert
|
||||
model_doc/albert
|
||||
model_doc/xlmroberta
|
||||
model_doc/flaubert
|
||||
model_doc/bart
|
||||
model_doc/flaubert
|
||||
@@ -41,8 +41,7 @@ AlbertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.AlbertTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
AlbertModel
|
||||
|
||||
@@ -1,52 +0,0 @@
|
||||
Bart
|
||||
----------------------------------------------------
|
||||
**DISCLAIMER:** This model is still a work in progress, if you see something strange,
|
||||
file a `Github Issue <https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title>`__ and assign
|
||||
@sshleifer
|
||||
|
||||
The Bart model was `proposed <https://arxiv.org/abs/1910.13461>`_ by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov, Luke Zettlemoyer on 29 Oct, 2019.
|
||||
It is a sequence to sequence model where both encoder and decoder are transformers. The paper also introduces a novel pretraining objective, and demonstrates excellent summarization results.
|
||||
The authors released their code `here <https://github.com/pytorch/fairseq/tree/master/examples/bart>`_
|
||||
|
||||
**Abstract:**
|
||||
|
||||
*We present BART, a denoising autoencoder for pretraining sequence-to-sequence models. BART is trained by (1) corrupting text with an arbitrary noising function, and (2) learning a model to reconstruct the original text. It uses a standard Tranformer-based neural machine translation architecture which, despite its simplicity, can be seen as generalizing BERT (due to the bidirectional encoder), GPT (with the left-to-right decoder), and many other more recent pretraining schemes. We evaluate a number of noising approaches, finding the best performance by both randomly shuffling the order of the original sentences and using a novel in-filling scheme, where spans of text are replaced with a single mask token. BART is particularly effective when fine tuned for text generation but also works well for comprehension tasks. It matches the performance of RoBERTa with comparable training resources on GLUE and SQuAD, achieves new state-of-the-art results on a range of abstractive dialogue, question answering, and summarization tasks, with gains of up to 6 ROUGE. BART also provides a 1.1 BLEU increase over a back-translation system for machine translation, with only target language pretraining. We also report ablation experiments that replicate other pretraining schemes within the BART framework, to better measure which factors most influence end-task performance.*
|
||||
`BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension`
|
||||
|
||||
|
||||
Notes:
|
||||
- Bart doesn't use :obj:`token_type_ids`, for sequence classification just use BartTokenizer.encode to get the proper splitting.
|
||||
- Inputs to the decoder are created by BartModel.forward if they are not passed. This is different than some other model APIs.
|
||||
- Model predictions are intended to be identical to the original implementation. This only works, however, if the string you pass to fairseq.encode starts with a space.
|
||||
|
||||
BartModel
|
||||
~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartModel
|
||||
:members: forward
|
||||
|
||||
|
||||
BartForMaskedLM
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartForMaskedLM
|
||||
:members: forward
|
||||
|
||||
|
||||
BartForSequenceClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartForSequenceClassification
|
||||
:members: forward
|
||||
|
||||
BartConfig
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BartConfig
|
||||
:members:
|
||||
|
||||
Automatic Creation of Decoder Inputs
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
This is enabled by default
|
||||
|
||||
.. autofunction:: transformers.modeling_bart._prepare_bart_decoder_inputs
|
||||
@@ -46,8 +46,7 @@ BertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.BertTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
BertModel
|
||||
|
||||
@@ -33,8 +33,7 @@ CamembertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.CamembertTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
CamembertModel
|
||||
|
||||
@@ -43,7 +43,7 @@ CTRLTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.CTRLTokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
CTRLModel
|
||||
|
||||
@@ -47,7 +47,7 @@ OpenAIGPTTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.OpenAIGPTTokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
OpenAIGPTModel
|
||||
|
||||
@@ -5,7 +5,7 @@ Overview
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
OpenAI GPT-2 model was proposed in
|
||||
`Language Models are Unsupervised Multitask Learners <https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf>`_
|
||||
`Language Models are Unsupervised Multitask Learners`_
|
||||
by Alec Radford*, Jeffrey Wu*, Rewon Child, David Luan, Dario Amodei** and Ilya Sutskever**.
|
||||
It's a causal (unidirectional) transformer pre-trained using language modeling on a very large
|
||||
corpus of ~40 GB of text data.
|
||||
@@ -46,7 +46,7 @@ GPT2Tokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.GPT2Tokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
GPT2Model
|
||||
|
||||
@@ -39,8 +39,7 @@ RobertaTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.RobertaTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
RobertaModel
|
||||
|
||||
@@ -42,7 +42,7 @@ TransfoXLTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TransfoXLTokenizer
|
||||
:members: save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
TransfoXLModel
|
||||
|
||||
@@ -41,8 +41,7 @@ XLMTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.XLMTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
XLMModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
@@ -39,8 +39,7 @@ XLMRobertaTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.XLMRobertaTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
XLMRobertaModel
|
||||
|
||||
@@ -44,8 +44,7 @@ XLNetTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.XLNetTokenizer
|
||||
:members: build_inputs_with_special_tokens, get_special_tokens_mask,
|
||||
create_token_type_ids_from_sequences, save_vocabulary
|
||||
:members:
|
||||
|
||||
|
||||
XLNetModel
|
||||
|
||||
@@ -275,13 +275,6 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | | | FlauBERT large architecture |
|
||||
| | | (see `details <https://github.com/getalp/Flaubert>`__) |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| Bart | ``bart-large`` | | 12-layer, 1024-hidden, 16-heads, 406M parameters |
|
||||
| | | (see `details <https://github.com/pytorch/fairseq/tree/master/examples/bart>`_) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``bart-large-mnli`` | | Adds a 2 layer classification head with 1 million parameters |
|
||||
| | | | bart-large base architecture with a classification head |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
|
||||
|
||||
.. <https://huggingface.co/transformers/examples.html>`__
|
||||
@@ -1,597 +0,0 @@
|
||||
Usage
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
This page shows the most frequent use-cases when using the library. The models available allow for many different
|
||||
configurations and a great versatility in use-cases. The most simple ones are presented here, showcasing usage
|
||||
for tasks such as question answering, sequence classification, named entity recognition and others.
|
||||
|
||||
These examples leverage auto-models, which are classes that will instantiate a model according to a given checkpoint,
|
||||
automatically selecting the correct model architecture. Please check the :class:`~transformers.AutoModel` documentation
|
||||
for more information.
|
||||
Feel free to modify the code to be more specific and adapt it to your specific use-case.
|
||||
|
||||
In order for a model to perform well on a task, it must be loaded from a checkpoint corresponding to that task. These
|
||||
checkpoints are usually pre-trained on a large corpus of data and fine-tuned on a specific task. This means the
|
||||
following:
|
||||
|
||||
- Not all models were fine-tuned on all tasks. If you want to fine-tune a model on a specific task, you can leverage
|
||||
one of the `run_$TASK.py` script in the
|
||||
`examples <https://github.com/huggingface/transformers/tree/master/examples>`_ directory.
|
||||
- Fine-tuned models were fine-tuned on a specific dataset. This dataset may or may not overlap with your use-case
|
||||
and domain. As mentioned previously, you may leverage the
|
||||
`examples <https://github.com/huggingface/transformers/tree/master/examples>`_ scripts to fine-tune your model, or you
|
||||
may create your own training script.
|
||||
|
||||
In order to do an inference on a task, several mechanisms are made available by the library:
|
||||
|
||||
- Pipelines: very easy-to-use abstractions, which require as little as two lines of code.
|
||||
- Using a model directly with a tokenizer (PyTorch/TensorFlow): the full inference using the model. Less abstraction,
|
||||
but much more powerful.
|
||||
|
||||
Both approaches are showcased here.
|
||||
|
||||
.. note::
|
||||
|
||||
All tasks presented here leverage pre-trained checkpoints that were fine-tuned on specific tasks. Loading a
|
||||
checkpoint that was not fine-tuned on a specific task would load only the base transformer layers and not the
|
||||
additional head that is used for the task, initializing the weights of that head randomly.
|
||||
|
||||
This would produce random output.
|
||||
|
||||
Sequence Classification
|
||||
--------------------------
|
||||
|
||||
Sequence classification is the task of classifying sequences according to a given number of classes. An example
|
||||
of sequence classification is the GLUE dataset, which is entirely based on that task. If you would like to fine-tune
|
||||
a model on a GLUE sequence classification task, you may leverage the
|
||||
`run_glue.py <https://github.com/huggingface/transformers/tree/master/examples/run_glue.py>`_ or
|
||||
`run_tf_glue.py <https://github.com/huggingface/transformers/tree/master/examples/run_tf_glue.py>`_ scripts.
|
||||
|
||||
Here is an example using the pipelines do to sentiment analysis: identifying if a sequence is positive or negative.
|
||||
It leverages a fine-tuned model on sst2, which is a GLUE task.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("sentiment-analysis")
|
||||
|
||||
print(nlp("I hate you"))
|
||||
print(nlp("I love you"))
|
||||
|
||||
This returns a label ("POSITIVE" or "NEGATIVE") alongside a score, as follows:
|
||||
|
||||
::
|
||||
|
||||
[{'label': 'NEGATIVE', 'score': 0.9991129}]
|
||||
[{'label': 'POSITIVE', 'score': 0.99986565}]
|
||||
|
||||
|
||||
Here is an example of doing a sequence classification using a model to determine if two sequences are paraphrases
|
||||
of each other. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a BERT model and loads it
|
||||
with the weights stored in the checkpoint.
|
||||
- Build a sequence from the two sentences, with the correct model-specific separators token type ids
|
||||
and attention masks (:func:`~transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`~transformers.PreTrainedTokenizer.encode_plus` take care of this)
|
||||
- Pass this sequence through the model so that it is classified in one of the two available classes: 0
|
||||
(not a paraphrase) and 1 (is a paraphrase)
|
||||
- Compute the softmax of the result to get probabilities over the classes
|
||||
- Print the results
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoTokenizer, AutoModelForSequenceClassification
|
||||
import torch
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
model = AutoModelForSequenceClassification.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
|
||||
classes = ["not paraphrase", "is paraphrase"]
|
||||
|
||||
sequence_0 = "The company HuggingFace is based in New York City"
|
||||
sequence_1 = "Apples are especially bad for your health"
|
||||
sequence_2 = "HuggingFace's headquarters are situated in Manhattan"
|
||||
|
||||
paraphrase = tokenizer.encode_plus(sequence_0, sequence_2, return_tensors="pt")
|
||||
not_paraphrase = tokenizer.encode_plus(sequence_0, sequence_1, return_tensors="pt")
|
||||
|
||||
paraphrase_classification_logits = model(**paraphrase)[0]
|
||||
not_paraphrase_classification_logits = model(**not_paraphrase)[0]
|
||||
|
||||
paraphrase_results = torch.softmax(paraphrase_classification_logits, dim=1).tolist()[0]
|
||||
not_paraphrase_results = torch.softmax(not_paraphrase_classification_logits, dim=1).tolist()[0]
|
||||
|
||||
print("Should be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(paraphrase_results[i] * 100)}%")
|
||||
|
||||
print("\nShould not be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(not_paraphrase_results[i] * 100)}%")
|
||||
## TENSORFLOW CODE
|
||||
from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
model = TFAutoModelForSequenceClassification.from_pretrained("bert-base-cased-finetuned-mrpc")
|
||||
|
||||
classes = ["not paraphrase", "is paraphrase"]
|
||||
|
||||
sequence_0 = "The company HuggingFace is based in New York City"
|
||||
sequence_1 = "Apples are especially bad for your health"
|
||||
sequence_2 = "HuggingFace's headquarters are situated in Manhattan"
|
||||
|
||||
paraphrase = tokenizer.encode_plus(sequence_0, sequence_2, return_tensors="tf")
|
||||
not_paraphrase = tokenizer.encode_plus(sequence_0, sequence_1, return_tensors="tf")
|
||||
|
||||
paraphrase_classification_logits = model(paraphrase)[0]
|
||||
not_paraphrase_classification_logits = model(not_paraphrase)[0]
|
||||
|
||||
paraphrase_results = tf.nn.softmax(paraphrase_classification_logits, axis=1).numpy()[0]
|
||||
not_paraphrase_results = tf.nn.softmax(not_paraphrase_classification_logits, axis=1).numpy()[0]
|
||||
|
||||
print("Should be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(paraphrase_results[i] * 100)}%")
|
||||
|
||||
print("\nShould not be paraphrase")
|
||||
for i in range(len(classes)):
|
||||
print(f"{classes[i]}: {round(not_paraphrase_results[i] * 100)}%")
|
||||
|
||||
This outputs the following results:
|
||||
|
||||
::
|
||||
|
||||
Should be paraphrase
|
||||
not paraphrase: 10%
|
||||
is paraphrase: 90%
|
||||
|
||||
Should not be paraphrase
|
||||
not paraphrase: 94%
|
||||
is paraphrase: 6%
|
||||
|
||||
Extractive Question Answering
|
||||
----------------------------------------------------
|
||||
|
||||
Extractive Question Answering is the task of extracting an answer from a text given a question. An example of a
|
||||
question answering dataset is the SQuAD dataset, which is entirely based on that task. If you would like to fine-tune
|
||||
a model on a SQuAD task, you may leverage the `run_squad.py`.
|
||||
|
||||
Here is an example using the pipelines do to question answering: extracting an answer from a text given a question.
|
||||
It leverages a fine-tuned model on SQuAD.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("question-answering")
|
||||
|
||||
context = r"""
|
||||
Extractive Question Answering is the task of extracting an answer from a text given a question. An example of a
|
||||
question answering dataset is the SQuAD dataset, which is entirely based on that task. If you would like to fine-tune
|
||||
a model on a SQuAD task, you may leverage the `run_squad.py`.
|
||||
"""
|
||||
|
||||
print(nlp(question="What is extractive question answering?", context=context))
|
||||
print(nlp(question="What is a good example of a question answering dataset?", context=context))
|
||||
|
||||
This returns an answer extracted from the text, a confidence score, alongside "start" and "end" values which
|
||||
are the positions of the extracted answer in the text.
|
||||
|
||||
::
|
||||
|
||||
{'score': 0.622232091629833, 'start': 34, 'end': 96, 'answer': 'the task of extracting an answer from a text given a question.'}
|
||||
{'score': 0.5115299158662765, 'start': 147, 'end': 161, 'answer': 'SQuAD dataset,'}
|
||||
|
||||
|
||||
Here is an example of question answering using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a BERT model and loads it
|
||||
with the weights stored in the checkpoint.
|
||||
- Define a text and a few questions.
|
||||
- Iterate over the questions and build a sequence from the text and the current question, with the correct
|
||||
model-specific separators token type ids and attention masks
|
||||
- Pass this sequence through the model. This outputs a range of scores across the entire sequence tokens (question and
|
||||
text), for both the start and end positions.
|
||||
- Compute the softmax of the result to get probabilities over the tokens
|
||||
- Fetch the tokens from the identified start and stop values, convert those tokens to a string.
|
||||
- Print the results
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoTokenizer, AutoModelForQuestionAnswering
|
||||
import torch
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
model = AutoModelForQuestionAnswering.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
|
||||
text = r"""
|
||||
🤗 Transformers (formerly known as pytorch-transformers and pytorch-pretrained-bert) provides general-purpose
|
||||
architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet…) for Natural Language Understanding (NLU) and Natural
|
||||
Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between
|
||||
TensorFlow 2.0 and PyTorch.
|
||||
"""
|
||||
|
||||
questions = [
|
||||
"How many pretrained models are available in Transformers?",
|
||||
"What does Transformers provide?",
|
||||
"Transformers provides interoperability between which frameworks?",
|
||||
]
|
||||
|
||||
for question in questions:
|
||||
inputs = tokenizer.encode_plus(question, text, add_special_tokens=True, return_tensors="pt")
|
||||
input_ids = inputs["input_ids"].tolist()[0]
|
||||
|
||||
text_tokens = tokenizer.convert_ids_to_tokens(input_ids)
|
||||
answer_start_scores, answer_end_scores = model(**inputs)
|
||||
|
||||
answer_start = torch.argmax(
|
||||
answer_start_scores
|
||||
) # Get the most likely beginning of answer with the argmax of the score
|
||||
answer_end = torch.argmax(answer_end_scores) + 1 # Get the most likely end of answer with the argmax of the score
|
||||
|
||||
answer = tokenizer.convert_tokens_to_string(tokenizer.convert_ids_to_tokens(input_ids[answer_start:answer_end]))
|
||||
|
||||
print(f"Question: {question}")
|
||||
print(f"Answer: {answer}\n")
|
||||
## TENSORFLOW CODE
|
||||
from transformers import AutoTokenizer, TFAutoModelForQuestionAnswering
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
model = TFAutoModelForQuestionAnswering.from_pretrained("bert-large-uncased-whole-word-masking-finetuned-squad")
|
||||
|
||||
text = r"""
|
||||
🤗 Transformers (formerly known as pytorch-transformers and pytorch-pretrained-bert) provides general-purpose
|
||||
architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet…) for Natural Language Understanding (NLU) and Natural
|
||||
Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between
|
||||
TensorFlow 2.0 and PyTorch.
|
||||
"""
|
||||
|
||||
questions = [
|
||||
"How many pretrained models are available in Transformers?",
|
||||
"What does Transformers provide?",
|
||||
"Transformers provides interoperability between which frameworks?",
|
||||
]
|
||||
|
||||
for question in questions:
|
||||
inputs = tokenizer.encode_plus(question, text, add_special_tokens=True, return_tensors="tf")
|
||||
input_ids = inputs["input_ids"].numpy()[0]
|
||||
|
||||
text_tokens = tokenizer.convert_ids_to_tokens(input_ids)
|
||||
answer_start_scores, answer_end_scores = model(inputs)
|
||||
|
||||
answer_start = tf.argmax(
|
||||
answer_start_scores, axis=1
|
||||
).numpy()[0] # Get the most likely beginning of answer with the argmax of the score
|
||||
answer_end = (
|
||||
tf.argmax(answer_end_scores, axis=1) + 1
|
||||
).numpy()[0] # Get the most likely end of answer with the argmax of the score
|
||||
answer = tokenizer.convert_tokens_to_string(tokenizer.convert_ids_to_tokens(input_ids[answer_start:answer_end]))
|
||||
|
||||
print(f"Question: {question}")
|
||||
print(f"Answer: {answer}\n")
|
||||
|
||||
This outputs the questions followed by the predicted answers:
|
||||
|
||||
::
|
||||
|
||||
Question: How many pretrained models are available in Transformers?
|
||||
Answer: over 32 +
|
||||
|
||||
Question: What does Transformers provide?
|
||||
Answer: general - purpose architectures
|
||||
|
||||
Question: Transformers provides interoperability between which frameworks?
|
||||
Answer: tensorflow 2 . 0 and pytorch
|
||||
|
||||
|
||||
|
||||
Language Modeling
|
||||
----------------------------------------------------
|
||||
|
||||
Language modeling is the task of fitting a model to a corpus, which can be domain specific. All popular transformer
|
||||
based models are trained using a variant of language modeling, e.g. BERT with masked language modeling, GPT-2 with
|
||||
causal language modeling.
|
||||
|
||||
Language modeling can be useful outside of pre-training as well, for example to shift the model distribution to be
|
||||
domain-specific: using a language model trained over a very large corpus, and then fine-tuning it to a news dataset
|
||||
or on scientific papers e.g. `LysandreJik/arxiv-nlp <https://huggingface.co/lysandre/arxiv-nlp>`__.
|
||||
|
||||
Masked Language Modeling
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Masked language modeling is the task of masking tokens in a sequence with a masking token, and prompting the model to
|
||||
fill that mask with an appropriate token. This allows the model to attend to both the right context (tokens on the
|
||||
right of the mask) and the left context (tokens on the left of the mask). Such a training creates a strong basis
|
||||
for downstream tasks requiring bi-directional context such as SQuAD (question answering,
|
||||
see `Lewis, Lui, Goyal et al. <https://arxiv.org/abs/1910.13461>`__, part 4.2).
|
||||
|
||||
Here is an example of using pipelines to replace a mask from a sequence:
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("fill-mask")
|
||||
print(nlp(f"HuggingFace is creating a {nlp.tokenizer.mask_token} that the community uses to solve NLP tasks."))
|
||||
|
||||
This outputs the sequences with the mask filled, the confidence score as well as the token id in the tokenizer
|
||||
vocabulary:
|
||||
|
||||
::
|
||||
|
||||
[
|
||||
{'sequence': '<s> HuggingFace is creating a tool that the community uses to solve NLP tasks.</s>', 'score': 0.15627853572368622, 'token': 3944},
|
||||
{'sequence': '<s> HuggingFace is creating a framework that the community uses to solve NLP tasks.</s>', 'score': 0.11690319329500198, 'token': 7208},
|
||||
{'sequence': '<s> HuggingFace is creating a library that the community uses to solve NLP tasks.</s>', 'score': 0.058063216507434845, 'token': 5560},
|
||||
{'sequence': '<s> HuggingFace is creating a database that the community uses to solve NLP tasks.</s>', 'score': 0.04211743175983429, 'token': 8503},
|
||||
{'sequence': '<s> HuggingFace is creating a prototype that the community uses to solve NLP tasks.</s>', 'score': 0.024718601256608963, 'token': 17715}
|
||||
]
|
||||
|
||||
Here is an example doing masked language modeling using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a DistilBERT model and
|
||||
loads it with the weights stored in the checkpoint.
|
||||
- Define a sequence with a masked token, placing the :obj:`tokenizer.mask_token` instead of a word.
|
||||
- Encode that sequence into IDs and find the position of the masked token in that list of IDs.
|
||||
- Retrieve the predictions at the index of the mask token: this tensor has the same size as the vocabulary, and the
|
||||
values are the scores attributed to each token. The model gives higher score to tokens he deems probable in that
|
||||
context.
|
||||
- Retrieve the top 5 tokens using the PyTorch :obj:`topk` or TensorFlow :obj:`top_k` methods.
|
||||
- Replace the mask token by the tokens and print the results
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
import torch
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("distilbert-base-cased")
|
||||
model = AutoModelWithLMHead.from_pretrained("distilbert-base-cased")
|
||||
|
||||
sequence = f"Distilled models are smaller than the models they mimic. Using them instead of the large versions would help {tokenizer.mask_token} our carbon footprint."
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="pt")
|
||||
mask_token_index = torch.where(input == tokenizer.mask_token_id)[1]
|
||||
|
||||
token_logits = model(input)[0]
|
||||
mask_token_logits = token_logits[0, mask_token_index, :]
|
||||
|
||||
top_5_tokens = torch.topk(mask_token_logits, 5, dim=1).indices[0].tolist()
|
||||
|
||||
for token in top_5_tokens:
|
||||
print(sequence.replace(tokenizer.mask_token, tokenizer.decode([token])))
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelWithLMHead, AutoTokenizer
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("distilbert-base-cased")
|
||||
model = TFAutoModelWithLMHead.from_pretrained("distilbert-base-cased")
|
||||
|
||||
sequence = f"Distilled models are smaller than the models they mimic. Using them instead of the large versions would help {tokenizer.mask_token} our carbon footprint."
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="tf")
|
||||
mask_token_index = tf.where(input == tokenizer.mask_token_id)[0, 1]
|
||||
|
||||
token_logits = model(input)[0]
|
||||
mask_token_logits = token_logits[0, mask_token_index, :]
|
||||
|
||||
top_5_tokens = tf.math.top_k(mask_token_logits, 5).indices.numpy()
|
||||
|
||||
for token in top_5_tokens:
|
||||
print(sequence.replace(tokenizer.mask_token, tokenizer.decode([token])))
|
||||
|
||||
This prints five sequences, with the top 5 tokens predicted by the model:
|
||||
|
||||
::
|
||||
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help reduce our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help increase our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help decrease our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help offset our carbon footprint.
|
||||
Distilled models are smaller than the models they mimic. Using them instead of the large versions would help improve our carbon footprint.
|
||||
|
||||
|
||||
Causal Language Modeling
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Causal language modeling is the task of predicting the token following a sequence of tokens. In this situation, the
|
||||
model only attends to the left context (tokens on the left of the mask). Such a training is particularly interesting
|
||||
for generation tasks.
|
||||
|
||||
There is currently no pipeline to do causal language modeling/generation.
|
||||
|
||||
Here is an example using the tokenizer and model. leveraging the :func:`~transformers.PreTrainedModel.generate` method
|
||||
to generate the tokens following the initial sequence in PyTorch, and creating a simple loop in TensorFlow.
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("gpt2")
|
||||
model = AutoModelWithLMHead.from_pretrained("gpt2")
|
||||
|
||||
sequence = f"Hugging Face is based in DUMBO, New York City, and is"
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="pt")
|
||||
generated = model.generate(input, max_length=50)
|
||||
|
||||
resulting_string = tokenizer.decode(generated.tolist()[0])
|
||||
print(resulting_string)
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelWithLMHead, AutoTokenizer
|
||||
import tensorflow as tf
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("gpt2")
|
||||
model = TFAutoModelWithLMHead.from_pretrained("gpt2")
|
||||
|
||||
sequence = f"Hugging Face is based in DUMBO, New York City, and is"
|
||||
generated = tokenizer.encode(sequence)
|
||||
|
||||
for i in range(50):
|
||||
predictions = model(tf.constant([generated]))[0]
|
||||
token = tf.argmax(predictions[0], axis=1)[-1].numpy()
|
||||
generated += [token]
|
||||
|
||||
resulting_string = tokenizer.decode(generated)
|
||||
print(resulting_string)
|
||||
|
||||
|
||||
This outputs a (hopefully) coherent string from the original sequence, as the
|
||||
:func:`~transformers.PreTrainedModel.generate` samples from a top_p/tok_k distribution:
|
||||
|
||||
::
|
||||
|
||||
Hugging Face is based in DUMBO, New York City, and is a live-action TV series based on the novel by John
|
||||
Carpenter, and its producers, David Kustlin and Steve Pichar. The film is directed by!
|
||||
|
||||
|
||||
Named Entity Recognition
|
||||
----------------------------------------------------
|
||||
|
||||
Named Entity Recognition (NER) is the task of classifying tokens according to a class, for example identifying a
|
||||
token as a person, an organisation or a location.
|
||||
An example of a named entity recognition dataset is the CoNLL-2003 dataset, which is entirely based on that task.
|
||||
If you would like to fine-tune a model on an NER task, you may leverage the `ner/run_ner.py` (PyTorch),
|
||||
`ner/run_pl_ner.py` (leveraging pytorch-lightning) or the `ner/run_tf_ner.py` (TensorFlow) scripts.
|
||||
|
||||
Here is an example using the pipelines do to named entity recognition, trying to identify tokens as belonging to one
|
||||
of 9 classes:
|
||||
|
||||
- O, Outside of a named entity
|
||||
- B-MIS, Beginning of a miscellaneous entity right after another miscellaneous entity
|
||||
- I-MIS, Miscellaneous entity
|
||||
- B-PER, Beginning of a person's name right after another person's name
|
||||
- I-PER, Person's name
|
||||
- B-ORG, Beginning of an organisation right after another organisation
|
||||
- I-ORG, Organisation
|
||||
- B-LOC, Beginning of a location right after another location
|
||||
- I-LOC, Location
|
||||
|
||||
It leverages a fine-tuned model on CoNLL-2003, fine-tuned by `@stefan-it <https://github.com/stefan-it>`__ from
|
||||
`dbmdz <https://github.com/dbmdz>`__.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline("ner")
|
||||
|
||||
sequence = "Hugging Face Inc. is a company based in New York City. Its headquarters are in DUMBO, therefore very" \
|
||||
"close to the Manhattan Bridge which is visible from the window."
|
||||
|
||||
print(nlp(sequence))
|
||||
|
||||
This outputs a list of all words that have been identified as an entity from the 9 classes defined above. Here is the
|
||||
expected results:
|
||||
|
||||
::
|
||||
|
||||
[
|
||||
{'word': 'Hu', 'score': 0.9995632767677307, 'entity': 'I-ORG'},
|
||||
{'word': '##gging', 'score': 0.9915938973426819, 'entity': 'I-ORG'},
|
||||
{'word': 'Face', 'score': 0.9982671737670898, 'entity': 'I-ORG'},
|
||||
{'word': 'Inc', 'score': 0.9994403719902039, 'entity': 'I-ORG'},
|
||||
{'word': 'New', 'score': 0.9994346499443054, 'entity': 'I-LOC'},
|
||||
{'word': 'York', 'score': 0.9993270635604858, 'entity': 'I-LOC'},
|
||||
{'word': 'City', 'score': 0.9993864893913269, 'entity': 'I-LOC'},
|
||||
{'word': 'D', 'score': 0.9825621843338013, 'entity': 'I-LOC'},
|
||||
{'word': '##UM', 'score': 0.936983048915863, 'entity': 'I-LOC'},
|
||||
{'word': '##BO', 'score': 0.8987102508544922, 'entity': 'I-LOC'},
|
||||
{'word': 'Manhattan', 'score': 0.9758241176605225, 'entity': 'I-LOC'},
|
||||
{'word': 'Bridge', 'score': 0.990249514579773, 'entity': 'I-LOC'}
|
||||
]
|
||||
|
||||
Note how the words "Hugging Face" have been identified as an organisation, and "New York City", "DUMBO" and
|
||||
"Manhattan Bridge" have been identified as locations.
|
||||
|
||||
Here is an example doing named entity recognition using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. The model is identified as a BERT model and
|
||||
loads it with the weights stored in the checkpoint.
|
||||
- Define the label list with which the model was trained on.
|
||||
- Define a sequence with known entities, such as "Hugging Face" as an organisation and "New York City" as a location.
|
||||
- Split words into tokens so that they can be mapped to the predictions. We use a small hack by firstly completely
|
||||
encoding and decoding the sequence, so that we're left with a string that contains the special tokens.
|
||||
- Encode that sequence into IDs (special tokens are added automatically).
|
||||
- Retrieve the predictions by passing the input to the model and getting the first output. This results in a
|
||||
distribution over the 9 possible classes for each token. We take the argmax to retrieve the most likely class
|
||||
for each token.
|
||||
- Zip together each token with its prediction and print it.
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelForTokenClassification, AutoTokenizer
|
||||
import torch
|
||||
|
||||
model = AutoModelForTokenClassification.from_pretrained("dbmdz/bert-large-cased-finetuned-conll03-english")
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
|
||||
|
||||
label_list = [
|
||||
"O", # Outside of a named entity
|
||||
"B-MISC", # Beginning of a miscellaneous entity right after another miscellaneous entity
|
||||
"I-MISC", # Miscellaneous entity
|
||||
"B-PER", # Beginning of a person's name right after another person's name
|
||||
"I-PER", # Person's name
|
||||
"B-ORG", # Beginning of an organisation right after another organisation
|
||||
"I-ORG", # Organisation
|
||||
"B-LOC", # Beginning of a location right after another location
|
||||
"I-LOC" # Location
|
||||
]
|
||||
|
||||
sequence = "Hugging Face Inc. is a company based in New York City. Its headquarters are in DUMBO, therefore very" \
|
||||
"close to the Manhattan Bridge."
|
||||
|
||||
# Bit of a hack to get the tokens with the special tokens
|
||||
tokens = tokenizer.tokenize(tokenizer.decode(tokenizer.encode(sequence)))
|
||||
inputs = tokenizer.encode(sequence, return_tensors="pt")
|
||||
|
||||
outputs = model(inputs)[0]
|
||||
predictions = torch.argmax(outputs, dim=2)
|
||||
|
||||
print([(token, label_list[prediction]) for token, prediction in zip(tokens, predictions[0].tolist())])
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelForTokenClassification, AutoTokenizer
|
||||
import tensorflow as tf
|
||||
|
||||
model = TFAutoModelForTokenClassification.from_pretrained("dbmdz/bert-large-cased-finetuned-conll03-english")
|
||||
tokenizer = AutoTokenizer.from_pretrained("bert-base-cased")
|
||||
|
||||
label_list = [
|
||||
"O", # Outside of a named entity
|
||||
"B-MISC", # Beginning of a miscellaneous entity right after another miscellaneous entity
|
||||
"I-MISC", # Miscellaneous entity
|
||||
"B-PER", # Beginning of a person's name right after another person's name
|
||||
"I-PER", # Person's name
|
||||
"B-ORG", # Beginning of an organisation right after another organisation
|
||||
"I-ORG", # Organisation
|
||||
"B-LOC", # Beginning of a location right after another location
|
||||
"I-LOC" # Location
|
||||
]
|
||||
|
||||
sequence = "Hugging Face Inc. is a company based in New York City. Its headquarters are in DUMBO, therefore very" \
|
||||
"close to the Manhattan Bridge."
|
||||
|
||||
# Bit of a hack to get the tokens with the special tokens
|
||||
tokens = tokenizer.tokenize(tokenizer.decode(tokenizer.encode(sequence)))
|
||||
inputs = tokenizer.encode(sequence, return_tensors="tf")
|
||||
|
||||
outputs = model(inputs)[0]
|
||||
predictions = tf.argmax(outputs, axis=2)
|
||||
|
||||
print([(token, label_list[prediction]) for token, prediction in zip(tokens, predictions[0].numpy())])
|
||||
|
||||
This outputs a list of each token mapped to their prediction. Differently from the pipeline, here every token has
|
||||
a prediction as we didn't remove the "0" class which means that no particular entity was found on that token. The
|
||||
following array should be the output:
|
||||
|
||||
::
|
||||
|
||||
[('[CLS]', 'O'), ('Hu', 'I-ORG'), ('##gging', 'I-ORG'), ('Face', 'I-ORG'), ('Inc', 'I-ORG'), ('.', 'O'), ('is', 'O'), ('a', 'O'), ('company', 'O'), ('based', 'O'), ('in', 'O'), ('New', 'I-LOC'), ('York', 'I-LOC'), ('City', 'I-LOC'), ('.', 'O'), ('Its', 'O'), ('headquarters', 'O'), ('are', 'O'), ('in', 'O'), ('D', 'I-LOC'), ('##UM', 'I-LOC'), ('##BO', 'I-LOC'), (',', 'O'), ('therefore', 'O'), ('very', 'O'), ('##c', 'O'), ('##lose', 'O'), ('to', 'O'), ('the', 'O'), ('Manhattan', 'I-LOC'), ('Bridge', 'I-LOC'), ('.', 'O'), ('[SEP]', 'O')]
|
||||
+202
-23
@@ -3,7 +3,7 @@
|
||||
In this section a few examples are put together. All of these examples work for several models, making use of the very
|
||||
similar API between the different models.
|
||||
|
||||
**Important**
|
||||
**Important**
|
||||
To run the latest versions of the examples, you have to install from source and install some specific requirements for the examples.
|
||||
Execute the following steps in a new virtual environment:
|
||||
|
||||
@@ -15,14 +15,14 @@ pip install -r ./examples/requirements.txt
|
||||
```
|
||||
|
||||
| Section | Description |
|
||||
|----------------------------|------------------------------------------------------------------------------------------------------------------------------------------
|
||||
| [TensorFlow 2.0 models on GLUE](#TensorFlow-2.0-Bert-models-on-GLUE) | Examples running BERT TensorFlow 2.0 model on the GLUE tasks. |
|
||||
|----------------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| [TensorFlow 2.0 models on GLUE](#TensorFlow-2.0-Bert-models-on-GLUE) | Examples running BERT TensorFlow 2.0 model on the GLUE tasks.
|
||||
| [Language Model training](#language-model-training) | Fine-tuning (or training from scratch) the library models for language modeling on a text dataset. Causal language modeling for GPT/GPT-2, masked language modeling for BERT/RoBERTa. |
|
||||
| [Language Generation](#language-generation) | Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, Transformer-XL and XLNet. |
|
||||
| [GLUE](#glue) | Examples running BERT/XLM/XLNet/RoBERTa on the 9 GLUE tasks. Examples feature distributed training as well as half-precision. |
|
||||
| [SQuAD](#squad) | Using BERT/RoBERTa/XLNet/XLM for question answering, examples with distributed training. |
|
||||
| [Multiple Choice](#multiple-choice) | Examples running BERT/XLNet/RoBERTa on the SWAG/RACE/ARC tasks. |
|
||||
| [Named Entity Recognition](https://github.com/huggingface/transformers/tree/master/examples/ner) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [Named Entity Recognition](#named-entity-recognition) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [XNLI](#xnli) | Examples running BERT/XLM on the XNLI benchmark. |
|
||||
| [Adversarial evaluation of model performances](#adversarial-evaluation-of-model-performances) | Testing a model with adversarial evaluation of natural language inference on the Heuristic Analysis for NLI Systems (HANS) dataset (McCoy et al., 2019.) |
|
||||
|
||||
@@ -88,7 +88,7 @@ a score of ~20 perplexity once fine-tuned on the dataset.
|
||||
|
||||
The following example fine-tunes RoBERTa on WikiText-2. Here too, we're using the raw WikiText-2. The loss is different
|
||||
as BERT/RoBERTa have a bidirectional mechanism; we're therefore using the same loss that was used during their
|
||||
pre-training: masked language modeling.
|
||||
pre-training: masked language modeling.
|
||||
|
||||
In accordance to the RoBERTa paper, we use dynamic masking rather than static masking. The model may, therefore, converge
|
||||
slightly slower (over-fitting takes more epochs).
|
||||
@@ -130,8 +130,8 @@ python run_generation.py \
|
||||
|
||||
Based on the script [`run_glue.py`](https://github.com/huggingface/transformers/blob/master/examples/run_glue.py).
|
||||
|
||||
Fine-tuning the library models for sequence classification on the GLUE benchmark: [General Language Understanding
|
||||
Evaluation](https://gluebenchmark.com/). This script can fine-tune the following models: BERT, XLM, XLNet and RoBERTa.
|
||||
Fine-tuning the library models for sequence classification on the GLUE benchmark: [General Language Understanding
|
||||
Evaluation](https://gluebenchmark.com/). This script can fine-tune the following models: BERT, XLM, XLNet and RoBERTa.
|
||||
|
||||
GLUE is made up of a total of 9 different tasks. We get the following results on the dev set of the benchmark with an
|
||||
uncased BERT base model (the checkpoint `bert-base-uncased`). All experiments ran single V100 GPUs with a total train
|
||||
@@ -179,20 +179,20 @@ python run_glue.py \
|
||||
|
||||
where task name can be one of CoLA, SST-2, MRPC, STS-B, QQP, MNLI, QNLI, RTE, WNLI.
|
||||
|
||||
The dev set results will be present within the text file `eval_results.txt` in the specified output_dir.
|
||||
In case of MNLI, since there are two separate dev sets (matched and mismatched), there will be a separate
|
||||
The dev set results will be present within the text file `eval_results.txt` in the specified output_dir.
|
||||
In case of MNLI, since there are two separate dev sets (matched and mismatched), there will be a separate
|
||||
output folder called `/tmp/MNLI-MM/` in addition to `/tmp/MNLI/`.
|
||||
|
||||
The code has not been tested with half-precision training with apex on any GLUE task apart from MRPC, MNLI,
|
||||
CoLA, SST-2. The following section provides details on how to run half-precision training with MRPC. With that being
|
||||
said, there shouldn’t be any issues in running half-precision training with the remaining GLUE tasks as well,
|
||||
since the data processor for each task inherits from the base class DataProcessor.
|
||||
|
||||
### MRPC
|
||||
|
||||
#### Fine-tuning example
|
||||
|
||||
The following examples fine-tune BERT on the Microsoft Research Paraphrase Corpus (MRPC) corpus and runs in less
|
||||
The following examples fine-tune BERT on the Microsoft Research Paraphrase Corpus (MRPC) corpus and runs in less
|
||||
than 10 minutes on a single K-80 and in 27 seconds (!) on single tesla V100 16GB with apex installed.
|
||||
|
||||
Before running any one of these GLUE tasks you should download the
|
||||
@@ -219,12 +219,12 @@ python run_glue.py \
|
||||
```
|
||||
|
||||
Our test ran on a few seeds with [the original implementation hyper-
|
||||
parameters](https://github.com/google-research/bert#sentence-and-sentence-pair-classification-tasks) gave evaluation
|
||||
parameters](https://github.com/google-research/bert#sentence-and-sentence-pair-classification-tasks) gave evaluation
|
||||
results between 84% and 88%.
|
||||
|
||||
#### Using Apex and mixed-precision
|
||||
|
||||
Using Apex and 16 bit precision, the fine-tuning on MRPC only takes 27 seconds. First install
|
||||
Using Apex and 16 bit precision, the fine-tuning on MRPC only takes 27 seconds. First install
|
||||
[apex](https://github.com/NVIDIA/apex), then run the following example:
|
||||
|
||||
```bash
|
||||
@@ -360,8 +360,8 @@ Based on the script [`run_squad.py`](https://github.com/huggingface/transformers
|
||||
|
||||
#### Fine-tuning BERT on SQuAD1.0
|
||||
|
||||
This example code fine-tunes BERT on the SQuAD1.0 dataset. It runs in 24 min (with BERT-base) or 68 min (with BERT-large)
|
||||
on a single tesla V100 16GB. The data for SQuAD can be downloaded with the following links and should be saved in a
|
||||
This example code fine-tunes BERT on the SQuAD1.0 dataset. It runs in 24 min (with BERT-base) or 68 min (with BERT-large)
|
||||
on a single tesla V100 16GB. The data for SQuAD can be downloaded with the following links and should be saved in a
|
||||
$SQUAD_DIR directory.
|
||||
|
||||
* [train-v1.1.json](https://rajpurkar.github.io/SQuAD-explorer/dataset/train-v1.1.json)
|
||||
@@ -442,14 +442,14 @@ This example code fine-tunes XLNet on both SQuAD1.0 and SQuAD2.0 dataset. See ab
|
||||
```bash
|
||||
export SQUAD_DIR=/path/to/SQUAD
|
||||
|
||||
python run_squad.py \
|
||||
python /data/home/hlu/transformers/examples/run_squad.py \
|
||||
--model_type xlnet \
|
||||
--model_name_or_path xlnet-large-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file $SQUAD_DIR/train-v1.1.json \
|
||||
--predict_file $SQUAD_DIR/dev-v1.1.json \
|
||||
--train_file /data/home/hlu/notebooks/NLP/examples/question_answering/train-v1.1.json \
|
||||
--predict_file /data/home/hlu/notebooks/NLP/examples/question_answering/dev-v1.1.json \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
@@ -516,6 +516,185 @@ Larger batch size may improve the performance while costing more memory.
|
||||
|
||||
|
||||
|
||||
## Named Entity Recognition
|
||||
|
||||
Based on the scripts [`run_ner.py`](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py) for Pytorch and
|
||||
[`run_tf_ner.py`](https://github.com/huggingface/transformers/blob/master/examples/run_tf_ner.py) for Tensorflow 2.
|
||||
This example fine-tune Bert Multilingual on GermEval 2014 (German NER).
|
||||
Details and results for the fine-tuning provided by @stefan-it.
|
||||
|
||||
### Data (Download and pre-processing steps)
|
||||
|
||||
Data can be obtained from the [GermEval 2014](https://sites.google.com/site/germeval2014ner/data) shared task page.
|
||||
|
||||
Here are the commands for downloading and pre-processing train, dev and test datasets. The original data format has four (tab-separated) columns, in a pre-processing step only the two relevant columns (token and outer span NER annotation) are extracted:
|
||||
|
||||
```bash
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-train.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-dev.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-test.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
|
||||
```
|
||||
|
||||
The GermEval 2014 dataset contains some strange "control character" tokens like `'\x96', '\u200e', '\x95', '\xad' or '\x80'`. One problem with these tokens is, that `BertTokenizer` returns an empty token for them, resulting in misaligned `InputExample`s. I wrote a script that a) filters these tokens and b) splits longer sentences into smaller ones (once the max. subtoken length is reached).
|
||||
|
||||
```bash
|
||||
wget "https://raw.githubusercontent.com/stefan-it/fine-tuned-berts-seq/master/scripts/preprocess.py"
|
||||
```
|
||||
Let's define some variables that we need for further pre-processing steps and training the model:
|
||||
|
||||
```bash
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
```
|
||||
|
||||
Run the pre-processing script on training, dev and test datasets:
|
||||
|
||||
```bash
|
||||
python3 preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
|
||||
python3 preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
|
||||
python3 preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
|
||||
```
|
||||
|
||||
The GermEval 2014 dataset has much more labels than CoNLL-2002/2003 datasets, so an own set of labels must be used:
|
||||
|
||||
```bash
|
||||
cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
|
||||
```
|
||||
|
||||
### Prepare the run
|
||||
|
||||
Additional environment variables must be set:
|
||||
|
||||
```bash
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
```
|
||||
|
||||
### Run the Pytorch version
|
||||
|
||||
To start training, just run:
|
||||
|
||||
```bash
|
||||
python3 run_ner.py --data_dir ./ \
|
||||
--model_type bert \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_gpu_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
```
|
||||
|
||||
If your GPU supports half-precision training, just add the `--fp16` flag. After training, the model will be both evaluated on development and test datasets.
|
||||
|
||||
#### Evaluation
|
||||
|
||||
Evaluation on development dataset outputs the following for our example:
|
||||
|
||||
```bash
|
||||
10/04/2019 00:42:06 - INFO - __main__ - ***** Eval results *****
|
||||
10/04/2019 00:42:06 - INFO - __main__ - f1 = 0.8623348017621146
|
||||
10/04/2019 00:42:06 - INFO - __main__ - loss = 0.07183869666975543
|
||||
10/04/2019 00:42:06 - INFO - __main__ - precision = 0.8467916366258111
|
||||
10/04/2019 00:42:06 - INFO - __main__ - recall = 0.8784592370979806
|
||||
```
|
||||
|
||||
On the test dataset the following results could be achieved:
|
||||
|
||||
```bash
|
||||
10/04/2019 00:42:42 - INFO - __main__ - ***** Eval results *****
|
||||
10/04/2019 00:42:42 - INFO - __main__ - f1 = 0.8614389652384803
|
||||
10/04/2019 00:42:42 - INFO - __main__ - loss = 0.07064602487454782
|
||||
10/04/2019 00:42:42 - INFO - __main__ - precision = 0.8604651162790697
|
||||
10/04/2019 00:42:42 - INFO - __main__ - recall = 0.8624150210424085
|
||||
```
|
||||
|
||||
#### Comparing BERT (large, cased), RoBERTa (large, cased) and DistilBERT (base, uncased)
|
||||
|
||||
Here is a small comparison between BERT (large, cased), RoBERTa (large, cased) and DistilBERT (base, uncased) with the same hyperparameters as specified in the [example documentation](https://huggingface.co/transformers/examples.html#named-entity-recognition) (one run):
|
||||
|
||||
| Model | F-Score Dev | F-Score Test
|
||||
| --------------------------------- | ------- | --------
|
||||
| `bert-large-cased` | 95.59 | 91.70
|
||||
| `roberta-large` | 95.96 | 91.87
|
||||
| `distilbert-base-uncased` | 94.34 | 90.32
|
||||
|
||||
### Run the Tensorflow 2 version
|
||||
|
||||
To start training, just run:
|
||||
|
||||
```bash
|
||||
python3 run_tf_ner.py --data_dir ./ \
|
||||
--model_type bert \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_device_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
```
|
||||
|
||||
Such as the Pytorch version, if your GPU supports half-precision training, just add the `--fp16` flag. After training, the model will be both evaluated on development and test datasets.
|
||||
|
||||
#### Evaluation
|
||||
|
||||
Evaluation on development dataset outputs the following for our example:
|
||||
```bash
|
||||
precision recall f1-score support
|
||||
|
||||
LOCderiv 0.7619 0.6154 0.6809 52
|
||||
PERpart 0.8724 0.8997 0.8858 4057
|
||||
OTHpart 0.9360 0.9466 0.9413 711
|
||||
ORGpart 0.7015 0.6989 0.7002 269
|
||||
LOCpart 0.7668 0.8488 0.8057 496
|
||||
LOC 0.8745 0.9191 0.8963 235
|
||||
ORGderiv 0.7723 0.8571 0.8125 91
|
||||
OTHderiv 0.4800 0.6667 0.5581 18
|
||||
OTH 0.5789 0.6875 0.6286 16
|
||||
PERderiv 0.5385 0.3889 0.4516 18
|
||||
PER 0.5000 0.5000 0.5000 2
|
||||
ORG 0.0000 0.0000 0.0000 3
|
||||
|
||||
micro avg 0.8574 0.8862 0.8715 5968
|
||||
macro avg 0.8575 0.8862 0.8713 5968
|
||||
```
|
||||
|
||||
On the test dataset the following results could be achieved:
|
||||
```bash
|
||||
precision recall f1-score support
|
||||
|
||||
PERpart 0.8847 0.8944 0.8896 9397
|
||||
OTHpart 0.9376 0.9353 0.9365 1639
|
||||
ORGpart 0.7307 0.7044 0.7173 697
|
||||
LOC 0.9133 0.9394 0.9262 561
|
||||
LOCpart 0.8058 0.8157 0.8107 1150
|
||||
ORG 0.0000 0.0000 0.0000 8
|
||||
OTHderiv 0.5882 0.4762 0.5263 42
|
||||
PERderiv 0.6571 0.5227 0.5823 44
|
||||
OTH 0.4906 0.6667 0.5652 39
|
||||
ORGderiv 0.7016 0.7791 0.7383 172
|
||||
LOCderiv 0.8256 0.6514 0.7282 109
|
||||
PER 0.0000 0.0000 0.0000 11
|
||||
|
||||
micro avg 0.8722 0.8774 0.8748 13869
|
||||
macro avg 0.8712 0.8774 0.8740 13869
|
||||
```
|
||||
|
||||
## XNLI
|
||||
|
||||
@@ -526,7 +705,7 @@ Based on the script [`run_xnli.py`](https://github.com/huggingface/transformers/
|
||||
#### Fine-tuning on XNLI
|
||||
|
||||
This example code fine-tunes mBERT (multi-lingual BERT) on the XNLI dataset. It runs in 106 mins
|
||||
on a single tesla V100 16GB. The data for XNLI can be downloaded with the following links and should be both saved (and un-zipped) in a
|
||||
on a single tesla V100 16GB. The data for XNLI can be downloaded with the following links and should be both saved (and un-zipped) in a
|
||||
`$XNLI_DIR` directory.
|
||||
|
||||
* [XNLI 1.0](https://www.nyu.edu/projects/bowman/xnli/XNLI-1.0.zip)
|
||||
@@ -593,7 +772,7 @@ export HANS_DIR=path-to-hans
|
||||
export MODEL_TYPE=type-of-the-model-e.g.-bert-roberta-xlnet-etc
|
||||
export MODEL_PATH=path-to-the-model-directory-that-is-trained-on-NLI-e.g.-by-using-run_glue.py
|
||||
|
||||
python examples/hans/test_hans.py \
|
||||
python examples/test_hans.py \
|
||||
--task_name hans \
|
||||
--model_type $MODEL_TYPE \
|
||||
--do_eval \
|
||||
@@ -601,7 +780,7 @@ python examples/hans/test_hans.py \
|
||||
--data_dir $HANS_DIR \
|
||||
--model_name_or_path $MODEL_PATH \
|
||||
--max_seq_length 128 \
|
||||
--output_dir $MODEL_PATH \
|
||||
-output_dir $MODEL_PATH \
|
||||
```
|
||||
|
||||
This will create the hans_predictions.txt file in MODEL_PATH, which can then be evaluated using hans/evaluate_heur_output.py from the HANS dataset.
|
||||
|
||||
@@ -75,17 +75,13 @@ def main():
|
||||
iter += 1
|
||||
if iter % interval == 0:
|
||||
end = time.time()
|
||||
logger.info(f"{iter} examples processed. - {(end-start):.2f}s/{interval}expl")
|
||||
logger.info(f"{iter} examples processed. - {(end-start)/interval:.2f}s/expl")
|
||||
start = time.time()
|
||||
logger.info("Finished binarization")
|
||||
logger.info(f"{len(data)} examples processed.")
|
||||
|
||||
dp_file = f"{args.dump_file}.{args.tokenizer_name}.pickle"
|
||||
vocab_size = tokenizer.vocab_size
|
||||
if vocab_size < (1 << 16):
|
||||
rslt_ = [np.uint16(d) for d in rslt]
|
||||
else:
|
||||
rslt_ = [np.int32(d) for d in rslt]
|
||||
rslt_ = [np.uint16(d) for d in rslt]
|
||||
random.shuffle(rslt_)
|
||||
logger.info(f"Dump to {dp_file}")
|
||||
with open(dp_file, "wb") as handle:
|
||||
|
||||
@@ -1,179 +0,0 @@
|
||||
## Named Entity Recognition
|
||||
|
||||
Based on the scripts [`run_ner.py`](https://github.com/huggingface/transformers/blob/master/examples/ner/run_ner.py) for Pytorch and
|
||||
[`run_tf_ner.py`](https://github.com/huggingface/transformers/blob/master/examples/ner/run_tf_ner.py) for Tensorflow 2.
|
||||
This example fine-tune Bert Multilingual on GermEval 2014 (German NER).
|
||||
Details and results for the fine-tuning provided by @stefan-it.
|
||||
|
||||
### Data (Download and pre-processing steps)
|
||||
|
||||
Data can be obtained from the [GermEval 2014](https://sites.google.com/site/germeval2014ner/data) shared task page.
|
||||
|
||||
Here are the commands for downloading and pre-processing train, dev and test datasets. The original data format has four (tab-separated) columns, in a pre-processing step only the two relevant columns (token and outer span NER annotation) are extracted:
|
||||
|
||||
```bash
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-train.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-dev.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-test.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
|
||||
```
|
||||
|
||||
The GermEval 2014 dataset contains some strange "control character" tokens like `'\x96', '\u200e', '\x95', '\xad' or '\x80'`. One problem with these tokens is, that `BertTokenizer` returns an empty token for them, resulting in misaligned `InputExample`s. I wrote a script that a) filters these tokens and b) splits longer sentences into smaller ones (once the max. subtoken length is reached).
|
||||
|
||||
```bash
|
||||
wget "https://raw.githubusercontent.com/stefan-it/fine-tuned-berts-seq/master/scripts/preprocess.py"
|
||||
```
|
||||
Let's define some variables that we need for further pre-processing steps and training the model:
|
||||
|
||||
```bash
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
```
|
||||
|
||||
Run the pre-processing script on training, dev and test datasets:
|
||||
|
||||
```bash
|
||||
python3 preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
|
||||
python3 preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
|
||||
python3 preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
|
||||
```
|
||||
|
||||
The GermEval 2014 dataset has much more labels than CoNLL-2002/2003 datasets, so an own set of labels must be used:
|
||||
|
||||
```bash
|
||||
cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
|
||||
```
|
||||
|
||||
### Prepare the run
|
||||
|
||||
Additional environment variables must be set:
|
||||
|
||||
```bash
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
```
|
||||
|
||||
### Run the Pytorch version
|
||||
|
||||
To start training, just run:
|
||||
|
||||
```bash
|
||||
python3 run_ner.py --data_dir ./ \
|
||||
--model_type bert \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_gpu_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
```
|
||||
|
||||
If your GPU supports half-precision training, just add the `--fp16` flag. After training, the model will be both evaluated on development and test datasets.
|
||||
|
||||
#### Evaluation
|
||||
|
||||
Evaluation on development dataset outputs the following for our example:
|
||||
|
||||
```bash
|
||||
10/04/2019 00:42:06 - INFO - __main__ - ***** Eval results *****
|
||||
10/04/2019 00:42:06 - INFO - __main__ - f1 = 0.8623348017621146
|
||||
10/04/2019 00:42:06 - INFO - __main__ - loss = 0.07183869666975543
|
||||
10/04/2019 00:42:06 - INFO - __main__ - precision = 0.8467916366258111
|
||||
10/04/2019 00:42:06 - INFO - __main__ - recall = 0.8784592370979806
|
||||
```
|
||||
|
||||
On the test dataset the following results could be achieved:
|
||||
|
||||
```bash
|
||||
10/04/2019 00:42:42 - INFO - __main__ - ***** Eval results *****
|
||||
10/04/2019 00:42:42 - INFO - __main__ - f1 = 0.8614389652384803
|
||||
10/04/2019 00:42:42 - INFO - __main__ - loss = 0.07064602487454782
|
||||
10/04/2019 00:42:42 - INFO - __main__ - precision = 0.8604651162790697
|
||||
10/04/2019 00:42:42 - INFO - __main__ - recall = 0.8624150210424085
|
||||
```
|
||||
|
||||
#### Comparing BERT (large, cased), RoBERTa (large, cased) and DistilBERT (base, uncased)
|
||||
|
||||
Here is a small comparison between BERT (large, cased), RoBERTa (large, cased) and DistilBERT (base, uncased) with the same hyperparameters as specified in the [example documentation](https://huggingface.co/transformers/examples.html#named-entity-recognition) (one run):
|
||||
|
||||
| Model | F-Score Dev | F-Score Test
|
||||
| --------------------------------- | ------- | --------
|
||||
| `bert-large-cased` | 95.59 | 91.70
|
||||
| `roberta-large` | 95.96 | 91.87
|
||||
| `distilbert-base-uncased` | 94.34 | 90.32
|
||||
|
||||
### Run the Tensorflow 2 version
|
||||
|
||||
To start training, just run:
|
||||
|
||||
```bash
|
||||
python3 run_tf_ner.py --data_dir ./ \
|
||||
--model_type bert \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_device_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
```
|
||||
|
||||
Such as the Pytorch version, if your GPU supports half-precision training, just add the `--fp16` flag. After training, the model will be both evaluated on development and test datasets.
|
||||
|
||||
#### Evaluation
|
||||
|
||||
Evaluation on development dataset outputs the following for our example:
|
||||
```bash
|
||||
precision recall f1-score support
|
||||
|
||||
LOCderiv 0.7619 0.6154 0.6809 52
|
||||
PERpart 0.8724 0.8997 0.8858 4057
|
||||
OTHpart 0.9360 0.9466 0.9413 711
|
||||
ORGpart 0.7015 0.6989 0.7002 269
|
||||
LOCpart 0.7668 0.8488 0.8057 496
|
||||
LOC 0.8745 0.9191 0.8963 235
|
||||
ORGderiv 0.7723 0.8571 0.8125 91
|
||||
OTHderiv 0.4800 0.6667 0.5581 18
|
||||
OTH 0.5789 0.6875 0.6286 16
|
||||
PERderiv 0.5385 0.3889 0.4516 18
|
||||
PER 0.5000 0.5000 0.5000 2
|
||||
ORG 0.0000 0.0000 0.0000 3
|
||||
|
||||
micro avg 0.8574 0.8862 0.8715 5968
|
||||
macro avg 0.8575 0.8862 0.8713 5968
|
||||
```
|
||||
|
||||
On the test dataset the following results could be achieved:
|
||||
```bash
|
||||
precision recall f1-score support
|
||||
|
||||
PERpart 0.8847 0.8944 0.8896 9397
|
||||
OTHpart 0.9376 0.9353 0.9365 1639
|
||||
ORGpart 0.7307 0.7044 0.7173 697
|
||||
LOC 0.9133 0.9394 0.9262 561
|
||||
LOCpart 0.8058 0.8157 0.8107 1150
|
||||
ORG 0.0000 0.0000 0.0000 8
|
||||
OTHderiv 0.5882 0.4762 0.5263 42
|
||||
PERderiv 0.6571 0.5227 0.5823 44
|
||||
OTH 0.4906 0.6667 0.5652 39
|
||||
ORGderiv 0.7016 0.7791 0.7383 172
|
||||
LOCderiv 0.8256 0.6514 0.7282 109
|
||||
PER 0.0000 0.0000 0.0000 11
|
||||
|
||||
micro avg 0.8722 0.8774 0.8748 13869
|
||||
macro avg 0.8712 0.8774 0.8740 13869
|
||||
```
|
||||
@@ -1,32 +0,0 @@
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-train.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-dev.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
|
||||
curl -L 'https://sites.google.com/site/germeval2014ner/data/NER-de-test.tsv?attredirects=0&d=1' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
|
||||
wget "https://raw.githubusercontent.com/stefan-it/fine-tuned-berts-seq/master/scripts/preprocess.py"
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
python3 preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
|
||||
python3 preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
|
||||
python3 preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
|
||||
cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
|
||||
python3 run_ner.py --data_dir ./ \
|
||||
--model_type bert \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_gpu_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
@@ -1,21 +0,0 @@
|
||||
# Require pytorch-lightning=0.6
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
|
||||
python3 run_pl_ner.py --data_dir ./ \
|
||||
--model_type bert \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--train_batch_size 32 \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_predict
|
||||
@@ -1,238 +0,0 @@
|
||||
import argparse
|
||||
import glob
|
||||
import logging
|
||||
import os
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from seqeval.metrics import f1_score, precision_score, recall_score
|
||||
from torch.nn import CrossEntropyLoss
|
||||
from torch.utils.data import DataLoader, RandomSampler, SequentialSampler, TensorDataset
|
||||
from torch.utils.data.distributed import DistributedSampler
|
||||
|
||||
from transformer_base import BaseTransformer, add_generic_args, generic_train
|
||||
from utils_ner import convert_examples_to_features, get_labels, read_examples_from_file
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class NERTransformer(BaseTransformer):
|
||||
"""
|
||||
A training module for NER. See BaseTransformer for the core options.
|
||||
"""
|
||||
|
||||
def __init__(self, hparams):
|
||||
self.labels = get_labels(hparams.labels)
|
||||
num_labels = len(self.labels)
|
||||
super(NERTransformer, self).__init__(hparams, num_labels)
|
||||
|
||||
def forward(self, **inputs):
|
||||
return self.model(**inputs)
|
||||
|
||||
def training_step(self, batch, batch_num):
|
||||
"Compute loss"
|
||||
inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
|
||||
if self.hparams.model_type != "distilbert":
|
||||
inputs["token_type_ids"] = (
|
||||
batch[2] if self.hparams.model_type in ["bert", "xlnet"] else None
|
||||
) # XLM and RoBERTa don"t use segment_ids
|
||||
|
||||
outputs = self.forward(**inputs)
|
||||
loss = outputs[0]
|
||||
|
||||
tensorboard_logs = {"loss": loss, "rate": self.lr_scheduler.get_last_lr()[-1]}
|
||||
return {"loss": loss, "log": tensorboard_logs}
|
||||
|
||||
def load_dataset(self, mode, batch_size):
|
||||
labels = get_labels(self.hparams.labels)
|
||||
self.pad_token_label_id = CrossEntropyLoss().ignore_index
|
||||
dataset = self.load_and_cache_examples(labels, self.pad_token_label_id, mode)
|
||||
if mode == "train":
|
||||
if self.hparams.n_gpu > 1:
|
||||
sampler = DistributedSampler(dataset)
|
||||
else:
|
||||
sampler = RandomSampler(dataset)
|
||||
else:
|
||||
sampler = SequentialSampler(dataset)
|
||||
dataloader = DataLoader(dataset, sampler=sampler, batch_size=batch_size)
|
||||
return dataloader
|
||||
|
||||
def validation_step(self, batch, batch_nb):
|
||||
inputs = {"input_ids": batch[0], "attention_mask": batch[1], "labels": batch[3]}
|
||||
if self.hparams.model_type != "distilbert":
|
||||
inputs["token_type_ids"] = (
|
||||
batch[2] if self.hparams.model_type in ["bert", "xlnet"] else None
|
||||
) # XLM and RoBERTa don"t use segment_ids
|
||||
outputs = self.forward(**inputs)
|
||||
tmp_eval_loss, logits = outputs[:2]
|
||||
preds = logits.detach().cpu().numpy()
|
||||
out_label_ids = inputs["labels"].detach().cpu().numpy()
|
||||
|
||||
return {"val_loss": tmp_eval_loss, "pred": preds, "target": out_label_ids}
|
||||
|
||||
def _eval_end(self, outputs):
|
||||
"Task specific validation"
|
||||
val_loss_mean = torch.stack([x["val_loss"] for x in outputs]).mean()
|
||||
preds = np.concatenate([x["pred"] for x in outputs], axis=0)
|
||||
preds = np.argmax(preds, axis=2)
|
||||
out_label_ids = np.concatenate([x["target"] for x in outputs], axis=0)
|
||||
|
||||
label_map = {i: label for i, label in enumerate(self.labels)}
|
||||
out_label_list = [[] for _ in range(out_label_ids.shape[0])]
|
||||
preds_list = [[] for _ in range(out_label_ids.shape[0])]
|
||||
|
||||
for i in range(out_label_ids.shape[0]):
|
||||
for j in range(out_label_ids.shape[1]):
|
||||
if out_label_ids[i, j] != self.pad_token_label_id:
|
||||
out_label_list[i].append(label_map[out_label_ids[i][j]])
|
||||
preds_list[i].append(label_map[preds[i][j]])
|
||||
|
||||
results = {
|
||||
"val_loss": val_loss_mean,
|
||||
"precision": precision_score(out_label_list, preds_list),
|
||||
"recall": recall_score(out_label_list, preds_list),
|
||||
"f1": f1_score(out_label_list, preds_list),
|
||||
}
|
||||
|
||||
if self.is_logger():
|
||||
logger.info(self.proc_rank)
|
||||
logger.info("***** Eval results *****")
|
||||
for key in sorted(results.keys()):
|
||||
logger.info(" %s = %s", key, str(results[key]))
|
||||
|
||||
tensorboard_logs = results
|
||||
ret = {k: v for k, v in results.items()}
|
||||
ret["log"] = tensorboard_logs
|
||||
return ret, preds_list, out_label_list
|
||||
|
||||
def validation_end(self, outputs):
|
||||
ret, preds, targets = self._eval_end(outputs)
|
||||
return ret
|
||||
|
||||
def test_end(self, outputs):
|
||||
ret, predictions, targets = self._eval_end(outputs)
|
||||
|
||||
if self.is_logger():
|
||||
# Write output to a file:
|
||||
# Save results
|
||||
output_test_results_file = os.path.join(self.hparams.output_dir, "test_results.txt")
|
||||
with open(output_test_results_file, "w") as writer:
|
||||
for key in sorted(ret.keys()):
|
||||
if key != "log":
|
||||
writer.write("{} = {}\n".format(key, str(ret[key])))
|
||||
# Save predictions
|
||||
output_test_predictions_file = os.path.join(self.hparams.output_dir, "test_predictions.txt")
|
||||
with open(output_test_predictions_file, "w") as writer:
|
||||
with open(os.path.join(self.hparams.data_dir, "test.txt"), "r") as f:
|
||||
example_id = 0
|
||||
for line in f:
|
||||
if line.startswith("-DOCSTART-") or line == "" or line == "\n":
|
||||
writer.write(line)
|
||||
if not predictions[example_id]:
|
||||
example_id += 1
|
||||
elif predictions[example_id]:
|
||||
output_line = line.split()[0] + " " + predictions[example_id].pop(0) + "\n"
|
||||
writer.write(output_line)
|
||||
else:
|
||||
logger.warning(
|
||||
"Maximum sequence length exceeded: No prediction for '%s'.", line.split()[0]
|
||||
)
|
||||
return ret
|
||||
|
||||
def load_and_cache_examples(self, labels, pad_token_label_id, mode):
|
||||
args = self.hparams
|
||||
tokenizer = self.tokenizer
|
||||
if self.proc_rank not in [-1, 0] and mode == "train":
|
||||
torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
|
||||
|
||||
# Load data features from cache or dataset file
|
||||
cached_features_file = os.path.join(
|
||||
args.data_dir,
|
||||
"cached_{}_{}_{}".format(
|
||||
mode, list(filter(None, args.model_name_or_path.split("/"))).pop(), str(args.max_seq_length)
|
||||
),
|
||||
)
|
||||
if os.path.exists(cached_features_file) and not args.overwrite_cache:
|
||||
logger.info("Loading features from cached file %s", cached_features_file)
|
||||
features = torch.load(cached_features_file)
|
||||
else:
|
||||
logger.info("Creating features from dataset file at %s", args.data_dir)
|
||||
examples = read_examples_from_file(args.data_dir, mode)
|
||||
features = convert_examples_to_features(
|
||||
examples,
|
||||
labels,
|
||||
args.max_seq_length,
|
||||
tokenizer,
|
||||
cls_token_at_end=bool(args.model_type in ["xlnet"]),
|
||||
cls_token=tokenizer.cls_token,
|
||||
cls_token_segment_id=2 if args.model_type in ["xlnet"] else 0,
|
||||
sep_token=tokenizer.sep_token,
|
||||
sep_token_extra=bool(args.model_type in ["roberta"]),
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]),
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token_label_id=pad_token_label_id,
|
||||
)
|
||||
if self.proc_rank in [-1, 0]:
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
torch.save(features, cached_features_file)
|
||||
|
||||
if self.proc_rank == 0 and mode == "train":
|
||||
torch.distributed.barrier() # Make sure only the first process in distributed training process the dataset, and the others will use the cache
|
||||
|
||||
# Convert to Tensors and build dataset
|
||||
all_input_ids = torch.tensor([f.input_ids for f in features], dtype=torch.long)
|
||||
all_input_mask = torch.tensor([f.input_mask for f in features], dtype=torch.long)
|
||||
all_segment_ids = torch.tensor([f.segment_ids for f in features], dtype=torch.long)
|
||||
all_label_ids = torch.tensor([f.label_ids for f in features], dtype=torch.long)
|
||||
|
||||
dataset = TensorDataset(all_input_ids, all_input_mask, all_segment_ids, all_label_ids)
|
||||
return dataset
|
||||
|
||||
@staticmethod
|
||||
def add_model_specific_args(parser, root_dir):
|
||||
# Add NER specific options
|
||||
BaseTransformer.add_model_specific_args(parser, root_dir)
|
||||
parser.add_argument(
|
||||
"--max_seq_length",
|
||||
default=128,
|
||||
type=int,
|
||||
help="The maximum total input sequence length after tokenization. Sequences longer "
|
||||
"than this will be truncated, sequences shorter will be padded.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--labels",
|
||||
default="",
|
||||
type=str,
|
||||
help="Path to a file containing all labels. If not specified, CoNLL-2003 labels are used.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--data_dir",
|
||||
default=None,
|
||||
type=str,
|
||||
required=True,
|
||||
help="The input data dir. Should contain the training files for the CoNLL-2003 NER task.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--overwrite_cache", action="store_true", help="Overwrite the cached training and evaluation sets"
|
||||
)
|
||||
|
||||
return parser
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
add_generic_args(parser, os.getcwd())
|
||||
parser = NERTransformer.add_model_specific_args(parser, os.getcwd())
|
||||
args = parser.parse_args()
|
||||
model = NERTransformer(args)
|
||||
trainer = generic_train(model, args)
|
||||
|
||||
if args.do_predict:
|
||||
checkpoints = list(sorted(glob.glob(args.output_dir + "/checkpoint_*.ckpt", recursive=True)))
|
||||
NERTransformer.load_from_checkpoint(checkpoints[-1])
|
||||
trainer.test(model)
|
||||
@@ -1,270 +0,0 @@
|
||||
import os
|
||||
import random
|
||||
|
||||
import numpy as np
|
||||
import pytorch_lightning as pl
|
||||
import torch
|
||||
|
||||
from transformers import (
|
||||
AdamW,
|
||||
BertConfig,
|
||||
BertForTokenClassification,
|
||||
BertTokenizer,
|
||||
CamembertConfig,
|
||||
CamembertForTokenClassification,
|
||||
CamembertTokenizer,
|
||||
DistilBertConfig,
|
||||
DistilBertForTokenClassification,
|
||||
DistilBertTokenizer,
|
||||
RobertaConfig,
|
||||
RobertaForTokenClassification,
|
||||
RobertaTokenizer,
|
||||
XLMRobertaConfig,
|
||||
XLMRobertaForTokenClassification,
|
||||
XLMRobertaTokenizer,
|
||||
get_linear_schedule_with_warmup,
|
||||
)
|
||||
|
||||
|
||||
ALL_MODELS = sum(
|
||||
(
|
||||
tuple(conf.pretrained_config_archive_map.keys())
|
||||
for conf in (BertConfig, RobertaConfig, DistilBertConfig, CamembertConfig, XLMRobertaConfig)
|
||||
),
|
||||
(),
|
||||
)
|
||||
|
||||
MODEL_CLASSES = {
|
||||
"bert": (BertConfig, BertForTokenClassification, BertTokenizer),
|
||||
"roberta": (RobertaConfig, RobertaForTokenClassification, RobertaTokenizer),
|
||||
"distilbert": (DistilBertConfig, DistilBertForTokenClassification, DistilBertTokenizer),
|
||||
"camembert": (CamembertConfig, CamembertForTokenClassification, CamembertTokenizer),
|
||||
"xlmroberta": (XLMRobertaConfig, XLMRobertaForTokenClassification, XLMRobertaTokenizer),
|
||||
}
|
||||
|
||||
|
||||
def set_seed(args):
|
||||
random.seed(args.seed)
|
||||
np.random.seed(args.seed)
|
||||
torch.manual_seed(args.seed)
|
||||
if args.n_gpu > 0:
|
||||
torch.cuda.manual_seed_all(args.seed)
|
||||
|
||||
|
||||
class BaseTransformer(pl.LightningModule):
|
||||
def __init__(self, hparams, num_labels=None):
|
||||
"Initialize a model."
|
||||
|
||||
super(BaseTransformer, self).__init__()
|
||||
self.hparams = hparams
|
||||
self.hparams.model_type = self.hparams.model_type.lower()
|
||||
|
||||
config_class, model_class, tokenizer_class = MODEL_CLASSES[self.hparams.model_type]
|
||||
config = config_class.from_pretrained(
|
||||
self.hparams.config_name if self.hparams.config_name else self.hparams.model_name_or_path,
|
||||
num_labels=num_labels,
|
||||
cache_dir=self.hparams.cache_dir if self.hparams.cache_dir else None,
|
||||
)
|
||||
tokenizer = tokenizer_class.from_pretrained(
|
||||
self.hparams.tokenizer_name if self.hparams.tokenizer_name else self.hparams.model_name_or_path,
|
||||
do_lower_case=self.hparams.do_lower_case,
|
||||
cache_dir=self.hparams.cache_dir if self.hparams.cache_dir else None,
|
||||
)
|
||||
model = model_class.from_pretrained(
|
||||
self.hparams.model_name_or_path,
|
||||
from_tf=bool(".ckpt" in self.hparams.model_name_or_path),
|
||||
config=config,
|
||||
cache_dir=self.hparams.cache_dir if self.hparams.cache_dir else None,
|
||||
)
|
||||
self.config, self.tokenizer, self.model = config, tokenizer, model
|
||||
self.proc_rank = -1
|
||||
|
||||
def is_logger(self):
|
||||
return self.proc_rank <= 0
|
||||
|
||||
def configure_optimizers(self):
|
||||
"Prepare optimizer and schedule (linear warmup and decay)"
|
||||
model = self.model
|
||||
|
||||
t_total = (
|
||||
len(self.train_dataloader())
|
||||
// self.hparams.gradient_accumulation_steps
|
||||
* float(self.hparams.num_train_epochs)
|
||||
)
|
||||
no_decay = ["bias", "LayerNorm.weight"]
|
||||
optimizer_grouped_parameters = [
|
||||
{
|
||||
"params": [p for n, p in model.named_parameters() if not any(nd in n for nd in no_decay)],
|
||||
"weight_decay": self.hparams.weight_decay,
|
||||
},
|
||||
{
|
||||
"params": [p for n, p in model.named_parameters() if any(nd in n for nd in no_decay)],
|
||||
"weight_decay": 0.0,
|
||||
},
|
||||
]
|
||||
optimizer = AdamW(optimizer_grouped_parameters, lr=self.hparams.learning_rate, eps=self.hparams.adam_epsilon)
|
||||
scheduler = get_linear_schedule_with_warmup(
|
||||
optimizer, num_warmup_steps=self.hparams.warmup_steps, num_training_steps=t_total
|
||||
)
|
||||
self.lr_scheduler = scheduler
|
||||
return [optimizer]
|
||||
|
||||
def optimizer_step(self, epoch, batch_idx, optimizer, optimizer_idx, second_order_closure=None):
|
||||
|
||||
# Step each time.
|
||||
optimizer.step()
|
||||
self.lr_scheduler.step()
|
||||
optimizer.zero_grad()
|
||||
|
||||
def get_tqdm_dict(self):
|
||||
tqdm_dict = {"loss": "{:.3f}".format(self.trainer.avg_loss), "lr": self.lr_scheduler.get_last_lr()[-1]}
|
||||
|
||||
return tqdm_dict
|
||||
|
||||
def test_step(self, batch, batch_nb):
|
||||
return self.validation_step(batch, batch_nb)
|
||||
|
||||
def test_end(self, outputs):
|
||||
return self.validation_end(outputs)
|
||||
|
||||
@pl.data_loader
|
||||
def train_dataloader(self):
|
||||
return self.load_dataset("train", self.hparams.train_batch_size)
|
||||
|
||||
@pl.data_loader
|
||||
def val_dataloader(self):
|
||||
return self.load_dataset("dev", self.hparams.eval_batch_size)
|
||||
|
||||
@pl.data_loader
|
||||
def test_dataloader(self):
|
||||
return self.load_dataset("test", self.hparams.eval_batch_size)
|
||||
|
||||
def init_ddp_connection(self, proc_rank, world_size):
|
||||
self.proc_rank = proc_rank
|
||||
super(BaseTransformer, self).init_ddp_connection(proc_rank, world_size)
|
||||
|
||||
@staticmethod
|
||||
def add_model_specific_args(parser, root_dir):
|
||||
parser.add_argument(
|
||||
"--model_type",
|
||||
default=None,
|
||||
type=str,
|
||||
required=True,
|
||||
help="Model type selected in the list: " + ", ".join(MODEL_CLASSES.keys()),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_name_or_path",
|
||||
default=None,
|
||||
type=str,
|
||||
required=True,
|
||||
help="Path to pre-trained model or shortcut name selected in the list: " + ", ".join(ALL_MODELS),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--config_name", default="", type=str, help="Pretrained config name or path if not the same as model_name"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--tokenizer_name",
|
||||
default="",
|
||||
type=str,
|
||||
help="Pretrained tokenizer name or path if not the same as model_name",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--cache_dir",
|
||||
default="",
|
||||
type=str,
|
||||
help="Where do you want to store the pre-trained models downloaded from s3",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--do_lower_case", action="store_true", help="Set this flag if you are using an uncased model."
|
||||
)
|
||||
parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
|
||||
parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
parser.add_argument(
|
||||
"--num_train_epochs", default=3, type=int, help="Total number of training epochs to perform."
|
||||
)
|
||||
|
||||
parser.add_argument("--train_batch_size", default=32, type=int)
|
||||
parser.add_argument("--eval_batch_size", default=32, type=int)
|
||||
|
||||
|
||||
def add_generic_args(parser, root_dir):
|
||||
parser.add_argument(
|
||||
"--output_dir",
|
||||
default=None,
|
||||
type=str,
|
||||
required=True,
|
||||
help="The output directory where the model predictions and checkpoints will be written.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--fp16",
|
||||
action="store_true",
|
||||
help="Whether to use 16-bit (mixed) precision (through NVIDIA apex) instead of 32-bit",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--fp16_opt_level",
|
||||
type=str,
|
||||
default="O1",
|
||||
help="For fp16: Apex AMP optimization level selected in ['O0', 'O1', 'O2', and 'O3']."
|
||||
"See details at https://nvidia.github.io/apex/amp.html",
|
||||
)
|
||||
|
||||
parser.add_argument("--n_gpu", type=int, default=1)
|
||||
parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
|
||||
parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
|
||||
parser.add_argument("--do_predict", action="store_true", help="Whether to run predictions on the test set.")
|
||||
parser.add_argument(
|
||||
"--gradient_accumulation_steps",
|
||||
type=int,
|
||||
default=1,
|
||||
help="Number of updates steps to accumulate before performing a backward/update pass.",
|
||||
)
|
||||
|
||||
parser.add_argument("--server_ip", type=str, default="", help="For distant debugging.")
|
||||
parser.add_argument("--server_port", type=str, default="", help="For distant debugging.")
|
||||
parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
|
||||
|
||||
|
||||
def generic_train(model, args):
|
||||
# init model
|
||||
set_seed(args)
|
||||
|
||||
# Setup distant debugging if needed
|
||||
if args.server_ip and args.server_port:
|
||||
# Distant debugging - see https://code.visualstudio.com/docs/python/debugging#_attach-to-a-local-script
|
||||
import ptvsd
|
||||
|
||||
print("Waiting for debugger attach")
|
||||
ptvsd.enable_attach(address=(args.server_ip, args.server_port), redirect_output=True)
|
||||
ptvsd.wait_for_attach()
|
||||
|
||||
if os.path.exists(args.output_dir) and os.listdir(args.output_dir) and args.do_train:
|
||||
raise ValueError("Output directory ({}) already exists and is not empty.".format(args.output_dir))
|
||||
|
||||
checkpoint_callback = pl.callbacks.ModelCheckpoint(
|
||||
filepath=args.output_dir, prefix="checkpoint", monitor="val_loss", mode="min", save_top_k=5
|
||||
)
|
||||
|
||||
train_params = dict(
|
||||
accumulate_grad_batches=args.gradient_accumulation_steps,
|
||||
gpus=args.n_gpu,
|
||||
max_epochs=args.num_train_epochs,
|
||||
gradient_clip_val=args.max_grad_norm,
|
||||
checkpoint_callback=checkpoint_callback,
|
||||
)
|
||||
if args.fp16:
|
||||
train_params["use_amp"] = args.fp16
|
||||
train_params["amp_level"] = args.fp16_opt_level
|
||||
|
||||
if args.n_gpu > 1:
|
||||
train_params["distributed_backend"] = "ddp"
|
||||
|
||||
trainer = pl.Trainer(**train_params)
|
||||
|
||||
if args.do_train:
|
||||
trainer.fit(model)
|
||||
|
||||
return trainer
|
||||
+12
-37
@@ -59,7 +59,7 @@ MODEL_CLASSES = {
|
||||
# Padding text to help Transformer-XL and XLNet with short prompts as proposed by Aman Rusia
|
||||
# in https://github.com/rusiaaman/XLNet-gen#methodology
|
||||
# and https://medium.com/@amanrusia/xlnet-speaks-comparison-to-gpt-2-ea1a4e9ba39e
|
||||
PADDING_TEXT = """In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
PADDING_TEXT = """ In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
(except for Alexei and Maria) are discovered.
|
||||
The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
|
||||
remainder of the story. 1883 Western Siberia,
|
||||
@@ -106,8 +106,6 @@ def prepare_xlm_input(args, model, tokenizer, prompt_text):
|
||||
language = None
|
||||
while language not in available_languages:
|
||||
language = input("Using XLM. Select language in " + str(list(available_languages)) + " >>> ")
|
||||
|
||||
model.config.lang_id = model.config.lang2id[language]
|
||||
# kwargs["language"] = tokenizer.lang2id[language]
|
||||
|
||||
# TODO fix mask_token_id setup when configurations will be synchronized between models and tokenizers
|
||||
@@ -121,12 +119,12 @@ def prepare_xlm_input(args, model, tokenizer, prompt_text):
|
||||
|
||||
def prepare_xlnet_input(args, _, tokenizer, prompt_text):
|
||||
prompt_text = (args.padding_text if args.padding_text else PADDING_TEXT) + prompt_text
|
||||
return prompt_text
|
||||
return prompt_text, {}
|
||||
|
||||
|
||||
def prepare_transfoxl_input(args, _, tokenizer, prompt_text):
|
||||
prompt_text = (args.padding_text if args.padding_text else PADDING_TEXT) + prompt_text
|
||||
return prompt_text
|
||||
return prompt_text, {}
|
||||
|
||||
|
||||
PREPROCESSING_FUNCTIONS = {
|
||||
@@ -185,7 +183,6 @@ def main():
|
||||
|
||||
parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
|
||||
parser.add_argument("--no_cuda", action="store_true", help="Avoid using CUDA when available")
|
||||
parser.add_argument("--num_return_sequences", type=int, default=1, help="The number of samples to generate.")
|
||||
args = parser.parse_args()
|
||||
|
||||
args.device = torch.device("cuda" if torch.cuda.is_available() and not args.no_cuda else "cpu")
|
||||
@@ -213,50 +210,28 @@ def main():
|
||||
requires_preprocessing = args.model_type in PREPROCESSING_FUNCTIONS.keys()
|
||||
if requires_preprocessing:
|
||||
prepare_input = PREPROCESSING_FUNCTIONS.get(args.model_type)
|
||||
preprocessed_prompt_text = prepare_input(args, model, tokenizer, prompt_text)
|
||||
encoded_prompt = tokenizer.encode(
|
||||
preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt", add_space_before_punct_symbol=True
|
||||
)
|
||||
else:
|
||||
encoded_prompt = tokenizer.encode(prompt_text, add_special_tokens=False, return_tensors="pt")
|
||||
prompt_text = prepare_input(args, model, tokenizer, prompt_text)
|
||||
encoded_prompt = tokenizer.encode(prompt_text, add_special_tokens=False, return_tensors="pt")
|
||||
encoded_prompt = encoded_prompt.to(args.device)
|
||||
|
||||
output_sequences = model.generate(
|
||||
input_ids=encoded_prompt,
|
||||
max_length=args.length + len(encoded_prompt[0]),
|
||||
max_length=args.length,
|
||||
temperature=args.temperature,
|
||||
top_k=args.k,
|
||||
top_p=args.p,
|
||||
repetition_penalty=args.repetition_penalty,
|
||||
do_sample=True,
|
||||
num_return_sequences=args.num_return_sequences,
|
||||
)
|
||||
|
||||
# Remove the batch dimension when returning multiple sequences
|
||||
if len(output_sequences.shape) > 2:
|
||||
output_sequences.squeeze_()
|
||||
# Batch size == 1. to add more examples please use num_return_sequences > 1
|
||||
generated_sequence = output_sequences[0].tolist()
|
||||
text = tokenizer.decode(generated_sequence, clean_up_tokenization_spaces=True)
|
||||
text = text[: text.find(args.stop_token) if args.stop_token else None]
|
||||
|
||||
generated_sequences = []
|
||||
print(text)
|
||||
|
||||
for generated_sequence_idx, generated_sequence in enumerate(output_sequences):
|
||||
print("=== GENERATED SEQUENCE {} ===".format(generated_sequence_idx + 1))
|
||||
generated_sequence = generated_sequence.tolist()
|
||||
|
||||
# Decode text
|
||||
text = tokenizer.decode(generated_sequence, clean_up_tokenization_spaces=True)
|
||||
|
||||
# Remove all text after the stop token
|
||||
text = text[: text.find(args.stop_token) if args.stop_token else None]
|
||||
|
||||
# Add the prompt at the beginning of the sequence. Remove the excess text that was used for pre-processing
|
||||
total_sequence = (
|
||||
prompt_text + text[len(tokenizer.decode(encoded_prompt[0], clean_up_tokenization_spaces=True)) :]
|
||||
)
|
||||
|
||||
generated_sequences.append(total_sequence)
|
||||
print(total_sequence)
|
||||
|
||||
return generated_sequences
|
||||
return text
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
|
||||
@@ -160,10 +160,7 @@ def train(args, train_dataset, model, tokenizer, labels, pad_token_label_id):
|
||||
# Check if continuing training from a checkpoint
|
||||
if os.path.exists(args.model_name_or_path):
|
||||
# set global_step to gobal_step of last saved checkpoint from model path
|
||||
try:
|
||||
global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
|
||||
except ValueError:
|
||||
global_step = 0
|
||||
global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
|
||||
epochs_trained = global_step // (len(train_dataloader) // args.gradient_accumulation_steps)
|
||||
steps_trained_in_current_epoch = global_step % (len(train_dataloader) // args.gradient_accumulation_steps)
|
||||
|
||||
@@ -586,8 +583,6 @@ def main():
|
||||
config = config_class.from_pretrained(
|
||||
args.config_name if args.config_name else args.model_name_or_path,
|
||||
num_labels=num_labels,
|
||||
id2label={str(i): label for i, label in enumerate(labels)},
|
||||
label2id={label: i for i, label in enumerate(labels)},
|
||||
cache_dir=args.cache_dir if args.cache_dir else None,
|
||||
)
|
||||
tokenizer = tokenizer_class.from_pretrained(
|
||||
+3
-10
@@ -38,9 +38,6 @@ from transformers import (
|
||||
BertConfig,
|
||||
BertForQuestionAnswering,
|
||||
BertTokenizer,
|
||||
CamembertConfig,
|
||||
CamembertForQuestionAnswering,
|
||||
CamembertTokenizer,
|
||||
DistilBertConfig,
|
||||
DistilBertForQuestionAnswering,
|
||||
DistilBertTokenizer,
|
||||
@@ -73,16 +70,12 @@ except ImportError:
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
ALL_MODELS = sum(
|
||||
(
|
||||
tuple(conf.pretrained_config_archive_map.keys())
|
||||
for conf in (BertConfig, CamembertConfig, RobertaConfig, XLNetConfig, XLMConfig)
|
||||
),
|
||||
(tuple(conf.pretrained_config_archive_map.keys()) for conf in (BertConfig, RobertaConfig, XLNetConfig, XLMConfig)),
|
||||
(),
|
||||
)
|
||||
|
||||
MODEL_CLASSES = {
|
||||
"bert": (BertConfig, BertForQuestionAnswering, BertTokenizer),
|
||||
"camembert": (CamembertConfig, CamembertForQuestionAnswering, CamembertTokenizer),
|
||||
"roberta": (RobertaConfig, RobertaForQuestionAnswering, RobertaTokenizer),
|
||||
"xlnet": (XLNetConfig, XLNetForQuestionAnswering, XLNetTokenizer),
|
||||
"xlm": (XLMConfig, XLMForQuestionAnswering, XLMTokenizer),
|
||||
@@ -219,7 +212,7 @@ def train(args, train_dataset, model, tokenizer):
|
||||
"end_positions": batch[4],
|
||||
}
|
||||
|
||||
if args.model_type in ["xlm", "roberta", "distilbert", "camembert"]:
|
||||
if args.model_type in ["xlm", "roberta", "distilbert"]:
|
||||
del inputs["token_type_ids"]
|
||||
|
||||
if args.model_type in ["xlnet", "xlm"]:
|
||||
@@ -334,7 +327,7 @@ def evaluate(args, model, tokenizer, prefix=""):
|
||||
"token_type_ids": batch[2],
|
||||
}
|
||||
|
||||
if args.model_type in ["xlm", "roberta", "distilbert", "camembert"]:
|
||||
if args.model_type in ["xlm", "roberta", "distilbert"]:
|
||||
del inputs["token_type_ids"]
|
||||
|
||||
example_indices = batch[3]
|
||||
|
||||
File renamed without changes.
@@ -459,7 +459,7 @@ def main():
|
||||
help="Number of updates steps to accumulate before performing a backward/update pass.",
|
||||
)
|
||||
parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight deay if we apply some.")
|
||||
parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
|
||||
parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
|
||||
parser.add_argument(
|
||||
|
||||
@@ -303,7 +303,7 @@ class TransformerDecoderLayer(nn.Module):
|
||||
self.layer_norm_2 = nn.LayerNorm(d_model, eps=1e-6)
|
||||
self.drop = nn.Dropout(dropout)
|
||||
mask = self._get_attn_subsequent_mask(MAX_SIZE)
|
||||
# Register self.mask as a saved_state in TransformerDecoderLayer, so
|
||||
# Register self.mask as a buffer in TransformerDecoderLayer, so
|
||||
# it gets TransformerDecoderLayer's cuda behavior automatically.
|
||||
self.register_buffer("mask", mask)
|
||||
|
||||
|
||||
@@ -97,4 +97,4 @@ class ExamplesTests(unittest.TestCase):
|
||||
model_type, model_name = ("--model_type=openai-gpt", "--model_name_or_path=openai-gpt")
|
||||
with patch.object(sys, "argv", testargs + [model_type, model_name]):
|
||||
result = run_generation.main()
|
||||
self.assertGreaterEqual(len(result[0]), 10)
|
||||
self.assertGreaterEqual(len(result), 10)
|
||||
File renamed without changes.
@@ -1,77 +0,0 @@
|
||||
## XLNet large language model fine-tuned on SQuAD2.0
|
||||
|
||||
### with the following results:
|
||||
|
||||
```
|
||||
"exact": 82.07698138633876,
|
||||
"f1": 85.898874470488,
|
||||
"total": 11873,
|
||||
"HasAns_exact": 79.60526315789474,
|
||||
"HasAns_f1": 87.26000954590184,
|
||||
"HasAns_total": 5928,
|
||||
"NoAns_exact": 84.54163162321278,
|
||||
"NoAns_f1": 84.54163162321278,
|
||||
"NoAns_total": 5945,
|
||||
"best_exact": 83.22243746315169,
|
||||
"best_exact_thresh": -11.112004280090332,
|
||||
"best_f1": 86.88541353813282,
|
||||
"best_f1_thresh": -11.112004280090332
|
||||
```
|
||||
### from script:
|
||||
```
|
||||
python -m torch.distributed.launch --nproc_per_node=2 ${RUN_SQUAD_DIR}/run_squad.py \
|
||||
--model_type xlnet \
|
||||
--model_name_or_path xlnet-large-cased \
|
||||
--do_train \
|
||||
--train_file ${SQUAD_DIR}/train-v2.0.json \
|
||||
--predict_file ${SQUAD_DIR}/dev-v2.0.json \
|
||||
--version_2_with_negative \
|
||||
--num_train_epochs 3 \
|
||||
--learning_rate 3e-5 \
|
||||
--adam_epsilon 1e-6 \
|
||||
--max_seq_length 512 \
|
||||
--doc_stride 128 \
|
||||
--save_steps 2000 \
|
||||
--per_gpu_train_batch_size 1 \
|
||||
--gradient_accumulation_steps 24 \
|
||||
--output_dir ${MODEL_PATH}
|
||||
|
||||
CUDA_VISIBLE_DEVICES=0 python ${RUN_SQUAD_DIR}/run_squad_II.py \
|
||||
--model_type xlnet \
|
||||
--model_name_or_path ${MODEL_PATH} \
|
||||
--do_eval \
|
||||
--train_file ${SQUAD_DIR}/train-v2.0.json \
|
||||
--predict_file ${SQUAD_DIR}/dev-v2.0.json \
|
||||
--version_2_with_negative \
|
||||
--max_seq_length 512 \
|
||||
--per_gpu_eval_batch_size 48 \
|
||||
--output_dir ${MODEL_PATH}
|
||||
```
|
||||
### using the following system & software:
|
||||
```
|
||||
OS/Platform: Linux-4.15.0-76-generic-x86_64-with-debian-buster-sid
|
||||
GPU/CPU: 2 x NVIDIA 1080Ti / Intel i7-8700
|
||||
Transformers: 2.1.1
|
||||
PyTorch: 1.4.0
|
||||
TensorFlow: 2.1.0
|
||||
Python: 3.7.6
|
||||
```
|
||||
### Inferencing / prediction works with Transformers v2.4.1, the latest version tested
|
||||
|
||||
### Utilize this xlnet_large_squad2_512 fine-tuned model with:
|
||||
```python
|
||||
config_class, model_class, tokenizer_class = \
|
||||
XLNetConfig, XLNetforQuestionAnswering, XLNetTokenizer
|
||||
model_name_or_path = "ahotrod/xlnet_large_squad2_512"
|
||||
config = config_class.from_pretrained(model_name_or_path)
|
||||
tokenizer = tokenizer_class.from_pretrained(model_name_or_path, do_lower_case=True)
|
||||
model = model_class.from_pretrained(model_name_or_path, config=config)
|
||||
```
|
||||
### or the AutoModels (AutoConfig, AutoTokenizer & AutoModel) should also work, however I have yet to use them in my apps & confirm:
|
||||
```python
|
||||
from transformers import AutoConfig, AutoTokenizer, AutoModel
|
||||
model_name_or_path = "ahotrod/xlnet_large_squad2_512"
|
||||
config = AutoConfig.from_pretrained(model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, do_lower_case=True)
|
||||
model = AutoModel.from_pretrained(model_name_or_path, config=config)
|
||||
```
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
language: german
|
||||
thumbnail: https://static.tildacdn.com/tild6438-3730-4164-b266-613634323466/german_bert.png
|
||||
thumbnail: https://thumb.tildacdn.com/tild3330-3735-4461-b133-656238643834/-/format/webp/deepset_performance.png
|
||||
---
|
||||
|
||||
# German BERT
|
||||
|
||||
|
||||
## Overview
|
||||
**Language model:** bert-base-cased
|
||||
**Language:** German
|
||||
@@ -42,12 +42,12 @@ During training we monitored the loss and evaluated different model checkpoints
|
||||
- CONLL03: Seq f1 score for NER
|
||||
- 10kGNAD: Accuracy for document classification
|
||||
|
||||
Even without thorough hyperparameter tuning, we observed quite stable learning especially for our German model. Multiple restarts with different seeds produced quite similar results.
|
||||
|
||||
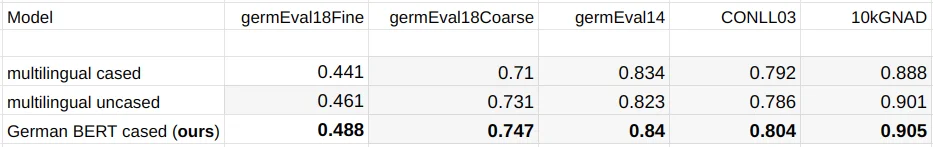
|
||||
Even without thorough hyperparameter tuning, we observed quite stable learning especially for our German model. Multiple restarts with different seeds produced quite similar results.
|
||||

|
||||
|
||||
While outperforming on 4 out of 5 task we wondered why the German BERT model did not outperform on CONLL03-de. So we compared English BERT with multilingual on CONLL03-en and found them to perform similar as well.
|
||||
|
||||
We further evaluated different points during the 9 days of pre-training and were astonished how fast the model converges to the maximally reachable performance. We ran all 5 downstream tasks on 7 different model checkpoints - taken at 0 up to 840k training steps (x-axis in figure below). Most checkpoints are taken from early training where we expected most performance changes. Surprisingly, even a randomly initialized BERT can be trained only on labeled downstream datasets and reach good performance (blue line, GermEval 2018 Coarse task, 795 kB trainset size).
|
||||
|
||||
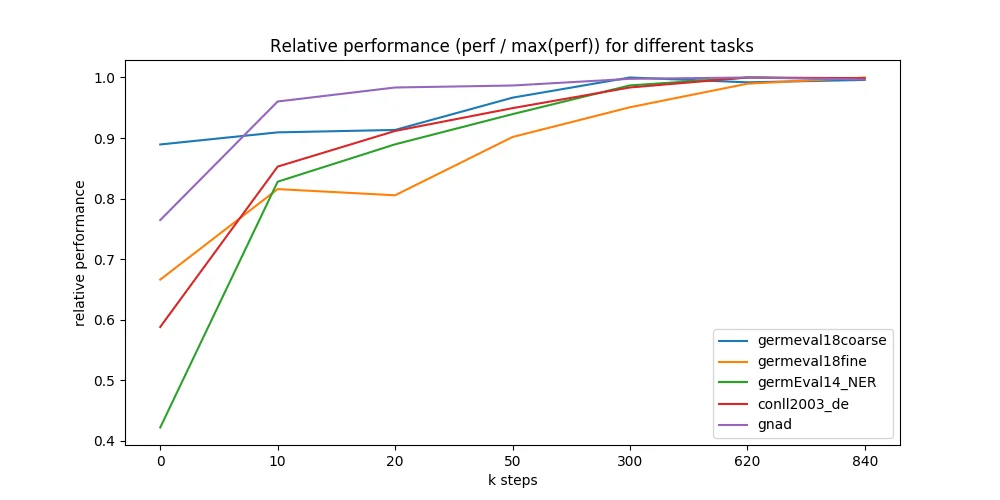
|
||||
|
||||
## Authors
|
||||
@@ -68,4 +68,4 @@ Some of our work:
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
@@ -1,5 +0,0 @@
|
||||
This model is pre-trained **XLNET** with 12 layers.
|
||||
|
||||
It comes with paper: SBERT-WK: A Sentence Embedding Method By Dissecting BERT-based Word Models
|
||||
|
||||
Project Page: [SBERT-WK](https://github.com/BinWang28/SBERT-WK-Sentence-Embedding)
|
||||
@@ -1,74 +0,0 @@
|
||||
---
|
||||
language: turkish
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Turkish BERT model
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources a cased model for Turkish 🎉
|
||||
|
||||
# 🇹🇷 BERTurk
|
||||
|
||||
BERTurk is a community-driven cased BERT model for Turkish.
|
||||
|
||||
Some datasets used for pretraining and evaluation are contributed from the
|
||||
awesome Turkish NLP community, as well as the decision for the model name: BERTurk.
|
||||
|
||||
## Stats
|
||||
|
||||
The current version of the model is trained on a filtered and sentence
|
||||
segmented version of the Turkish [OSCAR corpus](https://traces1.inria.fr/oscar/),
|
||||
a recent Wikipedia dump, various [OPUS corpora](http://opus.nlpl.eu/) and a
|
||||
special corpus provided by [Kemal Oflazer](http://www.andrew.cmu.edu/user/ko/).
|
||||
|
||||
The final training corpus has a size of 35GB and 44,04,976,662 tokens.
|
||||
|
||||
Thanks to Google's TensorFlow Research Cloud (TFRC) we could train a cased model
|
||||
on a TPU v3-8 for 2M steps.
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| --------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-turkish-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-turkish-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-turkish-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-turkish-cased/vocab.txt)
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our BERTurk cased model can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-turkish-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-turkish-cased")
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
For results on PoS tagging or NER tasks, please refer to
|
||||
[this repository](https://github.com/stefan-it/turkish-bert).
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Thanks to [Kemal Oflazer](http://www.andrew.cmu.edu/user/ko/) for providing us
|
||||
additional large corpora for Turkish. Many thanks to Reyyan Yeniterzi for providing
|
||||
us the Turkish NER dataset for evaluation.
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -1,48 +0,0 @@
|
||||
---
|
||||
language: french
|
||||
---
|
||||
|
||||
# flaubert-base-uncased-squad
|
||||
|
||||
## Description
|
||||
|
||||
A baseline model for question-answering in french ([flaubert](https://github.com/getalp/Flaubert) model fine-tuned on [french-translated SQuAD 1.1 dataset](https://github.com/Alikabbadj/French-SQuAD))
|
||||
|
||||
## Training hyperparameters
|
||||
|
||||
```shell
|
||||
python3 ./examples/run_squad.py \
|
||||
--model_type flaubert \
|
||||
--model_name_or_path flaubert-base-uncased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file SQuAD-v1.1-train_fr_ss999_awstart2_net.json \
|
||||
--predict_file SQuAD-v1.1-dev_fr_ss999_awstart2_net.json \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir output \
|
||||
--per_gpu_eval_batch_size=3 \
|
||||
--per_gpu_train_batch_size=3
|
||||
```
|
||||
|
||||
## Evaluation results
|
||||
|
||||
```shell
|
||||
{"f1": 68.66174806561969, "exact_match": 49.299692063176714}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline('question-answering', model='fmikaelian/flaubert-base-uncased-squad', tokenizer='fmikaelian/flaubert-base-uncased-squad')
|
||||
|
||||
nlp({
|
||||
'question': "Qui est Claude Monet?",
|
||||
'context': "Claude Monet, né le 14 novembre 1840 à Paris et mort le 5 décembre 1926 à Giverny, est un peintre français et l’un des fondateurs de l'impressionnisme."
|
||||
})
|
||||
```
|
||||
@@ -1,40 +0,0 @@
|
||||
---
|
||||
language: esperanto
|
||||
thumbnail: https://huggingface.co/blog/assets/EsperBERTo-thumbnail-v2.png
|
||||
---
|
||||
|
||||
# EsperBERTo: RoBERTa-like Language model trained on Esperanto
|
||||
|
||||
**Companion model to blog post https://huggingface.co/blog/how-to-train** 🔥
|
||||
|
||||
## Training Details
|
||||
|
||||
- current checkpoint: 566000
|
||||
- machine name: `galinette`
|
||||
|
||||
|
||||

|
||||
|
||||
## Example pipeline
|
||||
|
||||
```python
|
||||
from transformers import TokenClassificationPipeline, pipeline
|
||||
|
||||
|
||||
MODEL_PATH = "./models/EsperBERTo-small-pos/"
|
||||
|
||||
nlp = pipeline(
|
||||
"ner",
|
||||
model=MODEL_PATH,
|
||||
tokenizer=MODEL_PATH,
|
||||
)
|
||||
# or instantiate a TokenClassificationPipeline directly.
|
||||
|
||||
nlp("Mi estas viro kej estas tago varma.")
|
||||
|
||||
# {'entity': 'PRON', 'score': 0.9979867339134216, 'word': ' Mi'}
|
||||
# {'entity': 'VERB', 'score': 0.9683094620704651, 'word': ' estas'}
|
||||
# {'entity': 'VERB', 'score': 0.9797462821006775, 'word': ' estas'}
|
||||
# {'entity': 'NOUN', 'score': 0.8509314060211182, 'word': ' tago'}
|
||||
# {'entity': 'ADJ', 'score': 0.9996201395988464, 'word': ' varma'}
|
||||
```
|
||||
@@ -1,59 +0,0 @@
|
||||
---
|
||||
language: esperanto
|
||||
thumbnail: https://huggingface.co/blog/assets/EsperBERTo-thumbnail-v2.png
|
||||
---
|
||||
|
||||
# EsperBERTo: RoBERTa-like Language model trained on Esperanto
|
||||
|
||||
**Companion model to blog post https://huggingface.co/blog/how-to-train** 🔥
|
||||
|
||||
## Training Details
|
||||
|
||||
- current checkpoint: 566000
|
||||
- machine name: `galinette`
|
||||
|
||||
|
||||

|
||||
|
||||
## Example pipeline
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
fill_mask = pipeline(
|
||||
"fill-mask",
|
||||
model="julien-c/EsperBERTo-small",
|
||||
tokenizer="julien-c/EsperBERTo-small"
|
||||
)
|
||||
|
||||
fill_mask("Jen la komenco de bela <mask>.")
|
||||
|
||||
# This is the beginning of a beautiful <mask>.
|
||||
# =>
|
||||
|
||||
# {
|
||||
# 'score':0.06502299010753632
|
||||
# 'sequence':'<s> Jen la komenco de bela vivo.</s>'
|
||||
# 'token':1099
|
||||
# }
|
||||
# {
|
||||
# 'score':0.0421181358397007
|
||||
# 'sequence':'<s> Jen la komenco de bela vespero.</s>'
|
||||
# 'token':5100
|
||||
# }
|
||||
# {
|
||||
# 'score':0.024884626269340515
|
||||
# 'sequence':'<s> Jen la komenco de bela laboro.</s>'
|
||||
# 'token':1570
|
||||
# }
|
||||
# {
|
||||
# 'score':0.02324388362467289
|
||||
# 'sequence':'<s> Jen la komenco de bela tago.</s>'
|
||||
# 'token':1688
|
||||
# }
|
||||
# {
|
||||
# 'score':0.020378097891807556
|
||||
# 'sequence':'<s> Jen la komenco de bela festo.</s>'
|
||||
# 'token':4580
|
||||
# }
|
||||
```
|
||||
@@ -1,58 +0,0 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# Spanish BERT (BETO) + NER
|
||||
|
||||
This model is a fine-tuned on [NER-C](https://www.kaggle.com/nltkdata/conll-corpora) of the Spanish BERT cased [(BETO)](https://github.com/dccuchile/beto) for **NER** downstream task.
|
||||
|
||||
## Details of the downstream task (NER) - Dataset
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora)
|
||||
|
||||
I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
|
||||
| Dataset | # Examples |
|
||||
| ---------------------- | ----- |
|
||||
| Train | 8.7 K |
|
||||
| Dev | 2.2 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
```bash
|
||||
!export NER_DIR='/content/ner_dataset'
|
||||
!python /content/transformers/examples/run_ner.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--data_dir '/content/ner_dataset' \
|
||||
--num_train_epochs 15.0 \
|
||||
--max_seq_length 384 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
|
||||
```
|
||||
|
||||
## Comparison:
|
||||
|
||||
| Model | # score |
|
||||
| :--------------------------------------------------------------------------------------------------------------: | :-------: |
|
||||
| bert-base-spanish-wwm-cased (BETO) | 88.43 |
|
||||
| [bert-spanish-cased-finetuned-ner (this one)](https://huggingface.co/mrm8488/bert-spanish-cased-finetuned-ner) | **89.65** |
|
||||
| Best Multilingual BERT | 87.38 |
|
||||
|
||||
```
|
||||
***** All metrics on Eval results *****
|
||||
|
||||
f1 = 0.8965040489828165
|
||||
loss = 0.11504213575173258
|
||||
precision = 0.893679858239811
|
||||
recall = 0.8993461462254805
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -1,80 +0,0 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# Spanish BERT (BETO) + POS
|
||||
|
||||
This model is a fine-tuned on [NER-C](https://www.kaggle.com/nltkdata/conll-corpora) Of the Spanish BERT cased [(BETO)](https://github.com/dccuchile/beto) for **POS** (Part of Speech tagging) downstream task.
|
||||
|
||||
## Details of the downstream task (POS) - Dataset
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora) with data augmentation techniques
|
||||
|
||||
I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
|
||||
| Dataset | # Examples |
|
||||
| ---------------------- | ----- |
|
||||
| Train | 340 K |
|
||||
| Dev | 50 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
```
|
||||
AO, AQ, CC, CS, DA, DD, DE, DI, DN, DP, DT, Faa, Fat, Fc, Fd, Fe, Fg, Fh, Fia, Fit, Fp, Fpa, Fpt, Fs, Ft, Fx, Fz, I, NC, NP, P0, PD, PI, PN, PP, PR, PT, PX, RG, RN, SP, VAI, VAM, VAN, VAP, VAS, VMG, VMI, VMM, VMN, VMP, VMS, VSG, VSI, VSM, VSN, VSP, VSS, Y and Z
|
||||
```
|
||||
|
||||
|
||||
## Metrics on evaluation set:
|
||||
|
||||
| Metric | # score |
|
||||
| :------------------------------------------------------------------------------------: | :-------: |
|
||||
| F1 | **90.06**
|
||||
| Precision | **89.46** |
|
||||
| Recall | **90.67** |
|
||||
|
||||
## Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp_pos = pipeline(
|
||||
"ner",
|
||||
model="mrm8488/bert-spanish-cased-finetuned-pos",
|
||||
tokenizer=(
|
||||
'mrm8488/bert-spanish-cased-finetuned-pos',
|
||||
{"use_fast": False}
|
||||
))
|
||||
|
||||
|
||||
text = 'Mis amigos están pensando en viajar a Londres este verano'
|
||||
|
||||
nlp_pos(text)
|
||||
|
||||
#Output:
|
||||
'''
|
||||
[{'entity': 'NC', 'score': 0.7792173624038696, 'word': '[CLS]'},
|
||||
{'entity': 'DP', 'score': 0.9996283650398254, 'word': 'Mis'},
|
||||
{'entity': 'NC', 'score': 0.9999253749847412, 'word': 'amigos'},
|
||||
{'entity': 'VMI', 'score': 0.9998560547828674, 'word': 'están'},
|
||||
{'entity': 'VMG', 'score': 0.9992249011993408, 'word': 'pensando'},
|
||||
{'entity': 'SP', 'score': 0.9999602437019348, 'word': 'en'},
|
||||
{'entity': 'VMN', 'score': 0.9998666048049927, 'word': 'viajar'},
|
||||
{'entity': 'SP', 'score': 0.9999545216560364, 'word': 'a'},
|
||||
{'entity': 'VMN', 'score': 0.8722310662269592, 'word': 'Londres'},
|
||||
{'entity': 'DD', 'score': 0.9995203614234924, 'word': 'este'},
|
||||
{'entity': 'NC', 'score': 0.9999248385429382, 'word': 'verano'},
|
||||
{'entity': 'NC', 'score': 0.8802427649497986, 'word': '[SEP]'}]
|
||||
'''
|
||||
```
|
||||
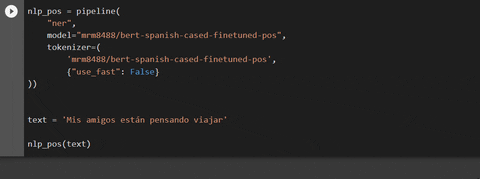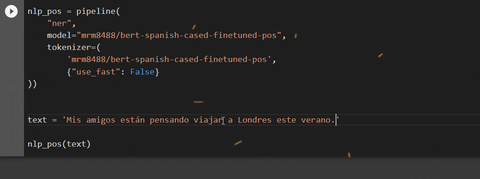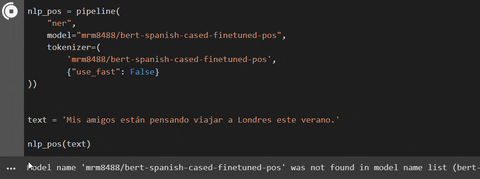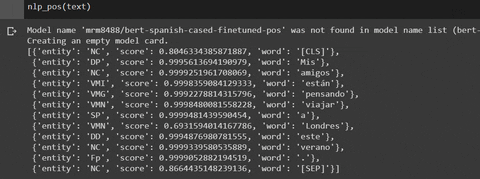
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
-141
@@ -1,141 +0,0 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# BETO (Spanish BERT) + Spanish SQuAD2.0 + distillation using 'bert-base-multilingual-cased' as teacher
|
||||
|
||||
This model is a fine-tuned on [SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve) and **distilled** version of [BETO](https://github.com/dccuchile/beto) for **Q&A**.
|
||||
|
||||
Distillation makes the model **smaller, faster, cheaper and lighter** than [bert-base-spanish-wwm-cased-finetuned-spa-squad2-es](https://github.com/huggingface/transformers/blob/master/model_cards/mrm8488/bert-base-spanish-wwm-cased-finetuned-spa-squad2-es/README.md)
|
||||
|
||||
This model was fine-tuned on the same dataset but using **distillation** during the process as mentioned above (and one more train epoch).
|
||||
|
||||
The **teacher model** for the distillation was `bert-base-multilingual-cased`. It is the same teacher used for `distilbert-base-multilingual-cased` AKA [**DistilmBERT**](https://github.com/huggingface/transformers/tree/master/examples/distillation) (on average is twice as fast as **mBERT-base**).
|
||||
|
||||
## Details of the downstream task (Q&A) - Dataset
|
||||
|
||||
<details>
|
||||
|
||||
[SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve)
|
||||
|
||||
| Dataset | # Q&A |
|
||||
| ----------------------- | ----- |
|
||||
| SQuAD2.0 Train | 130 K |
|
||||
| SQuAD2.0-es-v2.0 | 111 K |
|
||||
| SQuAD2.0 Dev | 12 K |
|
||||
| SQuAD-es-v2.0-small Dev | 69 K |
|
||||
|
||||
</details>
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||
|
||||
```bash
|
||||
!export SQUAD_DIR=/path/to/squad-v2_spanish \
|
||||
&& python transformers/examples/distillation/run_squad_w_distillation.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--teacher_type bert \
|
||||
--teacher_name_or_path bert-base-multilingual-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file $SQUAD_DIR/train-v2.json \
|
||||
--predict_file $SQUAD_DIR/dev-v2.json \
|
||||
--per_gpu_train_batch_size 12 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 5.0 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
--threads 4 \
|
||||
--version_2_with_negative
|
||||
```
|
||||
|
||||
## Results:
|
||||
|
||||
| Metric | # Value |
|
||||
| --------- | ----------- |
|
||||
| **Exact** | **90.77**48 |
|
||||
| **F1** | **94.94**71 |
|
||||
|
||||
```json
|
||||
{
|
||||
"exact": 90.77483309730933,
|
||||
"f1": 94.94714391266254,
|
||||
"total": 69202,
|
||||
"HasAns_exact": 86.60850599781898,
|
||||
"HasAns_f1": 92.90582885592328,
|
||||
"HasAns_total": 45850,
|
||||
"NoAns_exact": 98.95512161699212,
|
||||
"NoAns_f1": 98.95512161699212,
|
||||
"NoAns_total": 23352,
|
||||
"best_exact": 90.77483309730933,
|
||||
"best_exact_thresh": 0.0,
|
||||
"best_f1": 94.94714391266305,
|
||||
"best_f1_thresh": 0.0
|
||||
}
|
||||
```
|
||||
|
||||
## Comparison:
|
||||
|
||||
| Model | f1 score |
|
||||
| :-------------------------------------------------------------: | :-------: |
|
||||
| bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | 86.07 |
|
||||
| **distill**-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | **94.94** |
|
||||
|
||||
So, yes, this version is even more accurate.
|
||||
|
||||
### Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import *
|
||||
|
||||
# Important!: By now the QA pipeline is not compatible with fast tokenizer, but they are working on it. So that pass the object to the tokenizer {"use_fast": False} as in the following example:
|
||||
|
||||
nlp = pipeline(
|
||||
'question-answering',
|
||||
model='mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es',
|
||||
tokenizer=(
|
||||
'mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es',
|
||||
{"use_fast": False}
|
||||
)
|
||||
)
|
||||
|
||||
nlp(
|
||||
{
|
||||
'question': '¿Para qué lenguaje está trabajando?',
|
||||
'context': 'Manuel Romero está colaborando activamente con huggingface/transformers ' +
|
||||
'para traer el poder de las últimas técnicas de procesamiento de lenguaje natural al idioma español'
|
||||
}
|
||||
)
|
||||
# Output: {'answer': 'español', 'end': 169, 'score': 0.67530957344621, 'start': 163}
|
||||
```
|
||||
|
||||
Play with this model and ```pipelines``` in a Colab:
|
||||
|
||||
<a href="https://colab.research.google.com/github/mrm8488/shared_colab_notebooks/blob/master/Using_Spanish_BERT_fine_tuned_for_Q%26A_pipelines.ipynb" target="_parent"><img src="https://camo.githubusercontent.com/52feade06f2fecbf006889a904d221e6a730c194/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open In Colab" data-canonical-src="https://colab.research.google.com/assets/colab-badge.svg"></a>
|
||||
|
||||
<details>
|
||||
|
||||
1. Set the context and ask some questions:
|
||||
|
||||
|
||||
|
||||
2. Run predictions:
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
More about ``` Huggingface pipelines```? check this Colab out:
|
||||
|
||||
<a href="https://colab.research.google.com/github/mrm8488/shared_colab_notebooks/blob/master/Huggingface_pipelines_demo.ipynb" target="_parent"><img src="https://camo.githubusercontent.com/52feade06f2fecbf006889a904d221e6a730c194/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open In Colab" data-canonical-src="https://colab.research.google.com/assets/colab-badge.svg"></a>
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -1,134 +0,0 @@
|
||||
---
|
||||
language: greek
|
||||
thumbnail: https://github.com/nlpaueb/GreekBERT/raw/master/greek-bert-logo.png
|
||||
---
|
||||
|
||||
# GreekBERT
|
||||
|
||||
A Greek version of BERT pre-trained language model.
|
||||
|
||||
<img src="https://github.com/nlpaueb/GreekBERT/raw/master/greek-bert-logo.png" width="600"/>
|
||||
|
||||
|
||||
## Pre-training corpora
|
||||
|
||||
The pre-training corpora of `bert-base-greek-uncased-v1` include:
|
||||
|
||||
* The Greek part of [Wikipedia](https://el.wikipedia.org/wiki/Βικιπαίδεια:Αντίγραφα_της_βάσης_δεδομένων),
|
||||
* The Greek part of [European Parliament Proceedings Parallel Corpus](https://www.statmt.org/europarl/), and
|
||||
* The Greek part of [OSCAR](https://traces1.inria.fr/oscar/), a cleansed version of [Common Crawl](https://commoncrawl.org).
|
||||
|
||||
Future release will also include:
|
||||
|
||||
* The entire corpus of Greek legislation, as published by the [National Publication Office](http://www.et.gr),
|
||||
* The entire corpus of EU legislation (Greek translation), as published in [Eur-Lex](https://eur-lex.europa.eu/homepage.html?locale=en).
|
||||
|
||||
## Pre-training details
|
||||
|
||||
* We trained BERT using the official code provided in Google BERT's github repository (https://github.com/google-research/bert). We then used [Hugging Face](https://huggingface.co)'s [Transformers](https://github.com/huggingface/transformers) conversion script to convert the TF checkpoint and vocabulary in the desirable format in order to be able to load the model in two lines of code for both PyTorch and TF2 users.
|
||||
* We released a model similar to the English `bert-base-uncased` model (12-layer, 768-hidden, 12-heads, 110M parameters).
|
||||
* We chose to follow the same training set-up: 1 million training steps with batches of 256 sequences of length 512 with an initial learning rate 1e-4.
|
||||
* We were able to use a single Google Cloud TPU v3-8 provided for free from [TensorFlow Research Cloud (TFRC)](https://www.tensorflow.org/tfrc), while also utilizing [GCP research credits](https://edu.google.com/programs/credits/research). Huge thanks to both Google programs for supporting us!
|
||||
|
||||
|
||||
## Requirements
|
||||
|
||||
We published `bert-base-greek-uncased-v1` as part of [Hugging Face](https://huggingface.co)'s [Transformers](https://github.com/huggingface/transformers) repository. So, you need to install the transfomers library through pip along with PyTorch or Tensorflow 2.
|
||||
|
||||
```
|
||||
pip install transfomers
|
||||
pip install (torch|tensorflow)
|
||||
```
|
||||
|
||||
## Pre-process text (Deaccent - Lower)
|
||||
|
||||
In order to use `bert-base-greek-uncased-v1`, you have to pre-process texts to lowercase letters and remove all Greek diacritics.
|
||||
|
||||
```python
|
||||
|
||||
import unicodedata
|
||||
|
||||
def strip_accents_and_lowercase(s):
|
||||
return ''.join(c for c in unicodedata.normalize('NFD', s)
|
||||
if unicodedata.category(c) != 'Mn').lower()
|
||||
|
||||
accented_string = "Αυτή είναι η Ελληνική έκδοση του BERT."
|
||||
unaccented_string = strip_accents_and_lowercase(accented_string)
|
||||
|
||||
print(unaccented_string) # αυτη ειναι η ελληνικη εκδοση του bert.
|
||||
|
||||
```
|
||||
|
||||
## Load Pretrained Model
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("nlpaueb/bert-base-greek-uncased-v1")
|
||||
model = AutoModel.from_pretrained("nlpaueb/bert-base-greek-uncased-v1")
|
||||
```
|
||||
|
||||
## Use Pretrained Model as a Language Model
|
||||
|
||||
```python
|
||||
import torch
|
||||
from transformers import *
|
||||
|
||||
# Load model and tokenizer
|
||||
tokenizer_greek = AutoTokenizer.from_pretrained('nlpaueb/bert-base-greek-uncased-v1')
|
||||
lm_model_greek = AutoModelWithLMHead.from_pretrained('nlpaueb/bert-base-greek-uncased-v1')
|
||||
|
||||
# ================ EXAMPLE 1 ================
|
||||
text_1 = 'O ποιητής έγραψε ένα [MASK] .'
|
||||
# EN: 'The poet wrote a [MASK].'
|
||||
input_ids = tokenizer_greek.encode(text_1)
|
||||
print(tokenizer_greek.convert_ids_to_tokens(input_ids))
|
||||
# ['[CLS]', 'o', 'ποιητης', 'εγραψε', 'ενα', '[MASK]', '.', '[SEP]']
|
||||
outputs = lm_model_greek(torch.tensor([input_ids]))[0]
|
||||
print(tokenizer_greek.convert_ids_to_tokens(outputs[0, 5].max(0)[1].item()))
|
||||
# the most plausible prediction for [MASK] is "song"
|
||||
|
||||
# ================ EXAMPLE 2 ================
|
||||
text_2 = 'Είναι ένας [MASK] άνθρωπος.'
|
||||
# EN: 'He is a [MASK] person.'
|
||||
input_ids = tokenizer_greek.encode(text_1)
|
||||
print(tokenizer_greek.convert_ids_to_tokens(input_ids))
|
||||
# ['[CLS]', 'ειναι', 'ενας', '[MASK]', 'ανθρωπος', '.', '[SEP]']
|
||||
outputs = lm_model_greek(torch.tensor([input_ids]))[0]
|
||||
print(tokenizer_greek.convert_ids_to_tokens(outputs[0, 3].max(0)[1].item()))
|
||||
# the most plausible prediction for [MASK] is "good"
|
||||
|
||||
# ================ EXAMPLE 3 ================
|
||||
text_3 = 'Είναι ένας [MASK] άνθρωπος και κάνει συχνά [MASK].'
|
||||
# EN: 'He is a [MASK] person he does frequently [MASK].'
|
||||
input_ids = tokenizer_greek.encode(text_3)
|
||||
print(tokenizer_greek.convert_ids_to_tokens(input_ids))
|
||||
# ['[CLS]', 'ειναι', 'ενας', '[MASK]', 'ανθρωπος', 'και', 'κανει', 'συχνα', '[MASK]', '.', '[SEP]']
|
||||
outputs = lm_model_greek(torch.tensor([input_ids]))[0]
|
||||
print(tokenizer_greek.convert_ids_to_tokens(outputs[0, 8].max(0)[1].item()))
|
||||
# the most plausible prediction for the second [MASK] is "trips"
|
||||
```
|
||||
|
||||
## Evaluation on downstream tasks
|
||||
|
||||
TBA
|
||||
|
||||
## Author
|
||||
|
||||
Ilias Chalkidis on behalf of [AUEB's Natural Language Processing Group](http://nlp.cs.aueb.gr)
|
||||
|
||||
| Github: [@ilias.chalkidis](https://github.com/seolhokim) | Twitter: [@KiddoThe2B](https://twitter.com/KiddoThe2B) |
|
||||
|
||||
## About Us
|
||||
|
||||
[AUEB's Natural Language Processing Group](http://nlp.cs.aueb.gr) develops algorithms, models, and systems that allow computers to process and generate natural language texts.
|
||||
|
||||
The group's current research interests include:
|
||||
* question answering systems for databases, ontologies, document collections, and the Web, especially biomedical question answering,
|
||||
* natural language generation from databases and ontologies, especially Semantic Web ontologies,
|
||||
text classification, including filtering spam and abusive content,
|
||||
* information extraction and opinion mining, including legal text analytics and sentiment analysis,
|
||||
* natural language processing tools for Greek, for example parsers and named-entity recognizers,
|
||||
machine learning in natural language processing, especially deep learning.
|
||||
|
||||
The group is part of the Information Processing Laboratory of the Department of Informatics of the Athens University of Economics and Business.
|
||||
@@ -1,49 +0,0 @@
|
||||
---
|
||||
language:
|
||||
- english
|
||||
- dutch
|
||||
- german
|
||||
- french
|
||||
- italian
|
||||
- spanish
|
||||
---
|
||||
|
||||
# bert-base-multilingual-uncased-sentiment
|
||||
|
||||
This a bert-base-multilingual-uncased model finetuned for sentiment analysis on product reviews in six languages: English, Dutch, German, French, Spanish and Italian. It predicts the sentiment of the review as a number of stars (between 1 and 5).
|
||||
|
||||
This model is intended for direct use as a sentiment analysis model for product reviews in any of the six languages above, or for further finetuning on related sentiment analysis tasks.
|
||||
|
||||
## Training data
|
||||
|
||||
Here is the number of product reviews we used for finetuning the model:
|
||||
|
||||
| Language | Number of reviews |
|
||||
| -------- | ----------------- |
|
||||
| English | 150k |
|
||||
| Dutch | 80k |
|
||||
| German | 137k |
|
||||
| French | 140k |
|
||||
| Italian | 72k |
|
||||
| Spanish | 50k |
|
||||
|
||||
## Accuracy
|
||||
|
||||
The finetuned model obtained the following accuracy on 5,000 held-out product reviews in each of the languages:
|
||||
|
||||
- Accuracy (exact) is the exact match on the number of stars.
|
||||
- Accuracy (off-by-1) is the percentage of reviews where the number of stars the model predicts differs by a maximum of 1 from the number given by the human reviewer.
|
||||
|
||||
|
||||
| Language | Accuracy (exact) | Accuracy (off-by-1) |
|
||||
| -------- | ---------------------- | ------------------- |
|
||||
| English | 67% | 95%
|
||||
| Dutch | 57% | 93%
|
||||
| German | 61% | 94%
|
||||
| French | 59% | 94%
|
||||
| Italian | 59% | 95%
|
||||
| Spanish | 58% | 95%
|
||||
|
||||
## Contact
|
||||
|
||||
Contact [NLP Town](https://www.nlp.town) for questions, feedback and/or requests for similar models.
|
||||
@@ -1,51 +0,0 @@
|
||||
---
|
||||
language: german
|
||||
thumbnail: kfold.png
|
||||
---
|
||||
|
||||
# German BERT for literary texts
|
||||
|
||||
This German BERT is based on `bert-base-german-dbmdz-cased`, and has been adapted to the domain of literary texts by fine-tuning the language modeling task on the [Corpus of German-Language Fiction](https://figshare.com/articles/Corpus_of_German-Language_Fiction_txt_/4524680/1). Afterwards the model was fine-tuned for named entity recognition on the [DROC](https://gitlab2.informatik.uni-wuerzburg.de/kallimachos/DROC-Release) corpus, so you can use it to recognize protagonists in German novels.
|
||||
|
||||
|
||||
# Stats
|
||||
|
||||
## Language modeling
|
||||
|
||||
The [Corpus of German-Language Fiction](https://figshare.com/articles/Corpus_of_German-Language_Fiction_txt_/4524680/1) consists of 3,194 documents with 203,516,988 tokens or 1,520,855 types. The publication year of the texts ranges from the 18th to the 20th century:
|
||||
|
||||

|
||||
|
||||
|
||||
### Results
|
||||
|
||||
After one epoch:
|
||||
|
||||
| Model | Perplexity |
|
||||
| ---------------- | ---------- |
|
||||
| Vanilla BERT | 6.82 |
|
||||
| Fine-tuned BERT | 4.98 |
|
||||
|
||||
|
||||
## Named entity recognition
|
||||
|
||||
The provided model was also fine-tuned for two epochs on 10,799 sentences for training, validated on 547 and tested on 1,845 with three labels: `B-PER`, `I-PER` and `O`.
|
||||
|
||||
|
||||
## Results
|
||||
|
||||
| Dataset | Precision | Recall | F1 |
|
||||
| ------- | --------- | ------ | ---- |
|
||||
| Dev | 96.4 | 87.3 | 91.6 |
|
||||
| Test | 92.8 | 94.9 | 93.8 |
|
||||
|
||||
The model has also been evaluated using 10-fold cross validation and compared with a classic Conditional Random Field baseline described in [Jannidis et al.](https://opus.bibliothek.uni-wuerzburg.de/opus4-wuerzburg/frontdoor/deliver/index/docId/14333/file/Jannidis_Figurenerkennung_Roman.pdf) (2015):
|
||||
|
||||

|
||||
|
||||
|
||||
# References
|
||||
|
||||
Markus Krug, Lukas Weimer, Isabella Reger, Luisa Macharowsky, Stephan Feldhaus, Frank Puppe, Fotis Jannidis, [Description of a Corpus of Character References in German Novels](http://webdoc.sub.gwdg.de/pub/mon/dariah-de/dwp-2018-27.pdf), 2018.
|
||||
|
||||
Fotis Jannidis, Isabella Reger, Lukas Weimer, Markus Krug, Martin Toepfer, Frank Puppe, [Automatische Erkennung von Figuren in deutschsprachigen Romanen](https://opus.bibliothek.uni-wuerzburg.de/opus4-wuerzburg/frontdoor/deliver/index/docId/14333/file/Jannidis_Figurenerkennung_Roman.pdf), 2015.
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 5.6 KiB |

Binary file not shown.
|
Before Width: | Height: | Size: 21 KiB |
@@ -15,7 +15,6 @@ known_third_party =
|
||||
packaging
|
||||
PIL
|
||||
psutil
|
||||
pytorch_lightning
|
||||
seqeval
|
||||
sklearn
|
||||
tensorboardX
|
||||
@@ -24,7 +23,6 @@ known_third_party =
|
||||
torch
|
||||
torchtext
|
||||
torchvision
|
||||
torch_xla
|
||||
|
||||
line_length = 119
|
||||
lines_after_imports = 2
|
||||
|
||||
@@ -34,9 +34,6 @@ To create the package for pypi.
|
||||
|
||||
7. Copy the release notes from RELEASE.md to the tag in github once everything is looking hunky-dory.
|
||||
|
||||
8. Update the documentation commit in .circleci/deploy.sh for the accurate documentation to be displayed
|
||||
|
||||
9. Update README.md to redirect to correct documentation.
|
||||
"""
|
||||
|
||||
import shutil
|
||||
@@ -79,8 +76,8 @@ extras["dev"] = extras["testing"] + extras["quality"] + ["mecab-python3", "sciki
|
||||
|
||||
setup(
|
||||
name="transformers",
|
||||
version="2.5.1",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Sam Shleifer, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
version="2.4.1",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
author_email="thomas@huggingface.co",
|
||||
description="State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch",
|
||||
long_description=open("README.md", "r", encoding="utf-8").read(),
|
||||
@@ -92,7 +89,7 @@ setup(
|
||||
packages=find_packages("src"),
|
||||
install_requires=[
|
||||
"numpy",
|
||||
"tokenizers == 0.5.2",
|
||||
"tokenizers == 0.0.11",
|
||||
# accessing files from S3 directly
|
||||
"boto3",
|
||||
# filesystem locks e.g. to prevent parallel downloads
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# There's no way to ignore "F401 '...' imported but unused" warnings in this
|
||||
# module, but to preserve other warnings. So, don't check this module at all.
|
||||
|
||||
__version__ = "2.5.1"
|
||||
__version__ = "2.4.1"
|
||||
|
||||
# Work around to update TensorFlow's absl.logging threshold which alters the
|
||||
# default Python logging output behavior when present.
|
||||
@@ -21,7 +21,6 @@ import logging
|
||||
|
||||
from .configuration_albert import ALBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, AlbertConfig
|
||||
from .configuration_auto import ALL_PRETRAINED_CONFIG_ARCHIVE_MAP, AutoConfig
|
||||
from .configuration_bart import BartConfig
|
||||
from .configuration_bert import BERT_PRETRAINED_CONFIG_ARCHIVE_MAP, BertConfig
|
||||
from .configuration_camembert import CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, CamembertConfig
|
||||
from .configuration_ctrl import CTRL_PRETRAINED_CONFIG_ARCHIVE_MAP, CTRLConfig
|
||||
@@ -102,23 +101,21 @@ from .pipelines import (
|
||||
PipelineDataFormat,
|
||||
QuestionAnsweringPipeline,
|
||||
TextClassificationPipeline,
|
||||
TokenClassificationPipeline,
|
||||
pipeline,
|
||||
)
|
||||
from .tokenization_albert import AlbertTokenizer
|
||||
from .tokenization_auto import AutoTokenizer
|
||||
from .tokenization_bart import BartTokenizer
|
||||
from .tokenization_bert import BasicTokenizer, BertTokenizer, BertTokenizerFast, WordpieceTokenizer
|
||||
from .tokenization_bert_japanese import BertJapaneseTokenizer, CharacterTokenizer, MecabTokenizer
|
||||
from .tokenization_camembert import CamembertTokenizer
|
||||
from .tokenization_ctrl import CTRLTokenizer
|
||||
from .tokenization_distilbert import DistilBertTokenizer, DistilBertTokenizerFast
|
||||
from .tokenization_distilbert import DistilBertTokenizer
|
||||
from .tokenization_flaubert import FlaubertTokenizer
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer, OpenAIGPTTokenizerFast
|
||||
from .tokenization_roberta import RobertaTokenizer, RobertaTokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer
|
||||
from .tokenization_roberta import RobertaTokenizer
|
||||
from .tokenization_t5 import T5Tokenizer
|
||||
from .tokenization_transfo_xl import TransfoXLCorpus, TransfoXLTokenizer, TransfoXLTokenizerFast
|
||||
from .tokenization_transfo_xl import TransfoXLCorpus, TransfoXLTokenizer
|
||||
|
||||
# Tokenizers
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
@@ -206,7 +203,6 @@ if is_torch_available():
|
||||
XLMForQuestionAnsweringSimple,
|
||||
XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_bart import BartForSequenceClassification, BartModel, BartForMaskedLM
|
||||
from .modeling_roberta import (
|
||||
RobertaForMaskedLM,
|
||||
RobertaModel,
|
||||
@@ -221,7 +217,6 @@ if is_torch_available():
|
||||
CamembertModel,
|
||||
CamembertForSequenceClassification,
|
||||
CamembertForTokenClassification,
|
||||
CamembertForQuestionAnswering,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_distilbert import (
|
||||
|
||||
@@ -18,10 +18,7 @@ def _gelu_python(x):
|
||||
return x * 0.5 * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
if torch.__version__ < "1.4.0":
|
||||
gelu = _gelu_python
|
||||
else:
|
||||
gelu = F.gelu
|
||||
gelu = getattr(F, "gelu", _gelu_python)
|
||||
|
||||
|
||||
def gelu_new(x):
|
||||
|
||||
@@ -19,7 +19,6 @@ import logging
|
||||
from collections import OrderedDict
|
||||
|
||||
from .configuration_albert import ALBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, AlbertConfig
|
||||
from .configuration_bart import BART_PRETRAINED_CONFIG_ARCHIVE_MAP, BartConfig
|
||||
from .configuration_bert import BERT_PRETRAINED_CONFIG_ARCHIVE_MAP, BertConfig
|
||||
from .configuration_camembert import CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, CamembertConfig
|
||||
from .configuration_ctrl import CTRL_PRETRAINED_CONFIG_ARCHIVE_MAP, CTRLConfig
|
||||
@@ -43,7 +42,6 @@ ALL_PRETRAINED_CONFIG_ARCHIVE_MAP = dict(
|
||||
(key, value)
|
||||
for pretrained_map in [
|
||||
BERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
BART_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
OPENAI_GPT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
TRANSFO_XL_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
GPT2_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
@@ -69,7 +67,6 @@ CONFIG_MAPPING = OrderedDict(
|
||||
("albert", AlbertConfig,),
|
||||
("camembert", CamembertConfig,),
|
||||
("xlm-roberta", XLMRobertaConfig,),
|
||||
("bart", BartConfig,),
|
||||
("roberta", RobertaConfig,),
|
||||
("flaubert", FlaubertConfig,),
|
||||
("bert", BertConfig,),
|
||||
|
||||
@@ -1,101 +0,0 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2020 The Fairseq Authors and The HuggingFace Inc. team.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" BART configuration """
|
||||
|
||||
|
||||
import logging
|
||||
|
||||
from .configuration_utils import PretrainedConfig
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_bart_large_url = "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large/config.json"
|
||||
BART_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"bart-large": _bart_large_url,
|
||||
"bart-large-mnli": _bart_large_url, # fine as same
|
||||
"bart-cnn": None, # not done
|
||||
}
|
||||
|
||||
|
||||
class BartConfig(PretrainedConfig):
|
||||
r"""
|
||||
Configuration class for Bart. Parameters are renamed from the fairseq implementation
|
||||
"""
|
||||
model_type = "bart"
|
||||
pretrained_config_archive_map = BART_PRETRAINED_CONFIG_ARCHIVE_MAP
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
activation_dropout=0.0,
|
||||
vocab_size=50265,
|
||||
pad_token_id=1,
|
||||
eos_token_id=2,
|
||||
d_model=1024,
|
||||
encoder_ffn_dim=4096,
|
||||
encoder_layers=12,
|
||||
encoder_attention_heads=16,
|
||||
decoder_ffn_dim=4096,
|
||||
decoder_layers=12,
|
||||
decoder_attention_heads=16,
|
||||
encoder_layerdrop=0.0,
|
||||
decoder_layerdrop=0.0,
|
||||
attention_dropout=0.0,
|
||||
dropout=0.1,
|
||||
max_position_embeddings=1024,
|
||||
init_std=0.02,
|
||||
classifier_dropout=0.0,
|
||||
output_past=False,
|
||||
num_labels=3,
|
||||
**common_kwargs
|
||||
):
|
||||
r"""
|
||||
:class:`~transformers.BartConfig` is the configuration class for `BartModel`.
|
||||
Examples:
|
||||
config = BartConfig.from_pretrained('bart-large')
|
||||
model = BartModel(config)
|
||||
"""
|
||||
super().__init__(num_labels=num_labels, output_past=output_past, pad_token_id=pad_token_id, **common_kwargs)
|
||||
|
||||
self.vocab_size = vocab_size
|
||||
self.d_model = d_model # encoder_embed_dim and decoder_embed_dim
|
||||
self.eos_token_id = eos_token_id
|
||||
|
||||
self.encoder_ffn_dim = encoder_ffn_dim
|
||||
self.encoder_layers = self.num_hidden_layers = encoder_layers
|
||||
self.encoder_attention_heads = encoder_attention_heads
|
||||
self.encoder_layerdrop = encoder_layerdrop
|
||||
self.decoder_layerdrop = decoder_layerdrop
|
||||
self.decoder_ffn_dim = decoder_ffn_dim
|
||||
self.decoder_layers = decoder_layers
|
||||
self.decoder_attention_heads = decoder_attention_heads
|
||||
self.max_position_embeddings = max_position_embeddings
|
||||
self.init_std = init_std # Normal(0, this parameter)
|
||||
|
||||
# 3 Types of Dropout
|
||||
self.attention_dropout = attention_dropout
|
||||
self.activation_dropout = activation_dropout
|
||||
self.dropout = dropout
|
||||
|
||||
# Classifier stuff
|
||||
self.classif_dropout = classifier_dropout
|
||||
|
||||
@property
|
||||
def num_attention_heads(self):
|
||||
return self.encoder_attention_heads
|
||||
|
||||
@property
|
||||
def hidden_size(self):
|
||||
return self.d_model
|
||||
@@ -109,12 +109,11 @@ class FlaubertConfig(XLMConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
|
||||
@@ -73,12 +73,11 @@ class GPT2Config(PretrainedConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.GPT2DoubleHeadsModel`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.GPT2DoubleHeadsModel`.
|
||||
|
||||
@@ -73,12 +73,11 @@ class OpenAIGPTConfig(PretrainedConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.OpenAIGPTDoubleHeadsModel`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.OpenAIGPTDoubleHeadsModel`.
|
||||
|
||||
@@ -75,9 +75,9 @@ class PretrainedConfig(object):
|
||||
self.top_k = kwargs.pop("top_k", 50)
|
||||
self.top_p = kwargs.pop("top_p", 1.0)
|
||||
self.repetition_penalty = kwargs.pop("repetition_penalty", 1.0)
|
||||
self.bos_token_id = kwargs.pop("bos_token_id", None)
|
||||
self.pad_token_id = kwargs.pop("pad_token_id", None)
|
||||
self.eos_token_ids = kwargs.pop("eos_token_ids", None)
|
||||
self.bos_token_id = kwargs.pop("bos_token_id", 0)
|
||||
self.pad_token_id = kwargs.pop("pad_token_id", 0)
|
||||
self.eos_token_ids = kwargs.pop("eos_token_ids", 0)
|
||||
self.length_penalty = kwargs.pop("length_penalty", 1.0)
|
||||
self.num_return_sequences = kwargs.pop("num_return_sequences", 1)
|
||||
|
||||
@@ -198,7 +198,6 @@ class PretrainedConfig(object):
|
||||
force_download = kwargs.pop("force_download", False)
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
if pretrained_config_archive_map is None:
|
||||
pretrained_config_archive_map = cls.pretrained_config_archive_map
|
||||
@@ -220,7 +219,6 @@ class PretrainedConfig(object):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
# Load config dict
|
||||
if resolved_config_file is None:
|
||||
|
||||
@@ -108,12 +108,11 @@ class XLMConfig(PretrainedConfig):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Is one of the following options:
|
||||
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
|
||||
@@ -1,100 +0,0 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2020 The HuggingFace Inc. team.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Convert BART checkpoint."""
|
||||
|
||||
|
||||
import argparse
|
||||
import logging
|
||||
from pathlib import Path
|
||||
|
||||
import fairseq
|
||||
import torch
|
||||
from packaging import version
|
||||
|
||||
from transformers import BartConfig, BartForSequenceClassification, BartModel, BartTokenizer
|
||||
|
||||
|
||||
if version.parse(fairseq.__version__) < version.parse("0.9.0"):
|
||||
raise Exception("requires fairseq >= 0.9.0")
|
||||
|
||||
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
SAMPLE_TEXT = "Hello world! cécé herlolip"
|
||||
|
||||
rename_keys = [
|
||||
("model.classification_heads.mnli.dense.weight", "classification_head.dense.weight"),
|
||||
("model.classification_heads.mnli.dense.bias", "classification_head.dense.bias"),
|
||||
("model.classification_heads.mnli.out_proj.weight", "classification_head.out_proj.weight"),
|
||||
("model.classification_heads.mnli.out_proj.bias", "classification_head.out_proj.bias"),
|
||||
]
|
||||
IGNORE_KEYS = ["encoder.version", "decoder.version", "model.encoder.version", "model.decoder.version"]
|
||||
|
||||
|
||||
def rename_key(dct, old, new):
|
||||
val = dct.pop(old)
|
||||
dct[new] = val
|
||||
|
||||
|
||||
def convert_bart_checkpoint(checkpoint_path, pytorch_dump_folder_path):
|
||||
"""
|
||||
Copy/paste/tweak model's weights to our BERT structure.
|
||||
"""
|
||||
b2 = torch.hub.load("pytorch/fairseq", checkpoint_path)
|
||||
b2.eval() # disable dropout
|
||||
b2.model.upgrade_state_dict(b2.model.state_dict())
|
||||
config = BartConfig()
|
||||
tokens = b2.encode(SAMPLE_TEXT).unsqueeze(0)
|
||||
tokens2 = BartTokenizer.from_pretrained("bart-large").encode(SAMPLE_TEXT).unsqueeze(0)
|
||||
assert torch.eq(tokens, tokens2).all()
|
||||
|
||||
# assert their_output.size() == (1, 11, 1024)
|
||||
|
||||
if checkpoint_path == "bart.large":
|
||||
state_dict = b2.model.state_dict()
|
||||
state_dict["shared.weight"] = state_dict["decoder.embed_tokens.weight"]
|
||||
model = BartModel(config)
|
||||
their_output = b2.extract_features(tokens)
|
||||
|
||||
else: # MNLI Case
|
||||
state_dict = b2.state_dict()
|
||||
state_dict["model.shared.weight"] = state_dict["model.decoder.embed_tokens.weight"]
|
||||
for src, dest in rename_keys:
|
||||
rename_key(state_dict, src, dest)
|
||||
state_dict.pop("_float_tensor", None)
|
||||
model = BartForSequenceClassification(config)
|
||||
their_output = b2.predict("mnli", tokens, return_logits=True)
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
model.load_state_dict(state_dict)
|
||||
model.eval()
|
||||
our_outputs = model.forward(tokens)[0]
|
||||
|
||||
assert their_output.shape == our_outputs.shape
|
||||
assert (their_output == our_outputs).all().item()
|
||||
Path(pytorch_dump_folder_path).mkdir(exist_ok=True)
|
||||
model.save_pretrained(pytorch_dump_folder_path)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
# Required parameters
|
||||
parser.add_argument("fairseq_path", choices=["bart.large", "bart.large.mnli"], type=str, help="")
|
||||
parser.add_argument("pytorch_dump_folder_path", default=None, type=str, help="Path to the output PyTorch model.")
|
||||
args = parser.parse_args()
|
||||
convert_bart_checkpoint(
|
||||
args.fairseq_path, args.pytorch_dump_folder_path,
|
||||
)
|
||||
@@ -123,7 +123,7 @@ def squad_convert_example_to_features(example, max_seq_length, doc_stride, max_q
|
||||
truncated_query = tokenizer.encode(example.question_text, add_special_tokens=False, max_length=max_query_length)
|
||||
sequence_added_tokens = (
|
||||
tokenizer.max_len - tokenizer.max_len_single_sentence + 1
|
||||
if "roberta" in str(type(tokenizer)) or "camembert" in str(type(tokenizer))
|
||||
if "roberta" in str(type(tokenizer))
|
||||
else tokenizer.max_len - tokenizer.max_len_single_sentence
|
||||
)
|
||||
sequence_pair_added_tokens = tokenizer.max_len - tokenizer.max_len_sentences_pair
|
||||
|
||||
@@ -32,11 +32,11 @@ class InputExample(object):
|
||||
Args:
|
||||
guid: Unique id for the example.
|
||||
text_a: string. The untokenized text of the first sequence. For single
|
||||
sequence tasks, only this sequence must be specified.
|
||||
sequence tasks, only this sequence must be specified.
|
||||
text_b: (Optional) string. The untokenized text of the second sequence.
|
||||
Only must be specified for sequence pair tasks.
|
||||
Only must be specified for sequence pair tasks.
|
||||
label: (Optional) string. The label of the example. This should be
|
||||
specified for train and dev examples, but not for test examples.
|
||||
specified for train and dev examples, but not for test examples.
|
||||
"""
|
||||
|
||||
def __init__(self, guid, text_a, text_b=None, label=None):
|
||||
|
||||
@@ -214,7 +214,6 @@ def cached_path(
|
||||
user_agent=None,
|
||||
extract_compressed_file=False,
|
||||
force_extract=False,
|
||||
local_files_only=False,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given something that might be a URL (or might be a local path),
|
||||
@@ -251,7 +250,6 @@ def cached_path(
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
user_agent=user_agent,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
elif os.path.exists(url_or_filename):
|
||||
# File, and it exists.
|
||||
@@ -380,14 +378,7 @@ def http_get(url, temp_file, proxies=None, resume_size=0, user_agent=None):
|
||||
|
||||
|
||||
def get_from_cache(
|
||||
url,
|
||||
cache_dir=None,
|
||||
force_download=False,
|
||||
proxies=None,
|
||||
etag_timeout=10,
|
||||
resume_download=False,
|
||||
user_agent=None,
|
||||
local_files_only=False,
|
||||
url, cache_dir=None, force_download=False, proxies=None, etag_timeout=10, resume_download=False, user_agent=None
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given a URL, look for the corresponding file in the local cache.
|
||||
@@ -404,19 +395,18 @@ def get_from_cache(
|
||||
|
||||
os.makedirs(cache_dir, exist_ok=True)
|
||||
|
||||
etag = None
|
||||
if not local_files_only:
|
||||
# Get eTag to add to filename, if it exists.
|
||||
if url.startswith("s3://"):
|
||||
etag = s3_etag(url, proxies=proxies)
|
||||
else:
|
||||
try:
|
||||
response = requests.head(url, allow_redirects=True, proxies=proxies, timeout=etag_timeout)
|
||||
if response.status_code == 200:
|
||||
etag = response.headers.get("ETag")
|
||||
except (EnvironmentError, requests.exceptions.Timeout):
|
||||
# etag is already None
|
||||
pass
|
||||
# Get eTag to add to filename, if it exists.
|
||||
if url.startswith("s3://"):
|
||||
etag = s3_etag(url, proxies=proxies)
|
||||
else:
|
||||
try:
|
||||
response = requests.head(url, allow_redirects=True, proxies=proxies, timeout=etag_timeout)
|
||||
if response.status_code != 200:
|
||||
etag = None
|
||||
else:
|
||||
etag = response.headers.get("ETag")
|
||||
except (EnvironmentError, requests.exceptions.Timeout):
|
||||
etag = None
|
||||
|
||||
filename = url_to_filename(url, etag)
|
||||
|
||||
@@ -437,15 +427,6 @@ def get_from_cache(
|
||||
if len(matching_files) > 0:
|
||||
return os.path.join(cache_dir, matching_files[-1])
|
||||
else:
|
||||
# If files cannot be found and local_files_only=True,
|
||||
# the models might've been found if local_files_only=False
|
||||
# Notify the user about that
|
||||
if local_files_only:
|
||||
raise ValueError(
|
||||
"Cannot find the requested files in the cached path and outgoing traffic has been"
|
||||
" disabled. To enable model look-ups and downloads online, set 'local_files_only'"
|
||||
" to False."
|
||||
)
|
||||
return None
|
||||
|
||||
# From now on, etag is not None.
|
||||
|
||||
@@ -600,7 +600,7 @@ class AlbertMLMHead(nn.Module):
|
||||
hidden_states = self.LayerNorm(hidden_states)
|
||||
hidden_states = self.decoder(hidden_states)
|
||||
|
||||
prediction_scores = hidden_states
|
||||
prediction_scores = hidden_states + self.bias
|
||||
|
||||
return prediction_scores
|
||||
|
||||
|
||||
@@ -21,7 +21,6 @@ from collections import OrderedDict
|
||||
from .configuration_auto import (
|
||||
AlbertConfig,
|
||||
AutoConfig,
|
||||
BartConfig,
|
||||
BertConfig,
|
||||
CamembertConfig,
|
||||
CTRLConfig,
|
||||
@@ -44,7 +43,6 @@ from .modeling_albert import (
|
||||
AlbertForSequenceClassification,
|
||||
AlbertModel,
|
||||
)
|
||||
from .modeling_bart import BART_PRETRAINED_MODEL_ARCHIVE_MAP, BartForMaskedLM, BartForSequenceClassification, BartModel
|
||||
from .modeling_bert import (
|
||||
BERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
BertForMaskedLM,
|
||||
@@ -120,7 +118,6 @@ ALL_PRETRAINED_MODEL_ARCHIVE_MAP = dict(
|
||||
(key, value)
|
||||
for pretrained_map in [
|
||||
BERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
BART_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
OPENAI_GPT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
TRANSFO_XL_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
GPT2_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
@@ -145,7 +142,6 @@ MODEL_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertModel),
|
||||
(CamembertConfig, CamembertModel),
|
||||
(XLMRobertaConfig, XLMRobertaModel),
|
||||
(BartConfig, BartModel),
|
||||
(RobertaConfig, RobertaModel),
|
||||
(BertConfig, BertModel),
|
||||
(OpenAIGPTConfig, OpenAIGPTModel),
|
||||
@@ -165,7 +161,6 @@ MODEL_FOR_PRETRAINING_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertForMaskedLM),
|
||||
(CamembertConfig, CamembertForMaskedLM),
|
||||
(XLMRobertaConfig, XLMRobertaForMaskedLM),
|
||||
(BartConfig, BartForMaskedLM),
|
||||
(RobertaConfig, RobertaForMaskedLM),
|
||||
(BertConfig, BertForPreTraining),
|
||||
(OpenAIGPTConfig, OpenAIGPTLMHeadModel),
|
||||
@@ -185,7 +180,6 @@ MODEL_WITH_LM_HEAD_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertForMaskedLM),
|
||||
(CamembertConfig, CamembertForMaskedLM),
|
||||
(XLMRobertaConfig, XLMRobertaForMaskedLM),
|
||||
(BartConfig, BartForMaskedLM),
|
||||
(RobertaConfig, RobertaForMaskedLM),
|
||||
(BertConfig, BertForMaskedLM),
|
||||
(OpenAIGPTConfig, OpenAIGPTLMHeadModel),
|
||||
@@ -204,7 +198,6 @@ MODEL_FOR_SEQUENCE_CLASSIFICATION_MAPPING = OrderedDict(
|
||||
(AlbertConfig, AlbertForSequenceClassification),
|
||||
(CamembertConfig, CamembertForSequenceClassification),
|
||||
(XLMRobertaConfig, XLMRobertaForSequenceClassification),
|
||||
(BartConfig, BartForSequenceClassification),
|
||||
(RobertaConfig, RobertaForSequenceClassification),
|
||||
(BertConfig, BertForSequenceClassification),
|
||||
(XLNetConfig, XLNetForSequenceClassification),
|
||||
@@ -359,12 +352,16 @@ class AutoModel(object):
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
These arguments will be passed to the configuration and the model.
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModel.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModel.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModel.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -499,12 +496,24 @@ class AutoModelForPreTraining(object):
|
||||
output_loading_info: (`optional`) boolean:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
These arguments will be passed to the configuration and the model.
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model.
|
||||
(e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or
|
||||
automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the
|
||||
underlying model's ``__init__`` method (we assume all relevant updates to the configuration have
|
||||
already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class
|
||||
initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of
|
||||
``kwargs`` that corresponds to a configuration attribute will be used to override said attribute
|
||||
with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration
|
||||
attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForPreTraining.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForPreTraining.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForPreTraining.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -641,12 +650,24 @@ class AutoModelWithLMHead(object):
|
||||
output_loading_info: (`optional`) boolean:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
These arguments will be passed to the configuration and the model.
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model.
|
||||
(e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or
|
||||
automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the
|
||||
underlying model's ``__init__`` method (we assume all relevant updates to the configuration have
|
||||
already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class
|
||||
initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of
|
||||
``kwargs`` that corresponds to a configuration attribute will be used to override said attribute
|
||||
with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration
|
||||
attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelWithLMHead.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelWithLMHead.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -786,12 +807,16 @@ class AutoModelForSequenceClassification(object):
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
These arguments will be passed to the configuration and the model.
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForSequenceClassification.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForSequenceClassification.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForSequenceClassification.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -925,12 +950,16 @@ class AutoModelForQuestionAnswering(object):
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
These arguments will be passed to the configuration and the model.
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -1065,12 +1094,16 @@ class AutoModelForTokenClassification:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
These arguments will be passed to the configuration and the model.
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForTokenClassification.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForTokenClassification.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForTokenClassification.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
|
||||
File diff suppressed because it is too large.
Load diff
@@ -471,7 +471,7 @@ class BertLMPredictionHead(nn.Module):
|
||||
|
||||
def forward(self, hidden_states):
|
||||
hidden_states = self.transform(hidden_states)
|
||||
hidden_states = self.decoder(hidden_states)
|
||||
hidden_states = self.decoder(hidden_states) + self.bias
|
||||
return hidden_states
|
||||
|
||||
|
||||
@@ -1230,7 +1230,7 @@ class BertForMultipleChoice(BertPreTrainedModel):
|
||||
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
loss (:obj:`torch.FloatTensor`` of shape ``(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification loss.
|
||||
classification_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_choices)`):
|
||||
`num_choices` is the second dimension of the input tensors. (see `input_ids` above).
|
||||
@@ -1382,10 +1382,8 @@ class BertForTokenClassification(BertPreTrainedModel):
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -15,6 +15,7 @@
|
||||
# limitations under the License.
|
||||
"""PyTorch CamemBERT model. """
|
||||
|
||||
|
||||
import logging
|
||||
|
||||
from .configuration_camembert import CamembertConfig
|
||||
@@ -22,7 +23,6 @@ from .file_utils import add_start_docstrings
|
||||
from .modeling_roberta import (
|
||||
RobertaForMaskedLM,
|
||||
RobertaForMultipleChoice,
|
||||
RobertaForQuestionAnswering,
|
||||
RobertaForSequenceClassification,
|
||||
RobertaForTokenClassification,
|
||||
RobertaModel,
|
||||
@@ -37,6 +37,7 @@ CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"umberto-wikipedia-uncased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/Musixmatch/umberto-wikipedia-uncased-v1/pytorch_model.bin",
|
||||
}
|
||||
|
||||
|
||||
CAMEMBERT_START_DOCSTRING = r"""
|
||||
|
||||
This model is a PyTorch `torch.nn.Module <https://pytorch.org/docs/stable/nn.html#torch.nn.Module>`_ sub-class.
|
||||
@@ -45,8 +46,7 @@ CAMEMBERT_START_DOCSTRING = r"""
|
||||
|
||||
Parameters:
|
||||
config (:class:`~transformers.CamembertConfig`): Model configuration class with all the parameters of the
|
||||
model. Initializing with a config file does not load the weights associated with the model, only the
|
||||
configuration.
|
||||
model. Initializing with a config file does not load the weights associated with the model, only the configuration.
|
||||
Check out the :meth:`~transformers.PreTrainedModel.from_pretrained` method to load the model weights.
|
||||
"""
|
||||
|
||||
@@ -121,18 +121,3 @@ class CamembertForTokenClassification(RobertaForTokenClassification):
|
||||
|
||||
config_class = CamembertConfig
|
||||
pretrained_model_archive_map = CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""CamemBERT Model with a span classification head on top for extractive question-answering tasks like SQuAD
|
||||
(a linear layers on top of the hidden-states output to compute `span start logits` and `span end logits` """,
|
||||
CAMEMBERT_START_DOCSTRING,
|
||||
)
|
||||
class CamembertForQuestionAnswering(RobertaForQuestionAnswering):
|
||||
"""
|
||||
This class overrides :class:`~transformers.RobertaForQuestionAnswering`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = CamembertConfig
|
||||
pretrained_model_archive_map = CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
@@ -217,6 +217,11 @@ class TransformerBlock(nn.Module):
|
||||
def __init__(self, config):
|
||||
super().__init__()
|
||||
|
||||
self.n_heads = config.n_heads
|
||||
self.dim = config.dim
|
||||
self.hidden_dim = config.hidden_dim
|
||||
self.dropout = nn.Dropout(p=config.dropout)
|
||||
self.activation = config.activation
|
||||
self.output_attentions = config.output_attentions
|
||||
|
||||
assert config.dim % config.n_heads == 0
|
||||
@@ -818,10 +823,8 @@ class DistilBertForTokenClassification(DistilBertPreTrainedModel):
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -18,6 +18,7 @@
|
||||
import logging
|
||||
import os
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
from .modeling_auto import AutoModel, AutoModelWithLMHead
|
||||
@@ -235,6 +236,42 @@ class PreTrainedEncoderDecoder(nn.Module):
|
||||
|
||||
return decoder_outputs + encoder_outputs
|
||||
|
||||
@staticmethod
|
||||
def prepare_model_kwargs(**kwargs):
|
||||
""" Prepare the encoder and decoder's keyword arguments.
|
||||
|
||||
Keyword arguments come in 3 flavors:
|
||||
- encoder-specific (prefixed by `encoder_`)
|
||||
- decoder-specific (prefixed by `decoder_`)
|
||||
- those that apply to the model as whole.
|
||||
|
||||
We let the specific kwargs override the common ones in case of
|
||||
conflict.
|
||||
"""
|
||||
kwargs_common = {
|
||||
argument: value
|
||||
for argument, value in kwargs.items()
|
||||
if not argument.startswith("encoder_") and not argument.startswith("decoder_")
|
||||
}
|
||||
decoder_kwargs = kwargs_common.copy()
|
||||
encoder_kwargs = kwargs_common.copy()
|
||||
encoder_kwargs.update(
|
||||
{
|
||||
argument[len("encoder_") :]: value
|
||||
for argument, value in kwargs.items()
|
||||
if argument.startswith("encoder_")
|
||||
}
|
||||
)
|
||||
decoder_kwargs.update(
|
||||
{
|
||||
argument[len("decoder_") :]: value
|
||||
for argument, value in kwargs.items()
|
||||
if argument.startswith("decoder_")
|
||||
}
|
||||
)
|
||||
decoder_kwargs["encoder_attention_mask"] = encoder_kwargs.get("attention_mask", None)
|
||||
return encoder_kwargs, decoder_kwargs
|
||||
|
||||
|
||||
class Model2Model(PreTrainedEncoderDecoder):
|
||||
r"""
|
||||
@@ -293,3 +330,21 @@ class Model2Model(PreTrainedEncoderDecoder):
|
||||
)
|
||||
|
||||
return model
|
||||
|
||||
|
||||
class Model2LSTM(PreTrainedEncoderDecoder):
|
||||
@classmethod
|
||||
def from_pretrained(cls, *args, **kwargs):
|
||||
if kwargs.get("decoder_model", None) is None:
|
||||
# We will create a randomly initilized LSTM model as decoder
|
||||
if "decoder_config" not in kwargs:
|
||||
raise ValueError(
|
||||
"To load an LSTM in Encoder-Decoder model, please supply either: "
|
||||
" - a torch.nn.LSTM model as `decoder_model` parameter (`decoder_model=lstm_model`), or"
|
||||
" - a dictionary of configuration parameters that will be used to initialize a"
|
||||
" torch.nn.LSTM model as `decoder_config` keyword argument. "
|
||||
" E.g. `decoder_config={'input_size': 768, 'hidden_size': 768, 'num_layers': 2}`"
|
||||
)
|
||||
kwargs["decoder_model"] = torch.nn.LSTM(kwargs.pop("decoder_config"))
|
||||
model = super().from_pretrained(*args, **kwargs)
|
||||
return model
|
||||
@@ -25,7 +25,6 @@ from torch.nn import CrossEntropyLoss, MSELoss
|
||||
from .configuration_roberta import RobertaConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_bert import BertEmbeddings, BertLayerNorm, BertModel, BertPreTrainedModel, gelu
|
||||
from .modeling_utils import create_position_ids_from_input_ids
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -57,7 +56,7 @@ class RobertaEmbeddings(BertEmbeddings):
|
||||
if position_ids is None:
|
||||
if input_ids is not None:
|
||||
# Create the position ids from the input token ids. Any padded tokens remain padded.
|
||||
position_ids = create_position_ids_from_input_ids(input_ids, self.padding_idx).to(input_ids.device)
|
||||
position_ids = self.create_position_ids_from_input_ids(input_ids).to(input_ids.device)
|
||||
else:
|
||||
position_ids = self.create_position_ids_from_inputs_embeds(inputs_embeds)
|
||||
|
||||
@@ -65,6 +64,18 @@ class RobertaEmbeddings(BertEmbeddings):
|
||||
input_ids, token_type_ids=token_type_ids, position_ids=position_ids, inputs_embeds=inputs_embeds
|
||||
)
|
||||
|
||||
def create_position_ids_from_input_ids(self, x):
|
||||
""" Replace non-padding symbols with their position numbers. Position numbers begin at
|
||||
padding_idx+1. Padding symbols are ignored. This is modified from fairseq's
|
||||
`utils.make_positions`.
|
||||
|
||||
:param torch.Tensor x:
|
||||
:return torch.Tensor:
|
||||
"""
|
||||
mask = x.ne(self.padding_idx).long()
|
||||
incremental_indicies = torch.cumsum(mask, dim=1) * mask
|
||||
return incremental_indicies + self.padding_idx
|
||||
|
||||
def create_position_ids_from_inputs_embeds(self, inputs_embeds):
|
||||
""" We are provided embeddings directly. We cannot infer which are padded so just generate
|
||||
sequential position ids.
|
||||
@@ -264,7 +275,7 @@ class RobertaLMHead(nn.Module):
|
||||
x = self.layer_norm(x)
|
||||
|
||||
# project back to size of vocabulary with bias
|
||||
x = self.decoder(x)
|
||||
x = self.decoder(x) + self.bias
|
||||
|
||||
return x
|
||||
|
||||
@@ -542,16 +553,13 @@ class RobertaForTokenClassification(BertPreTrainedModel):
|
||||
logits = self.classifier(sequence_output)
|
||||
|
||||
outputs = (logits,) + outputs[2:] # add hidden states and attention if they are here
|
||||
|
||||
if labels is not None:
|
||||
loss_fct = CrossEntropyLoss()
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -29,14 +29,14 @@ from .modeling_tf_utils import TFPreTrainedModel, get_initializer, shape_list
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
TF_ALBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"albert-base-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-base-v1-with-prefix-tf_model.h5",
|
||||
"albert-large-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-large-v1-with-prefix-tf_model.h5",
|
||||
"albert-xlarge-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xlarge-v1-with-prefix-tf_model.h5",
|
||||
"albert-xxlarge-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xxlarge-v1-with-prefix-tf_model.h5",
|
||||
"albert-base-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-base-v2-with-prefix-tf_model.h5",
|
||||
"albert-large-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-large-v2-with-prefix-tf_model.h5",
|
||||
"albert-xlarge-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xlarge-v2-with-prefix-tf_model.h5",
|
||||
"albert-xxlarge-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xxlarge-v2-with-prefix-tf_model.h5",
|
||||
"albert-base-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-base-v1-tf_model.h5",
|
||||
"albert-large-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-large-v1-tf_model.h5",
|
||||
"albert-xlarge-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xlarge-v1-tf_model.h5",
|
||||
"albert-xxlarge-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xxlarge-v1-tf_model.h5",
|
||||
"albert-base-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-base-v2-tf_model.h5",
|
||||
"albert-large-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-large-v2-tf_model.h5",
|
||||
"albert-xlarge-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xlarge-v2-tf_model.h5",
|
||||
"albert-xxlarge-v2": "https://s3.amazonaws.com/models.huggingface.co/bert/albert-xxlarge-v2-tf_model.h5",
|
||||
}
|
||||
|
||||
|
||||
@@ -478,115 +478,6 @@ class TFAlbertMLMHead(tf.keras.layers.Layer):
|
||||
return hidden_states
|
||||
|
||||
|
||||
class TFAlbertMainLayer(tf.keras.layers.Layer):
|
||||
def __init__(self, config, **kwargs):
|
||||
super().__init__(config, **kwargs)
|
||||
self.num_hidden_layers = config.num_hidden_layers
|
||||
|
||||
self.embeddings = TFAlbertEmbeddings(config, name="embeddings")
|
||||
self.encoder = TFAlbertTransformer(config, name="encoder")
|
||||
self.pooler = tf.keras.layers.Dense(
|
||||
config.hidden_size,
|
||||
kernel_initializer=get_initializer(config.initializer_range),
|
||||
activation="tanh",
|
||||
name="pooler",
|
||||
)
|
||||
|
||||
def get_input_embeddings(self):
|
||||
return self.embeddings
|
||||
|
||||
def _resize_token_embeddings(self, new_num_tokens):
|
||||
raise NotImplementedError
|
||||
|
||||
def _prune_heads(self, heads_to_prune):
|
||||
""" Prunes heads of the model.
|
||||
heads_to_prune: dict of {layer_num: list of heads to prune in this layer}
|
||||
See base class PreTrainedModel
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
def call(
|
||||
self,
|
||||
inputs,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
inputs_embeds=None,
|
||||
training=False,
|
||||
):
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
position_ids = inputs[3] if len(inputs) > 3 else position_ids
|
||||
head_mask = inputs[4] if len(inputs) > 4 else head_mask
|
||||
inputs_embeds = inputs[5] if len(inputs) > 5 else inputs_embeds
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
elif isinstance(inputs, dict):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
position_ids = inputs.get("position_ids", position_ids)
|
||||
head_mask = inputs.get("head_mask", head_mask)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
if input_ids is not None and inputs_embeds is not None:
|
||||
raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
|
||||
elif input_ids is not None:
|
||||
input_shape = shape_list(input_ids)
|
||||
elif inputs_embeds is not None:
|
||||
input_shape = shape_list(inputs_embeds)[:-1]
|
||||
else:
|
||||
raise ValueError("You have to specify either input_ids or inputs_embeds")
|
||||
|
||||
if attention_mask is None:
|
||||
attention_mask = tf.fill(input_shape, 1)
|
||||
if token_type_ids is None:
|
||||
token_type_ids = tf.fill(input_shape, 0)
|
||||
|
||||
# We create a 3D attention mask from a 2D tensor mask.
|
||||
# Sizes are [batch_size, 1, 1, to_seq_length]
|
||||
# So we can broadcast to [batch_size, num_heads, from_seq_length, to_seq_length]
|
||||
# this attention mask is more simple than the triangular masking of causal attention
|
||||
# used in OpenAI GPT, we just need to prepare the broadcast dimension here.
|
||||
extended_attention_mask = attention_mask[:, tf.newaxis, tf.newaxis, :]
|
||||
|
||||
# Since attention_mask is 1.0 for positions we want to attend and 0.0 for
|
||||
# masked positions, this operation will create a tensor which is 0.0 for
|
||||
# positions we want to attend and -10000.0 for masked positions.
|
||||
# Since we are adding it to the raw scores before the softmax, this is
|
||||
# effectively the same as removing these entirely.
|
||||
|
||||
extended_attention_mask = tf.cast(extended_attention_mask, tf.float32)
|
||||
extended_attention_mask = (1.0 - extended_attention_mask) * -10000.0
|
||||
|
||||
# Prepare head mask if needed
|
||||
# 1.0 in head_mask indicate we keep the head
|
||||
# attention_probs has shape bsz x n_heads x N x N
|
||||
# input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
|
||||
# and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
|
||||
if head_mask is not None:
|
||||
raise NotImplementedError
|
||||
else:
|
||||
head_mask = [None] * self.num_hidden_layers
|
||||
# head_mask = tf.constant([0] * self.num_hidden_layers)
|
||||
|
||||
embedding_output = self.embeddings([input_ids, position_ids, token_type_ids, inputs_embeds], training=training)
|
||||
encoder_outputs = self.encoder([embedding_output, extended_attention_mask, head_mask], training=training)
|
||||
|
||||
sequence_output = encoder_outputs[0]
|
||||
pooled_output = self.pooler(sequence_output[:, 0])
|
||||
|
||||
# add hidden_states and attentions if they are here
|
||||
outputs = (sequence_output, pooled_output,) + encoder_outputs[1:]
|
||||
# sequence_output, pooled_output, (hidden_states), (attentions)
|
||||
return outputs
|
||||
|
||||
|
||||
ALBERT_START_DOCSTRING = r"""
|
||||
This model is a `tf.keras.Model <https://www.tensorflow.org/api_docs/python/tf/keras/Model>`__ sub-class.
|
||||
Use it as a regular TF 2.0 Keras Model and
|
||||
@@ -669,48 +560,147 @@ ALBERT_INPUTS_DOCSTRING = r"""
|
||||
ALBERT_START_DOCSTRING,
|
||||
)
|
||||
class TFAlbertModel(TFAlbertPreTrainedModel):
|
||||
def __init__(self, config, *inputs, **kwargs):
|
||||
super().__init__(config, *inputs, **kwargs)
|
||||
self.albert = TFAlbertMainLayer(config, name="albert")
|
||||
def __init__(self, config, **kwargs):
|
||||
super().__init__(config, **kwargs)
|
||||
self.num_hidden_layers = config.num_hidden_layers
|
||||
|
||||
self.embeddings = TFAlbertEmbeddings(config, name="embeddings")
|
||||
self.encoder = TFAlbertTransformer(config, name="encoder")
|
||||
self.pooler = tf.keras.layers.Dense(
|
||||
config.hidden_size,
|
||||
kernel_initializer=get_initializer(config.initializer_range),
|
||||
activation="tanh",
|
||||
name="pooler",
|
||||
)
|
||||
|
||||
def get_input_embeddings(self):
|
||||
return self.embeddings
|
||||
|
||||
def _resize_token_embeddings(self, new_num_tokens):
|
||||
raise NotImplementedError
|
||||
|
||||
def _prune_heads(self, heads_to_prune):
|
||||
""" Prunes heads of the model.
|
||||
heads_to_prune: dict of {layer_num: list of heads to prune in this layer}
|
||||
See base class PreTrainedModel
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
@add_start_docstrings_to_callable(ALBERT_INPUTS_DOCSTRING)
|
||||
def call(self, inputs, **kwargs):
|
||||
def call(
|
||||
self,
|
||||
inputs,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
inputs_embeds=None,
|
||||
training=False,
|
||||
):
|
||||
r"""
|
||||
Returns:
|
||||
:obj:`tuple(tf.Tensor)` comprising various elements depending on the configuration (:class:`~transformers.AlbertConfig`) and inputs:
|
||||
last_hidden_state (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
pooler_output (:obj:`tf.Tensor` of shape :obj:`(batch_size, hidden_size)`):
|
||||
Last layer hidden-state of the first token of the sequence (classification token)
|
||||
further processed by a Linear layer and a Tanh activation function. The Linear
|
||||
layer weights are trained from the next sentence prediction (classification)
|
||||
objective during Albert pretraining. This output is usually *not* a good summary
|
||||
of the semantic content of the input, you're often better with averaging or pooling
|
||||
the sequence of hidden-states for the whole input sequence.
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when :obj:`config.output_hidden_states=True`):
|
||||
tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`:
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
|
||||
|
||||
Examples::
|
||||
Examples::
|
||||
|
||||
import tensorflow as tf
|
||||
from transformers import AlbertTokenizer, TFAlbertModel
|
||||
import tensorflow as tf
|
||||
from transformers import AlbertTokenizer, TFAlbertModel
|
||||
|
||||
tokenizer = AlbertTokenizer.from_pretrained('albert-base-v2')
|
||||
model = TFAlbertModel.from_pretrained('albert-base-v2')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
|
||||
"""
|
||||
outputs = self.albert(inputs, **kwargs)
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
position_ids = inputs[3] if len(inputs) > 3 else position_ids
|
||||
head_mask = inputs[4] if len(inputs) > 4 else head_mask
|
||||
inputs_embeds = inputs[5] if len(inputs) > 5 else inputs_embeds
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
elif isinstance(inputs, dict):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
position_ids = inputs.get("position_ids", position_ids)
|
||||
head_mask = inputs.get("head_mask", head_mask)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
if input_ids is not None and inputs_embeds is not None:
|
||||
raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
|
||||
elif input_ids is not None:
|
||||
input_shape = shape_list(input_ids)
|
||||
elif inputs_embeds is not None:
|
||||
input_shape = shape_list(inputs_embeds)[:-1]
|
||||
else:
|
||||
raise ValueError("You have to specify either input_ids or inputs_embeds")
|
||||
|
||||
if attention_mask is None:
|
||||
attention_mask = tf.fill(input_shape, 1)
|
||||
if token_type_ids is None:
|
||||
token_type_ids = tf.fill(input_shape, 0)
|
||||
|
||||
# We create a 3D attention mask from a 2D tensor mask.
|
||||
# Sizes are [batch_size, 1, 1, to_seq_length]
|
||||
# So we can broadcast to [batch_size, num_heads, from_seq_length, to_seq_length]
|
||||
# this attention mask is more simple than the triangular masking of causal attention
|
||||
# used in OpenAI GPT, we just need to prepare the broadcast dimension here.
|
||||
extended_attention_mask = attention_mask[:, tf.newaxis, tf.newaxis, :]
|
||||
|
||||
# Since attention_mask is 1.0 for positions we want to attend and 0.0 for
|
||||
# masked positions, this operation will create a tensor which is 0.0 for
|
||||
# positions we want to attend and -10000.0 for masked positions.
|
||||
# Since we are adding it to the raw scores before the softmax, this is
|
||||
# effectively the same as removing these entirely.
|
||||
|
||||
extended_attention_mask = tf.cast(extended_attention_mask, tf.float32)
|
||||
extended_attention_mask = (1.0 - extended_attention_mask) * -10000.0
|
||||
|
||||
# Prepare head mask if needed
|
||||
# 1.0 in head_mask indicate we keep the head
|
||||
# attention_probs has shape bsz x n_heads x N x N
|
||||
# input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
|
||||
# and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
|
||||
if head_mask is not None:
|
||||
raise NotImplementedError
|
||||
else:
|
||||
head_mask = [None] * self.num_hidden_layers
|
||||
# head_mask = tf.constant([0] * self.num_hidden_layers)
|
||||
|
||||
embedding_output = self.embeddings([input_ids, position_ids, token_type_ids, inputs_embeds], training=training)
|
||||
encoder_outputs = self.encoder([embedding_output, extended_attention_mask, head_mask], training=training)
|
||||
|
||||
sequence_output = encoder_outputs[0]
|
||||
pooled_output = self.pooler(sequence_output[:, 0])
|
||||
|
||||
# add hidden_states and attentions if they are here
|
||||
outputs = (sequence_output, pooled_output,) + encoder_outputs[1:]
|
||||
# sequence_output, pooled_output, (hidden_states), (attentions)
|
||||
return outputs
|
||||
|
||||
|
||||
@@ -719,7 +709,7 @@ class TFAlbertForMaskedLM(TFAlbertPreTrainedModel):
|
||||
def __init__(self, config, *inputs, **kwargs):
|
||||
super(TFAlbertForMaskedLM, self).__init__(config, *inputs, **kwargs)
|
||||
|
||||
self.albert = TFAlbertMainLayer(config, name="albert")
|
||||
self.albert = TFAlbertModel(config, name="albert")
|
||||
self.predictions = TFAlbertMLMHead(config, self.albert.embeddings, name="predictions")
|
||||
|
||||
def get_output_embeddings(self):
|
||||
@@ -776,7 +766,7 @@ class TFAlbertForSequenceClassification(TFAlbertPreTrainedModel):
|
||||
super(TFAlbertForSequenceClassification, self).__init__(config, *inputs, **kwargs)
|
||||
self.num_labels = config.num_labels
|
||||
|
||||
self.albert = TFAlbertMainLayer(config, name="albert")
|
||||
self.albert = TFAlbertModel(config, name="albert")
|
||||
self.dropout = tf.keras.layers.Dropout(config.hidden_dropout_prob)
|
||||
self.classifier = tf.keras.layers.Dense(
|
||||
config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
|
||||
|
||||
@@ -668,39 +668,38 @@ class TFBertModel(TFBertPreTrainedModel):
|
||||
@add_start_docstrings_to_callable(BERT_INPUTS_DOCSTRING)
|
||||
def call(self, inputs, **kwargs):
|
||||
r"""
|
||||
Returns:
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
|
||||
last_hidden_state (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
pooler_output (:obj:`tf.Tensor` of shape :obj:`(batch_size, hidden_size)`):
|
||||
Last layer hidden-state of the first token of the sequence (classification token)
|
||||
further processed by a Linear layer and a Tanh activation function. The Linear
|
||||
layer weights are trained from the next sentence prediction (classification)
|
||||
objective during Bert pretraining. This output is usually *not* a good summary
|
||||
of the semantic content of the input, you're often better with averaging or pooling
|
||||
the sequence of hidden-states for the whole input sequence.
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when :obj:`config.output_hidden_states=True`):
|
||||
tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`:
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention heads.
|
||||
|
||||
Examples::
|
||||
|
||||
Examples::
|
||||
import tensorflow as tf
|
||||
from transformers import BertTokenizer, TFBertModel
|
||||
|
||||
import tensorflow as tf
|
||||
from transformers import BertTokenizer, TFBertModel
|
||||
|
||||
tokenizer = BertTokenizer.from_pretrained('bert-base-uncased')
|
||||
model = TFBertModel.from_pretrained('bert-base-uncased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
"""
|
||||
outputs = self.bert(inputs, **kwargs)
|
||||
return outputs
|
||||
|
||||
@@ -192,6 +192,9 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
def from_pretrained(cls, pretrained_model_name_or_path, *model_args, **kwargs):
|
||||
r"""Instantiate a pretrained TF 2.0 model from a pre-trained model configuration.
|
||||
|
||||
The model is set in evaluation mode by default using ``model.eval()`` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with ``model.train()``
|
||||
|
||||
The warning ``Weights from XXX not initialized from pretrained model`` means that the weights of XXX do not come pre-trained with the rest of the model.
|
||||
It is up to you to train those weights with a downstream fine-tuning task.
|
||||
|
||||
|
||||
@@ -645,7 +645,7 @@ class TransfoXLModel(TransfoXLPreTrainedModel):
|
||||
else:
|
||||
return None
|
||||
|
||||
def _update_mems(self, hids, mems, mlen, qlen):
|
||||
def _update_mems(self, hids, mems, qlen, mlen):
|
||||
# does not deal with None
|
||||
if mems is None:
|
||||
return None
|
||||
|
||||
@@ -376,7 +376,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
output_loading_info = kwargs.pop("output_loading_info", False)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
# Load config if we don't provide a configuration
|
||||
if not isinstance(config, PretrainedConfig):
|
||||
@@ -389,7 +388,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
force_download=force_download,
|
||||
resume_download=resume_download,
|
||||
proxies=proxies,
|
||||
local_files_only=local_files_only,
|
||||
**kwargs,
|
||||
)
|
||||
else:
|
||||
@@ -437,7 +435,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
except EnvironmentError:
|
||||
if pretrained_model_name_or_path in cls.pretrained_model_archive_map:
|
||||
@@ -648,39 +645,33 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
num_return_sequences: (`optional`) int
|
||||
The number of independently computed returned sequences for each element in the batch. Default to 1.
|
||||
|
||||
Return:
|
||||
|
||||
output: `torch.LongTensor` of shape `(batch_size * num_return_sequences, sequence_length)`
|
||||
sequence_length is either equal to max_length or shorter if all batches finished early due to the `eos_token_id`
|
||||
|
||||
Examples::
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('distilgpt2') # Initialize tokenizer
|
||||
model = AutoModelWithLMHead.from_pretrained('distilgpt2') # Download model and configuration from S3 and cache.
|
||||
outputs = model.generate(max_length=40, bos_token_id=tokenizer.bos_token_id, eos_token_ids=tokenizer.eos_token_id, do_sample=False) # do greedy decoding
|
||||
outputs = model.generate(max_length=40, bos_token_id=tokenizer.bos_token_id, eos_token_ids=tokenizer.eos_token_id) # do greedy decoding without beam search
|
||||
print('Generated: {}'.format(tokenizer.decode(outputs[0], skip_special_tokens=True)))
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('openai-gpt') # Initialize tokenizer
|
||||
model = AutoModelWithLMHead.from_pretrained('openai-gpt') # Download model and configuration from S3 and cache.
|
||||
input_context = 'The dog'
|
||||
input_ids = torch.tensor(tokenizer.encode(input_context)).unsqueeze(0) # encode input context
|
||||
outputs = model.generate(input_ids=input_ids, num_beams=5, num_return_sequences=3, temperature=1.5) # generate 3 independent sequences using beam search decoding (5 beams) with sampling from initial context 'The dog'
|
||||
outputs = model.generate(input_ids=input_ids, do_sample=True, num_beams=5, num_return_sequences=3, temperature=1.5) # generate 3 independent sequences using beam search decoding (5 beams) with sampling from initial context 'The dog'
|
||||
for i in range(3): # 3 output sequences were generated
|
||||
print('Generated {}: {}'.format(i, tokenizer.decode(outputs[i], skip_special_tokens=True)))
|
||||
print('Generated {}: {}'.format(i, tokenizer.decode(outputs[0][i], skip_special_tokens=True)))
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('distilgpt2') # Initialize tokenizer
|
||||
model = AutoModelWithLMHead.from_pretrained('distilgpt2') # Download model and configuration from S3 and cache.
|
||||
input_context = 'The dog'
|
||||
input_ids = torch.tensor(tokenizer.encode(input_context)).unsqueeze(0) # encode input context
|
||||
outputs = model.generate(input_ids=input_ids, max_length=40, temperature=0.7, bos_token_id=tokenizer.bos_token_id, pad_token_id=tokenizer.pad_token_id, eos_token_ids=tokenizer.eos_token_id, num_return_sequences=3) # 3 generate sequences using by sampling
|
||||
for i in range(3): # 3 output sequences were generated
|
||||
print('Generated {}: {}'.format(i, tokenizer.decode(outputs[i], skip_special_tokens=True)))
|
||||
outputs = model.generate(input_ids=input_ids, max_length=40, temperature=0.7, bos_token_id=tokenizer.bos_token_id, eos_token_ids=tokenizer.eos_token_id, num_beams=3) # generate sequences using greedy beam search decoding (3 beams)
|
||||
print('Generated: {}'.format(tokenizer.decode(outputs[0], skip_special_tokens=True)))
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('ctrl') # Initialize tokenizer
|
||||
model = AutoModelWithLMHead.from_pretrained('ctrl') # Download model and configuration from S3 and cache.
|
||||
input_context = 'Legal My neighbor is' # "Legal" is one of the control codes for ctrl
|
||||
input_ids = torch.tensor(tokenizer.encode(input_context)).unsqueeze(0) # encode input context
|
||||
outputs = model.generate(input_ids=input_ids, max_length=50, temperature=0.7, repetition_penalty=1.2) # generate sequences
|
||||
outputs = model.generate(input_ids=input_ids, max_length=50, temperature=0.7, repetition_penalty=1.2) # generate sequences using using greedy search
|
||||
print('Generated: {}'.format(tokenizer.decode(outputs[0], skip_special_tokens=True)))
|
||||
|
||||
"""
|
||||
@@ -721,14 +712,10 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
assert isinstance(top_k, int) and top_k >= 0, "`top_k` should be a positive integer."
|
||||
assert 0 <= top_p <= 1, "`top_p` should be between 0 and 1."
|
||||
assert repetition_penalty >= 1.0, "`repetition_penalty` should be >= 1."
|
||||
assert input_ids is not None or (
|
||||
isinstance(bos_token_id, int) and bos_token_id >= 0
|
||||
), "If input_ids is not defined, `bos_token_id` should be a positive integer."
|
||||
assert pad_token_id is None or (
|
||||
isinstance(pad_token_id, int) and (pad_token_id >= 0)
|
||||
), "`pad_token_id` should be a positive integer."
|
||||
assert (eos_token_ids is None) or (
|
||||
isinstance(eos_token_ids, (list, tuple)) and ((isinstance(e, int) and e >= 0) for e in eos_token_ids)
|
||||
assert isinstance(bos_token_id, int) and bos_token_id >= 0, "`bos_token_id` should be a positive integer."
|
||||
assert isinstance(pad_token_id, int) and pad_token_id >= 0, "`pad_token_id` should be a positive integer."
|
||||
assert isinstance(eos_token_ids, (list, tuple)) and (
|
||||
e >= 0 for e in eos_token_ids
|
||||
), "`eos_token_ids` should be a positive integer or a list/tuple of positive integers."
|
||||
assert length_penalty > 0, "`length_penalty` should be strictely positive."
|
||||
assert (
|
||||
@@ -736,22 +723,12 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
), "`num_return_sequences` should be a strictely positive integer."
|
||||
|
||||
if input_ids is None:
|
||||
assert isinstance(bos_token_id, int) and bos_token_id >= 0, (
|
||||
"you should either supply a context to complete as `input_ids` input "
|
||||
"or a `bos_token_id` (integer >= 0) as a first token to start the generation."
|
||||
)
|
||||
input_ids = torch.full(
|
||||
(batch_size, 1), bos_token_id, dtype=torch.long, device=next(self.parameters()).device
|
||||
)
|
||||
else:
|
||||
assert input_ids.dim() == 2, "Input prompt should be of shape (batch_size, sequence length)."
|
||||
|
||||
if pad_token_id is None and eos_token_ids is not None:
|
||||
logger.warning(
|
||||
"Setting `pad_token_id` to {} (first `eos_token_id`) to generate sequence".format(eos_token_ids[0])
|
||||
)
|
||||
pad_token_id = eos_token_ids[0]
|
||||
|
||||
# current position and vocab size
|
||||
cur_len = input_ids.shape[1]
|
||||
vocab_size = self.config.vocab_size
|
||||
@@ -798,6 +775,8 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
effective_batch_size,
|
||||
)
|
||||
|
||||
if num_return_sequences != 1:
|
||||
output = output.view(batch_size, num_return_sequences, -1)
|
||||
return output
|
||||
|
||||
def _generate_no_beam_search(
|
||||
@@ -819,7 +798,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
"""
|
||||
# current position / max lengths / length of generated sentences / unfinished sentences
|
||||
unfinished_sents = input_ids.new(batch_size).fill_(1)
|
||||
sent_lengths = input_ids.new(batch_size).fill_(max_length)
|
||||
|
||||
past = None
|
||||
|
||||
@@ -855,41 +833,21 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
next_token = torch.argmax(next_token_logits, dim=-1)
|
||||
|
||||
# update generations and finished sentences
|
||||
if eos_token_ids is not None:
|
||||
# pad finished sentences if eos_token_ids exist
|
||||
tokens_to_add = next_token * unfinished_sents + (pad_token_id) * (1 - unfinished_sents)
|
||||
else:
|
||||
tokens_to_add = next_token
|
||||
|
||||
tokens_to_add = next_token * unfinished_sents + pad_token_id * (1 - unfinished_sents)
|
||||
input_ids = torch.cat([input_ids, tokens_to_add.unsqueeze(-1)], dim=-1)
|
||||
|
||||
if eos_token_ids is not None:
|
||||
for eos_token_id in eos_token_ids:
|
||||
eos_in_sents = tokens_to_add == eos_token_id
|
||||
# if sentence is unfinished and the token to add is eos, sent_lengths is filled with current length
|
||||
is_sents_unfinished_and_token_to_add_is_eos = unfinished_sents.mul(eos_in_sents.long()).bool()
|
||||
sent_lengths.masked_fill_(is_sents_unfinished_and_token_to_add_is_eos, cur_len + 1)
|
||||
# unfinished_sents is set to zero if eos in sentence
|
||||
unfinished_sents.mul_((~eos_in_sents).long())
|
||||
|
||||
for eos_token_id in eos_token_ids:
|
||||
unfinished_sents.mul_(tokens_to_add.ne(eos_token_id).long())
|
||||
cur_len = cur_len + 1
|
||||
|
||||
# stop when there is a </s> in each sentence, or if we exceed the maximul length
|
||||
if unfinished_sents.max() == 0:
|
||||
break
|
||||
|
||||
# if there are different sentences lengths in the batch, some batches have to be padded
|
||||
if sent_lengths.min().item() != sent_lengths.max().item():
|
||||
assert pad_token_id is not None, "`Pad_token_id` has to be defined if batches have different lengths"
|
||||
# finished sents are filled with pad_token
|
||||
decoded = input_ids.new(batch_size, sent_lengths.max().item()).fill_(pad_token_id)
|
||||
else:
|
||||
decoded = input_ids
|
||||
# add eos_token_ids to unfinished sentences
|
||||
if cur_len == max_length:
|
||||
input_ids[:, -1].masked_fill_(unfinished_sents.to(dtype=torch.bool), eos_token_ids[0])
|
||||
|
||||
for hypo_idx, hypo in enumerate(input_ids):
|
||||
decoded[hypo_idx, : sent_lengths[hypo_idx]] = hypo[: sent_lengths[hypo_idx]]
|
||||
|
||||
return decoded
|
||||
return input_ids
|
||||
|
||||
def _generate_beam_search(
|
||||
self,
|
||||
@@ -983,19 +941,11 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
next_batch_beam = []
|
||||
|
||||
# for each sentence
|
||||
for batch_idx in range(batch_size):
|
||||
for batch_ex in range(batch_size):
|
||||
|
||||
# if we are done with this sentence
|
||||
done[batch_idx] = done[batch_idx] or generated_hyps[batch_idx].is_done(
|
||||
next_scores[batch_idx].max().item()
|
||||
)
|
||||
if done[batch_idx]:
|
||||
assert (
|
||||
len(generated_hyps[batch_idx]) >= num_beams
|
||||
), "Batch can only be done if at least {} beams have been generated".format(num_beams)
|
||||
assert (
|
||||
eos_token_ids is not None and pad_token_id is not None
|
||||
), "generated beams >= num_beams -> eos_token_id and pad_token have to be defined"
|
||||
done[batch_ex] = done[batch_ex] or generated_hyps[batch_ex].is_done(next_scores[batch_ex].max().item())
|
||||
if done[batch_ex]:
|
||||
next_batch_beam.extend([(0, pad_token_id, 0)] * num_beams) # pad the batch
|
||||
continue
|
||||
|
||||
@@ -1003,29 +953,30 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
next_sent_beam = []
|
||||
|
||||
# next words for this sentence
|
||||
for idx, score in zip(next_words[batch_idx], next_scores[batch_idx]):
|
||||
for idx, score in zip(next_words[batch_ex], next_scores[batch_ex]):
|
||||
|
||||
# get beam and word IDs
|
||||
beam_id = idx // vocab_size
|
||||
word_id = idx % vocab_size
|
||||
|
||||
# add to generated hypotheses if end of sentence or last iteration
|
||||
if eos_token_ids is not None and word_id.item() in eos_token_ids:
|
||||
generated_hyps[batch_idx].add(
|
||||
input_ids[batch_idx * num_beams + beam_id, :cur_len].clone(), score.item()
|
||||
# end of sentence, or next word
|
||||
if word_id.item() in eos_token_ids or cur_len + 1 == max_length:
|
||||
generated_hyps[batch_ex].add(
|
||||
input_ids[batch_ex * num_beams + beam_id, :cur_len].clone(), score.item()
|
||||
)
|
||||
else:
|
||||
# add next predicted word if it is not eos_token
|
||||
next_sent_beam.append((score, word_id, batch_idx * num_beams + beam_id))
|
||||
next_sent_beam.append((score, word_id, batch_ex * num_beams + beam_id))
|
||||
|
||||
# the beam for next step is full
|
||||
if len(next_sent_beam) == num_beams:
|
||||
break
|
||||
|
||||
# update next beam content
|
||||
assert len(next_sent_beam) == num_beams, "Beam should always be full"
|
||||
assert len(next_sent_beam) == 0 if cur_len + 1 == max_length else num_beams
|
||||
if len(next_sent_beam) == 0:
|
||||
next_sent_beam = [(0, pad_token_id, 0)] * num_beams # pad the batch
|
||||
next_batch_beam.extend(next_sent_beam)
|
||||
assert len(next_batch_beam) == num_beams * (batch_idx + 1)
|
||||
assert len(next_batch_beam) == num_beams * (batch_ex + 1)
|
||||
|
||||
# sanity check / prepare next batch
|
||||
assert len(next_batch_beam) == batch_size * num_beams
|
||||
@@ -1057,42 +1008,29 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
if all(done):
|
||||
break
|
||||
|
||||
for batch_idx in range(batch_size):
|
||||
# Add all open beam hypothesis to generated_hyps
|
||||
if not done[batch_idx]:
|
||||
for idx, score in zip(next_words[batch_idx], next_scores[batch_idx]):
|
||||
|
||||
# get beam and word IDs
|
||||
beam_id = idx // vocab_size
|
||||
word_id = idx % vocab_size
|
||||
generated_hyps[batch_idx].add(
|
||||
input_ids[batch_idx * num_beams + beam_id, :cur_len].clone(), score.item()
|
||||
)
|
||||
# visualize hypotheses
|
||||
# print([len(x) for x in generated_hyps], cur_len)
|
||||
# globals().update( locals() );
|
||||
# !import code; code.interact(local=vars())
|
||||
# for ii in range(batch_size):
|
||||
# for ss, ww in sorted(generated_hyps[ii].hyp, key=lambda x: x[0], reverse=True):
|
||||
# print("%.3f " % ss + " ".join(self.dico[x] for x in ww.tolist()))
|
||||
# print("")
|
||||
|
||||
# select the best hypotheses
|
||||
sent_lengths = input_ids.new(batch_size)
|
||||
tgt_len = input_ids.new(batch_size)
|
||||
best = []
|
||||
|
||||
for i, hypotheses in enumerate(generated_hyps):
|
||||
best_hyp = max(hypotheses.beams, key=lambda x: x[0])[1]
|
||||
sent_lengths[i] = len(best_hyp)
|
||||
best_hyp = max(hypotheses.hyp, key=lambda x: x[0])[1]
|
||||
tgt_len[i] = len(best_hyp) + 1 # +1 for the <EOS> symbol
|
||||
best.append(best_hyp)
|
||||
|
||||
# shorter batches are filled with pad_token
|
||||
if sent_lengths.min().item() != sent_lengths.max().item():
|
||||
assert pad_token_id is not None, "`Pad_token_id` has to be defined"
|
||||
sent_max_len = min(sent_lengths.max().item() + 1, max_length)
|
||||
decoded = input_ids.new(batch_size, sent_max_len).fill_(pad_token_id)
|
||||
|
||||
# fill with hypothesis and eos_token_id if necessary
|
||||
for i, hypo in enumerate(best):
|
||||
decoded[i, : sent_lengths[i]] = hypo
|
||||
if sent_lengths[i] < max_length:
|
||||
decoded[i, sent_lengths[i]] = eos_token_ids[0]
|
||||
else:
|
||||
# none of the hypotheses have an eos_token
|
||||
assert (len(hypo) == max_length for hypo in best)
|
||||
decoded = torch.stack(best).type(torch.long).to(next(self.parameters()).device)
|
||||
# generate target batch
|
||||
decoded = input_ids.new(batch_size, tgt_len.max().item()).fill_(pad_token_id)
|
||||
for i, hypo in enumerate(best):
|
||||
decoded[i, : tgt_len[i] - 1] = hypo
|
||||
decoded[i, tgt_len[i] - 1] = eos_token_ids[0]
|
||||
|
||||
return decoded
|
||||
|
||||
@@ -1133,33 +1071,33 @@ def top_k_top_p_filtering(logits, top_k=0, top_p=1.0, filter_value=-float("Inf")
|
||||
|
||||
|
||||
class BeamHypotheses(object):
|
||||
def __init__(self, num_beams, max_length, length_penalty, early_stopping):
|
||||
def __init__(self, n_hyp, max_length, length_penalty, early_stopping):
|
||||
"""
|
||||
Initialize n-best list of hypotheses.
|
||||
"""
|
||||
self.max_length = max_length - 1 # ignoring bos_token
|
||||
self.length_penalty = length_penalty
|
||||
self.early_stopping = early_stopping
|
||||
self.num_beams = num_beams
|
||||
self.beams = []
|
||||
self.n_hyp = n_hyp
|
||||
self.hyp = []
|
||||
self.worst_score = 1e9
|
||||
|
||||
def __len__(self):
|
||||
"""
|
||||
Number of hypotheses in the list.
|
||||
"""
|
||||
return len(self.beams)
|
||||
return len(self.hyp)
|
||||
|
||||
def add(self, hyp, sum_logprobs):
|
||||
"""
|
||||
Add a new hypothesis to the list.
|
||||
"""
|
||||
score = sum_logprobs / len(hyp) ** self.length_penalty
|
||||
if len(self) < self.num_beams or score > self.worst_score:
|
||||
self.beams.append((score, hyp))
|
||||
if len(self) > self.num_beams:
|
||||
sorted_scores = sorted([(s, idx) for idx, (s, _) in enumerate(self.beams)])
|
||||
del self.beams[sorted_scores[0][1]]
|
||||
if len(self) < self.n_hyp or score > self.worst_score:
|
||||
self.hyp.append((score, hyp))
|
||||
if len(self) > self.n_hyp:
|
||||
sorted_scores = sorted([(s, idx) for idx, (s, _) in enumerate(self.hyp)])
|
||||
del self.hyp[sorted_scores[0][1]]
|
||||
self.worst_score = sorted_scores[1][0]
|
||||
else:
|
||||
self.worst_score = min(score, self.worst_score)
|
||||
@@ -1169,7 +1107,7 @@ class BeamHypotheses(object):
|
||||
If there are enough hypotheses and that none of the hypotheses being generated
|
||||
can become better than the worst one in the heap, then we are done with this sentence.
|
||||
"""
|
||||
if len(self) < self.num_beams:
|
||||
if len(self) < self.n_hyp:
|
||||
return False
|
||||
elif self.early_stopping:
|
||||
return True
|
||||
@@ -1510,20 +1448,6 @@ class SequenceSummary(nn.Module):
|
||||
return output
|
||||
|
||||
|
||||
def create_position_ids_from_input_ids(input_ids, padding_idx):
|
||||
""" Replace non-padding symbols with their position numbers. Position numbers begin at
|
||||
padding_idx+1. Padding symbols are ignored. This is modified from fairseq's
|
||||
`utils.make_positions`.
|
||||
|
||||
:param torch.Tensor x:
|
||||
:return torch.Tensor:
|
||||
"""
|
||||
# The series of casts and type-conversions here are carefully balanced to both work with ONNX export and XLA.
|
||||
mask = input_ids.ne(padding_idx).int()
|
||||
incremental_indicies = torch.cumsum(mask, dim=1).type_as(mask) * mask
|
||||
return incremental_indicies.long() + padding_idx
|
||||
|
||||
|
||||
def prune_linear_layer(layer, index, dim=0):
|
||||
""" Prune a linear layer (a model parameters) to keep only entries in index.
|
||||
Return the pruned layer as a new layer with requires_grad=True.
|
||||
|
||||
@@ -512,7 +512,7 @@ class XLMModel(XLMPreTrainedModel):
|
||||
inputs_embeds = self.embeddings(input_ids)
|
||||
|
||||
tensor = inputs_embeds + self.position_embeddings(position_ids).expand_as(inputs_embeds)
|
||||
if langs is not None and self.use_lang_emb and self.n_langs > 1:
|
||||
if langs is not None and self.use_lang_emb:
|
||||
tensor = tensor + self.lang_embeddings(langs)
|
||||
if token_type_ids is not None:
|
||||
tensor = tensor + self.embeddings(token_type_ids)
|
||||
|
||||
@@ -702,9 +702,8 @@ class XLNetModel(XLNetPreTrainedModel):
|
||||
r"""
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLNetConfig`) and inputs:
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_predict, hidden_size)`):
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the last layer of the model.
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
mems (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks).
|
||||
Can be used (see `mems` input) to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -729,7 +728,7 @@ class XLNetModel(XLNetPreTrainedModel):
|
||||
tokenizer = XLNetTokenizer.from_pretrained('xlnet-large-cased')
|
||||
model = XLNetModel.from_pretrained('xlnet-large-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=False)).unsqueeze(0) # Batch size 1
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
@@ -978,21 +977,19 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
labels=None,
|
||||
):
|
||||
r"""
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, num_predict)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for masked language modeling.
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
The labels should correspond to the masked input words that should be predicted and depends on `target_mapping`. Note in order to perform standard auto-regressive language modeling a `<mask>` token has to be added to the `input_ids` (see `prepare_inputs_for_generation` fn and examples below)
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for language modeling.
|
||||
Note that the labels **are shifted** inside the model, i.e. you can set ``lm_labels = input_ids``
|
||||
Indices are selected in ``[-100, 0, ..., config.vocab_size]``
|
||||
All labels set to ``-100`` are ignored, the loss is only
|
||||
All labels set to ``-100`` are ignored (masked), the loss is only
|
||||
computed for labels in ``[0, ..., config.vocab_size]``
|
||||
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLNetConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when ``labels`` is provided)
|
||||
Language modeling loss.
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_predict, config.vocab_size)`):
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`):
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
mems (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks).
|
||||
Can be used (see `past` input) to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -1018,7 +1015,7 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
model = XLNetLMHeadModel.from_pretrained('xlnet-large-cased')
|
||||
|
||||
# We show how to setup inputs to predict a next token using a bi-directional context.
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=False)).unsqueeze(0) # We will predict the masked token
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=True)).unsqueeze(0) # We will predict the masked token
|
||||
perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
|
||||
perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token
|
||||
target_mapping = torch.zeros((1, 1, input_ids.shape[1]), dtype=torch.float) # Shape [1, 1, seq_length] => let's predict one token
|
||||
@@ -1027,18 +1024,6 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping)
|
||||
next_token_logits = outputs[0] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
|
||||
|
||||
# The same way can the XLNetLMHeadModel be used to be trained by standard auto-regressive language modeling.
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=False)).unsqueeze(0) # We will predict the masked token
|
||||
labels = torch.tensor(tokenizer.encode("cute", add_special_tokens=False)).unsqueeze(0)
|
||||
assert labels.shape[0] == 1, 'only one word will be predicted'
|
||||
perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
|
||||
perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token as is done in standard auto-regressive lm training
|
||||
target_mapping = torch.zeros((1, 1, input_ids.shape[1]), dtype=torch.float) # Shape [1, 1, seq_length] => let's predict one token
|
||||
target_mapping[0, 0, -1] = 1.0 # Our first (and only) prediction will be the last token of the sequence (the masked token)
|
||||
|
||||
outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping, labels=labels)
|
||||
loss, next_token_logits = outputs[:2] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
|
||||
|
||||
"""
|
||||
transformer_outputs = self.transformer(
|
||||
input_ids,
|
||||
@@ -1264,10 +1249,8 @@ class XLNetForTokenClassification(XLNetPreTrainedModel):
|
||||
# Only keep active parts of the loss
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.view(-1) == 1
|
||||
active_logits = logits.view(-1, self.num_labels)
|
||||
active_labels = torch.where(
|
||||
active_loss, labels.view(-1), torch.tensor(loss_fct.ignore_index).type_as(labels)
|
||||
)
|
||||
active_logits = logits.view(-1, self.num_labels)[active_loss]
|
||||
active_labels = labels.view(-1)[active_loss]
|
||||
loss = loss_fct(active_logits, active_labels)
|
||||
else:
|
||||
loss = loss_fct(logits.view(-1, self.num_labels), labels.view(-1))
|
||||
|
||||
@@ -649,9 +649,6 @@ class NerPipeline(Pipeline):
|
||||
return answers
|
||||
|
||||
|
||||
TokenClassificationPipeline = NerPipeline
|
||||
|
||||
|
||||
class QuestionAnsweringArgumentHandler(ArgumentHandler):
|
||||
"""
|
||||
QuestionAnsweringPipeline requires the user to provide multiple arguments (i.e. question & context) to be mapped
|
||||
@@ -982,7 +979,7 @@ SUPPORTED_TASKS = {
|
||||
"default": {
|
||||
"model": {"pt": "distilbert-base-cased-distilled-squad", "tf": "distilbert-base-cased-distilled-squad"},
|
||||
"config": None,
|
||||
"tokenizer": ("distilbert-base-cased", {"use_fast": False}),
|
||||
"tokenizer": "distilbert-base-cased",
|
||||
},
|
||||
},
|
||||
"fill-mask": {
|
||||
@@ -992,7 +989,7 @@ SUPPORTED_TASKS = {
|
||||
"default": {
|
||||
"model": {"pt": "distilroberta-base", "tf": "distilroberta-base"},
|
||||
"config": None,
|
||||
"tokenizer": ("distilroberta-base", {"use_fast": False}),
|
||||
"tokenizer": "distilroberta-base",
|
||||
},
|
||||
},
|
||||
}
|
||||
@@ -1004,7 +1001,6 @@ def pipeline(
|
||||
config: Optional[Union[str, PretrainedConfig]] = None,
|
||||
tokenizer: Optional[Union[str, PreTrainedTokenizer]] = None,
|
||||
modelcard: Optional[Union[str, ModelCard]] = None,
|
||||
framework: Optional[str] = None,
|
||||
**kwargs
|
||||
) -> Pipeline:
|
||||
"""
|
||||
@@ -1025,7 +1021,7 @@ def pipeline(
|
||||
if task not in SUPPORTED_TASKS:
|
||||
raise KeyError("Unknown task {}, available tasks are {}".format(task, list(SUPPORTED_TASKS.keys())))
|
||||
|
||||
framework = framework or get_framework(model)
|
||||
framework = get_framework(model)
|
||||
|
||||
targeted_task = SUPPORTED_TASKS[task]
|
||||
task, model_class = targeted_task["impl"], targeted_task[framework]
|
||||
@@ -1057,12 +1053,8 @@ def pipeline(
|
||||
modelcard = config
|
||||
|
||||
# Instantiate tokenizer if needed
|
||||
if isinstance(tokenizer, (str, tuple)):
|
||||
if isinstance(tokenizer, tuple):
|
||||
# For tuple we have (tokenizer name, {kwargs})
|
||||
tokenizer = AutoTokenizer.from_pretrained(tokenizer[0], **tokenizer[1])
|
||||
else:
|
||||
tokenizer = AutoTokenizer.from_pretrained(tokenizer)
|
||||
if isinstance(tokenizer, str):
|
||||
tokenizer = AutoTokenizer.from_pretrained(tokenizer)
|
||||
|
||||
# Instantiate config if needed
|
||||
if isinstance(config, str):
|
||||
|
||||
@@ -19,7 +19,6 @@ import logging
|
||||
import os
|
||||
import unicodedata
|
||||
from shutil import copyfile
|
||||
from typing import List, Optional
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
@@ -56,55 +55,9 @@ SPIECE_UNDERLINE = "▁"
|
||||
|
||||
class AlbertTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Constructs an ALBERT tokenizer. Based on `SentencePiece <https://github.com/google/sentencepiece>`__
|
||||
SentencePiece based tokenizer. Peculiarities:
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
`SentencePiece <https://github.com/google/sentencepiece>`__ file (generally has a .spm extension) that
|
||||
contains the vocabulary necessary to instantiate a tokenizer.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
remove_space (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to strip the text when tokenizing (removing excess spaces before and after the string).
|
||||
keep_accents (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Whether to keep accents when tokenizing.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "[CLS]"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "[SEP]"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "[SEP]"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "[CLS]"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "[MASK]"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
|
||||
Attributes:
|
||||
sp_model (:obj:`SentencePieceProcessor`):
|
||||
The `SentencePiece` processor that is used for every conversion (string, tokens and IDs).
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -161,11 +114,6 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.sp_model)
|
||||
|
||||
def get_vocab(self):
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def __getstate__(self):
|
||||
state = self.__dict__.copy()
|
||||
state["sp_model"] = None
|
||||
@@ -232,28 +180,17 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return self.sp_model.IdToPiece(index)
|
||||
|
||||
def convert_tokens_to_string(self, tokens):
|
||||
"""Converts a sequence of tokens (strings for sub-words) in a single string."""
|
||||
out_string = "".join(tokens).replace(SPIECE_UNDERLINE, " ").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
An ALBERT sequence has the following format:
|
||||
|
||||
- single sequence: ``[CLS] X [SEP]``
|
||||
- pair of sequences: ``[CLS] A [SEP] B [SEP]``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: [CLS] X [SEP]
|
||||
pair of sequences: [CLS] A [SEP] B [SEP]
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -261,30 +198,27 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return cls + token_ids_0 + sep
|
||||
return cls + token_ids_0 + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
raise ValueError(
|
||||
"You should not supply a second sequence if the provided sequence of "
|
||||
"ids is already formatted with special tokens for the model."
|
||||
"ids is already formated with special tokens for the model."
|
||||
)
|
||||
return list(map(lambda x: 1 if x in [self.sep_token_id, self.cls_token_id] else 0, token_ids_0))
|
||||
|
||||
@@ -292,29 +226,14 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
An ALBERT sequence pair mask has the following format:
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence |
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0s).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -324,15 +243,8 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1]
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
""" Save the sentencepiece vocabulary (copy original file) and special tokens file
|
||||
to a directory.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
|
||||
@@ -21,7 +21,6 @@ from collections import OrderedDict
|
||||
from .configuration_auto import (
|
||||
AlbertConfig,
|
||||
AutoConfig,
|
||||
BartConfig,
|
||||
BertConfig,
|
||||
CamembertConfig,
|
||||
CTRLConfig,
|
||||
@@ -38,18 +37,17 @@ from .configuration_auto import (
|
||||
)
|
||||
from .configuration_utils import PretrainedConfig
|
||||
from .tokenization_albert import AlbertTokenizer
|
||||
from .tokenization_bart import BartTokenizer
|
||||
from .tokenization_bert import BertTokenizer, BertTokenizerFast
|
||||
from .tokenization_bert import BertTokenizer
|
||||
from .tokenization_bert_japanese import BertJapaneseTokenizer
|
||||
from .tokenization_camembert import CamembertTokenizer
|
||||
from .tokenization_ctrl import CTRLTokenizer
|
||||
from .tokenization_distilbert import DistilBertTokenizer, DistilBertTokenizerFast
|
||||
from .tokenization_distilbert import DistilBertTokenizer
|
||||
from .tokenization_flaubert import FlaubertTokenizer
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer, OpenAIGPTTokenizerFast
|
||||
from .tokenization_roberta import RobertaTokenizer, RobertaTokenizerFast
|
||||
from .tokenization_gpt2 import GPT2Tokenizer
|
||||
from .tokenization_openai import OpenAIGPTTokenizer
|
||||
from .tokenization_roberta import RobertaTokenizer
|
||||
from .tokenization_t5 import T5Tokenizer
|
||||
from .tokenization_transfo_xl import TransfoXLTokenizer, TransfoXLTokenizerFast
|
||||
from .tokenization_transfo_xl import TransfoXLTokenizer
|
||||
from .tokenization_xlm import XLMTokenizer
|
||||
from .tokenization_xlm_roberta import XLMRobertaTokenizer
|
||||
from .tokenization_xlnet import XLNetTokenizer
|
||||
@@ -60,21 +58,20 @@ logger = logging.getLogger(__name__)
|
||||
|
||||
TOKENIZER_MAPPING = OrderedDict(
|
||||
[
|
||||
(T5Config, (T5Tokenizer, None)),
|
||||
(DistilBertConfig, (DistilBertTokenizer, DistilBertTokenizerFast)),
|
||||
(AlbertConfig, (AlbertTokenizer, None)),
|
||||
(CamembertConfig, (CamembertTokenizer, None)),
|
||||
(XLMRobertaConfig, (XLMRobertaTokenizer, None)),
|
||||
(BartConfig, (BartTokenizer, None)),
|
||||
(RobertaConfig, (RobertaTokenizer, RobertaTokenizerFast)),
|
||||
(BertConfig, (BertTokenizer, BertTokenizerFast)),
|
||||
(OpenAIGPTConfig, (OpenAIGPTTokenizer, OpenAIGPTTokenizerFast)),
|
||||
(GPT2Config, (GPT2Tokenizer, GPT2TokenizerFast)),
|
||||
(TransfoXLConfig, (TransfoXLTokenizer, TransfoXLTokenizerFast)),
|
||||
(XLNetConfig, (XLNetTokenizer, None)),
|
||||
(FlaubertConfig, (FlaubertTokenizer, None)),
|
||||
(XLMConfig, (XLMTokenizer, None)),
|
||||
(CTRLConfig, (CTRLTokenizer, None)),
|
||||
(T5Config, T5Tokenizer),
|
||||
(DistilBertConfig, DistilBertTokenizer),
|
||||
(AlbertConfig, AlbertTokenizer),
|
||||
(CamembertConfig, CamembertTokenizer),
|
||||
(XLMRobertaConfig, XLMRobertaTokenizer),
|
||||
(RobertaConfig, RobertaTokenizer),
|
||||
(BertConfig, BertTokenizer),
|
||||
(OpenAIGPTConfig, OpenAIGPTTokenizer),
|
||||
(GPT2Config, GPT2Tokenizer),
|
||||
(TransfoXLConfig, TransfoXLTokenizer),
|
||||
(XLNetConfig, XLNetTokenizer),
|
||||
(FlaubertConfig, FlaubertTokenizer),
|
||||
(XLMConfig, XLMTokenizer),
|
||||
(CTRLConfig, CTRLTokenizer),
|
||||
]
|
||||
)
|
||||
|
||||
@@ -157,9 +154,6 @@ class AutoTokenizer:
|
||||
A dictionary of proxy servers to use by protocol or endpoint, e.g.: {'http': 'foo.bar:3128', 'http://hostname': 'foo.bar:4012'}.
|
||||
The proxies are used on each request.
|
||||
|
||||
use_fast: (`optional`) boolean, default False:
|
||||
Indicate if transformers should try to load the fast version of the tokenizer (True) or use the Python one (False).
|
||||
|
||||
inputs: (`optional`) positional arguments: will be passed to the Tokenizer ``__init__`` method.
|
||||
|
||||
kwargs: (`optional`) keyword arguments: will be passed to the Tokenizer ``__init__`` method. Can be used to set special tokens like ``bos_token``, ``eos_token``, ``unk_token``, ``sep_token``, ``pad_token``, ``cls_token``, ``mask_token``, ``additional_special_tokens``. See parameters in the doc string of :class:`~transformers.PreTrainedTokenizer` for details.
|
||||
@@ -183,13 +177,9 @@ class AutoTokenizer:
|
||||
if "bert-base-japanese" in pretrained_model_name_or_path:
|
||||
return BertJapaneseTokenizer.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
|
||||
use_fast = kwargs.pop("use_fast", False)
|
||||
for config_class, (tokenizer_class_py, tokenizer_class_fast) in TOKENIZER_MAPPING.items():
|
||||
for config_class, tokenizer_class in TOKENIZER_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
if tokenizer_class_fast and use_fast:
|
||||
return tokenizer_class_fast.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
else:
|
||||
return tokenizer_class_py.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
return tokenizer_class.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
|
||||
raise ValueError(
|
||||
"Unrecognized configuration class {} to build an AutoTokenizer.\n"
|
||||
|
||||
@@ -1,35 +0,0 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2020 The Facebook AI Research Team Authors and The HuggingFace Inc. team.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from .tokenization_roberta import RobertaTokenizer
|
||||
|
||||
|
||||
# vocab and merges same as roberta
|
||||
vocab_url = "https://s3.amazonaws.com/models.huggingface.co/bert/roberta-large-vocab.json"
|
||||
merges_url = "https://s3.amazonaws.com/models.huggingface.co/bert/roberta-large-merges.txt"
|
||||
_all_bart_models = [
|
||||
"bart-large",
|
||||
"bart-large-mnli",
|
||||
# "bart-large-cnn"
|
||||
]
|
||||
|
||||
|
||||
class BartTokenizer(RobertaTokenizer):
|
||||
# merges and vocab same as Roberta
|
||||
max_model_input_sizes = {m: 1024 for m in _all_bart_models}
|
||||
pretrained_vocab_files_map = {
|
||||
"vocab_file": {m: vocab_url for m in _all_bart_models},
|
||||
"merges_file": {m: merges_url for m in _all_bart_models},
|
||||
}
|
||||
@@ -19,9 +19,8 @@ import collections
|
||||
import logging
|
||||
import os
|
||||
import unicodedata
|
||||
from typing import List, Optional
|
||||
|
||||
from tokenizers import BertWordPieceTokenizer
|
||||
import tokenizers as tk
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
|
||||
@@ -118,41 +117,17 @@ def whitespace_tokenize(text):
|
||||
|
||||
class BertTokenizer(PreTrainedTokenizer):
|
||||
r"""
|
||||
Constructs a BERT tokenizer. Based on WordPiece.
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
Constructs a BertTokenizer.
|
||||
:class:`~transformers.BertTokenizer` runs end-to-end tokenization: punctuation splitting + wordpiece
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
File containing the vocabulary.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
do_basic_tokenize (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to do basic tokenization before WordPiece.
|
||||
never_split (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
List of tokens which will never be split during tokenization. Only has an effect when
|
||||
:obj:`do_basic_tokenize=True`
|
||||
unk_token (:obj:`string`, `optional`, defaults to "[UNK]"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "[SEP]"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "[PAD]"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "[CLS]"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "[MASK]"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
tokenize_chinese_chars (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to tokenize Chinese characters.
|
||||
This should likely be deactivated for Japanese:
|
||||
see: https://github.com/huggingface/transformers/issues/328
|
||||
vocab_file: Path to a one-wordpiece-per-line vocabulary file
|
||||
do_lower_case: Whether to lower case the input. Only has an effect when do_basic_tokenize=True
|
||||
do_basic_tokenize: Whether to do basic tokenization before wordpiece.
|
||||
max_len: An artificial maximum length to truncate tokenized sequences to; Effective maximum length is always the
|
||||
minimum of this value (if specified) and the underlying BERT model's sequence length.
|
||||
never_split: List of tokens which will never be split during tokenization. Only has an effect when
|
||||
do_basic_tokenize=True
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -174,6 +149,23 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
tokenize_chinese_chars=True,
|
||||
**kwargs
|
||||
):
|
||||
"""Constructs a BertTokenizer.
|
||||
|
||||
Args:
|
||||
**vocab_file**: Path to a one-wordpiece-per-line vocabulary file
|
||||
**do_lower_case**: (`optional`) boolean (default True)
|
||||
Whether to lower case the input
|
||||
Only has an effect when do_basic_tokenize=True
|
||||
**do_basic_tokenize**: (`optional`) boolean (default True)
|
||||
Whether to do basic tokenization before wordpiece.
|
||||
**never_split**: (`optional`) list of string
|
||||
List of tokens which will never be split during tokenization.
|
||||
Only has an effect when do_basic_tokenize=True
|
||||
**tokenize_chinese_chars**: (`optional`) boolean (default True)
|
||||
Whether to tokenize Chinese characters.
|
||||
This should likely be deactivated for Japanese:
|
||||
see: https://github.com/huggingface/pytorch-pretrained-BERT/issues/328
|
||||
"""
|
||||
super().__init__(
|
||||
unk_token=unk_token,
|
||||
sep_token=sep_token,
|
||||
@@ -203,9 +195,6 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.vocab)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.vocab, **self.added_tokens_encoder)
|
||||
|
||||
def _tokenize(self, text):
|
||||
split_tokens = []
|
||||
if self.do_basic_tokenize:
|
||||
@@ -229,25 +218,13 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
out_string = " ".join(tokens).replace(" ##", "").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A BERT sequence has the following format:
|
||||
|
||||
- single sequence: ``[CLS] X [SEP]``
|
||||
- pair of sequences: ``[CLS] A [SEP] B [SEP]``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: [CLS] X [SEP]
|
||||
pair of sequences: [CLS] A [SEP] B [SEP]
|
||||
"""
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
@@ -255,23 +232,20 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
@@ -286,29 +260,14 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
A BERT sequence pair mask has the following format:
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence |
|
||||
0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -317,16 +276,7 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1]
|
||||
|
||||
def save_vocabulary(self, vocab_path):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
vocab_path (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary to a directory or file."""
|
||||
index = 0
|
||||
if os.path.isdir(vocab_path):
|
||||
vocab_file = os.path.join(vocab_path, VOCAB_FILES_NAMES["vocab_file"])
|
||||
@@ -599,26 +549,15 @@ class BertTokenizerFast(PreTrainedTokenizerFast):
|
||||
pad_token="[PAD]",
|
||||
cls_token="[CLS]",
|
||||
mask_token="[MASK]",
|
||||
clean_text=True,
|
||||
tokenize_chinese_chars=True,
|
||||
max_length=None,
|
||||
pad_to_max_length=False,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
add_special_tokens=True,
|
||||
strip_accents=True,
|
||||
wordpieces_prefix="##",
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(
|
||||
BertWordPieceTokenizer(
|
||||
vocab_file=vocab_file,
|
||||
add_special_tokens=add_special_tokens,
|
||||
unk_token=unk_token,
|
||||
sep_token=sep_token,
|
||||
cls_token=cls_token,
|
||||
clean_text=clean_text,
|
||||
handle_chinese_chars=tokenize_chinese_chars,
|
||||
strip_accents=strip_accents,
|
||||
lowercase=do_lower_case,
|
||||
wordpieces_prefix=wordpieces_prefix,
|
||||
),
|
||||
unk_token=unk_token,
|
||||
sep_token=sep_token,
|
||||
pad_token=pad_token,
|
||||
@@ -627,12 +566,32 @@ class BertTokenizerFast(PreTrainedTokenizerFast):
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
self.do_lower_case = do_lower_case
|
||||
self._tokenizer = tk.Tokenizer(tk.models.WordPiece.from_files(vocab_file, unk_token=unk_token))
|
||||
self._update_special_tokens()
|
||||
self._tokenizer.with_pre_tokenizer(
|
||||
tk.pre_tokenizers.BertPreTokenizer.new(
|
||||
do_basic_tokenize=do_basic_tokenize,
|
||||
do_lower_case=do_lower_case,
|
||||
tokenize_chinese_chars=tokenize_chinese_chars,
|
||||
never_split=never_split if never_split is not None else [],
|
||||
)
|
||||
)
|
||||
self._tokenizer.with_decoder(tk.decoders.WordPiece.new())
|
||||
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
output = [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
|
||||
if token_ids_1:
|
||||
output += token_ids_1 + [self.sep_token_id]
|
||||
|
||||
return output
|
||||
if add_special_tokens:
|
||||
self._tokenizer.with_post_processor(
|
||||
tk.processors.BertProcessing.new(
|
||||
(sep_token, self._tokenizer.token_to_id(sep_token)),
|
||||
(cls_token, self._tokenizer.token_to_id(cls_token)),
|
||||
)
|
||||
)
|
||||
if max_length is not None:
|
||||
self._tokenizer.with_truncation(max_length, stride=stride, strategy=truncation_strategy)
|
||||
self._tokenizer.with_padding(
|
||||
max_length=max_length if pad_to_max_length else None,
|
||||
direction=self.padding_side,
|
||||
pad_id=self.pad_token_id,
|
||||
pad_type_id=self.pad_token_type_id,
|
||||
pad_token=self.pad_token,
|
||||
)
|
||||
self._decoder = tk.decoders.WordPiece.new()
|
||||
@@ -18,7 +18,6 @@
|
||||
import logging
|
||||
import os
|
||||
from shutil import copyfile
|
||||
from typing import List, Optional
|
||||
|
||||
import sentencepiece as spm
|
||||
|
||||
@@ -54,50 +53,7 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
Adapted from RobertaTokenizer and XLNetTokenizer
|
||||
SentencePiece based tokenizer. Peculiarities:
|
||||
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<mask>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`["<s>NOTUSED", "</s>NOTUSED"]`):
|
||||
Additional special tokens used by the tokenizer.
|
||||
|
||||
Attributes:
|
||||
sp_model (:obj:`SentencePieceProcessor`):
|
||||
The `SentencePiece` processor that is used for every conversion (string, tokens and IDs).
|
||||
- requires `SentencePiece <https://github.com/google/sentencepiece>`_
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -141,50 +97,34 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
self.fairseq_tokens_to_ids["<mask>"] = len(self.sp_model) + len(self.fairseq_tokens_to_ids)
|
||||
self.fairseq_ids_to_tokens = {v: k for k, v in self.fairseq_tokens_to_ids.items()}
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A CamemBERT sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s></s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
A RoBERTa sequence has the following format:
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s></s> B </s>
|
||||
"""
|
||||
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
@@ -198,29 +138,14 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
A CamemBERT sequence pair mask has the following format:
|
||||
A RoBERTa sequence pair mask has the following format:
|
||||
0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | | second sequence |
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0s).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -275,15 +200,8 @@ class CamembertTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the sentencepiece vocabulary (copy original file) and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
""" Save the sentencepiece vocabulary (copy original file) and special tokens file
|
||||
to a directory.
|
||||
"""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
|
||||
@@ -116,21 +116,8 @@ def get_pairs(word):
|
||||
|
||||
class CTRLTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Constructs a CTRL tokenizer. Peculiarities:
|
||||
|
||||
- Byte-Pair-Encoding
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
CTRL BPE tokenizer. Peculiarities:
|
||||
- Byte-Pair-Encoding
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -160,9 +147,6 @@ class CTRLTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
if token in self.cache:
|
||||
return self.cache[token]
|
||||
@@ -232,16 +216,7 @@ class CTRLTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
|
||||
@@ -17,7 +17,7 @@
|
||||
|
||||
import logging
|
||||
|
||||
from .tokenization_bert import BertTokenizer, BertTokenizerFast
|
||||
from .tokenization_bert import BertTokenizer
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -58,21 +58,19 @@ PRETRAINED_INIT_CONFIGURATION = {
|
||||
class DistilBertTokenizer(BertTokenizer):
|
||||
r"""
|
||||
Constructs a DistilBertTokenizer.
|
||||
:class:`~transformers.DistilBertTokenizer` is identical to :class:`~transformers.BertTokenizer` and runs end-to-end
|
||||
tokenization: punctuation splitting + wordpiece.
|
||||
:class:`~transformers.DistilBertTokenizer` is identical to BertTokenizer and runs end-to-end tokenization: punctuation splitting + wordpiece
|
||||
|
||||
Refer to superclass :class:`~transformers.BertTokenizer` for usage examples and documentation concerning
|
||||
parameters.
|
||||
Args:
|
||||
vocab_file: Path to a one-wordpiece-per-line vocabulary file
|
||||
do_lower_case: Whether to lower case the input. Only has an effect when do_basic_tokenize=True
|
||||
do_basic_tokenize: Whether to do basic tokenization before wordpiece.
|
||||
max_len: An artificial maximum length to truncate tokenized sequences to; Effective maximum length is always the
|
||||
minimum of this value (if specified) and the underlying BERT model's sequence length.
|
||||
never_split: List of tokens which will never be split during tokenization. Only has an effect when
|
||||
do_basic_tokenize=True
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
pretrained_init_configuration = PRETRAINED_INIT_CONFIGURATION
|
||||
|
||||
|
||||
class DistilBertTokenizerFast(BertTokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
pretrained_init_configuration = PRETRAINED_INIT_CONFIGURATION
|
||||
@@ -80,14 +80,14 @@ class FlaubertTokenizer(XLMTokenizer):
|
||||
"""
|
||||
BPE tokenizer for Flaubert
|
||||
|
||||
- Moses preprocessing & tokenization
|
||||
- Normalize all inputs text
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
- `do_lowercase` controle lower casing (automatically set for pretrained vocabularies)
|
||||
- Moses preprocessing & tokenization
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.XLMTokenizer`. Please check the superclass for usage examples
|
||||
and documentation regarding arguments.
|
||||
- Normalize all inputs text
|
||||
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
|
||||
- `do_lowercase` controle lower casing (automatically set for pretrained vocabularies)
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
|
||||
@@ -21,7 +21,7 @@ import os
|
||||
from functools import lru_cache
|
||||
|
||||
import regex as re
|
||||
from tokenizers import ByteLevelBPETokenizer
|
||||
import tokenizers as tk
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
|
||||
@@ -101,35 +101,11 @@ def get_pairs(word):
|
||||
class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
GPT-2 BPE tokenizer. Peculiarities:
|
||||
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer ``encode`` and ``decode`` method will not conserve
|
||||
the absence of a space at the beginning of a string:
|
||||
|
||||
::
|
||||
|
||||
tokenizer.decode(tokenizer.encode("Hello")) = " Hello"
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
errors (:obj:`str`, `optional`, defaults to "replace"):
|
||||
Paradigm to follow when decoding bytes to UTF-8. See `bytes.decode
|
||||
<https://docs.python.org/3/library/stdtypes.html#bytes.decode>`__ for more information.
|
||||
unk_token (:obj:`string`, `optional`, defaults to `<|endoftext|>`):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
bos_token (:obj:`string`, `optional`, defaults to `<|endoftext|>`):
|
||||
The beginning of sequence token.
|
||||
eos_token (:obj:`string`, `optional`, defaults to `<|endoftext|>`):
|
||||
The end of sequence token.
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding and tokenize methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer's ``encode``, ``decode``, and ``tokenize`` methods will not conserve
|
||||
the spaces at the beginning of a string: `tokenizer.decode(tokenizer.encode(" Hello")) = "Hello"`
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -173,9 +149,6 @@ class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
if token in self.cache:
|
||||
return self.cache[token]
|
||||
@@ -218,8 +191,15 @@ class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
self.cache[token] = word
|
||||
return word
|
||||
|
||||
def _tokenize(self, text):
|
||||
""" Tokenize a string. """
|
||||
def _tokenize(self, text, add_prefix_space=False):
|
||||
""" Tokenize a string.
|
||||
Args:
|
||||
- add_prefix_space (boolean, default False):
|
||||
Begin the sentence with at least one space to get invariance to word order in GPT-2 (and RoBERTa) tokenizers.
|
||||
"""
|
||||
if add_prefix_space:
|
||||
text = " " + text
|
||||
|
||||
bpe_tokens = []
|
||||
for token in re.findall(self.pat, text):
|
||||
token = "".join(
|
||||
@@ -243,16 +223,7 @@ class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
return text
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
@@ -277,11 +248,6 @@ class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
|
||||
return vocab_file, merge_file
|
||||
|
||||
def prepare_for_tokenization(self, text, **kwargs):
|
||||
if "add_prefix_space" in kwargs and kwargs["add_prefix_space"]:
|
||||
return " " + text
|
||||
return text
|
||||
|
||||
|
||||
class GPT2TokenizerFast(PreTrainedTokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -295,13 +261,26 @@ class GPT2TokenizerFast(PreTrainedTokenizerFast):
|
||||
unk_token="<|endoftext|>",
|
||||
bos_token="<|endoftext|>",
|
||||
eos_token="<|endoftext|>",
|
||||
pad_to_max_length=False,
|
||||
add_prefix_space=False,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(
|
||||
ByteLevelBPETokenizer(vocab_file=vocab_file, merges_file=merges_file, add_prefix_space=add_prefix_space),
|
||||
bos_token=bos_token,
|
||||
eos_token=eos_token,
|
||||
unk_token=unk_token,
|
||||
**kwargs,
|
||||
super().__init__(bos_token=bos_token, eos_token=eos_token, unk_token=unk_token, **kwargs)
|
||||
|
||||
self._tokenizer = tk.Tokenizer(tk.models.BPE.from_files(vocab_file, merges_file))
|
||||
self._update_special_tokens()
|
||||
self._tokenizer.with_pre_tokenizer(tk.pre_tokenizers.ByteLevel.new(add_prefix_space=add_prefix_space))
|
||||
self._tokenizer.with_decoder(tk.decoders.ByteLevel.new())
|
||||
if max_length:
|
||||
self._tokenizer.with_truncation(max_length, stride=stride, strategy=truncation_strategy)
|
||||
self._tokenizer.with_padding(
|
||||
max_length=max_length if pad_to_max_length else None,
|
||||
direction=self.padding_side,
|
||||
pad_id=self.pad_token_id if self.pad_token_id is not None else 0,
|
||||
pad_type_id=self.pad_token_type_id,
|
||||
pad_token=self.pad_token if self.pad_token is not None else "",
|
||||
)
|
||||
self._decoder = tk.decoders.ByteLevel.new()
|
||||
@@ -19,18 +19,9 @@ import json
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
from typing import List, Optional, Union
|
||||
|
||||
from tokenizers import Tokenizer
|
||||
from tokenizers.decoders import BPEDecoder
|
||||
from tokenizers.implementations import BaseTokenizer
|
||||
from tokenizers.models import BPE
|
||||
from tokenizers.normalizers import BertNormalizer, Sequence, unicode_normalizer_from_str
|
||||
from tokenizers.pre_tokenizers import BertPreTokenizer
|
||||
from tokenizers.trainers import BpeTrainer
|
||||
|
||||
from .tokenization_bert import BasicTokenizer
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -82,21 +73,8 @@ def text_standardize(text):
|
||||
class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
BPE tokenizer. Peculiarities:
|
||||
|
||||
- lower case all inputs
|
||||
- uses SpaCy tokenizer and ftfy for pre-BPE tokenization if they are installed, fallback to BERT's BasicTokenizer if not.
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
- lower case all inputs
|
||||
- uses SpaCy tokenizer and ftfy for pre-BPE tokenization if they are installed, fallback to BERT's BasicTokenizer if not.
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -138,9 +116,6 @@ class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
word = tuple(token[:-1]) + (token[-1] + "</w>",)
|
||||
if token in self.cache:
|
||||
@@ -214,16 +189,7 @@ class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
return out_string
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
@@ -247,93 +213,3 @@ class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
index += 1
|
||||
|
||||
return vocab_file, merge_file
|
||||
|
||||
|
||||
class _OpenAIGPTCharBPETokenizer(BaseTokenizer):
|
||||
"""
|
||||
OpenAI character-level BPE Tokenizer
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file: Optional[str] = None,
|
||||
merges_file: Optional[str] = None,
|
||||
unk_token: Optional[str] = "<unk>",
|
||||
suffix: Optional[str] = "</w>",
|
||||
dropout: Optional[float] = None,
|
||||
unicode_normalizer: Optional[str] = None,
|
||||
):
|
||||
if vocab_file is not None and merges_file is not None:
|
||||
tokenizer = Tokenizer(
|
||||
BPE.from_files(
|
||||
vocab_file, merges_file, dropout=dropout, unk_token=unk_token, end_of_word_suffix=suffix
|
||||
)
|
||||
)
|
||||
else:
|
||||
tokenizer = Tokenizer(BPE.empty())
|
||||
|
||||
# Check for Unicode normalization first (before everything else)
|
||||
normalizers = []
|
||||
|
||||
if unicode_normalizer:
|
||||
normalizers += [unicode_normalizer_from_str(unicode_normalizer)]
|
||||
|
||||
# OpenAI normalization is the same as Bert
|
||||
normalizers += [BertNormalizer()]
|
||||
|
||||
# Create the normalizer structure
|
||||
if len(normalizers) > 0:
|
||||
if len(normalizers) > 1:
|
||||
tokenizer.normalizer = Sequence(normalizers)
|
||||
else:
|
||||
tokenizer.normalizer = normalizers[0]
|
||||
|
||||
tokenizer.pre_tokenizer = BertPreTokenizer()
|
||||
tokenizer.decoder = BPEDecoder(suffix=suffix)
|
||||
|
||||
parameters = {
|
||||
"model": "BPE",
|
||||
"unk_token": unk_token,
|
||||
"suffix": suffix,
|
||||
"dropout": dropout,
|
||||
}
|
||||
|
||||
super().__init__(tokenizer, parameters)
|
||||
|
||||
def train(
|
||||
self,
|
||||
files: Union[str, List[str]],
|
||||
vocab_size: int = 30000,
|
||||
min_frequency: int = 2,
|
||||
special_tokens: List[str] = ["<unk>"],
|
||||
limit_alphabet: int = 1000,
|
||||
initial_alphabet: List[str] = [],
|
||||
suffix: Optional[str] = "</w>",
|
||||
show_progress: bool = True,
|
||||
):
|
||||
""" Train the model using the given files """
|
||||
|
||||
trainer = BpeTrainer(
|
||||
vocab_size=vocab_size,
|
||||
min_frequency=min_frequency,
|
||||
special_tokens=special_tokens,
|
||||
limit_alphabet=limit_alphabet,
|
||||
initial_alphabet=initial_alphabet,
|
||||
end_of_word_suffix=suffix,
|
||||
show_progress=show_progress,
|
||||
)
|
||||
if isinstance(files, str):
|
||||
files = [files]
|
||||
self._tokenizer.train(trainer, files)
|
||||
|
||||
|
||||
class OpenAIGPTTokenizerFast(PreTrainedTokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
def __init__(self, vocab_file, merges_file, unk_token="<unk>", **kwargs):
|
||||
kwargs.setdefault("unk_token", unk_token)
|
||||
super().__init__(
|
||||
_OpenAIGPTCharBPETokenizer(vocab_file=vocab_file, merges_file=merges_file, unk_token=unk_token), **kwargs
|
||||
)
|
||||
@@ -16,11 +16,8 @@
|
||||
|
||||
|
||||
import logging
|
||||
from typing import List, Optional
|
||||
|
||||
from tokenizers.processors import RobertaProcessing
|
||||
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_gpt2 import GPT2Tokenizer
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -61,59 +58,12 @@ PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
|
||||
class RobertaTokenizer(GPT2Tokenizer):
|
||||
"""
|
||||
Constructs a RoBERTa BPE tokenizer, derived from the GPT-2 tokenizer. Peculiarities:
|
||||
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer ``encode`` and ``decode`` method will not conserve
|
||||
the absence of a space at the beginning of a string:
|
||||
|
||||
::
|
||||
|
||||
tokenizer.decode(tokenizer.encode("Hello")) = " Hello"
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`str`):
|
||||
Path to the vocabulary file.
|
||||
merges_file (:obj:`str`):
|
||||
Path to the merges file.
|
||||
errors (:obj:`str`, `optional`, defaults to "replace"):
|
||||
Paradigm to follow when decoding bytes to UTF-8. See `bytes.decode
|
||||
<https://docs.python.org/3/library/stdtypes.html#bytes.decode>`__ for more information.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
|
||||
.. note::
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the end
|
||||
of sequence. The token used is the :obj:`sep_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<mask>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
RoBERTa BPE tokenizer, derived from the GPT-2 tokenizer. Peculiarities:
|
||||
- Byte-level Byte-Pair-Encoding
|
||||
- Requires a space to start the input string => the encoding methods should be called with the
|
||||
``add_prefix_space`` flag set to ``True``.
|
||||
Otherwise, this tokenizer ``encode`` and ``decode`` method will not conserve
|
||||
the absence of a space at the beginning of a string: `tokenizer.decode(tokenizer.encode("Hello")) = " Hello"`
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -150,25 +100,13 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
self.max_len_single_sentence = self.max_len - 2 # take into account special tokens
|
||||
self.max_len_sentences_pair = self.max_len - 4 # take into account special tokens
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A RoBERTa sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s></s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s></s> B </s>
|
||||
"""
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
@@ -176,23 +114,20 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
sep = [self.sep_token_id]
|
||||
return cls + token_ids_0 + sep + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
if already_has_special_tokens:
|
||||
if token_ids_1 is not None:
|
||||
@@ -206,22 +141,12 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1, 1] + ([0] * len(token_ids_1)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
RoBERTa does not make use of token type ids, therefore a list of zeros is returned.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of zeros.
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -229,70 +154,3 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
if token_ids_1 is None:
|
||||
return len(cls + token_ids_0 + sep) * [0]
|
||||
return len(cls + token_ids_0 + sep + sep + token_ids_1 + sep) * [0]
|
||||
|
||||
def prepare_for_tokenization(self, text, add_special_tokens=False, **kwargs):
|
||||
if "add_prefix_space" in kwargs:
|
||||
add_prefix_space = kwargs["add_prefix_space"]
|
||||
else:
|
||||
add_prefix_space = add_special_tokens
|
||||
if add_prefix_space and not text[0].isspace():
|
||||
text = " " + text
|
||||
return text
|
||||
|
||||
|
||||
class RobertaTokenizerFast(GPT2TokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file,
|
||||
merges_file,
|
||||
errors="replace",
|
||||
bos_token="<s>",
|
||||
eos_token="</s>",
|
||||
sep_token="</s>",
|
||||
cls_token="<s>",
|
||||
unk_token="<unk>",
|
||||
pad_token="<pad>",
|
||||
mask_token="<mask>",
|
||||
add_prefix_space=False,
|
||||
**kwargs
|
||||
):
|
||||
kwargs.setdefault("pad_token", pad_token)
|
||||
kwargs.setdefault("sep_token", sep_token)
|
||||
kwargs.setdefault("cls_token", cls_token)
|
||||
kwargs.setdefault("mask_token", mask_token)
|
||||
|
||||
super().__init__(
|
||||
vocab_file=vocab_file,
|
||||
merges_file=merges_file,
|
||||
unk_token=unk_token,
|
||||
bos_token=bos_token,
|
||||
eos_token=eos_token,
|
||||
add_prefix_space=add_prefix_space,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
self.tokenizer._tokenizer.post_processor = RobertaProcessing(
|
||||
(sep_token, self.sep_token_id), (cls_token, self.cls_token_id)
|
||||
)
|
||||
|
||||
# As we override the post_processor post super.__init__ the computed num_added_tokens is wrong in super().
|
||||
# We need to recompute max_len according to the newly register post_processor to get real values.
|
||||
self.max_len_single_sentence = self.max_len - self.num_added_tokens(False) # take into account special tokens
|
||||
self.max_len_sentences_pair = self.max_len - self.num_added_tokens(True) # take into account special tokens
|
||||
|
||||
logger.warning(
|
||||
"RobertaTokenizerFast has an issue when working on mask language modeling "
|
||||
"where it introduces an extra encoded space before the mask token."
|
||||
"See https://github.com/huggingface/transformers/pull/2778 for more information."
|
||||
)
|
||||
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
output = [self.bos_token_id] + token_ids_0 + [self.eos_token_id]
|
||||
if token_ids_1 is None:
|
||||
return output
|
||||
|
||||
return output + [self.eos_token_id] + token_ids_1 + [self.eos_token_id]
|
||||
@@ -98,12 +98,6 @@ class T5Tokenizer(PreTrainedTokenizer):
|
||||
additional_special_tokens=additional_special_tokens,
|
||||
**kwargs,
|
||||
)
|
||||
self.max_len_single_sentence = (
|
||||
self.max_len
|
||||
) # no default special tokens - you can update this value if you add special tokens
|
||||
self.max_len_sentences_pair = (
|
||||
self.max_len
|
||||
) # no default special tokens - you can update this value if you add special tokens
|
||||
|
||||
try:
|
||||
import sentencepiece as spm
|
||||
@@ -125,11 +119,6 @@ class T5Tokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return self.sp_model.get_piece_size() + self._extra_ids
|
||||
|
||||
def get_vocab(self):
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def __getstate__(self):
|
||||
state = self.__dict__.copy()
|
||||
state["sp_model"] = None
|
||||
|
||||
@@ -22,20 +22,12 @@ import glob
|
||||
import logging
|
||||
import os
|
||||
import pickle
|
||||
import re
|
||||
from collections import Counter, OrderedDict
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
from tokenizers import Encoding, Tokenizer
|
||||
from tokenizers.implementations import BaseTokenizer
|
||||
from tokenizers.models import WordLevel
|
||||
from tokenizers.normalizers import Lowercase, Sequence, unicode_normalizer_from_str
|
||||
from tokenizers.pre_tokenizers import CharDelimiterSplit, WhitespaceSplit
|
||||
from tokenizers.processors import BertProcessing
|
||||
|
||||
from .file_utils import cached_path, is_torch_available
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
@@ -45,7 +37,6 @@ if is_torch_available():
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
VOCAB_FILES_NAMES = {"pretrained_vocab_file": "vocab.bin", "vocab_file": "vocab.txt"}
|
||||
VOCAB_FILES_NAMES_FAST = {"pretrained_vocab_file": "vocab.json", "vocab_file": "vocab.json"}
|
||||
|
||||
PRETRAINED_VOCAB_FILES_MAP = {
|
||||
"pretrained_vocab_file": {
|
||||
@@ -53,12 +44,6 @@ PRETRAINED_VOCAB_FILES_MAP = {
|
||||
}
|
||||
}
|
||||
|
||||
PRETRAINED_VOCAB_FILES_MAP_FAST = {
|
||||
"pretrained_vocab_file": {
|
||||
"transfo-xl-wt103": "https://s3.amazonaws.com/models.huggingface.co/bert/transfo-xl-wt103-vocab.json",
|
||||
}
|
||||
}
|
||||
|
||||
PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
"transfo-xl-wt103": None,
|
||||
}
|
||||
@@ -72,9 +57,6 @@ CORPUS_NAME = "corpus.bin"
|
||||
class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Transformer-XL tokenizer adapted from Vocab class in https://github.com/kimiyoung/transformer-xl
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -119,36 +101,18 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
self.delimiter = delimiter
|
||||
self.vocab_file = vocab_file
|
||||
self.never_split = never_split
|
||||
self.punctuation_symbols = '!"#$%&()*+,-./\:;<=>?@[\\]^_`{|}~' # noqa: W605
|
||||
self.punction_without_space_before_pattern = re.compile(r"[^\s][{}]".format(self.punctuation_symbols))
|
||||
self.punctuation_with_space_around_pattern = self._compile_space_around_punctuation_pattern()
|
||||
|
||||
try:
|
||||
if pretrained_vocab_file is not None:
|
||||
# Hack because, honestly this tokenizer was not made to be used
|
||||
# in a library like ours, at all.
|
||||
vocab_dict = torch.load(pretrained_vocab_file)
|
||||
for key, value in vocab_dict.items():
|
||||
if key not in self.__dict__:
|
||||
self.__dict__[key] = value
|
||||
|
||||
if vocab_file is not None:
|
||||
self.build_vocab()
|
||||
except Exception:
|
||||
raise ValueError(
|
||||
"Unable to parse file {}. Unknown format. "
|
||||
"If you tried to load a model saved through TransfoXLTokenizerFast,"
|
||||
"please note they are not compatible.".format(pretrained_vocab_file)
|
||||
)
|
||||
if pretrained_vocab_file is not None:
|
||||
# Hack because, honestly this tokenizer was not made to be used
|
||||
# in a library like ours, at all.
|
||||
vocab_dict = torch.load(pretrained_vocab_file)
|
||||
for key, value in vocab_dict.items():
|
||||
if key not in self.__dict__:
|
||||
self.__dict__[key] = value
|
||||
|
||||
if vocab_file is not None:
|
||||
self.build_vocab()
|
||||
|
||||
def _compile_space_around_punctuation_pattern(self):
|
||||
look_ahead_for_special_token = "(?=[{}])".format(self.punctuation_symbols)
|
||||
look_ahead_to_match_all_except_space = "(?=[^\s])" # noqa: W605
|
||||
return re.compile(r"" + look_ahead_for_special_token + look_ahead_to_match_all_except_space)
|
||||
|
||||
def count_file(self, path, verbose=False, add_eos=False):
|
||||
if verbose:
|
||||
logger.info("counting file {} ...".format(path))
|
||||
@@ -192,22 +156,7 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
raise ValueError("No <unkown> token in vocabulary")
|
||||
|
||||
def save_vocabulary(self, vocab_path):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
vocab_path (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
|
||||
logger.warning(
|
||||
"Please note you will not be able to load the save vocabulary in"
|
||||
" Rust-based TransfoXLTokenizerFast as they don't share the same structure."
|
||||
)
|
||||
|
||||
"""Save the tokenizer vocabulary to a directory or file."""
|
||||
if os.path.isdir(vocab_path):
|
||||
vocab_file = os.path.join(vocab_path, VOCAB_FILES_NAMES["pretrained_vocab_file"])
|
||||
else:
|
||||
@@ -311,9 +260,6 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.idx2sym)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.sym2idx, **self.added_tokens_encoder)
|
||||
|
||||
def _tokenize(self, line, add_eos=False, add_double_eos=False):
|
||||
line = line.strip()
|
||||
# convert to lower case
|
||||
@@ -333,136 +279,6 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
else:
|
||||
return symbols
|
||||
|
||||
def prepare_for_tokenization(self, text, **kwargs):
|
||||
# add spaces before punctuation symbols as should be done in transfo-xl
|
||||
|
||||
if "add_space_before_punct_symbol" in kwargs and kwargs["add_space_before_punct_symbol"]:
|
||||
text = self.punctuation_with_space_around_pattern.sub(r" ", text)
|
||||
elif self.punction_without_space_before_pattern.search(text):
|
||||
# searches until the first occurence of a punctuation symbol without surrounding spaces
|
||||
logger.warning(
|
||||
"You might want to consider setting `add_space_before_punct_symbol=True` as an argument to the `tokenizer.encode()` to avoid tokenizing words with punctuation symbols to the `<unk>` token"
|
||||
)
|
||||
|
||||
return text
|
||||
|
||||
|
||||
class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file,
|
||||
delimiter,
|
||||
lowercase,
|
||||
unk_token,
|
||||
eos_token,
|
||||
add_eos=False,
|
||||
add_double_eos=False,
|
||||
normalization: Optional[str] = None,
|
||||
):
|
||||
|
||||
try:
|
||||
tokenizer = WordLevel.from_files(vocab_file, unk_token=unk_token)
|
||||
tokenizer = Tokenizer(tokenizer)
|
||||
except Exception:
|
||||
raise ValueError(
|
||||
"Unable to parse file {}. Unknown format. "
|
||||
"If you tried to load a model saved through TransfoXLTokenizer,"
|
||||
"please note they are not compatible.".format(vocab_file)
|
||||
)
|
||||
|
||||
# Create the correct normalization path
|
||||
normalizer = []
|
||||
|
||||
# Include unicode normalization
|
||||
if normalization:
|
||||
normalizer += [unicode_normalizer_from_str(normalization)]
|
||||
|
||||
# Include case normalization
|
||||
if lowercase:
|
||||
normalizer += [Lowercase()]
|
||||
|
||||
if len(normalizer) > 0:
|
||||
tokenizer.normalizer = Sequence(normalizer) if len(normalizer) > 1 else normalizer[0]
|
||||
|
||||
# Setup the splitter
|
||||
tokenizer.pre_tokenizer = CharDelimiterSplit(delimiter) if delimiter else WhitespaceSplit()
|
||||
|
||||
if add_double_eos:
|
||||
tokenizer.post_processor = BertProcessing(
|
||||
(eos_token, tokenizer.token_to_id(eos_token)), (eos_token, tokenizer.token_to_id(eos_token))
|
||||
)
|
||||
|
||||
parameters = {
|
||||
"model": "TransfoXLModel",
|
||||
"add_eos": add_eos,
|
||||
"add_double_eos": add_double_eos,
|
||||
"unk_token": unk_token,
|
||||
"eos_token": eos_token,
|
||||
"delimiter": delimiter,
|
||||
"lowercase": lowercase,
|
||||
}
|
||||
|
||||
super().__init__(tokenizer, parameters)
|
||||
|
||||
def encode_batch(self, sequences: List[Union[str, Tuple[str, str]]]) -> List[Encoding]:
|
||||
return super().encode_batch(
|
||||
[seq.strip() if isinstance(seq, str) else (seq[0].strip(), seq[1].strip()) for seq in sequences]
|
||||
)
|
||||
|
||||
def encode(self, sequence: str, pair: Optional[str] = None) -> Encoding:
|
||||
return super().encode(sequence.strip(), pair.strip() if pair else pair)
|
||||
|
||||
|
||||
class TransfoXLTokenizerFast(PreTrainedTokenizerFast):
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES_FAST
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP_FAST
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
special=None,
|
||||
min_freq=0,
|
||||
max_size=None,
|
||||
lower_case=False,
|
||||
delimiter=None,
|
||||
vocab_file=None,
|
||||
pretrained_vocab_file=None,
|
||||
never_split=None,
|
||||
unk_token="<unk>",
|
||||
eos_token="<eos>",
|
||||
additional_special_tokens=["<formula>"],
|
||||
add_eos=False,
|
||||
add_double_eos=False,
|
||||
normalization=None,
|
||||
**kwargs
|
||||
):
|
||||
|
||||
super().__init__(
|
||||
_TransfoXLDelimiterLookupTokenizer(
|
||||
vocab_file=vocab_file or pretrained_vocab_file,
|
||||
delimiter=delimiter,
|
||||
lowercase=lower_case,
|
||||
unk_token=unk_token,
|
||||
eos_token=eos_token,
|
||||
add_eos=add_eos,
|
||||
add_double_eos=add_double_eos,
|
||||
normalization=normalization,
|
||||
),
|
||||
unk_token=unk_token,
|
||||
eos_token=eos_token,
|
||||
additional_special_tokens=additional_special_tokens,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
def save_pretrained(self, save_directory):
|
||||
logger.warning(
|
||||
"Please note you will not be able to load the vocabulary in"
|
||||
" Python-based TransfoXLTokenizer as they don't share the same structure."
|
||||
)
|
||||
|
||||
return super().save_pretrained(save_directory)
|
||||
|
||||
|
||||
class LMOrderedIterator(object):
|
||||
def __init__(self, data, bsz, bptt, device="cpu", ext_len=None):
|
||||
|
||||
@@ -14,16 +14,13 @@
|
||||
# limitations under the License.
|
||||
"""Tokenization classes for OpenAI GPT."""
|
||||
|
||||
|
||||
import copy
|
||||
import itertools
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
from collections import defaultdict
|
||||
from contextlib import contextmanager
|
||||
|
||||
from tokenizers.implementations import BaseTokenizer
|
||||
|
||||
from .file_utils import cached_path, hf_bucket_url, is_remote_url, is_tf_available, is_torch_available
|
||||
|
||||
@@ -40,68 +37,6 @@ ADDED_TOKENS_FILE = "added_tokens.json"
|
||||
TOKENIZER_CONFIG_FILE = "tokenizer_config.json"
|
||||
|
||||
|
||||
@contextmanager
|
||||
def truncate_and_pad(
|
||||
tokenizer: BaseTokenizer,
|
||||
max_length: int,
|
||||
stride: int,
|
||||
strategy: str,
|
||||
pad_to_max_length: bool,
|
||||
padding_side: str,
|
||||
pad_token_id: int,
|
||||
pad_token_type_id: int,
|
||||
pad_token: str,
|
||||
):
|
||||
"""
|
||||
This contextmanager is in charge of defining the truncation and the padding strategies and then
|
||||
restore the tokenizer settings afterwards.
|
||||
|
||||
This contextmanager assumes the provider tokenizer has no padding / truncation strategy
|
||||
before the managed section. If your tokenizer set a padding / truncation strategy before,
|
||||
then it will be reset to no padding/truncation when exiting the managed section.
|
||||
|
||||
:param tokenizer:
|
||||
:param max_length:
|
||||
:param stride:
|
||||
:param strategy:
|
||||
:param pad_to_max_length:
|
||||
:param padding_side:
|
||||
:param pad_token_id:
|
||||
:param pad_token_type_id:
|
||||
:param pad_token:
|
||||
:return:
|
||||
"""
|
||||
|
||||
# Handle all the truncation and padding stuff
|
||||
if max_length is not None:
|
||||
tokenizer.enable_truncation(max_length, stride=stride, strategy=strategy)
|
||||
|
||||
if pad_to_max_length and (pad_token and pad_token_id >= 0):
|
||||
tokenizer.enable_padding(
|
||||
max_length=max_length,
|
||||
direction=padding_side,
|
||||
pad_id=pad_token_id,
|
||||
pad_type_id=pad_token_type_id,
|
||||
pad_token=pad_token,
|
||||
)
|
||||
elif pad_to_max_length:
|
||||
logger.warning(
|
||||
"Disabled padding because no padding token set (pad_token: {}, pad_token_id: {}).\n"
|
||||
"To remove this error, you can add a new pad token and then resize model embedding:\n"
|
||||
"\ttokenizer.pad_token = '<PAD>'\n\tmodel.resize_token_embeddings(len(tokenizer))".format(
|
||||
pad_token, pad_token_id
|
||||
)
|
||||
)
|
||||
|
||||
yield
|
||||
|
||||
if max_length is not None:
|
||||
tokenizer.no_truncation()
|
||||
|
||||
if pad_to_max_length and (pad_token and pad_token_id >= 0):
|
||||
tokenizer.no_padding()
|
||||
|
||||
|
||||
class PreTrainedTokenizer(object):
|
||||
""" Base class for all tokenizers.
|
||||
Handle all the shared methods for tokenization and special tokens as well as methods downloading/caching/loading pretrained tokenizers as well as adding tokens to the vocabulary.
|
||||
@@ -152,18 +87,6 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
padding_side = "right"
|
||||
|
||||
NO_PAD_TOKEN_FOR_BATCH_MSG = (
|
||||
"No padding token is set for this model, therefore no batch can be made with uneven "
|
||||
"sequences. Set a padding token or adjust the lengths of the sequences building the "
|
||||
"batch so that every sequence is of the same length."
|
||||
)
|
||||
|
||||
UNEVEN_SEQUENCES_FOR_BATCH_MSG = (
|
||||
"The sequences building the batch are not of the same size, no tensor "
|
||||
"can be built. Set `pad_to_max_length=True` to pad the smaller sequences"
|
||||
"up to the larger sequence's length."
|
||||
)
|
||||
|
||||
@property
|
||||
def bos_token(self):
|
||||
""" Beginning of sentence token (string). Log an error if used while not having been set. """
|
||||
@@ -297,10 +220,6 @@ class PreTrainedTokenizer(object):
|
||||
""" Ids of all the additional special tokens in the vocabulary (list of integers). Log an error if used while not having been set. """
|
||||
return self.convert_tokens_to_ids(self.additional_special_tokens)
|
||||
|
||||
def get_vocab(self):
|
||||
""" Returns the vocabulary as a dict of {token: index} pairs. `tokenizer.get_vocab()[token]` is equivalent to `tokenizer.convert_tokens_to_ids(token)` when `token` is in the vocab. """
|
||||
raise NotImplementedError()
|
||||
|
||||
def __init__(self, max_len=None, **kwargs):
|
||||
self._bos_token = None
|
||||
self._eos_token = None
|
||||
@@ -395,7 +314,6 @@ class PreTrainedTokenizer(object):
|
||||
force_download = kwargs.pop("force_download", False)
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
s3_models = list(cls.max_model_input_sizes.keys())
|
||||
vocab_files = {}
|
||||
@@ -463,7 +381,6 @@ class PreTrainedTokenizer(object):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
except EnvironmentError:
|
||||
if pretrained_model_name_or_path in s3_models:
|
||||
@@ -625,7 +542,7 @@ class PreTrainedTokenizer(object):
|
||||
vocabulary, they are added to it with indices starting from length of the current vocabulary.
|
||||
|
||||
Args:
|
||||
new_tokens: string or list of string. Each string is a token to add. Tokens are only added if they are not already in the vocabulary (tested by checking if the tokenizer assign the index of the ``unk_token`` to them).
|
||||
new_tokens: list of string. Each string is a token to add. Tokens are only added if they are not already in the vocabulary (tested by checking if the tokenizer assign the index of the ``unk_token`` to them).
|
||||
|
||||
Returns:
|
||||
Number of tokens added to the vocabulary.
|
||||
@@ -643,9 +560,6 @@ class PreTrainedTokenizer(object):
|
||||
if not new_tokens:
|
||||
return 0
|
||||
|
||||
if not isinstance(new_tokens, list):
|
||||
new_tokens = [new_tokens]
|
||||
|
||||
to_add_tokens = []
|
||||
for token in new_tokens:
|
||||
assert isinstance(token, str)
|
||||
@@ -748,12 +662,9 @@ class PreTrainedTokenizer(object):
|
||||
Take care of added tokens.
|
||||
|
||||
text: The sequence to be encoded.
|
||||
add_prefix_space: Only applies to GPT-2 and RoBERTa tokenizers. When `True`, this ensures that the sequence
|
||||
begins with an empty space. False by default except for when using RoBERTa with `add_special_tokens=True`.
|
||||
**kwargs: passed to the `prepare_for_tokenization` preprocessing method.
|
||||
**kwargs: passed to the child `self.tokenize()` method
|
||||
"""
|
||||
all_special_tokens = self.all_special_tokens
|
||||
text = self.prepare_for_tokenization(text, **kwargs)
|
||||
|
||||
def lowercase_text(t):
|
||||
# convert non-special tokens to lowercase
|
||||
@@ -768,7 +679,7 @@ class PreTrainedTokenizer(object):
|
||||
result = []
|
||||
split_text = text.split(tok)
|
||||
for i, sub_text in enumerate(split_text):
|
||||
sub_text = sub_text.rstrip()
|
||||
sub_text = sub_text.strip()
|
||||
if i == 0 and not sub_text:
|
||||
result += [tok]
|
||||
elif i == len(split_text) - 1:
|
||||
@@ -786,7 +697,7 @@ class PreTrainedTokenizer(object):
|
||||
if not text.strip():
|
||||
return []
|
||||
if not tok_list:
|
||||
return self._tokenize(text)
|
||||
return self._tokenize(text, **kwargs)
|
||||
|
||||
tokenized_text = []
|
||||
text_list = [text]
|
||||
@@ -802,7 +713,7 @@ class PreTrainedTokenizer(object):
|
||||
return list(
|
||||
itertools.chain.from_iterable(
|
||||
(
|
||||
self._tokenize(token) if token not in self.unique_added_tokens_encoder else [token]
|
||||
self._tokenize(token, **kwargs) if token not in self.unique_added_tokens_encoder else [token]
|
||||
for token in tokenized_text
|
||||
)
|
||||
)
|
||||
@@ -891,8 +802,6 @@ class PreTrainedTokenizer(object):
|
||||
Defaults to False: no padding.
|
||||
return_tensors: (optional) can be set to 'tf' or 'pt' to return respectively TensorFlow tf.constant
|
||||
or PyTorch torch.Tensor instead of a list of python integers.
|
||||
add_prefix_space: Only applies to GPT-2 and RoBERTa tokenizers. When `True`, this ensures that the sequence
|
||||
begins with an empty space. False by default except for when using RoBERTa with `add_special_tokens=True`.
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
"""
|
||||
encoded_inputs = self.encode_plus(
|
||||
@@ -923,7 +832,6 @@ class PreTrainedTokenizer(object):
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
"""
|
||||
@@ -957,15 +865,10 @@ class PreTrainedTokenizer(object):
|
||||
Defaults to False: no padding.
|
||||
return_tensors: (optional) can be set to 'tf' or 'pt' to return respectively TensorFlow tf.constant
|
||||
or PyTorch torch.Tensor instead of a list of python integers.
|
||||
add_prefix_space: Only applies to GPT-2 and RoBERTa tokenizers. When `True`, this ensures that the sequence
|
||||
begins with an empty space. False by default except for when using RoBERTa with `add_special_tokens=True`.
|
||||
return_token_type_ids: (optional) Set to False to avoid returning token_type_ids (default True).
|
||||
return_attention_mask: (optional) Set to False to avoid returning attention mask (default True)
|
||||
return_overflowing_tokens: (optional) Set to True to return overflowing token information (default False).
|
||||
return_special_tokens_mask: (optional) Set to True to return special tokens mask information (default False).
|
||||
return_offsets_mapping: (optional) Set to True to return (char_start, char_end) for each token (default False).
|
||||
If using Python's tokenizer, this method will raise NotImplementedError. This one is only available on
|
||||
Rust-based tokenizers inheriting from PreTrainedTokenizerFast.
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
|
||||
Return:
|
||||
@@ -992,8 +895,7 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
def get_input_ids(text):
|
||||
if isinstance(text, str):
|
||||
tokens = self.tokenize(text, add_special_tokens=add_special_tokens, **kwargs)
|
||||
return self.convert_tokens_to_ids(tokens)
|
||||
return self.convert_tokens_to_ids(self.tokenize(text, **kwargs))
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], str):
|
||||
return self.convert_tokens_to_ids(text)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], int):
|
||||
@@ -1003,15 +905,6 @@ class PreTrainedTokenizer(object):
|
||||
"Input is not valid. Should be a string, a list/tuple of strings or a list/tuple of integers."
|
||||
)
|
||||
|
||||
if return_offsets_mapping:
|
||||
raise NotImplementedError(
|
||||
"return_offset_mapping is not available when using Python tokenizers."
|
||||
"To use this feature, change your tokenizer to one deriving from "
|
||||
"transformers.PreTrainedTokenizerFast."
|
||||
"More information on available tokenizers at "
|
||||
"https://github.com/huggingface/transformers/pull/2674"
|
||||
)
|
||||
|
||||
first_ids = get_input_ids(text)
|
||||
second_ids = get_input_ids(text_pair) if text_pair is not None else None
|
||||
|
||||
@@ -1033,18 +926,13 @@ class PreTrainedTokenizer(object):
|
||||
def batch_encode_plus(
|
||||
self,
|
||||
batch_text_or_text_pairs=None,
|
||||
add_special_tokens=True,
|
||||
add_special_tokens=False,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
pad_to_max_length=False,
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_masks=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_masks=False,
|
||||
return_offsets_mapping=False,
|
||||
return_input_lengths=False,
|
||||
return_attention_masks=False,
|
||||
**kwargs
|
||||
):
|
||||
"""
|
||||
@@ -1067,104 +955,25 @@ class PreTrainedTokenizer(object):
|
||||
- 'only_first': Only truncate the first sequence
|
||||
- 'only_second': Only truncate the second sequence
|
||||
- 'do_not_truncate': Does not truncate (raise an error if the input sequence is longer than max_length)
|
||||
pad_to_max_length: if set to True, the returned sequences will be padded according to the model's padding side and
|
||||
padding index, up to their max length. If no max length is specified, the padding is done up to the model's max length.
|
||||
The tokenizer padding sides are handled by the class attribute `padding_side` which can be set to the following strings:
|
||||
- 'left': pads on the left of the sequences
|
||||
- 'right': pads on the right of the sequences
|
||||
Defaults to False: no padding.
|
||||
return_tensors: (optional) can be set to 'tf' or 'pt' to return respectively TensorFlow tf.constant
|
||||
or PyTorch torch.Tensor instead of a list of python integers.
|
||||
return_input_lengths: (optional) If set the resulting dictionary will include the length of each sample
|
||||
return_attention_masks: (optional) Set to True to return the attention mask (default False)
|
||||
return_offsets_mapping: (optional) Not available, should be set to False or it will throw NotImplementError
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
|
||||
Return:
|
||||
A Dictionary of shape::
|
||||
|
||||
{
|
||||
input_ids: list[List[int]],
|
||||
token_type_ids: list[List[int]] if return_token_type_ids is True (default)
|
||||
attention_mask: list[List[int]] if return_attention_mask is True (default)
|
||||
overflowing_tokens: list[List[int]] if a ``max_length`` is specified and return_overflowing_tokens is True
|
||||
num_truncated_tokens: List[int] if a ``max_length`` is specified and return_overflowing_tokens is True
|
||||
special_tokens_mask: list[List[int]] if ``add_special_tokens`` if set to ``True`` and return_special_tokens_mask is True
|
||||
}
|
||||
|
||||
With the fields:
|
||||
``input_ids``: list of token ids to be fed to a model
|
||||
``token_type_ids``: list of token type ids to be fed to a model
|
||||
``attention_mask``: list of indices specifying which tokens should be attended to by the model
|
||||
``overflowing_tokens``: list of overflowing tokens if a max length is specified.
|
||||
``num_truncated_tokens``: number of overflowing tokens a ``max_length`` is specified
|
||||
``special_tokens_mask``: if adding special tokens, this is a list of [0, 1], with 0 specifying special added
|
||||
tokens and 1 specifying sequence tokens.
|
||||
"""
|
||||
|
||||
def get_input_ids(text):
|
||||
if isinstance(text, str):
|
||||
tokens = self.tokenize(text, add_special_tokens=add_special_tokens, **kwargs)
|
||||
return self.convert_tokens_to_ids(tokens)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], str):
|
||||
return self.convert_tokens_to_ids(text)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], int):
|
||||
return text
|
||||
else:
|
||||
raise ValueError(
|
||||
"Input is not valid. Should be a string, a list/tuple of strings or a list/tuple of integers."
|
||||
)
|
||||
|
||||
if return_offsets_mapping:
|
||||
raise NotImplementedError(
|
||||
"return_offset_mapping is not available when using Python tokenizers."
|
||||
"To use this feature, change your tokenizer to one deriving from "
|
||||
"transformers.PreTrainedTokenizerFast."
|
||||
"More information on available tokenizers at "
|
||||
"https://github.com/huggingface/transformers/pull/2674"
|
||||
)
|
||||
|
||||
input_ids = []
|
||||
batch_outputs = {}
|
||||
for ids_or_pair_ids in batch_text_or_text_pairs:
|
||||
if isinstance(ids_or_pair_ids, (list, tuple)):
|
||||
assert len(ids_or_pair_ids) == 2
|
||||
ids, pair_ids = ids_or_pair_ids
|
||||
else:
|
||||
ids, pair_ids = ids_or_pair_ids, None
|
||||
|
||||
first_ids = get_input_ids(ids)
|
||||
second_ids = get_input_ids(pair_ids) if pair_ids is not None else None
|
||||
input_ids.append((first_ids, second_ids))
|
||||
|
||||
if max_length is None and pad_to_max_length:
|
||||
|
||||
def total_sequence_length(input_pairs):
|
||||
first_ids, second_ids = input_pairs
|
||||
return len(first_ids) + (
|
||||
self.num_added_tokens()
|
||||
if second_ids is None
|
||||
else (len(second_ids) + self.num_added_tokens(pair=True))
|
||||
)
|
||||
|
||||
max_length = max([total_sequence_length(ids) for ids in input_ids])
|
||||
|
||||
batch_outputs = {}
|
||||
for first_ids, second_ids in input_ids:
|
||||
# Prepares a sequence of input id, or a pair of sequences of inputs ids so that it can be used by
|
||||
# the model. It adds special tokens, truncates sequences if overflowing while taking into account
|
||||
# the special tokens and manages a window stride for overflowing tokens
|
||||
outputs = self.prepare_for_model(
|
||||
first_ids,
|
||||
pair_ids=second_ids,
|
||||
max_length=max_length,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
outputs = self.encode_plus(
|
||||
ids,
|
||||
pair_ids,
|
||||
add_special_tokens=add_special_tokens,
|
||||
max_length=max_length,
|
||||
stride=stride,
|
||||
truncation_strategy=truncation_strategy,
|
||||
return_attention_mask=return_attention_masks,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_masks,
|
||||
return_tensors=None,
|
||||
)
|
||||
|
||||
# Append the non-padded length to the output
|
||||
@@ -1176,28 +985,31 @@ class PreTrainedTokenizer(object):
|
||||
batch_outputs[key] = []
|
||||
batch_outputs[key].append(value)
|
||||
|
||||
# Compute longest sequence size
|
||||
max_seq_len = max(map(len, batch_outputs["input_ids"]))
|
||||
|
||||
if return_attention_masks:
|
||||
# Allow the model to not give any special attention to padded input
|
||||
batch_outputs["attention_mask"] = [[0] * len(v) for v in batch_outputs["input_ids"]]
|
||||
|
||||
if return_tensors is not None:
|
||||
|
||||
# Do the tensor conversion in batch
|
||||
for key, value in batch_outputs.items():
|
||||
|
||||
padded_value = value
|
||||
# verify that the tokenizer has a pad_token_id
|
||||
if key != "input_len" and self._pad_token is not None:
|
||||
# Padding handle
|
||||
padded_value = [
|
||||
v + [self.pad_token_id if key == "input_ids" else 1] * (max_seq_len - len(v))
|
||||
for v in padded_value
|
||||
]
|
||||
|
||||
if return_tensors == "tf" and is_tf_available():
|
||||
try:
|
||||
batch_outputs[key] = tf.constant(value)
|
||||
except ValueError:
|
||||
if None in [item for sequence in value for item in sequence]:
|
||||
raise ValueError(self.NO_PAD_TOKEN_FOR_BATCH_MSG)
|
||||
else:
|
||||
raise ValueError(self.UNEVEN_SEQUENCES_FOR_BATCH_MSG)
|
||||
batch_outputs[key] = tf.constant(padded_value)
|
||||
elif return_tensors == "pt" and is_torch_available():
|
||||
try:
|
||||
batch_outputs[key] = torch.tensor(value)
|
||||
except ValueError:
|
||||
raise ValueError(self.UNEVEN_SEQUENCES_FOR_BATCH_MSG)
|
||||
except RuntimeError:
|
||||
if None in [item for sequence in value for item in sequence]:
|
||||
raise ValueError(self.NO_PAD_TOKEN_FOR_BATCH_MSG)
|
||||
else:
|
||||
raise
|
||||
batch_outputs[key] = torch.tensor(padded_value)
|
||||
elif return_tensors is not None:
|
||||
logger.warning(
|
||||
"Unable to convert output to tensors format {}, PyTorch or TensorFlow is not available.".format(
|
||||
@@ -1205,6 +1017,13 @@ class PreTrainedTokenizer(object):
|
||||
)
|
||||
)
|
||||
|
||||
# encoder_attention_mask requires 1 for real token, 0 for padding, just invert value
|
||||
if return_attention_masks:
|
||||
if is_tf_available():
|
||||
batch_outputs["attention_mask"] = tf.abs(batch_outputs["attention_mask"] - 1)
|
||||
else:
|
||||
batch_outputs["attention_mask"] = torch.abs(batch_outputs["attention_mask"] - 1)
|
||||
|
||||
return batch_outputs
|
||||
|
||||
def prepare_for_model(
|
||||
@@ -1306,10 +1125,7 @@ class PreTrainedTokenizer(object):
|
||||
token_type_ids = [0] * len(ids) + ([1] * len(pair_ids) if pair else [])
|
||||
|
||||
if return_special_tokens_mask:
|
||||
if add_special_tokens:
|
||||
encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(ids, pair_ids)
|
||||
else:
|
||||
encoded_inputs["special_tokens_mask"] = [0] * len(sequence)
|
||||
encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(ids, pair_ids)
|
||||
|
||||
encoded_inputs["input_ids"] = sequence
|
||||
if return_token_type_ids:
|
||||
@@ -1399,10 +1215,6 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
return encoded_inputs
|
||||
|
||||
def prepare_for_tokenization(self, text, **kwargs):
|
||||
""" Performs any necessary transformations before tokenization """
|
||||
return text
|
||||
|
||||
def truncate_sequences(
|
||||
self, ids, pair_ids=None, num_tokens_to_remove=0, truncation_strategy="longest_first", stride=0
|
||||
):
|
||||
@@ -1606,29 +1418,30 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
|
||||
class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
def __init__(self, tokenizer: BaseTokenizer, **kwargs):
|
||||
if tokenizer is None:
|
||||
raise ValueError("Provided tokenizer cannot be None")
|
||||
self._tokenizer = tokenizer
|
||||
_tokenizer = None
|
||||
_decoder = None
|
||||
|
||||
def __init__(self, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.max_len_single_sentence = self.max_len - self.num_added_tokens(False) # take into account special tokens
|
||||
self.max_len_sentences_pair = self.max_len - self.num_added_tokens(True) # take into account special tokens
|
||||
|
||||
@property
|
||||
def tokenizer(self):
|
||||
if self._tokenizer is None:
|
||||
raise NotImplementedError
|
||||
return self._tokenizer
|
||||
|
||||
@property
|
||||
def decoder(self):
|
||||
return self._tokenizer._tokenizer.decoder
|
||||
if self._decoder is None:
|
||||
raise NotImplementedError
|
||||
return self._decoder
|
||||
|
||||
@property
|
||||
def vocab_size(self):
|
||||
return self._tokenizer.get_vocab_size(with_added_tokens=False)
|
||||
return self.tokenizer.get_vocab_size(with_added_tokens=False)
|
||||
|
||||
def __len__(self):
|
||||
return self._tokenizer.get_vocab_size(with_added_tokens=True)
|
||||
return self.tokenizer.get_vocab_size(with_added_tokens=True)
|
||||
|
||||
@PreTrainedTokenizer.bos_token.setter
|
||||
def bos_token(self, value):
|
||||
@@ -1682,42 +1495,36 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
):
|
||||
if return_overflowing_tokens and encoding.overflowing is not None:
|
||||
encodings = [encoding] + encoding.overflowing
|
||||
else:
|
||||
encodings = [encoding]
|
||||
|
||||
encoding_dict = defaultdict(list)
|
||||
for e in encodings:
|
||||
encoding_dict["input_ids"].append(e.ids)
|
||||
|
||||
if return_token_type_ids:
|
||||
encoding_dict["token_type_ids"].append(e.type_ids)
|
||||
if return_attention_mask:
|
||||
encoding_dict["attention_mask"].append(e.attention_mask)
|
||||
if return_special_tokens_mask:
|
||||
encoding_dict["special_tokens_mask"].append(e.special_tokens_mask)
|
||||
if return_offsets_mapping:
|
||||
encoding_dict["offset_mapping"].append([e.original_str.offsets(o) for o in e.offsets])
|
||||
encoding_dict = {
|
||||
"input_ids": encoding.ids,
|
||||
}
|
||||
if return_token_type_ids:
|
||||
encoding_dict["token_type_ids"] = encoding.type_ids
|
||||
if return_attention_mask:
|
||||
encoding_dict["attention_mask"] = encoding.attention_mask
|
||||
if return_overflowing_tokens:
|
||||
overflowing = encoding.overflowing
|
||||
encoding_dict["overflowing_tokens"] = overflowing.ids if overflowing is not None else []
|
||||
if return_special_tokens_mask:
|
||||
encoding_dict["special_tokens_mask"] = encoding.special_tokens_mask
|
||||
|
||||
# Prepare inputs as tensors if asked
|
||||
if return_tensors == "tf" and is_tf_available():
|
||||
encoding_dict["input_ids"] = tf.constant(encoding_dict["input_ids"])
|
||||
encoding_dict["input_ids"] = tf.constant([encoding_dict["input_ids"]])
|
||||
if "token_type_ids" in encoding_dict:
|
||||
encoding_dict["token_type_ids"] = tf.constant(encoding_dict["token_type_ids"])
|
||||
encoding_dict["token_type_ids"] = tf.constant([encoding_dict["token_type_ids"]])
|
||||
|
||||
if "attention_mask" in encoding_dict:
|
||||
encoding_dict["attention_mask"] = tf.constant(encoding_dict["attention_mask"])
|
||||
encoding_dict["attention_mask"] = tf.constant([encoding_dict["attention_mask"]])
|
||||
|
||||
elif return_tensors == "pt" and is_torch_available():
|
||||
encoding_dict["input_ids"] = torch.tensor(encoding_dict["input_ids"])
|
||||
encoding_dict["input_ids"] = torch.tensor([encoding_dict["input_ids"]])
|
||||
if "token_type_ids" in encoding_dict:
|
||||
encoding_dict["token_type_ids"] = torch.tensor(encoding_dict["token_type_ids"])
|
||||
encoding_dict["token_type_ids"] = torch.tensor([encoding_dict["token_type_ids"]])
|
||||
|
||||
if "attention_mask" in encoding_dict:
|
||||
encoding_dict["attention_mask"] = torch.tensor(encoding_dict["attention_mask"])
|
||||
encoding_dict["attention_mask"] = torch.tensor([encoding_dict["attention_mask"]])
|
||||
elif return_tensors is not None:
|
||||
logger.warning(
|
||||
"Unable to convert output to tensors format {}, PyTorch or TensorFlow is not available.".format(
|
||||
@@ -1727,174 +1534,71 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
|
||||
return encoding_dict
|
||||
|
||||
def encode_plus(
|
||||
self,
|
||||
text,
|
||||
text_pair=None,
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
**kwargs
|
||||
):
|
||||
encoding = self.tokenizer.encode(text, text_pair)
|
||||
return self._convert_encoding(
|
||||
encoding,
|
||||
return_tensors=return_tensors,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_attention_mask=return_attention_mask,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_mask,
|
||||
)
|
||||
|
||||
def tokenize(self, text):
|
||||
return self.tokenizer.encode(text).tokens
|
||||
|
||||
def _convert_token_to_id_with_added_voc(self, token):
|
||||
id = self._tokenizer.token_to_id(token)
|
||||
id = self.tokenizer.token_to_id(token)
|
||||
if id is None:
|
||||
return self.unk_token_id
|
||||
return id
|
||||
|
||||
def _convert_id_to_token(self, index):
|
||||
return self._tokenizer.id_to_token(int(index))
|
||||
return self.tokenizer.id_to_token(int(index))
|
||||
|
||||
def convert_tokens_to_string(self, tokens):
|
||||
return self._tokenizer.decode(tokens)
|
||||
return self.decoder.decode(tokens)
|
||||
|
||||
def add_tokens(self, new_tokens):
|
||||
if isinstance(new_tokens, str):
|
||||
new_tokens = [new_tokens]
|
||||
return self._tokenizer.add_tokens(new_tokens)
|
||||
self.tokenizer.add_tokens(new_tokens)
|
||||
|
||||
def add_special_tokens(self, special_tokens_dict):
|
||||
added = super().add_special_tokens(special_tokens_dict)
|
||||
self._update_special_tokens()
|
||||
return added
|
||||
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
if token_ids_1 is None:
|
||||
return token_ids_0
|
||||
else:
|
||||
return token_ids_0 + token_ids_1
|
||||
|
||||
def num_added_tokens(self, pair=False):
|
||||
return self.tokenizer.num_special_tokens_to_add(pair)
|
||||
|
||||
def tokenize(self, text, **kwargs):
|
||||
return self.tokenizer.encode(text).tokens
|
||||
|
||||
def batch_encode_plus(
|
||||
def encode_batch(
|
||||
self,
|
||||
batch_text_or_text_pairs=None,
|
||||
add_special_tokens=True,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
pad_to_max_length=False,
|
||||
texts,
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
if not add_special_tokens:
|
||||
logger.warning(
|
||||
"Fast tokenizers add special tokens by default. To remove special tokens, please specify"
|
||||
"`add_special_tokens=False` during the initialisation rather than when calling `encode`,"
|
||||
"`encode_plus` or `batch_encode_plus`."
|
||||
)
|
||||
|
||||
# Needed if we have to return a tensor
|
||||
pad_to_max_length = pad_to_max_length or (return_tensors is not None)
|
||||
|
||||
# Throw an error if we can pad because there is no padding token
|
||||
if pad_to_max_length and self.pad_token_id is None:
|
||||
raise ValueError("Unable to set proper padding strategy as the tokenizer does have padding token")
|
||||
|
||||
# Set the truncation and padding strategy and restore the initial configuration
|
||||
with truncate_and_pad(
|
||||
tokenizer=self._tokenizer,
|
||||
max_length=max_length,
|
||||
stride=stride,
|
||||
strategy=truncation_strategy,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
padding_side=self.padding_side,
|
||||
pad_token_id=self.pad_token_id,
|
||||
pad_token_type_id=self.pad_token_type_id,
|
||||
pad_token=self._pad_token,
|
||||
):
|
||||
|
||||
if not isinstance(batch_text_or_text_pairs, list):
|
||||
raise TypeError(
|
||||
"batch_text_or_text_pairs has to be a list (got {})".format(type(batch_text_or_text_pairs))
|
||||
)
|
||||
|
||||
# Avoid thread overhead if only one example.
|
||||
if len(batch_text_or_text_pairs) == 1:
|
||||
if isinstance(batch_text_or_text_pairs[0], (tuple, list)):
|
||||
tokens = self._tokenizer.encode(*batch_text_or_text_pairs[0])
|
||||
else:
|
||||
tokens = self._tokenizer.encode(batch_text_or_text_pairs[0])
|
||||
tokens = [tokens]
|
||||
else:
|
||||
tokens = self._tokenizer.encode_batch(batch_text_or_text_pairs)
|
||||
|
||||
# Convert encoding to dict
|
||||
tokens = [
|
||||
return [
|
||||
self._convert_encoding(
|
||||
encoding=encoding,
|
||||
encoding,
|
||||
return_tensors=return_tensors,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_attention_mask=return_attention_mask,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_mask,
|
||||
return_offsets_mapping=return_offsets_mapping,
|
||||
)
|
||||
for encoding in tokens
|
||||
for encoding in self.tokenizer.encode_batch(texts)
|
||||
]
|
||||
|
||||
# Sanitize the output to have dict[list] from list[dict]
|
||||
sanitized = {}
|
||||
for key in tokens[0].keys():
|
||||
stack = [e for item in tokens for e in item[key]]
|
||||
if return_tensors == "tf":
|
||||
stack = tf.stack(stack, axis=0)
|
||||
elif return_tensors == "pt":
|
||||
stack = torch.stack(stack, dim=0)
|
||||
elif not return_tensors and len(stack) == 1:
|
||||
stack = stack[0]
|
||||
|
||||
sanitized[key] = stack
|
||||
|
||||
# If returning overflowing tokens, we need to return a mapping
|
||||
# from the batch idx to the original sample
|
||||
if return_overflowing_tokens:
|
||||
overflow_to_sample_mapping = [
|
||||
i if len(item["input_ids"]) == 1 else [i] * len(item["input_ids"]) for i, item in enumerate(tokens)
|
||||
]
|
||||
sanitized["overflow_to_sample_mapping"] = overflow_to_sample_mapping
|
||||
return sanitized
|
||||
|
||||
def encode_plus(
|
||||
self,
|
||||
text,
|
||||
text_pair=None,
|
||||
add_special_tokens=False,
|
||||
max_length=None,
|
||||
pad_to_max_length=False,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
batched_input = [(text, text_pair)] if text_pair else [text]
|
||||
batched_output = self.batch_encode_plus(
|
||||
batched_input,
|
||||
add_special_tokens=add_special_tokens,
|
||||
max_length=max_length,
|
||||
stride=stride,
|
||||
truncation_strategy=truncation_strategy,
|
||||
return_tensors=return_tensors,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_attention_mask=return_attention_mask,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_mask,
|
||||
return_offsets_mapping=return_offsets_mapping,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
# Return tensor is None, then we can remove the leading batch axis
|
||||
if not return_tensors:
|
||||
return {key: value[0] if isinstance(value[0], list) else value for key, value in batched_output.items()}
|
||||
else:
|
||||
return batched_output
|
||||
|
||||
def decode(self, token_ids, skip_special_tokens=False, clean_up_tokenization_spaces=True):
|
||||
text = self.tokenizer.decode(token_ids, skip_special_tokens)
|
||||
|
||||
@@ -1904,11 +1608,8 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
else:
|
||||
return text
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
if os.path.isdir(save_directory):
|
||||
files = self._tokenizer.save(save_directory)
|
||||
else:
|
||||
folder, file = os.path.split(os.path.abspath(save_directory))
|
||||
files = self._tokenizer.save(folder, name=file)
|
||||
|
||||
return tuple(files)
|
||||
def decode_batch(self, ids_batch, skip_special_tokens=False, clear_up_tokenization_spaces=True):
|
||||
return [
|
||||
self.clean_up_tokenization(text) if clear_up_tokenization_spaces else text
|
||||
for text in self.tokenizer.decode_batch(ids_batch, skip_special_tokens)
|
||||
]
|
||||
@@ -21,7 +21,6 @@ import os
|
||||
import re
|
||||
import sys
|
||||
import unicodedata
|
||||
from typing import List, Optional
|
||||
|
||||
import sacremoses as sm
|
||||
|
||||
@@ -531,59 +530,20 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
BPE tokenizer for XLM
|
||||
|
||||
- Moses preprocessing & tokenization for most supported languages
|
||||
- Language specific tokenization for Chinese (Jieba), Japanese (KyTea) and Thai (PyThaiNLP)
|
||||
- (optionally) lower case & normalize all inputs text
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
- `lang2id` attribute maps the languages supported by the model with their ids if provided (automatically set for pretrained vocabularies)
|
||||
- `id2lang` attributes does reverse mapping if provided (automatically set for pretrained vocabularies)
|
||||
- Moses preprocessing & tokenization for most supported languages
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
- Language specific tokenization for Chinese (Jieba), Japanese (KyTea) and Thai (PyThaiNLP)
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
Vocabulary file.
|
||||
merges_file (:obj:`string`):
|
||||
Merges file.
|
||||
do_lower_case (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase the input when tokenizing.
|
||||
remove_space (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to strip the text when tokenizing (removing excess spaces before and after the string).
|
||||
keep_accents (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Whether to keep accents when tokenizing.
|
||||
unk_token (:obj:`string`, `optional`, defaults to "<unk>"):
|
||||
The unknown token. A token that is not in the vocabulary cannot be converted to an ID and is set to be this
|
||||
token instead.
|
||||
bos_token (:obj:`string`, `optional`, defaults to "<s>"):
|
||||
The beginning of sequence token that was used during pre-training. Can be used a sequence classifier token.
|
||||
- (optionally) lower case & normalize all inputs text
|
||||
|
||||
.. note::
|
||||
- argument ``special_tokens`` and function ``set_special_tokens``, can be used to add additional symbols \
|
||||
(ex: "__classify__") to a vocabulary
|
||||
|
||||
When building a sequence using special tokens, this is not the token that is used for the beginning
|
||||
of sequence. The token used is the :obj:`cls_token`.
|
||||
sep_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The separator token, which is used when building a sequence from multiple sequences, e.g. two sequences
|
||||
for sequence classification or for a text and a question for question answering.
|
||||
It is also used as the last token of a sequence built with special tokens.
|
||||
pad_token (:obj:`string`, `optional`, defaults to "<pad>"):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
cls_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The classifier token which is used when doing sequence classification (classification of the whole
|
||||
sequence instead of per-token classification). It is the first token of the sequence when built with
|
||||
special tokens.
|
||||
mask_token (:obj:`string`, `optional`, defaults to "<special1>"):
|
||||
The token used for masking values. This is the token used when training this model with masked language
|
||||
modeling. This is the token which the model will try to predict.
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`["<special0>","<special1>","<special2>","<special3>","<special4>","<special5>","<special6>","<special7>","<special8>","<special9>"]`):
|
||||
List of additional special tokens.
|
||||
lang2id (:obj:`Dict[str, int]`, `optional`, defaults to :obj:`None`):
|
||||
Dictionary mapping languages string identifiers to their IDs.
|
||||
id2lang (:obj:`Dict[int, str`, `optional`, defaults to :obj:`None`):
|
||||
Dictionary mapping language IDs to their string identifiers.
|
||||
do_lowercase_and_remove_accent (:obj:`bool`, `optional`, defaults to :obj:`True`):
|
||||
Whether to lowercase and remove accents when tokenizing.
|
||||
- `lang2id` attribute maps the languages supported by the model with their ids if provided (automatically set for pretrained vocabularies)
|
||||
|
||||
- `id2lang` attributes does reverse mapping if provided (automatically set for pretrained vocabularies)
|
||||
|
||||
- `do_lowercase_and_remove_accent` controle lower casing and accent (automatically set for pretrained vocabularies)
|
||||
"""
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
@@ -702,9 +662,6 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
word = tuple(token[:-1]) + (token[-1] + "</w>",)
|
||||
if token in self.cache:
|
||||
@@ -852,26 +809,13 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
out_string = "".join(tokens).replace("</w>", " ").strip()
|
||||
return out_string
|
||||
|
||||
def build_inputs_with_special_tokens(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def build_inputs_with_special_tokens(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Build model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens.
|
||||
A XLM sequence has the following format:
|
||||
|
||||
- single sequence: ``<s> X </s>``
|
||||
- pair of sequences: ``<s> A </s> B </s>``
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of IDs to which the special tokens will be added
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: list of `input IDs <../glossary.html#input-ids>`__ with the appropriate special tokens.
|
||||
|
||||
single sequence: <s> X </s>
|
||||
pair of sequences: <s> A </s> B </s>
|
||||
"""
|
||||
if token_ids_1 is None:
|
||||
return [self.cls_token_id] + token_ids_0 + [self.sep_token_id]
|
||||
@@ -879,23 +823,20 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
cls = [self.cls_token_id]
|
||||
return cls + token_ids_0 + sep + token_ids_1 + sep
|
||||
|
||||
def get_special_tokens_mask(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None, already_has_special_tokens: bool = False
|
||||
) -> List[int]:
|
||||
def get_special_tokens_mask(self, token_ids_0, token_ids_1=None, already_has_special_tokens=False):
|
||||
"""
|
||||
Retrieves sequence ids from a token list that has no special tokens added. This method is called when adding
|
||||
special tokens using the tokenizer ``prepare_for_model`` or ``encode_plus`` methods.
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
already_has_special_tokens (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Set to True if the token list is already formatted with special tokens for the model
|
||||
token_ids_0: list of ids (must not contain special tokens)
|
||||
token_ids_1: Optional list of ids (must not contain special tokens), necessary when fetching sequence ids
|
||||
for sequence pairs
|
||||
already_has_special_tokens: (default False) Set to True if the token list is already formated with
|
||||
special tokens for the model
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: A list of integers in the range [0, 1]: 0 for a special token, 1 for a sequence token.
|
||||
A list of integers in the range [0, 1]: 1 for a special token, 0 for a sequence token.
|
||||
"""
|
||||
|
||||
if already_has_special_tokens:
|
||||
@@ -910,29 +851,14 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
return [1] + ([0] * len(token_ids_0)) + [1] + ([0] * len(token_ids_1)) + [1]
|
||||
return [1] + ([0] * len(token_ids_0)) + [1]
|
||||
|
||||
def create_token_type_ids_from_sequences(
|
||||
self, token_ids_0: List[int], token_ids_1: Optional[List[int]] = None
|
||||
) -> List[int]:
|
||||
def create_token_type_ids_from_sequences(self, token_ids_0, token_ids_1=None):
|
||||
"""
|
||||
Creates a mask from the two sequences passed to be used in a sequence-pair classification task.
|
||||
An XLM sequence pair mask has the following format:
|
||||
0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence
|
||||
|
||||
::
|
||||
|
||||
0 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 1 1 1
|
||||
| first sequence | second sequence |
|
||||
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0s).
|
||||
|
||||
Args:
|
||||
token_ids_0 (:obj:`List[int]`):
|
||||
List of ids.
|
||||
token_ids_1 (:obj:`List[int]`, `optional`, defaults to :obj:`None`):
|
||||
Optional second list of IDs for sequence pairs.
|
||||
|
||||
Returns:
|
||||
:obj:`List[int]`: List of `token type IDs <../glossary.html#token-type-ids>`_ according to the given
|
||||
sequence(s).
|
||||
if token_ids_1 is None, only returns the first portion of the mask (0's).
|
||||
"""
|
||||
sep = [self.sep_token_id]
|
||||
cls = [self.cls_token_id]
|
||||
@@ -941,16 +867,7 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
return len(cls + token_ids_0 + sep) * [0] + len(token_ids_1 + sep) * [1]
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
"""
|
||||
Save the vocabulary and special tokens file to a directory.
|
||||
|
||||
Args:
|
||||
save_directory (:obj:`str`):
|
||||
The directory in which to save the vocabulary.
|
||||
|
||||
Returns:
|
||||
:obj:`Tuple(str)`: Paths to the files saved.
|
||||
"""
|
||||
"""Save the tokenizer vocabulary and merge files to a directory."""
|
||||
if not os.path.isdir(save_directory):
|
||||
logger.error("Vocabulary path ({}) should be a directory".format(save_directory))
|
||||
return
|
||||
|
||||
Loaded 100 of 120 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user