 Funtowicz MorganandMOI Anthony
71c8711970
* Added transformers-pytorch-cpu and gpu Docker images

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added automatic jupyter launch for Docker image.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Move image from alpine to Ubuntu to align with NVidia container images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added TRANSFORMERS_VERSION argument to Dockerfile.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added Pytorch-GPU based Docker image

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added Tensorflow images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Use python 3.7 as Tensorflow doesnt provide 3.8 compatible wheel.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Remove double FROM instructions on transformers-pytorch-cpu image.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added transformers-tensorflow-gpu Docker image.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* use the correct ubuntu version for tensorflow-gpu

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added pipelines example notebook

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added transformers-cpu and transformers-gpu (including both PyTorch and TensorFlow) images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Docker images doesnt start jupyter notebook by default.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Tokenizers notebook

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Update images links

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Update Docker images to python 3.7.6 and transformers 2.5.1

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added 02-transformers notebook.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Trying to realign 02-transformers notebook ?

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added Transformer image schema

* Some tweaks on tokenizers notebook

* Removed old notebooks.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Attempt to provide table of content for each notebooks

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Second attempt.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Reintroduce transformer image.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Keep trying

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* It's going to fly !

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Remaining of the Table of Content

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Fix inlined elements for the table of content

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Removed anaconda dependencies for Docker images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Removing notebooks ToC

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added LABEL to each docker image.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Removed old Dockerfile

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Directly use the context and include transformers from here.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Reduce overall size of compiled Docker images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Install jupyter by default and use CMD for easier launching of the images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Reduce number of layers in the images.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added README.md for notebooks.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Fix notebooks link in README

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Fix some wording issues.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Added blog notebooks too.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

* Addressing spelling errors in review comments.

Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>

Co-authored-by: MOI Anthony <xn1t0x@gmail.com>
20 KiB
Introduction
The transformers library is an open-source, community-based repository to train, use and share models based on the Transformer architecture (Vaswani & al., 2017) such as Bert (Devlin & al., 2018), Roberta (Liu & al., 2019), GPT2 (Radford & al., 2019), XLNet (Yang & al., 2019), etc.
Along with the models, the library contains multiple variations of each of them for a large variety of downstream-tasks like Named Entity Recognition (NER), Sentiment Analysis, Language Modeling, Question Answering and so on.
Before Transformer
Back to 2017, most of the people using Neural Networks when working on Natural Language Processing were relying on sequential processing of the input through Recurrent Neural Network (RNN).
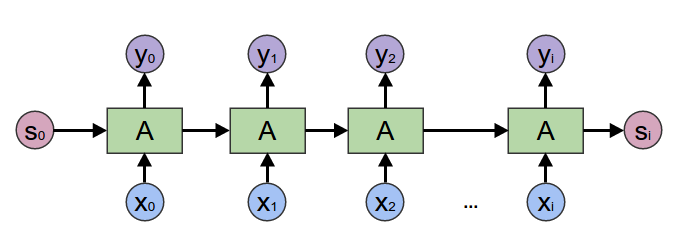
RNNs were performing well on large variety of tasks involving sequential dependency over the input sequence. However, this sequentially-dependent process had issues modeling very long range dependencies and was not well suited for the kind of hardware we're currently leveraging due to bad parallelization capabilities.
Some extensions were provided by the academic community, such as Bidirectional RNN (Schuster & Paliwal., 1997, Graves & al., 2005), which can be seen as a concatenation of two sequential process, on going forward, the other one going backward over the sequence input.
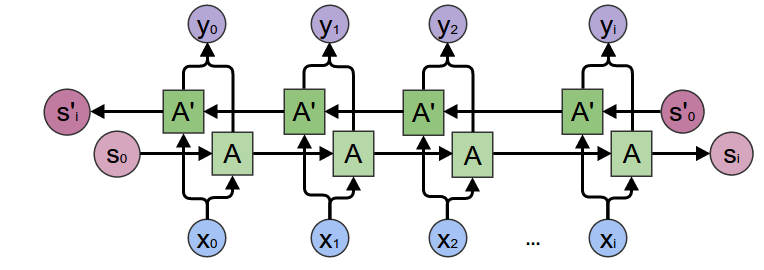
And also, the Attention mechanism, which introduced a good improvement over "raw" RNNs by giving a learned, weighted-importance to each element in the sequence, allowing the model to focus on important elements.

Then comes the Transformer
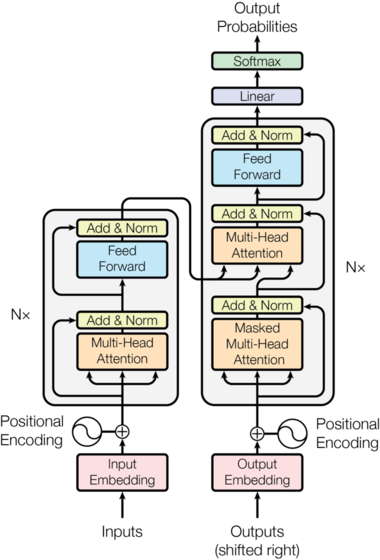
The Transformers era originally started from the work of (Vaswani & al., 2017) who demonstrated its superiority over Recurrent Neural Network (RNN) on translation tasks but it quickly extended to almost all the tasks RNNs were State-of-the-Art at that time.
One advantage of Transformer over its RNN counterpart was its non sequential attention model. Remember, the RNNs had to iterate over each element of the input sequence one-by-one and carry an "updatable-state" between each hop. With Transformer the, the model is able to look at every position in the sequence, at the same time, in one operation.
For a deep-dive into the Transformer architecture, The Annotated Transformer will drive you along all the details of the paper.
import torch
from transformers import AutoModel, AutoTokenizer, BertTokenizer

torch.set_grad_enabled(False)<torch.autograd.grad_mode.set_grad_enabled at 0x1af62fd450>
# Store the model we want to use
MODEL_NAME = "bert-base-cased"

# We need to create the model and tokenizer
model = AutoModel.from_pretrained(MODEL_NAME)
tokenizer = AutoTokenizer.from_pretrained(MODEL_NAME) # Tokens comes from a process that splits the input into sub-entities with interesting linguistic properties.
tokens = tokenizer.tokenize("This is an input example")
print("Tokens: {}".format(tokens))
# This is not sufficient for the model, as it requires integers as input,
# not a problem, let's convert tokens to ids.
tokens_ids = tokenizer.convert_tokens_to_ids(tokens)
print("Tokens id: {}".format(tokens_ids))
# We need to convert to a Deep Learning framework specific format, let's use PyTorch for now.
tokens_pt = torch.tensor([tokens_ids])
print("Tokens PyTorch: {}".format(tokens_pt))
# Now we're ready to go through BERT with out input
outputs, pooled = model(tokens_pt)
print("Tokenwise output: {}, Pooled output: {}".format(outputs.shape, pooled.shape))Tokens: ['[CLS]', 'This', 'is', 'an', 'input', 'example', '[SEP]'] Tokens id: [101, 1188, 1110, 1126, 7758, 1859, 102] Tokens PyTorch: tensor([[ 101, 1188, 1110, 1126, 7758, 1859, 102]]) Tokenwise output: torch.Size([1, 7, 768]), Pooled output: torch.Size([1, 768])
# tokens = tokenizer.tokenize("This is an input example")
# tokens_ids = tokenizer.convert_tokens_to_ids(tokens)
# tokens_pt = torch.tensor([tokens_ids])

# This code can be factored into one-line as follow
tokens_pt2 = tokenizer.encode_plus("This is an input example", return_tensors="pt")

for key, value in tokens_pt2.items():
    print("{}:\n\t{}".format(key, value))

outputs2, pooled2 = model(**tokens_pt2)
print("Difference with previous code: ({}, {})".format((outputs2 - outputs).sum(), (pooled2 - pooled).sum()))
input_ids: tensor([[ 101, 1188, 1110, 1126, 7758, 1859, 102]]) token_type_ids: tensor([[0, 0, 0, 0, 0, 0, 0]]) attention_mask: tensor([[1, 1, 1, 1, 1, 1, 1]]) Difference with previous code: (0.0, 0.0)
# Single segment input
single_seg_input = tokenizer.encode_plus("This is a sample input")

# Multiple segment input
multi_seg_input = tokenizer.encode_plus("This is segment A", "This is segment B")

print("Single segment token (str): {}".format(tokenizer.convert_ids_to_tokens(single_seg_input['input_ids'])))
print("Single segment token (int): {}".format(single_seg_input['input_ids']))
print("Single segment type       : {}".format(single_seg_input['token_type_ids']))

# Segments are concatened in the input to the model, with
print()
print("Multi segment token (str): {}".format(tokenizer.convert_ids_to_tokens(multi_seg_input['input_ids'])))
print("Multi segment token (int): {}".format(multi_seg_input['input_ids']))
print("Multi segment type       : {}".format(multi_seg_input['token_type_ids']))
Single segment token (str): ['[CLS]', 'This', 'is', 'a', 'sample', 'input', '[SEP]'] Single segment token (int): [101, 1188, 1110, 170, 6876, 7758, 102] Single segment type : [0, 0, 0, 0, 0, 0, 0] Multi segment token (str): ['[CLS]', 'This', 'is', 'segment', 'A', '[SEP]', 'This', 'is', 'segment', 'B', '[SEP]'] Multi segment token (int): [101, 1188, 1110, 6441, 138, 102, 1188, 1110, 6441, 139, 102] Multi segment type : [0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1]
# Padding highlight
tokens = tokenizer.batch_encode_plus(
    ["This is a sample", "This is another longer sample text"],
    pad_to_max_length=True  # First sentence will have some PADDED tokens to match second sequence length
)

for i in range(2):
    print("Tokens (int)      : {}".format(tokens['input_ids'][i]))
    print("Tokens (str)      : {}".format([tokenizer.convert_ids_to_tokens(s) for s in tokens['input_ids'][i]]))
    print("Tokens (attn_mask): {}".format(tokens['attention_mask'][i]))
    print()
Tokens (int) : [101, 1188, 1110, 170, 6876, 102, 0, 0] Tokens (str) : ['[CLS]', 'This', 'is', 'a', 'sample', '[SEP]', '[PAD]', '[PAD]'] Tokens (attn_mask): [1, 1, 1, 1, 1, 1, 0, 0] Tokens (int) : [101, 1188, 1110, 1330, 2039, 6876, 3087, 102] Tokens (str) : ['[CLS]', 'This', 'is', 'another', 'longer', 'sample', 'text', '[SEP]'] Tokens (attn_mask): [1, 1, 1, 1, 1, 1, 1, 1]
from transformers import TFBertModel, BertModel

# Let's load a BERT model for TensorFlow and PyTorch
model_tf = TFBertModel.from_pretrained('bert-base-cased')
model_pt = BertModel.from_pretrained('bert-base-cased')# transformers generates a ready to use dictionary with all the required parameters for the specific framework.
input_tf = tokenizer.encode_plus("This is a sample input", return_tensors="tf")
input_pt = tokenizer.encode_plus("This is a sample input", return_tensors="pt")
# Let's compare the outputs
output_tf, output_pt = model_tf(input_tf), model_pt(**input_pt)
# Models outputs 2 values (The value for each tokens, the pooled representation of the input sentence)
# Here we compare the output differences between PyTorch and TensorFlow.
for name, o_tf, o_pt in zip(["output", "pooled"], output_tf, output_pt):
print("{} differences: {}".format(name, (o_tf.numpy() - o_pt.numpy()).sum()))output differences: 2.971128560602665e-05 pooled differences: -8.576549589633942e-06
Want it lighter? Faster? Let's talk distillation!
One of the main concerns when using these Transformer based models is the computational power they require. All over this notebook we are using BERT model as it can be run on common machines but that's not the case for all of the models.
For example, Google released a few months ago T5 an Encoder/Decoder architecture based on Transformer and available in transformers with no more than 11 billions parameters. Microsoft also recently entered the game with Turing-NLG using 17 billions parameters. This kind of model requires tens of gigabytes to store the weights and a tremendous compute infrastructure to run such models which makes it impracticable for the common man !

With the goal of making Transformer-based NLP accessible to everyone we @huggingface developed models that take advantage of a training process called Distillation which allows us to drastically reduce the resources needed to run such models with almost zero drop in performances.
Going over the whole Distillation process is out of the scope of this notebook, but if you want more information on the subject you may refer to this Medium article written by my colleague Victor SANH, author of DistilBERT paper, you might also want to directly have a look at the paper (Sanh & al., 2019)
Of course, in transformers we have distilled some models and made them available directly in the library !
from transformers import DistilBertModel

bert_distil = DistilBertModel.from_pretrained('distilbert-base-cased')
input_pt = tokenizer.encode_plus(
    'This is a sample input to demonstrate performance of distiled models especially inference time',
    return_tensors="pt"
)


%time _ = bert_distil(input_pt['input_ids'])
%time _ = model_pt(input_pt['input_ids'])
CPU times: user 57.1 ms, sys: 2.44 ms, total: 59.5 ms Wall time: 35.5 ms CPU times: user 98.8 ms, sys: 725 µs, total: 99.5 ms Wall time: 50 ms
# Let's load German BERT from the Bavarian State Library
de_bert = BertModel.from_pretrained("dbmdz/bert-base-german-cased")
de_tokenizer = BertTokenizer.from_pretrained("dbmdz/bert-base-german-cased")

de_input = de_tokenizer.encode_plus(
    "Hugging Face ist einen französische Firma Mitarbeitern in New-York.",
    return_tensors="pt"
)
output_de, pooled_de = de_bert(**de_input)