Compare commits
3
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 thomwolf |
a40dd4ae86 | ||
|
thomwolf
|
ac8575ca5c | ||
|
thomwolf
|
ead691983b |
No files matched your search
@@ -139,6 +139,3 @@ serialization_dir
|
||||
# emacs
|
||||
*.*~
|
||||
debug.env
|
||||
|
||||
# vim
|
||||
.*.swp
|
||||
+1
-1
@@ -26,7 +26,7 @@ author = u'huggingface'
|
||||
# The short X.Y version
|
||||
version = u''
|
||||
# The full version, including alpha/beta/rc tags
|
||||
release = u'2.5.0'
|
||||
release = u'2.4.1'
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
|
||||
+2
-2
@@ -772,7 +772,7 @@ export HANS_DIR=path-to-hans
|
||||
export MODEL_TYPE=type-of-the-model-e.g.-bert-roberta-xlnet-etc
|
||||
export MODEL_PATH=path-to-the-model-directory-that-is-trained-on-NLI-e.g.-by-using-run_glue.py
|
||||
|
||||
python examples/hans/test_hans.py \
|
||||
python examples/test_hans.py \
|
||||
--task_name hans \
|
||||
--model_type $MODEL_TYPE \
|
||||
--do_eval \
|
||||
@@ -780,7 +780,7 @@ python examples/hans/test_hans.py \
|
||||
--data_dir $HANS_DIR \
|
||||
--model_name_or_path $MODEL_PATH \
|
||||
--max_seq_length 128 \
|
||||
--output_dir $MODEL_PATH \
|
||||
-output_dir $MODEL_PATH \
|
||||
```
|
||||
|
||||
This will create the hans_predictions.txt file in MODEL_PATH, which can then be evaluated using hans/evaluate_heur_output.py from the HANS dataset.
|
||||
|
||||
@@ -75,17 +75,13 @@ def main():
|
||||
iter += 1
|
||||
if iter % interval == 0:
|
||||
end = time.time()
|
||||
logger.info(f"{iter} examples processed. - {(end-start):.2f}s/{interval}expl")
|
||||
logger.info(f"{iter} examples processed. - {(end-start)/interval:.2f}s/expl")
|
||||
start = time.time()
|
||||
logger.info("Finished binarization")
|
||||
logger.info(f"{len(data)} examples processed.")
|
||||
|
||||
dp_file = f"{args.dump_file}.{args.tokenizer_name}.pickle"
|
||||
vocab_size = tokenizer.vocab_size
|
||||
if vocab_size < (1 << 16):
|
||||
rslt_ = [np.uint16(d) for d in rslt]
|
||||
else:
|
||||
rslt_ = [np.int32(d) for d in rslt]
|
||||
rslt_ = [np.uint16(d) for d in rslt]
|
||||
random.shuffle(rslt_)
|
||||
logger.info(f"Dump to {dp_file}")
|
||||
with open(dp_file, "wb") as handle:
|
||||
|
||||
@@ -1,5 +0,0 @@
|
||||
This model is pre-trained **XLNET** with 12 layers.
|
||||
|
||||
It comes with paper: SBERT-WK: A Sentence Embedding Method By Dissecting BERT-based Word Models
|
||||
|
||||
Project Page: [SBERT-WK](https://github.com/BinWang28/SBERT-WK-Sentence-Embedding)
|
||||
@@ -1,74 +0,0 @@
|
||||
---
|
||||
language: turkish
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Turkish BERT model
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources a cased model for Turkish 🎉
|
||||
|
||||
# 🇹🇷 BERTurk
|
||||
|
||||
BERTurk is a community-driven cased BERT model for Turkish.
|
||||
|
||||
Some datasets used for pretraining and evaluation are contributed from the
|
||||
awesome Turkish NLP community, as well as the decision for the model name: BERTurk.
|
||||
|
||||
## Stats
|
||||
|
||||
The current version of the model is trained on a filtered and sentence
|
||||
segmented version of the Turkish [OSCAR corpus](https://traces1.inria.fr/oscar/),
|
||||
a recent Wikipedia dump, various [OPUS corpora](http://opus.nlpl.eu/) and a
|
||||
special corpus provided by [Kemal Oflazer](http://www.andrew.cmu.edu/user/ko/).
|
||||
|
||||
The final training corpus has a size of 35GB and 44,04,976,662 tokens.
|
||||
|
||||
Thanks to Google's TensorFlow Research Cloud (TFRC) we could train a cased model
|
||||
on a TPU v3-8 for 2M steps.
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| --------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-turkish-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-turkish-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-turkish-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-turkish-cased/vocab.txt)
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our BERTurk cased model can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-turkish-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-turkish-cased")
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
For results on PoS tagging or NER tasks, please refer to
|
||||
[this repository](https://github.com/stefan-it/turkish-bert).
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Thanks to [Kemal Oflazer](http://www.andrew.cmu.edu/user/ko/) for providing us
|
||||
additional large corpora for Turkish. Many thanks to Reyyan Yeniterzi for providing
|
||||
us the Turkish NER dataset for evaluation.
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -1,58 +0,0 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# Spanish BERT (BETO) + NER
|
||||
|
||||
This model is a fine-tuned on [NER-C](https://www.kaggle.com/nltkdata/conll-corpora) of the Spanish BERT cased [(BETO)](https://github.com/dccuchile/beto) for **NER** downstream task.
|
||||
|
||||
## Details of the downstream task (NER) - Dataset
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora)
|
||||
|
||||
I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
|
||||
| Dataset | # Examples |
|
||||
| ---------------------- | ----- |
|
||||
| Train | 8.7 K |
|
||||
| Dev | 2.2 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
```bash
|
||||
!export NER_DIR='/content/ner_dataset'
|
||||
!python /content/transformers/examples/run_ner.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--data_dir '/content/ner_dataset' \
|
||||
--num_train_epochs 15.0 \
|
||||
--max_seq_length 384 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
|
||||
```
|
||||
|
||||
## Comparison:
|
||||
|
||||
| Model | # score |
|
||||
| :--------------------------------------------------------------------------------------------------------------: | :-------: |
|
||||
| bert-base-spanish-wwm-cased (BETO) | 88.43 |
|
||||
| [bert-spanish-cased-finetuned-ner (this one)](https://huggingface.co/mrm8488/bert-spanish-cased-finetuned-ner) | **89.65** |
|
||||
| Best Multilingual BERT | 87.38 |
|
||||
|
||||
```
|
||||
***** All metrics on Eval results *****
|
||||
|
||||
f1 = 0.8965040489828165
|
||||
loss = 0.11504213575173258
|
||||
precision = 0.893679858239811
|
||||
recall = 0.8993461462254805
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
+12
-16
@@ -46,7 +46,7 @@ The model was trained on a Tesla P100 GPU and 25GB of RAM with the following com
|
||||
--predict_file $SQUAD_DIR/dev-v2.json \
|
||||
--per_gpu_train_batch_size 12 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 5.0 \
|
||||
--num_train_epochs 3.0 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /content/model_output \
|
||||
@@ -59,23 +59,23 @@ The model was trained on a Tesla P100 GPU and 25GB of RAM with the following com
|
||||
|
||||
| Metric | # Value |
|
||||
| --------- | ----------- |
|
||||
| **Exact** | **90.77**48 |
|
||||
| **F1** | **94.94**71 |
|
||||
| **Exact** | **82.40**65 |
|
||||
| **F1** | **90.50**36 |
|
||||
|
||||
```json
|
||||
{
|
||||
"exact": 90.77483309730933,
|
||||
"f1": 94.94714391266254,
|
||||
"exact": 82.40657784457096,
|
||||
"f1": 90.50369643376753,
|
||||
"total": 69202,
|
||||
"HasAns_exact": 86.60850599781898,
|
||||
"HasAns_f1": 92.90582885592328,
|
||||
"HasAns_exact": 75.13413304253,
|
||||
"HasAns_f1": 87.35521920631561,
|
||||
"HasAns_total": 45850,
|
||||
"NoAns_exact": 98.95512161699212,
|
||||
"NoAns_f1": 98.95512161699212,
|
||||
"NoAns_exact": 96.68550873586845,
|
||||
"NoAns_f1": 96.68550873586845,
|
||||
"NoAns_total": 23352,
|
||||
"best_exact": 90.77483309730933,
|
||||
"best_exact": 82.40657784457096,
|
||||
"best_exact_thresh": 0.0,
|
||||
"best_f1": 94.94714391266305,
|
||||
"best_f1": 90.50369643376902,
|
||||
"best_f1_thresh": 0.0
|
||||
}
|
||||
```
|
||||
@@ -85,7 +85,7 @@ The model was trained on a Tesla P100 GPU and 25GB of RAM with the following com
|
||||
| Model | f1 score |
|
||||
| :-------------------------------------------------------------: | :-------: |
|
||||
| bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | 86.07 |
|
||||
| **distill**-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | **94.94** |
|
||||
| **distill**-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | **90.50** |
|
||||
|
||||
So, yes, this version is even more accurate.
|
||||
|
||||
@@ -101,10 +101,6 @@ So, yes, this version is even more accurate.
|
||||
|
||||
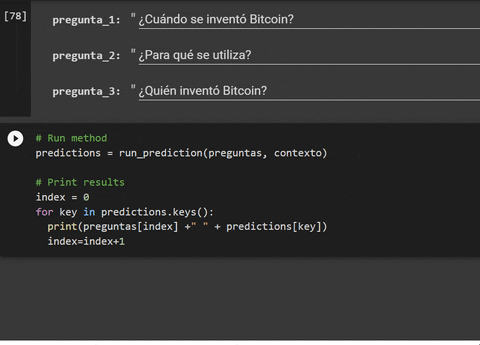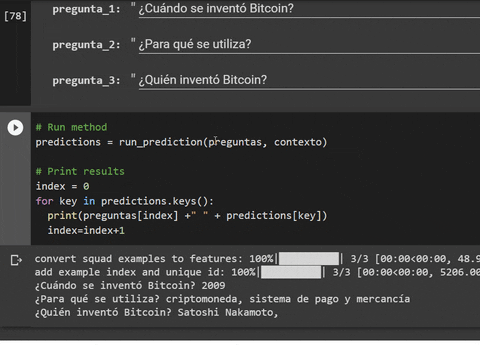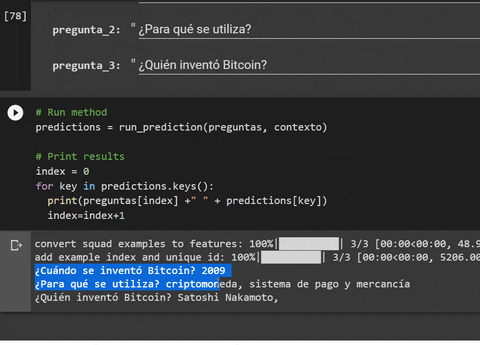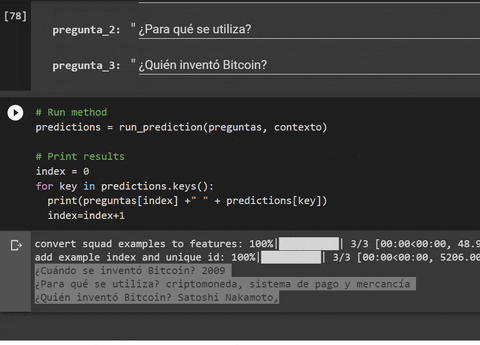
|
||||
|
||||
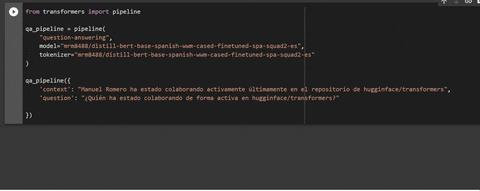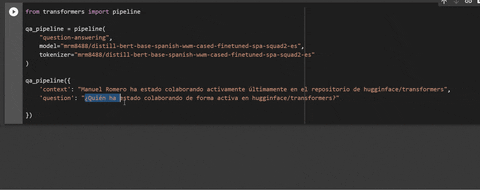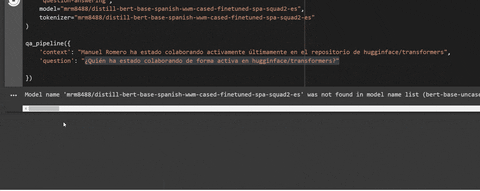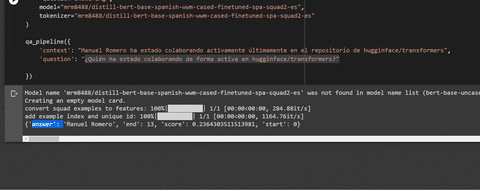
3. Using **Pipelines**
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
@@ -76,8 +76,8 @@ extras["dev"] = extras["testing"] + extras["quality"] + ["mecab-python3", "sciki
|
||||
|
||||
setup(
|
||||
name="transformers",
|
||||
version="2.5.0",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Sam Shleifer, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
version="2.4.1",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
author_email="thomas@huggingface.co",
|
||||
description="State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch",
|
||||
long_description=open("README.md", "r", encoding="utf-8").read(),
|
||||
@@ -89,7 +89,7 @@ setup(
|
||||
packages=find_packages("src"),
|
||||
install_requires=[
|
||||
"numpy",
|
||||
"tokenizers == 0.5.0",
|
||||
"tokenizers == 0.0.11",
|
||||
# accessing files from S3 directly
|
||||
"boto3",
|
||||
# filesystem locks e.g. to prevent parallel downloads
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# There's no way to ignore "F401 '...' imported but unused" warnings in this
|
||||
# module, but to preserve other warnings. So, don't check this module at all.
|
||||
|
||||
__version__ = "2.5.0"
|
||||
__version__ = "2.4.1"
|
||||
|
||||
# Work around to update TensorFlow's absl.logging threshold which alters the
|
||||
# default Python logging output behavior when present.
|
||||
@@ -110,13 +110,13 @@ from .tokenization_bert import BasicTokenizer, BertTokenizer, BertTokenizerFast,
|
||||
from .tokenization_bert_japanese import BertJapaneseTokenizer, CharacterTokenizer, MecabTokenizer
|
||||
from .tokenization_camembert import CamembertTokenizer
|
||||
from .tokenization_ctrl import CTRLTokenizer
|
||||
from .tokenization_distilbert import DistilBertTokenizer, DistilBertTokenizerFast
|
||||
from .tokenization_distilbert import DistilBertTokenizer
|
||||
from .tokenization_flaubert import FlaubertTokenizer
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer, OpenAIGPTTokenizerFast
|
||||
from .tokenization_roberta import RobertaTokenizer, RobertaTokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer
|
||||
from .tokenization_roberta import RobertaTokenizer
|
||||
from .tokenization_t5 import T5Tokenizer
|
||||
from .tokenization_transfo_xl import TransfoXLCorpus, TransfoXLTokenizer, TransfoXLTokenizerFast
|
||||
from .tokenization_transfo_xl import TransfoXLCorpus, TransfoXLTokenizer
|
||||
|
||||
# Tokenizers
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
@@ -214,6 +214,7 @@ def cached_path(
|
||||
user_agent=None,
|
||||
extract_compressed_file=False,
|
||||
force_extract=False,
|
||||
extract_dir=None,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given something that might be a URL (or might be a local path),
|
||||
@@ -229,6 +230,7 @@ def cached_path(
|
||||
file in a folder along the archive.
|
||||
force_extract: if True when extract_compressed_file is True and the archive was already extracted,
|
||||
re-extract the archive and overide the folder where it was extracted.
|
||||
extract_dir: specify a directory to extract the archive to (overwrite the default created directory).
|
||||
|
||||
Return:
|
||||
None in case of non-recoverable file (non-existent or inaccessible url + no cache on disk).
|
||||
@@ -261,7 +263,7 @@ def cached_path(
|
||||
# Something unknown
|
||||
raise ValueError("unable to parse {} as a URL or as a local path".format(url_or_filename))
|
||||
|
||||
if extract_compressed_file:
|
||||
if extract_compressed_file and os.path.isfile(output_path):
|
||||
if not is_zipfile(output_path) and not tarfile.is_tarfile(output_path):
|
||||
return output_path
|
||||
|
||||
@@ -271,24 +273,22 @@ def cached_path(
|
||||
output_extract_dir_name = output_file.replace(".", "-") + "-extracted"
|
||||
output_path_extracted = os.path.join(output_dir, output_extract_dir_name)
|
||||
|
||||
if os.path.isdir(output_path_extracted) and os.listdir(output_path_extracted) and not force_extract:
|
||||
return output_path_extracted
|
||||
|
||||
# Prevent parallel extractions
|
||||
lock_path = output_path + ".lock"
|
||||
with FileLock(lock_path):
|
||||
shutil.rmtree(output_path_extracted, ignore_errors=True)
|
||||
os.makedirs(output_path_extracted)
|
||||
if is_zipfile(output_path):
|
||||
with ZipFile(output_path, "r") as zip_file:
|
||||
zip_file.extractall(output_path_extracted)
|
||||
zip_file.close()
|
||||
elif tarfile.is_tarfile(output_path):
|
||||
tar_file = tarfile.open(output_path)
|
||||
tar_file.extractall(output_path_extracted)
|
||||
tar_file.close()
|
||||
else:
|
||||
raise EnvironmentError("Archive format of {} could not be identified".format(output_path))
|
||||
if not os.path.isdir(output_path_extracted) or force_extract:
|
||||
# Extract file with a lock to prevent parallel extractions
|
||||
lock_path = output_path + ".lock"
|
||||
with FileLock(lock_path):
|
||||
shutil.rmtree(output_path_extracted, ignore_errors=True)
|
||||
os.makedirs(output_path_extracted)
|
||||
if is_zipfile(output_path):
|
||||
with ZipFile(output_path, "r") as zip_file:
|
||||
zip_file.extractall(output_path_extracted)
|
||||
zip_file.close()
|
||||
elif tarfile.is_tarfile(output_path):
|
||||
tar_file = tarfile.open(output_path)
|
||||
tar_file.extractall(output_path_extracted)
|
||||
tar_file.close()
|
||||
else:
|
||||
raise EnvironmentError("Archive format of {} could not be identified".format(output_path))
|
||||
|
||||
return output_path_extracted
|
||||
|
||||
|
||||
@@ -982,7 +982,7 @@ SUPPORTED_TASKS = {
|
||||
"default": {
|
||||
"model": {"pt": "distilbert-base-cased-distilled-squad", "tf": "distilbert-base-cased-distilled-squad"},
|
||||
"config": None,
|
||||
"tokenizer": ("distilbert-base-cased", {"use_fast": False}),
|
||||
"tokenizer": "distilbert-base-cased",
|
||||
},
|
||||
},
|
||||
"fill-mask": {
|
||||
@@ -992,7 +992,7 @@ SUPPORTED_TASKS = {
|
||||
"default": {
|
||||
"model": {"pt": "distilroberta-base", "tf": "distilroberta-base"},
|
||||
"config": None,
|
||||
"tokenizer": ("distilroberta-base", {"use_fast": False}),
|
||||
"tokenizer": "distilroberta-base",
|
||||
},
|
||||
},
|
||||
}
|
||||
@@ -1057,12 +1057,8 @@ def pipeline(
|
||||
modelcard = config
|
||||
|
||||
# Instantiate tokenizer if needed
|
||||
if isinstance(tokenizer, (str, tuple)):
|
||||
if isinstance(tokenizer, tuple):
|
||||
# For tuple we have (tokenizer name, {kwargs})
|
||||
tokenizer = AutoTokenizer.from_pretrained(tokenizer[0], **tokenizer[1])
|
||||
else:
|
||||
tokenizer = AutoTokenizer.from_pretrained(tokenizer)
|
||||
if isinstance(tokenizer, str):
|
||||
tokenizer = AutoTokenizer.from_pretrained(tokenizer)
|
||||
|
||||
# Instantiate config if needed
|
||||
if isinstance(config, str):
|
||||
|
||||
@@ -37,17 +37,17 @@ from .configuration_auto import (
|
||||
)
|
||||
from .configuration_utils import PretrainedConfig
|
||||
from .tokenization_albert import AlbertTokenizer
|
||||
from .tokenization_bert import BertTokenizer, BertTokenizerFast
|
||||
from .tokenization_bert import BertTokenizer
|
||||
from .tokenization_bert_japanese import BertJapaneseTokenizer
|
||||
from .tokenization_camembert import CamembertTokenizer
|
||||
from .tokenization_ctrl import CTRLTokenizer
|
||||
from .tokenization_distilbert import DistilBertTokenizer, DistilBertTokenizerFast
|
||||
from .tokenization_distilbert import DistilBertTokenizer
|
||||
from .tokenization_flaubert import FlaubertTokenizer
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer, OpenAIGPTTokenizerFast
|
||||
from .tokenization_roberta import RobertaTokenizer, RobertaTokenizerFast
|
||||
from .tokenization_gpt2 import GPT2Tokenizer
|
||||
from .tokenization_openai import OpenAIGPTTokenizer
|
||||
from .tokenization_roberta import RobertaTokenizer
|
||||
from .tokenization_t5 import T5Tokenizer
|
||||
from .tokenization_transfo_xl import TransfoXLTokenizer, TransfoXLTokenizerFast
|
||||
from .tokenization_transfo_xl import TransfoXLTokenizer
|
||||
from .tokenization_xlm import XLMTokenizer
|
||||
from .tokenization_xlm_roberta import XLMRobertaTokenizer
|
||||
from .tokenization_xlnet import XLNetTokenizer
|
||||
@@ -58,20 +58,20 @@ logger = logging.getLogger(__name__)
|
||||
|
||||
TOKENIZER_MAPPING = OrderedDict(
|
||||
[
|
||||
(T5Config, (T5Tokenizer, None)),
|
||||
(DistilBertConfig, (DistilBertTokenizer, DistilBertTokenizerFast)),
|
||||
(AlbertConfig, (AlbertTokenizer, None)),
|
||||
(CamembertConfig, (CamembertTokenizer, None)),
|
||||
(XLMRobertaConfig, (XLMRobertaTokenizer, None)),
|
||||
(RobertaConfig, (RobertaTokenizer, RobertaTokenizerFast)),
|
||||
(BertConfig, (BertTokenizer, BertTokenizerFast)),
|
||||
(OpenAIGPTConfig, (OpenAIGPTTokenizer, OpenAIGPTTokenizerFast)),
|
||||
(GPT2Config, (GPT2Tokenizer, GPT2TokenizerFast)),
|
||||
(TransfoXLConfig, (TransfoXLTokenizer, TransfoXLTokenizerFast)),
|
||||
(XLNetConfig, (XLNetTokenizer, None)),
|
||||
(FlaubertConfig, (FlaubertTokenizer, None)),
|
||||
(XLMConfig, (XLMTokenizer, None)),
|
||||
(CTRLConfig, (CTRLTokenizer, None)),
|
||||
(T5Config, T5Tokenizer),
|
||||
(DistilBertConfig, DistilBertTokenizer),
|
||||
(AlbertConfig, AlbertTokenizer),
|
||||
(CamembertConfig, CamembertTokenizer),
|
||||
(XLMRobertaConfig, XLMRobertaTokenizer),
|
||||
(RobertaConfig, RobertaTokenizer),
|
||||
(BertConfig, BertTokenizer),
|
||||
(OpenAIGPTConfig, OpenAIGPTTokenizer),
|
||||
(GPT2Config, GPT2Tokenizer),
|
||||
(TransfoXLConfig, TransfoXLTokenizer),
|
||||
(XLNetConfig, XLNetTokenizer),
|
||||
(FlaubertConfig, FlaubertTokenizer),
|
||||
(XLMConfig, XLMTokenizer),
|
||||
(CTRLConfig, CTRLTokenizer),
|
||||
]
|
||||
)
|
||||
|
||||
@@ -154,9 +154,6 @@ class AutoTokenizer:
|
||||
A dictionary of proxy servers to use by protocol or endpoint, e.g.: {'http': 'foo.bar:3128', 'http://hostname': 'foo.bar:4012'}.
|
||||
The proxies are used on each request.
|
||||
|
||||
use_fast: (`optional`) boolean, default True:
|
||||
Indicate if transformers should try to load the fast version of the tokenizer (True) or use the Python one (False).
|
||||
|
||||
inputs: (`optional`) positional arguments: will be passed to the Tokenizer ``__init__`` method.
|
||||
|
||||
kwargs: (`optional`) keyword arguments: will be passed to the Tokenizer ``__init__`` method. Can be used to set special tokens like ``bos_token``, ``eos_token``, ``unk_token``, ``sep_token``, ``pad_token``, ``cls_token``, ``mask_token``, ``additional_special_tokens``. See parameters in the doc string of :class:`~transformers.PreTrainedTokenizer` for details.
|
||||
@@ -180,13 +177,9 @@ class AutoTokenizer:
|
||||
if "bert-base-japanese" in pretrained_model_name_or_path:
|
||||
return BertJapaneseTokenizer.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
|
||||
use_fast = kwargs.pop("use_fast", True)
|
||||
for config_class, (tokenizer_class_py, tokenizer_class_fast) in TOKENIZER_MAPPING.items():
|
||||
for config_class, tokenizer_class in TOKENIZER_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
if tokenizer_class_fast and use_fast:
|
||||
return tokenizer_class_fast.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
else:
|
||||
return tokenizer_class_py.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
return tokenizer_class.from_pretrained(pretrained_model_name_or_path, *inputs, **kwargs)
|
||||
|
||||
raise ValueError(
|
||||
"Unrecognized configuration class {} to build an AutoTokenizer.\n"
|
||||
|
||||
@@ -20,7 +20,7 @@ import logging
|
||||
import os
|
||||
import unicodedata
|
||||
|
||||
from tokenizers import BertWordPieceTokenizer
|
||||
import tokenizers as tk
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
|
||||
@@ -550,19 +550,14 @@ class BertTokenizerFast(PreTrainedTokenizerFast):
|
||||
cls_token="[CLS]",
|
||||
mask_token="[MASK]",
|
||||
tokenize_chinese_chars=True,
|
||||
max_length=None,
|
||||
pad_to_max_length=False,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
add_special_tokens=True,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(
|
||||
BertWordPieceTokenizer(
|
||||
vocab_file=vocab_file,
|
||||
add_special_tokens=add_special_tokens,
|
||||
unk_token=unk_token,
|
||||
sep_token=sep_token,
|
||||
cls_token=cls_token,
|
||||
handle_chinese_chars=tokenize_chinese_chars,
|
||||
lowercase=do_lower_case,
|
||||
),
|
||||
unk_token=unk_token,
|
||||
sep_token=sep_token,
|
||||
pad_token=pad_token,
|
||||
@@ -571,4 +566,32 @@ class BertTokenizerFast(PreTrainedTokenizerFast):
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
self.do_lower_case = do_lower_case
|
||||
self._tokenizer = tk.Tokenizer(tk.models.WordPiece.from_files(vocab_file, unk_token=unk_token))
|
||||
self._update_special_tokens()
|
||||
self._tokenizer.with_pre_tokenizer(
|
||||
tk.pre_tokenizers.BertPreTokenizer.new(
|
||||
do_basic_tokenize=do_basic_tokenize,
|
||||
do_lower_case=do_lower_case,
|
||||
tokenize_chinese_chars=tokenize_chinese_chars,
|
||||
never_split=never_split if never_split is not None else [],
|
||||
)
|
||||
)
|
||||
self._tokenizer.with_decoder(tk.decoders.WordPiece.new())
|
||||
|
||||
if add_special_tokens:
|
||||
self._tokenizer.with_post_processor(
|
||||
tk.processors.BertProcessing.new(
|
||||
(sep_token, self._tokenizer.token_to_id(sep_token)),
|
||||
(cls_token, self._tokenizer.token_to_id(cls_token)),
|
||||
)
|
||||
)
|
||||
if max_length is not None:
|
||||
self._tokenizer.with_truncation(max_length, stride=stride, strategy=truncation_strategy)
|
||||
self._tokenizer.with_padding(
|
||||
max_length=max_length if pad_to_max_length else None,
|
||||
direction=self.padding_side,
|
||||
pad_id=self.pad_token_id,
|
||||
pad_type_id=self.pad_token_type_id,
|
||||
pad_token=self.pad_token,
|
||||
)
|
||||
self._decoder = tk.decoders.WordPiece.new()
|
||||
@@ -17,7 +17,7 @@
|
||||
|
||||
import logging
|
||||
|
||||
from .tokenization_bert import BertTokenizer, BertTokenizerFast
|
||||
from .tokenization_bert import BertTokenizer
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -74,10 +74,3 @@ class DistilBertTokenizer(BertTokenizer):
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
pretrained_init_configuration = PRETRAINED_INIT_CONFIGURATION
|
||||
|
||||
|
||||
class DistilBertTokenizerFast(BertTokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
pretrained_init_configuration = PRETRAINED_INIT_CONFIGURATION
|
||||
@@ -21,7 +21,7 @@ import os
|
||||
from functools import lru_cache
|
||||
|
||||
import regex as re
|
||||
from tokenizers import ByteLevelBPETokenizer
|
||||
import tokenizers as tk
|
||||
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
|
||||
@@ -259,19 +259,26 @@ class GPT2TokenizerFast(PreTrainedTokenizerFast):
|
||||
unk_token="<|endoftext|>",
|
||||
bos_token="<|endoftext|>",
|
||||
eos_token="<|endoftext|>",
|
||||
pad_to_max_length=False,
|
||||
add_prefix_space=False,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(
|
||||
ByteLevelBPETokenizer(vocab_file=vocab_file, merges_file=merges_file, add_prefix_space=add_prefix_space),
|
||||
bos_token=bos_token,
|
||||
eos_token=eos_token,
|
||||
unk_token=unk_token,
|
||||
**kwargs,
|
||||
)
|
||||
super().__init__(bos_token=bos_token, eos_token=eos_token, unk_token=unk_token, **kwargs)
|
||||
|
||||
logger.warning(
|
||||
"RobertaTokenizerFast has an issue when working on mask language modeling "
|
||||
"where it introduces an extra encoded space before the mask token."
|
||||
"See https://github.com/huggingface/transformers/pull/2778 for more information."
|
||||
self._tokenizer = tk.Tokenizer(tk.models.BPE.from_files(vocab_file, merges_file))
|
||||
self._update_special_tokens()
|
||||
self._tokenizer.with_pre_tokenizer(tk.pre_tokenizers.ByteLevel.new(add_prefix_space=add_prefix_space))
|
||||
self._tokenizer.with_decoder(tk.decoders.ByteLevel.new())
|
||||
if max_length:
|
||||
self._tokenizer.with_truncation(max_length, stride=stride, strategy=truncation_strategy)
|
||||
self._tokenizer.with_padding(
|
||||
max_length=max_length if pad_to_max_length else None,
|
||||
direction=self.padding_side,
|
||||
pad_id=self.pad_token_id if self.pad_token_id is not None else 0,
|
||||
pad_type_id=self.pad_token_type_id,
|
||||
pad_token=self.pad_token if self.pad_token is not None else "",
|
||||
)
|
||||
self._decoder = tk.decoders.ByteLevel.new()
|
||||
@@ -19,18 +19,9 @@ import json
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
from typing import List, Optional, Union
|
||||
|
||||
from tokenizers import Tokenizer
|
||||
from tokenizers.decoders import BPEDecoder
|
||||
from tokenizers.implementations import BaseTokenizer
|
||||
from tokenizers.models import BPE
|
||||
from tokenizers.normalizers import BertNormalizer, Sequence, unicode_normalizer_from_str
|
||||
from tokenizers.pre_tokenizers import BertPreTokenizer
|
||||
from tokenizers.trainers import BpeTrainer
|
||||
|
||||
from .tokenization_bert import BasicTokenizer
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -222,93 +213,3 @@ class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
index += 1
|
||||
|
||||
return vocab_file, merge_file
|
||||
|
||||
|
||||
class _OpenAIGPTCharBPETokenizer(BaseTokenizer):
|
||||
"""
|
||||
OpenAI character-level BPE Tokenizer
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file: Optional[str] = None,
|
||||
merges_file: Optional[str] = None,
|
||||
unk_token: Optional[str] = "<unk>",
|
||||
suffix: Optional[str] = "</w>",
|
||||
dropout: Optional[float] = None,
|
||||
unicode_normalizer: Optional[str] = None,
|
||||
):
|
||||
if vocab_file is not None and merges_file is not None:
|
||||
tokenizer = Tokenizer(
|
||||
BPE.from_files(
|
||||
vocab_file, merges_file, dropout=dropout, unk_token=unk_token, end_of_word_suffix=suffix
|
||||
)
|
||||
)
|
||||
else:
|
||||
tokenizer = Tokenizer(BPE.empty())
|
||||
|
||||
# Check for Unicode normalization first (before everything else)
|
||||
normalizers = []
|
||||
|
||||
if unicode_normalizer:
|
||||
normalizers += [unicode_normalizer_from_str(unicode_normalizer)]
|
||||
|
||||
# OpenAI normalization is the same as Bert
|
||||
normalizers += [BertNormalizer()]
|
||||
|
||||
# Create the normalizer structure
|
||||
if len(normalizers) > 0:
|
||||
if len(normalizers) > 1:
|
||||
tokenizer.normalizer = Sequence(normalizers)
|
||||
else:
|
||||
tokenizer.normalizer = normalizers[0]
|
||||
|
||||
tokenizer.pre_tokenizer = BertPreTokenizer()
|
||||
tokenizer.decoder = BPEDecoder(suffix=suffix)
|
||||
|
||||
parameters = {
|
||||
"model": "BPE",
|
||||
"unk_token": unk_token,
|
||||
"suffix": suffix,
|
||||
"dropout": dropout,
|
||||
}
|
||||
|
||||
super().__init__(tokenizer, parameters)
|
||||
|
||||
def train(
|
||||
self,
|
||||
files: Union[str, List[str]],
|
||||
vocab_size: int = 30000,
|
||||
min_frequency: int = 2,
|
||||
special_tokens: List[str] = ["<unk>"],
|
||||
limit_alphabet: int = 1000,
|
||||
initial_alphabet: List[str] = [],
|
||||
suffix: Optional[str] = "</w>",
|
||||
show_progress: bool = True,
|
||||
):
|
||||
""" Train the model using the given files """
|
||||
|
||||
trainer = BpeTrainer(
|
||||
vocab_size=vocab_size,
|
||||
min_frequency=min_frequency,
|
||||
special_tokens=special_tokens,
|
||||
limit_alphabet=limit_alphabet,
|
||||
initial_alphabet=initial_alphabet,
|
||||
end_of_word_suffix=suffix,
|
||||
show_progress=show_progress,
|
||||
)
|
||||
if isinstance(files, str):
|
||||
files = [files]
|
||||
self._tokenizer.train(trainer, files)
|
||||
|
||||
|
||||
class OpenAIGPTTokenizerFast(PreTrainedTokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
def __init__(self, vocab_file, merges_file, unk_token="<unk>", **kwargs):
|
||||
kwargs.setdefault("unk_token", unk_token)
|
||||
super().__init__(
|
||||
_OpenAIGPTCharBPETokenizer(vocab_file=vocab_file, merges_file=merges_file, unk_token=unk_token), **kwargs
|
||||
)
|
||||
@@ -17,9 +17,7 @@
|
||||
|
||||
import logging
|
||||
|
||||
from tokenizers.processors import RobertaProcessing
|
||||
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_gpt2 import GPT2Tokenizer
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -165,48 +163,3 @@ class RobertaTokenizer(GPT2Tokenizer):
|
||||
if add_prefix_space and not text[0].isspace():
|
||||
text = " " + text
|
||||
return text
|
||||
|
||||
|
||||
class RobertaTokenizerFast(GPT2TokenizerFast):
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file,
|
||||
merges_file,
|
||||
errors="replace",
|
||||
bos_token="<s>",
|
||||
eos_token="</s>",
|
||||
sep_token="</s>",
|
||||
cls_token="<s>",
|
||||
unk_token="<unk>",
|
||||
pad_token="<pad>",
|
||||
mask_token="<mask>",
|
||||
add_prefix_space=False,
|
||||
**kwargs
|
||||
):
|
||||
kwargs.setdefault("pad_token", pad_token)
|
||||
kwargs.setdefault("sep_token", sep_token)
|
||||
kwargs.setdefault("cls_token", cls_token)
|
||||
kwargs.setdefault("mask_token", mask_token)
|
||||
|
||||
super().__init__(
|
||||
vocab_file=vocab_file,
|
||||
merges_file=merges_file,
|
||||
unk_token=unk_token,
|
||||
bos_token=bos_token,
|
||||
eos_token=eos_token,
|
||||
add_prefix_space=add_prefix_space,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
self.tokenizer._tokenizer.post_processor = RobertaProcessing(
|
||||
(sep_token, self.sep_token_id), (cls_token, self.cls_token_id)
|
||||
)
|
||||
|
||||
# As we override the post_processor post super.__init__ the computed num_added_tokens is wrong in super().
|
||||
# We need to recompute max_len according to the newly register post_processor to get real values.
|
||||
self.max_len_single_sentence = self.max_len - self.num_added_tokens(False) # take into account special tokens
|
||||
self.max_len_sentences_pair = self.max_len - self.num_added_tokens(True) # take into account special tokens
|
||||
@@ -23,18 +23,11 @@ import logging
|
||||
import os
|
||||
import pickle
|
||||
from collections import Counter, OrderedDict
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
from tokenizers import Encoding, Tokenizer
|
||||
from tokenizers.implementations import BaseTokenizer
|
||||
from tokenizers.models import WordLevel
|
||||
from tokenizers.normalizers import Lowercase, Sequence, unicode_normalizer_from_str
|
||||
from tokenizers.pre_tokenizers import CharDelimiterSplit, WhitespaceSplit
|
||||
from tokenizers.processors import BertProcessing
|
||||
|
||||
from .file_utils import cached_path, is_torch_available
|
||||
from .tokenization_utils import PreTrainedTokenizer, PreTrainedTokenizerFast
|
||||
from .tokenization_utils import PreTrainedTokenizer
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
@@ -51,12 +44,6 @@ PRETRAINED_VOCAB_FILES_MAP = {
|
||||
}
|
||||
}
|
||||
|
||||
PRETRAINED_VOCAB_FILES_MAP_FAST = {
|
||||
"pretrained_vocab_file": {
|
||||
"transfo-xl-wt103": "https://s3.amazonaws.com/models.huggingface.co/bert/transfo-xl-wt103-vocab.json",
|
||||
}
|
||||
}
|
||||
|
||||
PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
"transfo-xl-wt103": None,
|
||||
}
|
||||
@@ -293,108 +280,6 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
return symbols
|
||||
|
||||
|
||||
class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
def __init__(
|
||||
self,
|
||||
vocab_file,
|
||||
delimiter,
|
||||
lowercase,
|
||||
unk_token,
|
||||
eos_token,
|
||||
add_eos=False,
|
||||
add_double_eos=False,
|
||||
normalization: Optional[str] = None,
|
||||
):
|
||||
|
||||
tokenizer = WordLevel.from_files(vocab_file, unk_token=unk_token)
|
||||
tokenizer = Tokenizer(tokenizer)
|
||||
|
||||
# Create the correct normalization path
|
||||
normalizer = []
|
||||
|
||||
# Include unicode normalization
|
||||
if normalization:
|
||||
normalizer += [unicode_normalizer_from_str(normalization)]
|
||||
|
||||
# Include case normalization
|
||||
if lowercase:
|
||||
normalizer += [Lowercase()]
|
||||
|
||||
if len(normalizer) > 0:
|
||||
tokenizer.normalizer = Sequence(normalizer) if len(normalizer) > 1 else normalizer[0]
|
||||
|
||||
# Setup the splitter
|
||||
tokenizer.pre_tokenizer = CharDelimiterSplit(delimiter) if delimiter else WhitespaceSplit()
|
||||
|
||||
if add_double_eos:
|
||||
tokenizer.post_processor = BertProcessing(
|
||||
(eos_token, tokenizer.token_to_id(eos_token)), (eos_token, tokenizer.token_to_id(eos_token))
|
||||
)
|
||||
|
||||
parameters = {
|
||||
"model": "TransfoXLModel",
|
||||
"add_eos": add_eos,
|
||||
"add_double_eos": add_double_eos,
|
||||
"unk_token": unk_token,
|
||||
"eos_token": eos_token,
|
||||
"delimiter": delimiter,
|
||||
"lowercase": lowercase,
|
||||
}
|
||||
|
||||
super().__init__(tokenizer, parameters)
|
||||
|
||||
def encode_batch(self, sequences: List[Union[str, Tuple[str, str]]]) -> List[Encoding]:
|
||||
return super().encode_batch(
|
||||
[seq.strip() if isinstance(seq, str) else (seq[0].strip(), seq[1].strip()) for seq in sequences]
|
||||
)
|
||||
|
||||
def encode(self, sequence: str, pair: Optional[str] = None) -> Encoding:
|
||||
return super().encode(sequence.strip(), pair.strip() if pair else pair)
|
||||
|
||||
|
||||
class TransfoXLTokenizerFast(PreTrainedTokenizerFast):
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP_FAST
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
special=None,
|
||||
min_freq=0,
|
||||
max_size=None,
|
||||
lower_case=False,
|
||||
delimiter=None,
|
||||
vocab_file=None,
|
||||
pretrained_vocab_file=None,
|
||||
never_split=None,
|
||||
unk_token="<unk>",
|
||||
eos_token="<eos>",
|
||||
additional_special_tokens=["<formula>"],
|
||||
add_eos=False,
|
||||
add_double_eos=False,
|
||||
normalization=None,
|
||||
**kwargs
|
||||
):
|
||||
|
||||
super().__init__(
|
||||
_TransfoXLDelimiterLookupTokenizer(
|
||||
vocab_file=vocab_file or pretrained_vocab_file,
|
||||
delimiter=delimiter,
|
||||
lowercase=lower_case,
|
||||
unk_token=unk_token,
|
||||
eos_token=eos_token,
|
||||
add_eos=add_eos,
|
||||
add_double_eos=add_double_eos,
|
||||
normalization=normalization,
|
||||
),
|
||||
unk_token=unk_token,
|
||||
eos_token=eos_token,
|
||||
additional_special_tokens=additional_special_tokens,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
class LMOrderedIterator(object):
|
||||
def __init__(self, data, bsz, bptt, device="cpu", ext_len=None):
|
||||
"""
|
||||
|
||||
@@ -21,10 +21,6 @@ import json
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
from collections import defaultdict
|
||||
from contextlib import contextmanager
|
||||
|
||||
from tokenizers.implementations import BaseTokenizer
|
||||
|
||||
from .file_utils import cached_path, hf_bucket_url, is_remote_url, is_tf_available, is_torch_available
|
||||
|
||||
@@ -41,68 +37,6 @@ ADDED_TOKENS_FILE = "added_tokens.json"
|
||||
TOKENIZER_CONFIG_FILE = "tokenizer_config.json"
|
||||
|
||||
|
||||
@contextmanager
|
||||
def truncate_and_pad(
|
||||
tokenizer: BaseTokenizer,
|
||||
max_length: int,
|
||||
stride: int,
|
||||
strategy: str,
|
||||
pad_to_max_length: bool,
|
||||
padding_side: str,
|
||||
pad_token_id: int,
|
||||
pad_token_type_id: int,
|
||||
pad_token: str,
|
||||
):
|
||||
"""
|
||||
This contextmanager is in charge of defining the truncation and the padding strategies and then
|
||||
restore the tokenizer settings afterwards.
|
||||
|
||||
This contextmanager assumes the provider tokenizer has no padding / truncation strategy
|
||||
before the managed section. If your tokenizer set a padding / truncation strategy before,
|
||||
then it will be reset to no padding/truncation when exiting the managed section.
|
||||
|
||||
:param tokenizer:
|
||||
:param max_length:
|
||||
:param stride:
|
||||
:param strategy:
|
||||
:param pad_to_max_length:
|
||||
:param padding_side:
|
||||
:param pad_token_id:
|
||||
:param pad_token_type_id:
|
||||
:param pad_token:
|
||||
:return:
|
||||
"""
|
||||
|
||||
# Handle all the truncation and padding stuff
|
||||
if max_length is not None:
|
||||
tokenizer.enable_truncation(max_length, stride=stride, strategy=strategy)
|
||||
|
||||
if pad_to_max_length and (pad_token and pad_token_id >= 0):
|
||||
tokenizer.enable_padding(
|
||||
max_length=None,
|
||||
direction=padding_side,
|
||||
pad_id=pad_token_id,
|
||||
pad_type_id=pad_token_type_id,
|
||||
pad_token=pad_token,
|
||||
)
|
||||
else:
|
||||
logger.warning(
|
||||
"Disabled padding because no padding token set (pad_token: {}, pad_token_id: {}).\n"
|
||||
"To remove this error, you can add a new pad token and then resize model embedding:\n"
|
||||
"\ttokenizer.pad_token = '<PAD>'\n\tmodel.resize_token_embeddings(len(tokenizer))".format(
|
||||
pad_token, pad_token_id
|
||||
)
|
||||
)
|
||||
|
||||
yield
|
||||
|
||||
if max_length is not None:
|
||||
tokenizer.no_truncation()
|
||||
|
||||
if pad_to_max_length and (pad_token and pad_token_id >= 0):
|
||||
tokenizer.no_padding()
|
||||
|
||||
|
||||
class PreTrainedTokenizer(object):
|
||||
""" Base class for all tokenizers.
|
||||
Handle all the shared methods for tokenization and special tokens as well as methods downloading/caching/loading pretrained tokenizers as well as adding tokens to the vocabulary.
|
||||
@@ -608,7 +542,7 @@ class PreTrainedTokenizer(object):
|
||||
vocabulary, they are added to it with indices starting from length of the current vocabulary.
|
||||
|
||||
Args:
|
||||
new_tokens: string or list of string. Each string is a token to add. Tokens are only added if they are not already in the vocabulary (tested by checking if the tokenizer assign the index of the ``unk_token`` to them).
|
||||
new_tokens: list of string. Each string is a token to add. Tokens are only added if they are not already in the vocabulary (tested by checking if the tokenizer assign the index of the ``unk_token`` to them).
|
||||
|
||||
Returns:
|
||||
Number of tokens added to the vocabulary.
|
||||
@@ -626,9 +560,6 @@ class PreTrainedTokenizer(object):
|
||||
if not new_tokens:
|
||||
return 0
|
||||
|
||||
if not isinstance(new_tokens, list):
|
||||
new_tokens = [new_tokens]
|
||||
|
||||
to_add_tokens = []
|
||||
for token in new_tokens:
|
||||
assert isinstance(token, str)
|
||||
@@ -906,7 +837,6 @@ class PreTrainedTokenizer(object):
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
"""
|
||||
@@ -946,9 +876,6 @@ class PreTrainedTokenizer(object):
|
||||
return_attention_mask: (optional) Set to False to avoid returning attention mask (default True)
|
||||
return_overflowing_tokens: (optional) Set to True to return overflowing token information (default False).
|
||||
return_special_tokens_mask: (optional) Set to True to return special tokens mask information (default False).
|
||||
return_offsets_mapping: (optional) Set to True to return (char_start, char_end) for each token (default False).
|
||||
If using Python's tokenizer, this method will raise NotImplementedError. This one is only available on
|
||||
Rust-based tokenizers inheriting from PreTrainedTokenizerFast.
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
|
||||
Return:
|
||||
@@ -986,15 +913,6 @@ class PreTrainedTokenizer(object):
|
||||
"Input is not valid. Should be a string, a list/tuple of strings or a list/tuple of integers."
|
||||
)
|
||||
|
||||
if return_offsets_mapping:
|
||||
raise NotImplementedError(
|
||||
"return_offset_mapping is not available when using Python tokenizers."
|
||||
"To use this feature, change your tokenizer to one deriving from "
|
||||
"transformers.PreTrainedTokenizerFast."
|
||||
"More information on available tokenizers at "
|
||||
"https://github.com/huggingface/transformers/pull/2674"
|
||||
)
|
||||
|
||||
first_ids = get_input_ids(text)
|
||||
second_ids = get_input_ids(text_pair) if text_pair is not None else None
|
||||
|
||||
@@ -1023,7 +941,6 @@ class PreTrainedTokenizer(object):
|
||||
return_tensors=None,
|
||||
return_input_lengths=False,
|
||||
return_attention_masks=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
"""
|
||||
@@ -1048,21 +965,8 @@ class PreTrainedTokenizer(object):
|
||||
- 'do_not_truncate': Does not truncate (raise an error if the input sequence is longer than max_length)
|
||||
return_tensors: (optional) can be set to 'tf' or 'pt' to return respectively TensorFlow tf.constant
|
||||
or PyTorch torch.Tensor instead of a list of python integers.
|
||||
return_input_lengths: (optional) If set the resulting dictionary will include the length of each sample
|
||||
return_attention_masks: (optional) Set to True to return the attention mask (default False)
|
||||
return_offsets_mapping: (optional) Not available, should be set to False or it will throw NotImplementError
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
"""
|
||||
|
||||
if return_offsets_mapping:
|
||||
raise NotImplementedError(
|
||||
"return_offset_mapping is not available when using Python tokenizers."
|
||||
"To use this feature, change your tokenizer to one deriving from "
|
||||
"transformers.PreTrainedTokenizerFast."
|
||||
"More information on available tokenizers at "
|
||||
"https://github.com/huggingface/transformers/pull/2674"
|
||||
)
|
||||
|
||||
batch_outputs = {}
|
||||
for ids_or_pair_ids in batch_text_or_text_pairs:
|
||||
if isinstance(ids_or_pair_ids, (list, tuple)):
|
||||
@@ -1526,29 +1430,30 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
|
||||
class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
def __init__(self, tokenizer: BaseTokenizer, **kwargs):
|
||||
if tokenizer is None:
|
||||
raise ValueError("Provided tokenizer cannot be None")
|
||||
self._tokenizer = tokenizer
|
||||
_tokenizer = None
|
||||
_decoder = None
|
||||
|
||||
def __init__(self, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.max_len_single_sentence = self.max_len - self.num_added_tokens(False) # take into account special tokens
|
||||
self.max_len_sentences_pair = self.max_len - self.num_added_tokens(True) # take into account special tokens
|
||||
|
||||
@property
|
||||
def tokenizer(self):
|
||||
if self._tokenizer is None:
|
||||
raise NotImplementedError
|
||||
return self._tokenizer
|
||||
|
||||
@property
|
||||
def decoder(self):
|
||||
return self._tokenizer._tokenizer.decoder
|
||||
if self._decoder is None:
|
||||
raise NotImplementedError
|
||||
return self._decoder
|
||||
|
||||
@property
|
||||
def vocab_size(self):
|
||||
return self._tokenizer.get_vocab_size(with_added_tokens=False)
|
||||
return self.tokenizer.get_vocab_size(with_added_tokens=False)
|
||||
|
||||
def __len__(self):
|
||||
return self._tokenizer.get_vocab_size(with_added_tokens=True)
|
||||
return self.tokenizer.get_vocab_size(with_added_tokens=True)
|
||||
|
||||
@PreTrainedTokenizer.bos_token.setter
|
||||
def bos_token(self, value):
|
||||
@@ -1602,42 +1507,36 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
):
|
||||
if return_overflowing_tokens and encoding.overflowing is not None:
|
||||
encodings = [encoding] + encoding.overflowing
|
||||
else:
|
||||
encodings = [encoding]
|
||||
|
||||
encoding_dict = defaultdict(list)
|
||||
for e in encodings:
|
||||
encoding_dict["input_ids"].append(e.ids)
|
||||
|
||||
if return_token_type_ids:
|
||||
encoding_dict["token_type_ids"].append(e.type_ids)
|
||||
if return_attention_mask:
|
||||
encoding_dict["attention_mask"].append(e.attention_mask)
|
||||
if return_special_tokens_mask:
|
||||
encoding_dict["special_tokens_mask"].append(e.special_tokens_mask)
|
||||
if return_offsets_mapping:
|
||||
encoding_dict["offset_mapping"].append([e.original_str.offsets(o) for o in e.offsets])
|
||||
encoding_dict = {
|
||||
"input_ids": encoding.ids,
|
||||
}
|
||||
if return_token_type_ids:
|
||||
encoding_dict["token_type_ids"] = encoding.type_ids
|
||||
if return_attention_mask:
|
||||
encoding_dict["attention_mask"] = encoding.attention_mask
|
||||
if return_overflowing_tokens:
|
||||
overflowing = encoding.overflowing
|
||||
encoding_dict["overflowing_tokens"] = overflowing.ids if overflowing is not None else []
|
||||
if return_special_tokens_mask:
|
||||
encoding_dict["special_tokens_mask"] = encoding.special_tokens_mask
|
||||
|
||||
# Prepare inputs as tensors if asked
|
||||
if return_tensors == "tf" and is_tf_available():
|
||||
encoding_dict["input_ids"] = tf.constant(encoding_dict["input_ids"])
|
||||
encoding_dict["input_ids"] = tf.constant([encoding_dict["input_ids"]])
|
||||
if "token_type_ids" in encoding_dict:
|
||||
encoding_dict["token_type_ids"] = tf.constant(encoding_dict["token_type_ids"])
|
||||
encoding_dict["token_type_ids"] = tf.constant([encoding_dict["token_type_ids"]])
|
||||
|
||||
if "attention_mask" in encoding_dict:
|
||||
encoding_dict["attention_mask"] = tf.constant(encoding_dict["attention_mask"])
|
||||
encoding_dict["attention_mask"] = tf.constant([encoding_dict["attention_mask"]])
|
||||
|
||||
elif return_tensors == "pt" and is_torch_available():
|
||||
encoding_dict["input_ids"] = torch.tensor(encoding_dict["input_ids"])
|
||||
encoding_dict["input_ids"] = torch.tensor([encoding_dict["input_ids"]])
|
||||
if "token_type_ids" in encoding_dict:
|
||||
encoding_dict["token_type_ids"] = torch.tensor(encoding_dict["token_type_ids"])
|
||||
encoding_dict["token_type_ids"] = torch.tensor([encoding_dict["token_type_ids"]])
|
||||
|
||||
if "attention_mask" in encoding_dict:
|
||||
encoding_dict["attention_mask"] = torch.tensor(encoding_dict["attention_mask"])
|
||||
encoding_dict["attention_mask"] = torch.tensor([encoding_dict["attention_mask"]])
|
||||
elif return_tensors is not None:
|
||||
logger.warning(
|
||||
"Unable to convert output to tensors format {}, PyTorch or TensorFlow is not available.".format(
|
||||
@@ -1647,161 +1546,71 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
|
||||
return encoding_dict
|
||||
|
||||
def encode_plus(
|
||||
self,
|
||||
text,
|
||||
text_pair=None,
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
**kwargs
|
||||
):
|
||||
encoding = self.tokenizer.encode(text, text_pair)
|
||||
return self._convert_encoding(
|
||||
encoding,
|
||||
return_tensors=return_tensors,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_attention_mask=return_attention_mask,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_mask,
|
||||
)
|
||||
|
||||
def tokenize(self, text):
|
||||
return self.tokenizer.encode(text).tokens
|
||||
|
||||
def _convert_token_to_id_with_added_voc(self, token):
|
||||
id = self._tokenizer.token_to_id(token)
|
||||
id = self.tokenizer.token_to_id(token)
|
||||
if id is None:
|
||||
return self.unk_token_id
|
||||
return id
|
||||
|
||||
def _convert_id_to_token(self, index):
|
||||
return self._tokenizer.id_to_token(int(index))
|
||||
return self.tokenizer.id_to_token(int(index))
|
||||
|
||||
def convert_tokens_to_string(self, tokens):
|
||||
return self._tokenizer.decode(tokens)
|
||||
return self.decoder.decode(tokens)
|
||||
|
||||
def add_tokens(self, new_tokens):
|
||||
if isinstance(new_tokens, str):
|
||||
new_tokens = [new_tokens]
|
||||
return self._tokenizer.add_tokens(new_tokens)
|
||||
self.tokenizer.add_tokens(new_tokens)
|
||||
|
||||
def add_special_tokens(self, special_tokens_dict):
|
||||
added = super().add_special_tokens(special_tokens_dict)
|
||||
self._update_special_tokens()
|
||||
return added
|
||||
|
||||
def num_added_tokens(self, pair=False):
|
||||
return self.tokenizer.num_special_tokens_to_add(pair)
|
||||
|
||||
def tokenize(self, text, **kwargs):
|
||||
return self.tokenizer.encode(text).tokens
|
||||
|
||||
def batch_encode_plus(
|
||||
def encode_batch(
|
||||
self,
|
||||
batch_text_or_text_pairs=None,
|
||||
add_special_tokens=True,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
pad_to_max_length=False,
|
||||
texts,
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
# Needed if we have to return a tensor
|
||||
pad_to_max_length = pad_to_max_length or (return_tensors is not None)
|
||||
|
||||
# Throw an error if we can pad because there is no padding token
|
||||
if pad_to_max_length and self.pad_token_id is None:
|
||||
raise ValueError("Unable to set proper padding strategy as the tokenizer does have padding token")
|
||||
|
||||
# Set the truncation and padding strategy and restore the initial configuration
|
||||
with truncate_and_pad(
|
||||
tokenizer=self._tokenizer,
|
||||
max_length=max_length,
|
||||
stride=stride,
|
||||
strategy=truncation_strategy,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
padding_side=self.padding_side,
|
||||
pad_token_id=self.pad_token_id,
|
||||
pad_token_type_id=self.pad_token_type_id,
|
||||
pad_token=self._pad_token,
|
||||
):
|
||||
|
||||
if not isinstance(batch_text_or_text_pairs, list):
|
||||
raise TypeError(
|
||||
"batch_text_or_text_pairs has to be a list (got {})".format(type(batch_text_or_text_pairs))
|
||||
)
|
||||
|
||||
# Avoid thread overhead if only one example.
|
||||
if len(batch_text_or_text_pairs) == 1:
|
||||
if isinstance(batch_text_or_text_pairs[0], (tuple, list)):
|
||||
tokens = self._tokenizer.encode(*batch_text_or_text_pairs[0])
|
||||
else:
|
||||
tokens = self._tokenizer.encode(batch_text_or_text_pairs[0])
|
||||
tokens = [tokens]
|
||||
else:
|
||||
tokens = self._tokenizer.encode_batch(batch_text_or_text_pairs)
|
||||
|
||||
# Convert encoding to dict
|
||||
tokens = [
|
||||
return [
|
||||
self._convert_encoding(
|
||||
encoding=encoding,
|
||||
encoding,
|
||||
return_tensors=return_tensors,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_attention_mask=return_attention_mask,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_mask,
|
||||
return_offsets_mapping=return_offsets_mapping,
|
||||
)
|
||||
for encoding in tokens
|
||||
for encoding in self.tokenizer.encode_batch(texts)
|
||||
]
|
||||
|
||||
# Sanitize the output to have dict[list] from list[dict]
|
||||
sanitized = {}
|
||||
for key in tokens[0].keys():
|
||||
stack = [e for item in tokens for e in item[key]]
|
||||
if return_tensors == "tf":
|
||||
stack = tf.stack(stack, axis=0)
|
||||
elif return_tensors == "pt":
|
||||
stack = torch.stack(stack, dim=0)
|
||||
elif not return_tensors and len(stack) == 1:
|
||||
stack = stack[0]
|
||||
|
||||
sanitized[key] = stack
|
||||
|
||||
# If returning overflowing tokens, we need to return a mapping
|
||||
# from the batch idx to the original sample
|
||||
if return_overflowing_tokens:
|
||||
overflow_to_sample_mapping = [
|
||||
i if len(item["input_ids"]) == 1 else [i] * len(item["input_ids"]) for i, item in enumerate(tokens)
|
||||
]
|
||||
sanitized["overflow_to_sample_mapping"] = overflow_to_sample_mapping
|
||||
return sanitized
|
||||
|
||||
def encode_plus(
|
||||
self,
|
||||
text,
|
||||
text_pair=None,
|
||||
add_special_tokens=False,
|
||||
max_length=None,
|
||||
pad_to_max_length=False,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
return_tensors=None,
|
||||
return_token_type_ids=True,
|
||||
return_attention_mask=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_mask=False,
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
batched_input = [(text, text_pair)] if text_pair else [text]
|
||||
batched_output = self.batch_encode_plus(
|
||||
batched_input,
|
||||
add_special_tokens=add_special_tokens,
|
||||
max_length=max_length,
|
||||
stride=stride,
|
||||
truncation_strategy=truncation_strategy,
|
||||
return_tensors=return_tensors,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_attention_mask=return_attention_mask,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_mask,
|
||||
return_offsets_mapping=return_offsets_mapping,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
# Return tensor is None, then we can remove the leading batch axis
|
||||
if not return_tensors:
|
||||
return {key: value[0] if isinstance(value[0], list) else value for key, value in batched_output.items()}
|
||||
else:
|
||||
return batched_output
|
||||
|
||||
def decode(self, token_ids, skip_special_tokens=False, clean_up_tokenization_spaces=True):
|
||||
text = self.tokenizer.decode(token_ids, skip_special_tokens)
|
||||
|
||||
@@ -1811,9 +1620,8 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
else:
|
||||
return text
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
if os.path.isdir(save_directory):
|
||||
folder, file = save_directory, self.vocab_files_names["vocab_file"]
|
||||
else:
|
||||
folder, file = os.path.split(os.path.abspath(save_directory))
|
||||
self._tokenizer.save(folder, file)
|
||||
def decode_batch(self, ids_batch, skip_special_tokens=False, clear_up_tokenization_spaces=True):
|
||||
return [
|
||||
self.clean_up_tokenization(text) if clear_up_tokenization_spaces else text
|
||||
for text in self.tokenizer.decode_batch(ids_batch, skip_special_tokens)
|
||||
]
|
||||
+16
-17
@@ -7,17 +7,17 @@ from transformers.pipelines import Pipeline
|
||||
from .utils import require_tf, require_torch
|
||||
|
||||
|
||||
QA_FINETUNED_MODELS = [
|
||||
(("bert-base-uncased", {"use_fast": False}), "bert-large-uncased-whole-word-masking-finetuned-squad", None),
|
||||
(("bert-base-cased", {"use_fast": False}), "bert-large-cased-whole-word-masking-finetuned-squad", None),
|
||||
(("bert-base-cased", {"use_fast": False}), "distilbert-base-cased-distilled-squad", None),
|
||||
]
|
||||
QA_FINETUNED_MODELS = {
|
||||
("bert-base-uncased", "bert-large-uncased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-cased", "bert-large-cased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-cased", "distilbert-base-cased-distilled-squad", None),
|
||||
}
|
||||
|
||||
TF_QA_FINETUNED_MODELS = [
|
||||
(("bert-base-uncased", {"use_fast": False}), "bert-large-uncased-whole-word-masking-finetuned-squad", None),
|
||||
(("bert-base-cased", {"use_fast": False}), "bert-large-cased-whole-word-masking-finetuned-squad", None),
|
||||
(("bert-base-cased", {"use_fast": False}), "distilbert-base-cased-distilled-squad", None),
|
||||
]
|
||||
TF_QA_FINETUNED_MODELS = {
|
||||
("bert-base-uncased", "bert-large-uncased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-cased", "bert-large-cased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-cased", "distilbert-base-cased-distilled-squad", None),
|
||||
}
|
||||
|
||||
TF_NER_FINETUNED_MODELS = {
|
||||
(
|
||||
@@ -63,13 +63,13 @@ TEXT_CLASSIF_FINETUNED_MODELS = {
|
||||
)
|
||||
}
|
||||
|
||||
FILL_MASK_FINETUNED_MODELS = [
|
||||
(("distilroberta-base", {"use_fast": False}), "distilroberta-base", None),
|
||||
]
|
||||
FILL_MASK_FINETUNED_MODELS = {
|
||||
("distilroberta-base", "distilroberta-base", None),
|
||||
}
|
||||
|
||||
TF_FILL_MASK_FINETUNED_MODELS = [
|
||||
(("distilroberta-base", {"use_fast": False}), "distilroberta-base", None),
|
||||
]
|
||||
TF_FILL_MASK_FINETUNED_MODELS = {
|
||||
("distilroberta-base", "distilroberta-base", None),
|
||||
}
|
||||
|
||||
|
||||
class MonoColumnInputTestCase(unittest.TestCase):
|
||||
@@ -284,7 +284,6 @@ class MultiColumnInputTestCase(unittest.TestCase):
|
||||
self._test_multicolumn_pipeline(nlp, valid_samples, invalid_samples, mandatory_output_keys)
|
||||
|
||||
@require_tf
|
||||
@unittest.skip("This test is failing intermittently. Skipping it until we resolve.")
|
||||
def test_tf_question_answering(self):
|
||||
mandatory_output_keys = {"score", "answer", "start", "end"}
|
||||
valid_samples = [
|
||||
|
||||
@@ -22,11 +22,8 @@ from transformers import (
|
||||
GPT2_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
AutoTokenizer,
|
||||
BertTokenizer,
|
||||
BertTokenizerFast,
|
||||
GPT2Tokenizer,
|
||||
GPT2TokenizerFast,
|
||||
RobertaTokenizer,
|
||||
RobertaTokenizerFast,
|
||||
)
|
||||
from transformers.tokenization_auto import TOKENIZER_MAPPING
|
||||
|
||||
@@ -40,43 +37,38 @@ class AutoTokenizerTest(unittest.TestCase):
|
||||
for model_name in (x for x in BERT_PRETRAINED_CONFIG_ARCHIVE_MAP.keys() if "japanese" not in x):
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
self.assertIsNotNone(tokenizer)
|
||||
self.assertIsInstance(tokenizer, (BertTokenizer, BertTokenizerFast))
|
||||
self.assertIsInstance(tokenizer, BertTokenizer)
|
||||
self.assertGreater(len(tokenizer), 0)
|
||||
|
||||
for model_name in GPT2_PRETRAINED_CONFIG_ARCHIVE_MAP.keys():
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
self.assertIsNotNone(tokenizer)
|
||||
self.assertIsInstance(tokenizer, (GPT2Tokenizer, GPT2TokenizerFast))
|
||||
self.assertIsInstance(tokenizer, GPT2Tokenizer)
|
||||
self.assertGreater(len(tokenizer), 0)
|
||||
|
||||
def test_tokenizer_from_pretrained_identifier(self):
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
tokenizer = AutoTokenizer.from_pretrained(SMALL_MODEL_IDENTIFIER)
|
||||
self.assertIsInstance(tokenizer, (BertTokenizer, BertTokenizerFast))
|
||||
self.assertEqual(tokenizer.vocab_size, 12)
|
||||
self.assertIsInstance(tokenizer, BertTokenizer)
|
||||
self.assertEqual(len(tokenizer), 12)
|
||||
|
||||
def test_tokenizer_from_model_type(self):
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
tokenizer = AutoTokenizer.from_pretrained(DUMMY_UNKWOWN_IDENTIFIER)
|
||||
self.assertIsInstance(tokenizer, (RobertaTokenizer, RobertaTokenizerFast))
|
||||
self.assertEqual(tokenizer.vocab_size, 20)
|
||||
self.assertIsInstance(tokenizer, RobertaTokenizer)
|
||||
self.assertEqual(len(tokenizer), 20)
|
||||
|
||||
def test_tokenizer_identifier_with_correct_config(self):
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
for tokenizer_class in [BertTokenizer, BertTokenizerFast, AutoTokenizer]:
|
||||
for tokenizer_class in [BertTokenizer, AutoTokenizer]:
|
||||
tokenizer = tokenizer_class.from_pretrained("wietsedv/bert-base-dutch-cased")
|
||||
self.assertIsInstance(tokenizer, (BertTokenizer, BertTokenizerFast))
|
||||
|
||||
if isinstance(tokenizer, BertTokenizer):
|
||||
self.assertEqual(tokenizer.basic_tokenizer.do_lower_case, False)
|
||||
else:
|
||||
self.assertEqual(tokenizer.do_lower_case, False)
|
||||
|
||||
self.assertIsInstance(tokenizer, BertTokenizer)
|
||||
self.assertEqual(tokenizer.basic_tokenizer.do_lower_case, False)
|
||||
self.assertEqual(tokenizer.max_len, 512)
|
||||
|
||||
def test_tokenizer_identifier_non_existent(self):
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
for tokenizer_class in [BertTokenizer, BertTokenizerFast, AutoTokenizer]:
|
||||
for tokenizer_class in [BertTokenizer, AutoTokenizer]:
|
||||
with self.assertRaises(EnvironmentError):
|
||||
_ = tokenizer_class.from_pretrained("julien-c/herlolip-not-exists")
|
||||
|
||||
@@ -88,18 +80,10 @@ class AutoTokenizerTest(unittest.TestCase):
|
||||
|
||||
for mapping in mappings:
|
||||
mapping = tuple(mapping.items())
|
||||
for index, (child_config, (child_model_py, child_model_fast)) in enumerate(mapping[1:]):
|
||||
for parent_config, (parent_model_py, parent_model_fast) in mapping[: index + 1]:
|
||||
for index, (child_config, child_model) in enumerate(mapping[1:]):
|
||||
for parent_config, parent_model in mapping[: index + 1]:
|
||||
with self.subTest(
|
||||
msg="Testing if {} is child of {}".format(child_config.__name__, parent_config.__name__)
|
||||
):
|
||||
self.assertFalse(issubclass(child_config, parent_config))
|
||||
self.assertFalse(issubclass(child_model_py, parent_model_py))
|
||||
|
||||
# Check for Fast tokenizer implementation if provided
|
||||
if child_model_fast and parent_model_fast:
|
||||
self.assertFalse(issubclass(child_model_fast, parent_model_fast))
|
||||
|
||||
def test_from_pretrained_use_fast_toggle(self):
|
||||
self.assertIsInstance(AutoTokenizer.from_pretrained("bert-base-cased"), BertTokenizerFast)
|
||||
self.assertIsInstance(AutoTokenizer.from_pretrained("bert-base-cased", use_fast=False), BertTokenizer)
|
||||
self.assertFalse(issubclass(child_model, parent_model))
|
||||
@@ -1,371 +0,0 @@
|
||||
import unittest
|
||||
|
||||
import numpy as np
|
||||
|
||||
from tests.utils import require_torch
|
||||
from transformers import (
|
||||
BertTokenizer,
|
||||
BertTokenizerFast,
|
||||
DistilBertTokenizer,
|
||||
GPT2Tokenizer,
|
||||
GPT2TokenizerFast,
|
||||
OpenAIGPTTokenizer,
|
||||
PreTrainedTokenizer,
|
||||
RobertaTokenizer,
|
||||
TransfoXLTokenizer,
|
||||
is_torch_available,
|
||||
)
|
||||
from transformers.tokenization_distilbert import DistilBertTokenizerFast
|
||||
from transformers.tokenization_openai import OpenAIGPTTokenizerFast
|
||||
from transformers.tokenization_roberta import RobertaTokenizerFast
|
||||
from transformers.tokenization_transfo_xl import TransfoXLTokenizerFast
|
||||
|
||||
|
||||
class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
with open("tests/fixtures/sample_text.txt") as f_data:
|
||||
self._data = f_data.read().replace("\n\n", "\n").strip()
|
||||
|
||||
def assert_sequence_almost_equals(self, a, b, threshold):
|
||||
|
||||
# Handle padding
|
||||
if len(a) != len(b):
|
||||
max_len = max(len(a), len(b))
|
||||
|
||||
# Pad with a negative number as vocab doesnt allow idx < 0
|
||||
# if will be tracked as differences
|
||||
if len(a) < max_len:
|
||||
a += [-1] * (max_len - len(a))
|
||||
|
||||
if len(b) < max_len:
|
||||
b += [-1] * (max_len - len(b))
|
||||
|
||||
# Convert to numpy for convenience
|
||||
a_, b_ = np.array(a), np.array(b)
|
||||
|
||||
# Compute elementwise difference
|
||||
inputs_diffs = a_ - b_
|
||||
inputs_diff = np.count_nonzero(inputs_diffs)
|
||||
self.assertLessEqual(inputs_diff / a_.shape[0], threshold)
|
||||
|
||||
def assert_tokenization_python_rust_almost_equals(self, tokenizer_p, tokenizer_r, threshold: float):
|
||||
# Ensure basic input match
|
||||
input_p = tokenizer_p.encode_plus(self._data)
|
||||
input_r = tokenizer_r.encode_plus(self._data)
|
||||
|
||||
for key in filter(lambda x: x in ["input_ids", "token_type_ids", "attention_mask"], input_p.keys()):
|
||||
self.assert_sequence_almost_equals(input_p[key], input_r[key], threshold)
|
||||
|
||||
input_pairs_p = tokenizer_p.encode_plus(self._data, self._data)
|
||||
input_pairs_r = tokenizer_r.encode_plus(self._data, self._data)
|
||||
|
||||
for key in filter(lambda x: x in ["input_ids", "token_type_ids", "attention_mask"], input_p.keys()):
|
||||
self.assert_sequence_almost_equals(input_pairs_p[key], input_pairs_r[key], threshold)
|
||||
|
||||
# Ensure truncation match
|
||||
input_p = tokenizer_p.encode_plus(self._data, max_length=512)
|
||||
input_r = tokenizer_r.encode_plus(self._data, max_length=512)
|
||||
|
||||
for key in filter(lambda x: x in ["input_ids", "token_type_ids", "attention_mask"], input_p.keys()):
|
||||
self.assert_sequence_almost_equals(input_p[key], input_r[key], threshold)
|
||||
|
||||
# Ensure truncation with stride match
|
||||
input_p = tokenizer_p.encode_plus(self._data, max_length=512, stride=3, return_overflowing_tokens=True)
|
||||
input_r = tokenizer_r.encode_plus(self._data, max_length=512, stride=3, return_overflowing_tokens=True)
|
||||
|
||||
for key in filter(lambda x: x in ["input_ids", "token_type_ids", "attention_mask"], input_p.keys()):
|
||||
self.assert_sequence_almost_equals(input_p[key], input_r[key], threshold)
|
||||
|
||||
def assert_add_tokens(self, tokenizer_r):
|
||||
vocab_size = tokenizer_r.vocab_size
|
||||
self.assertEqual(tokenizer_r.add_tokens(""), 0)
|
||||
self.assertEqual(tokenizer_r.add_tokens("testoken"), 1)
|
||||
self.assertEqual(tokenizer_r.add_tokens(["testoken1", "testtoken2"]), 2)
|
||||
self.assertEqual(len(tokenizer_r), vocab_size + 3)
|
||||
|
||||
self.assertEqual(tokenizer_r.add_special_tokens({}), 0)
|
||||
self.assertRaises(
|
||||
AssertionError, tokenizer_r.add_special_tokens, {"additional_special_tokens": "<testtoken1>"}
|
||||
)
|
||||
self.assertEqual(tokenizer_r.add_special_tokens({"additional_special_tokens": ["<testtoken2>"]}), 1)
|
||||
self.assertEqual(
|
||||
tokenizer_r.add_special_tokens({"additional_special_tokens": ["<testtoken3>", "<testtoken4>"]}), 2
|
||||
)
|
||||
self.assertEqual(len(tokenizer_r), vocab_size + 6)
|
||||
|
||||
def assert_offsets_mapping(self, tokenizer):
|
||||
text = "Wonderful no inspiration example with subtoken"
|
||||
pair = "Along with an awesome pair"
|
||||
|
||||
# No pair
|
||||
tokens_with_offsets = tokenizer.encode_plus(text, return_special_tokens_mask=True, return_offsets_mapping=True)
|
||||
added_tokens = tokenizer.num_added_tokens(False)
|
||||
offsets = tokens_with_offsets["offset_mapping"]
|
||||
|
||||
# Assert there is the same number of tokens and offsets
|
||||
self.assertEqual(len(offsets), len(tokens_with_offsets["input_ids"]))
|
||||
|
||||
# Assert there is online added_tokens special_tokens
|
||||
self.assertEqual(sum([0 if x else 1 for x in offsets]), added_tokens)
|
||||
self.assertEqual(sum(tokens_with_offsets["special_tokens_mask"]), added_tokens)
|
||||
|
||||
# Pairs
|
||||
tokens_with_offsets = tokenizer.encode_plus(
|
||||
text, pair, return_special_tokens_mask=True, return_offsets_mapping=True
|
||||
)
|
||||
added_tokens = tokenizer.num_added_tokens(True)
|
||||
offsets = tokens_with_offsets["offset_mapping"]
|
||||
|
||||
# Assert there is the same number of tokens and offsets
|
||||
self.assertEqual(len(offsets), len(tokens_with_offsets["input_ids"]))
|
||||
|
||||
# Assert there is online added_tokens special_tokens
|
||||
self.assertEqual(sum([0 if x else 1 for x in offsets]), added_tokens)
|
||||
self.assertEqual(sum(tokens_with_offsets["special_tokens_mask"]), added_tokens)
|
||||
|
||||
def assert_batch_encode_dynamic_overflowing(self, tokenizer: PreTrainedTokenizer):
|
||||
"""
|
||||
When calling batch_encode with multiple sequence it can returns different number of
|
||||
overflowing encoding for each sequence:
|
||||
[
|
||||
Sequence 1: [Encoding 1, Encoding 2],
|
||||
Sequence 2: [Encoding 1],
|
||||
Sequence 3: [Encoding 1, Encoding 2, ... Encoding N]
|
||||
]
|
||||
This needs to be padded so that it can represented as a tensor
|
||||
"""
|
||||
returned_tensor = "pt" if is_torch_available() else "tf"
|
||||
|
||||
tokens = tokenizer.encode_plus(
|
||||
"HuggingFace is solving NLP one commit at a time",
|
||||
max_length=6,
|
||||
return_tensors=returned_tensor,
|
||||
return_overflowing_tokens=True,
|
||||
)
|
||||
|
||||
for key in filter(lambda x: "overflow_to_sample_mapping" not in x, tokens.keys()):
|
||||
self.assertEqual(len(tokens[key].shape), 2)
|
||||
|
||||
# Mono sample
|
||||
tokens = tokenizer.batch_encode_plus(
|
||||
["HuggingFace is solving NLP one commit at a time"],
|
||||
max_length=6,
|
||||
pad_to_max_len=True,
|
||||
return_tensors=returned_tensor,
|
||||
return_overflowing_tokens=True,
|
||||
)
|
||||
|
||||
for key in filter(lambda x: "overflow_to_sample_mapping" not in x, tokens.keys()):
|
||||
self.assertEqual(len(tokens[key].shape), 2)
|
||||
self.assertEqual(tokens[key].shape[-1], 6)
|
||||
|
||||
# Multi sample
|
||||
tokens = tokenizer.batch_encode_plus(
|
||||
["HuggingFace is solving NLP one commit at a time", "Very tiny input"],
|
||||
max_length=6,
|
||||
pad_to_max_len=True,
|
||||
return_tensors=returned_tensor,
|
||||
return_overflowing_tokens=True,
|
||||
)
|
||||
|
||||
for key in filter(lambda x: "overflow_to_sample_mapping" not in x, tokens.keys()):
|
||||
self.assertEqual(len(tokens[key].shape), 2)
|
||||
self.assertEqual(tokens[key].shape[-1], 6)
|
||||
|
||||
def test_bert(self):
|
||||
for tokenizer_name in BertTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = BertTokenizer.from_pretrained(tokenizer_name)
|
||||
tokenizer_r = BertTokenizerFast.from_pretrained(tokenizer_name)
|
||||
|
||||
# Check we have the same number of added_tokens for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(False), tokenizer_p.num_added_tokens(False))
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(True), tokenizer_p.num_added_tokens(True))
|
||||
|
||||
# Check we have the correct max_length for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.max_len_single_sentence, tokenizer_p.max_len_single_sentence)
|
||||
self.assertEqual(tokenizer_r.max_len_sentences_pair, tokenizer_p.max_len_sentences_pair)
|
||||
|
||||
# Assert the set of special tokens match.
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_p.special_tokens_map.items(),
|
||||
tokenizer_r.special_tokens_map.items(),
|
||||
"Bert tokenizers doesn't have the same set of special_tokens",
|
||||
)
|
||||
|
||||
# Assure tokenization overlap between python and rust impl.
|
||||
self.assert_tokenization_python_rust_almost_equals(tokenizer_p, tokenizer_r, 0.0)
|
||||
|
||||
# Ensure add_tokens and add_special_tokens return the correct vocab size
|
||||
self.assert_add_tokens(tokenizer_r)
|
||||
|
||||
# Check for offsets mapping
|
||||
self.assert_offsets_mapping(tokenizer_r)
|
||||
|
||||
# Check for dynamic encoding sequence handling in batch_encode_plus
|
||||
self.assert_batch_encode_dynamic_overflowing(tokenizer_r)
|
||||
|
||||
@require_torch
|
||||
def test_transfoxl(self):
|
||||
for tokenizer_name in TransfoXLTokenizer.pretrained_vocab_files_map["pretrained_vocab_file"].keys():
|
||||
tokenizer_p = TransfoXLTokenizer.from_pretrained(tokenizer_name)
|
||||
tokenizer_r = TransfoXLTokenizerFast.from_pretrained(tokenizer_name)
|
||||
|
||||
# Check we have the same number of added_tokens for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(False), tokenizer_p.num_added_tokens(False))
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(True), tokenizer_p.num_added_tokens(True))
|
||||
|
||||
# Check we have the correct max_length for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.max_len_single_sentence, tokenizer_p.max_len_single_sentence)
|
||||
self.assertEqual(tokenizer_r.max_len_sentences_pair, tokenizer_p.max_len_sentences_pair)
|
||||
|
||||
# Assert the set of special tokens match.
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_p.special_tokens_map.items(),
|
||||
tokenizer_r.special_tokens_map.items(),
|
||||
"TransfoXL tokenizers doesn't have the same set of special_tokens",
|
||||
)
|
||||
|
||||
# Assure tokenization overlap between python and rust impl.
|
||||
self.assert_tokenization_python_rust_almost_equals(tokenizer_p, tokenizer_r, 0.0)
|
||||
|
||||
# Ensure add_tokens and add_special_tokens return the correct vocab size
|
||||
self.assert_add_tokens(tokenizer_r)
|
||||
|
||||
# Check for offsets mapping
|
||||
self.assert_offsets_mapping(tokenizer_r)
|
||||
|
||||
# Check for dynamic encoding sequence handling in batch_encode_plus
|
||||
self.assertRaises(ValueError, self.assert_batch_encode_dynamic_overflowing, tokenizer_r)
|
||||
|
||||
def test_distilbert(self):
|
||||
for tokenizer_name in DistilBertTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = DistilBertTokenizer.from_pretrained(tokenizer_name)
|
||||
tokenizer_r = DistilBertTokenizerFast.from_pretrained(tokenizer_name)
|
||||
|
||||
# Check we have the same number of added_tokens for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(False), tokenizer_p.num_added_tokens(False))
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(True), tokenizer_p.num_added_tokens(True))
|
||||
|
||||
# Check we have the correct max_length for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.max_len_single_sentence, tokenizer_p.max_len_single_sentence)
|
||||
self.assertEqual(tokenizer_r.max_len_sentences_pair, tokenizer_p.max_len_sentences_pair)
|
||||
|
||||
# DistilBert should match 100%
|
||||
# Assert the set of special tokens match.
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_p.special_tokens_map.items(),
|
||||
tokenizer_r.special_tokens_map.items(),
|
||||
"DistilBert tokenizers doesn't have the same set of special_tokens",
|
||||
)
|
||||
|
||||
# Assure tokenization overlap between python and rust impl.
|
||||
self.assert_tokenization_python_rust_almost_equals(tokenizer_p, tokenizer_r, 0.0)
|
||||
|
||||
# Ensure add_tokens and add_special_tokens return the correct vocab size
|
||||
self.assert_add_tokens(tokenizer_r)
|
||||
|
||||
# Check for offsets mapping
|
||||
self.assert_offsets_mapping(tokenizer_r)
|
||||
|
||||
# Check for dynamic encoding sequence handling in batch_encode_plus
|
||||
self.assert_batch_encode_dynamic_overflowing(tokenizer_r)
|
||||
|
||||
def test_gpt2(self):
|
||||
for tokenizer_name in GPT2Tokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = GPT2Tokenizer.from_pretrained(tokenizer_name)
|
||||
tokenizer_r = GPT2TokenizerFast.from_pretrained(tokenizer_name)
|
||||
|
||||
# Check we have the same number of added_tokens for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(False), tokenizer_p.num_added_tokens(False))
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(True), tokenizer_p.num_added_tokens(True))
|
||||
|
||||
# Check we have the correct max_length for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.max_len_single_sentence, tokenizer_p.max_len_single_sentence)
|
||||
self.assertEqual(tokenizer_r.max_len_sentences_pair, tokenizer_p.max_len_sentences_pair)
|
||||
|
||||
# Assert the set of special tokens match.
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_p.special_tokens_map.items(),
|
||||
tokenizer_r.special_tokens_map.items(),
|
||||
"GPT2 tokenizers doesn't have the same set of special_tokens",
|
||||
)
|
||||
|
||||
# Assure tokenization overlap between python and rust impl.
|
||||
self.assert_tokenization_python_rust_almost_equals(tokenizer_p, tokenizer_r, 0.0)
|
||||
|
||||
# Ensure add_tokens and add_special_tokens return the correct vocab size
|
||||
self.assert_add_tokens(tokenizer_r)
|
||||
|
||||
# Check for offsets mapping
|
||||
self.assert_offsets_mapping(tokenizer_r)
|
||||
|
||||
# Check for dynamic encoding sequence handling in batch_encode_plus
|
||||
self.assertRaises(ValueError, self.assert_batch_encode_dynamic_overflowing, tokenizer_r)
|
||||
|
||||
def test_roberta(self):
|
||||
for tokenizer_name in RobertaTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = RobertaTokenizer.from_pretrained(tokenizer_name)
|
||||
tokenizer_r = RobertaTokenizerFast.from_pretrained(tokenizer_name)
|
||||
|
||||
# Check we have the same number of added_tokens for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(False), tokenizer_p.num_added_tokens(False))
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(True), tokenizer_p.num_added_tokens(True))
|
||||
|
||||
# Check we have the correct max_length for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.max_len_single_sentence, tokenizer_p.max_len_single_sentence)
|
||||
self.assertEqual(tokenizer_r.max_len_sentences_pair, tokenizer_p.max_len_sentences_pair)
|
||||
|
||||
# Assert the set of special tokens match.
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_p.special_tokens_map.items(),
|
||||
tokenizer_r.special_tokens_map.items(),
|
||||
"Roberta tokenizers doesn't have the same set of special_tokens",
|
||||
)
|
||||
|
||||
# Assure tokenization overlap between python and rust impl.
|
||||
self.assert_tokenization_python_rust_almost_equals(tokenizer_p, tokenizer_r, 0.01)
|
||||
|
||||
# Ensure add_tokens and add_special_tokens return the correct vocab size
|
||||
self.assert_add_tokens(tokenizer_r)
|
||||
|
||||
# Check for offsets mapping
|
||||
self.assert_offsets_mapping(tokenizer_r)
|
||||
|
||||
# Check for dynamic encoding sequence handling in batch_encode_plus
|
||||
self.assert_batch_encode_dynamic_overflowing(tokenizer_r)
|
||||
|
||||
def test_openai(self):
|
||||
for tokenizer_name in OpenAIGPTTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = OpenAIGPTTokenizer.from_pretrained(tokenizer_name)
|
||||
tokenizer_r = OpenAIGPTTokenizerFast.from_pretrained(tokenizer_name)
|
||||
|
||||
# Check we have the same number of added_tokens for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(False), tokenizer_p.num_added_tokens(False))
|
||||
self.assertEqual(tokenizer_r.num_added_tokens(True), tokenizer_p.num_added_tokens(True))
|
||||
|
||||
# Check we have the correct max_length for both pair and non-pair inputs.
|
||||
self.assertEqual(tokenizer_r.max_len_single_sentence, tokenizer_p.max_len_single_sentence)
|
||||
self.assertEqual(tokenizer_r.max_len_sentences_pair, tokenizer_p.max_len_sentences_pair)
|
||||
|
||||
# Assert the set of special tokens match.
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_p.special_tokens_map.items(),
|
||||
tokenizer_r.special_tokens_map.items(),
|
||||
"GPT tokenizers doesn't have the same set of special_tokens",
|
||||
)
|
||||
|
||||
# Assure tokenization overlap between python and rust impl.
|
||||
self.assert_tokenization_python_rust_almost_equals(tokenizer_p, tokenizer_r, 0.0)
|
||||
|
||||
# Ensure add_tokens and add_special_tokens return the correct vocab size
|
||||
self.assert_add_tokens(tokenizer_r)
|
||||
|
||||
# Check for offsets mapping
|
||||
self.assert_offsets_mapping(tokenizer_r)
|
||||
|
||||
# Check for dynamic encoding sequence handling in batch_encode_plus
|
||||
self.assertRaises(ValueError, self.assert_batch_encode_dynamic_overflowing, tokenizer_r)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
Reference in new issue
Block a user