Compare commits
77
Commits
tapas-final
...
v3.5.0
| Author | SHA1 | Date | |
|---|---|---|---|
 Lysandre |
818878dc88 | ||
|
Lysandre Debut
|
9cebee38ad | ||
|
Julien Chaumond
|
ad2303a401 | ||
|
Julien Chaumond
|
55e8d0cea2 | ||
|
Lysandre DebutandNicolas Patry
|
850afb422d | ||
|
|
70f622fab4 | ||
|
Teven
|
4185b115d4 | ||
|
Stas BekmanandSam Shleifer
|
190df58560 | ||
|
Sylvain Gugger
|
a39218b75b | ||
|
Stas BekmanandLysandre Debut
|
ef032ddd1e | ||
|
Sam Shleifer
|
a8339b9ecc | ||
|
Sam Shleifer
|
46509d1c19 | ||
|
Patrick von Platen
|
9c83b96e62 | ||
|
Sylvain Gugger
|
52040517b8 | ||
|
Stas Bekman
|
d4d1fbfc5a | ||
|
Sylvain Gugger
|
5c766ecb50 | ||
|
Sylvain GuggerandThomas Wolf
|
908a28894c | ||
|
Sylvain Gugger
|
c7cb1aa26c | ||
|
Stas Bekman
|
78d706f3ae | ||
|
Shashank Gupta
|
1e2acd0dcf | ||
|
Philip MayandSylvain Gugger
|
bf8625e70b | ||
|
Sam Shleifer
|
ebde57acac | ||
|
Julien Plu
|
76e7a44dee | ||
|
dartrevan
|
507dfb40c3 | ||
|
smanjil
|
7247d0b4ea | ||
|
Stas Bekman
|
4ab5617b0b | ||
|
Sam Shleifer
|
e6d9cdaafe | ||
|
Stas Bekman
|
66582492d3 | ||
|
Stas Bekman
|
f62755a600 | ||
|
Jonathan Chang
|
4a53e8e9e4 | ||
|
Manav Rathod
|
610730998f | ||
|
Chengxi GuoandJulien Chaumond
|
0b02489b2c | ||
|
Stas Bekman
|
187554366f | ||
|
Jonathan Chang
|
77a257fc21 | ||
|
Stas Bekman
|
517eaf460b | ||
|
Patrick von Platen
|
07708793f2 | ||
|
Yossi SynettandPatrick von Platen
|
bc0d26d1de | ||
|
hassoudi
|
30f2507a07 | ||
|
Jonathan Chang
|
5807ba3fa9 | ||
|
hassoudi
|
82146496b6 | ||
|
ktrapeznikovandJulien Chaumond
|
9e5c4d39ab | ||
|
hasantanvir79andJulien Chaumond
|
06ebc37967 | ||
|
Karthik Uppuluri
|
41cd031cf2 | ||
|
Karthik Uppuluri
|
f932ddeff5 | ||
|
Karthik Uppuluri
|
08b92f78fa | ||
|
Karthik UppuluriandJulien Chaumond
|
77d62e78b0 | ||
|
Yifan Peng
|
dd6bfcaefb | ||
|
smanjilandJulien Chaumond
|
ddeecf08e6 | ||
|
Jiaxin Pei
|
96baaafd34 | ||
|
Stefan Schweter
|
185259c261 | ||
|
Manuel Romero
|
34bbf60bf8 | ||
|
Manuel RomeroandJulien Chaumond
|
973218fd3b | ||
|
Manuel Romero
|
f833ca418b | ||
|
Stas Bekman
|
9edafaebef | ||
|
Leandro von WerraandSam Shleifer
|
17450397a7 | ||
|
Stas BekmanandSam Shleifer
|
d787935a14 | ||
|
Sylvain Gugger
|
04e442d575 | ||
|
Guillaume Filionandpatrickvonplaten
|
27b402cab0 | ||
|
Sam Shleifer
|
7abc1d96d1 | ||
|
Bobby DonchevandLysandre
|
52f44dd6d2 | ||
|
Guillem García Subies
|
77c8f6c627 | ||
|
Patrick von Platen
|
226b9debb7 | ||
|
Patrick von Platen
|
6f35c61f93 | ||
|
|
638c0b7c50 | ||
|
Sylvain GuggerandLysandre Debut
|
9c4aa4ac1a | ||
|
Manuel Romero
|
b1d3e95eb5 | ||
|
Sylvain Gugger
|
b6e58db277 | ||
|
Victor SANH
|
969ccac2e9 | ||
|
Nicolas Patry
|
7342d9a583 | ||
|
Branden ChanandJulien Chaumond
|
38630e7a87 | ||
|
Manuel Romero
|
04561ecbe6 | ||
|
Sylvain Gugger
|
854b44aa38 | ||
|
Sylvain Gugger
|
414985c427 | ||
|
Sylvain Gugger
|
cf89724696 | ||
|
Patrick von Platen
|
cb966e640b | ||
|
Pengzhi Gao
|
734afa37f6 | ||
|
Stas Bekman
|
7a7e2c2606 |
@@ -30,20 +30,22 @@ assignees: ''
|
||||
Trainer: @sgugger
|
||||
Speed and Memory Benchmarks: @patrickvonplaten
|
||||
Model Cards: @julien-c
|
||||
Translation: @sshleifer
|
||||
Summarization: @sshleifer
|
||||
TextGeneration: @TevenLeScao
|
||||
examples/distillation: @VictorSanh
|
||||
nlp datasets: [different repo](https://github.com/huggingface/nlp)
|
||||
rust tokenizers: [different repo](https://github.com/huggingface/tokenizers)
|
||||
Text Generation: @TevenLeScao
|
||||
blenderbot: @mariamabarham
|
||||
Bart: @sshleifer
|
||||
Marian: @sshleifer
|
||||
Text Generation: @patrickvonplaten @TevenLeScao
|
||||
Blenderbot: @patrickvonplaten
|
||||
Bart: @patrickvonplaten
|
||||
Marian: @patrickvonplaten
|
||||
Pegasus: @patrickvonplaten
|
||||
mBART: @patrickvonplaten
|
||||
T5: @patrickvonplaten
|
||||
Longformer/Reformer: @patrickvonplaten
|
||||
TransfoXL/XLNet: @TevenLeScao
|
||||
examples/seq2seq: @sshleifer
|
||||
TransfoXL/XLNet: @TevenLeScao
|
||||
RAG: @patrickvonplaten, @lhoestq
|
||||
FSMT: @stas00
|
||||
examples/seq2seq: @patil-suraj
|
||||
examples/bert-loses-patience: @JetRunner
|
||||
tensorflow: @jplu
|
||||
examples/token-classification: @stefan-it
|
||||
|
||||
@@ -43,21 +43,20 @@ members/contributors which may be interested in your PR.
|
||||
Trainer: @sgugger
|
||||
Benchmarks: @patrickvonplaten
|
||||
Model Cards: @julien-c
|
||||
Translation: @sshleifer
|
||||
Summarization: @sshleifer
|
||||
examples/distillation: @VictorSanh
|
||||
nlp datasets: [different repo](https://github.com/huggingface/nlp)
|
||||
rust tokenizers: [different repo](https://github.com/huggingface/tokenizers)
|
||||
Text Generation: @patrickvonplaten, @TevenLeScao
|
||||
Blenderbot, Bart, Marian, Pegasus: @sshleifer
|
||||
Blenderbot, Bart, Marian, Pegasus: @patrickvonplaten
|
||||
T5: @patrickvonplaten
|
||||
Rag: @patrickvonplaten, @lhoestq
|
||||
EncoderDecoder: @patrickvonplaten
|
||||
Longformer, Reformer: @patrickvonplaten
|
||||
TransfoXL, XLNet: @TevenLeScao, @patrickvonplaten
|
||||
examples/seq2seq: @sshleifer
|
||||
examples/seq2seq: @patil-suraj
|
||||
examples/bert-loses-patience: @JetRunner
|
||||
tensorflow: @jplu
|
||||
examples/token-classification: @stefan-it
|
||||
documentation: @sgugger
|
||||
FSTM: @stas00
|
||||
-->
|
||||
|
||||
@@ -1,3 +1,8 @@
|
||||
# configuration notes:
|
||||
#
|
||||
# - `source .env/bin/activate` is currently needed to be run first thing first in each step. Otherwise
|
||||
# the step uses the system-wide python interpreter.
|
||||
|
||||
name: Self-hosted runner (scheduled)
|
||||
|
||||
on:
|
||||
@@ -227,7 +232,7 @@ jobs:
|
||||
python -c "import torch; print('Cuda available:', torch.cuda.is_available())"
|
||||
python -c "import torch; print('Number of GPUs available:', torch.cuda.device_count())"
|
||||
|
||||
- name: Run all tests on GPU
|
||||
- name: Run all tests on multi-GPU
|
||||
env:
|
||||
OMP_NUM_THREADS: 1
|
||||
RUN_SLOW: yes
|
||||
@@ -238,8 +243,20 @@ jobs:
|
||||
- name: Failure short reports
|
||||
if: ${{ always() }}
|
||||
run: cat reports/tests_torch_multiple_gpu_failures_short.txt
|
||||
|
||||
- name: Run all pipeline tests on GPU
|
||||
|
||||
- name: Run examples tests on multi-GPU
|
||||
env:
|
||||
OMP_NUM_THREADS: 1
|
||||
RUN_SLOW: yes
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -m pytest -n 1 --dist=loadfile -s --make-reports=examples_torch_multiple_gpu examples
|
||||
|
||||
- name: Failure short reports
|
||||
if: ${{ always() }}
|
||||
run: cat reports/examples_torch_multiple_gpu_failures_short.txt
|
||||
|
||||
- name: Run all pipeline tests on multi-GPU
|
||||
if: ${{ always() }}
|
||||
env:
|
||||
TF_FORCE_GPU_ALLOW_GROWTH: "true"
|
||||
@@ -306,7 +323,7 @@ jobs:
|
||||
TF_CPP_MIN_LOG_LEVEL=3 python -c "import tensorflow as tf; print('TF GPUs available:', bool(tf.config.list_physical_devices('GPU')))"
|
||||
TF_CPP_MIN_LOG_LEVEL=3 python -c "import tensorflow as tf; print('Number of TF GPUs available:', len(tf.config.list_physical_devices('GPU')))"
|
||||
|
||||
- name: Run all tests on GPU
|
||||
- name: Run all tests on multi-GPU
|
||||
env:
|
||||
OMP_NUM_THREADS: 1
|
||||
RUN_SLOW: yes
|
||||
@@ -318,7 +335,7 @@ jobs:
|
||||
if: ${{ always() }}
|
||||
run: cat reports/tests_tf_multiple_gpu_failures_short.txt
|
||||
|
||||
- name: Run all pipeline tests on GPU
|
||||
- name: Run all pipeline tests on multi-GPU
|
||||
if: ${{ always() }}
|
||||
env:
|
||||
TF_FORCE_GPU_ALLOW_GROWTH: "true"
|
||||
|
||||
@@ -3,14 +3,9 @@
|
||||
|
||||
check_dirs := examples tests src utils
|
||||
|
||||
# get modified files since the branch was made
|
||||
fork_point_sha := $(shell git merge-base --fork-point master)
|
||||
joined_dirs := $(shell echo $(check_dirs) | tr " " "|")
|
||||
modified_py_files := $(shell git diff --name-only $(fork_point_sha) | egrep '^($(joined_dirs))' | egrep '\.py$$')
|
||||
#$(info modified files are: $(modified_py_files))
|
||||
|
||||
modified_only_fixup:
|
||||
@if [ -n "$(modified_py_files)" ]; then \
|
||||
$(eval modified_py_files := $(shell python utils/get_modified_files.py $(check_dirs)))
|
||||
@if test -n "$(modified_py_files)"; then \
|
||||
echo "Checking/fixing $(modified_py_files)"; \
|
||||
black $(modified_py_files); \
|
||||
isort $(modified_py_files); \
|
||||
|
||||
+1
-1
@@ -26,7 +26,7 @@ author = u'huggingface'
|
||||
# The short X.Y version
|
||||
version = u''
|
||||
# The full version, including alpha/beta/rc tags
|
||||
release = u'3.4.0'
|
||||
release = u'3.5.0'
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
|
||||
@@ -65,12 +65,34 @@ BaseModelOutputWithPooling
|
||||
:members:
|
||||
|
||||
|
||||
BaseModelOutputWithCrossAttentions
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_outputs.BaseModelOutputWithCrossAttentions
|
||||
:members:
|
||||
|
||||
|
||||
BaseModelOutputWithPoolingAndCrossAttentions
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions
|
||||
:members:
|
||||
|
||||
|
||||
BaseModelOutputWithPast
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_outputs.BaseModelOutputWithPast
|
||||
:members:
|
||||
|
||||
|
||||
BaseModelOutputWithPastAndCrossAttentions
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_outputs.BaseModelOutputWithPastAndCrossAttentions
|
||||
:members:
|
||||
|
||||
|
||||
Seq2SeqModelOutput
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
@@ -85,6 +107,20 @@ CausalLMOutput
|
||||
:members:
|
||||
|
||||
|
||||
CausalLMOutputWithCrossAttentions
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_outputs.CausalLMOutputWithCrossAttentions
|
||||
:members:
|
||||
|
||||
|
||||
CausalLMOutputWithPastAndCrossAttentions
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_outputs.CausalLMOutputWithPastAndCrossAttentions
|
||||
:members:
|
||||
|
||||
|
||||
CausalLMOutputWithPast
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
|
||||
@@ -81,6 +81,13 @@ AutoModelForMultipleChoice
|
||||
:members:
|
||||
|
||||
|
||||
AutoModelForNextSentencePrediction
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.AutoModelForNextSentencePrediction
|
||||
:members:
|
||||
|
||||
|
||||
AutoModelForTokenClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
|
||||
@@ -3,7 +3,7 @@ BART
|
||||
|
||||
**DISCLAIMER:** If you see something strange, file a `Github Issue
|
||||
<https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title>`__ and assign
|
||||
@sshleifer
|
||||
@patrickvonplaten
|
||||
|
||||
Overview
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
@@ -26,6 +26,16 @@ According to the abstract,
|
||||
The Authors' code can be found `here <https://github.com/pytorch/fairseq/tree/master/examples/bart>`__.
|
||||
|
||||
|
||||
Examples
|
||||
_______________________________________________________________________________________________________________________
|
||||
|
||||
- Examples and scripts for fine-tuning BART and other models for sequence to sequence tasks can be found in
|
||||
`examples/seq2seq/ <https://github.com/huggingface/transformers/blob/master/examples/seq2seq/README.md>`__.
|
||||
- An example of how to train :class:`~transformers.BartForConditionalGeneration` with a Hugging Face :obj:`datasets`
|
||||
object can be found in this `forum discussion
|
||||
<https://discuss.huggingface.co/t/train-bart-for-conditional-generation-e-g-summarization/1904>`__.
|
||||
|
||||
|
||||
Implementation Notes
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
|
||||
@@ -90,6 +90,32 @@ LongformerTokenizerFast
|
||||
.. autoclass:: transformers.LongformerTokenizerFast
|
||||
:members:
|
||||
|
||||
Longformer specific outputs
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.modeling_longformer.LongformerBaseModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.modeling_longformer.LongformerBaseModelOutputWithPooling
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.modeling_longformer.LongformerMultipleChoiceModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.modeling_longformer.LongformerQuestionAnsweringModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.modeling_tf_longformer.TFLongformerBaseModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.modeling_tf_longformer.TFLongformerBaseModelOutputWithPooling
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.modeling_tf_longformer.TFLongformerQuestionAnsweringModelOutput
|
||||
:members:
|
||||
|
||||
LongformerModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
LongformerModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
@@ -3,7 +3,7 @@ MarianMT
|
||||
|
||||
**Bugs:** If you see something strange, file a `Github Issue
|
||||
<https://github.com/huggingface/transformers/issues/new?assignees=sshleifer&labels=&template=bug-report.md&title>`__
|
||||
and assign @sshleifer.
|
||||
and assign @patrickvonplaten.
|
||||
|
||||
Translations should be similar, but not identical to, output in the test set linked to in each model card.
|
||||
|
||||
|
||||
@@ -3,7 +3,7 @@ MBart
|
||||
|
||||
**DISCLAIMER:** If you see something strange, file a `Github Issue
|
||||
<https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title>`__ and assign
|
||||
@sshleifer
|
||||
@patrickvonplaten
|
||||
|
||||
Overview
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
@@ -3,7 +3,7 @@ Pegasus
|
||||
|
||||
**DISCLAIMER:** If you see something strange, file a `Github Issue
|
||||
<https://github.com/huggingface/transformers/issues/new?assignees=sshleifer&labels=&template=bug-report.md&title>`__
|
||||
and assign @sshleifer.
|
||||
and assign @patrickvonplaten.
|
||||
|
||||
|
||||
Overview
|
||||
|
||||
@@ -18,39 +18,65 @@ done something similar on your task, either using the model directly in your own
|
||||
:class:`~.transformers.Trainer`/:class:`~.transformers.TFTrainer` class. Let's see how you can share the result on the
|
||||
`model hub <https://huggingface.co/models>`__.
|
||||
|
||||
Model versioning
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
Since version v3.5.0, the model hub has built-in model versioning based on git and git-lfs. It is based on the paradigm
|
||||
that one model *is* one repo.
|
||||
|
||||
This allows:
|
||||
|
||||
- built-in versioning
|
||||
- access control
|
||||
- scalability
|
||||
|
||||
This is built around *revisions*, which is a way to pin a specific version of a model, using a commit hash, tag or
|
||||
branch.
|
||||
|
||||
For instance:
|
||||
|
||||
.. code-block::
|
||||
|
||||
>>> tokenizer = AutoTokenizer.from_pretrained(
|
||||
>>> "julien-c/EsperBERTo-small",
|
||||
>>> revision="v2.0.1" # tag name, or branch name, or commit hash
|
||||
>>> )
|
||||
|
||||
Basic steps
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
..
|
||||
When #5258 is merged, we can remove the need to create the directory.
|
||||
In order to upload a model, you'll need to first create a git repo. This repo will live on the model hub, allowing
|
||||
users to clone it and you (and your organization members) to push to it. First, you should ensure you are logged in the
|
||||
``transformers-cli``:
|
||||
|
||||
First, pick a directory with the name you want your model to have on the model hub (its full name will then be
|
||||
`username/awesome-name-you-picked` or `organization/awesome-name-you-picked`) and create it with either
|
||||
Go in a terminal and run the following command. It should be in the virtual environment where you installed 🤗
|
||||
Transformers, since that command :obj:`transformers-cli` comes from the library.
|
||||
|
||||
.. code-block::
|
||||
|
||||
mkdir path/to/awesome-name-you-picked
|
||||
transformers-cli login
|
||||
|
||||
or in python
|
||||
|
||||
Once you are logged in with your model hub credentials, you can start building your repositories. To create a repo:
|
||||
|
||||
.. code-block::
|
||||
|
||||
import os
|
||||
os.makedirs("path/to/awesome-name-you-picked")
|
||||
transformers-cli repo create your-model-name
|
||||
|
||||
then you can save your model and tokenizer with:
|
||||
This creates a repo on the model hub, which can be cloned. You can then add/remove from that repo as you would with any
|
||||
other git repo.
|
||||
|
||||
.. code-block::
|
||||
|
||||
model.save_pretrained("path/to/awesome-name-you-picked")
|
||||
tokenizer.save_pretrained("path/to/awesome-name-you-picked")
|
||||
git clone https://huggingface.co/username/your-model-name
|
||||
|
||||
Or, if you're using the Trainer API
|
||||
# Then commit as usual
|
||||
cd your-model-name
|
||||
echo "hello" >> README.md
|
||||
git add . && git commit -m "Update from $USER"
|
||||
|
||||
.. code-block::
|
||||
We are intentionally not wrapping git too much, so as to stay intuitive and easy-to-use.
|
||||
|
||||
trainer.save_model("path/to/awesome-name-you-picked")
|
||||
tokenizer.save_pretrained("path/to/awesome-name-you-picked")
|
||||
|
||||
Make your model work on all frameworks
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
@@ -71,13 +97,13 @@ or removing TF. For instance, if you trained a :class:`~transformers.DistilBertF
|
||||
|
||||
.. code-block::
|
||||
|
||||
from transformers import TFDistilBertForSequenceClassification
|
||||
>>> from transformers import TFDistilBertForSequenceClassification
|
||||
|
||||
and if you trained a :class:`~transformers.TFDistilBertForSequenceClassification`, try to type
|
||||
|
||||
.. code-block::
|
||||
|
||||
from transformers import DistilBertForSequenceClassification
|
||||
>>> from transformers import DistilBertForSequenceClassification
|
||||
|
||||
This will give back an error if your model does not exist in the other framework (something that should be pretty rare
|
||||
since we're aiming for full parity between the two frameworks). In this case, skip this and go to the next step.
|
||||
@@ -87,20 +113,20 @@ model class:
|
||||
|
||||
.. code-block::
|
||||
|
||||
tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
|
||||
tf_model.save_pretrained("path/to/awesome-name-you-picked")
|
||||
>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
|
||||
>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
|
||||
|
||||
and if you trained your model in TensorFlow and have to create a PyTorch version, adapt the following code to your
|
||||
model class:
|
||||
|
||||
.. code-block::
|
||||
|
||||
pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
|
||||
pt_model.save_pretrained("path/to/awesome-name-you-picked")
|
||||
>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
|
||||
>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
|
||||
|
||||
That's all there is to it!
|
||||
|
||||
Check the directory before uploading
|
||||
Check the directory before pushing to the model hub.
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
Make sure there are no garbage files in the directory you'll upload. It should only have:
|
||||
@@ -116,62 +142,46 @@ Make sure there are no garbage files in the directory you'll upload. It should o
|
||||
|
||||
Other files can safely be deleted.
|
||||
|
||||
Upload your model with the CLI
|
||||
|
||||
Uploading your files
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Now go in a terminal and run the following command. It should be in the virtual environment where you installed 🤗
|
||||
Transformers, since that command :obj:`transformers-cli` comes from the library.
|
||||
Once the repo is cloned, you can add the model, configuration and tokenizer files. For instance, saving the model and
|
||||
tokenizer files:
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli login
|
||||
>>> model.save_pretrained("path/to/repo/clone/your-model-name")
|
||||
>>> tokenizer.save_pretrained("path/to/repo/clone/your-model-name")
|
||||
|
||||
Then log in using the same credentials as on huggingface.co. To upload your model, just type
|
||||
Or, if you're using the Trainer API
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli upload path/to/awesome-name-you-picked/
|
||||
>>> trainer.save_model("path/to/awesome-name-you-picked")
|
||||
|
||||
This will upload the folder containing the weights, tokenizer and configuration we prepared in the previous section.
|
||||
|
||||
By default you will be prompted to confirm that you want these files to be uploaded. If you are uploading multiple
|
||||
models and need to script that process, you can add `-y` to bypass the prompt. For example:
|
||||
You can then add these files to the staging environment and verify that they have been correctly staged with the ``git
|
||||
status`` command:
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli upload -y path/to/awesome-name-you-picked/
|
||||
git add --all
|
||||
git status
|
||||
|
||||
|
||||
If you want to upload a single file (a new version of your model, or the other framework checkpoint you want to add),
|
||||
just type:
|
||||
Finally, the files should be comitted:
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli upload path/to/awesome-name-you-picked/that-file
|
||||
git commit -m "First version of the your-model-name model and tokenizer."
|
||||
|
||||
or
|
||||
And pushed to the remote:
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli upload path/to/awesome-name-you-picked/that-file --filename awesome-name-you-picked/new_name
|
||||
git push
|
||||
|
||||
if you want to change its filename.
|
||||
This will upload the folder containing the weights, tokenizer and configuration we have just prepared.
|
||||
|
||||
This uploads the model to your personal account. If you want your model to be namespaced by your organization name
|
||||
rather than your username, add the following flag to any command:
|
||||
|
||||
.. code-block::
|
||||
|
||||
--organization organization_name
|
||||
|
||||
so for instance:
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli upload path/to/awesome-name-you-picked/ --organization organization_name
|
||||
|
||||
Your model will then be accessible through its identifier, which is, as we saw above,
|
||||
`username/awesome-name-you-picked` or `organization/awesome-name-you-picked`.
|
||||
|
||||
Add a model card
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
@@ -203,20 +213,15 @@ Anyone can load it from code:
|
||||
|
||||
.. code-block::
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("namespace/awesome-name-you-picked")
|
||||
model = AutoModel.from_pretrained("namespace/awesome-name-you-picked")
|
||||
>>> tokenizer = AutoTokenizer.from_pretrained("namespace/awesome-name-you-picked")
|
||||
>>> model = AutoModel.from_pretrained("namespace/awesome-name-you-picked")
|
||||
|
||||
Additional commands
|
||||
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
|
||||
|
||||
You can list all the files you uploaded on the hub like this:
|
||||
You may specify a revision by using the ``revision`` flag in the ``from_pretrained`` method:
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli s3 ls
|
||||
|
||||
You can also delete unneeded files with
|
||||
|
||||
.. code-block::
|
||||
|
||||
transformers-cli s3 rm awesome-name-you-picked/filename
|
||||
>>> tokenizer = AutoTokenizer.from_pretrained(
|
||||
>>> "julien-c/EsperBERTo-small",
|
||||
>>> revision="v2.0.1" # tag name, or branch name, or commit hash
|
||||
>>> )
|
||||
|
||||
+18
-1
@@ -409,6 +409,22 @@ decorators are used to set the requirements of tests CPU/GPU/TPU-wise:
|
||||
* ``require_torch_non_multigpu`` - as ``require_torch`` plus requires 0 or 1 GPUs
|
||||
* ``require_torch_tpu`` - as ``require_torch`` plus requires at least 1 TPU
|
||||
|
||||
Let's depict the GPU requirements in the following table:
|
||||
|
||||
|
||||
+----------+---------------------------------+
|
||||
| n gpus | decorator |
|
||||
+==========+=================================+
|
||||
| ``>= 0`` | ``@require_torch`` |
|
||||
+----------+---------------------------------+
|
||||
| ``>= 1`` | ``@require_torch_gpu`` |
|
||||
+----------+---------------------------------+
|
||||
| ``>= 2`` | ``@require_torch_multigpu`` |
|
||||
+----------+---------------------------------+
|
||||
| ``< 2`` | ``@require_torch_non_multigpu`` |
|
||||
+----------+---------------------------------+
|
||||
|
||||
|
||||
For example, here is a test that must be run only when there are 2 or more GPUs available and pytorch is installed:
|
||||
|
||||
.. code-block:: python
|
||||
@@ -450,7 +466,8 @@ Inside tests:
|
||||
|
||||
.. code-block:: bash
|
||||
|
||||
torch.cuda.device_count()
|
||||
from transformers.testing_utils import get_gpu_count
|
||||
n_gpu = get_gpu_count() # works with torch and tf
|
||||
|
||||
|
||||
|
||||
|
||||
+4
-3
@@ -37,7 +37,7 @@ git checkout tags/v3.4.0
|
||||
|---|---|:---:|:---:|:---:|:---:|
|
||||
| [**`language-modeling`**](https://github.com/huggingface/transformers/tree/master/examples/language-modeling) | Raw text | ✅ | - | ✅ | [](https://colab.research.google.com/github/huggingface/blog/blob/master/notebooks/01_how_to_train.ipynb)
|
||||
| [**`text-classification`**](https://github.com/huggingface/transformers/tree/master/examples/text-classification) | GLUE, XNLI | ✅ | ✅ | ✅ | [](https://github.com/huggingface/notebooks/blob/master/examples/text_classification.ipynb)
|
||||
| [**`token-classification`**](https://github.com/huggingface/transformers/tree/master/examples/token-classification) | CoNLL NER | ✅ | ✅ | - | -
|
||||
| [**`token-classification`**](https://github.com/huggingface/transformers/tree/master/examples/token-classification) | CoNLL NER | ✅ | ✅ | ✅ | -
|
||||
| [**`multiple-choice`**](https://github.com/huggingface/transformers/tree/master/examples/multiple-choice) | SWAG, RACE, ARC | ✅ | ✅ | - | [](https://colab.research.google.com/github/ViktorAlm/notebooks/blob/master/MPC_GPU_Demo_for_TF_and_PT.ipynb)
|
||||
| [**`question-answering`**](https://github.com/huggingface/transformers/tree/master/examples/question-answering) | SQuAD | ✅ | ✅ | - | -
|
||||
| [**`text-generation`**](https://github.com/huggingface/transformers/tree/master/examples/text-generation) | - | n/a | n/a | - | [](https://colab.research.google.com/github/huggingface/blog/blob/master/notebooks/02_how_to_generate.ipynb)
|
||||
@@ -62,13 +62,14 @@ When using PyTorch, we support TPUs thanks to `pytorch/xla`. For more context an
|
||||
very detailed [pytorch/xla README](https://github.com/pytorch/xla/blob/master/README.md).
|
||||
|
||||
In this repo, we provide a very simple launcher script named [xla_spawn.py](https://github.com/huggingface/transformers/tree/master/examples/xla_spawn.py) that lets you run our example scripts on multiple TPU cores without any boilerplate.
|
||||
Just pass a `--num_cores` flag to this script, then your regular training script with its arguments (this is similar to the `torch.distributed.launch` helper for torch.distributed).
|
||||
Just pass a `--num_cores` flag to this script, then your regular training script with its arguments (this is similar to the `torch.distributed.launch` helper for torch.distributed).
|
||||
Note that this approach does not work for examples that use `pytorch-lightning`.
|
||||
|
||||
For example for `run_glue`:
|
||||
|
||||
```bash
|
||||
python examples/xla_spawn.py --num_cores 8 \
|
||||
examples/text-classification/run_glue.py
|
||||
examples/text-classification/run_glue.py \
|
||||
--model_name_or_path bert-base-cased \
|
||||
--task_name mnli \
|
||||
--data_dir ./data/glue_data/MNLI \
|
||||
|
||||
@@ -4,7 +4,7 @@ import sys
|
||||
from unittest.mock import patch
|
||||
|
||||
import run_glue_with_pabee
|
||||
from transformers.testing_utils import TestCasePlus
|
||||
from transformers.testing_utils import TestCasePlus, require_torch_non_multigpu_but_fix_me
|
||||
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
@@ -20,6 +20,7 @@ def get_setup_file():
|
||||
|
||||
|
||||
class PabeeTests(TestCasePlus):
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_glue(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
|
||||
@@ -5,7 +5,7 @@ import unittest
|
||||
from unittest.mock import patch
|
||||
|
||||
import run_glue_deebert
|
||||
from transformers.testing_utils import slow
|
||||
from transformers.testing_utils import require_torch_non_multigpu_but_fix_me, slow
|
||||
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
@@ -26,6 +26,7 @@ class DeeBertTests(unittest.TestCase):
|
||||
logger.addHandler(stream_handler)
|
||||
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_glue_deebert_train(self):
|
||||
|
||||
train_args = """
|
||||
|
||||
@@ -12,7 +12,7 @@ This folder contains the original code used to train Distil* as well as examples
|
||||
|
||||
**October 3, 2019 - Update** We release our [NeurIPS workshop paper](https://arxiv.org/abs/1910.01108) explaining our approach on **DistilBERT**. It includes updated results and further experiments. We applied the same method to GPT2 and release the weights of **DistilGPT2**. DistilGPT2 is two times faster and 33% smaller than GPT2. **The paper supersedes our [previous blogpost](https://medium.com/huggingface/distilbert-8cf3380435b5) with a different distillation loss and better performances. Please use the paper as a reference when comparing/reporting results on DistilBERT.**
|
||||
|
||||
**September 19, 2019 - Update:** We fixed bugs in the code and released an upadted version of the weights trained with a modification of the distillation loss. DistilBERT now reaches 99% of `BERT-base`'s performance on GLUE, and 86.9 F1 score on SQuAD v1.1 dev set (compared to 88.5 for `BERT-base`). We will publish a formal write-up of our approach in the near future!
|
||||
**September 19, 2019 - Update:** We fixed bugs in the code and released an updated version of the weights trained with a modification of the distillation loss. DistilBERT now reaches 99% of `BERT-base`'s performance on GLUE, and 86.9 F1 score on SQuAD v1.1 dev set (compared to 88.5 for `BERT-base`). We will publish a formal write-up of our approach in the near future!
|
||||
|
||||
|
||||
## What is Distil*
|
||||
|
||||
@@ -10,7 +10,7 @@ These scripts leverage the 🤗 Datasets library and the Trainer API. You can ea
|
||||
need extra processing on your datasets.
|
||||
|
||||
**Note:** The old script `run_language_modeling.py` is still available
|
||||
[here](https://github.com/huggingface/transformers/blob/master/examples/contrib/legacy/language-modeling/run_language_modeling.py).
|
||||
[here](https://github.com/huggingface/transformers/blob/master/examples/contrib/legacy/run_language_modeling.py).
|
||||
|
||||
The following examples, will run on a datasets hosted on our [hub](https://huggingface.co/datasets) or with your own
|
||||
text files for training and validation. We give examples of both below.
|
||||
@@ -68,13 +68,13 @@ python run_mlm.py \
|
||||
To run on your own training and validation files, use the following command:
|
||||
|
||||
```bash
|
||||
python run_clm.py \
|
||||
python run_mlm.py \
|
||||
--model_name_or_path roberta-base \
|
||||
--train_file path_to_train_file \
|
||||
--validation_file path_to_validation_file \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--output_dir /tmp/test-clm
|
||||
--output_dir /tmp/test-mlm
|
||||
```
|
||||
|
||||
If your dataset is organized with one sample per line, you can use the `--line_by_line` flag (otherwise the script
|
||||
|
||||
@@ -190,7 +190,7 @@ def main():
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.train_file
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
|
||||
@@ -201,7 +201,7 @@ def main():
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.train_file
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
@@ -264,7 +264,15 @@ def main():
|
||||
def tokenize_function(examples):
|
||||
# Remove empty lines
|
||||
examples["text"] = [line for line in examples["text"] if len(line) > 0 and not line.isspace()]
|
||||
return tokenizer(examples["text"], padding=padding, truncation=True, max_length=data_args.max_seq_length)
|
||||
return tokenizer(
|
||||
examples["text"],
|
||||
padding=padding,
|
||||
truncation=True,
|
||||
max_length=data_args.max_seq_length,
|
||||
# We use this option because DataCollatorForLanguageModeling (see below) is more efficient when it
|
||||
# receives the `special_tokens_mask`.
|
||||
return_special_tokens_mask=True,
|
||||
)
|
||||
|
||||
tokenized_datasets = datasets.map(
|
||||
tokenize_function,
|
||||
@@ -275,8 +283,10 @@ def main():
|
||||
)
|
||||
else:
|
||||
# Otherwise, we tokenize every text, then concatenate them together before splitting them in smaller parts.
|
||||
# We use `return_special_tokens_mask=True` because DataCollatorForLanguageModeling (see below) is more
|
||||
# efficient when it receives the `special_tokens_mask`.
|
||||
def tokenize_function(examples):
|
||||
return tokenizer(examples[text_column_name])
|
||||
return tokenizer(examples[text_column_name], return_special_tokens_mask=True)
|
||||
|
||||
tokenized_datasets = datasets.map(
|
||||
tokenize_function,
|
||||
|
||||
@@ -204,7 +204,7 @@ def main():
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.train_file
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
|
||||
@@ -198,7 +198,7 @@ def main():
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.train_file
|
||||
data_files["validation"] = data_args.validation_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
if extension == "txt":
|
||||
extension = "text"
|
||||
|
||||
@@ -1801,7 +1801,7 @@ class GeneralizedRCNN(nn.Module):
|
||||
f"Some weights of the model checkpoint at {pretrained_model_name_or_path} were not used when "
|
||||
f"initializing {model.__class__.__name__}: {unexpected_keys}\n"
|
||||
f"- This IS expected if you are initializing {model.__class__.__name__} from the checkpoint of a model trained on another task "
|
||||
f"or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPretraining model).\n"
|
||||
f"or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).\n"
|
||||
f"- This IS NOT expected if you are initializing {model.__class__.__name__} from the checkpoint of a model that you expect "
|
||||
f"to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model)."
|
||||
)
|
||||
|
||||
@@ -16,6 +16,7 @@ from transformers.configuration_dpr import DPRConfig
|
||||
from transformers.configuration_rag import RagConfig
|
||||
from transformers.file_utils import is_datasets_available, is_faiss_available, is_psutil_available, is_torch_available
|
||||
from transformers.retrieval_rag import CustomHFIndex
|
||||
from transformers.testing_utils import require_torch_non_multigpu_but_fix_me
|
||||
from transformers.tokenization_bart import BartTokenizer
|
||||
from transformers.tokenization_bert import VOCAB_FILES_NAMES as DPR_VOCAB_FILES_NAMES
|
||||
from transformers.tokenization_dpr import DPRQuestionEncoderTokenizer
|
||||
@@ -178,6 +179,7 @@ class RagRetrieverTest(TestCase):
|
||||
retriever.init_retrieval(port)
|
||||
return retriever
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_pytorch_distributed_retriever_retrieve(self):
|
||||
n_docs = 1
|
||||
retriever = self.get_dummy_pytorch_distributed_retriever(init_retrieval=True)
|
||||
@@ -193,6 +195,7 @@ class RagRetrieverTest(TestCase):
|
||||
self.assertEqual(doc_dicts[1]["id"][0], "0") # max inner product is reached with first doc
|
||||
self.assertListEqual(doc_ids.tolist(), [[1], [0]])
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_custom_hf_index_retriever_retrieve(self):
|
||||
n_docs = 1
|
||||
retriever = self.get_dummy_custom_hf_index_retriever(init_retrieval=True, from_disk=False)
|
||||
@@ -208,6 +211,7 @@ class RagRetrieverTest(TestCase):
|
||||
self.assertEqual(doc_dicts[1]["id"][0], "0") # max inner product is reached with first doc
|
||||
self.assertListEqual(doc_ids.tolist(), [[1], [0]])
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_custom_pytorch_distributed_retriever_retrieve_from_disk(self):
|
||||
n_docs = 1
|
||||
retriever = self.get_dummy_custom_hf_index_retriever(init_retrieval=True, from_disk=True)
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
## Sequence to Sequence Training and Evaluation
|
||||
|
||||
This directory contains examples for finetuning and evaluating transformers on summarization and translation tasks.
|
||||
Please tag @sshleifer with any issues/unexpected behaviors, or send a PR!
|
||||
Please tag @patil-suraj with any issues/unexpected behaviors, or send a PR!
|
||||
For deprecated `bertabs` instructions, see [`bertabs/README.md`](bertabs/README.md).
|
||||
|
||||
### Supported Architectures
|
||||
|
||||
@@ -23,7 +23,7 @@ logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
BERTABS_FINETUNED_CONFIG_MAP = {
|
||||
"bertabs-finetuned-cnndm": "https://s3.amazonaws.com/models.huggingface.co/bert/remi/bertabs-finetuned-cnndm-extractive-abstractive-summarization/config.json",
|
||||
"bertabs-finetuned-cnndm": "https://huggingface.co/remi/bertabs-finetuned-cnndm-extractive-abstractive-summarization/resolve/main/config.json",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -1,10 +0,0 @@
|
||||
# Add parent directory to python path to access lightning_base.py
|
||||
export PYTHONPATH="../":"${PYTHONPATH}"
|
||||
|
||||
python distillation.py \
|
||||
--learning_rate=3e-4 \
|
||||
--do_train \
|
||||
--do_predict \
|
||||
--fp16 \
|
||||
--val_check_interval 0.1 \
|
||||
"$@"
|
||||
@@ -3,93 +3,110 @@
|
||||
import argparse
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
import pytest
|
||||
import pytorch_lightning as pl
|
||||
import timeout_decorator
|
||||
import torch
|
||||
|
||||
from distillation import BartSummarizationDistiller, distill_main
|
||||
from finetune import SummarizationModule, main
|
||||
from test_seq2seq_examples import CUDA_AVAILABLE, MBART_TINY
|
||||
from transformers import BartForConditionalGeneration, MarianMTModel
|
||||
from transformers.testing_utils import TestCasePlus, slow
|
||||
from transformers import MarianMTModel
|
||||
from transformers.file_utils import cached_path
|
||||
from transformers.testing_utils import TestCasePlus, require_torch_gpu, require_torch_non_multigpu_but_fix_me, slow
|
||||
from utils import load_json
|
||||
|
||||
|
||||
MODEL_NAME = MBART_TINY
|
||||
MARIAN_MODEL = "sshleifer/student_marian_en_ro_6_1"
|
||||
MARIAN_MODEL = "sshleifer/mar_enro_6_3_student"
|
||||
|
||||
|
||||
class TestAll(TestCasePlus):
|
||||
class TestMbartCc25Enro(TestCasePlus):
|
||||
def setUp(self):
|
||||
super().setUp()
|
||||
|
||||
data_cached = cached_path(
|
||||
"https://cdn-datasets.huggingface.co/translation/wmt_en_ro-tr40k-va0.5k-te0.5k.tar.gz",
|
||||
extract_compressed_file=True,
|
||||
)
|
||||
self.data_dir = f"{data_cached}/wmt_en_ro-tr40k-va0.5k-te0.5k"
|
||||
|
||||
@slow
|
||||
@pytest.mark.skipif(not CUDA_AVAILABLE, reason="too slow to run on CPU")
|
||||
@require_torch_gpu
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_model_download(self):
|
||||
"""This warms up the cache so that we can time the next test without including download time, which varies between machines."""
|
||||
BartForConditionalGeneration.from_pretrained(MODEL_NAME)
|
||||
MarianMTModel.from_pretrained(MARIAN_MODEL)
|
||||
|
||||
@timeout_decorator.timeout(120)
|
||||
# @timeout_decorator.timeout(1200)
|
||||
@slow
|
||||
@pytest.mark.skipif(not CUDA_AVAILABLE, reason="too slow to run on CPU")
|
||||
@require_torch_gpu
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_train_mbart_cc25_enro_script(self):
|
||||
data_dir = "examples/seq2seq/test_data/wmt_en_ro"
|
||||
env_vars_to_replace = {
|
||||
"--fp16_opt_level=O1": "",
|
||||
"$MAX_LEN": 128,
|
||||
"$BS": 4,
|
||||
"$MAX_LEN": 64,
|
||||
"$BS": 64,
|
||||
"$GAS": 1,
|
||||
"$ENRO_DIR": data_dir,
|
||||
"facebook/mbart-large-cc25": MODEL_NAME,
|
||||
# Download is 120MB in previous test.
|
||||
"val_check_interval=0.25": "val_check_interval=1.0",
|
||||
"$ENRO_DIR": self.data_dir,
|
||||
"facebook/mbart-large-cc25": MARIAN_MODEL,
|
||||
# "val_check_interval=0.25": "val_check_interval=1.0",
|
||||
"--learning_rate=3e-5": "--learning_rate 3e-4",
|
||||
"--num_train_epochs 6": "--num_train_epochs 1",
|
||||
}
|
||||
|
||||
# Clean up bash script
|
||||
bash_script = Path("examples/seq2seq/train_mbart_cc25_enro.sh").open().read().split("finetune.py")[1].strip()
|
||||
bash_script = (self.test_file_dir / "train_mbart_cc25_enro.sh").open().read().split("finetune.py")[1].strip()
|
||||
bash_script = bash_script.replace("\\\n", "").strip().replace('"$@"', "")
|
||||
for k, v in env_vars_to_replace.items():
|
||||
bash_script = bash_script.replace(k, str(v))
|
||||
output_dir = self.get_auto_remove_tmp_dir()
|
||||
|
||||
bash_script = bash_script.replace("--fp16 ", "")
|
||||
testargs = (
|
||||
["finetune.py"]
|
||||
+ bash_script.split()
|
||||
+ [
|
||||
f"--output_dir={output_dir}",
|
||||
"--gpus=1",
|
||||
"--learning_rate=3e-1",
|
||||
"--warmup_steps=0",
|
||||
"--val_check_interval=1.0",
|
||||
"--tokenizer_name=facebook/mbart-large-en-ro",
|
||||
]
|
||||
)
|
||||
# bash_script = bash_script.replace("--fp16 ", "")
|
||||
args = f"""
|
||||
--output_dir {output_dir}
|
||||
--tokenizer_name Helsinki-NLP/opus-mt-en-ro
|
||||
--sortish_sampler
|
||||
--do_predict
|
||||
--gpus 1
|
||||
--freeze_encoder
|
||||
--n_train 40000
|
||||
--n_val 500
|
||||
--n_test 500
|
||||
--fp16_opt_level O1
|
||||
--num_sanity_val_steps 0
|
||||
--eval_beams 2
|
||||
""".split()
|
||||
# XXX: args.gpus > 1 : handle multigpu in the future
|
||||
|
||||
testargs = ["finetune.py"] + bash_script.split() + args
|
||||
with patch.object(sys, "argv", testargs):
|
||||
parser = argparse.ArgumentParser()
|
||||
parser = pl.Trainer.add_argparse_args(parser)
|
||||
parser = SummarizationModule.add_model_specific_args(parser, os.getcwd())
|
||||
args = parser.parse_args()
|
||||
args.do_predict = False
|
||||
# assert args.gpus == gpus THIS BREAKS for multigpu
|
||||
model = main(args)
|
||||
|
||||
# Check metrics
|
||||
metrics = load_json(model.metrics_save_path)
|
||||
first_step_stats = metrics["val"][0]
|
||||
last_step_stats = metrics["val"][-1]
|
||||
assert (
|
||||
len(metrics["val"]) == (args.max_epochs / args.val_check_interval) + 1
|
||||
) # +1 accounts for val_sanity_check
|
||||
|
||||
assert last_step_stats["val_avg_gen_time"] >= 0.01
|
||||
|
||||
assert first_step_stats["val_avg_bleu"] < last_step_stats["val_avg_bleu"] # model learned nothing
|
||||
assert 1.0 >= last_step_stats["val_avg_gen_time"] # model hanging on generate. Maybe bad config was saved.
|
||||
self.assertEqual(len(metrics["val"]), (args.max_epochs / args.val_check_interval))
|
||||
assert isinstance(last_step_stats[f"val_avg_{model.val_metric}"], float)
|
||||
|
||||
self.assertGreater(last_step_stats["val_avg_gen_time"], 0.01)
|
||||
# model hanging on generate. Maybe bad config was saved. (XXX: old comment/assert?)
|
||||
self.assertLessEqual(last_step_stats["val_avg_gen_time"], 1.0)
|
||||
|
||||
# test learning requirements:
|
||||
|
||||
# 1. BLEU improves over the course of training by more than 2 pts
|
||||
self.assertGreater(last_step_stats["val_avg_bleu"] - first_step_stats["val_avg_bleu"], 2)
|
||||
|
||||
# 2. BLEU finishes above 17
|
||||
self.assertGreater(last_step_stats["val_avg_bleu"], 17)
|
||||
|
||||
# 3. test BLEU and val BLEU within ~1.1 pt.
|
||||
self.assertLess(abs(metrics["val"][-1]["val_avg_bleu"] - metrics["test"][-1]["test_avg_bleu"]), 1.1)
|
||||
|
||||
# check lightning ckpt can be loaded and has a reasonable statedict
|
||||
contents = os.listdir(output_dir)
|
||||
ckpt_path = [x for x in contents if x.endswith(".ckpt")][0]
|
||||
@@ -107,11 +124,14 @@ class TestAll(TestCasePlus):
|
||||
# assert len(metrics["val"]) == desired_n_evals
|
||||
assert len(metrics["test"]) == 1
|
||||
|
||||
|
||||
class TestDistilMarianNoTeacher(TestCasePlus):
|
||||
@timeout_decorator.timeout(600)
|
||||
@slow
|
||||
@pytest.mark.skipif(not CUDA_AVAILABLE, reason="too slow to run on CPU")
|
||||
@require_torch_gpu
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_opus_mt_distill_script(self):
|
||||
data_dir = "examples/seq2seq/test_data/wmt_en_ro"
|
||||
data_dir = f"{self.test_file_dir_str}/test_data/wmt_en_ro"
|
||||
env_vars_to_replace = {
|
||||
"--fp16_opt_level=O1": "",
|
||||
"$MAX_LEN": 128,
|
||||
@@ -124,7 +144,7 @@ class TestAll(TestCasePlus):
|
||||
|
||||
# Clean up bash script
|
||||
bash_script = (
|
||||
Path("examples/seq2seq/distil_marian_no_teacher.sh").open().read().split("distillation.py")[1].strip()
|
||||
(self.test_file_dir / "distil_marian_no_teacher.sh").open().read().split("distillation.py")[1].strip()
|
||||
)
|
||||
bash_script = bash_script.replace("\\\n", "").strip().replace('"$@"', "")
|
||||
bash_script = bash_script.replace("--fp16 ", " ")
|
||||
|
||||
@@ -11,7 +11,7 @@ from save_len_file import save_len_file
|
||||
from test_seq2seq_examples import ARTICLES, BART_TINY, MARIAN_TINY, MBART_TINY, SUMMARIES, T5_TINY, make_test_data_dir
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.modeling_bart import shift_tokens_right
|
||||
from transformers.testing_utils import TestCasePlus, slow
|
||||
from transformers.testing_utils import TestCasePlus, require_torch_non_multigpu_but_fix_me, slow
|
||||
from utils import FAIRSEQ_AVAILABLE, DistributedSortishSampler, LegacySeq2SeqDataset, Seq2SeqDataset
|
||||
|
||||
|
||||
@@ -30,6 +30,7 @@ class TestAll(TestCasePlus):
|
||||
],
|
||||
)
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_seq2seq_dataset_truncation(self, tok_name):
|
||||
tokenizer = AutoTokenizer.from_pretrained(tok_name)
|
||||
tmp_dir = make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir())
|
||||
@@ -69,6 +70,7 @@ class TestAll(TestCasePlus):
|
||||
break # No need to test every batch
|
||||
|
||||
@parameterized.expand([BART_TINY, BERT_BASE_CASED])
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_legacy_dataset_truncation(self, tok):
|
||||
tokenizer = AutoTokenizer.from_pretrained(tok)
|
||||
tmp_dir = make_test_data_dir(tmp_dir=self.get_auto_remove_tmp_dir())
|
||||
@@ -93,6 +95,7 @@ class TestAll(TestCasePlus):
|
||||
assert max_len_target > trunc_target # Truncated
|
||||
break # No need to test every batch
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_pack_dataset(self):
|
||||
tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-cc25")
|
||||
|
||||
@@ -111,6 +114,7 @@ class TestAll(TestCasePlus):
|
||||
assert orig_paths == new_paths
|
||||
|
||||
@pytest.mark.skipif(not FAIRSEQ_AVAILABLE, reason="This test requires fairseq")
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_dynamic_batch_size(self):
|
||||
if not FAIRSEQ_AVAILABLE:
|
||||
return
|
||||
@@ -135,6 +139,7 @@ class TestAll(TestCasePlus):
|
||||
if failures:
|
||||
raise AssertionError(f"too many tokens in {len(failures)} batches")
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_sortish_sampler_reduces_padding(self):
|
||||
ds, _, tokenizer = self._get_dataset(max_len=512)
|
||||
bs = 2
|
||||
@@ -174,6 +179,7 @@ class TestAll(TestCasePlus):
|
||||
)
|
||||
return ds, max_tokens, tokenizer
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_distributed_sortish_sampler_splits_indices_between_procs(self):
|
||||
ds, max_tokens, tokenizer = self._get_dataset()
|
||||
ids1 = set(DistributedSortishSampler(ds, 256, num_replicas=2, rank=0, add_extra_examples=False))
|
||||
@@ -189,6 +195,7 @@ class TestAll(TestCasePlus):
|
||||
PEGASUS_XSUM,
|
||||
],
|
||||
)
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_dataset_kwargs(self, tok_name):
|
||||
tokenizer = AutoTokenizer.from_pretrained(tok_name)
|
||||
if tok_name == MBART_TINY:
|
||||
|
||||
@@ -2,9 +2,9 @@ import os
|
||||
import sys
|
||||
from unittest.mock import patch
|
||||
|
||||
from transformers import BertTokenizer, EncoderDecoderModel, is_torch_available
|
||||
from transformers import BertTokenizer, EncoderDecoderModel
|
||||
from transformers.file_utils import is_datasets_available
|
||||
from transformers.testing_utils import TestCasePlus, execute_subprocess_async, slow
|
||||
from transformers.testing_utils import TestCasePlus, execute_subprocess_async, get_gpu_count, slow
|
||||
from transformers.trainer_callback import TrainerState
|
||||
from transformers.trainer_utils import set_seed
|
||||
|
||||
@@ -13,9 +13,6 @@ from .seq2seq_trainer import Seq2SeqTrainer
|
||||
from .test_seq2seq_examples import MBART_TINY
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
|
||||
set_seed(42)
|
||||
MARIAN_MODEL = "sshleifer/student_marian_en_ro_6_1"
|
||||
|
||||
@@ -180,7 +177,7 @@ class TestFinetuneTrainer(TestCasePlus):
|
||||
--num_train_epochs {str(num_train_epochs)}
|
||||
--per_device_train_batch_size 4
|
||||
--per_device_eval_batch_size 4
|
||||
--learning_rate 3e-4
|
||||
--learning_rate 3e-3
|
||||
--warmup_steps 8
|
||||
--evaluate_during_training
|
||||
--predict_with_generate
|
||||
@@ -196,7 +193,7 @@ class TestFinetuneTrainer(TestCasePlus):
|
||||
""".split()
|
||||
# --eval_beams 2
|
||||
|
||||
n_gpu = torch.cuda.device_count()
|
||||
n_gpu = get_gpu_count()
|
||||
if n_gpu > 1:
|
||||
distributed_args = f"""
|
||||
-m torch.distributed.launch
|
||||
|
||||
@@ -19,7 +19,13 @@ import unittest
|
||||
|
||||
from parameterized import parameterized
|
||||
from transformers import FSMTForConditionalGeneration, FSMTTokenizer
|
||||
from transformers.testing_utils import get_tests_dir, require_torch, slow, torch_device
|
||||
from transformers.testing_utils import (
|
||||
get_tests_dir,
|
||||
require_torch,
|
||||
require_torch_non_multigpu_but_fix_me,
|
||||
slow,
|
||||
torch_device,
|
||||
)
|
||||
from utils import calculate_bleu
|
||||
|
||||
|
||||
@@ -48,6 +54,7 @@ class ModelEvalTester(unittest.TestCase):
|
||||
]
|
||||
)
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_bleu_scores(self, pair, min_bleu_score):
|
||||
# note: this test is not testing the best performance since it only evals a small batch
|
||||
# but it should be enough to detect a regression in the output quality
|
||||
|
||||
@@ -4,7 +4,7 @@ import unittest
|
||||
from make_student import create_student_by_copying_alternating_layers
|
||||
from transformers import AutoConfig
|
||||
from transformers.file_utils import cached_property
|
||||
from transformers.testing_utils import require_torch
|
||||
from transformers.testing_utils import require_torch, require_torch_non_multigpu_but_fix_me
|
||||
|
||||
|
||||
TINY_BART = "sshleifer/bart-tiny-random"
|
||||
@@ -17,23 +17,28 @@ class MakeStudentTester(unittest.TestCase):
|
||||
def teacher_config(self):
|
||||
return AutoConfig.from_pretrained(TINY_BART)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_valid_t5(self):
|
||||
student, *_ = create_student_by_copying_alternating_layers(TINY_T5, tempfile.mkdtemp(), e=1, d=1)
|
||||
self.assertEqual(student.config.num_hidden_layers, 1)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_asymmetric_t5(self):
|
||||
student, *_ = create_student_by_copying_alternating_layers(TINY_T5, tempfile.mkdtemp(), e=1, d=None)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_same_decoder_small_encoder(self):
|
||||
student, *_ = create_student_by_copying_alternating_layers(TINY_BART, tempfile.mkdtemp(), e=1, d=None)
|
||||
self.assertEqual(student.config.encoder_layers, 1)
|
||||
self.assertEqual(student.config.decoder_layers, self.teacher_config.encoder_layers)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_small_enc_small_dec(self):
|
||||
student, *_ = create_student_by_copying_alternating_layers(TINY_BART, tempfile.mkdtemp(), e=1, d=1)
|
||||
self.assertEqual(student.config.encoder_layers, 1)
|
||||
self.assertEqual(student.config.decoder_layers, 1)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_raises_assert(self):
|
||||
with self.assertRaises(AssertionError):
|
||||
create_student_by_copying_alternating_layers(TINY_BART, tempfile.mkdtemp(), e=None, d=None)
|
||||
|
||||
@@ -19,7 +19,14 @@ from run_eval import generate_summaries_or_translations, run_generate
|
||||
from run_eval_search import run_search
|
||||
from transformers import AutoConfig, AutoModelForSeq2SeqLM
|
||||
from transformers.hf_api import HfApi
|
||||
from transformers.testing_utils import CaptureStderr, CaptureStdout, TestCasePlus, require_torch_gpu, slow
|
||||
from transformers.testing_utils import (
|
||||
CaptureStderr,
|
||||
CaptureStdout,
|
||||
TestCasePlus,
|
||||
require_torch_gpu,
|
||||
require_torch_non_multigpu_but_fix_me,
|
||||
slow,
|
||||
)
|
||||
from utils import ROUGE_KEYS, label_smoothed_nll_loss, lmap, load_json
|
||||
|
||||
|
||||
@@ -126,6 +133,7 @@ class TestSummarizationDistiller(TestCasePlus):
|
||||
|
||||
@slow
|
||||
@require_torch_gpu
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_hub_configs(self):
|
||||
"""I put require_torch_gpu cause I only want this to run with self-scheduled."""
|
||||
|
||||
@@ -143,10 +151,12 @@ class TestSummarizationDistiller(TestCasePlus):
|
||||
failures.append(m)
|
||||
assert not failures, f"The following models could not be loaded through AutoConfig: {failures}"
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_distill_no_teacher(self):
|
||||
updates = dict(student_encoder_layers=2, student_decoder_layers=1, no_teacher=True)
|
||||
self._test_distiller_cli(updates)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_distill_checkpointing_with_teacher(self):
|
||||
updates = dict(
|
||||
student_encoder_layers=2,
|
||||
@@ -171,6 +181,7 @@ class TestSummarizationDistiller(TestCasePlus):
|
||||
convert_pl_to_hf(ckpts[0], transformer_ckpts[0].parent, out_path_new)
|
||||
assert os.path.exists(os.path.join(out_path_new, "pytorch_model.bin"))
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_loss_fn(self):
|
||||
model = AutoModelForSeq2SeqLM.from_pretrained(BART_TINY, return_dict=True)
|
||||
input_ids, mask = model.dummy_inputs["input_ids"], model.dummy_inputs["attention_mask"]
|
||||
@@ -191,6 +202,7 @@ class TestSummarizationDistiller(TestCasePlus):
|
||||
# TODO: understand why this breaks
|
||||
self.assertEqual(nll_loss, model_computed_loss)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_distill_mbart(self):
|
||||
updates = dict(
|
||||
student_encoder_layers=2,
|
||||
@@ -215,6 +227,7 @@ class TestSummarizationDistiller(TestCasePlus):
|
||||
assert len(all_files) > 2
|
||||
self.assertEqual(len(transformer_ckpts), 2)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_distill_t5(self):
|
||||
updates = dict(
|
||||
student_encoder_layers=1,
|
||||
@@ -296,18 +309,21 @@ class TestTheRest(TestCasePlus):
|
||||
|
||||
# test one model to quickly (no-@slow) catch simple problems and do an
|
||||
# extensive testing of functionality with multiple models as @slow separately
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_eval(self):
|
||||
self.run_eval_tester(T5_TINY)
|
||||
|
||||
# any extra models should go into the list here - can be slow
|
||||
@parameterized.expand([BART_TINY, MBART_TINY])
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_eval_slow(self, model):
|
||||
self.run_eval_tester(model)
|
||||
|
||||
# testing with 2 models to validate: 1. translation (t5) 2. summarization (mbart)
|
||||
@parameterized.expand([T5_TINY, MBART_TINY])
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_eval_search(self, model):
|
||||
input_file_name = Path(self.get_auto_remove_tmp_dir()) / "utest_input.source"
|
||||
output_file_name = input_file_name.parent / "utest_output.txt"
|
||||
@@ -358,6 +374,7 @@ class TestTheRest(TestCasePlus):
|
||||
@parameterized.expand(
|
||||
[T5_TINY, BART_TINY, MBART_TINY, MARIAN_TINY, FSMT_TINY],
|
||||
)
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_finetune(self, model):
|
||||
args_d: dict = CHEAP_ARGS.copy()
|
||||
task = "translation" if model in [MBART_TINY, MARIAN_TINY, FSMT_TINY] else "summarization"
|
||||
@@ -409,6 +426,7 @@ class TestTheRest(TestCasePlus):
|
||||
assert isinstance(example_batch, dict)
|
||||
assert len(example_batch) >= 4
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_finetune_extra_model_args(self):
|
||||
args_d: dict = CHEAP_ARGS.copy()
|
||||
|
||||
@@ -459,6 +477,7 @@ class TestTheRest(TestCasePlus):
|
||||
model = main(args)
|
||||
assert str(excinfo.value) == f"model config doesn't have a `{unsupported_param}` attribute"
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_finetune_lr_schedulers(self):
|
||||
args_d: dict = CHEAP_ARGS.copy()
|
||||
|
||||
|
||||
@@ -3,7 +3,14 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
from transformers.testing_utils import TestCasePlus, execute_subprocess_async, require_torch_multigpu
|
||||
from transformers.testing_utils import (
|
||||
TestCasePlus,
|
||||
execute_subprocess_async,
|
||||
get_gpu_count,
|
||||
require_torch_gpu,
|
||||
require_torch_multigpu,
|
||||
slow,
|
||||
)
|
||||
|
||||
from .test_seq2seq_examples import CHEAP_ARGS, make_test_data_dir
|
||||
from .utils import load_json
|
||||
@@ -80,3 +87,30 @@ class TestSummarizationDistillerMultiGPU(TestCasePlus):
|
||||
self.assertEqual(len(metrics["test"]), 1)
|
||||
desired_n_evals = int(args_d["max_epochs"] * (1 / args_d["val_check_interval"]) / 2 + 1)
|
||||
self.assertEqual(len(metrics["val"]), desired_n_evals)
|
||||
|
||||
@slow
|
||||
@require_torch_gpu
|
||||
def test_distributed_eval(self):
|
||||
output_dir = self.get_auto_remove_tmp_dir()
|
||||
args = f"""
|
||||
--model_name Helsinki-NLP/opus-mt-en-ro
|
||||
--save_dir {output_dir}
|
||||
--data_dir {self.test_file_dir_str}/test_data/wmt_en_ro
|
||||
--num_beams 2
|
||||
--task translation
|
||||
""".split()
|
||||
|
||||
# we want this test to run even if there is only one GPU, but if there are more we use them all
|
||||
n_gpu = get_gpu_count()
|
||||
distributed_args = f"""
|
||||
-m torch.distributed.launch
|
||||
--nproc_per_node={n_gpu}
|
||||
{self.test_file_dir}/run_distributed_eval.py
|
||||
""".split()
|
||||
cmd = [sys.executable] + distributed_args + args
|
||||
execute_subprocess_async(cmd, env=self.get_env())
|
||||
|
||||
metrics_save_path = os.path.join(output_dir, "test_bleu.json")
|
||||
metrics = load_json(metrics_save_path)
|
||||
# print(metrics)
|
||||
self.assertGreaterEqual(metrics["bleu"], 25)
|
||||
|
||||
@@ -4,7 +4,7 @@ import unittest
|
||||
|
||||
from transformers.convert_marian_tatoeba_to_pytorch import DEFAULT_REPO, TatoebaConverter
|
||||
from transformers.file_utils import cached_property
|
||||
from transformers.testing_utils import slow
|
||||
from transformers.testing_utils import require_torch_non_multigpu_but_fix_me, slow
|
||||
|
||||
|
||||
@unittest.skipUnless(os.path.exists(DEFAULT_REPO), "Tatoeba directory does not exist.")
|
||||
@@ -15,10 +15,12 @@ class TatoebaConversionTester(unittest.TestCase):
|
||||
return TatoebaConverter(save_dir=tmp_dir)
|
||||
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_resolver(self):
|
||||
self.resolver.convert_models(["heb-eng"])
|
||||
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_model_card(self):
|
||||
content, mmeta = self.resolver.write_model_card("opus-mt-he-en", dry_run=True)
|
||||
assert mmeta["long_pair"] == "heb-eng"
|
||||
|
||||
@@ -2,6 +2,7 @@
|
||||
export PYTHONPATH="../":"${PYTHONPATH}"
|
||||
python distillation.py \
|
||||
--teacher facebook/bart-large-xsum --data_dir xsum \
|
||||
--tokenizer_name facebook/bart-large-xsum \
|
||||
--student_decoder_layers 6 --student_encoder_layers 12 \
|
||||
--freeze_encoder --freeze_embeds \
|
||||
--learning_rate=3e-4 \
|
||||
|
||||
@@ -269,7 +269,7 @@ class Seq2SeqDataCollator:
|
||||
), f"pad_token_id is not defined for ({self.tokenizer.__class__.__name__}), it must be defined."
|
||||
self.data_args = data_args
|
||||
self.tpu_num_cores = tpu_num_cores
|
||||
self.dataset_kwargs = {"add_prefix_space": isinstance(tokenizer, BartTokenizer)}
|
||||
self.dataset_kwargs = {"add_prefix_space": True} if isinstance(tokenizer, BartTokenizer) else {}
|
||||
if data_args.src_lang is not None:
|
||||
self.dataset_kwargs["src_lang"] = data_args.src_lang
|
||||
if data_args.tgt_lang is not None:
|
||||
|
||||
@@ -23,12 +23,18 @@ from unittest.mock import patch
|
||||
import torch
|
||||
|
||||
from transformers.file_utils import is_apex_available
|
||||
from transformers.testing_utils import TestCasePlus, torch_device
|
||||
from transformers.testing_utils import TestCasePlus, require_torch_non_multigpu_but_fix_me, torch_device
|
||||
|
||||
|
||||
SRC_DIRS = [
|
||||
os.path.join(os.path.dirname(__file__), dirname)
|
||||
for dirname in ["text-generation", "text-classification", "language-modeling", "question-answering"]
|
||||
for dirname in [
|
||||
"text-generation",
|
||||
"text-classification",
|
||||
"token-classification",
|
||||
"language-modeling",
|
||||
"question-answering",
|
||||
]
|
||||
]
|
||||
sys.path.extend(SRC_DIRS)
|
||||
|
||||
@@ -38,6 +44,7 @@ if SRC_DIRS is not None:
|
||||
import run_generation
|
||||
import run_glue
|
||||
import run_mlm
|
||||
import run_ner
|
||||
import run_pl_glue
|
||||
import run_squad
|
||||
|
||||
@@ -60,6 +67,7 @@ def is_cuda_and_apex_available():
|
||||
|
||||
|
||||
class ExamplesTests(TestCasePlus):
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_glue(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
@@ -92,6 +100,7 @@ class ExamplesTests(TestCasePlus):
|
||||
for value in result.values():
|
||||
self.assertGreaterEqual(value, 0.75)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_pl_glue(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
@@ -129,6 +138,7 @@ class ExamplesTests(TestCasePlus):
|
||||
# self.assertGreaterEqual(v, 0.75, f"({k})")
|
||||
#
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_clm(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
@@ -160,6 +170,7 @@ class ExamplesTests(TestCasePlus):
|
||||
result = run_clm.main()
|
||||
self.assertLess(result["perplexity"], 100)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_mlm(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
@@ -185,6 +196,38 @@ class ExamplesTests(TestCasePlus):
|
||||
result = run_mlm.main()
|
||||
self.assertLess(result["perplexity"], 42)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_ner(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
|
||||
tmp_dir = self.get_auto_remove_tmp_dir()
|
||||
testargs = f"""
|
||||
run_ner.py
|
||||
--model_name_or_path bert-base-uncased
|
||||
--train_file tests/fixtures/tests_samples/conll/sample.json
|
||||
--validation_file tests/fixtures/tests_samples/conll/sample.json
|
||||
--output_dir {tmp_dir}
|
||||
--overwrite_output_dir
|
||||
--do_train
|
||||
--do_eval
|
||||
--warmup_steps=2
|
||||
--learning_rate=2e-4
|
||||
--per_gpu_train_batch_size=2
|
||||
--per_gpu_eval_batch_size=2
|
||||
--num_train_epochs=2
|
||||
""".split()
|
||||
|
||||
if torch_device != "cuda":
|
||||
testargs.append("--no_cuda")
|
||||
|
||||
with patch.object(sys, "argv", testargs):
|
||||
result = run_ner.main()
|
||||
self.assertGreaterEqual(result["eval_accuracy_score"], 0.75)
|
||||
self.assertGreaterEqual(result["eval_precision"], 0.75)
|
||||
self.assertLess(result["eval_loss"], 0.5)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_squad(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
@@ -213,6 +256,7 @@ class ExamplesTests(TestCasePlus):
|
||||
self.assertGreaterEqual(result["f1"], 25)
|
||||
self.assertGreaterEqual(result["exact"], 21)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_generation(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
|
||||
@@ -20,7 +20,7 @@ import unittest
|
||||
from time import time
|
||||
from unittest.mock import patch
|
||||
|
||||
from transformers.testing_utils import require_torch_tpu
|
||||
from transformers.testing_utils import require_torch_non_multigpu_but_fix_me, require_torch_tpu
|
||||
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
@@ -30,6 +30,7 @@ logger = logging.getLogger()
|
||||
|
||||
@require_torch_tpu
|
||||
class TorchXLAExamplesTests(unittest.TestCase):
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_glue(self):
|
||||
import xla_spawn
|
||||
|
||||
@@ -81,6 +82,7 @@ class TorchXLAExamplesTests(unittest.TestCase):
|
||||
# Assert that the script takes less than 300 seconds to make sure it doesn't hang.
|
||||
self.assertLess(end - start, 500)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_trainer_tpu(self):
|
||||
import xla_spawn
|
||||
|
||||
|
||||
@@ -1,6 +1,40 @@
|
||||
## Named Entity Recognition
|
||||
## Token classification
|
||||
|
||||
Based on the scripts [`run_ner.py`](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py) for Pytorch and
|
||||
Fine-tuning the library models for token classification task such as Named Entity Recognition (NER) or Parts-of-speech
|
||||
tagging (POS). The main scrip `run_ner.py` leverages the 🤗 Datasets library and the Trainer API. You can easily
|
||||
customize it to your needs if you need extra processing on your datasets.
|
||||
|
||||
It will either run on a datasets hosted on our [hub](https://huggingface.co/datasets) or with your own text files for
|
||||
training and validation.
|
||||
|
||||
The following example fine-tunes BERT on CoNLL-2003:
|
||||
|
||||
```bash
|
||||
python run_ner.py \
|
||||
--model_name_or_path bert-base-uncased \
|
||||
--dataset_name conll2003 \
|
||||
--output_dir /tmp/test-ner \
|
||||
--do_train \
|
||||
--do_eval
|
||||
```
|
||||
|
||||
or just can just run the bash script `run.sh`.
|
||||
|
||||
To run on your own training and validation files, use the following command:
|
||||
|
||||
```bash
|
||||
python run_ner.py \
|
||||
--model_name_or_path bert-base-uncased \
|
||||
--train_file path_to_train_file \
|
||||
--validation_file path_to_validation_file \
|
||||
--output_dir /tmp/test-ner \
|
||||
--do_train \
|
||||
--do_eval
|
||||
```
|
||||
|
||||
## Old version of the script
|
||||
|
||||
Based on the scripts [`run_ner_old.py`](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py) for Pytorch and
|
||||
[`run_tf_ner.py`](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_tf_ner.py) for Tensorflow 2.
|
||||
|
||||
The following examples are covered in this section:
|
||||
@@ -69,7 +103,7 @@ export SEED=1
|
||||
To start training, just run:
|
||||
|
||||
```bash
|
||||
python3 run_ner.py --data_dir ./ \
|
||||
python3 run_ner_old.py --data_dir ./ \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
@@ -87,7 +121,7 @@ If your GPU supports half-precision training, just add the `--fp16` flag. After
|
||||
|
||||
#### JSON-based configuration file
|
||||
|
||||
Instead of passing all parameters via commandline arguments, the `run_ner.py` script also supports reading parameters from a json-based configuration file:
|
||||
Instead of passing all parameters via commandline arguments, the `run_ner_old.py` script also supports reading parameters from a json-based configuration file:
|
||||
|
||||
```json
|
||||
{
|
||||
@@ -106,7 +140,7 @@ Instead of passing all parameters via commandline arguments, the `run_ner.py` sc
|
||||
}
|
||||
```
|
||||
|
||||
It must be saved with a `.json` extension and can be used by running `python3 run_ner.py config.json`.
|
||||
It must be saved with a `.json` extension and can be used by running `python3 run_ner_old.py config.json`.
|
||||
|
||||
#### Evaluation
|
||||
|
||||
@@ -250,7 +284,7 @@ cat data_wnut_17/train.txt data_wnut_17/dev.txt data_wnut_17/test.txt | cut -d "
|
||||
|
||||
#### Run the Pytorch version
|
||||
|
||||
Fine-tuning with the PyTorch version can be started using the `run_ner.py` script. In this example we use a JSON-based configuration file.
|
||||
Fine-tuning with the PyTorch version can be started using the `run_ner_old.py` script. In this example we use a JSON-based configuration file.
|
||||
|
||||
This configuration file looks like:
|
||||
|
||||
@@ -274,7 +308,7 @@ This configuration file looks like:
|
||||
|
||||
If your GPU supports half-precision training, please set `fp16` to `true`.
|
||||
|
||||
Save this JSON-based configuration under `wnut_17.json`. The fine-tuning can be started with `python3 run_ner.py wnut_17.json`.
|
||||
Save this JSON-based configuration under `wnut_17.json`. The fine-tuning can be started with `python3 run_ner_old.py wnut_17.json`.
|
||||
|
||||
#### Evaluation
|
||||
|
||||
|
||||
@@ -1,36 +1,6 @@
|
||||
## The relevant files are currently on a shared Google
|
||||
## drive at https://drive.google.com/drive/folders/1kC0I2UGl2ltrluI9NqDjaQJGw5iliw_J
|
||||
## Monitor for changes and eventually migrate to nlp dataset
|
||||
curl -L 'https://drive.google.com/uc?export=download&id=1Jjhbal535VVz2ap4v4r_rN1UEHTdLK5P' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
|
||||
curl -L 'https://drive.google.com/uc?export=download&id=1ZfRcQThdtAR5PPRjIDtrVP7BtXSCUBbm' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
|
||||
curl -L 'https://drive.google.com/uc?export=download&id=1u9mb7kNJHWQCWyweMDRMuTFoOHOfeBTH' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
|
||||
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
python3 scripts/preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
|
||||
python3 scripts/preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
|
||||
python3 scripts/preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
|
||||
cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
|
||||
python3 run_ner.py \
|
||||
--task_type NER \
|
||||
--data_dir . \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_gpu_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
--model_name_or_path bert-base-uncased \
|
||||
--dataset_name conll2003 \
|
||||
--output_dir /tmp/test-ner \
|
||||
--do_train \
|
||||
--do_eval
|
||||
|
||||
@@ -21,7 +21,7 @@ export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
|
||||
python3 run_ner.py \
|
||||
python3 run_ner_old.py \
|
||||
--task_type Chunk \
|
||||
--data_dir . \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
|
||||
# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
|
||||
# Copyright 2020 The HuggingFace Team All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
@@ -13,29 +12,33 @@
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" Fine-tuning the library models for named entity recognition on CoNLL-2003. """
|
||||
"""
|
||||
Fine-tuning the library models for token classification.
|
||||
"""
|
||||
# You can also adapt this script on your own token classification task and datasets. Pointers for this are left as comments.
|
||||
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from dataclasses import dataclass, field
|
||||
from importlib import import_module
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
from datasets import load_dataset
|
||||
from seqeval.metrics import accuracy_score, f1_score, precision_score, recall_score
|
||||
from torch import nn
|
||||
|
||||
import transformers
|
||||
from transformers import (
|
||||
AutoConfig,
|
||||
AutoModelForTokenClassification,
|
||||
AutoTokenizer,
|
||||
EvalPrediction,
|
||||
DataCollatorForTokenClassification,
|
||||
HfArgumentParser,
|
||||
Trainer,
|
||||
TrainingArguments,
|
||||
set_seed,
|
||||
)
|
||||
from utils_ner import Split, TokenClassificationDataset, TokenClassificationTask
|
||||
from transformers.trainer_utils import is_main_process
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
@@ -53,15 +56,9 @@ class ModelArguments:
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
task_type: Optional[str] = field(
|
||||
default="NER", metadata={"help": "Task type to fine tune in training (e.g. NER, POS, etc)"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
use_fast: bool = field(default=False, metadata={"help": "Set this flag to use fast tokenization."})
|
||||
# If you want to tweak more attributes on your tokenizer, you should do it in a distinct script,
|
||||
# or just modify its tokenizer_config.json.
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
@@ -73,23 +70,58 @@ class DataTrainingArguments:
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
data_dir: str = field(
|
||||
metadata={"help": "The input data dir. Should contain the .txt files for a CoNLL-2003-formatted task."}
|
||||
task_name: Optional[str] = field(default="ner", metadata={"help": "The name of the task (ner, pos...)."})
|
||||
dataset_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
labels: Optional[str] = field(
|
||||
dataset_config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "The configuration name of the dataset to use (via the datasets library)."}
|
||||
)
|
||||
train_file: Optional[str] = field(
|
||||
default=None, metadata={"help": "The input training data file (a csv or JSON file)."}
|
||||
)
|
||||
validation_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "Path to a file containing all labels. If not specified, CoNLL-2003 labels are used."},
|
||||
metadata={"help": "An optional input evaluation data file to evaluate on (a csv or JSON file)."},
|
||||
)
|
||||
max_seq_length: int = field(
|
||||
default=128,
|
||||
metadata={
|
||||
"help": "The maximum total input sequence length after tokenization. Sequences longer "
|
||||
"than this will be truncated, sequences shorter will be padded."
|
||||
},
|
||||
test_file: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "An optional input test data file to predict on (a csv or JSON file)."},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
preprocessing_num_workers: Optional[int] = field(
|
||||
default=None,
|
||||
metadata={"help": "The number of processes to use for the preprocessing."},
|
||||
)
|
||||
pad_to_max_length: bool = field(
|
||||
default=False,
|
||||
metadata={
|
||||
"help": "Whether to pad all samples to model maximum sentence length. "
|
||||
"If False, will pad the samples dynamically when batching to the maximum length in the batch. More "
|
||||
"efficient on GPU but very bad for TPU."
|
||||
},
|
||||
)
|
||||
label_all_tokens: bool = field(
|
||||
default=False,
|
||||
metadata={
|
||||
"help": "Whether to put the label for one word on all tokens of generated by that word or just on the "
|
||||
"one (in which case the other tokens will have a padding index)."
|
||||
},
|
||||
)
|
||||
|
||||
def __post_init__(self):
|
||||
if self.dataset_name is None and self.train_file is None and self.validation_file is None:
|
||||
raise ValueError("Need either a dataset name or a training/validation file.")
|
||||
else:
|
||||
if self.train_file is not None:
|
||||
extension = self.train_file.split(".")[-1]
|
||||
assert extension in ["csv", "json"], "`train_file` should be a csv or a json file."
|
||||
if self.validation_file is not None:
|
||||
extension = self.validation_file.split(".")[-1]
|
||||
assert extension in ["csv", "json"], "`validation_file` should be a csv or a json file."
|
||||
self.task_name = self.task_name.lower()
|
||||
|
||||
|
||||
def main():
|
||||
@@ -112,60 +144,90 @@ def main():
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty. Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
module = import_module("tasks")
|
||||
try:
|
||||
token_classification_task_clazz = getattr(module, model_args.task_type)
|
||||
token_classification_task: TokenClassificationTask = token_classification_task_clazz()
|
||||
except AttributeError:
|
||||
raise ValueError(
|
||||
f"Task {model_args.task_type} needs to be defined as a TokenClassificationTask subclass in {module}. "
|
||||
f"Available tasks classes are: {TokenClassificationTask.__subclasses__()}"
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty."
|
||||
"Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
# Setup logging
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
|
||||
level=logging.INFO if is_main_process(training_args.local_rank) else logging.WARN,
|
||||
)
|
||||
|
||||
# Log on each process the small summary:
|
||||
logger.warning(
|
||||
"Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
|
||||
training_args.local_rank,
|
||||
training_args.device,
|
||||
training_args.n_gpu,
|
||||
bool(training_args.local_rank != -1),
|
||||
training_args.fp16,
|
||||
f"Process rank: {training_args.local_rank}, device: {training_args.device}, n_gpu: {training_args.n_gpu}"
|
||||
+ f"distributed training: {bool(training_args.local_rank != -1)}, 16-bits training: {training_args.fp16}"
|
||||
)
|
||||
# Set the verbosity to info of the Transformers logger (on main process only):
|
||||
if is_main_process(training_args.local_rank):
|
||||
transformers.utils.logging.set_verbosity_info()
|
||||
logger.info("Training/evaluation parameters %s", training_args)
|
||||
|
||||
# Set seed
|
||||
# Set seed before initializing model.
|
||||
set_seed(training_args.seed)
|
||||
|
||||
# Prepare CONLL-2003 task
|
||||
labels = token_classification_task.get_labels(data_args.labels)
|
||||
label_map: Dict[int, str] = {i: label for i, label in enumerate(labels)}
|
||||
num_labels = len(labels)
|
||||
# Get the datasets: you can either provide your own CSV/JSON/TXT training and evaluation files (see below)
|
||||
# or just provide the name of one of the public datasets available on the hub at https://huggingface.co/datasets/
|
||||
# (the dataset will be downloaded automatically from the datasets Hub).
|
||||
#
|
||||
# For CSV/JSON files, this script will use the column called 'text' or the first column if no column called
|
||||
# 'text' is found. You can easily tweak this behavior (see below).
|
||||
#
|
||||
# In distributed training, the load_dataset function guarantee that only one local process can concurrently
|
||||
# download the dataset.
|
||||
if data_args.dataset_name is not None:
|
||||
# Downloading and loading a dataset from the hub.
|
||||
datasets = load_dataset(data_args.dataset_name, data_args.dataset_config_name)
|
||||
else:
|
||||
data_files = {}
|
||||
if data_args.train_file is not None:
|
||||
data_files["train"] = data_args.train_file
|
||||
if data_args.validation_file is not None:
|
||||
data_files["validation"] = data_args.validation_file
|
||||
if data_args.test_file is not None:
|
||||
data_files["test"] = data_args.test_file
|
||||
extension = data_args.train_file.split(".")[-1]
|
||||
datasets = load_dataset(extension, data_files=data_files)
|
||||
# See more about loading any type of standard or custom dataset (from files, python dict, pandas DataFrame, etc) at
|
||||
# https://huggingface.co/docs/datasets/loading_datasets.html.
|
||||
|
||||
if training_args.do_train:
|
||||
column_names = datasets["train"].column_names
|
||||
else:
|
||||
column_names = datasets["validation"].column_names
|
||||
text_column_name = "words" if "words" in column_names else column_names[0]
|
||||
label_column_name = data_args.task_name if data_args.task_name in column_names else column_names[1]
|
||||
|
||||
# Labeling (this part will be easier when https://github.com/huggingface/datasets/issues/797 is solved)
|
||||
def get_label_list(labels):
|
||||
unique_labels = set()
|
||||
for label in labels:
|
||||
unique_labels = unique_labels | set(label)
|
||||
label_list = list(unique_labels)
|
||||
label_list.sort()
|
||||
return label_list
|
||||
|
||||
label_list = get_label_list(datasets["train"][label_column_name])
|
||||
label_to_id = {l: i for i, l in enumerate(label_list)}
|
||||
num_labels = len(label_list)
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
#
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
|
||||
config = AutoConfig.from_pretrained(
|
||||
model_args.config_name if model_args.config_name else model_args.model_name_or_path,
|
||||
num_labels=num_labels,
|
||||
id2label=label_map,
|
||||
label2id={label: i for i, label in enumerate(labels)},
|
||||
finetuning_task=data_args.task_name,
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
|
||||
cache_dir=model_args.cache_dir,
|
||||
use_fast=model_args.use_fast,
|
||||
use_fast=True,
|
||||
)
|
||||
model = AutoModelForTokenClassification.from_pretrained(
|
||||
model_args.model_name_or_path,
|
||||
@@ -174,67 +236,85 @@ def main():
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
|
||||
# Get datasets
|
||||
train_dataset = (
|
||||
TokenClassificationDataset(
|
||||
token_classification_task=token_classification_task,
|
||||
data_dir=data_args.data_dir,
|
||||
tokenizer=tokenizer,
|
||||
labels=labels,
|
||||
model_type=config.model_type,
|
||||
max_seq_length=data_args.max_seq_length,
|
||||
overwrite_cache=data_args.overwrite_cache,
|
||||
mode=Split.train,
|
||||
# Preprocessing the dataset
|
||||
# Padding strategy
|
||||
padding = "max_length" if data_args.pad_to_max_length else False
|
||||
|
||||
# Tokenize all texts and align the labels with them.
|
||||
def tokenize_and_align_labels(examples):
|
||||
tokenized_inputs = tokenizer(
|
||||
examples[text_column_name],
|
||||
padding=padding,
|
||||
truncation=True,
|
||||
# We use this argument because the texts in our dataset are lists of words (with a label for each word).
|
||||
is_split_into_words=True,
|
||||
return_offsets_mapping=True,
|
||||
)
|
||||
if training_args.do_train
|
||||
else None
|
||||
)
|
||||
eval_dataset = (
|
||||
TokenClassificationDataset(
|
||||
token_classification_task=token_classification_task,
|
||||
data_dir=data_args.data_dir,
|
||||
tokenizer=tokenizer,
|
||||
labels=labels,
|
||||
model_type=config.model_type,
|
||||
max_seq_length=data_args.max_seq_length,
|
||||
overwrite_cache=data_args.overwrite_cache,
|
||||
mode=Split.dev,
|
||||
)
|
||||
if training_args.do_eval
|
||||
else None
|
||||
offset_mappings = tokenized_inputs.pop("offset_mapping")
|
||||
labels = []
|
||||
for label, offset_mapping in zip(examples[label_column_name], offset_mappings):
|
||||
label_index = 0
|
||||
current_label = -100
|
||||
label_ids = []
|
||||
for offset in offset_mapping:
|
||||
# We set the label for the first token of each word. Special characters will have an offset of (0, 0)
|
||||
# so the test ignores them.
|
||||
if offset[0] == 0 and offset[1] != 0:
|
||||
current_label = label_to_id[label[label_index]]
|
||||
label_index += 1
|
||||
label_ids.append(current_label)
|
||||
# For special tokens, we set the label to -100 so it's automatically ignored in the loss function.
|
||||
elif offset[0] == 0 and offset[1] == 0:
|
||||
label_ids.append(-100)
|
||||
# For the other tokens in a word, we set the label to either the current label or -100, depending on
|
||||
# the label_all_tokens flag.
|
||||
else:
|
||||
label_ids.append(current_label if data_args.label_all_tokens else -100)
|
||||
|
||||
labels.append(label_ids)
|
||||
tokenized_inputs["labels"] = labels
|
||||
return tokenized_inputs
|
||||
|
||||
tokenized_datasets = datasets.map(
|
||||
tokenize_and_align_labels,
|
||||
batched=True,
|
||||
num_proc=data_args.preprocessing_num_workers,
|
||||
load_from_cache_file=not data_args.overwrite_cache,
|
||||
)
|
||||
|
||||
def align_predictions(predictions: np.ndarray, label_ids: np.ndarray) -> Tuple[List[int], List[int]]:
|
||||
preds = np.argmax(predictions, axis=2)
|
||||
# Data collator
|
||||
data_collator = DataCollatorForTokenClassification(tokenizer)
|
||||
|
||||
batch_size, seq_len = preds.shape
|
||||
# Metrics
|
||||
def compute_metrics(p):
|
||||
predictions, labels = p
|
||||
predictions = np.argmax(predictions, axis=2)
|
||||
|
||||
out_label_list = [[] for _ in range(batch_size)]
|
||||
preds_list = [[] for _ in range(batch_size)]
|
||||
# Remove ignored index (special tokens)
|
||||
true_predictions = [
|
||||
[label_list[p] for (p, l) in zip(prediction, label) if l != -100]
|
||||
for prediction, label in zip(predictions, labels)
|
||||
]
|
||||
true_labels = [
|
||||
[label_list[l] for (p, l) in zip(prediction, label) if l != -100]
|
||||
for prediction, label in zip(predictions, labels)
|
||||
]
|
||||
|
||||
for i in range(batch_size):
|
||||
for j in range(seq_len):
|
||||
if label_ids[i, j] != nn.CrossEntropyLoss().ignore_index:
|
||||
out_label_list[i].append(label_map[label_ids[i][j]])
|
||||
preds_list[i].append(label_map[preds[i][j]])
|
||||
|
||||
return preds_list, out_label_list
|
||||
|
||||
def compute_metrics(p: EvalPrediction) -> Dict:
|
||||
preds_list, out_label_list = align_predictions(p.predictions, p.label_ids)
|
||||
return {
|
||||
"accuracy_score": accuracy_score(out_label_list, preds_list),
|
||||
"precision": precision_score(out_label_list, preds_list),
|
||||
"recall": recall_score(out_label_list, preds_list),
|
||||
"f1": f1_score(out_label_list, preds_list),
|
||||
"accuracy_score": accuracy_score(true_labels, true_predictions),
|
||||
"precision": precision_score(true_labels, true_predictions),
|
||||
"recall": recall_score(true_labels, true_predictions),
|
||||
"f1": f1_score(true_labels, true_predictions),
|
||||
}
|
||||
|
||||
# Initialize our Trainer
|
||||
trainer = Trainer(
|
||||
model=model,
|
||||
args=training_args,
|
||||
train_dataset=train_dataset,
|
||||
eval_dataset=eval_dataset,
|
||||
train_dataset=tokenized_datasets["train"] if training_args.do_train else None,
|
||||
eval_dataset=tokenized_datasets["validation"] if training_args.do_eval else None,
|
||||
tokenizer=tokenizer,
|
||||
data_collator=data_collator,
|
||||
compute_metrics=compute_metrics,
|
||||
)
|
||||
|
||||
@@ -243,58 +323,50 @@ def main():
|
||||
trainer.train(
|
||||
model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
|
||||
)
|
||||
trainer.save_model()
|
||||
# For convenience, we also re-save the tokenizer to the same directory,
|
||||
# so that you can share your model easily on huggingface.co/models =)
|
||||
if trainer.is_world_master():
|
||||
tokenizer.save_pretrained(training_args.output_dir)
|
||||
trainer.save_model() # Saves the tokenizer too for easy upload
|
||||
|
||||
# Evaluation
|
||||
results = {}
|
||||
if training_args.do_eval:
|
||||
logger.info("*** Evaluate ***")
|
||||
|
||||
result = trainer.evaluate()
|
||||
results = trainer.evaluate()
|
||||
|
||||
output_eval_file = os.path.join(training_args.output_dir, "eval_results.txt")
|
||||
if trainer.is_world_master():
|
||||
output_eval_file = os.path.join(training_args.output_dir, "eval_results_ner.txt")
|
||||
if trainer.is_world_process_zero():
|
||||
with open(output_eval_file, "w") as writer:
|
||||
logger.info("***** Eval results *****")
|
||||
for key, value in result.items():
|
||||
logger.info(" %s = %s", key, value)
|
||||
writer.write("%s = %s\n" % (key, value))
|
||||
|
||||
results.update(result)
|
||||
for key, value in results.items():
|
||||
logger.info(f" {key} = {value}")
|
||||
writer.write(f"{key} = {value}\n")
|
||||
|
||||
# Predict
|
||||
if training_args.do_predict:
|
||||
test_dataset = TokenClassificationDataset(
|
||||
token_classification_task=token_classification_task,
|
||||
data_dir=data_args.data_dir,
|
||||
tokenizer=tokenizer,
|
||||
labels=labels,
|
||||
model_type=config.model_type,
|
||||
max_seq_length=data_args.max_seq_length,
|
||||
overwrite_cache=data_args.overwrite_cache,
|
||||
mode=Split.test,
|
||||
)
|
||||
logger.info("*** Predict ***")
|
||||
|
||||
predictions, label_ids, metrics = trainer.predict(test_dataset)
|
||||
preds_list, _ = align_predictions(predictions, label_ids)
|
||||
test_dataset = datasets["test"]
|
||||
predictions, labels, metrics = trainer.predict(test_dataset)
|
||||
predictions = np.argmax(predictions, axis=2)
|
||||
|
||||
# Remove ignored index (special tokens)
|
||||
true_predictions = [
|
||||
[label_list[p] for (p, l) in zip(prediction, label) if l != -100]
|
||||
for prediction, label in zip(predictions, labels)
|
||||
]
|
||||
|
||||
output_test_results_file = os.path.join(training_args.output_dir, "test_results.txt")
|
||||
if trainer.is_world_master():
|
||||
with open(output_test_results_file, "w") as writer:
|
||||
for key, value in metrics.items():
|
||||
logger.info(" %s = %s", key, value)
|
||||
writer.write("%s = %s\n" % (key, value))
|
||||
logger.info(f" {key} = {value}")
|
||||
writer.write(f"{key} = {value}\n")
|
||||
|
||||
# Save predictions
|
||||
output_test_predictions_file = os.path.join(training_args.output_dir, "test_predictions.txt")
|
||||
if trainer.is_world_master():
|
||||
with open(output_test_predictions_file, "w") as writer:
|
||||
with open(os.path.join(data_args.data_dir, "test.txt"), "r") as f:
|
||||
token_classification_task.write_predictions_to_file(writer, f, preds_list)
|
||||
for prediction in true_predictions:
|
||||
writer.write(" ".join(prediction) + "\n")
|
||||
|
||||
return results
|
||||
|
||||
|
||||
@@ -0,0 +1,308 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
|
||||
# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" Fine-tuning the library models for named entity recognition on CoNLL-2003. """
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from dataclasses import dataclass, field
|
||||
from importlib import import_module
|
||||
from typing import Dict, List, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
from seqeval.metrics import accuracy_score, f1_score, precision_score, recall_score
|
||||
from torch import nn
|
||||
|
||||
from transformers import (
|
||||
AutoConfig,
|
||||
AutoModelForTokenClassification,
|
||||
AutoTokenizer,
|
||||
EvalPrediction,
|
||||
HfArgumentParser,
|
||||
Trainer,
|
||||
TrainingArguments,
|
||||
set_seed,
|
||||
)
|
||||
from utils_ner import Split, TokenClassificationDataset, TokenClassificationTask
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ModelArguments:
|
||||
"""
|
||||
Arguments pertaining to which model/config/tokenizer we are going to fine-tune from.
|
||||
"""
|
||||
|
||||
model_name_or_path: str = field(
|
||||
metadata={"help": "Path to pretrained model or model identifier from huggingface.co/models"}
|
||||
)
|
||||
config_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained config name or path if not the same as model_name"}
|
||||
)
|
||||
task_type: Optional[str] = field(
|
||||
default="NER", metadata={"help": "Task type to fine tune in training (e.g. NER, POS, etc)"}
|
||||
)
|
||||
tokenizer_name: Optional[str] = field(
|
||||
default=None, metadata={"help": "Pretrained tokenizer name or path if not the same as model_name"}
|
||||
)
|
||||
use_fast: bool = field(default=False, metadata={"help": "Set this flag to use fast tokenization."})
|
||||
# If you want to tweak more attributes on your tokenizer, you should do it in a distinct script,
|
||||
# or just modify its tokenizer_config.json.
|
||||
cache_dir: Optional[str] = field(
|
||||
default=None, metadata={"help": "Where do you want to store the pretrained models downloaded from s3"}
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DataTrainingArguments:
|
||||
"""
|
||||
Arguments pertaining to what data we are going to input our model for training and eval.
|
||||
"""
|
||||
|
||||
data_dir: str = field(
|
||||
metadata={"help": "The input data dir. Should contain the .txt files for a CoNLL-2003-formatted task."}
|
||||
)
|
||||
labels: Optional[str] = field(
|
||||
default=None,
|
||||
metadata={"help": "Path to a file containing all labels. If not specified, CoNLL-2003 labels are used."},
|
||||
)
|
||||
max_seq_length: int = field(
|
||||
default=128,
|
||||
metadata={
|
||||
"help": "The maximum total input sequence length after tokenization. Sequences longer "
|
||||
"than this will be truncated, sequences shorter will be padded."
|
||||
},
|
||||
)
|
||||
overwrite_cache: bool = field(
|
||||
default=False, metadata={"help": "Overwrite the cached training and evaluation sets"}
|
||||
)
|
||||
|
||||
|
||||
def main():
|
||||
# See all possible arguments in src/transformers/training_args.py
|
||||
# or by passing the --help flag to this script.
|
||||
# We now keep distinct sets of args, for a cleaner separation of concerns.
|
||||
|
||||
parser = HfArgumentParser((ModelArguments, DataTrainingArguments, TrainingArguments))
|
||||
if len(sys.argv) == 2 and sys.argv[1].endswith(".json"):
|
||||
# If we pass only one argument to the script and it's the path to a json file,
|
||||
# let's parse it to get our arguments.
|
||||
model_args, data_args, training_args = parser.parse_json_file(json_file=os.path.abspath(sys.argv[1]))
|
||||
else:
|
||||
model_args, data_args, training_args = parser.parse_args_into_dataclasses()
|
||||
|
||||
if (
|
||||
os.path.exists(training_args.output_dir)
|
||||
and os.listdir(training_args.output_dir)
|
||||
and training_args.do_train
|
||||
and not training_args.overwrite_output_dir
|
||||
):
|
||||
raise ValueError(
|
||||
f"Output directory ({training_args.output_dir}) already exists and is not empty. Use --overwrite_output_dir to overcome."
|
||||
)
|
||||
|
||||
module = import_module("tasks")
|
||||
try:
|
||||
token_classification_task_clazz = getattr(module, model_args.task_type)
|
||||
token_classification_task: TokenClassificationTask = token_classification_task_clazz()
|
||||
except AttributeError:
|
||||
raise ValueError(
|
||||
f"Task {model_args.task_type} needs to be defined as a TokenClassificationTask subclass in {module}. "
|
||||
f"Available tasks classes are: {TokenClassificationTask.__subclasses__()}"
|
||||
)
|
||||
|
||||
# Setup logging
|
||||
logging.basicConfig(
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO if training_args.local_rank in [-1, 0] else logging.WARN,
|
||||
)
|
||||
logger.warning(
|
||||
"Process rank: %s, device: %s, n_gpu: %s, distributed training: %s, 16-bits training: %s",
|
||||
training_args.local_rank,
|
||||
training_args.device,
|
||||
training_args.n_gpu,
|
||||
bool(training_args.local_rank != -1),
|
||||
training_args.fp16,
|
||||
)
|
||||
logger.info("Training/evaluation parameters %s", training_args)
|
||||
|
||||
# Set seed
|
||||
set_seed(training_args.seed)
|
||||
|
||||
# Prepare CONLL-2003 task
|
||||
labels = token_classification_task.get_labels(data_args.labels)
|
||||
label_map: Dict[int, str] = {i: label for i, label in enumerate(labels)}
|
||||
num_labels = len(labels)
|
||||
|
||||
# Load pretrained model and tokenizer
|
||||
#
|
||||
# Distributed training:
|
||||
# The .from_pretrained methods guarantee that only one local process can concurrently
|
||||
# download model & vocab.
|
||||
|
||||
config = AutoConfig.from_pretrained(
|
||||
model_args.config_name if model_args.config_name else model_args.model_name_or_path,
|
||||
num_labels=num_labels,
|
||||
id2label=label_map,
|
||||
label2id={label: i for i, label in enumerate(labels)},
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
model_args.tokenizer_name if model_args.tokenizer_name else model_args.model_name_or_path,
|
||||
cache_dir=model_args.cache_dir,
|
||||
use_fast=model_args.use_fast,
|
||||
)
|
||||
model = AutoModelForTokenClassification.from_pretrained(
|
||||
model_args.model_name_or_path,
|
||||
from_tf=bool(".ckpt" in model_args.model_name_or_path),
|
||||
config=config,
|
||||
cache_dir=model_args.cache_dir,
|
||||
)
|
||||
|
||||
# Get datasets
|
||||
train_dataset = (
|
||||
TokenClassificationDataset(
|
||||
token_classification_task=token_classification_task,
|
||||
data_dir=data_args.data_dir,
|
||||
tokenizer=tokenizer,
|
||||
labels=labels,
|
||||
model_type=config.model_type,
|
||||
max_seq_length=data_args.max_seq_length,
|
||||
overwrite_cache=data_args.overwrite_cache,
|
||||
mode=Split.train,
|
||||
)
|
||||
if training_args.do_train
|
||||
else None
|
||||
)
|
||||
eval_dataset = (
|
||||
TokenClassificationDataset(
|
||||
token_classification_task=token_classification_task,
|
||||
data_dir=data_args.data_dir,
|
||||
tokenizer=tokenizer,
|
||||
labels=labels,
|
||||
model_type=config.model_type,
|
||||
max_seq_length=data_args.max_seq_length,
|
||||
overwrite_cache=data_args.overwrite_cache,
|
||||
mode=Split.dev,
|
||||
)
|
||||
if training_args.do_eval
|
||||
else None
|
||||
)
|
||||
|
||||
def align_predictions(predictions: np.ndarray, label_ids: np.ndarray) -> Tuple[List[int], List[int]]:
|
||||
preds = np.argmax(predictions, axis=2)
|
||||
|
||||
batch_size, seq_len = preds.shape
|
||||
|
||||
out_label_list = [[] for _ in range(batch_size)]
|
||||
preds_list = [[] for _ in range(batch_size)]
|
||||
|
||||
for i in range(batch_size):
|
||||
for j in range(seq_len):
|
||||
if label_ids[i, j] != nn.CrossEntropyLoss().ignore_index:
|
||||
out_label_list[i].append(label_map[label_ids[i][j]])
|
||||
preds_list[i].append(label_map[preds[i][j]])
|
||||
|
||||
return preds_list, out_label_list
|
||||
|
||||
def compute_metrics(p: EvalPrediction) -> Dict:
|
||||
preds_list, out_label_list = align_predictions(p.predictions, p.label_ids)
|
||||
return {
|
||||
"accuracy_score": accuracy_score(out_label_list, preds_list),
|
||||
"precision": precision_score(out_label_list, preds_list),
|
||||
"recall": recall_score(out_label_list, preds_list),
|
||||
"f1": f1_score(out_label_list, preds_list),
|
||||
}
|
||||
|
||||
# Initialize our Trainer
|
||||
trainer = Trainer(
|
||||
model=model,
|
||||
args=training_args,
|
||||
train_dataset=train_dataset,
|
||||
eval_dataset=eval_dataset,
|
||||
compute_metrics=compute_metrics,
|
||||
)
|
||||
|
||||
# Training
|
||||
if training_args.do_train:
|
||||
trainer.train(
|
||||
model_path=model_args.model_name_or_path if os.path.isdir(model_args.model_name_or_path) else None
|
||||
)
|
||||
trainer.save_model()
|
||||
# For convenience, we also re-save the tokenizer to the same directory,
|
||||
# so that you can share your model easily on huggingface.co/models =)
|
||||
if trainer.is_world_master():
|
||||
tokenizer.save_pretrained(training_args.output_dir)
|
||||
|
||||
# Evaluation
|
||||
results = {}
|
||||
if training_args.do_eval:
|
||||
logger.info("*** Evaluate ***")
|
||||
|
||||
result = trainer.evaluate()
|
||||
|
||||
output_eval_file = os.path.join(training_args.output_dir, "eval_results.txt")
|
||||
if trainer.is_world_master():
|
||||
with open(output_eval_file, "w") as writer:
|
||||
logger.info("***** Eval results *****")
|
||||
for key, value in result.items():
|
||||
logger.info(" %s = %s", key, value)
|
||||
writer.write("%s = %s\n" % (key, value))
|
||||
|
||||
results.update(result)
|
||||
|
||||
# Predict
|
||||
if training_args.do_predict:
|
||||
test_dataset = TokenClassificationDataset(
|
||||
token_classification_task=token_classification_task,
|
||||
data_dir=data_args.data_dir,
|
||||
tokenizer=tokenizer,
|
||||
labels=labels,
|
||||
model_type=config.model_type,
|
||||
max_seq_length=data_args.max_seq_length,
|
||||
overwrite_cache=data_args.overwrite_cache,
|
||||
mode=Split.test,
|
||||
)
|
||||
|
||||
predictions, label_ids, metrics = trainer.predict(test_dataset)
|
||||
preds_list, _ = align_predictions(predictions, label_ids)
|
||||
|
||||
output_test_results_file = os.path.join(training_args.output_dir, "test_results.txt")
|
||||
if trainer.is_world_master():
|
||||
with open(output_test_results_file, "w") as writer:
|
||||
for key, value in metrics.items():
|
||||
logger.info(" %s = %s", key, value)
|
||||
writer.write("%s = %s\n" % (key, value))
|
||||
|
||||
# Save predictions
|
||||
output_test_predictions_file = os.path.join(training_args.output_dir, "test_predictions.txt")
|
||||
if trainer.is_world_master():
|
||||
with open(output_test_predictions_file, "w") as writer:
|
||||
with open(os.path.join(data_args.data_dir, "test.txt"), "r") as f:
|
||||
token_classification_task.write_predictions_to_file(writer, f, preds_list)
|
||||
|
||||
return results
|
||||
|
||||
|
||||
def _mp_fn(index):
|
||||
# For xla_spawn (TPUs)
|
||||
main()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
Executable
+36
@@ -0,0 +1,36 @@
|
||||
## The relevant files are currently on a shared Google
|
||||
## drive at https://drive.google.com/drive/folders/1kC0I2UGl2ltrluI9NqDjaQJGw5iliw_J
|
||||
## Monitor for changes and eventually migrate to nlp dataset
|
||||
curl -L 'https://drive.google.com/uc?export=download&id=1Jjhbal535VVz2ap4v4r_rN1UEHTdLK5P' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > train.txt.tmp
|
||||
curl -L 'https://drive.google.com/uc?export=download&id=1ZfRcQThdtAR5PPRjIDtrVP7BtXSCUBbm' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > dev.txt.tmp
|
||||
curl -L 'https://drive.google.com/uc?export=download&id=1u9mb7kNJHWQCWyweMDRMuTFoOHOfeBTH' \
|
||||
| grep -v "^#" | cut -f 2,3 | tr '\t' ' ' > test.txt.tmp
|
||||
|
||||
export MAX_LENGTH=128
|
||||
export BERT_MODEL=bert-base-multilingual-cased
|
||||
python3 scripts/preprocess.py train.txt.tmp $BERT_MODEL $MAX_LENGTH > train.txt
|
||||
python3 scripts/preprocess.py dev.txt.tmp $BERT_MODEL $MAX_LENGTH > dev.txt
|
||||
python3 scripts/preprocess.py test.txt.tmp $BERT_MODEL $MAX_LENGTH > test.txt
|
||||
cat train.txt dev.txt test.txt | cut -d " " -f 2 | grep -v "^$"| sort | uniq > labels.txt
|
||||
export OUTPUT_DIR=germeval-model
|
||||
export BATCH_SIZE=32
|
||||
export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
|
||||
python3 run_ner_old.py \
|
||||
--task_type NER \
|
||||
--data_dir . \
|
||||
--labels ./labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
--output_dir $OUTPUT_DIR \
|
||||
--max_seq_length $MAX_LENGTH \
|
||||
--num_train_epochs $NUM_EPOCHS \
|
||||
--per_gpu_train_batch_size $BATCH_SIZE \
|
||||
--save_steps $SAVE_STEPS \
|
||||
--seed $SEED \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_predict
|
||||
@@ -21,7 +21,7 @@ export NUM_EPOCHS=3
|
||||
export SAVE_STEPS=750
|
||||
export SEED=1
|
||||
|
||||
python3 run_ner.py \
|
||||
python3 run_ner_old.py \
|
||||
--task_type POS \
|
||||
--data_dir . \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
|
||||
@@ -3,8 +3,8 @@ import sys
|
||||
import unittest
|
||||
from unittest.mock import patch
|
||||
|
||||
import run_ner
|
||||
from transformers.testing_utils import slow
|
||||
import run_ner_old as run_ner
|
||||
from transformers.testing_utils import require_torch_non_multigpu_but_fix_me, slow
|
||||
|
||||
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
@@ -14,6 +14,7 @@ logger = logging.getLogger()
|
||||
|
||||
class ExamplesTests(unittest.TestCase):
|
||||
@slow
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_ner(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
@@ -34,6 +35,7 @@ class ExamplesTests(unittest.TestCase):
|
||||
result = run_ner.main()
|
||||
self.assertLess(result["eval_loss"], 1.5)
|
||||
|
||||
@require_torch_non_multigpu_but_fix_me
|
||||
def test_run_ner_pl(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
|
||||
@@ -66,14 +66,16 @@ class Split(Enum):
|
||||
|
||||
|
||||
class TokenClassificationTask:
|
||||
def read_examples_from_file(self, data_dir, mode: Union[Split, str]) -> List[InputExample]:
|
||||
@staticmethod
|
||||
def read_examples_from_file(data_dir, mode: Union[Split, str]) -> List[InputExample]:
|
||||
raise NotImplementedError
|
||||
|
||||
def get_labels(self, path: str) -> List[str]:
|
||||
@staticmethod
|
||||
def get_labels(path: str) -> List[str]:
|
||||
raise NotImplementedError
|
||||
|
||||
@staticmethod
|
||||
def convert_examples_to_features(
|
||||
self,
|
||||
examples: List[InputExample],
|
||||
label_list: List[str],
|
||||
max_seq_length: int,
|
||||
|
||||
@@ -10,11 +10,12 @@ widget:
|
||||
|
||||
[MagBERT-NER] is a state-of-the-art NER model for Moroccan French language (Maghreb). The MagBERT-NER model was fine-tuned for NER Task based the language model for French Camembert (based on the RoBERTa architecture).
|
||||
|
||||
For further information or requests, please go to [Typica.AI Website](https://typicasoft.io/)
|
||||
For further information or requests, please visite our website at [typica.ai Website](https://typica.ai/) or send us an email at contactus@typica.ai
|
||||
|
||||
## How to use MagBERT-NER with HuggingFace
|
||||
|
||||
##### Load MagBERT-NER and its sub-word tokenizer :
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModelForTokenClassification
|
||||
|
||||
@@ -45,11 +46,14 @@ nlp("Saad Dine El Otmani, né le 16 janvier 1956 à Inezgane, est un homme d'Ét
|
||||
|
||||
```
|
||||
|
||||
```
|
||||
|
||||
|
||||
## Authors
|
||||
|
||||
MagBert-NER was trained and evaluated by Hicham Assoudi, Ph.D.
|
||||
MagBert-NER Model was trained by Hicham Assoudi, Ph.D.
|
||||
For any questions, comments you can contact me at assoudi@typica.ai
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
If you use our work, please cite:
|
||||
Hicham Assoudi, Ph.D., MagBERT-NER: a state-of-the-art NER model for Moroccan French language (Maghreb), (2020)
|
||||
|
||||
@@ -61,7 +61,7 @@ Pretrained weights were left identical to the original model released by allenai
|
||||
Here are the BLEU scores:
|
||||
|
||||
model | transformers
|
||||
-------|---------|----------
|
||||
-------|---------
|
||||
wmt19-de-en-6-6-base | 38.37
|
||||
|
||||
The score was calculated using this code:
|
||||
|
||||
@@ -61,7 +61,7 @@ Pretrained weights were left identical to the original model released by allenai
|
||||
Here are the BLEU scores:
|
||||
|
||||
model | transformers
|
||||
-------|---------|----------
|
||||
-------|---------
|
||||
wmt19-de-en-6-6-big | 39.9
|
||||
|
||||
The score was calculated using this code:
|
||||
|
||||
@@ -0,0 +1,80 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
tags:
|
||||
- bert
|
||||
- bluebert
|
||||
license:
|
||||
- PUBLIC DOMAIN NOTICE
|
||||
datasets:
|
||||
- PubMed
|
||||
- MIMIC-III
|
||||
|
||||
---
|
||||
|
||||
# BlueBert-Base, Uncased, PubMed and MIMIC-III
|
||||
|
||||
## Model description
|
||||
|
||||
A BERT model pre-trained on PubMed abstracts and clinical notes ([MIMIC-III](https://mimic.physionet.org/)).
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
#### How to use
|
||||
|
||||
Please see https://github.com/ncbi-nlp/bluebert
|
||||
|
||||
## Training data
|
||||
|
||||
We provide [preprocessed PubMed texts](https://ftp.ncbi.nlm.nih.gov/pub/lu/Suppl/NCBI-BERT/pubmed_uncased_sentence_nltk.txt.tar.gz) that were used to pre-train the BlueBERT models.
|
||||
The corpus contains ~4000M words extracted from the [PubMed ASCII code version](https://www.ncbi.nlm.nih.gov/research/bionlp/APIs/BioC-PubMed/).
|
||||
|
||||
Pre-trained model: https://huggingface.co/bert-base-uncased
|
||||
|
||||
## Training procedure
|
||||
|
||||
* lowercasing the text
|
||||
* removing speical chars `\x00`-`\x7F`
|
||||
* tokenizing the text using the [NLTK Treebank tokenizer](https://www.nltk.org/_modules/nltk/tokenize/treebank.html)
|
||||
|
||||
Below is a code snippet for more details.
|
||||
|
||||
```python
|
||||
value = value.lower()
|
||||
value = re.sub(r'[\r\n]+', ' ', value)
|
||||
value = re.sub(r'[^\x00-\x7F]+', ' ', value)
|
||||
|
||||
tokenized = TreebankWordTokenizer().tokenize(value)
|
||||
sentence = ' '.join(tokenized)
|
||||
sentence = re.sub(r"\s's\b", "'s", sentence)
|
||||
```
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@InProceedings{peng2019transfer,
|
||||
author = {Yifan Peng and Shankai Yan and Zhiyong Lu},
|
||||
title = {Transfer Learning in Biomedical Natural Language Processing: An Evaluation of BERT and ELMo on Ten Benchmarking Datasets},
|
||||
booktitle = {Proceedings of the 2019 Workshop on Biomedical Natural Language Processing (BioNLP 2019)},
|
||||
year = {2019},
|
||||
pages = {58--65},
|
||||
}
|
||||
```
|
||||
|
||||
### Acknowledgments
|
||||
|
||||
This work was supported by the Intramural Research Programs of the National Institutes of Health, National Library of
|
||||
Medicine and Clinical Center. This work was supported by the National Library of Medicine of the National Institutes of Health under award number 4R00LM013001-01.
|
||||
|
||||
We are also grateful to the authors of BERT and ELMo to make the data and codes publicly available.
|
||||
|
||||
We would like to thank Dr Sun Kim for processing the PubMed texts.
|
||||
|
||||
### Disclaimer
|
||||
|
||||
This tool shows the results of research conducted in the Computational Biology Branch, NCBI. The information produced
|
||||
on this website is not intended for direct diagnostic use or medical decision-making without review and oversight
|
||||
by a clinical professional. Individuals should not change their health behavior solely on the basis of information
|
||||
produced on this website. NIH does not independently verify the validity or utility of the information produced
|
||||
by this tool. If you have questions about the information produced on this website, please see a health care
|
||||
professional. More information about NCBI's disclaimer policy is available.
|
||||
@@ -0,0 +1,60 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
tags:
|
||||
- bluebert
|
||||
license:
|
||||
- PUBLIC DOMAIN NOTICE
|
||||
datasets:
|
||||
- pubmed
|
||||
|
||||
---
|
||||
|
||||
# BlueBert-Base, Uncased, PubMed
|
||||
|
||||
## Model description
|
||||
|
||||
A BERT model pre-trained on PubMed abstracts
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
#### How to use
|
||||
|
||||
Please see https://github.com/ncbi-nlp/bluebert
|
||||
|
||||
## Training data
|
||||
|
||||
We provide [preprocessed PubMed texts](https://ftp.ncbi.nlm.nih.gov/pub/lu/Suppl/NCBI-BERT/pubmed_uncased_sentence_nltk.txt.tar.gz) that were used to pre-train the BlueBERT models.
|
||||
The corpus contains ~4000M words extracted from the [PubMed ASCII code version](https://www.ncbi.nlm.nih.gov/research/bionlp/APIs/BioC-PubMed/).
|
||||
|
||||
Pre-trained model: https://huggingface.co/bert-base-uncased
|
||||
|
||||
## Training procedure
|
||||
|
||||
* lowercasing the text
|
||||
* removing speical chars `\x00`-`\x7F`
|
||||
* tokenizing the text using the [NLTK Treebank tokenizer](https://www.nltk.org/_modules/nltk/tokenize/treebank.html)
|
||||
|
||||
Below is a code snippet for more details.
|
||||
|
||||
```python
|
||||
value = value.lower()
|
||||
value = re.sub(r'[\r\n]+', ' ', value)
|
||||
value = re.sub(r'[^\x00-\x7F]+', ' ', value)
|
||||
|
||||
tokenized = TreebankWordTokenizer().tokenize(value)
|
||||
sentence = ' '.join(tokenized)
|
||||
sentence = re.sub(r"\s's\b", "'s", sentence)
|
||||
```
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@InProceedings{peng2019transfer,
|
||||
author = {Yifan Peng and Shankai Yan and Zhiyong Lu},
|
||||
title = {Transfer Learning in Biomedical Natural Language Processing: An Evaluation of BERT and ELMo on Ten Benchmarking Datasets},
|
||||
booktitle = {Proceedings of the 2019 Workshop on Biomedical Natural Language Processing (BioNLP 2019)},
|
||||
year = {2019},
|
||||
pages = {58--65},
|
||||
}
|
||||
```
|
||||
@@ -3,9 +3,9 @@ language:
|
||||
- ru
|
||||
- en
|
||||
---
|
||||
## RuDR-BERT
|
||||
## EnRuDR-BERT
|
||||
|
||||
EnRuDR-BERT - Multilingual, Cased, which pretrained on the raw part of the RuDReC corpus (1.4M reviews) and collecting of consumer comments on drug administration from [2]. Pre-training was based on the [original BERT code](https://github.com/google-research/bert) provided by Google. In particular, Multi-BERT was for used for initialization; vocabulary of Russian subtokens and parameters are the same as in Multi-BERT. Training details are described in our paper. \
|
||||
EnRuDR-BERT - Multilingual, Cased, which pretrained on the raw part of the RuDReC corpus (1.4M reviews) and english collection of consumer comments on drug administration from [2]. Pre-training was based on the [original BERT code](https://github.com/google-research/bert) provided by Google. In particular, Multi-BERT was for used for initialization; vocabulary of Russian subtokens and parameters are the same as in Multi-BERT. Training details are described in our paper. \
|
||||
link: https://yadi.sk/d/-PTn0xhk1PqvgQ
|
||||
|
||||
|
||||
|
||||
@@ -1,12 +1,14 @@
|
||||
---
|
||||
language: it
|
||||
license: mit
|
||||
datasets:
|
||||
- wikipedia
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
# 🤗 + 📚 dbmdz BERT and ELECTRA models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources Italian BERT models 🎉
|
||||
Library open sources Italian BERT and ELECTRA models 🎉
|
||||
|
||||
# Italian BERT
|
||||
|
||||
@@ -22,23 +24,35 @@ For the XXL Italian models, we use the same training data from OPUS and extend
|
||||
it with data from the Italian part of the [OSCAR corpus](https://traces1.inria.fr/oscar/).
|
||||
Thus, the final training corpus has a size of 81GB and 13,138,379,147 tokens.
|
||||
|
||||
Note: Unfortunately, a wrong vocab size was used when training the XXL models.
|
||||
This explains the mismatch of the "real" vocab size of 31102, compared to the
|
||||
vocab size specified in `config.json`. However, the model is working and all
|
||||
evaluations were done under those circumstances.
|
||||
See [this issue](https://github.com/dbmdz/berts/issues/7) for more information.
|
||||
|
||||
The Italian ELECTRA model was trained on the "XXL" corpus for 1M steps in total using a batch
|
||||
size of 128. We pretty much following the ELECTRA training procedure as used for
|
||||
[BERTurk](https://github.com/stefan-it/turkish-bert/tree/master/electra).
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| --------------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-italian-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/vocab.txt)
|
||||
| Model | Downloads
|
||||
| ---------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-italian-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/vocab.txt)
|
||||
| `dbmdz/electra-base-italian-xxl-cased-discriminator` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/dbmdz/electra-base-italian-xxl-cased-discriminator/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-discriminator/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-discriminator/vocab.txt)
|
||||
| `dbmdz/electra-base-italian-xxl-cased-generator` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/dbmdz/electra-base-italian-xxl-cased-generator/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-generator/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-generator/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on downstream tasks like NER or PoS tagging, please refer to
|
||||
[this repository](https://github.com/stefan-it/fine-tuned-berts-seq).
|
||||
[this repository](https://github.com/stefan-it/italian-bertelectra).
|
||||
|
||||
## Usage
|
||||
|
||||
@@ -47,8 +61,11 @@ With Transformers >= 2.3 our Italian BERT models can be loaded like:
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-italian-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-italian-cased")
|
||||
model_name = "dbmdz/bert-base-italian-cased"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
|
||||
model = AutoModel.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
To load the (recommended) Italian XXL BERT models, just use:
|
||||
@@ -56,8 +73,23 @@ To load the (recommended) Italian XXL BERT models, just use:
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-italian-xxl-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-italian-xxl-cased")
|
||||
model_name = "dbmdz/bert-base-italian-xxl-cased"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
|
||||
model = AutoModel.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
To load the Italian XXL ELECTRA model (discriminator), just use:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
model_name = "dbmdz/electra-base-italian-xxl-cased-discriminator"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
@@ -66,7 +98,7 @@ All models are available on the [Huggingface model hub](https://huggingface.co/d
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
For questions about our BERT/ELECTRA models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
@@ -0,0 +1,110 @@
|
||||
---
|
||||
language: it
|
||||
license: mit
|
||||
datasets:
|
||||
- wikipedia
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT and ELECTRA models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources Italian BERT and ELECTRA models 🎉
|
||||
|
||||
# Italian BERT
|
||||
|
||||
The source data for the Italian BERT model consists of a recent Wikipedia dump and
|
||||
various texts from the [OPUS corpora](http://opus.nlpl.eu/) collection. The final
|
||||
training corpus has a size of 13GB and 2,050,057,573 tokens.
|
||||
|
||||
For sentence splitting, we use NLTK (faster compared to spacy).
|
||||
Our cased and uncased models are training with an initial sequence length of 512
|
||||
subwords for ~2-3M steps.
|
||||
|
||||
For the XXL Italian models, we use the same training data from OPUS and extend
|
||||
it with data from the Italian part of the [OSCAR corpus](https://traces1.inria.fr/oscar/).
|
||||
Thus, the final training corpus has a size of 81GB and 13,138,379,147 tokens.
|
||||
|
||||
Note: Unfortunately, a wrong vocab size was used when training the XXL models.
|
||||
This explains the mismatch of the "real" vocab size of 31102, compared to the
|
||||
vocab size specified in `config.json`. However, the model is working and all
|
||||
evaluations were done under those circumstances.
|
||||
See [this issue](https://github.com/dbmdz/berts/issues/7) for more information.
|
||||
|
||||
The Italian ELECTRA model was trained on the "XXL" corpus for 1M steps in total using a batch
|
||||
size of 128. We pretty much following the ELECTRA training procedure as used for
|
||||
[BERTurk](https://github.com/stefan-it/turkish-bert/tree/master/electra).
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| ---------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-italian-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/vocab.txt)
|
||||
| `dbmdz/electra-base-italian-xxl-cased-discriminator` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/dbmdz/electra-base-italian-xxl-cased-discriminator/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-discriminator/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-discriminator/vocab.txt)
|
||||
| `dbmdz/electra-base-italian-xxl-cased-generator` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/dbmdz/electra-base-italian-xxl-cased-generator/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-generator/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/electra-base-italian-xxl-cased-generator/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on downstream tasks like NER or PoS tagging, please refer to
|
||||
[this repository](https://github.com/stefan-it/italian-bertelectra).
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our Italian BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
model_name = "dbmdz/bert-base-italian-cased"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
|
||||
model = AutoModel.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
To load the (recommended) Italian XXL BERT models, just use:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
model_name = "dbmdz/bert-base-italian-xxl-cased"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
|
||||
model = AutoModel.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
To load the Italian XXL ELECTRA model (discriminator), just use:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
model_name = "dbmdz/electra-base-italian-xxl-cased-discriminator"
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT/ELECTRA models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,117 @@
|
||||
---
|
||||
datasets:
|
||||
- squad_v2
|
||||
---
|
||||
|
||||
# roberta-base for QA
|
||||
|
||||
## Overview
|
||||
**Language model:** roberta-base
|
||||
**Language:** English
|
||||
**Downstream-task:** Extractive QA
|
||||
**Training data:** SQuAD 2.0
|
||||
**Eval data:** SQuAD 2.0
|
||||
**Code:** See [example](https://github.com/deepset-ai/FARM/blob/master/examples/question_answering.py) in [FARM](https://github.com/deepset-ai/FARM/blob/master/examples/question_answering.py)
|
||||
**Infrastructure**: 4x Tesla v100
|
||||
|
||||
## Hyperparameters
|
||||
|
||||
```
|
||||
batch_size = 96
|
||||
n_epochs = 2
|
||||
base_LM_model = "roberta-base"
|
||||
max_seq_len = 386
|
||||
learning_rate = 3e-5
|
||||
lr_schedule = LinearWarmup
|
||||
warmup_proportion = 0.2
|
||||
doc_stride=128
|
||||
max_query_length=64
|
||||
```
|
||||
|
||||
## Performance
|
||||
Evaluated on the SQuAD 2.0 dev set with the [official eval script](https://worksheets.codalab.org/rest/bundles/0x6b567e1cf2e041ec80d7098f031c5c9e/contents/blob/).
|
||||
|
||||
```
|
||||
"exact": 79.97136359807968
|
||||
"f1": 83.00449234495325
|
||||
|
||||
"total": 11873
|
||||
"HasAns_exact": 78.03643724696356
|
||||
"HasAns_f1": 84.11139298441825
|
||||
"HasAns_total": 5928
|
||||
"NoAns_exact": 81.90075693860386
|
||||
"NoAns_f1": 81.90075693860386
|
||||
"NoAns_total": 5945
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### In Transformers
|
||||
```python
|
||||
from transformers.pipelines import pipeline
|
||||
from transformers.modeling_auto import AutoModelForQuestionAnswering
|
||||
from transformers.tokenization_auto import AutoTokenizer
|
||||
|
||||
model_name = "deepset/roberta-base-squad2-v2"
|
||||
|
||||
# a) Get predictions
|
||||
nlp = pipeline('question-answering', model=model_name, tokenizer=model_name)
|
||||
QA_input = {
|
||||
'question': 'Why is model conversion important?',
|
||||
'context': 'The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks.'
|
||||
}
|
||||
res = nlp(QA_input)
|
||||
|
||||
# b) Load model & tokenizer
|
||||
model = AutoModelForQuestionAnswering.from_pretrained(model_name)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
### In FARM
|
||||
|
||||
```python
|
||||
from farm.modeling.adaptive_model import AdaptiveModel
|
||||
from farm.modeling.tokenization import Tokenizer
|
||||
from farm.infer import Inferencer
|
||||
|
||||
model_name = "deepset/roberta-base-squad2-v2"
|
||||
|
||||
# a) Get predictions
|
||||
nlp = Inferencer.load(model_name, task_type="question_answering")
|
||||
QA_input = [{"questions": ["Why is model conversion important?"],
|
||||
"text": "The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks."}]
|
||||
res = nlp.inference_from_dicts(dicts=QA_input, rest_api_schema=True)
|
||||
|
||||
# b) Load model & tokenizer
|
||||
model = AdaptiveModel.convert_from_transformers(model_name, device="cpu", task_type="question_answering")
|
||||
tokenizer = Tokenizer.load(model_name)
|
||||
```
|
||||
|
||||
### In haystack
|
||||
For doing QA at scale (i.e. many docs instead of single paragraph), you can load the model also in [haystack](https://github.com/deepset-ai/haystack/):
|
||||
```python
|
||||
reader = FARMReader(model_name_or_path="deepset/roberta-base-squad2")
|
||||
# or
|
||||
reader = TransformersReader(model="deepset/roberta-base-squad2",tokenizer="deepset/roberta-base-squad2")
|
||||
```
|
||||
|
||||
|
||||
## Authors
|
||||
Branden Chan: `branden.chan [at] deepset.ai`
|
||||
Timo Möller: `timo.moeller [at] deepset.ai`
|
||||
Malte Pietsch: `malte.pietsch [at] deepset.ai`
|
||||
Tanay Soni: `tanay.soni [at] deepset.ai`
|
||||
|
||||
## About us
|
||||
|
||||
|
||||
We bring NLP to the industry via open source!
|
||||
Our focus: Industry specific language models & large scale QA systems.
|
||||
|
||||
Some of our work:
|
||||
- [German BERT (aka "bert-base-german-cased")](https://deepset.ai/german-bert)
|
||||
- [FARM](https://github.com/deepset-ai/FARM)
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
@@ -5,6 +5,8 @@ datasets:
|
||||
|
||||
# roberta-base for QA
|
||||
|
||||
NOTE: This model has been superseded by deepset/roberta-base-squad2-v2. For an explanation of why, see [this github issue](https://github.com/deepset-ai/FARM/issues/552) from the FARM repository.
|
||||
|
||||
## Overview
|
||||
**Language model:** roberta-base
|
||||
**Language:** English
|
||||
@@ -106,4 +108,3 @@ Some of our work:
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
|
||||
|
||||
@@ -1,3 +1,40 @@
|
||||
---
|
||||
language: en
|
||||
license: apache-2.0
|
||||
datasets:
|
||||
- bookcorpus
|
||||
- wikipedia
|
||||
---
|
||||
|
||||
# DistilBERT base model (cased)
|
||||
|
||||
This model is a distilled version of the [BERT base model](https://huggingface.co/bert-base-cased).
|
||||
It was introduced in [this paper](https://arxiv.org/abs/1910.01108).
|
||||
The code for the distillation process can be found
|
||||
[here](https://github.com/huggingface/transformers/tree/master/examples/distillation).
|
||||
This model is cased: it does make a difference between english and English.
|
||||
|
||||
All the training details on the pre-training, the uses, limitations and potential biases are the same as for [DistilBERT-base-uncased](https://huggingface.co/distilbert-base-uncased).
|
||||
We highly encourage to check it if you want to know more.
|
||||
|
||||
## Evaluation results
|
||||
|
||||
When fine-tuned on downstream tasks, this model achieves the following results:
|
||||
|
||||
Glue test results:
|
||||
|
||||
| Task | MNLI | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE |
|
||||
|:----:|:----:|:----:|:----:|:-----:|:----:|:-----:|:----:|:----:|
|
||||
| | 81.5 | 87.8 | 88.2 | 90.4 | 47.2 | 85.5 | 85.6 | 60.6 |
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@article{Sanh2019DistilBERTAD,
|
||||
title={DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter},
|
||||
author={Victor Sanh and Lysandre Debut and Julien Chaumond and Thomas Wolf},
|
||||
journal={ArXiv},
|
||||
year={2019},
|
||||
volume={abs/1910.01108}
|
||||
}
|
||||
```
|
||||
|
||||
@@ -6,3 +6,8 @@ metrics:
|
||||
- squad
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# DistilBERT base cased distilled SQuAD
|
||||
|
||||
This model is a fine-tune checkpoint of [DistilBERT-base-cased](https://huggingface.co/distilbert-base-cased), fine-tuned using (a second step of) knowledge distillation on SQuAD v1.1.
|
||||
This model reaches a F1 score of 87.1 on the dev set (for comparison, BERT bert-base-cased version reaches a F1 score of 88.7).
|
||||
|
||||
@@ -1,4 +1,35 @@
|
||||
---
|
||||
language: multilingual
|
||||
license: apache-2.0
|
||||
datasets:
|
||||
- wikipedia
|
||||
---
|
||||
|
||||
# DistilBERT base multilingual model (cased)
|
||||
|
||||
This model is a distilled version of the [BERT base multilingual model](bert-base-multilingual-cased). The code for the distillation process can be found
|
||||
[here](https://github.com/huggingface/transformers/tree/master/examples/distillation). This model is cased: it does make a difference between english and English.
|
||||
|
||||
The model is trained on the concatenation of Wikipedia in 104 different languages listed [here](https://github.com/google-research/bert/blob/master/multilingual.md#list-of-languages).
|
||||
The model has 6 layers, 768 dimension and 12 heads, totalizing 134M parameters (compared to 177M parameters for mBERT-base).
|
||||
On average DistilmBERT is twice as fast as mBERT-base.
|
||||
|
||||
We encourage to check [BERT base multilingual model](bert-base-multilingual-cased) to know more about usage, limitations and potential biases.
|
||||
|
||||
| Model | English | Spanish | Chinese | German | Arabic | Urdu |
|
||||
| :---: | :---: | :---: | :---: | :---: | :---: | :---:|
|
||||
| mBERT base cased (computed) | 82.1 | 74.6 | 69.1 | 72.3 | 66.4 | 58.5 |
|
||||
| mBERT base uncased (reported)| 81.4 | 74.3 | 63.8 | 70.5 | 62.1 | 58.3 |
|
||||
| DistilmBERT | 78.2 | 69.1 | 64.0 | 66.3 | 59.1 | 54.7 |
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@article{Sanh2019DistilBERTAD,
|
||||
title={DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter},
|
||||
author={Victor Sanh and Lysandre Debut and Julien Chaumond and Thomas Wolf},
|
||||
journal={ArXiv},
|
||||
year={2019},
|
||||
volume={abs/1910.01108}
|
||||
}
|
||||
```
|
||||
|
||||
@@ -10,7 +10,7 @@ datasets:
|
||||
|
||||
# DistilBERT base model (uncased)
|
||||
|
||||
This model is a distilled version of the [BERT base mode](https://huggingface.co/distilbert-base-uncased). It was
|
||||
This model is a distilled version of the [BERT base model](https://huggingface.co/bert-base-uncased). It was
|
||||
introduced in [this paper](https://arxiv.org/abs/1910.01108). The code for the distillation process can be found
|
||||
[here](https://github.com/huggingface/transformers/tree/master/examples/distillation). This model is uncased: it does
|
||||
not make a difference between english and English.
|
||||
@@ -102,7 +102,7 @@ output = model(encoded_input)
|
||||
|
||||
Even if the training data used for this model could be characterized as fairly neutral, this model can have biased
|
||||
predictions. It also inherits some of
|
||||
[the bias of its teacher model](https://huggingface.co/bert-base-uncased#limitations-and-bias).
|
||||
[the bias of its teacher model](https://huggingface.co/bert-base-uncased#limitations-and-bias).
|
||||
|
||||
```python
|
||||
>>> from transformers import pipeline
|
||||
@@ -196,9 +196,9 @@ When fine-tuned on downstream tasks, this model achieves the following results:
|
||||
|
||||
Glue test results:
|
||||
|
||||
| Task | MNLI | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE | Average |
|
||||
|:----:|:----:|:----:|:----:|:-----:|:----:|:-----:|:----:|:----:|:-------:|
|
||||
| | 82.2 | 88.5 | 89.2 | 91.3 | 51.3 | 85.8 | 87.5 | 59.9 | 77.0 |
|
||||
| Task | MNLI | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE |
|
||||
|:----:|:----:|:----:|:----:|:-----:|:----:|:-----:|:----:|:----:|
|
||||
| | 82.2 | 88.5 | 89.2 | 91.3 | 51.3 | 85.8 | 87.5 | 59.9 |
|
||||
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
@@ -1,4 +1,5 @@
|
||||
---
|
||||
language: en
|
||||
datasets:
|
||||
- squad
|
||||
widget:
|
||||
@@ -8,3 +9,8 @@ widget:
|
||||
context: "The Amazon rainforest (Portuguese: Floresta Amazônica or Amazônia; Spanish: Selva Amazónica, Amazonía or usually Amazonia; French: Forêt amazonienne; Dutch: Amazoneregenwoud), also known in English as Amazonia or the Amazon Jungle, is a moist broadleaf forest that covers most of the Amazon basin of South America. This basin encompasses 7,000,000 square kilometres (2,700,000 sq mi), of which 5,500,000 square kilometres (2,100,000 sq mi) are covered by the rainforest. This region includes territory belonging to nine nations. The majority of the forest is contained within Brazil, with 60% of the rainforest, followed by Peru with 13%, Colombia with 10%, and with minor amounts in Venezuela, Ecuador, Bolivia, Guyana, Suriname and French Guiana. States or departments in four nations contain \"Amazonas\" in their names. The Amazon represents over half of the planet's remaining rainforests, and comprises the largest and most biodiverse tract of tropical rainforest in the world, with an estimated 390 billion individual trees divided into 16,000 species."
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# DistilBERT base uncased distilled SQuAD
|
||||
|
||||
This model is a fine-tune checkpoint of [DistilBERT-base-uncased](https://huggingface.co/distilbert-base-uncased), fine-tuned using (a second step of) knowledge distillation on SQuAD v1.1.
|
||||
This model reaches a F1 score of 86.9 on the dev set (for comparison, Bert bert-base-uncased version reaches a F1 score of 88.5).
|
||||
|
||||
@@ -1,3 +1,19 @@
|
||||
---
|
||||
language: en
|
||||
license: apache-2.0
|
||||
datasets:
|
||||
- sst-2
|
||||
---
|
||||
|
||||
# DistilBERT base uncased finetuned SST-2
|
||||
|
||||
This model is a fine-tune checkpoint of [DistilBERT-base-uncased](https://huggingface.co/distilbert-base-uncased), fine-tuned on SST-2.
|
||||
This model reaches an accuracy of 91.3 on the dev set (for comparison, Bert bert-base-uncased version reaches an accuracy of 92.7).
|
||||
|
||||
# Fine-tuning hyper-parameters
|
||||
|
||||
- learning_rate = 1e-5
|
||||
- batch_size = 32
|
||||
- warmup = 600
|
||||
- max_seq_length = 128
|
||||
- num_train_epochs = 3.0
|
||||
|
||||
@@ -1,10 +1,21 @@
|
||||
---
|
||||
language: en
|
||||
tags:
|
||||
- exbert
|
||||
|
||||
license: apache-2.0
|
||||
datasets:
|
||||
- openwebtext
|
||||
---
|
||||
|
||||
# DistilGPT2
|
||||
|
||||
DistilGPT2 English language model pretrained with the supervision of [GPT2](https://huggingface.co/gpt2) (the smallest version of GPT2) on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset. The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 124M parameters for GPT2). On average, DistilGPT2 is two times faster than GPT2.
|
||||
|
||||
On the [WikiText-103](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/) benchmark, GPT2 reaches a perplexity on the test set of 16.3 compared to 21.1 for DistilGPT2 (after fine-tuning on the train set).
|
||||
|
||||
We encourage to check [GPT2](https://huggingface.co/gpt2) to know more about usage, limitations and potential biases.
|
||||
|
||||
<a href="https://huggingface.co/exbert/?model=distilgpt2">
|
||||
<img width="300px" src="https://cdn-media.huggingface.co/exbert/button.png">
|
||||
</a>
|
||||
|
||||
@@ -1,10 +1,50 @@
|
||||
---
|
||||
language: en
|
||||
tags:
|
||||
- exbert
|
||||
|
||||
license: apache-2.0
|
||||
datasets:
|
||||
- openwebtext
|
||||
---
|
||||
|
||||
# DistilRoBERTa base model
|
||||
|
||||
This model is a distilled version of the [RoBERTa-base model](https://huggingface.co/roberta-base). It follows the same training procedure as [DistilBERT](https://huggingface.co/distilbert-base-uncased).
|
||||
The code for the distillation process can be found [here](https://github.com/huggingface/transformers/tree/master/examples/distillation).
|
||||
This model is case-sensitive: it makes a difference between english and English.
|
||||
|
||||
The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 125M parameters for RoBERTa-base).
|
||||
On average DistilRoBERTa is twice as fast as Roberta-base.
|
||||
|
||||
We encourage to check [RoBERTa-base model](https://huggingface.co/roberta-base) to know more about usage, limitations and potential biases.
|
||||
|
||||
## Training data
|
||||
|
||||
DistilRoBERTa was pre-trained on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset (it is ~4 times less training data than the teacher RoBERTa).
|
||||
|
||||
## Evaluation results
|
||||
|
||||
When fine-tuned on downstream tasks, this model achieves the following results:
|
||||
|
||||
Glue test results:
|
||||
|
||||
| Task | MNLI | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE |
|
||||
|:----:|:----:|:----:|:----:|:-----:|:----:|:-----:|:----:|:----:|
|
||||
| | 84.0 | 89.4 | 90.8 | 92.5 | 59.3 | 88.3 | 86.6 | 67.9 |
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@article{Sanh2019DistilBERTAD,
|
||||
title={DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter},
|
||||
author={Victor Sanh and Lysandre Debut and Julien Chaumond and Thomas Wolf},
|
||||
journal={ArXiv},
|
||||
year={2019},
|
||||
volume={abs/1910.01108}
|
||||
}
|
||||
```
|
||||
|
||||
<a href="https://huggingface.co/exbert/?model=distilroberta-base">
|
||||
<img width="300px" src="https://cdn-media.huggingface.co/exbert/button.png">
|
||||
</a>
|
||||
|
||||
@@ -0,0 +1,41 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
thumbnail:
|
||||
widget:
|
||||
- text: "topic: climate article:"
|
||||
---
|
||||
|
||||
# GPT2-medium-topic-news
|
||||
|
||||
## Model description
|
||||
|
||||
GPT2-medium fine tuned on a large news corpus conditioned on a topic
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
#### How to use
|
||||
|
||||
To generate a news article text conditioned on a topic, prompt model with:
|
||||
`topic: climate article:`
|
||||
|
||||
The following tags were used during training:
|
||||
`arts law international science business politics disaster world conflict football sport sports artanddesign environment music film lifeandstyle business health commentisfree books technology media education politics travel stage uk society us money culture religion science news tv fashion uk australia cities global childrens sustainable global voluntary housing law local healthcare theguardian`
|
||||
|
||||
Zero shot generation works pretty well as long as `topic` is a single word and not too specific.
|
||||
|
||||
```python
|
||||
device = "cuda:0"
|
||||
tokenizer = AutoTokenizer.from_pretrained("ktrapeznikov/gpt2-medium-topic-news")
|
||||
model = AutoModelWithLMHead.from_pretrained("ktrapeznikov/gpt2-medium-topic-news")
|
||||
model.to(device)
|
||||
topic = "climate"
|
||||
prompt = tokenizer(f"topic: {topic} article:", return_tensors="pt")
|
||||
out = model.generate(prompt["input_ids"].to(device), do_sample=True,max_length=500, early_stopping=True, top_p=.9)
|
||||
print(tokenizer.decode(list(out.cpu()[0])))
|
||||
```
|
||||
|
||||
## Training data
|
||||
|
||||
|
||||
## Training procedure
|
||||
@@ -0,0 +1,24 @@
|
||||
---
|
||||
language: te
|
||||
---
|
||||
# telugu_bertu
|
||||
|
||||
## Model description
|
||||
|
||||
This model is a BERT MLM model trained on Telugu.
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
#### How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer, pipeline
|
||||
tokenizer = AutoTokenizer.from_pretrained("kuppuluri/telugu_bertu",
|
||||
clean_text=False,
|
||||
handle_chinese_chars=False,
|
||||
strip_accents=False,
|
||||
wordpieces_prefix='##')
|
||||
model = AutoModelWithLMHead.from_pretrained("kuppuluri/telugu_bertu")
|
||||
fill_mask = pipeline("fill-mask", model=model, tokenizer=tokenizer)
|
||||
results = fill_mask("మక్దూంపల్లి పేరుతో చాలా [MASK] ఉన్నాయి.")
|
||||
```
|
||||
@@ -0,0 +1,35 @@
|
||||
# Named Entity Recognition Model for Telugu
|
||||
|
||||
#### How to use
|
||||
|
||||
```python
|
||||
from simpletransformers.ner import NERModel
|
||||
model = NERModel('bert',
|
||||
'kuppuluri/telugu_bertu_ner',
|
||||
labels=[
|
||||
'B-PERSON', 'I-ORG', 'B-ORG', 'I-LOC', 'B-MISC',
|
||||
'I-MISC', 'I-PERSON', 'B-LOC', 'O'
|
||||
],
|
||||
use_cuda=False,
|
||||
args={"use_multiprocessing": False})
|
||||
|
||||
text = "విరాట్ కోహ్లీ కూడా అదే నిర్లక్ష్యాన్ని ప్రదర్శించి కేవలం ఒక పరుగుకే రనౌటై పెవిలియన్ చేరాడు ."
|
||||
results = model.predict([text])
|
||||
```
|
||||
|
||||
## Training data
|
||||
|
||||
Training data is from https://github.com/anikethjr/NER_Telugu
|
||||
|
||||
## Eval results
|
||||
|
||||
On the test set my results were
|
||||
|
||||
eval_loss = 0.0004407190410447974
|
||||
|
||||
f1_score = 0.999519076627124
|
||||
|
||||
precision = 0.9994389677005691
|
||||
|
||||
recall = 0.9995991983967936
|
||||
|
||||
@@ -0,0 +1,36 @@
|
||||
# Part of Speech tagging Model for Telugu
|
||||
|
||||
#### How to use
|
||||
|
||||
```python
|
||||
from simpletransformers.ner import NERModel
|
||||
model = NERModel('bert',
|
||||
'kuppuluri/telugu_bertu_pos',
|
||||
args={"use_multiprocessing": False},
|
||||
labels=[
|
||||
'QC', 'JJ', 'NN', 'QF', 'RDP', 'O',
|
||||
'NNO', 'PRP', 'RP', 'VM', 'WQ',
|
||||
'PSP', 'UT', 'CC', 'INTF', 'SYMP',
|
||||
'NNP', 'INJ', 'SYM', 'CL', 'QO',
|
||||
'DEM', 'RB', 'NST', ],
|
||||
use_cuda=False)
|
||||
|
||||
text = "విరాట్ కోహ్లీ కూడా అదే నిర్లక్ష్యాన్ని ప్రదర్శించి కేవలం ఒక పరుగుకే రనౌటై పెవిలియన్ చేరాడు ."
|
||||
results = model.predict([text])
|
||||
```
|
||||
|
||||
## Training data
|
||||
|
||||
Training data is from https://github.com/anikethjr/NER_Telugu
|
||||
|
||||
## Eval results
|
||||
|
||||
On the test set my results were
|
||||
|
||||
eval_loss = 0.0036797842364565416
|
||||
|
||||
f1_score = 0.9983795127912227
|
||||
|
||||
precision = 0.9984325602401637
|
||||
|
||||
recall = 0.9983264709788816
|
||||
@@ -0,0 +1,18 @@
|
||||
# Telugu Question-Answering model trained on Tydiqa dataset from Google
|
||||
|
||||
#### How to use
|
||||
|
||||
```python
|
||||
from transformers.pipelines import pipeline, AutoModelForQuestionAnswering, AutoTokenizer
|
||||
model = AutoModelForQuestionAnswering.from_pretrained(model_name)
|
||||
tokenizer = AutoTokenizer.from_pretrained("kuppuluri/telugu_bertu_tydiqa",
|
||||
clean_text=False,
|
||||
handle_chinese_chars=False,
|
||||
strip_accents=False,
|
||||
wordpieces_prefix='##')
|
||||
nlp = pipeline('question-answering', model=model, tokenizer=tokenizer)
|
||||
result = nlp({'question': question, 'context': context})
|
||||
```
|
||||
|
||||
## Training data
|
||||
I used Tydiqa Telugu data from Google https://github.com/google-research-datasets/tydiqa
|
||||
@@ -0,0 +1,63 @@
|
||||
---
|
||||
language: en
|
||||
datasets:
|
||||
- common_gen
|
||||
widget:
|
||||
- text: "<|endoftext|> apple, tree, pick:"
|
||||
---
|
||||
|
||||
# GPT-2 fine-tuned on CommonGen
|
||||
|
||||
[GPT-2](https://huggingface.co/gpt2) fine-tuned on [CommonGen](https://inklab.usc.edu/CommonGen/index.html) for *Generative Commonsense Reasoning*.
|
||||
|
||||
## Details of GPT-2
|
||||
|
||||
GPT-2 is a transformers model pretrained on a very large corpus of English data in a self-supervised fashion. This
|
||||
means it was pretrained on the raw texts only, with no humans labelling them in any way (which is why it can use lots
|
||||
of publicly available data) with an automatic process to generate inputs and labels from those texts. More precisely,
|
||||
it was trained to guess the next word in sentences.
|
||||
|
||||
More precisely, inputs are sequences of continuous text of a certain length and the targets are the same sequence,
|
||||
shifted one token (word or piece of word) to the right. The model uses internally a mask-mechanism to make sure the
|
||||
predictions for the token `i` only uses the inputs from `1` to `i` but not the future tokens.
|
||||
|
||||
This way, the model learns an inner representation of the English language that can then be used to extract features
|
||||
useful for downstream tasks. The model is best at what it was pretrained for however, which is generating texts from a
|
||||
prompt.
|
||||
|
||||
|
||||
## Details of the dataset 📚
|
||||
|
||||
CommonGen is a constrained text generation task, associated with a benchmark dataset, to explicitly test machines for the ability of generative commonsense reasoning. Given a set of common concepts; the task is to generate a coherent sentence describing an everyday scenario using these concepts.
|
||||
|
||||
CommonGen is challenging because it inherently requires 1) relational reasoning using background commonsense knowledge, and 2) compositional generalization ability to work on unseen concept combinations. Our dataset, constructed through a combination of crowd-sourcing from AMT and existing caption corpora, consists of 30k concept-sets and 50k sentences in total.
|
||||
|
||||
|
||||
| Dataset | Split | # samples |
|
||||
| -------- | ----- | --------- |
|
||||
| common_gen | train | 67389 |
|
||||
| common_gen | valid | 4018 |
|
||||
| common_gen | test | 1497 |
|
||||
|
||||
|
||||
## Model fine-tuning 🏋️
|
||||
|
||||
You can find the fine-tuning script [here](https://github.com/huggingface/transformers/tree/master/examples/language-modeling)
|
||||
|
||||
## Model in Action 🚀
|
||||
|
||||
```bash
|
||||
python ./transformers/examples/text-generation/run_generation.py \
|
||||
--model_type=gpt2 \
|
||||
--model_name_or_path="mrm8488/GPT-2-finetuned-common_gen" \
|
||||
--num_return_sequences 1 \
|
||||
--prompt "<|endoftext|> kid, room, dance:" \
|
||||
--stop_token "."
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
|
||||
|
||||
|
||||
@@ -17,7 +17,7 @@ This model is a fine-tuned on [NER-C](https://www.kaggle.com/nltkdata/conll-corp
|
||||
| Dev | 40 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
|
||||
@@ -16,7 +16,7 @@ This model is a fine-tuned on [CONLL CORPORA](https://www.kaggle.com/nltkdata/co
|
||||
| Train | 445 K |
|
||||
| Dev | 55 K |
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
|
||||
@@ -19,7 +19,7 @@ I preprocessed the dataset and split it as train / dev (80/20)
|
||||
| Dev | 2.2 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
|
||||
@@ -18,7 +18,7 @@ Court decisions from 2017 and 2018 were selected for the dataset, published onli
|
||||
| Train | 1657048 |
|
||||
| Eval | 500000 |
|
||||
|
||||
- Training script: [Fine-tuning script for NER provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
- Training script: [Fine-tuning script for NER provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
Colab: [How to fine-tune a model for NER using HF scripts](https://colab.research.google.com/drive/156Qrd7NsUHwA3nmQ6gXdZY0NzOvqk9AT?usp=sharing)
|
||||
|
||||
- Labels covered (and its distribution):
|
||||
|
||||
@@ -11,7 +11,7 @@ thumbnail:
|
||||
|
||||
- Dataset: [GitHub Typo Corpus](https://github.com/mhagiwara/github-typo-corpus) 📚
|
||||
|
||||
- [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py) 🏋️♂️
|
||||
- [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py) 🏋️♂️
|
||||
|
||||
## Metrics on test set 📋
|
||||
|
||||
|
||||
@@ -19,7 +19,7 @@ I preprocessed the dataset and split it as train / dev (80/20)
|
||||
| Dev | 2.2 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
|
||||
@@ -11,7 +11,7 @@ This model is a fine-tuned version of the Spanish BERT [(BETO)](https://github.c
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora)
|
||||
|
||||
#### [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
#### [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
|
||||
#### 21 Syntax annotations (Labels) covered:
|
||||
|
||||
|
||||
@@ -19,7 +19,7 @@ I preprocessed the dataset and split it as train / dev (80/20)
|
||||
| Dev | 50 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py)
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py)
|
||||
|
||||
- **60** Labels covered:
|
||||
|
||||
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
language: en
|
||||
datasets:
|
||||
- codexglue
|
||||
---
|
||||
|
||||
# CodeBERT fine-tuned for Insecure Code Detection 💾⛔
|
||||
|
||||
|
||||
[codebert-base](https://huggingface.co/microsoft/codebert-base) fine-tuned on [CodeXGLUE -- Defect Detection](https://github.com/microsoft/CodeXGLUE/tree/main/Code-Code/Defect-detection) dataset for **Insecure Code Detection** downstream task.
|
||||
|
||||
## Details of [CodeBERT](https://arxiv.org/abs/2002.08155)
|
||||
|
||||
We present CodeBERT, a bimodal pre-trained model for programming language (PL) and nat-ural language (NL). CodeBERT learns general-purpose representations that support downstream NL-PL applications such as natural language codesearch, code documentation generation, etc. We develop CodeBERT with Transformer-based neural architecture, and train it with a hybrid objective function that incorporates the pre-training task of replaced token detection, which is to detect plausible alternatives sampled from generators. This enables us to utilize both bimodal data of NL-PL pairs and unimodal data, where the former provides input tokens for model training while the latter helps to learn better generators. We evaluate CodeBERT on two NL-PL applications by fine-tuning model parameters. Results show that CodeBERT achieves state-of-the-art performance on both natural language code search and code documentation generation tasks. Furthermore, to investigate what type of knowledge is learned in CodeBERT, we construct a dataset for NL-PL probing, and evaluate in a zero-shot setting where parameters of pre-trained models are fixed. Results show that CodeBERT performs better than previous pre-trained models on NL-PL probing.
|
||||
|
||||
## Details of the downstream task (code classification) - Dataset 📚
|
||||
|
||||
Given a source code, the task is to identify whether it is an insecure code that may attack software systems, such as resource leaks, use-after-free vulnerabilities and DoS attack. We treat the task as binary classification (0/1), where 1 stands for insecure code and 0 for secure code.
|
||||
|
||||
The [dataset](https://github.com/microsoft/CodeXGLUE/tree/main/Code-Code/Defect-detection) used comes from the paper [*Devign*: Effective Vulnerability Identification by Learning Comprehensive Program Semantics via Graph Neural Networks](http://papers.nips.cc/paper/9209-devign-effective-vulnerability-identification-by-learning-comprehensive-program-semantics-via-graph-neural-networks.pdf). All projects are combined and splitted 80%/10%/10% for training/dev/test.
|
||||
|
||||
Data statistics of the dataset are shown in the below table:
|
||||
|
||||
| | #Examples |
|
||||
| ----- | :-------: |
|
||||
| Train | 21,854 |
|
||||
| Dev | 2,732 |
|
||||
| Test | 2,732 |
|
||||
|
||||
## Test set metrics 🧾
|
||||
|
||||
| Methods | ACC |
|
||||
| -------- | :-------: |
|
||||
| BiLSTM | 59.37 |
|
||||
| TextCNN | 60.69 |
|
||||
| [RoBERTa](https://arxiv.org/pdf/1907.11692.pdf) | 61.05 |
|
||||
| [CodeBERT](https://arxiv.org/pdf/2002.08155.pdf) | 62.08 |
|
||||
| [Ours](https://huggingface.co/mrm8488/codebert-base-finetuned-detect-insecure-code) | **65.30** |
|
||||
|
||||
|
||||
## Model in Action 🚀
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModelForSequenceClassification
|
||||
import torch
|
||||
import numpy as np
|
||||
tokenizer = AutoTokenizer.from_pretrained('mrm8488/codebert-base-finetuned-detect-insecure-code')
|
||||
model = AutoModelForSequenceClassification.from_pretrained('mrm8488/codebert-base-finetuned-detect-insecure-code', return_dict=True)
|
||||
|
||||
inputs = tokenizer("your code here", return_tensors="pt", truncation=True, padding='max_length')
|
||||
labels = torch.tensor([1]).unsqueeze(0) # Batch size 1
|
||||
outputs = model(**inputs, labels=labels)
|
||||
loss = outputs.loss
|
||||
logits = outputs.logits
|
||||
|
||||
print(np.argmax(logits.detach().numpy()))
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -11,7 +11,7 @@ thumbnail:
|
||||
|
||||
- Dataset: [GitHub Typo Corpus](https://github.com/mhagiwara/github-typo-corpus) 📚 for 15 languages
|
||||
|
||||
- [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner.py) 🏋️♂️
|
||||
- [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/token-classification/run_ner_old.py) 🏋️♂️
|
||||
|
||||
## Metrics on test set 📋
|
||||
|
||||
|
||||
@@ -0,0 +1,66 @@
|
||||
---
|
||||
language: en
|
||||
datasets:
|
||||
- qasc
|
||||
---
|
||||
|
||||
# T5-base fine-tuned on QASC
|
||||
|
||||
[Google's T5](https://ai.googleblog.com/2020/02/exploring-transfer-learning-with-t5.html) fine-tuned on [QASC](https://allenai.org/data/qasc) for **QA** (via *sentence composition*) downstream task.
|
||||
|
||||
## Details of T5
|
||||
|
||||
The **T5** model was presented in [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/pdf/1910.10683.pdf) by *Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, Peter J. Liu* in Here the abstract:
|
||||
|
||||
Transfer learning, where a model is first pre-trained on a data-rich task before being fine-tuned on a downstream task, has emerged as a powerful technique in natural language processing (NLP). The effectiveness of transfer learning has given rise to a diversity of approaches, methodology, and practice. In this paper, we explore the landscape of transfer learning techniques for NLP by introducing a unified framework that converts every language problem into a text-to-text format. Our systematic study compares pre-training objectives, architectures, unlabeled datasets, transfer approaches, and other factors on dozens of language understanding tasks. By combining the insights from our exploration with scale and our new “Colossal Clean Crawled Corpus”, we achieve state-of-the-art results on many benchmarks covering summarization, question answering, text classification, and more. To facilitate future work on transfer learning for NLP, we release our dataset, pre-trained models, and code.
|
||||
|
||||

|
||||
|
||||
|
||||
## Details of the dataset 📚
|
||||
|
||||
**Question Answering via Sentence Composition** (QASC) is a question-answering dataset with a focus on sentence composition. It consists of 9,980 8-way multiple-choice questions about grade school science (8,134 train, 926 dev, 920 test), and comes with a corpus of 17M sentences.
|
||||
|
||||
|
||||
## Model fine-tuning 🏋️
|
||||
|
||||
The training script is a slightly modified version of [this awesome one](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) by [Suraj Patil](https://twitter.com/psuraj28). The **context** passed to the *encoder* is the combination of the 2 *facts* (`fact1` and `fact2`). The **question** is just the `formatted_question` field. The **answer** passed to the *decoder* is the`text` right answer instead of the `label` (A, B, C... See `choices` field). More details about the dataset format/fields [here](https://huggingface.co/nlp/viewer/?dataset=qasc)
|
||||
|
||||
## Metrics on validation set 📋
|
||||
|
||||
| Metric | Score |
|
||||
|--------|-------|
|
||||
|Accuracy (EM) | **97.73**|
|
||||
|
||||
|
||||
## Model in Action 🚀
|
||||
|
||||
```python
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("mrm8488/t5-base-finetuned-qasc")
|
||||
model = AutoModelWithLMHead.from_pretrained("mrm8488/t5-base-finetuned-qasc")
|
||||
|
||||
def get_response(question, context, max_length=64):
|
||||
input_text = 'question: %s context: %s' % (question, context)
|
||||
features = tokenizer([input_text], return_tensors='pt')
|
||||
|
||||
output = model.generate(input_ids=features['input_ids'],
|
||||
attention_mask=features['attention_mask'],
|
||||
max_length=max_length)
|
||||
|
||||
return tokenizer.decode(output[0])
|
||||
|
||||
fact_1 = 'a watch is used for measuring time'
|
||||
fact_2 = 'Times are measured in seconds.'
|
||||
context = fact_1 + ' ' + fact_2
|
||||
question = 'What can be used to measure seconds? (A) Watch (B) seconds (C) fluid (D) Ruler (E) goggles (F) glasses (G) Drill (H) Scale'
|
||||
|
||||
get_response(question, context)
|
||||
|
||||
# output: 'Watch'
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -0,0 +1,65 @@
|
||||
---
|
||||
language: en
|
||||
datasets:
|
||||
- quarel
|
||||
---
|
||||
|
||||
# T5-base fine-tuned on QuaRel
|
||||
|
||||
[Google's T5](https://ai.googleblog.com/2020/02/exploring-transfer-learning-with-t5.html) fine-tuned on [QuaRel](https://allenai.org/data/quarel) for **QA** downstream task.
|
||||
|
||||
## Details of T5
|
||||
|
||||
The **T5** model was presented in [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/pdf/1910.10683.pdf) by *Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, Peter J. Liu* in Here the abstract:
|
||||
|
||||
Transfer learning, where a model is first pre-trained on a data-rich task before being fine-tuned on a downstream task, has emerged as a powerful technique in natural language processing (NLP). The effectiveness of transfer learning has given rise to a diversity of approaches, methodology, and practice. In this paper, we explore the landscape of transfer learning techniques for NLP by introducing a unified framework that converts every language problem into a text-to-text format. Our systematic study compares pre-training objectives, architectures, unlabeled datasets, transfer approaches, and other factors on dozens of language understanding tasks. By combining the insights from our exploration with scale and our new “Colossal Clean Crawled Corpus”, we achieve state-of-the-art results on many benchmarks covering summarization, question answering, text classification, and more. To facilitate future work on transfer learning for NLP, we release our dataset, pre-trained models, and code.
|
||||
|
||||

|
||||
|
||||
|
||||
## Details of the dataset 📚
|
||||
|
||||
**QuaRel**: *[A Dataset and Models for Answering Questions about Qualitative Relationships](https://www.semanticscholar.org/paper/QuaRel%3A-A-Dataset-and-Models-for-Answering-about-Tafjord-Clark/51004bc6461a572e1189a0e3b32b441155d760ce)*
|
||||
|
||||
Many natural language questions require recognizing and reasoning with qualitative relationships (e.g., in science, economics, and medicine), but are challenging to answer with corpus-based methods. Qualitative modeling provides tools that support such reasoning, but the semantic parsing task of mapping questions into those models has formidable challenges. We present QuaRel, a dataset of diverse story questions involving qualitative relationships that characterize these challenges, and techniques that begin to address them. The dataset has 2771 questions relating 19 different types of quantities. For example, "Jenny observes that the robot vacuum cleaner moves slower on the living room carpet than on the bedroom carpet. Which carpet has more friction?" We contribute (1) a simple and flexible conceptual framework for representing these kinds of questions; (2) the QuaRel dataset, including logical forms, exemplifying the parsing challenges; and (3) two novel models for this task, built as extensions of type-constrained semantic parsing. The first of these models (called QuaSP+) significantly outperforms off-the-shelf tools on QuaRel. The second (QuaSP+Zero) demonstrates zero-shot capability, i.e., the ability to handle new qualitative relationships without requiring additional training data, something not possible with previous models. This work thus makes inroads into answering complex, qualitative questions that require reasoning, and scaling to new relationships at low cost
|
||||
|
||||
## Model fine-tuning 🏋️
|
||||
|
||||
The training script is a slightly modified version of [this awesome one](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) by [Suraj Patil](https://twitter.com/psuraj28). The **context** passed to the *encoder* is the `logical_form_pretty` field (example: `qrel(speed, higher, ice) -> qrel(smoothness, higher, snow) ; qrel(smoothness, higher, ice`) . The **question** is just the `question` field. The **answer** passed to the *decoder* is obtained from `question`using the `answer_index` field. More details about the dataset format/fields [here](https://huggingface.co/nlp/viewer/?dataset=quarel)
|
||||
|
||||
## Metrics on validation set 📋
|
||||
|
||||
| Metric | Score |
|
||||
|--------|-------|
|
||||
|Accuracy (EM) | **67.98**|
|
||||
|
||||
|
||||
## Model in Action 🚀
|
||||
|
||||
```python
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("mrm8488/t5-base-finetuned-quarel")
|
||||
model = AutoModelWithLMHead.from_pretrained("mrm8488/t5-base-finetuned-quarel")
|
||||
|
||||
def get_response(question, context, max_length=32):
|
||||
input_text = 'question: %s context: %s' % (question, context)
|
||||
features = tokenizer([input_text], return_tensors='pt')
|
||||
|
||||
output = model.generate(input_ids=features['input_ids'],
|
||||
attention_mask=features['attention_mask'],
|
||||
max_length=max_length)
|
||||
|
||||
return tokenizer.decode(output[0])
|
||||
|
||||
question = 'As the train left the station it crossed the bridge and being farther away it looked (A) larger (B) smaller'
|
||||
context = 'qrel(distance, higher, Train on a bridge) -> qrel(apparentSize, higher, Train on a bridge) ; qrel(apparentSize, lower, Train on a bridge)'
|
||||
|
||||
get_response(question, context)
|
||||
|
||||
# output: 'smaller'
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -0,0 +1,35 @@
|
||||
---
|
||||
language: zh
|
||||
---
|
||||
|
||||
# gpt2-medium-chinese
|
||||
|
||||
|
||||
# Overview
|
||||
|
||||
- **Language model**: GPT2-Medium
|
||||
- **Model size**: 1.2GiB
|
||||
- **Language**: Chinese
|
||||
- **Training data**: [wiki2019zh_corpus](https://github.com/brightmart/nlp_chinese_corpus)
|
||||
- **Source code**: [gpt2-quickly](https://github.com/mymusise/gpt2-quickly)
|
||||
|
||||
# Example
|
||||
|
||||
```python
|
||||
from transformers import BertTokenizer, TFGPT2LMHeadModel
|
||||
from transformers import TextGenerationPipeline
|
||||
|
||||
tokenizer = BertTokenizer.from_pretrained("mymusise/EasternFantasyNoval")
|
||||
model = TFGPT2LMHeadModel.from_pretrained("mymusise/EasternFantasyNoval")
|
||||
|
||||
text_generator = TextGenerationPipeline(model, tokenizer)
|
||||
print(text_generator("今日", max_length=64, do_sample=True, top_k=10))
|
||||
print(text_generator("跨越山丘", max_length=64, do_sample=True, top_k=10))
|
||||
```
|
||||
输出
|
||||
```text
|
||||
[{'generated_text': '今日 , 他 的 作 品 也 在 各 种 报 刊 发 表 。 201 1 年 , 他 开 设 了 他 的 网 页 版 《 the dear 》 。 此 外 , 他 还 在 各 种 电 视 节 目 中 出 现 过 。 2017 年 1 月 , 他 被 任'}]
|
||||
[{'generated_text': '跨越山丘 , 其 中 有 三 分 之 二 的 地 区 被 划 入 山 区 。 最 高 峰 是 位 于 山 脚 上 的 大 岩 ( ) 。 其 中 的 山 脚 下 有 一 处 有 名 为 的 河 谷 , 因 其 高 度 在 其 中 , 而 得 名 。'}]
|
||||
```
|
||||
|
||||
[Try it on colab](https://colab.research.google.com/github/mymusise/gpt2-quickly/blob/main/examples/gpt2_medium_chinese.ipynb)
|
||||
@@ -29,7 +29,7 @@ For further information or requests, please go to [BERTimbau repository](https:/
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer # Or BertTokenizer
|
||||
from transformers import AutoModelForPretraining # Or BertForPreTraining for loading pretraining heads
|
||||
from transformers import AutoModelForPreTraining # Or BertForPreTraining for loading pretraining heads
|
||||
from transformers import AutoModel # or BertModel, for BERT without pretraining heads
|
||||
|
||||
model = AutoModelForPreTraining.from_pretrained('neuralmind/bert-base-portuguese-cased')
|
||||
|
||||
@@ -0,0 +1,5 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
inference: false
|
||||
---
|
||||
@@ -32,7 +32,7 @@ export SEED=1
|
||||
```
|
||||
Then run pre-training:
|
||||
```
|
||||
python3 run_ner.py --data_dir ./tr-data3 \
|
||||
python3 run_ner_old.py --data_dir ./tr-data3 \
|
||||
--model_type bert \
|
||||
--labels ./tr-data/labels.txt \
|
||||
--model_name_or_path $BERT_MODEL \
|
||||
|
||||
@@ -0,0 +1,39 @@
|
||||
---
|
||||
language: de
|
||||
tags:
|
||||
- exbert
|
||||
---
|
||||
|
||||
<a href="https://huggingface.co/exbert/?model=smanjil/German-MedBERT">
|
||||
<img width="300px" src="https://cdn-media.huggingface.co/exbert/button.png">
|
||||
</a>
|
||||
|
||||
# German Medical BERT
|
||||
|
||||
This is a fine-tuned model on Medical domain for German language and based on German BERT.
|
||||
|
||||
## Overview
|
||||
**Language model:** bert-base-german-cased
|
||||
|
||||
**Language:** German
|
||||
|
||||
**Fine-tuning:** Medical articles (diseases, symptoms, therapies, etc..)
|
||||
|
||||
**Eval data:** NTS-ICD-10 dataset (Classification)
|
||||
|
||||
**Infrastructure:** Gogle Colab
|
||||
|
||||
|
||||
## Details
|
||||
- We fine-tuned using Pytorch with Huggingface library on Colab GPU.
|
||||
- With standard parameter settings for fine-tuning as mentioned in original BERT's paper.
|
||||
- Although had to train for upto 25 epochs for classification.
|
||||
|
||||
## Performance (Micro precision, recall and f1 score for multilabel code classification)
|
||||
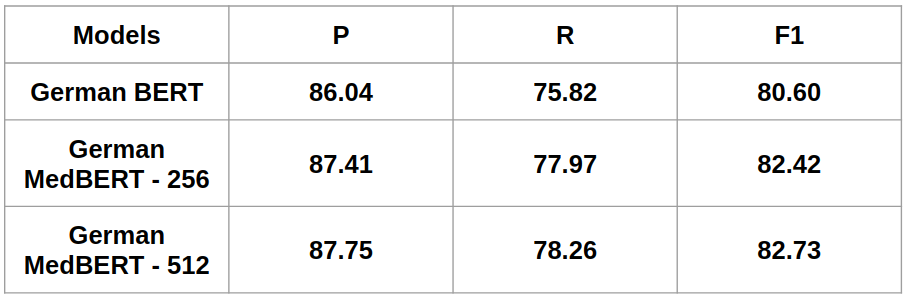
|
||||
|
||||
## Author
|
||||
Manjil Shrestha: `shresthamanjil21 [at] gmail.com`
|
||||
|
||||
Get in touch:
|
||||
[LinkedIn](https://www.linkedin.com/in/manjil-shrestha-038527b4/)
|
||||
@@ -12,8 +12,8 @@ inference: false
|
||||
|
||||
## Disclaimer
|
||||
|
||||
Due do it's immense size, `t5-11b` requires some special treatment.
|
||||
First, `t5-11b` should be loaded with flag `use_cdn` set to `False` as follows:
|
||||
**Before `transformers` v3.5.0**, due do its immense size, `t5-11b` required some special treatment.
|
||||
If you're using transformers `<= v3.4.0`, `t5-11b` should be loaded with flag `use_cdn` set to `False` as follows:
|
||||
|
||||
```python
|
||||
t5 = transformers.T5ForConditionalGeneration.from_pretrained('t5-11b', use_cdn = False)
|
||||
|
||||
@@ -0,0 +1,41 @@
|
||||
---
|
||||
language: et
|
||||
---
|
||||
# EstBERT
|
||||
|
||||
|
||||
### What's this?
|
||||
The EstBERT model is a pretrained BERT<sub>Base</sub> model exclusively trained on Estonian cased corpus on both 128 and 512 sequence length of data.
|
||||
|
||||
### How to use?
|
||||
You can use the model transformer library both in tensorflow and pytorch version.
|
||||
```
|
||||
from transformers import AutoTokenizer, AutoModelForMaskedLM
|
||||
tokenizer = AutoTokenizer.from_pretrained("tartuNLP/EstBERT")
|
||||
model = AutoModelForMaskedLM.from_pretrained("tartuNLP/EstBERT")
|
||||
```
|
||||
You can also download the pretrained model from here, [EstBERT_128]() [EstBERT_512]()
|
||||
#### Dataset used to train the model
|
||||
The EstBERT model is trained both on 128 and 512 sequence length of data. For training the EstBERT we used the [Estonian National Corpus 2017](https://metashare.ut.ee/repository/browse/estonian-national-corpus-2017/b616ceda30ce11e8a6e4005056b40024880158b577154c01bd3d3fcfc9b762b3/), which was the largest Estonian language corpus available at the time. It consists of four sub-corpora: Estonian Reference Corpus 1990-2008, Estonian Web Corpus 2013, Estonian Web Corpus 2017 and Estonian Wikipedia Corpus 2017.
|
||||
|
||||
### Why would I use?
|
||||
Overall EstBERT performs better in parts of speech (POS), name entity recognition (NER), rubric, and sentiment classification tasks compared to mBERT and XLM-RoBERTa. The comparative results can be found below;
|
||||
|
||||
|Model |UPOS |XPOS |Morph |bf UPOS |bf XPOS |Morph |
|
||||
|--------------|----------------------------|-------------|-------------|-------------|----------------------------|----------------------------|
|
||||
| EstBERT | **_97.89_** | **98.40** | **96.93** | **97.84** | **_98.43_** | **_96.80_** |
|
||||
| mBERT | 97.42 | 98.06 | 96.24 | 97.43 | 98.13 | 96.13 |
|
||||
| XLM-RoBERTa | 97.78 | 98.36 | 96.53 | 97.80 | 98.40 | 96.69 |
|
||||
|
||||
|
||||
|Model|Rubric<sub>128</sub> |Sentiment<sub>128</sub> | Rubric<sub>128</sub> |Sentiment<sub>512</sub> |
|
||||
|-------------------|----------------------------|--------------------|-----------------------------------------------|----------------------------|
|
||||
| EstBERT | **_81.70_** | 74.36 | **80.96** | 74.50 |
|
||||
| mBERT | 75.67 | 70.23 | 74.94 | 69.52 |
|
||||
| XLM\-RoBERTa | 80.34 | **74.50** | 78.62 | **_76.07_**|
|
||||
|
||||
|Model |Precicion<sub>128</sub> |Recall<sub>128</sub> |F1-Score<sub>128</sub> |Precision<sub>512</sub> |Recall<sub>512</sub> |F1-Score<sub>512</sub> |
|
||||
|--------------|----------------|----------------------------|----------------------------|----------------------------|-------------|----------------|
|
||||
| EstBERT | **88.42** | 90.38 |**_89.39_** | 88.35 | 89.74 | 89.04 |
|
||||
| mBERT | 85.88 | 87.09 | 86.51 |**_88.47_** | 88.28 | 88.37 |
|
||||
| XLM\-RoBERTa | 87.55 |**_91.19_** | 89.34 | 87.50 | **90.76** | **89.10** |
|
||||
@@ -56,7 +56,3 @@ cd -
|
||||
perl -le 'for $f (@ARGV) { print qq[transformers-cli upload -y $_/$f --filename $_/$f] for ("wmt16-en-de-dist-12-1", "wmt16-en-de-dist-6-1", "wmt16-en-de-12-1")}' vocab-src.json vocab-tgt.json tokenizer_config.json config.json
|
||||
# add/remove files as needed
|
||||
|
||||
# Caching note: Unfortunately due to CDN caching the uploaded model may be unavailable for up to 24hs after upload
|
||||
# So the only way to start using the new model sooner is either:
|
||||
# 1. download it to a local path and use that path as model_name
|
||||
# 2. make sure you use: from_pretrained(..., use_cdn=False) everywhere
|
||||
|
||||
@@ -44,7 +44,3 @@ cd -
|
||||
perl -le 'for $f (@ARGV) { print qq[transformers-cli upload -y $_/$f --filename $_/$f] for ("wmt19-de-en-6-6-base", "wmt19-de-en-6-6-big")}' vocab-src.json vocab-tgt.json tokenizer_config.json config.json
|
||||
# add/remove files as needed
|
||||
|
||||
# Caching note: Unfortunately due to CDN caching the uploaded model may be unavailable for up to 24hs after upload
|
||||
# So the only way to start using the new model sooner is either:
|
||||
# 1. download it to a local path and use that path as model_name
|
||||
# 2. make sure you use: from_pretrained(..., use_cdn=False) everywhere
|
||||
|
||||
@@ -55,7 +55,3 @@ cd -
|
||||
perl -le 'for $f (@ARGV) { print qq[transformers-cli upload -y $_/$f --filename $_/$f] for map { "wmt19-$_" } ("en-ru", "ru-en", "de-en", "en-de")}' vocab-src.json vocab-tgt.json tokenizer_config.json config.json
|
||||
# add/remove files as needed
|
||||
|
||||
# Caching note: Unfortunately due to CDN caching the uploaded model may be unavailable for up to 24hs after upload
|
||||
# So the only way to start using the new model sooner is either:
|
||||
# 1. download it to a local path and use that path as model_name
|
||||
# 2. make sure you use: from_pretrained(..., use_cdn=False) everywhere
|
||||
|
||||
@@ -85,7 +85,7 @@ Pretrained weights were left identical to the original model released by allenai
|
||||
Here are the BLEU scores:
|
||||
|
||||
model | transformers
|
||||
-------|---------|----------
|
||||
-------|---------
|
||||
{model_name} | {scores[model_name][1]}
|
||||
|
||||
The score was calculated using this code:
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user