Compare commits
47
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Thomas Wolf |
3bfeebe722 | ||
|
Thomas Wolf
|
ffed6a8a5d | ||
|
Thomas Wolf
|
426b5106e7 | ||
|
Patrick von Platen
|
a4ee4da18a | ||
|
Patrick von Platen
|
06dd597552 | ||
|
Anirudh Srinivasan
|
9de9ceb6c5 | ||
|
Patrick von Platen
|
b815edf69f | ||
|
HUSEIN ZOLKEPLI
|
8538ce9044 | ||
|
Manuel Romero
|
c1a6252be1 | ||
|
Julien Chaumond
|
50e15c825c | ||
|
Patrick von Platen
|
b38d552a92 | ||
|
Patrick von Platen
|
ae6834e028 | ||
|
Manuel Romero
|
0373b60c4c | ||
|
Patrick von Platen
|
83d1fbcff6 | ||
|
Patrick von Platen
|
55bcae7f25 | ||
|
Patrick von Platen
|
42e1e3c67f | ||
|
Patrick von Platen
|
57b0fab692 | ||
|
Manuel Romero
|
a8d4dff0a1 | ||
|
Manuel Romero
|
4a5663568f | ||
|
Branden Chan
|
bbedb59675 | ||
|
Manuel Romero
|
c2cf192943 | ||
|
Gabriele Sarti
|
c82ef72158 | ||
|
Manuel Romero
|
b48a1f08c1 | ||
|
Manuel Romero
|
99833a9cbf | ||
|
Sho Arora
|
ebceeeacda | ||
|
Leandro von Werra
|
a6c4ee27fd | ||
|
Ethan Perez
|
e5c393dceb | ||
|
Sam Shleifer
|
8deff3acf2 | ||
|
dougianandIoannis Douratsos
|
1f72865726 | ||
|
Julien Chaumond
|
cc598b312b | ||
|
Julien PluandJulien Plu
|
d38bbb225f | ||
|
LysandreJik
|
eff757f2e3 | ||
|
LysandreJik
|
a009d751c2 | ||
|
LysandreJik
|
6f5a12a583 | ||
|
Patrick von Platen
|
296252c49e | ||
|
Patrick von Platen
|
75ec6c9e3a | ||
|
Patrick von Platen
|
5b44e0a31b | ||
|
Sam Shleifer
|
33ef7002e1 | ||
|
Sam Shleifer
|
f6a23d1911 | ||
|
Stefan Schweter
|
601ac5b1dc | ||
|
Patrick von Platen
|
17dceae7a1 | ||
|
Patrick von Platen
|
00ea100e96 | ||
|
Funtowicz Morgan
|
b08259a120 | ||
|
Patrick von Platen
|
f4f4946836 | ||
|
Patrick von Platen
|
fa9af2468a | ||
|
Lysandre Debut
|
ff80b73157 | ||
|
LysandreJik
|
e2c05f06ef |
@@ -47,6 +47,8 @@ Once you have setup `sphinx`, you can build the documentation by running the fol
|
||||
make html
|
||||
```
|
||||
|
||||
A folder called ``_build/html`` should have been created. You can now open the file ``_build/html/index.html`` in your browser.
|
||||
|
||||
---
|
||||
**NOTE**
|
||||
|
||||
|
||||
+1
-1
@@ -26,7 +26,7 @@ author = u'huggingface'
|
||||
# The short X.Y version
|
||||
version = u''
|
||||
# The full version, including alpha/beta/rc tags
|
||||
release = u'2.6.0'
|
||||
release = u'2.7.0'
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
|
||||
@@ -16,13 +16,45 @@ To facilitate future work on transfer learning for NLP, we release our dataset,
|
||||
|
||||
The Authors' code can be found `here <https://github.com/google-research/text-to-text-transfer-transformer>`_ .
|
||||
|
||||
Training
|
||||
~~~~~~~~~~~~~~~~~~~~
|
||||
T5 is an encoder-decoder model and converts all NLP problems into a text-to-text format. It is trained using teacher forcing.
|
||||
This means that for training we always need an input sequence and a target sequence.
|
||||
The input sequence is fed to the model using ``input_ids``. The target sequence is shifted to the right, *i.e.* perprended by a start-sequence token and fed to the decoder using the `decoder_input_ids`. In teacher-forcing style, the target sequence is then appended by the EOS token and corresponds to the ``lm_labels``. The PAD token is hereby used as the start-sequence token.
|
||||
T5 can be trained / fine-tuned both in a supervised and unsupervised fashion.
|
||||
|
||||
- Unsupervised denoising training
|
||||
In this setup spans of the input sequence are masked by so-called sentinel tokens (*a.k.a* unique mask tokens)
|
||||
and the output sequence is formed as a concatenation of the same sentinel tokens and the *real* masked tokens.
|
||||
Each sentinel tokens represents a unique mask token for this sentence and should start with ``<extra_id_1>``, ``<extrac_id_2>``, ... up to ``<extra_id_100>``. As a default 100 sentinel tokens are available in ``T5Tokenizer``.
|
||||
*E.g.* the sentence "The cute dog walks in the park" with the masks put on "cute dog" and "the" should be processed as follows:
|
||||
|
||||
::
|
||||
|
||||
input_ids = tokenizer.encode('The <extra_id_1> walks in <extra_id_2> park', return_tensors='pt')
|
||||
lm_labels = tokenizer.encode('<extra_id_1> cute dog <extra_id_2> the <extra_id_3> </s>', return_tensors='pt')
|
||||
# the forward function automatically creates the correct decoder_input_ids
|
||||
model(input_ids=input_ids, lm_labels=lm_labels)
|
||||
|
||||
- Supervised training
|
||||
In this setup the input sequence and output sequence are standard sequence to sequence input output mapping.
|
||||
In translation, *e.g.* the input sequence "The house is wonderful." and output sequence "Das Haus ist wunderbar." should
|
||||
be processed as follows:
|
||||
|
||||
::
|
||||
|
||||
input_ids = tokenizer.encode('translate English to German: The house is wonderful. </s>', return_tensors='pt')
|
||||
lm_labels = tokenizer.encode('Das Haus ist wunderbar. </s>', return_tensors='pt')
|
||||
# the forward function automatically creates the correct decoder_input_ids
|
||||
model(input_ids=input_ids, lm_labels=lm_labels)
|
||||
|
||||
Tips
|
||||
~~~~~~~~~~~~~~~~~~~~
|
||||
- T5 is an encoder-decoder model pre-trained on a multi-task mixture of unsupervised
|
||||
and supervised tasks and which each task is cast as a sequence to sequence task.
|
||||
Therefore T5 works well on a variety of tasks out-of-the-box by prepending a different prefix to the input corresponding to each task, e.g.: for translation: *translate English to German: ..., summarize: ...*.
|
||||
For more information about the which prefix to use, it is easiest to look into Appendix D of the `paper <https://arxiv.org/pdf/1910.10683.pdf>`_ .
|
||||
- For sequence to sequence generation, it is recommended to use ``T5ForConditionalGeneration.generate()``. The method takes care of feeding the encoded input via cross-attention layers to the decoder and auto-regressively generating the decoder output.
|
||||
and supervised tasks and for which each task is converted into a text-to-text format.
|
||||
T5 works well on a variety of tasks out-of-the-box by prepending a different prefix to the input corresponding to each task, e.g.: for translation: *translate English to German: ..., summarize: ...*.
|
||||
For more information about which prefix to use, it is easiest to look into Appendix D of the `paper <https://arxiv.org/pdf/1910.10683.pdf>`_ .
|
||||
- For sequence to sequence generation, it is recommended to use ``T5ForConditionalGeneration.generate()``. The method takes care of feeding the encoded input via cross-attention layers to the decoder and auto-regressively generates the decoder output.
|
||||
- T5 uses relative scalar embeddings. Encoder input padding can be done on the left and on the right.
|
||||
|
||||
|
||||
@@ -55,7 +87,7 @@ T5ForConditionalGeneration
|
||||
:members:
|
||||
|
||||
|
||||
TFBertModel
|
||||
TFT5Model
|
||||
~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFT5Model
|
||||
|
||||
@@ -275,7 +275,6 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | | | FlauBERT large architecture |
|
||||
| | | (see `details <https://github.com/getalp/Flaubert>`__) |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| Bart | ``bart-large`` | | 12-layer, 1024-hidden, 16-heads, 406M parameters |
|
||||
| | | (see `details <https://github.com/pytorch/fairseq/tree/master/examples/bart>`_) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
@@ -285,6 +284,3 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | ``bart-large-cnn`` | | 12-layer, 1024-hidden, 16-heads, 406M parameters (same as base) |
|
||||
| | | | bart-large base architecture finetuned on cnn summarization task |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
|
||||
|
||||
.. <https://huggingface.co/transformers/examples.html>`__
|
||||
|
||||
+139
-9
@@ -420,7 +420,7 @@ to generate the tokens following the initial sequence in PyTorch, and creating a
|
||||
sequence = f"Hugging Face is based in DUMBO, New York City, and is"
|
||||
|
||||
input = tokenizer.encode(sequence, return_tensors="pt")
|
||||
generated = model.generate(input, max_length=50)
|
||||
generated = model.generate(input, max_length=50, do_sample=True)
|
||||
|
||||
resulting_string = tokenizer.decode(generated.tolist()[0])
|
||||
print(resulting_string)
|
||||
@@ -432,14 +432,10 @@ to generate the tokens following the initial sequence in PyTorch, and creating a
|
||||
model = TFAutoModelWithLMHead.from_pretrained("gpt2")
|
||||
|
||||
sequence = f"Hugging Face is based in DUMBO, New York City, and is"
|
||||
generated = tokenizer.encode(sequence)
|
||||
input = tokenizer.encode(sequence, return_tensors="tf")
|
||||
generated = model.generate(input, max_length=50, do_sample=True)
|
||||
|
||||
for i in range(50):
|
||||
predictions = model(tf.constant([generated]))[0]
|
||||
token = tf.argmax(predictions[0], axis=1)[-1].numpy()
|
||||
generated += [token]
|
||||
|
||||
resulting_string = tokenizer.decode(generated)
|
||||
resulting_string = tokenizer.decode(generated.tolist()[0])
|
||||
print(resulting_string)
|
||||
|
||||
|
||||
@@ -594,4 +590,138 @@ following array should be the output:
|
||||
|
||||
::
|
||||
|
||||
[('[CLS]', 'O'), ('Hu', 'I-ORG'), ('##gging', 'I-ORG'), ('Face', 'I-ORG'), ('Inc', 'I-ORG'), ('.', 'O'), ('is', 'O'), ('a', 'O'), ('company', 'O'), ('based', 'O'), ('in', 'O'), ('New', 'I-LOC'), ('York', 'I-LOC'), ('City', 'I-LOC'), ('.', 'O'), ('Its', 'O'), ('headquarters', 'O'), ('are', 'O'), ('in', 'O'), ('D', 'I-LOC'), ('##UM', 'I-LOC'), ('##BO', 'I-LOC'), (',', 'O'), ('therefore', 'O'), ('very', 'O'), ('##c', 'O'), ('##lose', 'O'), ('to', 'O'), ('the', 'O'), ('Manhattan', 'I-LOC'), ('Bridge', 'I-LOC'), ('.', 'O'), ('[SEP]', 'O')]
|
||||
Summarization
|
||||
----------------------------------------------------
|
||||
|
||||
Summarization is the task of summarizing a text / an article into a shorter text.
|
||||
|
||||
An example of a summarization dataset is the CNN / Daily Mail dataset, which consists of long news articles and was created for the task of summarization.
|
||||
If you would like to fine-tune a model on a summarization task, you may leverage the ``examples/summarization/bart/run_train.sh`` (leveraging pytorch-lightning) script.
|
||||
|
||||
Here is an example using the pipelines do to summarization.
|
||||
It leverages a Bart model that was fine-tuned on the CNN / Daily Mail data set.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
summarizer = pipeline("summarization")
|
||||
|
||||
ARTICLE = """ New York (CNN)When Liana Barrientos was 23 years old, she got married in Westchester County, New York.
|
||||
A year later, she got married again in Westchester County, but to a different man and without divorcing her first husband.
|
||||
Only 18 days after that marriage, she got hitched yet again. Then, Barrientos declared "I do" five more times, sometimes only within two weeks of each other.
|
||||
In 2010, she married once more, this time in the Bronx. In an application for a marriage license, she stated it was her "first and only" marriage.
|
||||
Barrientos, now 39, is facing two criminal counts of "offering a false instrument for filing in the first degree," referring to her false statements on the
|
||||
2010 marriage license application, according to court documents.
|
||||
Prosecutors said the marriages were part of an immigration scam.
|
||||
On Friday, she pleaded not guilty at State Supreme Court in the Bronx, according to her attorney, Christopher Wright, who declined to comment further.
|
||||
After leaving court, Barrientos was arrested and charged with theft of service and criminal trespass for allegedly sneaking into the New York subway through an emergency exit, said Detective
|
||||
Annette Markowski, a police spokeswoman. In total, Barrientos has been married 10 times, with nine of her marriages occurring between 1999 and 2002.
|
||||
All occurred either in Westchester County, Long Island, New Jersey or the Bronx. She is believed to still be married to four men, and at one time, she was married to eight men at once, prosecutors say.
|
||||
Prosecutors said the immigration scam involved some of her husbands, who filed for permanent residence status shortly after the marriages.
|
||||
Any divorces happened only after such filings were approved. It was unclear whether any of the men will be prosecuted.
|
||||
The case was referred to the Bronx District Attorney\'s Office by Immigration and Customs Enforcement and the Department of Homeland Security\'s
|
||||
Investigation Division. Seven of the men are from so-called "red-flagged" countries, including Egypt, Turkey, Georgia, Pakistan and Mali.
|
||||
Her eighth husband, Rashid Rajput, was deported in 2006 to his native Pakistan after an investigation by the Joint Terrorism Task Force.
|
||||
If convicted, Barrientos faces up to four years in prison. Her next court appearance is scheduled for May 18.
|
||||
"""
|
||||
|
||||
print(summarizer(ARTICLE, max_length=130, min_length=30))
|
||||
|
||||
Because the summarization pipeline depends on the ``PretrainedModel.generate()`` method, we can override the default arguments
|
||||
of ``PretrainedModel.generate()`` directly in the pipeline as is shown for ``max_length`` and ``min_length`` above.
|
||||
This outputs the following summary:
|
||||
|
||||
::
|
||||
|
||||
Liana Barrientos has been married 10 times, sometimes within two weeks of each other. Prosecutors say the marriages were part of an immigration scam. She pleaded not guilty at State Supreme Court in the Bronx on Friday.
|
||||
|
||||
Here is an example doing summarization using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. Summarization is usually done using an encoder-decoder model, such as ``Bart`` or ``T5``.
|
||||
- Define the article that should be summarizaed.
|
||||
- Leverage the ``PretrainedModel.generate()`` method.
|
||||
- Add the T5 specific prefix "summarize: ".
|
||||
|
||||
Here Google`s T5 model is used that was only pre-trained on a multi-task mixed data set (including CNN / Daily Mail), but nevertheless yields very good results.
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained("t5-base")
|
||||
tokenizer = AutoTokenizer.from_pretrained("t5-base")
|
||||
|
||||
# T5 uses a max_length of 512 so we cut the article to 512 tokens.
|
||||
inputs = tokenizer.encode("summarize: " + ARTICLE, return_tensors="pt", max_length=512)
|
||||
outputs = model.generate(inputs, max_length=150, min_length=40, length_penalty=2.0, num_beams=4, early_stopping=True)
|
||||
print(outputs)
|
||||
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
model = TFAutoModelWithLMHead.from_pretrained("t5-base")
|
||||
tokenizer = AutoTokenizer.from_pretrained("t5-base")
|
||||
|
||||
# T5 uses a max_length of 512 so we cut the article to 512 tokens.
|
||||
inputs = tokenizer.encode("summarize: " + ARTICLE, return_tensors="tf", max_length=512)
|
||||
outputs = model.generate(inputs, max_length=150, min_length=40, length_penalty=2.0, num_beams=4, early_stopping=True)
|
||||
print(outputs)
|
||||
Translation
|
||||
----------------------------------------------------
|
||||
|
||||
Translation is the task of translating a text from one language to another.
|
||||
|
||||
An example of a translation dataset is the WMT English to German dataset, which has English sentences as the input data
|
||||
and German sentences as the target data.
|
||||
|
||||
Here is an example using the pipelines do to translation.
|
||||
It leverages a T5 model that was only pre-trained on a multi-task mixture dataset (including WMT), but yields impressive
|
||||
translation results nevertheless.
|
||||
|
||||
::
|
||||
|
||||
from transformers import pipeline
|
||||
|
||||
translator = pipeline("translation_en_to_de")
|
||||
print(translator("Hugging Face is a technology company based in New York and Paris", max_length=40))
|
||||
|
||||
Because the translation pipeline depends on the ``PretrainedModel.generate()`` method, we can override the default arguments
|
||||
of ``PretrainedModel.generate()`` directly in the pipeline as is shown for ``max_length`` above.
|
||||
This outputs the following translation into German:
|
||||
|
||||
::
|
||||
|
||||
Hugging Face ist ein Technologieunternehmen mit Sitz in New York und Paris.
|
||||
|
||||
Here is an example doing translation using a model and a tokenizer. The process is the following:
|
||||
|
||||
- Instantiate a tokenizer and a model from the checkpoint name. Summarization is usually done using an encoder-decoder model, such as ``Bart`` or ``T5``.
|
||||
- Define the article that should be summarizaed.
|
||||
- Leverage the ``PretrainedModel.generate()`` method.
|
||||
- Add the T5 specific prefix "translate English to German: "
|
||||
|
||||
::
|
||||
|
||||
## PYTORCH CODE
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained("t5-base")
|
||||
tokenizer = AutoTokenizer.from_pretrained("t5-base")
|
||||
|
||||
inputs = tokenizer.encode("translate English to German: Hugging Face is a technology company based in New York and Paris", return_tensors="pt")
|
||||
outputs = model.generate(inputs, max_length=40, num_beams=4, early_stopping=True)
|
||||
|
||||
print(outputs)
|
||||
|
||||
## TENSORFLOW CODE
|
||||
from transformers import TFAutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
model = TFAutoModelWithLMHead.from_pretrained("t5-base")
|
||||
tokenizer = AutoTokenizer.from_pretrained("t5-base")
|
||||
|
||||
inputs = tokenizer.encode("translate English to German: Hugging Face is a technology company based in New York and Paris", return_tensors="tf")
|
||||
outputs = model.generate(inputs, max_length=40, num_beams=4, early_stopping=True)
|
||||
|
||||
print(outputs)
|
||||
|
||||
@@ -68,7 +68,7 @@ class GLUETransformer(BaseTransformer):
|
||||
output_mode=args.glue_output_mode,
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]), # pad on the left for xlnet
|
||||
pad_token=self.tokenizer.convert_tokens_to_ids([self.tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token_segment_id=self.tokenizer.pad_token_type_id,
|
||||
)
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
torch.save(features, cached_features_file)
|
||||
@@ -192,5 +192,5 @@ if __name__ == "__main__":
|
||||
# Optionally, predict on dev set and write to output_dir
|
||||
if args.do_predict:
|
||||
checkpoints = list(sorted(glob.glob(os.path.join(args.output_dir, "checkpointepoch=*.ckpt"), recursive=True)))
|
||||
GLUETransformer.load_from_checkpoint(checkpoints[-1])
|
||||
model = model.load_from_checkpoint(checkpoints[-1])
|
||||
trainer.test(model)
|
||||
|
||||
@@ -342,8 +342,8 @@ def load_and_cache_examples(args, task, tokenizer, evaluate=False):
|
||||
max_length=args.max_seq_length,
|
||||
output_mode=output_mode,
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]), # pad on the left for xlnet
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token=tokenizer.pad_token_id,
|
||||
pad_token_segment_id=tokenizer.pad_token_type_id,
|
||||
)
|
||||
if args.local_rank in [-1, 0]:
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
|
||||
@@ -348,8 +348,8 @@ def load_and_cache_examples(args, tokenizer, labels, pad_token_label_id, mode):
|
||||
# roberta uses an extra separator b/w pairs of sentences, cf. github.com/pytorch/fairseq/commit/1684e166e3da03f5b600dbb7855cb98ddfcd0805
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]),
|
||||
# pad on the left for xlnet
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token=tokenizer.pad_token_id,
|
||||
pad_token_segment_id=tokenizer.pad_token_type_id,
|
||||
pad_token_label_id=pad_token_label_id,
|
||||
)
|
||||
if args.local_rank in [-1, 0]:
|
||||
|
||||
@@ -64,8 +64,8 @@ class NERTransformer(BaseTransformer):
|
||||
sep_token=self.tokenizer.sep_token,
|
||||
sep_token_extra=bool(args.model_type in ["roberta"]),
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]),
|
||||
pad_token=self.tokenizer.convert_tokens_to_ids([self.tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token=self.tokenizer.pad_token_id,
|
||||
pad_token_segment_id=self.tokenizer.pad_token_type_id,
|
||||
pad_token_label_id=self.pad_token_label_id,
|
||||
)
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
@@ -192,5 +192,5 @@ if __name__ == "__main__":
|
||||
# https://github.com/PyTorchLightning/pytorch-lightning/blob/master\
|
||||
# /pytorch_lightning/callbacks/model_checkpoint.py#L169
|
||||
checkpoints = list(sorted(glob.glob(os.path.join(args.output_dir, "checkpointepoch=*.ckpt"), recursive=True)))
|
||||
NERTransformer.load_from_checkpoint(checkpoints[-1])
|
||||
model = model.load_from_checkpoint(checkpoints[-1])
|
||||
trainer.test(model)
|
||||
|
||||
+13
-16
@@ -157,7 +157,9 @@ def train(
|
||||
writer = tf.summary.create_file_writer("/tmp/mylogs")
|
||||
|
||||
with strategy.scope():
|
||||
loss_fct = tf.keras.losses.SparseCategoricalCrossentropy(reduction=tf.keras.losses.Reduction.NONE)
|
||||
loss_fct = tf.keras.losses.SparseCategoricalCrossentropy(
|
||||
from_logits=True, reduction=tf.keras.losses.Reduction.NONE
|
||||
)
|
||||
optimizer = create_optimizer(args["learning_rate"], num_train_steps, args["warmup_steps"])
|
||||
|
||||
if args["fp16"]:
|
||||
@@ -205,11 +207,9 @@ def train(
|
||||
|
||||
with tf.GradientTape() as tape:
|
||||
logits = model(train_features["input_ids"], **inputs)[0]
|
||||
logits = tf.reshape(logits, (-1, len(labels) + 1))
|
||||
active_loss = tf.reshape(train_features["input_mask"], (-1,))
|
||||
active_logits = tf.boolean_mask(logits, active_loss)
|
||||
train_labels = tf.reshape(train_labels, (-1,))
|
||||
active_labels = tf.boolean_mask(train_labels, active_loss)
|
||||
active_loss = tf.reshape(train_labels, (-1,)) != pad_token_label_id
|
||||
active_logits = tf.boolean_mask(tf.reshape(logits, (-1, len(labels))), active_loss)
|
||||
active_labels = tf.boolean_mask(tf.reshape(train_labels, (-1,)), active_loss)
|
||||
cross_entropy = loss_fct(active_labels, active_logits)
|
||||
loss = tf.reduce_sum(cross_entropy) * (1.0 / train_batch_size)
|
||||
grads = tape.gradient(loss, model.trainable_variables)
|
||||
@@ -329,11 +329,9 @@ def evaluate(args, strategy, model, tokenizer, labels, pad_token_label_id, mode)
|
||||
|
||||
with strategy.scope():
|
||||
logits = model(eval_features["input_ids"], **inputs)[0]
|
||||
tmp_logits = tf.reshape(logits, (-1, len(labels) + 1))
|
||||
active_loss = tf.reshape(eval_features["input_mask"], (-1,))
|
||||
active_logits = tf.boolean_mask(tmp_logits, active_loss)
|
||||
tmp_eval_labels = tf.reshape(eval_labels, (-1,))
|
||||
active_labels = tf.boolean_mask(tmp_eval_labels, active_loss)
|
||||
active_loss = tf.reshape(eval_labels, (-1,)) != pad_token_label_id
|
||||
active_logits = tf.boolean_mask(tf.reshape(logits, (-1, len(labels))), active_loss)
|
||||
active_labels = tf.boolean_mask(tf.reshape(eval_labels, (-1,)), active_loss)
|
||||
cross_entropy = loss_fct(active_labels, active_logits)
|
||||
loss += tf.reduce_sum(cross_entropy) * (1.0 / eval_batch_size)
|
||||
|
||||
@@ -436,8 +434,8 @@ def load_and_cache_examples(args, tokenizer, labels, pad_token_label_id, batch_s
|
||||
# roberta uses an extra separator b/w pairs of sentences, cf. github.com/pytorch/fairseq/commit/1684e166e3da03f5b600dbb7855cb98ddfcd0805
|
||||
pad_on_left=bool(args["model_type"] in ["xlnet"]),
|
||||
# pad on the left for xlnet
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args["model_type"] in ["xlnet"] else 0,
|
||||
pad_token=tokenizer.pad_token_id,
|
||||
pad_token_segment_id=tokenizer.pad_token_type_id,
|
||||
pad_token_label_id=pad_token_label_id,
|
||||
)
|
||||
logging.info("Saving features into cached file %s", cached_features_file)
|
||||
@@ -497,8 +495,8 @@ def main(_):
|
||||
)
|
||||
|
||||
labels = get_labels(args["labels"])
|
||||
num_labels = len(labels) + 1
|
||||
pad_token_label_id = 0
|
||||
num_labels = len(labels)
|
||||
pad_token_label_id = -1
|
||||
config = AutoConfig.from_pretrained(
|
||||
args["config_name"] if args["config_name"] else args["model_name_or_path"],
|
||||
num_labels=num_labels,
|
||||
@@ -522,7 +520,6 @@ def main(_):
|
||||
config=config,
|
||||
cache_dir=args["cache_dir"] if args["cache_dir"] else None,
|
||||
)
|
||||
model.layers[-1].activation = tf.keras.activations.softmax
|
||||
|
||||
train_batch_size = args["per_device_train_batch_size"] * args["n_device"]
|
||||
train_dataset, num_train_examples = load_and_cache_examples(
|
||||
|
||||
@@ -112,12 +112,15 @@ def convert_examples_to_features(
|
||||
label_ids = []
|
||||
for word, label in zip(example.words, example.labels):
|
||||
word_tokens = tokenizer.tokenize(word)
|
||||
tokens.extend(word_tokens)
|
||||
# Use the real label id for the first token of the word, and padding ids for the remaining tokens
|
||||
label_ids.extend([label_map[label]] + [pad_token_label_id] * (len(word_tokens) - 1))
|
||||
|
||||
# bert-base-multilingual-cased sometimes output "nothing ([]) when calling tokenize with just a space.
|
||||
if len(word_tokens) > 0:
|
||||
tokens.extend(word_tokens)
|
||||
# Use the real label id for the first token of the word, and padding ids for the remaining tokens
|
||||
label_ids.extend([label_map[label]] + [pad_token_label_id] * (len(word_tokens) - 1))
|
||||
|
||||
# Account for [CLS] and [SEP] with "- 2" and with "- 3" for RoBERTa.
|
||||
special_tokens_count = 3 if sep_token_extra else 2
|
||||
special_tokens_count = tokenizer.num_added_tokens()
|
||||
if len(tokens) > max_seq_length - special_tokens_count:
|
||||
tokens = tokens[: (max_seq_length - special_tokens_count)]
|
||||
label_ids = label_ids[: (max_seq_length - special_tokens_count)]
|
||||
|
||||
@@ -360,8 +360,8 @@ def load_and_cache_examples(args, task, tokenizer, evaluate=False):
|
||||
max_length=args.max_seq_length,
|
||||
output_mode=output_mode,
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]), # pad on the left for xlnet
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token=tokenizer.pad_token_id,
|
||||
pad_token_segment_id=tokenizer.pad_token_type_id,
|
||||
)
|
||||
if args.local_rank in [-1, 0]:
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
|
||||
@@ -361,7 +361,7 @@ def load_and_cache_examples(args, task, tokenizer, evaluate=False, test=False):
|
||||
args.max_seq_length,
|
||||
tokenizer,
|
||||
pad_on_left=bool(args.model_type in ["xlnet"]), # pad on the left for xlnet
|
||||
pad_token_segment_id=4 if args.model_type in ["xlnet"] else 0,
|
||||
pad_token_segment_id=tokenizer.pad_token_type_id,
|
||||
)
|
||||
if args.local_rank in [-1, 0]:
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
|
||||
@@ -350,8 +350,8 @@ def load_and_cache_examples(args, task, tokenizer, evaluate=False):
|
||||
max_length=args.max_seq_length,
|
||||
output_mode=output_mode,
|
||||
pad_on_left=False,
|
||||
pad_token=tokenizer.convert_tokens_to_ids([tokenizer.pad_token])[0],
|
||||
pad_token_segment_id=0,
|
||||
pad_token=tokenizer.pad_token_id,
|
||||
pad_token_segment_id=tokenizer.pad_token_type_id,
|
||||
)
|
||||
if args.local_rank in [-1, 0]:
|
||||
logger.info("Saving features into cached file %s", cached_features_file)
|
||||
|
||||
@@ -1,13 +1,15 @@
|
||||
### Get the CNN Data
|
||||
### Get Preprocessed CNN Data
|
||||
To be able to reproduce the authors' results on the CNN/Daily Mail dataset you first need to download both CNN and Daily Mail datasets [from Kyunghyun Cho's website](https://cs.nyu.edu/~kcho/DMQA/) (the links next to "Stories") in the same folder. Then uncompress the archives by running:
|
||||
|
||||
```bash
|
||||
tar -xvf cnn_stories.tgz && tar -xvf dailymail_stories.tgz
|
||||
wget https://s3.amazonaws.com/datasets.huggingface.co/summarization/cnn_dm.tgz
|
||||
tar -xzvf cnn_dm.tgz
|
||||
```
|
||||
|
||||
this should make a directory called cnn_dm/ with files like `test.source`.
|
||||
To use your own data, copy that files format. Each article to be summarized is on its own line.
|
||||
|
||||
### Usage
|
||||
### Evaluation
|
||||
To create summaries for each article in dataset, run:
|
||||
```bash
|
||||
python evaluate_cnn.py <path_to_test.source> cnn_test_summaries.txt
|
||||
@@ -16,21 +18,12 @@ the default batch size, 8, fits in 16GB GPU memory, but may need to be adjusted
|
||||
|
||||
|
||||
### Training
|
||||
|
||||
|
||||
|
||||
After downloading the CNN and Daily Mail datasets, preprocess the dataset:
|
||||
```commandline
|
||||
git clone https://github.com/artmatsak/cnn-dailymail
|
||||
cd cnn-dailymail && python make_datafiles.py ../cnn/stories/ ../dailymail/stories/
|
||||
```
|
||||
|
||||
Run the training script: `run_train.sh`
|
||||
|
||||
Run/modify `run_train.sh`
|
||||
|
||||
### Where is the code?
|
||||
The core model is in `src/transformers/modeling_bart.py`. This directory only contains examples.
|
||||
|
||||
### (WIP) Rouge Scores
|
||||
## (WIP) Rouge Scores
|
||||
|
||||
### Stanford CoreNLP Setup
|
||||
```
|
||||
|
||||
@@ -16,15 +16,17 @@ def chunks(lst, n):
|
||||
yield lst[i : i + n]
|
||||
|
||||
|
||||
def generate_summaries(lns, out_file, batch_size=8, device=DEFAULT_DEVICE):
|
||||
def generate_summaries(
|
||||
examples: list, out_file: str, model_name: str, batch_size: int = 8, device: str = DEFAULT_DEVICE
|
||||
):
|
||||
fout = Path(out_file).open("w")
|
||||
model = BartForConditionalGeneration.from_pretrained("bart-large-cnn", output_past=True,).to(device)
|
||||
model = BartForConditionalGeneration.from_pretrained(model_name, output_past=True,).to(device)
|
||||
tokenizer = BartTokenizer.from_pretrained("bart-large")
|
||||
|
||||
max_length = 140
|
||||
min_length = 55
|
||||
|
||||
for batch in tqdm(list(chunks(lns, batch_size))):
|
||||
for batch in tqdm(list(chunks(examples, batch_size))):
|
||||
dct = tokenizer.batch_encode_plus(batch, max_length=1024, return_tensors="pt", pad_to_max_length=True)
|
||||
summaries = model.generate(
|
||||
input_ids=dct["input_ids"].to(device),
|
||||
@@ -43,7 +45,7 @@ def generate_summaries(lns, out_file, batch_size=8, device=DEFAULT_DEVICE):
|
||||
fout.flush()
|
||||
|
||||
|
||||
def _run_generate():
|
||||
def run_generate():
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument(
|
||||
"source_path", type=str, help="like cnn_dm/test.source",
|
||||
@@ -51,6 +53,9 @@ def _run_generate():
|
||||
parser.add_argument(
|
||||
"output_path", type=str, help="where to save summaries",
|
||||
)
|
||||
parser.add_argument(
|
||||
"model_name", type=str, default="bart-large-cnn", help="like bart-large-cnn",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--device", type=str, required=False, default=DEFAULT_DEVICE, help="cuda, cuda:1, cpu etc.",
|
||||
)
|
||||
@@ -58,9 +63,9 @@ def _run_generate():
|
||||
"--bs", type=int, default=8, required=False, help="batch size: how many to summarize at a time",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
lns = [" " + x.rstrip() for x in open(args.source_path).readlines()]
|
||||
generate_summaries(lns, args.output_path, batch_size=args.bs, device=args.device)
|
||||
examples = [" " + x.rstrip() for x in open(args.source_path).readlines()]
|
||||
generate_summaries(examples, args.output_path, args.model_name, batch_size=args.bs, device=args.device)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
_run_generate()
|
||||
run_generate()
|
||||
|
||||
@@ -5,7 +5,7 @@ import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
from .evaluate_cnn import _run_generate
|
||||
from .evaluate_cnn import run_generate
|
||||
|
||||
|
||||
articles = [" New York (CNN)When Liana Barrientos was 23 years old, she got married in Westchester County."]
|
||||
@@ -19,10 +19,14 @@ class TestBartExamples(unittest.TestCase):
|
||||
def test_bart_cnn_cli(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
tmp = Path(tempfile.gettempdir()) / "utest_generations.hypo"
|
||||
tmp = Path(tempfile.gettempdir()) / "utest_generations_bart_sum.hypo"
|
||||
with tmp.open("w") as f:
|
||||
f.write("\n".join(articles))
|
||||
testargs = ["evaluate_cnn.py", str(tmp), "output.txt"]
|
||||
|
||||
output_file_name = Path(tempfile.gettempdir()) / "utest_output_bart_sum.hypo"
|
||||
|
||||
testargs = ["evaluate_cnn.py", str(tmp), str(output_file_name), "sshleifer/bart-tiny-random"]
|
||||
|
||||
with patch.object(sys, "argv", testargs):
|
||||
_run_generate()
|
||||
self.assertTrue(Path("output.txt").exists())
|
||||
run_generate()
|
||||
self.assertTrue(Path(output_file_name).exists())
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
***This script evaluates the the multitask pre-trained checkpoint for ``t5-large`` (see paper [here](https://arxiv.org/pdf/1910.10683.pdf)) on the CNN/Daily Mail test dataset. Please note that the results in the paper were attained using a model fine-tuned on summarization, so that results will be worse here by approx. 0.5 ROUGE points***
|
||||
***This script evaluates the the multitask pre-trained checkpoint for ``t5-base`` (see paper [here](https://arxiv.org/pdf/1910.10683.pdf)) on the CNN/Daily Mail test dataset. Please note that the results in the paper were attained using a model fine-tuned on summarization, so that results will be worse here by approx. 0.5 ROUGE points***
|
||||
|
||||
### Get the CNN Data
|
||||
First, you need to download the CNN data. It's about ~400 MB and can be downloaded by
|
||||
|
||||
@@ -14,13 +14,13 @@ def chunks(lst, n):
|
||||
yield lst[i : i + n]
|
||||
|
||||
|
||||
def generate_summaries(lns, output_file_path, batch_size, device):
|
||||
def generate_summaries(lns, output_file_path, model_size, batch_size, device):
|
||||
output_file = Path(output_file_path).open("w")
|
||||
|
||||
model = T5ForConditionalGeneration.from_pretrained("t5-large")
|
||||
model = T5ForConditionalGeneration.from_pretrained(model_size)
|
||||
model.to(device)
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained("t5-large")
|
||||
tokenizer = T5Tokenizer.from_pretrained(model_size)
|
||||
|
||||
# update config with summarization specific params
|
||||
task_specific_params = model.config.task_specific_params
|
||||
@@ -61,6 +61,12 @@ def calculate_rouge(output_lns, reference_lns, score_path):
|
||||
|
||||
def run_generate():
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument(
|
||||
"model_size",
|
||||
type=str,
|
||||
help="T5 model size, either 't5-small', 't5-base', 't5-large', 't5-3b', 't5-11b'. Defaults to 't5-base'.",
|
||||
default="t5-base",
|
||||
)
|
||||
parser.add_argument(
|
||||
"input_path", type=str, help="like cnn_dm/test_articles_input.txt",
|
||||
)
|
||||
@@ -83,7 +89,7 @@ def run_generate():
|
||||
|
||||
source_lns = [x.rstrip() for x in open(args.input_path).readlines()]
|
||||
|
||||
generate_summaries(source_lns, args.output_path, args.batch_size, args.device)
|
||||
generate_summaries(source_lns, args.output_path, args.model_size, args.batch_size, args.device)
|
||||
|
||||
output_lns = [x.rstrip() for x in open(args.output_path).readlines()]
|
||||
reference_lns = [x.rstrip() for x in open(args.reference_path).readlines()]
|
||||
|
||||
@@ -8,6 +8,9 @@ from unittest.mock import patch
|
||||
from .evaluate_cnn import run_generate
|
||||
|
||||
|
||||
output_file_name = "output_t5_sum.txt"
|
||||
score_file_name = "score_t5_sum.txt"
|
||||
|
||||
articles = ["New York (CNN)When Liana Barrientos was 23 years old, she got married in Westchester County."]
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
@@ -19,11 +22,16 @@ class TestT5Examples(unittest.TestCase):
|
||||
def test_t5_cli(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
tmp = Path(tempfile.gettempdir()) / "utest_generations.hypo"
|
||||
tmp = Path(tempfile.gettempdir()) / "utest_generations_t5_sum.hypo"
|
||||
with tmp.open("w") as f:
|
||||
f.write("\n".join(articles))
|
||||
testargs = ["evaluate_cnn.py", str(tmp), "output.txt", str(tmp), "score.txt"]
|
||||
|
||||
output_file_name = Path(tempfile.gettempdir()) / "utest_output_t5_sum.hypo"
|
||||
score_file_name = Path(tempfile.gettempdir()) / "utest_score_t5_sum.hypo"
|
||||
|
||||
testargs = ["evaluate_cnn.py", "t5-small", str(tmp), str(output_file_name), str(tmp), str(score_file_name)]
|
||||
|
||||
with patch.object(sys, "argv", testargs):
|
||||
run_generate()
|
||||
self.assertTrue(Path("output.txt").exists())
|
||||
self.assertTrue(Path("score.txt").exists())
|
||||
self.assertTrue(Path(output_file_name).exists())
|
||||
self.assertTrue(Path(score_file_name).exists())
|
||||
|
||||
@@ -14,13 +14,13 @@ def chunks(lst, n):
|
||||
yield lst[i : i + n]
|
||||
|
||||
|
||||
def generate_translations(lns, output_file_path, batch_size, device):
|
||||
def generate_translations(lns, output_file_path, model_size, batch_size, device):
|
||||
output_file = Path(output_file_path).open("w")
|
||||
|
||||
model = T5ForConditionalGeneration.from_pretrained("t5-base")
|
||||
model = T5ForConditionalGeneration.from_pretrained(model_size)
|
||||
model.to(device)
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained("t5-base")
|
||||
tokenizer = T5Tokenizer.from_pretrained(model_size)
|
||||
|
||||
# update config with summarization specific params
|
||||
task_specific_params = model.config.task_specific_params
|
||||
@@ -52,6 +52,12 @@ def calculate_bleu_score(output_lns, refs_lns, score_path):
|
||||
|
||||
def run_generate():
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument(
|
||||
"model_size",
|
||||
type=str,
|
||||
help="T5 model size, either 't5-small', 't5-base', 't5-large', 't5-3b', 't5-11b'. Defaults to 't5-base'.",
|
||||
default="t5-base",
|
||||
)
|
||||
parser.add_argument(
|
||||
"input_path", type=str, help="like wmt/newstest2013.en",
|
||||
)
|
||||
@@ -78,7 +84,7 @@ def run_generate():
|
||||
|
||||
input_lns = [x.strip().replace(dash_pattern[0], dash_pattern[1]) for x in open(args.input_path).readlines()]
|
||||
|
||||
generate_translations(input_lns, args.output_path, args.batch_size, args.device)
|
||||
generate_translations(input_lns, args.output_path, args.model_size, args.batch_size, args.device)
|
||||
|
||||
output_lns = [x.strip() for x in open(args.output_path).readlines()]
|
||||
refs_lns = [x.strip().replace(dash_pattern[0], dash_pattern[1]) for x in open(args.reference_path).readlines()]
|
||||
|
||||
@@ -8,7 +8,11 @@ from unittest.mock import patch
|
||||
from .evaluate_wmt import run_generate
|
||||
|
||||
|
||||
text = [" New York (CNN)When Liana Barrientos was 23 years old, she got married in Westchester County."]
|
||||
text = ["When Liana Barrientos was 23 years old, she got married in Westchester County."]
|
||||
translation = ["Als Liana Barrientos 23 Jahre alt war, heiratete sie in Westchester County."]
|
||||
|
||||
output_file_name = "output_t5_trans.txt"
|
||||
score_file_name = "score_t5_trans.txt"
|
||||
|
||||
logging.basicConfig(level=logging.DEBUG)
|
||||
|
||||
@@ -19,10 +23,28 @@ class TestT5Examples(unittest.TestCase):
|
||||
def test_t5_cli(self):
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
logger.addHandler(stream_handler)
|
||||
tmp = Path(tempfile.gettempdir()) / "utest_generations.hypo"
|
||||
with tmp.open("w") as f:
|
||||
|
||||
tmp_source = Path(tempfile.gettempdir()) / "utest_generations_t5_trans.hypo"
|
||||
with tmp_source.open("w") as f:
|
||||
f.write("\n".join(text))
|
||||
testargs = ["evaluate_cnn.py", str(tmp), "output.txt", str(tmp), "score.txt"]
|
||||
|
||||
tmp_target = Path(tempfile.gettempdir()) / "utest_generations_t5_trans.target"
|
||||
with tmp_target.open("w") as f:
|
||||
f.write("\n".join(translation))
|
||||
|
||||
output_file_name = Path(tempfile.gettempdir()) / "utest_output_trans.hypo"
|
||||
score_file_name = Path(tempfile.gettempdir()) / "utest_score.hypo"
|
||||
|
||||
testargs = [
|
||||
"evaluate_wmt.py",
|
||||
"t5-small",
|
||||
str(tmp_source),
|
||||
str(output_file_name),
|
||||
str(tmp_target),
|
||||
str(score_file_name),
|
||||
]
|
||||
|
||||
with patch.object(sys, "argv", testargs):
|
||||
run_generate()
|
||||
self.assertTrue(Path("output.txt").exists())
|
||||
self.assertTrue(Path(output_file_name).exists())
|
||||
self.assertTrue(Path(score_file_name).exists())
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: german
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz German BERT models
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: german
|
||||
license: mit
|
||||
tags:
|
||||
- "historic german"
|
||||
---
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: german
|
||||
license: mit
|
||||
tags:
|
||||
- "historic german"
|
||||
---
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: german
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz German BERT models
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: italian
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: italian
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: italian
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: italian
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: turkish
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Turkish BERT model
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: turkish
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Turkish BERT model
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: turkish
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Turkish BERT model
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: turkish
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Turkish BERT model
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
---
|
||||
language: turkish
|
||||
license: mit
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz Distilled Turkish BERT model
|
||||
|
||||
@@ -0,0 +1,59 @@
|
||||
This language model is trained using sentence_transformers (https://github.com/UKPLab/sentence-transformers)
|
||||
Started with bert-base-nli-stsb-mean-tokens
|
||||
Continue training on quora questions deduplication dataset (https://www.kaggle.com/c/quora-question-pairs)
|
||||
See train_script.py for script used
|
||||
|
||||
Below is the performance over the course of training
|
||||
epoch,steps,cosine_pearson,cosine_spearman,euclidean_pearson,euclidean_spearman,manhattan_pearson,manhattan_spearman,dot_pearson,dot_spearman
|
||||
0,1000,0.5944576426835938,0.6010801382777033,0.5942803776859142,0.5934485776801595,0.5939676679774666,0.593162725602328,0.5905591590826669,0.5921674789994058
|
||||
0,2000,0.6404080440207146,0.6416811632113405,0.6384419354012121,0.6352050423100778,0.6379917744471867,0.6347884067391001,0.6410544760582826,0.6379252046791412
|
||||
0,3000,0.6710168301884945,0.6676529324662036,0.6660195209784969,0.6618423144808695,0.6656461098096684,0.6615366331956389,0.6724401903484759,0.666073727723655
|
||||
0,4000,0.6886373265097949,0.6808948140300153,0.67907655686838,0.6714218133850957,0.6786809551564443,0.6711577956884357,0.6926435869763303,0.68190855298609
|
||||
0,5000,0.6991409753700026,0.6919630610321864,0.6991041519437052,0.6868961486499775,0.6987076032270729,0.6865385550504007,0.7035518148330993,0.6916275246101342
|
||||
0,6000,0.7120367327025509,0.6975005265298305,0.7065567493967201,0.6922375503495235,0.7060005509843024,0.6916475765570651,0.7147094303373102,0.6981390706722722
|
||||
0,7000,0.7254672394728687,0.7130118465900485,0.7261844956277705,0.7086213543110718,0.7257479964972307,0.7079315661881832,0.728729909455115,0.7122743793160531
|
||||
0,8000,0.7402421930101399,0.7216774208330149,0.7367901914441078,0.7166256588352043,0.7362607046874481,0.7158881916281887,0.7433902441373252,0.7220998491980078
|
||||
0,9000,0.7381005358120434,0.7197216844469877,0.7343228719349923,0.7139462687943793,0.7345247569255238,0.7145106206467152,0.7421843672419275,0.720686853053079
|
||||
0,10000,0.7465436564646095,0.7260327107480364,0.7467524239596304,0.7230195666847953,0.7467721566237211,0.7231367593302213,0.749792199122442,0.7263143296580317
|
||||
0,11000,0.7521805421706547,0.7323771570146701,0.7530672061250105,0.729223203496722,0.7530616532823367,0.7293818369675622,0.7552399002305836,0.7320808333541338
|
||||
0,12000,0.7579359969644401,0.7340677616737238,0.7570017235719905,0.7305965412825544,0.7570601853520393,0.730718189957289,0.7611254136080384,0.7351501229591327
|
||||
0,-1,0.7573407371218097,0.7329952035782198,0.755595312163209,0.7291445551777086,0.7557737117990928,0.7295404703700227,0.7607276219361719,0.7342415455980179
|
||||
1,1000,0.7619907683805341,0.7374667949734767,0.7629820517114324,0.7330364216044966,0.7628369522755882,0.7331912674450544,0.7658583898073758,0.7381503446695727
|
||||
1,2000,0.7618972640071228,0.7362151058969478,0.764582212425539,0.7335856230046062,0.7643125513700815,0.7334501607097152,0.7652852805583232,0.7369104639809163
|
||||
1,3000,0.7687362955240467,0.7404674623181671,0.7708304819979073,0.7380959815601529,0.7707835692712482,0.7379796800453193,0.772074854759756,0.7414513460702766
|
||||
1,4000,0.7685047787908202,0.7403088288815168,0.7703522257474043,0.7379787888808298,0.7701221475099808,0.7377898546753812,0.7713755359045312,0.7409415801952219
|
||||
1,5000,0.7696438109797803,0.7410393893292365,0.773270389327895,0.7392953127251652,0.7729880866533291,0.7389853982789335,0.7726236305835863,0.7416278035580925
|
||||
1,6000,0.7749538363837081,0.7436499342062207,0.774879168058157,0.7401827241766746,0.7745754601165837,0.739763415043146,0.7788801166152383,0.7446249060022169
|
||||
1,7000,0.7794560817870597,0.7480970176267153,0.7803506944510302,0.7453305130502859,0.7799867949176531,0.7447100155494814,0.7828208193123926,0.7486740690324809
|
||||
1,8000,0.7855844359073243,0.7496742172376921,0.7828816645965887,0.747176409009761,0.7827584875358967,0.7471037762845532,0.7879159073496309,0.7507349669102151
|
||||
1,9000,0.7844110753729492,0.7507746252693759,0.7847208586489722,0.7485172180290892,0.7846408087474059,0.748491818820158,0.7872061334510225,0.7514470349769437
|
||||
1,10000,0.7881311227435004,0.7530048509727403,0.7886917756879734,0.7508018068765787,0.7883332502188707,0.7505037008187275,0.7910707228932787,0.7537200382362567
|
||||
1,11000,0.7883300109606874,0.7513494487126553,0.7879329130497712,0.749818368689255,0.7876525616593218,0.7494872882301785,0.7911454269743292,0.7522843165147303
|
||||
1,12000,0.7853334933336618,0.7516809747712728,0.7893895316714998,0.749780492728257,0.7890075986655403,0.7494079715118533,0.7885959664070629,0.7523827940133203
|
||||
1,-1,0.7887529238148887,0.7534076729932393,0.7896864404801204,0.7513080079201105,0.7894077512343298,0.7510009899066772,0.7919617393746149,0.7542173273241598
|
||||
2,1000,0.7919209063905188,0.7550167329363414,0.7917464066515253,0.7523043685293455,0.7914371703225378,0.7520285423781206,0.7950297421784158,0.7562599556207076
|
||||
2,2000,0.7924507768792486,0.7542908512484463,0.7934519001953887,0.7517491515010692,0.7931885648751081,0.751521004535999,0.7951637852162545,0.7551495215642072
|
||||
2,3000,0.7937606244038364,0.755599577136169,0.7933633347508111,0.7527922999916203,0.7931581019714242,0.7527132061436363,0.797275652800117,0.7569827180764233
|
||||
2,4000,0.7938389298721445,0.7578716892320315,0.7963783770097079,0.7555928931784702,0.796150381773947,0.7555438771581088,0.7972911620482322,0.759178632650707
|
||||
2,5000,0.7935330563129844,0.7551129824372304,0.7970775059297484,0.7527285792572385,0.7967359830546507,0.7524478515463257,0.7966395126138969,0.756319220359678
|
||||
2,6000,0.7929852776759999,0.7525490026774382,0.7952484474454824,0.7503695753216607,0.7950784132079611,0.7503677929234961,0.7956152082976395,0.7535275392698093
|
||||
2,7000,0.794956504054517,0.756119591765251,0.7982025041673655,0.7532521587180684,0.7980261618830962,0.7532107179960499,0.7983222918908033,0.7571226363678287
|
||||
2,8000,0.7934568432535339,0.7538336661192452,0.797015698241178,0.7514773358161916,0.7968076980315735,0.7513458838811067,0.7960694134685949,0.754143803399873
|
||||
2,9000,0.7970040626682157,0.7576497805894974,0.7987855332059015,0.7550996144509958,0.7984693921009676,0.7548260162973456,0.7999509314900626,0.758347143906916
|
||||
2,10000,0.7979442987735523,0.7585338500791028,0.8018677081664496,0.7557412777548302,0.8015397301245205,0.7552916678886369,0.8007921348414564,0.7589772216225288
|
||||
2,11000,0.7985519561040211,0.7579986850302035,0.8021236875460913,0.7555826443181872,0.8019861620475348,0.7553763317660516,0.8009230128897853,0.7586541619907702
|
||||
2,12000,0.7986842143860736,0.7599570950134775,0.8029131054823838,0.7577678644678973,0.8027922603736795,0.7575152095990927,0.8020896747930555,0.7608540869254408
|
||||
2,-1,0.7994135319568432,0.7596286881516635,0.8022087183675333,0.7570593611974978,0.8020218401019292,0.7567291719729909,0.8026346812258125,0.7603928913647044
|
||||
3,1000,0.7985505039929134,0.7592588405681144,0.8023296699449267,0.7569345933969436,0.8023622066009718,0.7570237132696928,0.8013054275981851,0.759643838536062
|
||||
3,2000,0.7995482191699455,0.759205368623176,0.8026859405513612,0.7565709841358819,0.8024845263367439,0.7562920388231202,0.8021318586127523,0.7596496313300967
|
||||
3,3000,0.7991070423195897,0.7582027696555826,0.8016352550470427,0.7555585819429662,0.8014268261947898,0.7551838327642736,0.8013136081494014,0.7584429477727118
|
||||
3,4000,0.7999188836884763,0.7586764419322649,0.802987646214278,0.7561111254802977,0.8026549791861386,0.7556463650525692,0.8024068858366156,0.7591238238715613
|
||||
3,5000,0.7988075932525881,0.7583533823004922,0.8019498750207454,0.755792967372457,0.8016459824731964,0.7553834613587099,0.8015528810821693,0.7589527136833425
|
||||
3,6000,0.8003341798460688,0.7585432077405799,0.8032464035902267,0.7563722467405277,0.8028695045742804,0.7557626665682309,0.8027937010871594,0.7590404967573696
|
||||
3,7000,0.799187592384933,0.7579358555659604,0.8028413548398412,0.7555875459131398,0.8025187078191003,0.7551196665011402,0.8018680475193432,0.7585565756912578
|
||||
3,8000,0.797725037202641,0.757439012042047,0.802048241301358,0.7548888458326453,0.8017608103042271,0.7544606246736175,0.8005479449399782,0.758037452190282
|
||||
3,9000,0.7990232649360067,0.7573703896772077,0.8021375332910405,0.754873027155089,0.8018733796679427,0.7545680141630304,0.8016400687760605,0.7579461042843499
|
||||
3,10000,0.7994934439260372,0.758368978248884,0.8035693504115055,0.75619400688862,0.8032990505007025,0.7559016935896375,0.8022819185772518,0.7589558328445544
|
||||
3,11000,0.8002954591825011,0.758710753096932,0.8043310859792212,0.7566387152306694,0.8040865016706966,0.7564221538891368,0.8030873114870971,0.7592722085543488
|
||||
3,12000,0.8003726616196549,0.7588056657991931,0.8044000317617518,0.7566146528909147,0.8041705213966136,0.7563419459362758,0.8031760015719815,0.7593194421057111
|
||||
3,-1,0.8004926728141455,0.7587192194882135,0.8043340929890026,0.756546030526114,0.8041028559910275,0.7563103085106637,0.8032542493776693,0.7592325501951863
|
||||
@@ -0,0 +1,38 @@
|
||||
# CovidBERT-NLI
|
||||
|
||||
This is the model **CovidBERT** trained by DeepSet on AllenAI's [CORD19 Dataset](https://pages.semanticscholar.org/coronavirus-research) of scientific articles about coronaviruses.
|
||||
|
||||
The model uses the original BERT wordpiece vocabulary and was subsequently fine-tuned on the [SNLI](https://nlp.stanford.edu/projects/snli/) and the [MultiNLI](https://www.nyu.edu/projects/bowman/multinli/) datasets using the [`sentence-transformers` library](https://github.com/UKPLab/sentence-transformers/) to produce universal sentence embeddings [1] using the **average pooling strategy** and a **softmax loss**.
|
||||
|
||||
Parameter details for the original training on CORD-19 are available on [DeepSet's MLFlow](https://public-mlflow.deepset.ai/#/experiments/2/runs/ba27d00c30044ef6a33b1d307b4a6cba)
|
||||
|
||||
**Base model**: `deepset/covid_bert_base` from HuggingFace's `AutoModel`.
|
||||
|
||||
**Training time**: ~6 hours on the NVIDIA Tesla P100 GPU provided in Kaggle Notebooks.
|
||||
|
||||
**Parameters**:
|
||||
|
||||
| Parameter | Value |
|
||||
|------------------|-------|
|
||||
| Batch size | 64 |
|
||||
| Training steps | 23000 |
|
||||
| Warmup steps | 1450 |
|
||||
| Lowercasing | True |
|
||||
| Max. Seq. Length | 128 |
|
||||
|
||||
**Performances**: The performance was evaluated on the test portion of the [STS dataset](http://ixa2.si.ehu.es/stswiki/index.php/STSbenchmark) using Spearman rank correlation and compared to the performances of similar models obtained with the same procedure to verify its performances.
|
||||
|
||||
| Model | Score |
|
||||
|-------------------------------|-------------|
|
||||
| `covidbert-nli` (this) | 67.52 |
|
||||
| `gsarti/biobert-nli` | 73.40 |
|
||||
| `gsarti/scibert-nli` | 74.50 |
|
||||
| `bert-base-nli-mean-tokens`[2]| 77.12 |
|
||||
|
||||
An example usage for similarity-based scientific paper retrieval is provided in the [Covid-19 Semantic Browser](https://github.com/gsarti/covid-papers-browser) repository.
|
||||
|
||||
**References:**
|
||||
|
||||
[1] A. Conneau et al., [Supervised Learning of Universal Sentence Representations from Natural Language Inference Data](https://www.aclweb.org/anthology/D17-1070/)
|
||||
|
||||
[2] N. Reimers et I. Gurevych, [Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks](https://www.aclweb.org/anthology/D19-1410/)
|
||||
@@ -0,0 +1,92 @@
|
||||
---
|
||||
language: malay
|
||||
---
|
||||
|
||||
# Bahasa Tiny-BERT Model
|
||||
|
||||
General Distilled Tiny BERT base language model for Malay and Indonesian.
|
||||
|
||||
## Pretraining Corpus
|
||||
|
||||
`tiny-bert-bahasa-cased` model was distilled on ~1.8 Billion words. We distilled on both standard and social media language structures, and below is list of data we distilled on,
|
||||
|
||||
1. [dumping wikipedia](https://github.com/huseinzol05/Malaya-Dataset#wikipedia-1).
|
||||
2. [local instagram](https://github.com/huseinzol05/Malaya-Dataset#instagram).
|
||||
3. [local twitter](https://github.com/huseinzol05/Malaya-Dataset#twitter-1).
|
||||
4. [local news](https://github.com/huseinzol05/Malaya-Dataset#public-news).
|
||||
5. [local parliament text](https://github.com/huseinzol05/Malaya-Dataset#parliament).
|
||||
6. [local singlish/manglish text](https://github.com/huseinzol05/Malaya-Dataset#singlish-text).
|
||||
7. [IIUM Confession](https://github.com/huseinzol05/Malaya-Dataset#iium-confession).
|
||||
8. [Wattpad](https://github.com/huseinzol05/Malaya-Dataset#wattpad).
|
||||
9. [Academia PDF](https://github.com/huseinzol05/Malaya-Dataset#academia-pdf).
|
||||
|
||||
Preprocessing steps can reproduce from here, [Malaya/pretrained-model/preprocess](https://github.com/huseinzol05/Malaya/tree/master/pretrained-model/preprocess).
|
||||
|
||||
## Distilling details
|
||||
|
||||
- This model was distilled using huawei-noah Tiny-BERT's github [repository](https://github.com/huawei-noah/Pretrained-Language-Model/tree/master/TinyBERT) on 3 Titan V100 32GB VRAM.
|
||||
- All steps can reproduce from here, [Malaya/pretrained-model/tiny-bert](https://github.com/huseinzol05/Malaya/tree/master/pretrained-model/tiny-bert).
|
||||
|
||||
## Load Distilled Model
|
||||
|
||||
You can use this model by installing `torch` or `tensorflow` and Huggingface library `transformers`. And you can use it directly by initializing it like this:
|
||||
|
||||
```python
|
||||
from transformers import AlbertTokenizer, BertModel
|
||||
|
||||
model = BertModel.from_pretrained('huseinzol05/tiny-bert-bahasa-cased')
|
||||
tokenizer = AlbertTokenizer.from_pretrained(
|
||||
'huseinzol05/tiny-base-bahasa-cased',
|
||||
unk_token = '[UNK]',
|
||||
pad_token = '[PAD]',
|
||||
do_lower_case = False,
|
||||
)
|
||||
```
|
||||
|
||||
We use [google/sentencepiece](https://github.com/google/sentencepiece) to train the tokenizer, so to use it, need to load from `AlbertTokenizer`.
|
||||
|
||||
## Example using AutoModelWithLMHead
|
||||
|
||||
```python
|
||||
from transformers import AlbertTokenizer, AutoModelWithLMHead, pipeline
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained('huseinzol05/tiny-base-bahasa-cased')
|
||||
tokenizer = AlbertTokenizer.from_pretrained(
|
||||
'huseinzol05/tiny-base-bahasa-cased',
|
||||
unk_token = '[UNK]',
|
||||
pad_token = '[PAD]',
|
||||
do_lower_case = False,
|
||||
)
|
||||
fill_mask = pipeline('fill-mask', model = model, tokenizer = tokenizer)
|
||||
print(fill_mask('makan ayam dengan [MASK]'))
|
||||
```
|
||||
|
||||
Output is,
|
||||
|
||||
```text
|
||||
[{'sequence': '[CLS] makan ayam dengan berbual[SEP]',
|
||||
'score': 0.00015769545279908925,
|
||||
'token': 17859},
|
||||
{'sequence': '[CLS] makan ayam dengan kembar[SEP]',
|
||||
'score': 0.0001448775001335889,
|
||||
'token': 8289},
|
||||
{'sequence': '[CLS] makan ayam dengan memaklumkan[SEP]',
|
||||
'score': 0.00013484008377417922,
|
||||
'token': 6881},
|
||||
{'sequence': '[CLS] makan ayam dengan Senarai[SEP]',
|
||||
'score': 0.00013061291247140616,
|
||||
'token': 11698},
|
||||
{'sequence': '[CLS] makan ayam dengan Tiga[SEP]',
|
||||
'score': 0.00012453157978598028,
|
||||
'token': 4232}]
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
For further details on the model performance, simply checkout accuracy page from Malaya, https://malaya.readthedocs.io/en/latest/Accuracy.html, we compared with traditional models.
|
||||
|
||||
## Acknowledgement
|
||||
|
||||
Thanks to [Im Big](https://www.facebook.com/imbigofficial/), [LigBlou](https://www.facebook.com/ligblou), [Mesolitica](https://mesolitica.com/) and [KeyReply](https://www.keyreply.com/) for sponsoring AWS, Google and GPU clouds to train BERT for Bahasa.
|
||||
|
||||
|
||||
@@ -50,7 +50,7 @@ tokenizer = XLNetTokenizer.from_pretrained(
|
||||
'huseinzol05/xlnet-base-bahasa-cased', do_lower_case = False
|
||||
)
|
||||
fill_mask = pipeline('fill-mask', model = model, tokenizer = tokenizer)
|
||||
print(fill_mask('makan ayam dengan [MASK]'))
|
||||
print(fill_mask('makan ayam dengan <mask>'))
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
@@ -0,0 +1,14 @@
|
||||
# BERT-IMDB
|
||||
|
||||
## What is it?
|
||||
BERT (`bert-large-cased`) trained for sentiment classification on the [IMDB dataset](https://www.kaggle.com/lakshmi25npathi/imdb-dataset-of-50k-movie-reviews).
|
||||
|
||||
## Training setting
|
||||
|
||||
The model was trained on 80% of the IMDB dataset for sentiment classification for three epochs with a learning rate of `1e-5` with the `simpletransformers` library. The library uses a learning rate schedule.
|
||||
|
||||
## Result
|
||||
The model achieved 90% classification accuracy on the validation set.
|
||||
|
||||
## Reference
|
||||
The full experiment is available in the [tlr repo](https://lvwerra.github.io/trl/03-bert-imdb-training/).
|
||||
@@ -0,0 +1,18 @@
|
||||
# GPT2-IMDB-pos
|
||||
|
||||
## What is it?
|
||||
A small GPT2 (`lvwerra/gpt2-imdb`) language model fine-tuned to produce positive movie reviews based the [IMDB dataset](https://www.kaggle.com/lakshmi25npathi/imdb-dataset-of-50k-movie-reviews). The model is trained with rewards from a BERT sentiment classifier (`lvwerra/gpt2-imdb`) via PPO.
|
||||
|
||||
## Training setting
|
||||
The model was trained for `100` optimisation steps with a batch size of `256` which corresponds to `25600` training samples. The full experiment setup can be found in the Jupyter notebook in the [trl repo](https://lvwerra.github.io/trl/04-gpt2-sentiment-ppo-training/).
|
||||
|
||||
## Examples
|
||||
A few examples of the model response to a query before and after optimisation:
|
||||
|
||||
| query | response (before) | response (after) | rewards (before) | rewards (after) |
|
||||
|-------|-------------------|------------------|------------------|-----------------|
|
||||
|I'd never seen a |heavier, woodier example of Victorian archite... |film of this caliber, and I think it's wonder... |3.297736 |4.158653|
|
||||
|I love John's work |but I actually have to write language as in w... |and I hereby recommend this film. I am really... |-1.904006 |4.159198 |
|
||||
|I's a big struggle |to see anyone who acts in that way. by Jim Th... |, but overall I'm happy with the changes even ... |-1.595925 |2.651260|
|
||||
|
||||
|
||||
@@ -0,0 +1,27 @@
|
||||
# GPT2-IMDB
|
||||
|
||||
## What is it?
|
||||
A GPT2 (`gpt2`) language model fine-tuned on the [IMDB dataset](https://www.kaggle.com/lakshmi25npathi/imdb-dataset-of-50k-movie-reviews).
|
||||
|
||||
## Training setting
|
||||
|
||||
The GPT2 language model was fine-tuned for 1 epoch on the IMDB dataset. All comments were joined into a single text file separated by the EOS token:
|
||||
|
||||
```
|
||||
import pandas as pd
|
||||
df = pd.read_csv("imdb-dataset.csv")
|
||||
imdb_str = " <|endoftext|> ".join(df['review'].tolist())
|
||||
|
||||
with open ('imdb.txt', 'w') as f:
|
||||
f.write(imdb_str)
|
||||
```
|
||||
|
||||
To train the model the `run_language_modeling.py` script in the `transformer` library was used:
|
||||
|
||||
```
|
||||
python run_language_modeling.py
|
||||
--train_data_file imdb.txt
|
||||
--output_dir gpt2-imdb
|
||||
--model_type gpt2
|
||||
--model_name_or_path gpt2
|
||||
```
|
||||
@@ -5,15 +5,16 @@ thumbnail:
|
||||
|
||||
# GPT-2 + CORD19 dataset : 🦠 ✍ ⚕
|
||||
|
||||
**GPT-2** fine-tuned on **biorxiv_medrxiv** and **comm_use_subset files** from [CORD-19](https://www.kaggle.com/allen-institute-for-ai/CORD-19-research-challenge) dataset.
|
||||
**GPT-2** fine-tuned on **biorxiv_medrxiv**, **comm_use_subset** and **custom_license** files from [CORD-19](https://www.kaggle.com/allen-institute-for-ai/CORD-19-research-challenge) dataset.
|
||||
|
||||
|
||||
## Datasets details:
|
||||
## Datasets details
|
||||
|
||||
| Dataset | # Files |
|
||||
| ---------------------- | ----- |
|
||||
| biorxiv_medrxiv | 885 |
|
||||
| comm_use_subse | 9K |
|
||||
| comm_use_subset | 9K |
|
||||
| custom_license | 20.6K |
|
||||
|
||||
## Model training
|
||||
|
||||
@@ -37,7 +38,7 @@ python run_language_modeling.py \
|
||||
|
||||
<img alt="training loss" src="https://svgshare.com/i/JTf.svg' title='GTP-2-finetuned-CORDS19-loss" width="600" height="300" />
|
||||
|
||||
## Model in action / Example of usage: ✒
|
||||
## Model in action / Example of usage ✒
|
||||
|
||||
You can get the following script [here](https://github.com/huggingface/transformers/blob/master/examples/run_generation.py)
|
||||
|
||||
|
||||
@@ -0,0 +1,62 @@
|
||||
---
|
||||
language: english
|
||||
thumbnail:
|
||||
---
|
||||
|
||||
# GPT-2 + bio/medrxiv files from CORD19: 🦠 ✍ ⚕
|
||||
|
||||
**GPT-2** fine-tuned on **biorxiv_medrxiv** files from [CORD-19](https://www.kaggle.com/allen-institute-for-ai/CORD-19-research-challenge) dataset.
|
||||
|
||||
|
||||
## Datasets details:
|
||||
|
||||
| Dataset | # Files |
|
||||
| ---------------------- | ----- |
|
||||
| biorxiv_medrxiv | 885 |
|
||||
|
||||
|
||||
## Model training:
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||
|
||||
```bash
|
||||
|
||||
export TRAIN_FILE=/path/to/dataset/train.txt
|
||||
|
||||
python run_language_modeling.py \
|
||||
--model_type gpt2 \
|
||||
--model_name_or_path gpt2 \
|
||||
--do_train \
|
||||
--train_data_file $TRAIN_FILE \
|
||||
--num_train_epochs 4 \
|
||||
--output_dir model_output \
|
||||
--overwrite_output_dir \
|
||||
--save_steps 2000 \
|
||||
--per_gpu_train_batch_size 3
|
||||
```
|
||||
|
||||
## Model in action / Example of usage: ✒
|
||||
|
||||
You can get the following script [here](https://github.com/huggingface/transformers/blob/master/examples/run_generation.py)
|
||||
|
||||
```bash
|
||||
python run_generation.py \
|
||||
--model_type gpt2 \
|
||||
--model_name_or_path mrm8488/GPT-2-finetuned-CORD19 \
|
||||
--length 200
|
||||
```
|
||||
```txt
|
||||
👵👴🦠
|
||||
# Input: Old people with COVID-19 tends to suffer
|
||||
# Output: === GENERATED SEQUENCE 1 ===
|
||||
Old people with COVID-19 tends to suffer more symptom onset time and death. It is well known that many people with COVID-19 have high homozygous ZIKV infection in the face of severe symptoms in both severe and severe cases.
|
||||
The origin of Wuhan Fever was investigated by Prof. Shen Jiang at the outbreak of Wuhan Fever [34]. As Huanan Province is the epicenter of this outbreak, Huanan, the epicenter of epidemic Wuhan Fever, is the most potential location for the direct transmission of infection (source: Zhongzhen et al., 2020). A negative risk ratio indicates more frequent underlying signs in the people in Huanan Province with COVID-19 patients. Further analysis of reported Huanan Fever onset data in the past two years indicated that the intensity of exposure is the key risk factor for developing MERS-CoV infection in this region, especially among children and elderly. To be continued to develop infected patients would be a very important area for
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -66,6 +66,8 @@ nlp_ner = pipeline(
|
||||
{"use_fast": False}
|
||||
))
|
||||
|
||||
text = 'Mis amigos están pensando viajar a Londres este verano'
|
||||
|
||||
nlp_ner(text)
|
||||
|
||||
#Output: [{'entity': 'B-LOC', 'score': 0.9998720288276672, 'word': 'Londres'}]
|
||||
|
||||
@@ -0,0 +1,83 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail:
|
||||
---
|
||||
|
||||
# Spanish BERT (BETO) + Syntax POS tagging ✍🏷
|
||||
|
||||
This model is a fine-tuned version of the Spanish BERT [(BETO)](https://github.com/dccuchile/beto) on Spanish **syntax** annotations in [CONLL CORPORA](https://www.kaggle.com/nltkdata/conll-corpora) dataset for **syntax POS** (Part of Speech tagging) downstream task.
|
||||
|
||||
## Details of the downstream task (Syntax POS) - Dataset
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora)
|
||||
|
||||
#### [Fine-tune script on NER dataset provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
#### 21 Syntax annotations (Labels) covered:
|
||||
|
||||
- \_
|
||||
- ATR
|
||||
- ATR.d
|
||||
- CAG
|
||||
- CC
|
||||
- CD
|
||||
- CD.Q
|
||||
- CI
|
||||
- CPRED
|
||||
- CPRED.CD
|
||||
- CPRED.SUJ
|
||||
- CREG
|
||||
- ET
|
||||
- IMPERS
|
||||
- MOD
|
||||
- NEG
|
||||
- PASS
|
||||
- PUNC
|
||||
- ROOT
|
||||
- SUJ
|
||||
- VOC
|
||||
|
||||
## Metrics on test set 📋
|
||||
|
||||
| Metric | # score |
|
||||
| :-------: | :-------: |
|
||||
| F1 | **89.27** |
|
||||
| Precision | **89.44** |
|
||||
| Recall | **89.11** |
|
||||
|
||||
## Model in action 🔨
|
||||
|
||||
Fast usage with **pipelines** 🧪
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp_pos_syntax = pipeline(
|
||||
"ner",
|
||||
model="mrm8488/bert-spanish-cased-finetuned-pos-syntax",
|
||||
tokenizer="mrm8488/bert-spanish-cased-finetuned-pos-syntax"
|
||||
)
|
||||
|
||||
text = 'Mis amigos están pensando viajar a Londres este verano.'
|
||||
|
||||
nlp_pos_syntax(text)[1:len(nlp_pos_syntax(text))-1]
|
||||
```
|
||||
|
||||
```json
|
||||
[
|
||||
{ "entity": "_", "score": 0.9999216794967651, "word": "Mis" },
|
||||
{ "entity": "SUJ", "score": 0.999882698059082, "word": "amigos" },
|
||||
{ "entity": "_", "score": 0.9998869299888611, "word": "están" },
|
||||
{ "entity": "ROOT", "score": 0.9980518221855164, "word": "pensando" },
|
||||
{ "entity": "_", "score": 0.9998420476913452, "word": "viajar" },
|
||||
{ "entity": "CD", "score": 0.999351978302002, "word": "a" },
|
||||
{ "entity": "_", "score": 0.999959409236908, "word": "Londres" },
|
||||
{ "entity": "_", "score": 0.9998968839645386, "word": "este" },
|
||||
{ "entity": "CC", "score": 0.99931401014328, "word": "verano" },
|
||||
{ "entity": "PUNC", "score": 0.9998534917831421, "word": "." }
|
||||
]
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -21,7 +21,7 @@ I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
- Labels covered:
|
||||
- **60** Labels covered:
|
||||
|
||||
```
|
||||
AO, AQ, CC, CS, DA, DD, DE, DI, DN, DP, DT, Faa, Fat, Fc, Fd, Fe, Fg, Fh, Fia, Fit, Fp, Fpa, Fpt, Fs, Ft, Fx, Fz, I, NC, NP, P0, PD, PI, PN, PP, PR, PT, PX, RG, RN, SP, VAI, VAM, VAN, VAP, VAS, VMG, VMI, VMM, VMN, VMP, VMS, VSG, VSI, VSM, VSN, VSP, VSS, Y and Z
|
||||
@@ -74,6 +74,8 @@ nlp_pos(text)
|
||||
```
|
||||
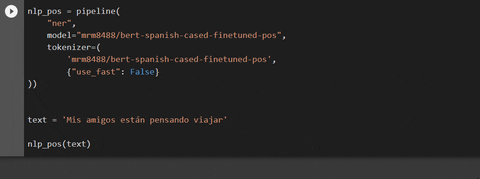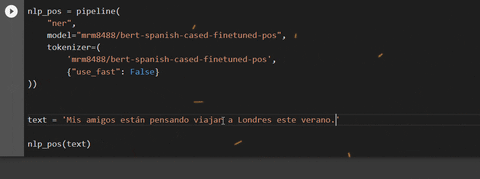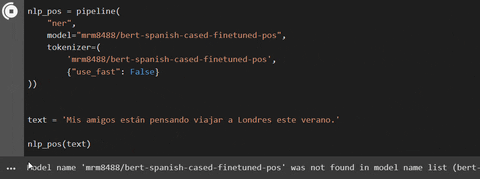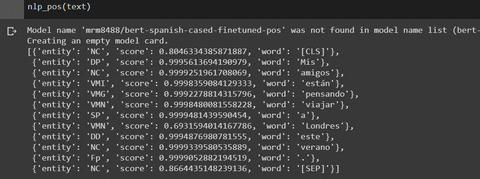
|
||||
|
||||
16 POS tags version also available [here](https://huggingface.co/mrm8488/bert-spanish-cased-finetuned-pos-16-tags)
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
|
||||
@@ -0,0 +1,82 @@
|
||||
---
|
||||
language: multilingual
|
||||
thumbnail:
|
||||
---
|
||||
|
||||
# DistilBERT multilingual fine-tuned on TydiQA (GoldP task) dataset for multilingual Q&A 😛🌍❓
|
||||
|
||||
|
||||
## Details of the language model
|
||||
|
||||
[distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased)
|
||||
|
||||
|
||||
## Details of the Tydi QA dataset
|
||||
|
||||
TyDi QA contains 200k human-annotated question-answer pairs in 11 Typologically Diverse languages, written without seeing the answer and without the use of translation, and is designed for the **training and evaluation** of automatic question answering systems. This repository provides evaluation code and a baseline system for the dataset. https://ai.google.com/research/tydiqa
|
||||
|
||||
|
||||
## Details of the downstream task (Gold Passage or GoldP aka the secondary task)
|
||||
|
||||
Given a passage that is guaranteed to contain the answer, predict the single contiguous span of characters that answers the question. the gold passage task differs from the [primary task](https://github.com/google-research-datasets/tydiqa/blob/master/README.md#the-tasks) in several ways:
|
||||
* only the gold answer passage is provided rather than the entire Wikipedia article;
|
||||
* unanswerable questions have been discarded, similar to MLQA and XQuAD;
|
||||
* we evaluate with the SQuAD 1.1 metrics like XQuAD; and
|
||||
* Thai and Japanese are removed since the lack of whitespace breaks some tools.
|
||||
|
||||
|
||||
## Model training 💪🏋️
|
||||
|
||||
The model was fine-tuned on a Tesla P100 GPU and 25GB of RAM.
|
||||
The script is the following:
|
||||
|
||||
```python
|
||||
python transformers/examples/run_squad.py \
|
||||
--model_type distilbert \
|
||||
--model_name_or_path distilbert-base-multilingual-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--train_file /path/to/dataset/train.json \
|
||||
--predict_file /path/to/dataset/dev.json \
|
||||
--per_gpu_train_batch_size 24 \
|
||||
--per_gpu_eval_batch_size 24 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 5 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /content/model_output \
|
||||
--overwrite_output_dir \
|
||||
--save_steps 1000 \
|
||||
--threads 400
|
||||
```
|
||||
|
||||
## Global Results (dev set) 📝
|
||||
|
||||
| Metric | # Value |
|
||||
| --------- | ----------- |
|
||||
| **EM** | **63.85** |
|
||||
| **F1** | **75.70** |
|
||||
|
||||
## Specific Results (per language) 🌍📝
|
||||
|
||||
| Language | # Samples | # EM | # F1 |
|
||||
| --------- | ----------- |--------| ------ |
|
||||
| Arabic | 1314 | 66.66 | 80.02 |
|
||||
| Bengali | 180 | 53.09 | 63.50 |
|
||||
| English | 654 | 62.42 | 73.12 |
|
||||
| Finnish | 1031 | 64.57 | 75.15 |
|
||||
| Indonesian| 773 | 67.89 | 79.70 |
|
||||
| Korean | 414 | 51.29 | 61.73 |
|
||||
| Russian | 1079 | 55.42 | 70.08 |
|
||||
| Swahili | 596 | 74.51 | 81.15 |
|
||||
| Telegu | 874 | 66.21 | 79.85 |
|
||||
|
||||
|
||||
## Similar models
|
||||
|
||||
You can also try [bert-multi-cased-finedtuned-xquad-tydiqa-goldp](https://huggingface.co/mrm8488/bert-multi-cased-finedtuned-xquad-tydiqa-goldp) that achieves **F1 = 82.16** and **EM = 71.06** (And of course better marks per language).
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -0,0 +1,60 @@
|
||||
# ALECTRA-small-OWT
|
||||
|
||||
This is an extension of
|
||||
[ELECTRA](https://openreview.net/forum?id=r1xMH1BtvB) small model, trained on the
|
||||
[OpenWebText corpus](https://skylion007.github.io/OpenWebTextCorpus/).
|
||||
The training task (discriminative LM / replaced-token-detection) can be generalized to any transformer type. Here, we train an ALBERT model under the same scheme.
|
||||
|
||||
## Pretraining task
|
||||

|
||||
(figure from [Clark et al. 2020](https://openreview.net/pdf?id=r1xMH1BtvB))
|
||||
|
||||
ELECTRA uses discriminative LM / replaced-token-detection for pretraining.
|
||||
This involves a generator (a Masked LM model) creating examples for a discriminator
|
||||
to classify as original or replaced for each token.
|
||||
|
||||
The generator generalizes to any `*ForMaskedLM` model and the discriminator could be
|
||||
any `*ForTokenClassification` model. Therefore, we can extend the task to ALBERT models,
|
||||
not just BERT as in the original paper.
|
||||
|
||||
## Usage
|
||||
```python
|
||||
from transformers import AlbertForSequenceClassification, BertTokenizer
|
||||
|
||||
# Both models use the bert-base-uncased tokenizer and vocab.
|
||||
tokenizer = BertTokenizer.from_pretrained('bert-base-uncased')
|
||||
alectra = AlbertForSequenceClassification.from_pretrained('shoarora/alectra-small-owt')
|
||||
```
|
||||
NOTE: this ALBERT model uses a BERT WordPiece tokenizer.
|
||||
|
||||
## Code
|
||||
The pytorch module that implements this task is available [here](https://github.com/shoarora/lmtuners/blob/master/lmtuners/lightning_modules/discriminative_lm.py).
|
||||
|
||||
Further implementation information [here](https://github.com/shoarora/lmtuners/tree/master/experiments/disc_lm_small),
|
||||
and [here](https://github.com/shoarora/lmtuners/blob/master/experiments/disc_lm_small/train_alectra_small.py) is the script that created this model.
|
||||
|
||||
This specific model was trained with the following params:
|
||||
- `batch_size: 512`
|
||||
- `training_steps: 5e5`
|
||||
- `warmup_steps: 4e4`
|
||||
- `learning_rate: 2e-3`
|
||||
|
||||
|
||||
## Downstream tasks
|
||||
#### GLUE Dev results
|
||||
| Model | # Params | CoLA | SST | MRPC | STS | QQP | MNLI | QNLI | RTE |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| ELECTRA-Small++ | 14M | 57.0 | 91. | 88.0 | 87.5 | 89.0 | 81.3 | 88.4 | 66.7|
|
||||
| ELECTRA-Small-OWT | 14M | 56.8 | 88.3| 87.4 | 86.8 | 88.3 | 78.9 | 87.9 | 68.5|
|
||||
| ELECTRA-Small-OWT (ours) | 17M | 56.3 | 88.4| 75.0 | 86.1 | 89.1 | 77.9 | 83.0 | 67.1|
|
||||
| ALECTRA-Small-OWT (ours) | 4M | 50.6 | 89.1| 86.3 | 87.2 | 89.1 | 78.2 | 85.9 | 69.6|
|
||||
|
||||
|
||||
#### GLUE Test results
|
||||
| Model | # Params | CoLA | SST | MRPC | STS | QQP | MNLI | QNLI | RTE |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| BERT-Base | 110M | 52.1 | 93.5| 84.8 | 85.9 | 89.2 | 84.6 | 90.5 | 66.4|
|
||||
| GPT | 117M | 45.4 | 91.3| 75.7 | 80.0 | 88.5 | 82.1 | 88.1 | 56.0|
|
||||
| ELECTRA-Small++ | 14M | 57.0 | 91.2| 88.0 | 87.5 | 89.0 | 81.3 | 88.4 | 66.7|
|
||||
| ELECTRA-Small-OWT (ours) | 17M | 57.4 | 89.3| 76.2 | 81.9 | 87.5 | 78.1 | 82.4 | 68.1|
|
||||
| ALECTRA-Small-OWT (ours) | 4M | 43.9 | 87.9| 82.1 | 82.0 | 87.6 | 77.9 | 85.8 | 67.5|
|
||||
@@ -0,0 +1,59 @@
|
||||
# ELECTRA-small-OWT
|
||||
|
||||
This is an unnoficial implementation of an
|
||||
[ELECTRA](https://openreview.net/forum?id=r1xMH1BtvB) small model, trained on the
|
||||
[OpenWebText corpus](https://skylion007.github.io/OpenWebTextCorpus/).
|
||||
|
||||
Differences from official ELECTRA models:
|
||||
- we use a `BertForMaskedLM` as the generator and `BertForTokenClassification` as the discriminator
|
||||
- they use an embedding projection layer, but Bert doesn't have one
|
||||
|
||||
## Pretraining ttask
|
||||

|
||||
(figure from [Clark et al. 2020](https://openreview.net/pdf?id=r1xMH1BtvB))
|
||||
|
||||
ELECTRA uses discriminative LM / replaced-token-detection for pretraining.
|
||||
This involves a generator (a Masked LM model) creating examples for a discriminator
|
||||
to classify as original or replaced for each token.
|
||||
|
||||
|
||||
## Usage
|
||||
```python
|
||||
from transformers import BertForSequenceClassification, BertTokenizer
|
||||
|
||||
tokenizer = BertTokenizer.from_pretrained('bert-base-uncased')
|
||||
electra = BertForSequenceClassification.from_pretrained('shoarora/electra-small-owt')
|
||||
```
|
||||
|
||||
## Code
|
||||
The pytorch module that implements this task is available [here](https://github.com/shoarora/lmtuners/blob/master/lmtuners/lightning_modules/discriminative_lm.py).
|
||||
|
||||
Further implementation information [here](https://github.com/shoarora/lmtuners/tree/master/experiments/disc_lm_small),
|
||||
and [here](https://github.com/shoarora/lmtuners/blob/master/experiments/disc_lm_small/train_electra_small.py) is the script that created this model.
|
||||
|
||||
This specific model was trained with the following params:
|
||||
- `batch_size: 512`
|
||||
- `training_steps: 5e5`
|
||||
- `warmup_steps: 4e4`
|
||||
- `learning_rate: 2e-3`
|
||||
|
||||
|
||||
## Downstream tasks
|
||||
#### GLUE Dev results
|
||||
| Model | # Params | CoLA | SST | MRPC | STS | QQP | MNLI | QNLI | RTE |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| ELECTRA-Small++ | 14M | 57.0 | 91. | 88.0 | 87.5 | 89.0 | 81.3 | 88.4 | 66.7|
|
||||
| ELECTRA-Small-OWT | 14M | 56.8 | 88.3| 87.4 | 86.8 | 88.3 | 78.9 | 87.9 | 68.5|
|
||||
| ELECTRA-Small-OWT (ours) | 17M | 56.3 | 88.4| 75.0 | 86.1 | 89.1 | 77.9 | 83.0 | 67.1|
|
||||
| ALECTRA-Small-OWT (ours) | 4M | 50.6 | 89.1| 86.3 | 87.2 | 89.1 | 78.2 | 85.9 | 69.6|
|
||||
|
||||
- Table initialized from [ELECTRA github repo](https://github.com/google-research/electra)
|
||||
|
||||
#### GLUE Test results
|
||||
| Model | # Params | CoLA | SST | MRPC | STS | QQP | MNLI | QNLI | RTE |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| BERT-Base | 110M | 52.1 | 93.5| 84.8 | 85.9 | 89.2 | 84.6 | 90.5 | 66.4|
|
||||
| GPT | 117M | 45.4 | 91.3| 75.7 | 80.0 | 88.5 | 82.1 | 88.1 | 56.0|
|
||||
| ELECTRA-Small++ | 14M | 57.0 | 91.2| 88.0 | 87.5 | 89.0 | 81.3 | 88.4 | 66.7|
|
||||
| ELECTRA-Small-OWT (ours) | 17M | 57.4 | 89.3| 76.2 | 81.9 | 87.5 | 78.1 | 82.4 | 68.1|
|
||||
| ALECTRA-Small-OWT (ours) | 4M | 43.9 | 87.9| 82.1 | 82.0 | 87.6 | 77.9 | 85.8 | 67.5|
|
||||
+3021
-482
File diff suppressed because it is too large
Load Diff
@@ -83,7 +83,7 @@ extras["dev"] = extras["testing"] + extras["quality"] + ["mecab-python3", "sciki
|
||||
|
||||
setup(
|
||||
name="transformers",
|
||||
version="2.6.0",
|
||||
version="2.7.0",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Sam Shleifer, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
author_email="thomas@huggingface.co",
|
||||
description="State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch",
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# There's no way to ignore "F401 '...' imported but unused" warnings in this
|
||||
# module, but to preserve other warnings. So, don't check this module at all.
|
||||
|
||||
__version__ = "2.6.0"
|
||||
__version__ = "2.7.0"
|
||||
|
||||
# Work around to update TensorFlow's absl.logging threshold which alters the
|
||||
# default Python logging output behavior when present.
|
||||
|
||||
@@ -26,6 +26,7 @@ BART_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"bart-large": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large/config.json",
|
||||
"bart-large-mnli": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-mnli/config.json",
|
||||
"bart-large-cnn": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-cnn/config.json",
|
||||
"bart-large-xsum": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-xsum/config.json",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -80,6 +80,7 @@ class PretrainedConfig(object):
|
||||
self.repetition_penalty = kwargs.pop("repetition_penalty", 1.0)
|
||||
self.length_penalty = kwargs.pop("length_penalty", 1.0)
|
||||
self.no_repeat_ngram_size = kwargs.pop("no_repeat_ngram_size", 0)
|
||||
self.bad_words_ids = kwargs.pop("bad_words_ids", None)
|
||||
self.num_return_sequences = kwargs.pop("num_return_sequences", 1)
|
||||
|
||||
# Fine-tuning task arguments
|
||||
|
||||
@@ -17,6 +17,7 @@
|
||||
|
||||
import argparse
|
||||
import logging
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
import fairseq
|
||||
@@ -30,10 +31,11 @@ from transformers import (
|
||||
BartModel,
|
||||
BartTokenizer,
|
||||
)
|
||||
from transformers.modeling_bart import _make_linear_from_emb
|
||||
|
||||
|
||||
FAIRSEQ_MODELS = ["bart.large", "bart.large.mnli", "bart.large.cnn"]
|
||||
|
||||
FAIRSEQ_MODELS = ["bart.large", "bart.large.mnli", "bart.large.cnn", "bart_xsum/model.pt"]
|
||||
extra_arch = {"bart.large": BartModel, "bart.large.mnli": BartForSequenceClassification}
|
||||
if version.parse(fairseq.__version__) < version.parse("0.9.0"):
|
||||
raise Exception("requires fairseq >= 0.9.0")
|
||||
|
||||
@@ -57,62 +59,79 @@ def rename_key(dct, old, new):
|
||||
dct[new] = val
|
||||
|
||||
|
||||
def convert_bart_checkpoint(checkpoint_path, pytorch_dump_folder_path):
|
||||
def load_xsum_checkpoint(checkpoint_path):
|
||||
"""Checkpoint path should end in model.pt"""
|
||||
sd = torch.load(checkpoint_path, map_location="cpu")
|
||||
hub_interface = torch.hub.load("pytorch/fairseq", "bart.large.cnn").eval()
|
||||
hub_interface.model.load_state_dict(sd["model"])
|
||||
return hub_interface
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def convert_bart_checkpoint(checkpoint_path, pytorch_dump_folder_path, hf_checkpoint_name=None):
|
||||
"""
|
||||
Copy/paste/tweak model's weights to our BERT structure.
|
||||
"""
|
||||
bart = torch.hub.load("pytorch/fairseq", checkpoint_path)
|
||||
bart.eval() # disable dropout
|
||||
if not os.path.exists(checkpoint_path):
|
||||
bart = torch.hub.load("pytorch/fairseq", checkpoint_path).eval()
|
||||
else:
|
||||
bart = load_xsum_checkpoint(checkpoint_path)
|
||||
|
||||
bart.model.upgrade_state_dict(bart.model.state_dict())
|
||||
hf_model_name = checkpoint_path.replace(".", "-")
|
||||
config = BartConfig.from_pretrained(hf_model_name)
|
||||
if hf_checkpoint_name is None:
|
||||
hf_checkpoint_name = checkpoint_path.replace(".", "-")
|
||||
config = BartConfig.from_pretrained(hf_checkpoint_name)
|
||||
tokens = bart.encode(SAMPLE_TEXT).unsqueeze(0)
|
||||
tokens2 = BartTokenizer.from_pretrained(hf_model_name).encode(SAMPLE_TEXT, return_tensors="pt").unsqueeze(0)
|
||||
tokens2 = BartTokenizer.from_pretrained(hf_checkpoint_name).encode(SAMPLE_TEXT, return_tensors="pt").unsqueeze(0)
|
||||
assert torch.eq(tokens, tokens2).all()
|
||||
|
||||
if checkpoint_path in ["bart.large", "bart.large.cnn"]:
|
||||
state_dict = bart.model.state_dict()
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
state_dict["shared.weight"] = state_dict["decoder.embed_tokens.weight"]
|
||||
model = BartModel(config)
|
||||
their_output = bart.extract_features(tokens)
|
||||
else: # MNLI Case
|
||||
if checkpoint_path == "bart.large.mnli":
|
||||
state_dict = bart.state_dict()
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
remove_ignore_keys_(state_dict)
|
||||
state_dict["model.shared.weight"] = state_dict["model.decoder.embed_tokens.weight"]
|
||||
for src, dest in rename_keys:
|
||||
rename_key(state_dict, src, dest)
|
||||
model = BartForSequenceClassification(config)
|
||||
their_output = bart.predict("mnli", tokens, return_logits=True)
|
||||
model = BartForSequenceClassification(config).eval()
|
||||
model.load_state_dict(state_dict)
|
||||
fairseq_output = bart.predict("mnli", tokens, return_logits=True)
|
||||
new_model_outputs = model(tokens)[0] # logits
|
||||
else: # no classification heads to worry about
|
||||
state_dict = bart.model.state_dict()
|
||||
remove_ignore_keys_(state_dict)
|
||||
state_dict["shared.weight"] = state_dict["decoder.embed_tokens.weight"]
|
||||
fairseq_output = bart.extract_features(tokens)
|
||||
if hf_checkpoint_name == "bart-large":
|
||||
model = BartModel(config).eval()
|
||||
model.load_state_dict(state_dict)
|
||||
new_model_outputs = model(tokens).model[0]
|
||||
else:
|
||||
model = BartForConditionalGeneration(config).eval() # an existing summarization ckpt
|
||||
model.model.load_state_dict(state_dict)
|
||||
if hasattr(model, "lm_head"):
|
||||
model.lm_head = _make_linear_from_emb(model.model.shared)
|
||||
new_model_outputs = model.model(tokens)[0]
|
||||
|
||||
# Load state dict
|
||||
model.load_state_dict(state_dict)
|
||||
model.eval()
|
||||
# Check results
|
||||
|
||||
if checkpoint_path == "bart.large.cnn":
|
||||
model = BartForConditionalGeneration(config, base_model=model)
|
||||
assert "lm_head.weight" in model.state_dict()
|
||||
assert model.lm_head.out_features == config.max_position_embeddings
|
||||
model.eval()
|
||||
our_outputs = model.model(tokens)[0]
|
||||
else:
|
||||
our_outputs = model(tokens)[0]
|
||||
assert their_output.shape == our_outputs.shape
|
||||
assert (their_output == our_outputs).all().item()
|
||||
assert fairseq_output.shape == new_model_outputs.shape
|
||||
assert (fairseq_output == new_model_outputs).all().item()
|
||||
Path(pytorch_dump_folder_path).mkdir(exist_ok=True)
|
||||
model.save_pretrained(pytorch_dump_folder_path)
|
||||
|
||||
|
||||
def remove_ignore_keys_(state_dict):
|
||||
for k in IGNORE_KEYS:
|
||||
state_dict.pop(k, None)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
# Required parameters
|
||||
parser.add_argument("fairseq_path", choices=FAIRSEQ_MODELS, type=str, help="")
|
||||
|
||||
parser.add_argument("pytorch_dump_folder_path", default=None, type=str, help="Path to the output PyTorch model.")
|
||||
args = parser.parse_args()
|
||||
convert_bart_checkpoint(
|
||||
args.fairseq_path, args.pytorch_dump_folder_path,
|
||||
parser.add_argument(
|
||||
"fairseq_path", type=str, help="bart.large, bart.large.cnn or a path to a model.pt on local filesystem."
|
||||
)
|
||||
parser.add_argument("pytorch_dump_folder_path", default=None, type=str, help="Path to the output PyTorch model.")
|
||||
parser.add_argument(
|
||||
"--hf_config", default=None, type=str, help="Which huggingface architecture to use: bart-large-xsum"
|
||||
)
|
||||
args = parser.parse_args()
|
||||
convert_bart_checkpoint(args.fairseq_path, args.pytorch_dump_folder_path, hf_checkpoint_name=args.hf_config)
|
||||
|
||||
@@ -28,7 +28,7 @@ from ...file_utils import is_tf_available, is_torch_available
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
@dataclass(frozen=False)
|
||||
class InputExample:
|
||||
"""
|
||||
A single training/test example for simple sequence classification.
|
||||
|
||||
@@ -34,6 +34,7 @@ BART_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"bart-large": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large/pytorch_model.bin",
|
||||
"bart-large-mnli": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-mnli/pytorch_model.bin",
|
||||
"bart-large-cnn": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-cnn/pytorch_model.bin",
|
||||
"bart-large-xsum": "https://s3.amazonaws.com/models.huggingface.co/bert/facebook/bart-large-xsum/pytorch_model.bin",
|
||||
}
|
||||
|
||||
BART_START_DOCSTRING = r"""
|
||||
@@ -72,7 +73,7 @@ BART_INPUTS_DOCSTRING = r"""
|
||||
Mask to avoid performing attention on padding token indices in input_ids.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
encoder_outputs (tuple(:obj:`tuple(torch.FloatTensor)`, `optional`, defaults to :obj:`None`):
|
||||
encoder_outputs (:obj:`tuple(tuple(torch.FloatTensor)`, `optional`, defaults to :obj:`None`):
|
||||
Tuple consists of (`last_hidden_state`, `optional`: `hidden_states`, `optional`: `attentions`)
|
||||
`last_hidden_state` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`) is a sequence of hidden-states at the output of the last layer of the encoder.
|
||||
Used in the cross-attention of the decoder.
|
||||
@@ -804,6 +805,8 @@ class BartModel(PretrainedBartModel):
|
||||
|
||||
def set_input_embeddings(self, value):
|
||||
self.shared = value
|
||||
self.encoder.embed_tokens = self.shared
|
||||
self.decoder.embed_tokens = self.shared
|
||||
|
||||
def get_output_embeddings(self):
|
||||
return _make_linear_from_emb(self.shared) # make it on the fly
|
||||
|
||||
@@ -845,7 +845,7 @@ class BertForPreTraining(BertPreTrainedModel):
|
||||
Total loss as the sum of the masked language modeling loss and the next sequence prediction (classification) loss.
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`)
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
seq_relationship_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, 2)`):
|
||||
seq_relationship_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, 2)`):
|
||||
Prediction scores of the next sequence prediction (classification) head (scores of True/False
|
||||
continuation before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when :obj:`config.output_hidden_states=True`):
|
||||
@@ -1048,7 +1048,7 @@ class BertForNextSentencePrediction(BertPreTrainedModel):
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.BertConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`next_sentence_label` is provided):
|
||||
Next sequence prediction (classification) loss.
|
||||
seq_relationship_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, 2)`):
|
||||
seq_relationship_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, 2)`):
|
||||
Prediction scores of the next sequence prediction (classification) head (scores of True/False continuation before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
|
||||
+147
-56
@@ -20,6 +20,7 @@ import itertools
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
from typing import List, Optional
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
@@ -404,6 +405,8 @@ class T5Block(nn.Module):
|
||||
def __init__(self, config, has_relative_attention_bias=False):
|
||||
super().__init__()
|
||||
self.is_decoder = config.is_decoder
|
||||
self.device = None
|
||||
self.next_device = None
|
||||
self.layer = nn.ModuleList()
|
||||
self.layer.append(T5LayerSelfAttention(config, has_relative_attention_bias=has_relative_attention_bias))
|
||||
if self.is_decoder:
|
||||
@@ -422,6 +425,21 @@ class T5Block(nn.Module):
|
||||
encoder_decoder_position_bias=None,
|
||||
head_mask=None,
|
||||
):
|
||||
if self.device is not None:
|
||||
(hidden_states,
|
||||
attention_mask,
|
||||
position_bias,
|
||||
encoder_hidden_states,
|
||||
encoder_attention_mask,
|
||||
encoder_decoder_position_bias,
|
||||
head_mask) = tuple(t.to(self.device) for t in (hidden_states,
|
||||
attention_mask,
|
||||
position_bias,
|
||||
encoder_hidden_states,
|
||||
encoder_attention_mask,
|
||||
encoder_decoder_position_bias,
|
||||
head_mask)) # Model parallelism
|
||||
|
||||
self_attention_outputs = self.layer[0](
|
||||
hidden_states, attention_mask=attention_mask, position_bias=position_bias, head_mask=head_mask
|
||||
)
|
||||
@@ -445,6 +463,10 @@ class T5Block(nn.Module):
|
||||
hidden_states = self.layer[2](hidden_states)
|
||||
|
||||
outputs = (hidden_states,) + outputs # add attentions if we output them
|
||||
|
||||
if self.next_device is not None:
|
||||
outputs = tuple(t.to(self.device) for t in outputs) # Model parallelism
|
||||
|
||||
return outputs # hidden-states, (self-attention weights), (self-attention position bias), (cross-attention weights), (cross-attention position bias)
|
||||
|
||||
|
||||
@@ -502,6 +524,27 @@ class T5PreTrainedModel(PreTrainedModel):
|
||||
if module.has_relative_attention_bias:
|
||||
module.relative_attention_bias.weight.data.normal_(mean=0.0, std=factor * ((d_model) ** -0.5))
|
||||
|
||||
def _shift_right(self, input_ids):
|
||||
decoder_start_token_id = self.config.decoder_start_token_id
|
||||
pad_token_id = self.config.pad_token_id
|
||||
|
||||
assert (
|
||||
decoder_start_token_id is not None
|
||||
), "self.model.config.decoder_start_token_id has to be defined. In T5 it is usually set to the pad_token_id. See T5 docs for more information"
|
||||
|
||||
# shift inputs to the right
|
||||
shifted_input_ids = input_ids.new_zeros(input_ids.shape)
|
||||
shifted_input_ids[..., 1:] = input_ids[..., :-1].clone()
|
||||
shifted_input_ids[..., 0] = decoder_start_token_id
|
||||
|
||||
assert pad_token_id is not None, "self.model.config.pad_token_id has to be defined."
|
||||
# replace possible -100 values in lm_labels by `pad_token_id`
|
||||
shifted_input_ids.masked_fill_(shifted_input_ids == -100, pad_token_id)
|
||||
|
||||
assert torch.all(shifted_input_ids >= 0).item(), "Verify that `lm_labels` has only positive values and -100"
|
||||
|
||||
return shifted_input_ids
|
||||
|
||||
|
||||
class T5Stack(T5PreTrainedModel):
|
||||
def __init__(self, config, embed_tokens=None):
|
||||
@@ -520,6 +563,9 @@ class T5Stack(T5PreTrainedModel):
|
||||
|
||||
self.init_weights()
|
||||
|
||||
def get_block_list(self):
|
||||
return list(self.block)
|
||||
|
||||
def get_input_embeddings(self):
|
||||
return self.embed_tokens
|
||||
|
||||
@@ -699,32 +745,24 @@ T5_INPUTS_DOCSTRING = r"""
|
||||
Args:
|
||||
input_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`):
|
||||
Indices of input sequence tokens in the vocabulary.
|
||||
To match pre-training, T5 input sequence should be formatted with [CLS] and [SEP] tokens as follows:
|
||||
|
||||
(a) For sequence pairs:
|
||||
|
||||
``tokens: [CLS] is this jack ##son ##ville ? [SEP] no it is not . [SEP]``
|
||||
|
||||
(b) For single sequences:
|
||||
|
||||
``tokens: [CLS] the dog is hairy . [SEP]``
|
||||
|
||||
T5 is a model with relative position embeddings so you should be able to pad the inputs on
|
||||
the right or the left.
|
||||
|
||||
Indices can be obtained using :class:`transformers.T5Tokenizer`.
|
||||
See :func:`transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`transformers.PreTrainedTokenizer.convert_tokens_to_ids` for details.
|
||||
To know more on how to prepare :obj:`input_ids` for pre-training take a look at
|
||||
`T5 Training <./t5.html#training>`_ .
|
||||
attention_mask (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to avoid performing attention on padding token indices.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
encoder_outputs (tuple(:obj:`tuple(torch.FloatTensor)`, `optional`, defaults to :obj:`None`):
|
||||
encoder_outputs (:obj:`tuple(tuple(torch.FloatTensor)`, `optional`, defaults to :obj:`None`):
|
||||
Tuple consists of (`last_hidden_state`, `optional`: `hidden_states`, `optional`: `attentions`)
|
||||
`last_hidden_state` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`) is a sequence of hidden-states at the output of the last layer of the encoder.
|
||||
Used in the cross-attention of the decoder.
|
||||
decoder_input_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, target_sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Provide for sequence to sequence training. T5 uses the pad_token_id as the starting token for decoder_input_ids generation
|
||||
Provide for sequence to sequence training. T5 uses the pad_token_id as the starting token for decoder_input_ids generation.
|
||||
To know more on how to prepare :obj:`decoder_input_ids` for pre-training take a look at
|
||||
`T5 Training <./t5.html#training>`_ .
|
||||
decoder_attention_mask (:obj:`torch.BoolTensor` of shape :obj:`(batch_size, tgt_seq_len)`, `optional`, defaults to :obj:`None`):
|
||||
Default behavior: generate a tensor that ignores pad tokens in decoder_input_ids. Causal mask will also be used by default.
|
||||
inputs_embeds (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`):
|
||||
@@ -760,6 +798,48 @@ class T5Model(T5PreTrainedModel):
|
||||
|
||||
self.init_weights()
|
||||
|
||||
def spread_on_devices(self, devices: Optional[List] = None):
|
||||
""" Spread a transformers model on several devices by moving block on several devices (simple model parallelism)
|
||||
|
||||
The blocks of the transformers are spread among the given device list
|
||||
or on all visible CUDA devices if no device list is given.
|
||||
|
||||
The first device will host in addition the embeddings and the input/output tensors.
|
||||
|
||||
"""
|
||||
if devices is None and torch.cuda.is_available():
|
||||
devices = list(range(torch.cuda.device_count()))
|
||||
if len(devices) < 2:
|
||||
self.to(devices[0] if devices else None)
|
||||
return
|
||||
|
||||
modules_to_move = set(self.modules)
|
||||
|
||||
# Evenly spread the blocks on devices
|
||||
block_list = self.get_block_list()
|
||||
group_size = len(block_list) // len(devices)
|
||||
for i, block in enumerate(block_list):
|
||||
device = devices[i // group_size]
|
||||
# Note that we cannot easily use `forward_pre_hook` to move tensors around since this type of hooks currently
|
||||
# only act on the positional arguments send to the forward pass (PyTorch 1.4.0).
|
||||
# So you should call your model's forward pass with tensors as positional arguments
|
||||
# see: https://github.com/pytorch/pytorch/blob/master/torch/nn/modules/module.py#L548-L554
|
||||
# block.register_forward_pre_hook(lambda module, input: tuple(t.to(device) for t in input))
|
||||
block.to(device)
|
||||
block.device = device
|
||||
modules_to_move.remove(block)
|
||||
|
||||
# Take care of brining back the tensors to the first device at the end of the last block's forward
|
||||
block.next_device = device[0]
|
||||
# block.register_forward_hook(lambda module, input, output: tuple(t.to(device[0]) for t in output))
|
||||
|
||||
# Move the remaining modules (embeddings) on the first device
|
||||
for module in list(modules_to_move):
|
||||
module.to(devices[0])
|
||||
|
||||
def get_block_list(self):
|
||||
return list(self.encoder.get_block_list()) + list(self.decoder.get_block_list())
|
||||
|
||||
def get_input_embeddings(self):
|
||||
return self.shared
|
||||
|
||||
@@ -789,28 +869,30 @@ class T5Model(T5PreTrainedModel):
|
||||
head_mask=None,
|
||||
):
|
||||
r"""
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.T5`) and inputs:
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs.
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
|
||||
Examples::
|
||||
Examples::
|
||||
|
||||
from transformers import T5Tokenizer, T5Model
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = T5Model.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensor="pt") # Batch size 1
|
||||
outputs = model(input_ids=input_ids)
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensors="pt") # Batch size 1
|
||||
outputs = model(input_ids=input_ids, decoder_input_ids=input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
|
||||
"""
|
||||
@@ -884,34 +966,41 @@ class T5ForConditionalGeneration(T5PreTrainedModel):
|
||||
):
|
||||
r"""
|
||||
lm_labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size,)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for computing the sequence classification/regression loss.
|
||||
Indices should be in :obj:`[0, ..., config.vocab_size - 1]`.
|
||||
If :obj:`config.num_labels > 1` a classification loss is computed (Cross-Entropy).
|
||||
Labels for computing the sequence classification/regression loss.
|
||||
Indices should be in :obj:`[-100, 0, ..., config.vocab_size - 1]`.
|
||||
All labels set to ``-100`` are ignored (masked), the loss is only
|
||||
computed for labels in ``[0, ..., config.vocab_size]``
|
||||
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`lm_label` is provided):
|
||||
Classification loss (cross entropy)
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`)
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
Returns:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs.
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`lm_label` is provided):
|
||||
Classification loss (cross entropy).
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`)
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention.
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
Examples::
|
||||
|
||||
Examples::
|
||||
from transformers import T5Tokenizer, T5ForConditionalGeneration
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = T5ForConditionalGeneration.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensor="pt") # Batch size 1
|
||||
outputs = model(input_ids=input_ids, lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = T5ForConditionalGeneration.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensors="pt") # Batch size 1
|
||||
outputs = model(input_ids=input_ids, decoder_input_ids=input_ids, lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = T5ForConditionalGeneration.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("summarize: Hello, my dog is cute", return_tensors="pt") # Batch size 1
|
||||
outputs = model.generate(input_ids)
|
||||
"""
|
||||
|
||||
# Encode if needed (training, first prediction pass)
|
||||
@@ -923,6 +1012,10 @@ class T5ForConditionalGeneration(T5PreTrainedModel):
|
||||
|
||||
hidden_states = encoder_outputs[0]
|
||||
|
||||
if lm_labels is not None and decoder_input_ids is None and decoder_inputs_embeds is None:
|
||||
# get decoder inputs from shifting lm labels to the right
|
||||
decoder_input_ids = self._shift_right(lm_labels)
|
||||
|
||||
# Decode
|
||||
decoder_outputs = self.decoder(
|
||||
input_ids=decoder_input_ids,
|
||||
@@ -941,10 +1034,8 @@ class T5ForConditionalGeneration(T5PreTrainedModel):
|
||||
|
||||
decoder_outputs = (lm_logits,) + decoder_outputs[1:] # Add hidden states and attention if they are here
|
||||
if lm_labels is not None:
|
||||
shift_logits = lm_logits[..., :-1, :].contiguous()
|
||||
shift_labels = lm_labels[..., 1:].contiguous()
|
||||
loss_fct = CrossEntropyLoss(ignore_index=-100)
|
||||
loss = loss_fct(shift_logits.view(-1, shift_logits.size(-1)), shift_labels.view(-1))
|
||||
loss = loss_fct(lm_logits.view(-1, lm_logits.size(-1)), lm_labels.view(-1))
|
||||
decoder_outputs = (
|
||||
loss,
|
||||
) + decoder_outputs # TODO(thom): Add z_loss https://github.com/tensorflow/mesh/blob/fa19d69eafc9a482aff0b59ddd96b025c0cb207d/mesh_tensorflow/layers.py#L666
|
||||
|
||||
+117
-114
@@ -119,7 +119,7 @@ class TFT5Attention(tf.keras.layers.Layer):
|
||||
|
||||
if self.has_relative_attention_bias:
|
||||
self.relative_attention_bias = tf.keras.layers.Embedding(
|
||||
self.relative_attention_num_buckets, self.n_heads, name="relative_attention_bias"
|
||||
self.relative_attention_num_buckets, self.n_heads, name="relative_attention_bias",
|
||||
)
|
||||
self.pruned_heads = set()
|
||||
|
||||
@@ -178,13 +178,15 @@ class TFT5Attention(tf.keras.layers.Layer):
|
||||
memory_position = tf.range(klen)[None, :]
|
||||
relative_position = memory_position - context_position # shape (qlen, klen)
|
||||
rp_bucket = self._relative_position_bucket(
|
||||
relative_position, bidirectional=not self.is_decoder, num_buckets=self.relative_attention_num_buckets
|
||||
relative_position, bidirectional=not self.is_decoder, num_buckets=self.relative_attention_num_buckets,
|
||||
)
|
||||
values = self.relative_attention_bias(rp_bucket) # shape (qlen, klen, num_heads)
|
||||
values = tf.expand_dims(tf.transpose(values, [2, 0, 1]), axis=0) # shape (1, num_heads, qlen, klen)
|
||||
return values
|
||||
|
||||
def call(self, input, mask=None, kv=None, position_bias=None, cache=None, head_mask=None, training=False):
|
||||
def call(
|
||||
self, input, mask=None, kv=None, position_bias=None, cache=None, head_mask=None, training=False,
|
||||
):
|
||||
"""
|
||||
Self-attention (if kv is None) or attention over source sentence (provided by kv).
|
||||
"""
|
||||
@@ -261,15 +263,17 @@ class TFT5LayerSelfAttention(tf.keras.layers.Layer):
|
||||
def __init__(self, config, has_relative_attention_bias=False, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.SelfAttention = TFT5Attention(
|
||||
config, has_relative_attention_bias=has_relative_attention_bias, name="SelfAttention"
|
||||
config, has_relative_attention_bias=has_relative_attention_bias, name="SelfAttention",
|
||||
)
|
||||
self.layer_norm = TFT5LayerNorm(epsilon=config.layer_norm_epsilon, name="layer_norm")
|
||||
self.dropout = tf.keras.layers.Dropout(config.dropout_rate)
|
||||
|
||||
def call(self, hidden_states, attention_mask=None, position_bias=None, head_mask=None, training=False):
|
||||
def call(
|
||||
self, hidden_states, attention_mask=None, position_bias=None, head_mask=None, training=False,
|
||||
):
|
||||
norm_x = self.layer_norm(hidden_states)
|
||||
attention_output = self.SelfAttention(
|
||||
norm_x, mask=attention_mask, position_bias=position_bias, head_mask=head_mask, training=training
|
||||
norm_x, mask=attention_mask, position_bias=position_bias, head_mask=head_mask, training=training,
|
||||
)
|
||||
y = attention_output[0]
|
||||
layer_output = hidden_states + self.dropout(y, training=training)
|
||||
@@ -281,15 +285,17 @@ class TFT5LayerCrossAttention(tf.keras.layers.Layer):
|
||||
def __init__(self, config, has_relative_attention_bias=False, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.EncDecAttention = TFT5Attention(
|
||||
config, has_relative_attention_bias=has_relative_attention_bias, name="EncDecAttention"
|
||||
config, has_relative_attention_bias=has_relative_attention_bias, name="EncDecAttention",
|
||||
)
|
||||
self.layer_norm = TFT5LayerNorm(epsilon=config.layer_norm_epsilon, name="layer_norm")
|
||||
self.dropout = tf.keras.layers.Dropout(config.dropout_rate)
|
||||
|
||||
def call(self, hidden_states, kv, attention_mask=None, position_bias=None, head_mask=None, training=False):
|
||||
def call(
|
||||
self, hidden_states, kv, attention_mask=None, position_bias=None, head_mask=None, training=False,
|
||||
):
|
||||
norm_x = self.layer_norm(hidden_states)
|
||||
attention_output = self.EncDecAttention(
|
||||
norm_x, mask=attention_mask, kv=kv, position_bias=position_bias, head_mask=head_mask, training=training
|
||||
norm_x, mask=attention_mask, kv=kv, position_bias=position_bias, head_mask=head_mask, training=training,
|
||||
)
|
||||
y = attention_output[0]
|
||||
layer_output = hidden_states + self.dropout(y, training=training)
|
||||
@@ -303,12 +309,12 @@ class TFT5Block(tf.keras.layers.Layer):
|
||||
self.is_decoder = config.is_decoder
|
||||
self.layer = []
|
||||
self.layer.append(
|
||||
TFT5LayerSelfAttention(config, has_relative_attention_bias=has_relative_attention_bias, name="layer_._0")
|
||||
TFT5LayerSelfAttention(config, has_relative_attention_bias=has_relative_attention_bias, name="layer_._0",)
|
||||
)
|
||||
if self.is_decoder:
|
||||
self.layer.append(
|
||||
TFT5LayerCrossAttention(
|
||||
config, has_relative_attention_bias=has_relative_attention_bias, name="layer_._1"
|
||||
config, has_relative_attention_bias=has_relative_attention_bias, name="layer_._1",
|
||||
)
|
||||
)
|
||||
self.layer.append(TFT5LayerFF(config, name="layer_._2"))
|
||||
@@ -402,7 +408,7 @@ class TFT5MainLayer(tf.keras.layers.Layer):
|
||||
self.num_hidden_layers = config.num_layers
|
||||
|
||||
self.block = [
|
||||
TFT5Block(config, has_relative_attention_bias=bool(i == 0), name="block_._{}".format(i))
|
||||
TFT5Block(config, has_relative_attention_bias=bool(i == 0), name="block_._{}".format(i),)
|
||||
for i in range(config.num_layers)
|
||||
]
|
||||
self.final_layer_norm = TFT5LayerNorm(epsilon=config.layer_norm_epsilon, name="final_layer_norm")
|
||||
@@ -469,7 +475,7 @@ class TFT5MainLayer(tf.keras.layers.Layer):
|
||||
if self.config.is_decoder:
|
||||
seq_ids = tf.range(seq_length)
|
||||
causal_mask = tf.less_equal(
|
||||
tf.tile(seq_ids[None, None, :], (batch_size, seq_length, 1)), seq_ids[None, :, None]
|
||||
tf.tile(seq_ids[None, None, :], (batch_size, seq_length, 1)), seq_ids[None, :, None],
|
||||
)
|
||||
causal_mask = tf.cast(causal_mask, dtype=tf.float32)
|
||||
extended_attention_mask = causal_mask[:, None, :, :] * attention_mask[:, None, None, :]
|
||||
@@ -586,8 +592,8 @@ class TFT5PreTrainedModel(TFPreTrainedModel):
|
||||
input_ids = tf.constant(DUMMY_INPUTS)
|
||||
input_mask = tf.constant(DUMMY_MASK)
|
||||
dummy_inputs = {
|
||||
"inputs": input_ids,
|
||||
"decoder_input_ids": input_ids,
|
||||
"input_ids": input_ids,
|
||||
"decoder_attention_mask": input_mask,
|
||||
}
|
||||
return dummy_inputs
|
||||
@@ -631,51 +637,43 @@ T5_START_DOCSTRING = r""" The T5 model was proposed in
|
||||
|
||||
T5_INPUTS_DOCSTRING = r"""
|
||||
Args:
|
||||
decoder_input_ids (:obj: `list`,`tuple`, or `dict`):
|
||||
decoder_input_ids are usually used as a `dict` (see T5 description above for more information) containing all the following:
|
||||
decoder_input_ids (:obj:`tf.Tensor` of shape :obj:`(batch_size, target_sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Provide for sequence to sequence training. T5 uses the pad_token_id as the starting token for decoder_input_ids generation
|
||||
inputs are usually used as a `dict` (see T5 description above for more information) containing all the following.
|
||||
|
||||
input_ids (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length)`):
|
||||
Indices of input sequence tokens in the vocabulary.
|
||||
To match pre-training, T5 input sequence should be formatted with [CLS] and [SEP] tokens as follows:
|
||||
|
||||
(a) For sequence pairs:
|
||||
|
||||
``tokens: [CLS] is this jack ##son ##ville ? [SEP] no it is not . [SEP]``
|
||||
|
||||
(b) For single sequences:
|
||||
|
||||
``tokens: [CLS] the dog is hairy . [SEP]``
|
||||
|
||||
T5 is a model with relative position embeddings so you should be able to pad the inputs on
|
||||
the right or the left.
|
||||
|
||||
Indices can be obtained using :class:`transformers.T5Tokenizer`.
|
||||
See :func:`transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`transformers.PreTrainedTokenizer.convert_tokens_to_ids` for details.
|
||||
attention_mask (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to avoid performing attention on padding token indices.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
encoder_outputs (tuple(:obj:`tuple(tf.FloatTensor)`, `optional`, defaults to :obj:`None`):
|
||||
Tuple consists of (`last_hidden_state`, `optional`: `hidden_states`, `optional`: `attentions`)
|
||||
`last_hidden_state` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`) is a sequence of hidden-states at the output of the last layer of the encoder.
|
||||
Used in the cross-attention of the decoder.
|
||||
decoder_attention_mask (:obj:`tf.Tensor` of shape :obj:`(batch_size, tgt_seq_len)`, `optional`, defaults to :obj:`None`):
|
||||
Default behavior: generate a tensor that ignores pad tokens in decoder_input_ids. Causal mask will also be used by default.
|
||||
inputs_embeds (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`):
|
||||
Optionally, instead of passing :obj:`input_ids` you can choose to directly pass an embedded representation.
|
||||
This is useful if you want more control over how to convert `input_ids` indices into associated vectors
|
||||
than the model's internal embedding lookup matrix.
|
||||
decoder_inputs_embeds (:obj:`tf.Tensor` of shape :obj:`(batch_size, target_sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`):
|
||||
Optionally, instead of passing :obj:`decoder_input_ids` you can choose to directly pass an embedded representation.
|
||||
This is useful if you want more control over how to convert `decoder_input_ids` indices into associated vectors
|
||||
than the model's internal embedding lookup matrix.
|
||||
head_mask: (:obj:`tf.Tensor` of shape :obj:`(num_heads,)` or :obj:`(num_layers, num_heads)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to nullify selected heads of the self-attention modules.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` indicates the head is **not masked**, ``0`` indicates the head is **masked**.
|
||||
inputs (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length)`):
|
||||
Indices of input sequence tokens in the vocabulary.
|
||||
T5 is a model with relative position embeddings so you should be able to pad the inputs on
|
||||
the right or the left.
|
||||
Indices can be obtained using :class:`transformers.T5Tokenizer`.
|
||||
To know more on how to prepare :obj:`input_ids` for pre-training take a look at
|
||||
`T5 Training <./t5.html#training>`_ .
|
||||
See :func:`transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`transformers.PreTrainedTokenizer.convert_tokens_to_ids` for details.
|
||||
decoder_input_ids (:obj:`tf.Tensor` of shape :obj:`(batch_size, target_sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Provide for sequence to sequence training. T5 uses the pad_token_id as the starting token for decoder_input_ids generation.
|
||||
attention_mask (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to avoid performing attention on padding token indices.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
encoder_outputs (:obj:`tuple(tuple(tf.FloatTensor)`, `optional`, defaults to :obj:`None`):
|
||||
Tuple consists of (`last_hidden_state`, `optional`: `hidden_states`, `optional`: `attentions`)
|
||||
`last_hidden_state` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`) is a sequence of hidden-states at the output of the last layer of the encoder.
|
||||
Used in the cross-attention of the decoder.
|
||||
decoder_attention_mask (:obj:`tf.Tensor` of shape :obj:`(batch_size, tgt_seq_len)`, `optional`, defaults to :obj:`None`):
|
||||
Default behavior: generate a tensor that ignores pad tokens in decoder_input_ids. Causal mask will also be used by default.
|
||||
inputs_embeds (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`):
|
||||
Optionally, instead of passing :obj:`input_ids` you can choose to directly pass an embedded representation.
|
||||
This is useful if you want more control over how to convert `input_ids` indices into associated vectors
|
||||
than the model's internal embedding lookup matrix.
|
||||
decoder_inputs_embeds (:obj:`tf.Tensor` of shape :obj:`(batch_size, target_sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`):
|
||||
Optionally, instead of passing :obj:`decoder_input_ids` you can choose to directly pass an embedded representation.
|
||||
This is useful if you want more control over how to convert `decoder_input_ids` indices into associated vectors
|
||||
than the model's internal embedding lookup matrix.
|
||||
To know more on how to prepare :obj:`decoder_input_ids` for pre-training take a look at
|
||||
`T5 Training <./t5.html#training>`_ .
|
||||
head_mask: (:obj:`tf.Tensor` of shape :obj:`(num_heads,)` or :obj:`(num_layers, num_heads)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to nullify selected heads of the self-attention modules.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` indicates the head is **not masked**, ``0`` indicates the head is **masked**.
|
||||
"""
|
||||
|
||||
|
||||
@@ -708,41 +706,43 @@ class TFT5Model(TFT5PreTrainedModel):
|
||||
return self.shared
|
||||
|
||||
@add_start_docstrings_to_callable(T5_INPUTS_DOCSTRING)
|
||||
def call(self, decoder_input_ids, **kwargs):
|
||||
def call(self, inputs, **kwargs):
|
||||
r"""
|
||||
Return:
|
||||
:obj:`tuple(tf.Tensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs:
|
||||
last_hidden_state (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
Return:
|
||||
:obj:`tuple(tf.Tensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs.
|
||||
last_hidden_state (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
|
||||
Examples::
|
||||
Examples::
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = TFT5Model.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensor="tf") # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
from transformers import T5Tokenizer, TFT5Model
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = TFT5Model.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensors="tf") # Batch size 1
|
||||
outputs = model(input_ids, input_ids=input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
|
||||
"""
|
||||
|
||||
if isinstance(decoder_input_ids, dict):
|
||||
kwargs.update(decoder_input_ids)
|
||||
if isinstance(inputs, dict):
|
||||
kwargs.update(inputs)
|
||||
else:
|
||||
kwargs["decoder_input_ids"] = decoder_input_ids
|
||||
kwargs["inputs"] = inputs
|
||||
|
||||
# retrieve arguments
|
||||
input_ids = kwargs.get("input_ids", None)
|
||||
input_ids = kwargs.get("inputs", None)
|
||||
decoder_input_ids = kwargs.get("decoder_input_ids", None)
|
||||
attention_mask = kwargs.get("attention_mask", None)
|
||||
encoder_outputs = kwargs.get("encoder_outputs", None)
|
||||
@@ -754,7 +754,7 @@ class TFT5Model(TFT5PreTrainedModel):
|
||||
# Encode if needed (training, first prediction pass)
|
||||
if encoder_outputs is None:
|
||||
encoder_outputs = self.encoder(
|
||||
input_ids, attention_mask=attention_mask, inputs_embeds=inputs_embeds, head_mask=head_mask
|
||||
input_ids, attention_mask=attention_mask, inputs_embeds=inputs_embeds, head_mask=head_mask,
|
||||
)
|
||||
|
||||
hidden_states = encoder_outputs[0]
|
||||
@@ -803,46 +803,49 @@ class TFT5ForConditionalGeneration(TFT5PreTrainedModel):
|
||||
return self.encoder
|
||||
|
||||
@add_start_docstrings_to_callable(T5_INPUTS_DOCSTRING)
|
||||
def call(self, decoder_input_ids, **kwargs):
|
||||
def call(self, inputs, **kwargs):
|
||||
r"""
|
||||
lm_labels (:obj:`tf.Tensor` of shape :obj:`(batch_size,)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for computing the sequence classification/regression loss.
|
||||
Indices should be in :obj:`[0, ..., config.vocab_size - 1]`.
|
||||
If :obj:`config.num_labels > 1` a classification loss is computed (Cross-Entropy).
|
||||
Return:
|
||||
:obj:`tuple(tf.Tensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs.
|
||||
loss (:obj:`tf.Tensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`lm_label` is provided):
|
||||
Classification loss (cross entropy).
|
||||
prediction_scores (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`)
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Returns:
|
||||
:obj:`tuple(tf.Tensor)` comprising various elements depending on the configuration (:class:`~transformers.T5Config`) and inputs:
|
||||
loss (:obj:`tf.Tensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`lm_label` is provided):
|
||||
Classification loss (cross entropy)
|
||||
prediction_scores (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`)
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention.
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
Examples::
|
||||
|
||||
Examples::
|
||||
from transformers import T5Tokenizer, TFT5ForConditionalGeneration
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = TFT5ForConditionalGeneration.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensors="tf") # Batch size 1
|
||||
outputs = model(input_ids, input_ids=input_ids)
|
||||
prediction_scores = outputs[0]
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = TFT5ForConditionalGeneration.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("summarize: Hello, my dog is cute", return_tensors="tf") # Batch size 1
|
||||
model.generate(input_ids)
|
||||
|
||||
tokenizer = T5Tokenizer.from_pretrained('t5-small')
|
||||
model = T5ForConditionalGeneration.from_pretrained('t5-small')
|
||||
input_ids = tokenizer.encode("Hello, my dog is cute", return_tensor="pt") # Batch size 1
|
||||
outputs = model(input_ids, lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
"""
|
||||
|
||||
if isinstance(decoder_input_ids, dict):
|
||||
kwargs.update(decoder_input_ids)
|
||||
if isinstance(inputs, dict):
|
||||
kwargs.update(inputs)
|
||||
else:
|
||||
kwargs["decoder_input_ids"] = decoder_input_ids
|
||||
kwargs["inputs"] = inputs
|
||||
|
||||
# retrieve arguments
|
||||
input_ids = kwargs.get("input_ids", None)
|
||||
input_ids = kwargs.get("inputs", None)
|
||||
decoder_input_ids = kwargs.get("decoder_input_ids", None)
|
||||
attention_mask = kwargs.get("attention_mask", None)
|
||||
encoder_outputs = kwargs.get("encoder_outputs", None)
|
||||
@@ -855,7 +858,7 @@ class TFT5ForConditionalGeneration(TFT5PreTrainedModel):
|
||||
if encoder_outputs is None:
|
||||
# Convert encoder inputs in embeddings if needed
|
||||
encoder_outputs = self.encoder(
|
||||
input_ids, attention_mask=attention_mask, inputs_embeds=inputs_embeds, head_mask=head_mask
|
||||
input_ids, attention_mask=attention_mask, inputs_embeds=inputs_embeds, head_mask=head_mask,
|
||||
)
|
||||
|
||||
hidden_states = encoder_outputs[0]
|
||||
@@ -870,7 +873,6 @@ class TFT5ForConditionalGeneration(TFT5PreTrainedModel):
|
||||
head_mask=head_mask,
|
||||
)
|
||||
|
||||
# TODO (thom / patrick): add lm_labels for loss function
|
||||
sequence_output = decoder_outputs[0] * (self.model_dim ** -0.5)
|
||||
embed_tokens = self.get_output_embeddings()
|
||||
lm_logits = embed_tokens(sequence_output, mode="linear")
|
||||
@@ -888,7 +890,8 @@ class TFT5ForConditionalGeneration(TFT5PreTrainedModel):
|
||||
encoder_outputs = (past,)
|
||||
|
||||
return {
|
||||
"inputs": input_ids,
|
||||
"inputs": None, # inputs don't have to be defined, but still need to be passed to make Keras.layer.__call__ happy
|
||||
"decoder_input_ids": input_ids, # input_ids are the decoder_input_ids
|
||||
"encoder_outputs": encoder_outputs,
|
||||
"attention_mask": attention_mask,
|
||||
}
|
||||
|
||||
@@ -231,7 +231,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
|
||||
def save_pretrained(self, save_directory):
|
||||
""" Save a model and its configuration file to a directory, so that it
|
||||
can be re-loaded using the `:func:`~transformers.PreTrainedModel.from_pretrained`` class method.
|
||||
can be re-loaded using the :func:`~transformers.PreTrainedModel.from_pretrained` class method.
|
||||
"""
|
||||
assert os.path.isdir(
|
||||
save_directory
|
||||
@@ -467,6 +467,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
top_k=None,
|
||||
top_p=None,
|
||||
repetition_penalty=None,
|
||||
bad_words_ids=None,
|
||||
bos_token_id=None,
|
||||
pad_token_id=None,
|
||||
eos_token_id=None,
|
||||
@@ -523,8 +524,8 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
pad_token_id: (`optional`) int
|
||||
Pad token. Defaults to pad_token_id as defined in the models config.
|
||||
|
||||
eos_token_ids: (`optional`) int or list of int
|
||||
End of sequence token or list of tokens to stop the generation. Default to 0.
|
||||
eos_token_id: (`optional`) int
|
||||
EOS token. Defaults to eos_token_id as defined in the models config.
|
||||
|
||||
length_penalty: (`optional`) float
|
||||
Exponential penalty to the length. Default to 1.
|
||||
@@ -532,6 +533,9 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
no_repeat_ngram_size: (`optional`) int
|
||||
If set to int > 0, all ngrams of size `no_repeat_ngram_size` can only occur once.
|
||||
|
||||
bad_words_ids: (`optional`) list of lists of int
|
||||
`bad_words_ids` contains tokens that are not allowed to be generated. In order to get the tokens of the words that should not appear in the generated text, use `tokenizer.encode(bad_word, add_prefix_space=True)`.
|
||||
|
||||
num_return_sequences: (`optional`) int
|
||||
The number of independently computed returned sequences for each element in the batch. Default to 1.
|
||||
|
||||
@@ -541,7 +545,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
Defaults to `None`.
|
||||
|
||||
`What are attention masks? <../glossary.html#attention-mask>`__
|
||||
`What are attention masks? <../glossary.html#attention-mask>`__
|
||||
|
||||
decoder_start_token_id=None: (`optional`) int
|
||||
If an encoder-decoder model starts decoding with a different token than BOS.
|
||||
@@ -582,6 +586,12 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
outputs = model.generate(input_ids=input_ids, max_length=50, temperature=0.7, repetition_penalty=1.2) # generate sequences
|
||||
print('Generated: {}'.format(tokenizer.decode(outputs[0], skip_special_tokens=True)))
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('gpt2') # Initialize tokenizer
|
||||
model = TFAutoModelWithLMHead.from_pretrained('gpt2') # Download model and configuration from S3 and cache.
|
||||
input_context = 'My cute dog' # "Legal" is one of the control codes for ctrl
|
||||
bad_words_ids = [tokenizer.encode(bad_word, add_prefix_space=True) for bad_word in ['idiot', 'stupid', 'shut up']]
|
||||
input_ids = tokenizer.encode(input_context, return_tensors='tf') # encode input context
|
||||
outputs = model.generate(input_ids=input_ids, max_length=100, do_sample=True, bad_words_ids=bad_words_ids) # generate sequences without allowing bad_words to be generated
|
||||
"""
|
||||
|
||||
# We cannot generate if the model does not have a LM head
|
||||
@@ -607,6 +617,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
no_repeat_ngram_size = (
|
||||
no_repeat_ngram_size if no_repeat_ngram_size is not None else self.config.no_repeat_ngram_size
|
||||
)
|
||||
bad_words_ids = bad_words_ids if bad_words_ids is not None else self.config.bad_words_ids
|
||||
num_return_sequences = (
|
||||
num_return_sequences if num_return_sequences is not None else self.config.num_return_sequences
|
||||
)
|
||||
@@ -641,6 +652,9 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
assert (
|
||||
isinstance(num_return_sequences, int) and num_return_sequences > 0
|
||||
), "`num_return_sequences` should be a strictely positive integer."
|
||||
assert (
|
||||
bad_words_ids is None or isinstance(bad_words_ids, list) and isinstance(bad_words_ids[0], list)
|
||||
), "`bad_words_ids` is either `None` or a list of lists of tokens that should not be generated"
|
||||
|
||||
if input_ids is None:
|
||||
assert isinstance(bos_token_id, int) and bos_token_id >= 0, (
|
||||
@@ -742,6 +756,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
top_p=top_p,
|
||||
repetition_penalty=repetition_penalty,
|
||||
no_repeat_ngram_size=no_repeat_ngram_size,
|
||||
bad_words_ids=bad_words_ids,
|
||||
bos_token_id=bos_token_id,
|
||||
pad_token_id=pad_token_id,
|
||||
eos_token_id=eos_token_id,
|
||||
@@ -766,6 +781,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
top_p=top_p,
|
||||
repetition_penalty=repetition_penalty,
|
||||
no_repeat_ngram_size=no_repeat_ngram_size,
|
||||
bad_words_ids=bad_words_ids,
|
||||
bos_token_id=bos_token_id,
|
||||
pad_token_id=pad_token_id,
|
||||
eos_token_id=eos_token_id,
|
||||
@@ -790,6 +806,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
top_p,
|
||||
repetition_penalty,
|
||||
no_repeat_ngram_size,
|
||||
bad_words_ids,
|
||||
bos_token_id,
|
||||
pad_token_id,
|
||||
eos_token_id,
|
||||
@@ -828,7 +845,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
if no_repeat_ngram_size > 0:
|
||||
# calculate a list of banned tokens to prevent repetitively generating the same ngrams
|
||||
# from fairseq: https://github.com/pytorch/fairseq/blob/a07cb6f40480928c9e0548b737aadd36ee66ac76/fairseq/sequence_generator.py#L345
|
||||
banned_tokens = calc_banned_tokens(input_ids, batch_size, no_repeat_ngram_size, cur_len)
|
||||
banned_tokens = calc_banned_ngram_tokens(input_ids, batch_size, no_repeat_ngram_size, cur_len)
|
||||
# create banned_tokens boolean mask
|
||||
banned_tokens_indices_mask = []
|
||||
for banned_tokens_slice in banned_tokens:
|
||||
@@ -840,6 +857,20 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
next_token_logits, tf.convert_to_tensor(banned_tokens_indices_mask, dtype=tf.bool), -float("inf")
|
||||
)
|
||||
|
||||
if bad_words_ids is not None:
|
||||
# calculate a list of banned tokens according to bad words
|
||||
banned_tokens = calc_banned_bad_words_ids(input_ids, bad_words_ids)
|
||||
|
||||
banned_tokens_indices_mask = []
|
||||
for banned_tokens_slice in banned_tokens:
|
||||
banned_tokens_indices_mask.append(
|
||||
[True if token in banned_tokens_slice else False for token in range(vocab_size)]
|
||||
)
|
||||
|
||||
next_token_logits = set_tensor_by_indices_to_value(
|
||||
next_token_logits, tf.convert_to_tensor(banned_tokens_indices_mask, dtype=tf.bool), -float("inf")
|
||||
)
|
||||
|
||||
# set eos token prob to zero if min_length is not reached
|
||||
if eos_token_id is not None and cur_len < min_length:
|
||||
# create eos_token_id boolean mask
|
||||
@@ -936,6 +967,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
top_p,
|
||||
repetition_penalty,
|
||||
no_repeat_ngram_size,
|
||||
bad_words_ids,
|
||||
bos_token_id,
|
||||
pad_token_id,
|
||||
decoder_start_token_id,
|
||||
@@ -1012,7 +1044,9 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
# calculate a list of banned tokens to prevent repetitively generating the same ngrams
|
||||
# from fairseq: https://github.com/pytorch/fairseq/blob/a07cb6f40480928c9e0548b737aadd36ee66ac76/fairseq/sequence_generator.py#L345
|
||||
num_batch_hypotheses = batch_size * num_beams
|
||||
banned_tokens = calc_banned_tokens(input_ids, num_batch_hypotheses, no_repeat_ngram_size, cur_len)
|
||||
banned_tokens = calc_banned_ngram_tokens(
|
||||
input_ids, num_batch_hypotheses, no_repeat_ngram_size, cur_len
|
||||
)
|
||||
# create banned_tokens boolean mask
|
||||
banned_tokens_indices_mask = []
|
||||
for banned_tokens_slice in banned_tokens:
|
||||
@@ -1024,6 +1058,20 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
scores, tf.convert_to_tensor(banned_tokens_indices_mask, dtype=tf.bool), -float("inf")
|
||||
)
|
||||
|
||||
if bad_words_ids is not None:
|
||||
# calculate a list of banned tokens according to bad words
|
||||
banned_tokens = calc_banned_bad_words_ids(input_ids, bad_words_ids)
|
||||
|
||||
banned_tokens_indices_mask = []
|
||||
for banned_tokens_slice in banned_tokens:
|
||||
banned_tokens_indices_mask.append(
|
||||
[True if token in banned_tokens_slice else False for token in range(vocab_size)]
|
||||
)
|
||||
|
||||
scores = set_tensor_by_indices_to_value(
|
||||
scores, tf.convert_to_tensor(banned_tokens_indices_mask, dtype=tf.bool), -float("inf")
|
||||
)
|
||||
|
||||
assert shape_list(scores) == [batch_size * num_beams, vocab_size]
|
||||
|
||||
if do_sample:
|
||||
@@ -1064,12 +1112,12 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
assert shape_list(next_scores) == shape_list(next_tokens) == [batch_size, 2 * num_beams]
|
||||
|
||||
# next batch beam content
|
||||
# list of (batch_size * num_beams) tuple(next hypothesis score, next token, current position in the batch)
|
||||
next_batch_beam = []
|
||||
|
||||
# for each sentence
|
||||
for batch_idx in range(batch_size):
|
||||
|
||||
# if we are done with this sentence
|
||||
if done[batch_idx]:
|
||||
assert (
|
||||
len(generated_hyps[batch_idx]) >= num_beams
|
||||
@@ -1087,14 +1135,13 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
for beam_token_rank, (beam_token_id, beam_token_score) in enumerate(
|
||||
zip(next_tokens[batch_idx], next_scores[batch_idx])
|
||||
):
|
||||
|
||||
# get beam and token IDs
|
||||
beam_id = beam_token_id // vocab_size
|
||||
token_id = beam_token_id % vocab_size
|
||||
|
||||
effective_beam_id = batch_idx * num_beams + beam_id
|
||||
# add to generated hypotheses if end of sentence or last iteration
|
||||
if eos_token_id is not None and token_id.numpy() is eos_token_id:
|
||||
if (eos_token_id is not None) and (token_id.numpy() == eos_token_id):
|
||||
# if beam_token does not belong to top num_beams tokens, it should not be added
|
||||
is_beam_token_worse_than_top_num_beams = beam_token_rank >= num_beams
|
||||
if is_beam_token_worse_than_top_num_beams:
|
||||
@@ -1110,9 +1157,9 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
if len(next_sent_beam) == num_beams:
|
||||
break
|
||||
|
||||
# if we are done with this sentence
|
||||
# Check if were done so that we can save a pad step if all(done)
|
||||
done[batch_idx] = done[batch_idx] or generated_hyps[batch_idx].is_done(
|
||||
tf.reduce_max(next_scores[batch_idx]).numpy()
|
||||
tf.reduce_max(next_scores[batch_idx]).numpy(), cur_len=cur_len
|
||||
)
|
||||
|
||||
# update next beam content
|
||||
@@ -1130,6 +1177,8 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
beam_tokens = tf.convert_to_tensor([x[1] for x in next_batch_beam], dtype=tf.int32)
|
||||
beam_idx = tf.convert_to_tensor([x[2] for x in next_batch_beam], dtype=tf.int32)
|
||||
|
||||
print("Scores: {}-{}".format(cur_len, beam_scores.numpy()))
|
||||
|
||||
# re-order batch
|
||||
input_ids = tf.stack([tf.identity(input_ids[x, :]) for x in beam_idx])
|
||||
input_ids = tf.concat([input_ids, tf.expand_dims(beam_tokens, 1)], axis=-1)
|
||||
@@ -1137,6 +1186,7 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
if past is not None:
|
||||
past = self._reorder_cache(past, beam_idx)
|
||||
|
||||
# extend attention_mask for new generated input if only decoder
|
||||
if self.config.is_encoder_decoder is False:
|
||||
attention_mask = tf.concat(
|
||||
[attention_mask, tf.ones((shape_list(attention_mask)[0], 1), dtype=tf.int32)], axis=-1
|
||||
@@ -1196,16 +1246,26 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
|
||||
# fill with hypothesis and eos_token_id if necessary
|
||||
for i, hypo in enumerate(best):
|
||||
padding = tf.ones((sent_max_len - shape_list(hypo)[0],), dtype=tf.int32) * pad_token_id
|
||||
decoded_hypo = tf.concat([hypo, padding], axis=0)
|
||||
assert sent_lengths[i] == shape_list(hypo)[0]
|
||||
# if sent_length is max_len do not pad
|
||||
if sent_lengths[i] == sent_max_len:
|
||||
decoded_slice = hypo
|
||||
else:
|
||||
# else pad to sent_max_len
|
||||
num_pad_tokens = sent_max_len - sent_lengths[i]
|
||||
padding = pad_token_id * tf.ones((num_pad_tokens,), dtype=tf.int32)
|
||||
decoded_slice = tf.concat([hypo, padding], axis=-1)
|
||||
|
||||
# finish sentence with EOS token
|
||||
if sent_lengths[i] < max_length:
|
||||
decoded_slice = tf.where(
|
||||
tf.range(sent_max_len, dtype=tf.int32) == sent_lengths[i],
|
||||
eos_token_id * tf.ones((sent_max_len,), dtype=tf.int32),
|
||||
decoded_slice,
|
||||
)
|
||||
# add to list
|
||||
decoded_list.append(decoded_slice)
|
||||
|
||||
if sent_lengths[i] < max_length:
|
||||
decoded_hypo = tf.where(
|
||||
tf.range(max_length) == sent_lengths[i],
|
||||
eos_token_id * tf.ones((sent_max_len,), dtype=tf.int32),
|
||||
decoded_hypo,
|
||||
)
|
||||
decoded_list.append(decoded_hypo)
|
||||
decoded = tf.stack(decoded_list)
|
||||
else:
|
||||
# none of the hypotheses have an eos_token
|
||||
@@ -1243,7 +1303,7 @@ def _create_next_token_logits_penalties(input_ids, logits, repetition_penalty):
|
||||
return tf.convert_to_tensor(token_penalties, dtype=tf.float32)
|
||||
|
||||
|
||||
def calc_banned_tokens(prev_input_ids, num_hypos, no_repeat_ngram_size, cur_len):
|
||||
def calc_banned_ngram_tokens(prev_input_ids, num_hypos, no_repeat_ngram_size, cur_len):
|
||||
# Copied from fairseq for no_repeat_ngram in beam_search"""
|
||||
if cur_len + 1 < no_repeat_ngram_size:
|
||||
# return no banned tokens if we haven't generated no_repeat_ngram_size tokens yet
|
||||
@@ -1266,6 +1326,42 @@ def calc_banned_tokens(prev_input_ids, num_hypos, no_repeat_ngram_size, cur_len)
|
||||
return banned_tokens
|
||||
|
||||
|
||||
def calc_banned_bad_words_ids(prev_input_ids, bad_words_ids):
|
||||
banned_tokens = []
|
||||
|
||||
def _tokens_match(prev_tokens, tokens):
|
||||
if len(tokens) == 0:
|
||||
# if bad word tokens is just one token always ban it
|
||||
return True
|
||||
if len(tokens) > len(prev_input_ids):
|
||||
# if bad word tokens are longer then prev input_ids they can't be equal
|
||||
return False
|
||||
|
||||
if prev_tokens[-len(tokens) :] == tokens:
|
||||
# if tokens match
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
|
||||
for prev_input_ids_slice in prev_input_ids:
|
||||
banned_tokens_slice = []
|
||||
|
||||
for banned_token_seq in bad_words_ids:
|
||||
assert len(banned_token_seq) > 0, "Banned words token sequences {} cannot have an empty list".format(
|
||||
bad_words_ids
|
||||
)
|
||||
|
||||
if _tokens_match(prev_input_ids_slice.numpy().tolist(), banned_token_seq[:-1]) is False:
|
||||
# if tokens do not match continue
|
||||
continue
|
||||
|
||||
banned_tokens_slice.append(banned_token_seq[-1])
|
||||
|
||||
banned_tokens.append(banned_tokens_slice)
|
||||
|
||||
return banned_tokens
|
||||
|
||||
|
||||
def tf_top_k_top_p_filtering(logits, top_k=0, top_p=1.0, filter_value=-float("Inf"), min_tokens_to_keep=1):
|
||||
""" Filter a distribution of logits using top-k and/or nucleus (top-p) filtering
|
||||
Args:
|
||||
|
||||
@@ -667,6 +667,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
top_k=None,
|
||||
top_p=None,
|
||||
repetition_penalty=None,
|
||||
bad_words_ids=None,
|
||||
bos_token_id=None,
|
||||
pad_token_id=None,
|
||||
eos_token_id=None,
|
||||
@@ -721,19 +722,18 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
Padding token. Default to specicic model pad_token_id or None if it does not exist.
|
||||
|
||||
bos_token_id: (`optional`) int
|
||||
BOS token. Defaults to bos_token_id as defined in the models config.
|
||||
BOS token. Defaults to `bos_token_id` as defined in the models config.
|
||||
|
||||
pad_token_id: (`optional`) int
|
||||
Pad token. Defaults to pad_token_id as defined in the models config.
|
||||
|
||||
eos_token_ids: (`optional`) int or list of int
|
||||
End of sequence token or list of tokens to stop the generation. Default to eos_token_ids as defined in the models config.
|
||||
eos_token_id: (`optional`) int
|
||||
EOS token. Defaults to `eos_token_id` as defined in the models config.
|
||||
|
||||
length_penalty: (`optional`) float
|
||||
Exponential penalty to the length. Default to 1.
|
||||
|
||||
no_repeat_ngram_size: (`optional`) int
|
||||
If set to int > 0, all ngrams of size `no_repeat_ngram_size` can only occur once.
|
||||
bad_words_ids: (`optional`) list of lists of int
|
||||
`bad_words_ids` contains tokens that are not allowed to be generated. In order to get the tokens of the words that should not appear in the generated text, use `tokenizer.encode(bad_word, add_prefix_space=True)`.
|
||||
|
||||
num_return_sequences: (`optional`) int
|
||||
The number of independently computed returned sequences for each element in the batch. Default to 1.
|
||||
@@ -785,6 +785,12 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
outputs = model.generate(input_ids=input_ids, max_length=50, temperature=0.7, repetition_penalty=1.2) # generate sequences
|
||||
print('Generated: {}'.format(tokenizer.decode(outputs[0], skip_special_tokens=True)))
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('gpt2') # Initialize tokenizer
|
||||
model = AutoModelWithLMHead.from_pretrained('gpt2') # Download model and configuration from S3 and cache.
|
||||
input_context = 'My cute dog' # "Legal" is one of the control codes for ctrl
|
||||
bad_words_ids = [tokenizer.encode(bad_word, add_prefix_space=True) for bad_word in ['idiot', 'stupid', 'shut up']]
|
||||
input_ids = tokenizer.encode(input_context, return_tensors='pt') # encode input context
|
||||
outputs = model.generate(input_ids=input_ids, max_length=100, do_sample=True, bad_words_ids=bad_words_ids) # generate sequences without allowing bad_words to be generated
|
||||
"""
|
||||
|
||||
# We cannot generate if the model does not have a LM head
|
||||
@@ -810,6 +816,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
no_repeat_ngram_size = (
|
||||
no_repeat_ngram_size if no_repeat_ngram_size is not None else self.config.no_repeat_ngram_size
|
||||
)
|
||||
bad_words_ids = bad_words_ids if bad_words_ids is not None else self.config.bad_words_ids
|
||||
num_return_sequences = (
|
||||
num_return_sequences if num_return_sequences is not None else self.config.num_return_sequences
|
||||
)
|
||||
@@ -847,6 +854,9 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
assert (
|
||||
isinstance(num_return_sequences, int) and num_return_sequences > 0
|
||||
), "`num_return_sequences` should be a strictly positive integer."
|
||||
assert (
|
||||
bad_words_ids is None or isinstance(bad_words_ids, list) and isinstance(bad_words_ids[0], list)
|
||||
), "`bad_words_ids` is either `None` or a list of lists of tokens that should not be generated"
|
||||
|
||||
if input_ids is None:
|
||||
assert isinstance(bos_token_id, int) and bos_token_id >= 0, (
|
||||
@@ -950,6 +960,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
.to(input_ids.device)
|
||||
)
|
||||
encoder_outputs = (encoder_outputs[0].index_select(batch_idx, expanded_idx), *encoder_outputs[1:])
|
||||
|
||||
else:
|
||||
encoder_outputs = None
|
||||
cur_len = input_ids.shape[-1]
|
||||
@@ -967,6 +978,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
top_p=top_p,
|
||||
repetition_penalty=repetition_penalty,
|
||||
no_repeat_ngram_size=no_repeat_ngram_size,
|
||||
bad_words_ids=bad_words_ids,
|
||||
bos_token_id=bos_token_id,
|
||||
pad_token_id=pad_token_id,
|
||||
decoder_start_token_id=decoder_start_token_id,
|
||||
@@ -991,6 +1003,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
top_p=top_p,
|
||||
repetition_penalty=repetition_penalty,
|
||||
no_repeat_ngram_size=no_repeat_ngram_size,
|
||||
bad_words_ids=bad_words_ids,
|
||||
bos_token_id=bos_token_id,
|
||||
pad_token_id=pad_token_id,
|
||||
decoder_start_token_id=decoder_start_token_id,
|
||||
@@ -1014,6 +1027,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
top_p,
|
||||
repetition_penalty,
|
||||
no_repeat_ngram_size,
|
||||
bad_words_ids,
|
||||
bos_token_id,
|
||||
pad_token_id,
|
||||
eos_token_id,
|
||||
@@ -1048,7 +1062,14 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
if no_repeat_ngram_size > 0:
|
||||
# calculate a list of banned tokens to prevent repetitively generating the same ngrams
|
||||
# from fairseq: https://github.com/pytorch/fairseq/blob/a07cb6f40480928c9e0548b737aadd36ee66ac76/fairseq/sequence_generator.py#L345
|
||||
banned_tokens = calc_banned_tokens(input_ids, batch_size, no_repeat_ngram_size, cur_len)
|
||||
banned_tokens = calc_banned_ngram_tokens(input_ids, batch_size, no_repeat_ngram_size, cur_len)
|
||||
for batch_idx in range(batch_size):
|
||||
next_token_logits[batch_idx, banned_tokens[batch_idx]] = -float("inf")
|
||||
|
||||
if bad_words_ids is not None:
|
||||
# calculate a list of banned tokens according to bad words
|
||||
banned_tokens = calc_banned_bad_words_ids(input_ids, bad_words_ids)
|
||||
|
||||
for batch_idx in range(batch_size):
|
||||
next_token_logits[batch_idx, banned_tokens[batch_idx]] = -float("inf")
|
||||
|
||||
@@ -1124,6 +1145,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
top_p,
|
||||
repetition_penalty,
|
||||
no_repeat_ngram_size,
|
||||
bad_words_ids,
|
||||
bos_token_id,
|
||||
pad_token_id,
|
||||
eos_token_id,
|
||||
@@ -1190,12 +1212,19 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
# calculate a list of banned tokens to prevent repetitively generating the same ngrams
|
||||
num_batch_hypotheses = batch_size * num_beams
|
||||
# from fairseq: https://github.com/pytorch/fairseq/blob/a07cb6f40480928c9e0548b737aadd36ee66ac76/fairseq/sequence_generator.py#L345
|
||||
banned_batch_tokens = calc_banned_tokens(
|
||||
banned_batch_tokens = calc_banned_ngram_tokens(
|
||||
input_ids, num_batch_hypotheses, no_repeat_ngram_size, cur_len
|
||||
)
|
||||
for i, banned_tokens in enumerate(banned_batch_tokens):
|
||||
scores[i, banned_tokens] = -float("inf")
|
||||
|
||||
if bad_words_ids is not None:
|
||||
# calculate a list of banned tokens according to bad words
|
||||
banned_tokens = calc_banned_bad_words_ids(input_ids, bad_words_ids)
|
||||
|
||||
for i, banned_tokens in enumerate(banned_tokens):
|
||||
scores[i, banned_tokens] = -float("inf")
|
||||
|
||||
assert scores.shape == (batch_size * num_beams, vocab_size), "Shapes of scores: {} != {}".format(
|
||||
scores.shape, (batch_size * num_beams, vocab_size)
|
||||
)
|
||||
@@ -1256,14 +1285,13 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
for beam_token_rank, (beam_token_id, beam_token_score) in enumerate(
|
||||
zip(next_tokens[batch_idx], next_scores[batch_idx])
|
||||
):
|
||||
# get beam and word IDs
|
||||
# get beam and token IDs
|
||||
beam_id = beam_token_id // vocab_size
|
||||
token_id = beam_token_id % vocab_size
|
||||
|
||||
effective_beam_id = batch_idx * num_beams + beam_id
|
||||
|
||||
# add to generated hypotheses if end of sentence
|
||||
if (eos_token_id is not None) and (token_id.item() is eos_token_id):
|
||||
# add to generated hypotheses if end of sentence or last iteration
|
||||
if (eos_token_id is not None) and (token_id.item() == eos_token_id):
|
||||
# if beam_token does not belong to top num_beams tokens, it should not be added
|
||||
is_beam_token_worse_than_top_num_beams = beam_token_rank >= num_beams
|
||||
if is_beam_token_worse_than_top_num_beams:
|
||||
@@ -1272,7 +1300,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
input_ids[effective_beam_id].clone(), beam_token_score.item(),
|
||||
)
|
||||
else:
|
||||
# add next predicted word if it is not eos_token
|
||||
# add next predicted token if it is not eos_token
|
||||
next_sent_beam.append((beam_token_score, token_id, effective_beam_id))
|
||||
|
||||
# the beam for next step is full
|
||||
@@ -1302,7 +1330,6 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
# re-order batch
|
||||
input_ids = input_ids[beam_idx, :]
|
||||
input_ids = torch.cat([input_ids, beam_tokens.unsqueeze(1)], dim=-1)
|
||||
|
||||
# re-order internal states
|
||||
if past is not None:
|
||||
past = self._reorder_cache(past, beam_idx)
|
||||
@@ -1400,7 +1427,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
return past
|
||||
|
||||
|
||||
def calc_banned_tokens(prev_input_ids, num_hypos, no_repeat_ngram_size, cur_len):
|
||||
def calc_banned_ngram_tokens(prev_input_ids, num_hypos, no_repeat_ngram_size, cur_len):
|
||||
# Copied from fairseq for no_repeat_ngram in beam_search"""
|
||||
if cur_len + 1 < no_repeat_ngram_size:
|
||||
# return no banned tokens if we haven't generated no_repeat_ngram_size tokens yet
|
||||
@@ -1423,6 +1450,42 @@ def calc_banned_tokens(prev_input_ids, num_hypos, no_repeat_ngram_size, cur_len)
|
||||
return banned_tokens
|
||||
|
||||
|
||||
def calc_banned_bad_words_ids(prev_input_ids, bad_words_ids):
|
||||
banned_tokens = []
|
||||
|
||||
def _tokens_match(prev_tokens, tokens):
|
||||
if len(tokens) == 0:
|
||||
# if bad word tokens is just one token always ban it
|
||||
return True
|
||||
if len(tokens) > len(prev_input_ids):
|
||||
# if bad word tokens are longer then prev input_ids they can't be equal
|
||||
return False
|
||||
|
||||
if prev_tokens[-len(tokens) :] == tokens:
|
||||
# if tokens match
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
|
||||
for prev_input_ids_slice in prev_input_ids:
|
||||
banned_tokens_slice = []
|
||||
|
||||
for banned_token_seq in bad_words_ids:
|
||||
assert len(banned_token_seq) > 0, "Banned words token sequences {} cannot have an empty list".format(
|
||||
bad_words_ids
|
||||
)
|
||||
|
||||
if _tokens_match(prev_input_ids_slice.tolist(), banned_token_seq[:-1]) is False:
|
||||
# if tokens do not match continue
|
||||
continue
|
||||
|
||||
banned_tokens_slice.append(banned_token_seq[-1])
|
||||
|
||||
banned_tokens.append(banned_tokens_slice)
|
||||
|
||||
return banned_tokens
|
||||
|
||||
|
||||
def top_k_top_p_filtering(logits, top_k=0, top_p=1.0, filter_value=-float("Inf"), min_tokens_to_keep=1):
|
||||
""" Filter a distribution of logits using top-k and/or nucleus (top-p) filtering
|
||||
Args:
|
||||
|
||||
@@ -214,7 +214,7 @@ class GradientAccumulator(object):
|
||||
raise ValueError("Expected %s gradients, but got %d" % (len(self._gradients), len(gradients)))
|
||||
|
||||
for accum_gradient, gradient in zip(self._get_replica_gradients(), gradients):
|
||||
if accum_gradient is not None:
|
||||
if accum_gradient is not None and gradient is not None:
|
||||
accum_gradient.assign_add(gradient)
|
||||
|
||||
self._accum_steps.assign_add(1)
|
||||
@@ -241,6 +241,7 @@ class GradientAccumulator(object):
|
||||
return (
|
||||
gradient.device_map.select_for_current_replica(gradient.values, replica_context)
|
||||
for gradient in self._gradients
|
||||
if gradient is not None
|
||||
)
|
||||
else:
|
||||
return self._gradients
|
||||
|
||||
@@ -1235,17 +1235,19 @@ class SummarizationPipeline(Pipeline):
|
||||
elif self.framework == "tf":
|
||||
input_length = tf.shape(inputs["input_ids"])[-1].numpy()
|
||||
|
||||
if input_length < self.model.config.min_length // 2:
|
||||
min_length = generate_kwargs.get("min_length", self.model.config.min_length)
|
||||
if input_length < min_length // 2:
|
||||
logger.warning(
|
||||
"Your min_length is set to {}, but you input_length is only {}. You might consider decreasing min_length manually, e.g. summarizer('...', min_length=10)".format(
|
||||
self.model.config.min_length, input_length
|
||||
min_length, input_length
|
||||
)
|
||||
)
|
||||
|
||||
if input_length < self.model.config.max_length:
|
||||
max_length = generate_kwargs.get("max_length", self.model.config.max_length)
|
||||
if input_length < max_length:
|
||||
logger.warning(
|
||||
"Your max_length is set to {}, but you input_length is only {}. You might consider decreasing max_length manually, e.g. summarizer('...', max_length=50)".format(
|
||||
self.model.config.max_length, input_length
|
||||
max_length, input_length
|
||||
)
|
||||
)
|
||||
|
||||
@@ -1349,10 +1351,11 @@ class TranslationPipeline(Pipeline):
|
||||
elif self.framework == "tf":
|
||||
input_length = tf.shape(inputs["input_ids"])[-1].numpy()
|
||||
|
||||
if input_length > 0.9 * self.model.config.max_length:
|
||||
max_length = generate_kwargs.get("max_length", self.model.config.max_length)
|
||||
if input_length > 0.9 * max_length:
|
||||
logger.warning(
|
||||
"Your input_length: {} is bigger than 0.9 * max_length: {}. You might consider increasing your max_length manually, e.g. translator('...', max_length=400)".format(
|
||||
input_length, self.model.config.max_length
|
||||
input_length, max_length
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
@@ -19,7 +19,7 @@ from .tokenization_roberta import RobertaTokenizer
|
||||
# vocab and merges same as roberta
|
||||
vocab_url = "https://s3.amazonaws.com/models.huggingface.co/bert/roberta-large-vocab.json"
|
||||
merges_url = "https://s3.amazonaws.com/models.huggingface.co/bert/roberta-large-merges.txt"
|
||||
_all_bart_models = ["bart-large", "bart-large-mnli", "bart-large-cnn"]
|
||||
_all_bart_models = ["bart-large", "bart-large-mnli", "bart-large-cnn", "bart-large-xsum"]
|
||||
|
||||
|
||||
class BartTokenizer(RobertaTokenizer):
|
||||
|
||||
@@ -61,14 +61,14 @@ PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
|
||||
class T5Tokenizer(PreTrainedTokenizer):
|
||||
"""
|
||||
Constructs an XLNet tokenizer. Based on `SentencePiece <https://github.com/google/sentencepiece>`__
|
||||
Constructs an XLNet tokenizer. Based on `SentencePiece <https://github.com/google/sentencepiece>`__ .
|
||||
|
||||
This tokenizer inherits from :class:`~transformers.PreTrainedTokenizer` which contains most of the methods. Users
|
||||
should refer to the superclass for more information regarding methods.
|
||||
|
||||
Args:
|
||||
vocab_file (:obj:`string`):
|
||||
`SentencePiece <https://github.com/google/sentencepiece>`__ file (generally has a .spm extension) that
|
||||
`SentencePiece <https://github.com/google/sentencepiece>`__ file (generally has a `.spm` extension) that
|
||||
contains the vocabulary necessary to instantiate a tokenizer.
|
||||
eos_token (:obj:`string`, `optional`, defaults to "</s>"):
|
||||
The end of sequence token.
|
||||
@@ -84,9 +84,8 @@ class T5Tokenizer(PreTrainedTokenizer):
|
||||
The token used for padding, for example when batching sequences of different lengths.
|
||||
extra_ids (:obj:`List[str]`, `optional`, defaults to :obj:`100`):
|
||||
Add a number of extra ids added to the end of the vocabulary for use as sentinels.
|
||||
These tokens are accessible as `<extra_id_{%d}>` where `{%d}` is a number between 0 and extra_ids-1.
|
||||
Extra tokens are indexed from the end of the vocabulary up to beginnning (<extra_id_0> is the last token in the vocabulary)
|
||||
(like in T5 preprocessing
|
||||
These tokens are accessible as "<extra_id_{%d}>" where "{%d}" is a number between 0 and extra_ids-1.
|
||||
Extra tokens are indexed from the end of the vocabulary up to beginnning ("<extra_id_0>" is the last token in the vocabulary like in T5 preprocessing
|
||||
see: https://github.com/google-research/text-to-text-transfer-transformer/blob/9fd7b14a769417be33bc6c850f9598764913c833/t5/data/preprocessors.py#L2117)
|
||||
additional_special_tokens (:obj:`List[str]`, `optional`, defaults to :obj:`None`):
|
||||
Additional special tokens used by the tokenizer.
|
||||
|
||||
@@ -27,7 +27,9 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
AutoModel,
|
||||
AutoModelForSequenceClassification,
|
||||
AutoTokenizer,
|
||||
BartModel,
|
||||
BartForConditionalGeneration,
|
||||
BartForSequenceClassification,
|
||||
@@ -183,6 +185,15 @@ class BARTModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
def test_inputs_embeds(self):
|
||||
pass
|
||||
|
||||
def test_tiny_model(self):
|
||||
model_name = "sshleifer/bart-tiny-random"
|
||||
tiny = AutoModel.from_pretrained(model_name) # same vocab size
|
||||
tok = AutoTokenizer.from_pretrained(model_name) # same tokenizer
|
||||
inputs_dict = tok.batch_encode_plus(["Hello my friends"], return_tensors="pt")
|
||||
|
||||
with torch.no_grad():
|
||||
tiny(**inputs_dict)
|
||||
|
||||
|
||||
@require_torch
|
||||
class BartHeadTests(unittest.TestCase):
|
||||
@@ -450,6 +461,38 @@ class BartModelIntegrationTests(unittest.TestCase):
|
||||
model = BartModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
@slow
|
||||
def test_xsum_summarization_same_as_fairseq(self):
|
||||
model = BartForConditionalGeneration.from_pretrained("bart-large-xsum").to(torch_device)
|
||||
tok = BartTokenizer.from_pretrained("bart-large")
|
||||
|
||||
PGE_ARTICLE = """ PG&E stated it scheduled the blackouts in response to forecasts for high winds amid dry conditions. The aim is to reduce the risk of wildfires. Nearly 800 thousand customers were scheduled to be affected by the shutoffs which were expected to last through at least midday tomorrow."""
|
||||
EXPECTED_SUMMARY = "California's largest power company has begun shutting off power to tens of thousands of homes and businesses in the state."
|
||||
dct = tok.batch_encode_plus([PGE_ARTICLE], max_length=1024, pad_to_max_length=True, return_tensors="pt",)
|
||||
|
||||
hypotheses_batch = model.generate(
|
||||
input_ids=dct["input_ids"].to(torch_device),
|
||||
attention_mask=dct["attention_mask"].to(torch_device),
|
||||
num_beams=2,
|
||||
max_length=62,
|
||||
min_length=11,
|
||||
length_penalty=1.0,
|
||||
no_repeat_ngram_size=3,
|
||||
early_stopping=True,
|
||||
decoder_start_token_id=model.config.eos_token_id,
|
||||
)
|
||||
|
||||
decoded = [
|
||||
tok.decode(g, skip_special_tokens=True, clean_up_tokenization_spaces=False) for g in hypotheses_batch
|
||||
]
|
||||
self.assertEqual(EXPECTED_SUMMARY, decoded[0])
|
||||
|
||||
def test_xsum_config_generation_params(self):
|
||||
config = BartConfig.from_pretrained("bart-large-xsum")
|
||||
expected_params = dict(num_beams=6, do_sample=False, early_stopping=True, length_penalty=1.0)
|
||||
config_params = {k: getattr(config, k, "MISSING") for k, v in expected_params.items()}
|
||||
self.assertDictEqual(expected_params, config_params)
|
||||
|
||||
@slow
|
||||
def test_cnn_summarization_same_as_fairseq(self):
|
||||
hf = BartForConditionalGeneration.from_pretrained("bart-large-cnn", output_past=True,).to(torch_device)
|
||||
|
||||
@@ -641,14 +641,14 @@ class ModelTesterMixin:
|
||||
with self.assertRaises(AssertionError):
|
||||
model.generate(do_sample=True, max_length=5)
|
||||
# batch_size = 1
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=True))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True))
|
||||
# batch_size = 1, num_beams > 1
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=True, num_beams=3))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True, num_beams=3))
|
||||
else:
|
||||
# batch_size = 1
|
||||
self._check_generated_tokens(model.generate(do_sample=True, max_length=5))
|
||||
self._check_generated_ids(model.generate(do_sample=True, max_length=5))
|
||||
# batch_size = 1, num_beams > 1
|
||||
self._check_generated_tokens(model.generate(do_sample=True, max_length=5, num_beams=3))
|
||||
self._check_generated_ids(model.generate(do_sample=True, max_length=5, num_beams=3))
|
||||
|
||||
with self.assertRaises(AssertionError):
|
||||
# generating multiple sequences when greedy no beam generation
|
||||
@@ -660,24 +660,52 @@ class ModelTesterMixin:
|
||||
model.generate(input_ids, do_sample=False, num_return_sequences=3, num_beams=2)
|
||||
|
||||
# batch_size > 1, sample
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=True, num_return_sequences=3))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True, num_return_sequences=3))
|
||||
# batch_size > 1, greedy
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=False))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=False))
|
||||
|
||||
# batch_size > 1, num_beams > 1, sample
|
||||
self._check_generated_tokens(
|
||||
model.generate(input_ids, do_sample=True, num_beams=3, num_return_sequences=3,)
|
||||
)
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True, num_beams=3, num_return_sequences=3,))
|
||||
# batch_size > 1, num_beams > 1, greedy
|
||||
self._check_generated_tokens(
|
||||
model.generate(input_ids, do_sample=False, num_beams=3, num_return_sequences=3)
|
||||
)
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=False, num_beams=3, num_return_sequences=3))
|
||||
|
||||
def _check_generated_tokens(self, output_ids):
|
||||
# check bad words tokens language generation
|
||||
bad_words_ids = [
|
||||
ids_tensor((1, 1), self.model_tester.vocab_size).squeeze(-1).tolist(),
|
||||
ids_tensor((2, 1), self.model_tester.vocab_size).squeeze(-1).tolist(),
|
||||
]
|
||||
|
||||
# sampling
|
||||
output_tokens = model.generate(
|
||||
input_ids, do_sample=True, bad_words_ids=bad_words_ids, num_return_sequences=3
|
||||
)
|
||||
generated_ids = output_tokens[:, input_ids.shape[-1] :]
|
||||
self.assertFalse(self._check_match_tokens(generated_ids.tolist(), bad_words_ids))
|
||||
|
||||
# beam search
|
||||
output_tokens = model.generate(
|
||||
input_ids, do_sample=False, bad_words_ids=bad_words_ids, num_beams=3, num_return_sequences=3
|
||||
)
|
||||
generated_ids = output_tokens[:, input_ids.shape[-1] :]
|
||||
self.assertFalse(self._check_match_tokens(generated_ids.tolist(), bad_words_ids))
|
||||
|
||||
def _check_generated_ids(self, output_ids):
|
||||
for token_id in output_ids[0].tolist():
|
||||
self.assertGreaterEqual(token_id, 0)
|
||||
self.assertLess(token_id, self.model_tester.vocab_size)
|
||||
|
||||
def _check_match_tokens(self, generated_ids, bad_words_ids):
|
||||
# for all bad word tokens
|
||||
for bad_word_ids in bad_words_ids:
|
||||
# for all slices in batch
|
||||
for generated_ids_slice in generated_ids:
|
||||
# for all word idx
|
||||
for i in range(len(bad_word_ids), len(generated_ids_slice)):
|
||||
# if tokens match
|
||||
if generated_ids_slice[i - len(bad_word_ids) : i] == bad_word_ids:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
global_rng = random.Random()
|
||||
|
||||
|
||||
+181
-3
File diff suppressed because one or more lines are too long
@@ -162,6 +162,10 @@ class TFModelTesterMixin:
|
||||
pt_inputs_dict = dict(
|
||||
(name, torch.from_numpy(key.numpy()).to(torch.long)) for name, key in inputs_dict.items()
|
||||
)
|
||||
# need to rename encoder-decoder "inputs" for PyTorch
|
||||
if "inputs" in pt_inputs_dict and self.is_encoder_decoder:
|
||||
pt_inputs_dict["input_ids"] = pt_inputs_dict.pop("inputs")
|
||||
|
||||
with torch.no_grad():
|
||||
pto = pt_model(**pt_inputs_dict)
|
||||
tfo = tf_model(inputs_dict, training=False)
|
||||
@@ -201,6 +205,10 @@ class TFModelTesterMixin:
|
||||
pt_inputs_dict = dict(
|
||||
(name, torch.from_numpy(key.numpy()).to(torch.long)) for name, key in inputs_dict.items()
|
||||
)
|
||||
# need to rename encoder-decoder "inputs" for PyTorch
|
||||
if "inputs" in pt_inputs_dict and self.is_encoder_decoder:
|
||||
pt_inputs_dict["input_ids"] = pt_inputs_dict.pop("inputs")
|
||||
|
||||
with torch.no_grad():
|
||||
pto = pt_model(**pt_inputs_dict)
|
||||
tfo = tf_model(inputs_dict)
|
||||
@@ -223,7 +231,7 @@ class TFModelTesterMixin:
|
||||
if self.is_encoder_decoder:
|
||||
input_ids = {
|
||||
"decoder_input_ids": tf.keras.Input(batch_shape=(2, 2000), name="decoder_input_ids", dtype="int32"),
|
||||
"input_ids": tf.keras.Input(batch_shape=(2, 2000), name="input_ids", dtype="int32"),
|
||||
"inputs": tf.keras.Input(batch_shape=(2, 2000), name="inputs", dtype="int32"),
|
||||
}
|
||||
else:
|
||||
input_ids = tf.keras.Input(batch_shape=(2, 2000), name="input_ids", dtype="int32")
|
||||
@@ -259,7 +267,7 @@ class TFModelTesterMixin:
|
||||
outputs_dict = model(inputs_dict)
|
||||
|
||||
inputs_keywords = copy.deepcopy(inputs_dict)
|
||||
input_ids = inputs_keywords.pop("input_ids" if not self.is_encoder_decoder else "decoder_input_ids", None,)
|
||||
input_ids = inputs_keywords.pop("input_ids" if not self.is_encoder_decoder else "inputs", None,)
|
||||
outputs_keywords = model(input_ids, **inputs_keywords)
|
||||
|
||||
output_dict = outputs_dict[0].numpy()
|
||||
@@ -395,9 +403,9 @@ class TFModelTesterMixin:
|
||||
input_ids = inputs_dict["input_ids"]
|
||||
del inputs_dict["input_ids"]
|
||||
else:
|
||||
encoder_input_ids = inputs_dict["input_ids"]
|
||||
encoder_input_ids = inputs_dict["inputs"]
|
||||
decoder_input_ids = inputs_dict["decoder_input_ids"]
|
||||
del inputs_dict["input_ids"]
|
||||
del inputs_dict["inputs"]
|
||||
del inputs_dict["decoder_input_ids"]
|
||||
|
||||
for model_class in self.all_model_classes:
|
||||
@@ -415,7 +423,7 @@ class TFModelTesterMixin:
|
||||
def test_lm_head_model_random_generate(self):
|
||||
|
||||
config, inputs_dict = self.model_tester.prepare_config_and_inputs_for_common()
|
||||
input_ids = inputs_dict["input_ids"]
|
||||
input_ids = inputs_dict["input_ids"] if "input_ids" in inputs_dict else inputs_dict["inputs"]
|
||||
|
||||
if self.is_encoder_decoder:
|
||||
config.output_past = True # needed for Bart TODO: might have to update for other encoder-decoder models
|
||||
@@ -427,14 +435,14 @@ class TFModelTesterMixin:
|
||||
with self.assertRaises(AssertionError):
|
||||
model.generate(do_sample=True, max_length=5)
|
||||
# batch_size = 1
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=True))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True))
|
||||
# batch_size = 1, num_beams > 1
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=True, num_beams=3))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True, num_beams=3))
|
||||
else:
|
||||
# batch_size = 1
|
||||
self._check_generated_tokens(model.generate(do_sample=True, max_length=5))
|
||||
self._check_generated_ids(model.generate(do_sample=True, max_length=5))
|
||||
# batch_size = 1, num_beams > 1
|
||||
self._check_generated_tokens(model.generate(do_sample=True, max_length=5, num_beams=3))
|
||||
self._check_generated_ids(model.generate(do_sample=True, max_length=5, num_beams=3))
|
||||
|
||||
with self.assertRaises(AssertionError):
|
||||
# generating multiple sequences when greedy no beam generation
|
||||
@@ -446,24 +454,52 @@ class TFModelTesterMixin:
|
||||
model.generate(input_ids, do_sample=False, num_return_sequences=3, num_beams=2)
|
||||
|
||||
# batch_size > 1, sample
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=True, num_return_sequences=3))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True, num_return_sequences=3))
|
||||
# batch_size > 1, greedy
|
||||
self._check_generated_tokens(model.generate(input_ids, do_sample=False))
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=False))
|
||||
|
||||
# batch_size > 1, num_beams > 1, sample
|
||||
self._check_generated_tokens(
|
||||
model.generate(input_ids, do_sample=True, num_beams=3, num_return_sequences=3,)
|
||||
)
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=True, num_beams=3, num_return_sequences=3,))
|
||||
# batch_size > 1, num_beams > 1, greedy
|
||||
self._check_generated_tokens(
|
||||
model.generate(input_ids, do_sample=False, num_beams=3, num_return_sequences=3)
|
||||
)
|
||||
self._check_generated_ids(model.generate(input_ids, do_sample=False, num_beams=3, num_return_sequences=3))
|
||||
|
||||
def _check_generated_tokens(self, output_ids):
|
||||
# check bad words tokens language generation
|
||||
bad_words_ids = [
|
||||
tf.squeeze(ids_tensor((1, 1), self.model_tester.vocab_size), -1).numpy().tolist(),
|
||||
tf.squeeze(ids_tensor((2, 1), self.model_tester.vocab_size), -1).numpy().tolist(),
|
||||
]
|
||||
|
||||
# sampling
|
||||
output_tokens = model.generate(
|
||||
input_ids, do_sample=True, bad_words_ids=bad_words_ids, num_return_sequences=3
|
||||
)
|
||||
generated_ids = output_tokens[:, input_ids.shape[-1] :]
|
||||
self.assertFalse(self._check_match_tokens(generated_ids.numpy().tolist(), bad_words_ids))
|
||||
|
||||
# beam search
|
||||
output_tokens = model.generate(
|
||||
input_ids, do_sample=False, bad_words_ids=bad_words_ids, num_beams=3, num_return_sequences=3
|
||||
)
|
||||
generated_ids = output_tokens[:, input_ids.shape[-1] :]
|
||||
self.assertFalse(self._check_match_tokens(generated_ids.numpy().tolist(), bad_words_ids))
|
||||
|
||||
def _check_generated_ids(self, output_ids):
|
||||
for token_id in output_ids[0].numpy().tolist():
|
||||
self.assertGreaterEqual(token_id, 0)
|
||||
self.assertLess(token_id, self.model_tester.vocab_size)
|
||||
|
||||
def _check_match_tokens(self, generated_ids, bad_words_ids):
|
||||
# for all bad word tokens
|
||||
for bad_word_ids in bad_words_ids:
|
||||
# for all slices in batch
|
||||
for generated_ids_slice in generated_ids:
|
||||
# for all word idx
|
||||
for i in range(len(bad_word_ids), len(generated_ids_slice)):
|
||||
# if tokens match
|
||||
if generated_ids_slice[i - len(bad_word_ids) : i] == bad_word_ids:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def ids_tensor(shape, vocab_size, rng=None, name=None, dtype=None):
|
||||
"""Creates a random int32 tensor of the shape within the vocab size."""
|
||||
|
||||
File diff suppressed because one or more lines are too long
Reference in New Issue
Block a user