Compare commits
61
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 sshleifer |
4c62bdc466 | ||
|
sshleifer
|
6e0680ace3 | ||
|
Sam Shleifer
|
ef74b0f07a | ||
|
Lysandre
|
f54a5bd37f | ||
|
Lysandre
|
569897ce2c | ||
|
Julien Chaumond
|
21da895013 | ||
|
Julien Chaumond
|
9a70910d47 | ||
|
Julien Chaumond
|
9274734a0d | ||
|
Manuel Romero
|
69f948461f | ||
|
Julien Chaumond
|
e0b6247cf7 | ||
|
sshleifer
|
5f2dd71d1b | ||
|
sshleifer
|
31158af57c | ||
|
sshleifer
|
5dd61fb9a9 | ||
|
Oleksiy Syvokon
|
ee5de0ba44 | ||
|
jiyeon
|
bed38d3afe | ||
|
Stefan Schweter
|
498d06e914 | ||
|
Funtowicz Morgan
|
3e3a9e2c01 | ||
|
Julien Chaumond
|
1f5db9a13c | ||
|
Julien Chaumond
|
95bac8dabb | ||
|
ahotrodandJulien Chaumond
|
ba498eac38 | ||
|
Malte Pietsch
|
68ccc04ee6 | ||
|
Lysandre
|
539f601be7 | ||
|
Lysandre
|
cfb7d108bd | ||
|
Julien ChaumondandKevin Canwen Xu
|
b4691a438d | ||
|
Julien Chaumond
|
fc325e97cd | ||
|
Lysandre
|
fd639e5be3 | ||
|
Julien Chaumond
|
63a5399bc4 | ||
|
Lysandre
|
125a75a121 | ||
|
Malte Pietsch
|
9c64d1da35 | ||
|
Kevin Canwen Xu
|
bf99014c46 | ||
|
Thomas Wolf
|
92e974196f | ||
|
Morgan Funtowicz
|
6aa7973aec | ||
|
Lysandre
|
520e7f2119 | ||
|
Lysandre
|
dd28830327 | ||
|
Lysandre
|
db97930122 | ||
|
Lysandre
|
7046de2991 | ||
|
VictorSanh
|
0d3aa3c04c | ||
|
VictorSanh
|
d8b43600fd | ||
|
VictorSanh
|
ee5a6856ca | ||
|
monologg
|
73368963b2 | ||
|
Ari
|
d7dabfeff5 | ||
|
Julien Chaumond
|
42f08e596f | ||
|
Julien Chaumond
|
4f7bdb0958 | ||
|
thomwolf
|
c6c5c3fd4e | ||
|
thomwolf
|
961c69776f | ||
|
thomwolf
|
d311f87bca | ||
|
thomwolf
|
7d99e05f76 | ||
|
dchurchwell
|
2c12464a20 | ||
|
Peter Izsak
|
6fc3d34abd | ||
|
Julien Chaumond
|
7748cbbe7d | ||
|
Julien Chaumond
|
432c12521e | ||
|
Clement
|
c069932f5d | ||
|
Lysandre Debut
|
33d3072e1c | ||
|
Julien Chaumond
|
eae8ee0389 | ||
|
James Betker
|
6bb6a01765 | ||
|
Julien ChaumondandLysandre Debut
|
ada24def22 | ||
|
Lysandre
|
2184f87003 | ||
|
Lysandre
|
e615269cb8 | ||
|
Lysandre
|
5f96ebc0be | ||
|
Lysandre
|
950c6a4f09 | ||
|
Lysandre
|
d28b81dc29 |
No files matched your search
@@ -10,7 +10,7 @@ jobs:
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[sklearn,tf,torch,testing]
|
||||
- run: sudo pip install .[sklearn,tf-cpu,torch,testing]
|
||||
- run: sudo pip install codecov pytest-cov
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/ --cov
|
||||
- run: codecov
|
||||
@@ -26,7 +26,7 @@ jobs:
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[mecab,sklearn,tf,torch,testing]
|
||||
- run: sudo pip install .[mecab,sklearn,tf-cpu,torch,testing]
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
run_tests_torch:
|
||||
working_directory: ~/transformers
|
||||
@@ -52,7 +52,7 @@ jobs:
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[sklearn,tf,testing]
|
||||
- run: sudo pip install .[sklearn,tf-cpu,testing]
|
||||
- run: sudo pip install codecov pytest-cov
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/ --cov
|
||||
- run: codecov
|
||||
|
||||
+5
-3
@@ -198,11 +198,13 @@ Follow these steps to start contributing:
|
||||
3. To indicate a work in progress please prefix the title with `[WIP]`. These
|
||||
are useful to avoid duplicated work, and to differentiate it from PRs ready
|
||||
to be merged;
|
||||
4. Make sure pre-existing tests still pass;
|
||||
5. Add high-coverage tests. No quality test, no merge;
|
||||
4. Make sure existing tests pass;
|
||||
5. Add high-coverage tests. No quality test, no merge.
|
||||
- If you are adding a new model, make sure that you use `ModelTester.all_model_classes = (MyModel, MyModelWithLMHead,...)`, which triggers the common tests.
|
||||
- If you are adding new `@slow` tests, make sure they pass using `RUN_SLOW=1 python -m pytest tests/test_my_new_model.py`.
|
||||
CircleCI does not run them.
|
||||
6. All public methods must have informative docstrings;
|
||||
|
||||
|
||||
### Tests
|
||||
|
||||
You can run 🤗 Transformers tests with `unittest` or `pytest`.
|
||||
|
||||
@@ -24,6 +24,8 @@
|
||||
|
||||
🤗 Transformers (formerly known as `pytorch-transformers` and `pytorch-pretrained-bert`) provides state-of-the-art general-purpose architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet, CTRL...) for Natural Language Understanding (NLU) and Natural Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between TensorFlow 2.0 and PyTorch.
|
||||
|
||||
[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/0)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/1)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/2)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/3)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/4)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/5)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/6)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/7)
|
||||
|
||||
### Features
|
||||
|
||||
- As easy to use as pytorch-transformers
|
||||
@@ -193,7 +195,7 @@ MODELS = [(BertModel, BertTokenizer, 'bert-base-uncased'),
|
||||
(TransfoXLModel, TransfoXLTokenizer, 'transfo-xl-wt103'),
|
||||
(XLNetModel, XLNetTokenizer, 'xlnet-base-cased'),
|
||||
(XLMModel, XLMTokenizer, 'xlm-mlm-enfr-1024'),
|
||||
(DistilBertModel, DistilBertTokenizer, 'distilbert-base-uncased'),
|
||||
(DistilBertModel, DistilBertTokenizer, 'distilbert-base-cased'),
|
||||
(RobertaModel, RobertaTokenizer, 'roberta-base'),
|
||||
(XLMRobertaModel, XLMRobertaTokenizer, 'xlm-roberta-base'),
|
||||
]
|
||||
@@ -493,19 +495,22 @@ Your model will then be accessible through its identifier, a concatenation of yo
|
||||
"username/pretrained_model"
|
||||
```
|
||||
|
||||
**Please add a README.md model card** to the repo under `model_cards/` with: model description, training params (dataset, preprocessing, hyperparameters), evaluation results, intended uses & limitations, etc.
|
||||
|
||||
Your model now has a page on huggingface.co/models 🔥
|
||||
|
||||
Anyone can load it from code:
|
||||
```python
|
||||
tokenizer = AutoTokenizer.from_pretrained("username/pretrained_model")
|
||||
model = AutoModel.from_pretrained("username/pretrained_model")
|
||||
```
|
||||
|
||||
Finally, list all your files on S3:
|
||||
List all your files on S3:
|
||||
```shell
|
||||
transformers-cli s3 ls
|
||||
# List all your S3 objects.
|
||||
```
|
||||
|
||||
You can also delete files:
|
||||
You can also delete unneeded files:
|
||||
|
||||
```shell
|
||||
transformers-cli s3 rm …
|
||||
|
||||
@@ -194,3 +194,41 @@ h2, .rst-content .toctree-wrapper p.caption, h3, h4, h5, h6, legend{
|
||||
src: url(./Calibre-Thin.otf);
|
||||
font-weight:400;
|
||||
}
|
||||
|
||||
|
||||
/**
|
||||
* Nav Links to other parts of huggingface.co
|
||||
*/
|
||||
div.menu {
|
||||
position: absolute;
|
||||
top: 0;
|
||||
right: 0;
|
||||
padding-top: 20px;
|
||||
padding-right: 20px;
|
||||
z-index: 1000;
|
||||
}
|
||||
div.menu a {
|
||||
font-size: 14px;
|
||||
letter-spacing: 0.3px;
|
||||
text-transform: uppercase;
|
||||
color: white;
|
||||
-webkit-font-smoothing: antialiased;
|
||||
background: linear-gradient(0deg, #6671ffb8, #9a66ffb8 50%);
|
||||
padding: 10px 16px 6px 16px;
|
||||
border-radius: 3px;
|
||||
margin-left: 12px;
|
||||
position: relative;
|
||||
}
|
||||
div.menu a:active {
|
||||
top: 1px;
|
||||
}
|
||||
@media (min-width: 768px) and (max-width: 1750px) {
|
||||
.wy-breadcrumbs {
|
||||
margin-top: 32px;
|
||||
}
|
||||
}
|
||||
@media (max-width: 768px) {
|
||||
div.menu {
|
||||
display: none;
|
||||
}
|
||||
}
|
||||
@@ -58,6 +58,16 @@ function addGithubButton() {
|
||||
document.querySelector(".wy-side-nav-search .icon-home").insertAdjacentHTML('afterend', div);
|
||||
}
|
||||
|
||||
function addHfMenu() {
|
||||
const div = `
|
||||
<div class="menu">
|
||||
<a href="/welcome">🔥 Sign in</a>
|
||||
<a href="/models">🚀 Models</a>
|
||||
</div>
|
||||
`;
|
||||
document.body.insertAdjacentHTML('afterbegin', div);
|
||||
}
|
||||
|
||||
/*!
|
||||
* github-buttons v2.2.10
|
||||
* (c) 2019 なつき
|
||||
@@ -74,6 +84,7 @@ function onLoad() {
|
||||
addCustomFooter();
|
||||
addGithubButton();
|
||||
parseGithubButtons();
|
||||
addHfMenu();
|
||||
}
|
||||
|
||||
window.addEventListener("load", onLoad);
|
||||
@@ -63,7 +63,7 @@ XNLI
|
||||
`The Cross-Lingual NLI Corpus (XNLI) <https://www.nyu.edu/projects/bowman/xnli/>`__ is a benchmark that evaluates
|
||||
the quality of cross-lingual text representations.
|
||||
XNLI is crowd-sourced dataset based on `MultiNLI <http://www.nyu.edu/projects/bowman/multinli/>`: pairs of text are labeled with textual entailment
|
||||
annotations for 15 different languages (including both high-ressource language such as English and low-ressource languages such as Swahili).
|
||||
annotations for 15 different languages (including both high-resource language such as English and low-resource languages such as Swahili).
|
||||
|
||||
It was released together with the paper
|
||||
`XNLI: Evaluating Cross-lingual Sentence Representations <https://arxiv.org/abs/1809.05053>`__
|
||||
|
||||
@@ -23,6 +23,9 @@ Tips:
|
||||
|
||||
- This implementation is the same as :class:`~transformers.BertModel` with a tiny embeddings tweak as well as a
|
||||
setup for Roberta pretrained models.
|
||||
- RoBERTa has the same architecture as BERT, but uses a byte-level BPE as a tokenizer (same as GPT-2) and uses a
|
||||
different pre-training scheme.
|
||||
- RoBERTa doesn't have `token_type_ids`, you don't need to indicate which token belongs to which segment. Just separate your segments with the separation token `tokenizer.sep_token` (or `</s>`)
|
||||
- `Camembert <./camembert.html>`__ is a wrapper around RoBERTa. Refer to this page for usage examples.
|
||||
|
||||
RobertaConfig
|
||||
|
||||
@@ -22,6 +22,9 @@ and XNLI benchmarks. We will make XLM-R code, data, and models publicly availabl
|
||||
|
||||
Tips:
|
||||
|
||||
- XLM-R is a multilingual model trained on 100 different languages. Unlike some XLM multilingual models, it does
|
||||
not require `lang` tensors to understand which language is used, and should be able to determine the correct
|
||||
language from the input ids.
|
||||
- This implementation is the same as RoBERTa. Refer to the `documentation of RoBERTa <./roberta.html>`__ for usage
|
||||
examples as well as the information relative to the inputs and outputs.
|
||||
|
||||
|
||||
@@ -26,19 +26,22 @@ Your model will then be accessible through its identifier, a concatenation of yo
|
||||
"username/pretrained_model"
|
||||
```
|
||||
|
||||
**Please add a README.md model card** to the repo under `model_cards/` with: model description, training params (dataset, preprocessing, hyperparameters), evaluation results, intended uses & limitations, etc.
|
||||
|
||||
Your model now has a page on huggingface.co/models 🔥
|
||||
|
||||
Anyone can load it from code:
|
||||
```python
|
||||
tokenizer = AutoTokenizer.from_pretrained("username/pretrained_model")
|
||||
model = AutoModel.from_pretrained("username/pretrained_model")
|
||||
```
|
||||
|
||||
Finally, list all your files on S3:
|
||||
List all your files on S3:
|
||||
```shell
|
||||
transformers-cli s3 ls
|
||||
# List all your S3 objects.
|
||||
```
|
||||
|
||||
You can also delete files:
|
||||
You can also delete unneeded files:
|
||||
|
||||
```shell
|
||||
transformers-cli s3 rm …
|
||||
|
||||
@@ -179,6 +179,14 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | | | The DistilBERT model distilled from the BERT model `bert-base-uncased` checkpoint, with an additional linear layer. |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``distilbert-base-cased`` | | 6-layer, 768-hidden, 12-heads, 65M parameters |
|
||||
| | | | The DistilBERT model distilled from the BERT model `bert-base-cased` checkpoint |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``distilbert-base-cased-distilled-squad`` | | 6-layer, 768-hidden, 12-heads, 65M parameters |
|
||||
| | | | The DistilBERT model distilled from the BERT model `bert-base-cased` checkpoint, with an additional question answering layer. |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``distilgpt2`` | | 6-layer, 768-hidden, 12-heads, 82M parameters |
|
||||
| | | | The DistilGPT2 model distilled from the GPT2 model `gpt2` checkpoint. |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
|
||||
@@ -209,7 +209,7 @@ past = None
|
||||
for i in range(100):
|
||||
print(i)
|
||||
output, past = model(context, past=past)
|
||||
token = torch.argmax(output[0, :])
|
||||
token = torch.argmax(output[..., -1, :])
|
||||
|
||||
generated += [token.tolist()]
|
||||
context = token.unsqueeze(0)
|
||||
|
||||
+16
-17
@@ -17,15 +17,14 @@ pip install -r ./examples/requirements.txt
|
||||
| Section | Description |
|
||||
|----------------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| [TensorFlow 2.0 models on GLUE](#TensorFlow-2.0-Bert-models-on-GLUE) | Examples running BERT TensorFlow 2.0 model on the GLUE tasks.
|
||||
| [Language Model fine-tuning](#language-model-fine-tuning) | Fine-tuning the library models for language modeling on a text dataset. Causal language modeling for GPT/GPT-2, masked language modeling for BERT/RoBERTa. |
|
||||
| [Language Generation](#language-generation) | Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, Transformer-XL and XLNet. |
|
||||
| [GLUE](#glue) | Examples running BERT/XLM/XLNet/RoBERTa on the 9 GLUE tasks. Examples feature distributed training as well as half-precision. |
|
||||
| [SQuAD](#squad) | Using BERT/RoBERTa/XLNet/XLM for question answering, examples with distributed training. |
|
||||
| [Multiple Choice](#multiple-choice) | Examples running BERT/XLNet/RoBERTa on the SWAG/RACE/ARC tasks.
|
||||
| [Named Entity Recognition](#named-entity-recognition) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [Language Model training](#language-model-training) | Fine-tuning (or training from scratch) the library models for language modeling on a text dataset. Causal language modeling for GPT/GPT-2, masked language modeling for BERT/RoBERTa. |
|
||||
| [Language Generation](#language-generation) | Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, Transformer-XL and XLNet. |
|
||||
| [GLUE](#glue) | Examples running BERT/XLM/XLNet/RoBERTa on the 9 GLUE tasks. Examples feature distributed training as well as half-precision. |
|
||||
| [SQuAD](#squad) | Using BERT/RoBERTa/XLNet/XLM for question answering, examples with distributed training. |
|
||||
| [Multiple Choice](#multiple-choice) | Examples running BERT/XLNet/RoBERTa on the SWAG/RACE/ARC tasks. |
|
||||
| [Named Entity Recognition](#named-entity-recognition) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [XNLI](#xnli) | Examples running BERT/XLM on the XNLI benchmark. |
|
||||
| [Adversarial evaluation of model performances](#adversarial-evaluation-of-model-performances) | Testing a model with adversarial evaluation of natural language
|
||||
inference on the Heuristic Analysis for NLI Systems (HANS) dataset (McCoy et al., 2019.) |
|
||||
| [Adversarial evaluation of model performances](#adversarial-evaluation-of-model-performances) | Testing a model with adversarial evaluation of natural language inference on the Heuristic Analysis for NLI Systems (HANS) dataset (McCoy et al., 2019.) |
|
||||
|
||||
## TensorFlow 2.0 Bert models on GLUE
|
||||
|
||||
@@ -49,16 +48,16 @@ Quick benchmarks from the script (no other modifications):
|
||||
|
||||
Mixed precision (AMP) reduces the training time considerably for the same hardware and hyper-parameters (same batch size was used).
|
||||
|
||||
## Language model fine-tuning
|
||||
## Language model training
|
||||
|
||||
Based on the script [`run_lm_finetuning.py`](https://github.com/huggingface/transformers/blob/master/examples/run_lm_finetuning.py).
|
||||
Based on the script [`run_language_modeling.py`](https://github.com/huggingface/transformers/blob/master/examples/run_language_modeling.py).
|
||||
|
||||
Fine-tuning the library models for language modeling on a text dataset for GPT, GPT-2, BERT and RoBERTa (DistilBERT
|
||||
Fine-tuning (or training from scratch) the library models for language modeling on a text dataset for GPT, GPT-2, BERT and RoBERTa (DistilBERT
|
||||
to be added soon). GPT and GPT-2 are fine-tuned using a causal language modeling (CLM) loss while BERT and RoBERTa
|
||||
are fine-tuned using a masked language modeling (MLM) loss.
|
||||
|
||||
Before running the following example, you should get a file that contains text on which the language model will be
|
||||
fine-tuned. A good example of such text is the [WikiText-2 dataset](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/).
|
||||
trained or fine-tuned. A good example of such text is the [WikiText-2 dataset](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/).
|
||||
|
||||
We will refer to two different files: `$TRAIN_FILE`, which contains text for training, and `$TEST_FILE`, which contains
|
||||
text that will be used for evaluation.
|
||||
@@ -72,7 +71,7 @@ the tokenization). The loss here is that of causal language modeling.
|
||||
export TRAIN_FILE=/path/to/dataset/wiki.train.raw
|
||||
export TEST_FILE=/path/to/dataset/wiki.test.raw
|
||||
|
||||
python run_lm_finetuning.py \
|
||||
python run_language_modeling.py \
|
||||
--output_dir=output \
|
||||
--model_type=gpt2 \
|
||||
--model_name_or_path=gpt2 \
|
||||
@@ -100,7 +99,7 @@ We use the `--mlm` flag so that the script may change its loss function.
|
||||
export TRAIN_FILE=/path/to/dataset/wiki.train.raw
|
||||
export TEST_FILE=/path/to/dataset/wiki.test.raw
|
||||
|
||||
python run_lm_finetuning.py \
|
||||
python run_language_modeling.py \
|
||||
--output_dir=output \
|
||||
--model_type=roberta \
|
||||
--model_name_or_path=roberta-base \
|
||||
@@ -154,7 +153,7 @@ between different runs. We report the median on 5 runs (with different seeds) fo
|
||||
Some of these results are significantly different from the ones reported on the test set
|
||||
of GLUE benchmark on the website. For QQP and WNLI, please refer to [FAQ #12](https://gluebenchmark.com/faq) on the webite.
|
||||
|
||||
Before running anyone of these GLUE tasks you should download the
|
||||
Before running any one of these GLUE tasks you should download the
|
||||
[GLUE data](https://gluebenchmark.com/tasks) by running
|
||||
[this script](https://gist.github.com/W4ngatang/60c2bdb54d156a41194446737ce03e2e)
|
||||
and unpack it to some directory `$GLUE_DIR`.
|
||||
@@ -196,7 +195,7 @@ since the data processor for each task inherits from the base class DataProcesso
|
||||
The following examples fine-tune BERT on the Microsoft Research Paraphrase Corpus (MRPC) corpus and runs in less
|
||||
than 10 minutes on a single K-80 and in 27 seconds (!) on single tesla V100 16GB with apex installed.
|
||||
|
||||
Before running anyone of these GLUE tasks you should download the
|
||||
Before running any one of these GLUE tasks you should download the
|
||||
[GLUE data](https://gluebenchmark.com/tasks) by running
|
||||
[this script](https://gist.github.com/W4ngatang/60c2bdb54d156a41194446737ce03e2e)
|
||||
and unpack it to some directory `$GLUE_DIR`.
|
||||
@@ -701,7 +700,7 @@ macro avg 0.8712 0.8774 0.8740 13869
|
||||
|
||||
Based on the script [`run_xnli.py`](https://github.com/huggingface/transformers/blob/master/examples/run_xnli.py).
|
||||
|
||||
[XNLI](https://www.nyu.edu/projects/bowman/xnli/) is crowd-sourced dataset based on [MultiNLI](http://www.nyu.edu/projects/bowman/multinli/). It is an evaluation benchmark for cross-lingual text representations. Pairs of text are labeled with textual entailment annotations for 15 different languages (including both high-ressource language such as English and low-ressource languages such as Swahili).
|
||||
[XNLI](https://www.nyu.edu/projects/bowman/xnli/) is crowd-sourced dataset based on [MultiNLI](http://www.nyu.edu/projects/bowman/multinli/). It is an evaluation benchmark for cross-lingual text representations. Pairs of text are labeled with textual entailment annotations for 15 different languages (including both high-resource language such as English and low-resource languages such as Swahili).
|
||||
|
||||
#### Fine-tuning on XNLI
|
||||
|
||||
|
||||
@@ -31,8 +31,10 @@ Here are the results on the dev sets of GLUE:
|
||||
|
||||
| Model | Macro-score | CoLA | MNLI | MRPC | QNLI | QQP | RTE | SST-2| STS-B| WNLI |
|
||||
| :---: | :---: | :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---: |
|
||||
| BERT-base-uncased | **77.6** | 49.2 | 80.8 | 87.4 | 87.5 | 86.4 | 61.7 | 92.0 | 83.8 | 45.1 |
|
||||
| DistilBERT-base-uncased | **76.8** | 43.6 | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 | 56.3 |
|
||||
| BERT-base-uncased | **74.9** | 49.2 | 80.8 | 87.4 | 87.5 | 86.4 | 61.7 | 92.0 | 83.8 | 45.1 |
|
||||
| DistilBERT-base-uncased | **74.3** | 43.6 | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 | 56.3 |
|
||||
| BERT-base-cased | **78.2** | 58.2 | 83.9 | 87.8 | 91.0 | 89.2 | 66.1 | 91.7 | 89.2 | 46.5 |
|
||||
| DistilBERT-base-cased | **75.9** | 47.2 | 81.5 | 85.6 | 88.2 | 87.8 | 60.6 | 90.4 | 85.5 | 56.3 |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| RoBERTa-base (reported) | **83.2**/**86.4**<sup>2</sup> | 63.6 | 87.6 | 90.2 | 92.8 | 91.9 | 78.7 | 94.8 | 91.2 | 57.7<sup>3</sup> |
|
||||
| DistilRoBERTa<sup>1</sup> | **79.0**/**82.3**<sup>2</sup> | 59.3 | 84.0 | 86.6 | 90.8 | 89.4 | 67.9 | 92.5 | 88.3 | 52.1 |
|
||||
@@ -63,7 +65,9 @@ This part of the library has only be tested with Python3.6+. There are few speci
|
||||
Transformers includes five pre-trained Distil* models, currently only provided for English and German (we are investigating the possibility to train and release a multilingual version of DistilBERT):
|
||||
|
||||
- `distilbert-base-uncased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-uncased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 66M parameters.
|
||||
- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 86.9 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 88.5 F1 score).
|
||||
- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 79.8 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 82.3 F1 score).
|
||||
- `distilbert-base-cased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-cased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 65M parameters.
|
||||
- `distilbert-base-cased-distilled-squad`: A finetuned version of `distilbert-base-cased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 87.1 on the dev set (for comparison, Bert `bert-base-cased` version reaches a 88.7 F1 score).
|
||||
- `distilbert-base-german-cased`: DistilBERT German language model pretrained on 1/2 of the data used to pretrain Bert using distillation with the supervision of the `bert-base-german-dbmdz-cased` version of German DBMDZ Bert. For NER tasks the model reaches a F1 score of 83.49 on the CoNLL-2003 test set (for comparison, `bert-base-german-dbmdz-cased` reaches a 84.52 F1 score), and a F1 score of 85.23 on the GermEval 2014 test set (`bert-base-german-dbmdz-cased` reaches a 86.89 F1 score).
|
||||
- `distilgpt2`: DistilGPT2 English language model pretrained with the supervision of `gpt2` (the smallest version of GPT2) on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset. The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 124M parameters for GPT2). On average, DistilGPT2 is two times faster than GPT2.
|
||||
- `distilroberta-base`: DistilRoBERTa English language model pretrained with the supervision of `roberta-base` solely on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset (it is ~4 times less training data than the teacher RoBERTa). The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 125M parameters for RoBERTa-base). On average DistilRoBERTa is twice as fast as Roberta-base.
|
||||
@@ -72,8 +76,8 @@ Transformers includes five pre-trained Distil* models, currently only provided f
|
||||
Using DistilBERT is very similar to using BERT. DistilBERT share the same tokenizer as BERT's `bert-base-uncased` even though we provide a link to this tokenizer under the `DistilBertTokenizer` name to have a consistent naming between the library models.
|
||||
|
||||
```python
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0)
|
||||
outputs = model(input_ids)
|
||||
@@ -81,6 +85,7 @@ last_hidden_states = outputs[0] # The last hidden-state is the first element of
|
||||
```
|
||||
|
||||
Similarly, using the other Distil* models simply consists in calling the base classes with a different pretrained checkpoint:
|
||||
- DistilBERT uncased: `model = DistilBertModel.from_pretrained('distilbert-base-uncased')`
|
||||
- DistilGPT2: `model = GPT2Model.from_pretrained('distilgpt2')`
|
||||
- DistilRoBERTa: `model = RobertaModel.from_pretrained('distilroberta-base')`
|
||||
- DistilmBERT: `model = DistilBertModel.from_pretrained('distilbert-base-multilingual-cased')`
|
||||
@@ -174,7 +179,7 @@ Happy distillation!
|
||||
|
||||
## Citation
|
||||
|
||||
If you find the ressource useful, you should cite the following paper:
|
||||
If you find the resource useful, you should cite the following paper:
|
||||
|
||||
```
|
||||
@inproceedings{sanh2019distilbert,
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
{
|
||||
"activation": "gelu",
|
||||
"attention_dropout": 0.1,
|
||||
"dim": 768,
|
||||
"dropout": 0.1,
|
||||
"hidden_dim": 3072,
|
||||
"initializer_range": 0.02,
|
||||
"max_position_embeddings": 512,
|
||||
"n_heads": 12,
|
||||
"n_layers": 6,
|
||||
"sinusoidal_pos_embds": true,
|
||||
"tie_weights_": true,
|
||||
"vocab_size": 28996
|
||||
}
|
||||
|
||||
@@ -310,7 +310,7 @@ def evaluate(args, model, tokenizer, prefix=""):
|
||||
eval_dataloader = DataLoader(eval_dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
|
||||
|
||||
# multi-gpu eval
|
||||
if args.n_gpu > 1:
|
||||
if args.n_gpu > 1 and not isinstance(model, torch.nn.DataParallel):
|
||||
model = torch.nn.DataParallel(model)
|
||||
|
||||
# Eval!
|
||||
|
||||
@@ -86,6 +86,9 @@ MODEL_CLASSES = {
|
||||
class TextDataset(Dataset):
|
||||
def __init__(self, tokenizer: PreTrainedTokenizer, args, file_path: str, block_size=512):
|
||||
assert os.path.isfile(file_path)
|
||||
|
||||
block_size = block_size - (tokenizer.max_len - tokenizer.max_len_single_sentence)
|
||||
|
||||
directory, filename = os.path.split(file_path)
|
||||
cached_features_file = os.path.join(
|
||||
directory, args.model_type + "_cached_lm_" + str(block_size) + "_" + filename
|
||||
@@ -118,7 +121,7 @@ class TextDataset(Dataset):
|
||||
return len(self.examples)
|
||||
|
||||
def __getitem__(self, item):
|
||||
return torch.tensor(self.examples[item])
|
||||
return torch.tensor(self.examples[item], dtype=torch.long)
|
||||
|
||||
|
||||
class LineByLineTextDataset(Dataset):
|
||||
@@ -130,15 +133,15 @@ class LineByLineTextDataset(Dataset):
|
||||
logger.info("Creating features from dataset file at %s", file_path)
|
||||
|
||||
with open(file_path, encoding="utf-8") as f:
|
||||
lines = [line for line in f.read().splitlines() if len(line) > 0]
|
||||
lines = [line for line in f.read().splitlines() if (len(line) > 0 and not line.isspace())]
|
||||
|
||||
self.examples = tokenizer.batch_encode_plus(lines, max_length=block_size)["input_ids"]
|
||||
self.examples = tokenizer.batch_encode_plus(lines, add_special_tokens=True, max_length=block_size)["input_ids"]
|
||||
|
||||
def __len__(self):
|
||||
return len(self.examples)
|
||||
|
||||
def __getitem__(self, i):
|
||||
return torch.tensor(self.examples[i])
|
||||
return torch.tensor(self.examples[i], dtype=torch.long)
|
||||
|
||||
|
||||
def load_and_cache_examples(args, tokenizer, evaluate=False):
|
||||
@@ -195,7 +198,12 @@ def _rotate_checkpoints(args, checkpoint_prefix="checkpoint", use_mtime=False) -
|
||||
|
||||
def mask_tokens(inputs: torch.Tensor, tokenizer: PreTrainedTokenizer, args) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
""" Prepare masked tokens inputs/labels for masked language modeling: 80% MASK, 10% random, 10% original. """
|
||||
inputs = inputs.clone().type(dtype=torch.long)
|
||||
|
||||
if tokenizer.mask_token is None:
|
||||
raise ValueError(
|
||||
"This tokenizer does not have a mask token which is necessary for masked language modeling. Remove the --mlm flag if you want to use this tokenizer."
|
||||
)
|
||||
|
||||
labels = inputs.clone()
|
||||
# We sample a few tokens in each sequence for masked-LM training (with probability args.mlm_probability defaults to 0.15 in Bert/RoBERTa)
|
||||
probability_matrix = torch.full(labels.shape, args.mlm_probability)
|
||||
@@ -705,10 +713,10 @@ def main():
|
||||
)
|
||||
|
||||
if args.block_size <= 0:
|
||||
args.block_size = tokenizer.max_len_single_sentence
|
||||
args.block_size = tokenizer.max_len
|
||||
# Our input block size will be the max possible for the model
|
||||
else:
|
||||
args.block_size = min(args.block_size, tokenizer.max_len_single_sentence)
|
||||
args.block_size = min(args.block_size, tokenizer.max_len)
|
||||
|
||||
if args.model_name_or_path:
|
||||
model = model_class.from_pretrained(
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: swedish
|
||||
---
|
||||
|
||||
# Swedish BERT Models
|
||||
|
||||
The National Library of Sweden / KBLab releases three pretrained language models based on BERT and ALBERT. The models are trained on aproximately 15-20GB of text (200M sentences, 3000M tokens) from various sources (books, news, government publications, swedish wikipedia and internet forums) aiming to provide a representative BERT model for Swedish text. A more complete description will be published later on.
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# UmBERTo Commoncrawl Cased
|
||||
|
||||
[UmBERTo](https://github.com/musixmatchresearch/umberto) is a Roberta-based Language Model trained on large Italian Corpora and uses two innovative approaches: SentencePiece and Whole Word Masking. Now available at [github.com/huggingface/transformers](https://huggingface.co/Musixmatch/umberto-commoncrawl-cased-v1)
|
||||
@@ -102,13 +106,13 @@ All of the original datasets are publicly available or were released with the ow
|
||||
|
||||
## Authors
|
||||
|
||||
**Loreto Parisi**: `loreto at musixmatch dot com`, [loretoparisi](https://github.com/loretoparisi)<br>
|
||||
**Simone Francia**: `simone.francia at musixmatch dot com`, [simonefrancia](https://github.com/simonefrancia)<br>
|
||||
**Paolo Magnani**: `paul.magnani95 at gmail dot com`, [paulthemagno](https://github.com/paulthemagno)<br>
|
||||
**Loreto Parisi**: `loreto at musixmatch dot com`, [loretoparisi](https://github.com/loretoparisi)
|
||||
**Simone Francia**: `simone.francia at musixmatch dot com`, [simonefrancia](https://github.com/simonefrancia)
|
||||
**Paolo Magnani**: `paul.magnani95 at gmail dot com`, [paulthemagno](https://github.com/paulthemagno)
|
||||
|
||||
## About Musixmatch AI
|
||||
<br>
|
||||
We do Machine Learning and Artificial Intelligence @[musixmatch](https://twitter.com/Musixmatch)<br>
|
||||

|
||||
We do Machine Learning and Artificial Intelligence @[musixmatch](https://twitter.com/Musixmatch)
|
||||
Follow us on [Twitter](https://twitter.com/musixmatchai) [Github](https://github.com/musixmatchresearch)
|
||||
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# UmBERTo Wikipedia Uncased
|
||||
|
||||
[UmBERTo](https://github.com/musixmatchresearch/umberto) is a Roberta-based Language Model trained on large Italian Corpora and uses two innovative approaches: SentencePiece and Whole Word Masking. Now available at [github.com/huggingface/transformers](https://huggingface.co/Musixmatch/umberto-commoncrawl-cased-v1)
|
||||
@@ -102,12 +106,12 @@ All of the original datasets are publicly available or were released with the ow
|
||||
|
||||
## Authors
|
||||
|
||||
**Loreto Parisi**: `loreto at musixmatch dot com`, [loretoparisi](https://github.com/loretoparisi)<br>
|
||||
**Simone Francia**: `simone.francia at musixmatch dot com`, [simonefrancia](https://github.com/simonefrancia)<br>
|
||||
**Paolo Magnani**: `paul.magnani95 at gmail dot com`, [paulthemagno](https://github.com/paulthemagno)<br>
|
||||
**Loreto Parisi**: `loreto at musixmatch dot com`, [loretoparisi](https://github.com/loretoparisi)
|
||||
**Simone Francia**: `simone.francia at musixmatch dot com`, [simonefrancia](https://github.com/simonefrancia)
|
||||
**Paolo Magnani**: `paul.magnani95 at gmail dot com`, [paulthemagno](https://github.com/paulthemagno)
|
||||
|
||||
## About Musixmatch AI
|
||||
<br>
|
||||
We do Machine Learning and Artificial Intelligence @[musixmatch](https://twitter.com/Musixmatch)<br>
|
||||

|
||||
We do Machine Learning and Artificial Intelligence @[musixmatch](https://twitter.com/Musixmatch)
|
||||
Follow us on [Twitter](https://twitter.com/musixmatchai) [Github](https://github.com/musixmatchresearch)
|
||||
|
||||
@@ -0,0 +1,90 @@
|
||||
## Albert xxlarge version 1 language model fine-tuned on SQuAD2.0
|
||||
|
||||
### with the following results:
|
||||
|
||||
```
|
||||
exact: 85.65653162637918
|
||||
f1: 89.260458954177
|
||||
total': 11873
|
||||
HasAns_exact': 82.6417004048583
|
||||
HasAns_f1': 89.8598902096736
|
||||
HasAns_total': 5928
|
||||
NoAns_exact': 88.66274179983179
|
||||
NoAns_f1': 88.66274179983179
|
||||
NoAns_total': 5945
|
||||
best_exact': 85.65653162637918
|
||||
best_exact_thresh': 0.0
|
||||
best_f1': 89.2604589541768
|
||||
best_f1_thresh': 0.0
|
||||
```
|
||||
|
||||
### from script:
|
||||
|
||||
```
|
||||
python -m torch.distributed.launch --nproc_per_node=2 ${RUN_SQUAD_DIR}/run_squad.py \
|
||||
--model_type albert \
|
||||
--model_name_or_path albert-xxlarge-v1 \
|
||||
--do_train \
|
||||
--train_file ${SQUAD_DIR}/train-v2.0.json \
|
||||
--predict_file ${SQUAD_DIR}/dev-v2.0.json \
|
||||
--version_2_with_negative \
|
||||
--num_train_epochs 3 \
|
||||
--max_steps 8144 \
|
||||
--warmup_steps 814 \
|
||||
--do_lower_case \
|
||||
--learning_rate 3e-5 \
|
||||
--max_seq_length 512 \
|
||||
--doc_stride 128 \
|
||||
--save_steps 2000 \
|
||||
--per_gpu_train_batch_size 1 \
|
||||
--gradient_accumulation_steps 24 \
|
||||
--output_dir ${MODEL_PATH}
|
||||
|
||||
CUDA_VISIBLE_DEVICES=0 python ${RUN_SQUAD_DIR}/run_squad.py \
|
||||
--model_type albert \
|
||||
--model_name_or_path ${MODEL_PATH} \
|
||||
--do_eval \
|
||||
--train_file ${SQUAD_DIR}/train-v2.0.json \
|
||||
--predict_file ${SQUAD_DIR}/dev-v2.0.json \
|
||||
--version_2_with_negative \
|
||||
--do_lower_case \
|
||||
--max_seq_length 512 \
|
||||
--per_gpu_eval_batch_size 48 \
|
||||
--output_dir ${MODEL_PATH}
|
||||
```
|
||||
|
||||
### using the following system & software:
|
||||
|
||||
```
|
||||
OS/Platform: Linux-4.15.0-76-generic-x86_64-with-debian-buster-sid
|
||||
GPU/CPU: 2 x NVIDIA 1080Ti / Intel i7-8700
|
||||
Transformers: 2.3.0
|
||||
PyTorch: 1.4.0
|
||||
TensorFlow: 2.1.0
|
||||
Python: 3.7.6
|
||||
```
|
||||
|
||||
### Inferencing / prediction works with the current Transformers v2.4.1
|
||||
|
||||
### Access this albert_xxlargev1_sqd2_512 fine-tuned model with "tried & true" code:
|
||||
|
||||
```python
|
||||
config_class, model_class, tokenizer_class = \
|
||||
AlbertConfig, AlbertForQuestionAnswering, AlbertTokenizer
|
||||
|
||||
model_name_or_path = "ahotrod/albert_xxlargev1_squad2_512"
|
||||
config = config_class.from_pretrained(model_name_or_path)
|
||||
tokenizer = tokenizer_class.from_pretrained(model_name_or_path, do_lower_case=True)
|
||||
model = model_class.from_pretrained(model_name_or_path, config=config)
|
||||
```
|
||||
|
||||
### or the AutoModels (AutoConfig, AutoTokenizer & AutoModel) should also work, however I have yet to use them in my app & confirm:
|
||||
|
||||
```python
|
||||
from transformers import AutoConfig, AutoTokenizer, AutoModel
|
||||
|
||||
model_name_or_path = "ahotrod/albert_xxlargev1_squad2_512"
|
||||
config = AutoConfig.from_pretrained(model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, do_lower_case=True)
|
||||
model = AutoModel.from_pretrained(model_name_or_path, config=config)
|
||||
```
|
||||
@@ -0,0 +1,71 @@
|
||||
---
|
||||
language: german
|
||||
thumbnail: https://thumb.tildacdn.com/tild3330-3735-4461-b133-656238643834/-/format/webp/deepset_performance.png
|
||||
---
|
||||
|
||||
# German BERT
|
||||
|
||||
## Overview
|
||||
**Language model:** bert-base-cased
|
||||
**Language:** German
|
||||
**Training data:** Wiki, OpenLegalData, News (~ 12GB)
|
||||
**Eval data:** Conll03 (NER), GermEval14 (NER), GermEval18 (Classification), GNAD (Classification)
|
||||
**Infrastructure**: 1x TPU v2
|
||||
**Published**: Jun 14th, 2019
|
||||
|
||||
## Details
|
||||
- We trained using Google's Tensorflow code on a single cloud TPU v2 with standard settings.
|
||||
- We trained 810k steps with a batch size of 1024 for sequence length 128 and 30k steps with sequence length 512. Training took about 9 days.
|
||||
- As training data we used the latest German Wikipedia dump (6GB of raw txt files), the OpenLegalData dump (2.4 GB) and news articles (3.6 GB).
|
||||
- We cleaned the data dumps with tailored scripts and segmented sentences with spacy v2.1. To create tensorflow records we used the recommended sentencepiece library for creating the word piece vocabulary and tensorflow scripts to convert the text to data usable by BERT.
|
||||
|
||||
See https://deepset.ai/german-bert for more details
|
||||
|
||||
## Hyperparameters
|
||||
|
||||
```
|
||||
batch_size = 1024
|
||||
n_steps = 810_000
|
||||
max_seq_len = 128 (and 512 later)
|
||||
learning_rate = 1e-4
|
||||
lr_schedule = LinearWarmup
|
||||
num_warmup_steps = 10_000
|
||||
```
|
||||
|
||||
## Performance
|
||||
|
||||
During training we monitored the loss and evaluated different model checkpoints on the following German datasets:
|
||||
|
||||
- germEval18Fine: Macro f1 score for multiclass sentiment classification
|
||||
- germEval18coarse: Macro f1 score for binary sentiment classification
|
||||
- germEval14: Seq f1 score for NER (file names deuutf.\*)
|
||||
- CONLL03: Seq f1 score for NER
|
||||
- 10kGNAD: Accuracy for document classification
|
||||
|
||||
Even without thorough hyperparameter tuning, we observed quite stable learning especially for our German model. Multiple restarts with different seeds produced quite similar results.
|
||||

|
||||
|
||||
While outperforming on 4 out of 5 task we wondered why the German BERT model did not outperform on CONLL03-de. So we compared English BERT with multilingual on CONLL03-en and found them to perform similar as well.
|
||||
|
||||
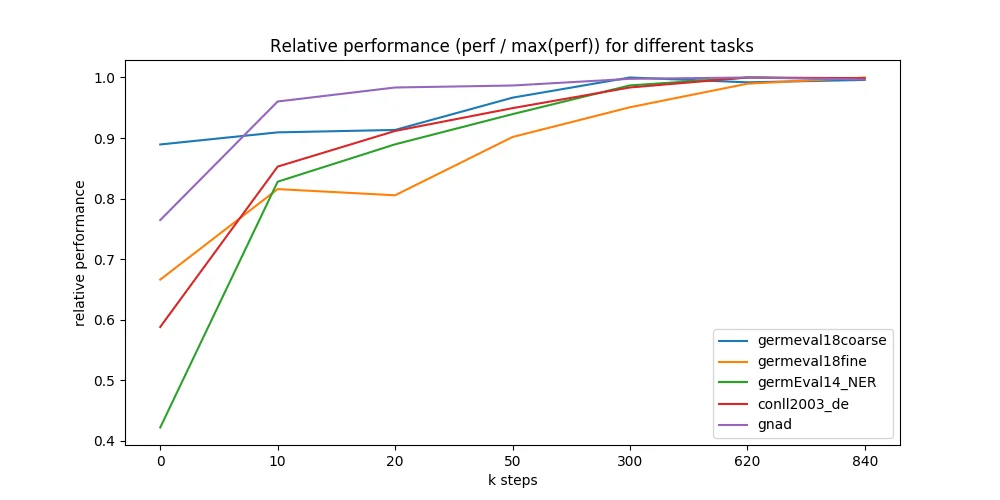
We further evaluated different points during the 9 days of pre-training and were astonished how fast the model converges to the maximally reachable performance. We ran all 5 downstream tasks on 7 different model checkpoints - taken at 0 up to 840k training steps (x-axis in figure below). Most checkpoints are taken from early training where we expected most performance changes. Surprisingly, even a randomly initialized BERT can be trained only on labeled downstream datasets and reach good performance (blue line, GermEval 2018 Coarse task, 795 kB trainset size).
|
||||
|
||||
|
||||
## Authors
|
||||
Branden Chan: `branden.chan [at] deepset.ai`
|
||||
Timo Möller: `timo.moeller [at] deepset.ai`
|
||||
Malte Pietsch: `malte.pietsch [at] deepset.ai`
|
||||
Tanay Soni: `tanay.soni [at] deepset.ai`
|
||||
|
||||
## About us
|
||||
|
||||
|
||||
We bring NLP to the industry via open source!
|
||||
Our focus: Industry specific language models & large scale QA systems.
|
||||
|
||||
Some of our work:
|
||||
- [German BERT (aka "bert-base-german-cased")](https://deepset.ai/german-bert)
|
||||
- [FARM](https://github.com/deepset-ai/FARM)
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
@@ -0,0 +1,20 @@
|
||||
---
|
||||
thumbnail: https://raw.githubusercontent.com/JetRunner/BERT-of-Theseus/master/bert-of-theseus.png
|
||||
---
|
||||
|
||||
# BERT-of-Theseus
|
||||
See our paper ["BERT-of-Theseus: Compressing BERT by Progressive Module Replacing"](http://arxiv.org/abs/2002.02925).
|
||||
|
||||
BERT-of-Theseus is a new compressed BERT by progressively replacing the components of the original BERT.
|
||||
|
||||
|
||||
|
||||
## Load Pretrained Model on MNLI
|
||||
|
||||
We provide a 6-layer pretrained model on MNLI as a general-purpose model, which can transfer to other sentence classification tasks, outperforming DistillBERT (with the same 6-layer structure) on six tasks of GLUE (dev set).
|
||||
|
||||
| Method | MNLI | MRPC | QNLI | QQP | RTE | SST-2 | STS-B |
|
||||
|-----------------|------|------|------|------|------|-------|-------|
|
||||
| BERT-base | 83.5 | 89.5 | 91.2 | 89.8 | 71.1 | 91.5 | 88.9 |
|
||||
| DistillBERT | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 |
|
||||
| BERT-of-Theseus | 82.1 | 87.5 | 88.8 | 88.8 | 70.1 | 91.8 | 87.8 |
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: german
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz German BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
language: german
|
||||
tags:
|
||||
- "historic german"
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources German Europeana BERT models 🎉
|
||||
|
||||
# German Europeana BERT
|
||||
|
||||
We use the open source [Europeana newspapers](http://www.europeana-newspapers.eu/)
|
||||
that were provided by *The European Library*. The final
|
||||
training corpus has a size of 51GB and consists of 8,035,986,369 tokens.
|
||||
|
||||
Detailed information about the data and pretraining steps can be found in
|
||||
[this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| ------------------------------------------ | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-german-europeana-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-cased/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on Historic NER, please refer to [this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our German Europeana BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-german-europeana-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-german-europeana-cased")
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
language: german
|
||||
tags:
|
||||
- "historic german"
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources German Europeana BERT models 🎉
|
||||
|
||||
# German Europeana BERT
|
||||
|
||||
We use the open source [Europeana newspapers](http://www.europeana-newspapers.eu/)
|
||||
that were provided by *The European Library*. The final
|
||||
training corpus has a size of 51GB and consists of 8,035,986,369 tokens.
|
||||
|
||||
Detailed information about the data and pretraining steps can be found in
|
||||
[this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| ------------------------------------------ | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-german-europeana-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-uncased/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on Historic NER, please refer to [this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our German Europeana BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-german-europeana-uncased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-german-europeana-uncased")
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: german
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz German BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
|
||||
@@ -0,0 +1,104 @@
|
||||
# roberta-base for QA
|
||||
|
||||
## Overview
|
||||
**Language model:** roberta-base
|
||||
**Language:** English
|
||||
**Downstream-task:** Extractive QA
|
||||
**Training data:** SQuAD 2.0
|
||||
**Eval data:** SQuAD 2.0
|
||||
**Code:** See [example](https://github.com/deepset-ai/FARM/blob/master/examples/question_answering.py) in [FARM](https://github.com/deepset-ai/FARM/blob/master/examples/question_answering.py)
|
||||
**Infrastructure**: 4x Tesla v100
|
||||
|
||||
## Hyperparameters
|
||||
|
||||
```
|
||||
batch_size = 50
|
||||
n_epochs = 3
|
||||
base_LM_model = "roberta-base"
|
||||
max_seq_len = 384
|
||||
learning_rate = 3e-5
|
||||
lr_schedule = LinearWarmup
|
||||
warmup_proportion = 0.2
|
||||
doc_stride=128
|
||||
max_query_length=64
|
||||
```
|
||||
|
||||
## Performance
|
||||
Evaluated on the SQuAD 2.0 dev set with the [official eval script](https://worksheets.codalab.org/rest/bundles/0x6b567e1cf2e041ec80d7098f031c5c9e/contents/blob/).
|
||||
```
|
||||
"exact": 78.49743114629833,
|
||||
"f1": 81.73092721240889
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### In Transformers
|
||||
```python
|
||||
from transformers.pipelines import pipeline
|
||||
from transformers.modeling_auto import AutoModelForQuestionAnswering
|
||||
from transformers.tokenization_auto import AutoTokenizer
|
||||
|
||||
model_name = "deepset/roberta-base-squad2"
|
||||
|
||||
# a) Get predictions
|
||||
nlp = pipeline('question-answering', model=model_name, tokenizer=model_name)
|
||||
QA_input = {
|
||||
'question': 'Why is model conversion important?',
|
||||
'context': 'The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks.'
|
||||
}
|
||||
res = nlp(QA_input)
|
||||
|
||||
# b) Load model & tokenizer
|
||||
model = AutoModelForQuestionAnswering.from_pretrained(model_name)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
### In FARM
|
||||
|
||||
```python
|
||||
from farm.modeling.adaptive_model import AdaptiveModel
|
||||
from farm.modeling.tokenization import Tokenizer
|
||||
from farm.infer import Inferencer
|
||||
|
||||
model_name = "deepset/roberta-base-squad2"
|
||||
|
||||
# a) Get predictions
|
||||
nlp = Inferencer.load(model_name, task_type="question_answering")
|
||||
QA_input = [{"questions": ["Why is model conversion important?"],
|
||||
"text": "The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks."}]
|
||||
res = nlp.inference_from_dicts(dicts=QA_input, rest_api_schema=True)
|
||||
|
||||
# b) Load model & tokenizer
|
||||
model = AdaptiveModel.convert_from_transformers(model_name, device="cpu", task_type="question_answering")
|
||||
tokenizer = Tokenizer.load(model_name)
|
||||
```
|
||||
|
||||
### In haystack
|
||||
For doing QA at scale (i.e. many docs instead of single paragraph), you can load the model also in [haystack](https://github.com/deepset-ai/haystack/):
|
||||
```python
|
||||
reader = FARMReader(model_name_or_path="deepset/roberta-base-squad2")
|
||||
# or
|
||||
reader = TransformersReader(model="deepset/roberta-base-squad2",tokenizer="deepset/roberta-base-squad2")
|
||||
```
|
||||
|
||||
|
||||
## Authors
|
||||
Branden Chan: `branden.chan [at] deepset.ai`
|
||||
Timo Möller: `timo.moeller [at] deepset.ai`
|
||||
Malte Pietsch: `malte.pietsch [at] deepset.ai`
|
||||
Tanay Soni: `tanay.soni [at] deepset.ai`
|
||||
|
||||
## About us
|
||||

|
||||
|
||||
We bring NLP to the industry via open source!
|
||||
Our focus: Industry specific language models & large scale QA systems.
|
||||
|
||||
Some of our work:
|
||||
- [German BERT (aka "bert-base-german-cased")](https://deepset.ai/german-bert)
|
||||
- [FARM](https://github.com/deepset-ai/FARM)
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
---
|
||||
language: dutch
|
||||
---
|
||||
|
||||
# Multilingual + Dutch SQuAD2.0
|
||||
|
||||
This model is the multilingual model provided by the Google research team with a fine-tuned dutch Q&A downstream task.
|
||||
|
||||
@@ -1,3 +1,10 @@
|
||||
---
|
||||
tags:
|
||||
- ci
|
||||
---
|
||||
|
||||
## Dummy model used for unit testing and CI
|
||||
|
||||
|
||||
```python
|
||||
import json
|
||||
|
||||
@@ -0,0 +1,7 @@
|
||||
# ArXiv-NLP GPT-2 checkpoint
|
||||
|
||||
This is a GPT-2 small checkpoint for PyTorch. It is the official `gpt2-small` fine-tuned to ArXiv paper on the computational linguistics field.
|
||||
|
||||
## Training data
|
||||
|
||||
This model was trained on a subset of ArXiv papers that were parsed from PDF to txt. The resulting data is made of 80MB of text from the computational linguistics (cs.CL) field.
|
||||
@@ -0,0 +1,7 @@
|
||||
# ArXiv GPT-2 checkpoint
|
||||
|
||||
This is a GPT-2 small checkpoint for PyTorch. It is the official `gpt2-small` finetuned to ArXiv paper on physics fields.
|
||||
|
||||
## Training data
|
||||
|
||||
This model was trained on a subset of ArXiv papers that were parsed from PDF to txt. The resulting data is made of 130MB of text, mostly from quantum physics (quant-ph) and other physics sub-fields.
|
||||
@@ -0,0 +1,91 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# BETO (Spanish BERT) + Spanish SQuAD2.0
|
||||
|
||||
This model is provided by [BETO team](https://github.com/dccuchile/beto) and fine-tuned on [SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve) for **Q&A** downstream task.
|
||||
|
||||
## Details of the language model('dccuchile/bert-base-spanish-wwm-cased')
|
||||
|
||||
Language model ([**'dccuchile/bert-base-spanish-wwm-cased'**](https://github.com/dccuchile/beto/blob/master/README.md)):
|
||||
|
||||
BETO is a [BERT model](https://github.com/google-research/bert) trained on a [big Spanish corpus](https://github.com/josecannete/spanish-corpora). BETO is of size similar to a BERT-Base and was trained with the Whole Word Masking technique. Below you find Tensorflow and Pytorch checkpoints for the uncased and cased versions, as well as some results for Spanish benchmarks comparing BETO with [Multilingual BERT](https://github.com/google-research/bert/blob/master/multilingual.md) as well as other (not BERT-based) models.
|
||||
|
||||
## Details of the downstream task (Q&A) - Dataset
|
||||
[SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve)
|
||||
|
||||
| Dataset | # Q&A |
|
||||
| ---------------------- | ----- |
|
||||
| SQuAD2.0 Train | 130 K |
|
||||
| SQuAD2.0-es-v2.0 | 111 K |
|
||||
| SQuAD2.0 Dev | 12 K |
|
||||
| SQuAD-es-v2.0-small Dev| 69 K |
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||
|
||||
```bash
|
||||
export SQUAD_DIR=path/to/nl_squad
|
||||
python transformers/examples/run_squad.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file $SQUAD_DIR/train_nl-v2.0.json \
|
||||
--predict_file $SQUAD_DIR/dev_nl-v2.0.json \
|
||||
--per_gpu_train_batch_size 12 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2.0 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
--threads 4 \
|
||||
--version_2_with_negative
|
||||
```
|
||||
|
||||
## Results:
|
||||
|
||||
|
||||
| Metric | # Value |
|
||||
| ---------------------- | ----- |
|
||||
| **Exact** | **76.50**50 |
|
||||
| **F1** | **86.07**81 |
|
||||
|
||||
```json
|
||||
{
|
||||
"exact": 76.50501430594491,
|
||||
"f1": 86.07818773108252,
|
||||
"total": 69202,
|
||||
"HasAns_exact": 67.93020719738277,
|
||||
"HasAns_f1": 82.37912207996466,
|
||||
"HasAns_total": 45850,
|
||||
"NoAns_exact": 93.34104145255225,
|
||||
"NoAns_f1": 93.34104145255225,
|
||||
"NoAns_total": 23352,
|
||||
"best_exact": 76.51223953064941,
|
||||
"best_exact_thresh": 0.0,
|
||||
"best_f1": 86.08541295578848,
|
||||
"best_f1_thresh": 0.0
|
||||
}
|
||||
```
|
||||
|
||||
### Model in action (in a Colab Notebook)
|
||||
<details>
|
||||
|
||||
1. Set the context and ask some questions:
|
||||
|
||||
|
||||
|
||||
2. Run predictions:
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -63,6 +63,7 @@ extras = {}
|
||||
extras["mecab"] = ["mecab-python3"]
|
||||
extras["sklearn"] = ["scikit-learn"]
|
||||
extras["tf"] = ["tensorflow"]
|
||||
extras["tf-cpu"] = ["tensorflow-cpu"]
|
||||
extras["torch"] = ["torch"]
|
||||
|
||||
extras["serving"] = ["pydantic", "uvicorn", "fastapi", "starlette"]
|
||||
|
||||
@@ -0,0 +1,48 @@
|
||||
import math
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
def _gelu_python(x):
|
||||
""" Original Implementation of the gelu activation function in Google Bert repo when initially created.
|
||||
For information: OpenAI GPT's gelu is slightly different (and gives slightly different results):
|
||||
0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
This is now written in C in torch.nn.functional
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return x * 0.5 * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
gelu = getattr(F, "gelu", _gelu_python)
|
||||
|
||||
|
||||
def gelu_new(x):
|
||||
""" Implementation of the gelu activation function currently in Google Bert repo (identical to OpenAI GPT).
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
ACT2FN = {
|
||||
"relu": F.relu,
|
||||
"swish": swish,
|
||||
"gelu": gelu,
|
||||
"tanh": F.tanh,
|
||||
"gelu_new": gelu_new,
|
||||
}
|
||||
|
||||
|
||||
def get_activation(activation_string):
|
||||
if activation_string in ACT2FN:
|
||||
return ACT2FN[activation_string]
|
||||
else:
|
||||
raise KeyError(
|
||||
"function {} not found in ACT2FN mapping {} or torch.nn.functional".format(
|
||||
activation_string, list(ACT2FN.keys())
|
||||
)
|
||||
)
|
||||
@@ -25,6 +25,8 @@ logger = logging.getLogger(__name__)
|
||||
DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-config.json",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-distilled-squad-config.json",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-config.json",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-distilled-squad-config.json",
|
||||
"distilbert-base-german-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-german-cased-config.json",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-multilingual-cased-config.json",
|
||||
"distilbert-base-uncased-finetuned-sst-2-english": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-finetuned-sst-2-english-config.json",
|
||||
@@ -58,7 +60,7 @@ class DistilBertConfig(PretrainedConfig):
|
||||
Number of attention heads for each attention layer in the Transformer encoder.
|
||||
dim (:obj:`int`, optional, defaults to 768):
|
||||
Dimensionality of the encoder layers and the pooler layer.
|
||||
intermediate_size (:obj:`int`, optional, defaults to 3072):
|
||||
hidden_dim (:obj:`int`, optional, defaults to 3072):
|
||||
The size of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
|
||||
dropout (:obj:`float`, optional, defaults to 0.1):
|
||||
The dropout probabilitiy for all fully connected layers in the embeddings, encoder, and pooler.
|
||||
|
||||
@@ -277,7 +277,7 @@ MODEL_CLASSES = {
|
||||
DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"distilbert-base-uncased-distilled-squad": (
|
||||
"distilbert-base-distilled-squad": (
|
||||
DistilBertConfig,
|
||||
TFDistilBertForQuestionAnswering,
|
||||
DistilBertForQuestionAnswering,
|
||||
|
||||
@@ -147,7 +147,14 @@ def squad_convert_example_to_features(example, max_seq_length, doc_stride, max_q
|
||||
)
|
||||
|
||||
if tokenizer.pad_token_id in encoded_dict["input_ids"]:
|
||||
non_padded_ids = encoded_dict["input_ids"][: encoded_dict["input_ids"].index(tokenizer.pad_token_id)]
|
||||
if tokenizer.padding_side == "right":
|
||||
non_padded_ids = encoded_dict["input_ids"][: encoded_dict["input_ids"].index(tokenizer.pad_token_id)]
|
||||
else:
|
||||
last_padding_id_position = (
|
||||
len(encoded_dict["input_ids"]) - 1 - encoded_dict["input_ids"][::-1].index(tokenizer.pad_token_id)
|
||||
)
|
||||
non_padded_ids = encoded_dict["input_ids"][last_padding_id_position + 1 :]
|
||||
|
||||
else:
|
||||
non_padded_ids = encoded_dict["input_ids"]
|
||||
|
||||
@@ -621,7 +628,7 @@ class SquadExample(object):
|
||||
self.doc_tokens = doc_tokens
|
||||
self.char_to_word_offset = char_to_word_offset
|
||||
|
||||
# Start end end positions only has a value during evaluation.
|
||||
# Start and end positions only has a value during evaluation.
|
||||
if start_position_character is not None and not is_impossible:
|
||||
self.start_position = char_to_word_offset[start_position_character]
|
||||
self.end_position = char_to_word_offset[
|
||||
|
||||
@@ -8,13 +8,16 @@ import fnmatch
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import shutil
|
||||
import sys
|
||||
import tarfile
|
||||
import tempfile
|
||||
from contextlib import contextmanager
|
||||
from functools import partial, wraps
|
||||
from hashlib import sha256
|
||||
from typing import Optional
|
||||
from urllib.parse import urlparse
|
||||
from zipfile import ZipFile, is_zipfile
|
||||
|
||||
import boto3
|
||||
import requests
|
||||
@@ -203,7 +206,14 @@ def filename_to_url(filename, cache_dir=None):
|
||||
|
||||
|
||||
def cached_path(
|
||||
url_or_filename, cache_dir=None, force_download=False, proxies=None, resume_download=False, user_agent=None
|
||||
url_or_filename,
|
||||
cache_dir=None,
|
||||
force_download=False,
|
||||
proxies=None,
|
||||
resume_download=False,
|
||||
user_agent=None,
|
||||
extract_compressed_file=False,
|
||||
force_extract=False,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given something that might be a URL (or might be a local path),
|
||||
@@ -215,6 +225,10 @@ def cached_path(
|
||||
force_download: if True, re-dowload the file even if it's already cached in the cache dir.
|
||||
resume_download: if True, resume the download if incompletly recieved file is found.
|
||||
user_agent: Optional string or dict that will be appended to the user-agent on remote requests.
|
||||
extract_compressed_file: if True and the path point to a zip or tar file, extract the compressed
|
||||
file in a folder along the archive.
|
||||
force_extract: if True when extract_compressed_file is True and the archive was already extracted,
|
||||
re-extract the archive and overide the folder where it was extracted.
|
||||
|
||||
Return:
|
||||
None in case of non-recoverable file (non-existent or inaccessible url + no cache on disk).
|
||||
@@ -229,7 +243,7 @@ def cached_path(
|
||||
|
||||
if is_remote_url(url_or_filename):
|
||||
# URL, so get it from the cache (downloading if necessary)
|
||||
return get_from_cache(
|
||||
output_path = get_from_cache(
|
||||
url_or_filename,
|
||||
cache_dir=cache_dir,
|
||||
force_download=force_download,
|
||||
@@ -239,7 +253,7 @@ def cached_path(
|
||||
)
|
||||
elif os.path.exists(url_or_filename):
|
||||
# File, and it exists.
|
||||
return url_or_filename
|
||||
output_path = url_or_filename
|
||||
elif urlparse(url_or_filename).scheme == "":
|
||||
# File, but it doesn't exist.
|
||||
raise EnvironmentError("file {} not found".format(url_or_filename))
|
||||
@@ -247,6 +261,39 @@ def cached_path(
|
||||
# Something unknown
|
||||
raise ValueError("unable to parse {} as a URL or as a local path".format(url_or_filename))
|
||||
|
||||
if extract_compressed_file:
|
||||
if not is_zipfile(output_path) and not tarfile.is_tarfile(output_path):
|
||||
return output_path
|
||||
|
||||
# Path where we extract compressed archives
|
||||
# We avoid '.' in dir name and add "-extracted" at the end: "./model.zip" => "./model-zip-extracted/"
|
||||
output_dir, output_file = os.path.split(output_path)
|
||||
output_extract_dir_name = output_file.replace(".", "-") + "-extracted"
|
||||
output_path_extracted = os.path.join(output_dir, output_extract_dir_name)
|
||||
|
||||
if os.path.isdir(output_path_extracted) and os.listdir(output_path_extracted) and not force_extract:
|
||||
return output_path_extracted
|
||||
|
||||
# Prevent parallel extractions
|
||||
lock_path = output_path + ".lock"
|
||||
with FileLock(lock_path):
|
||||
shutil.rmtree(output_path_extracted, ignore_errors=True)
|
||||
os.makedirs(output_path_extracted)
|
||||
if is_zipfile(output_path):
|
||||
with ZipFile(output_path, "r") as zip_file:
|
||||
zip_file.extractall(output_path_extracted)
|
||||
zip_file.close()
|
||||
elif tarfile.is_tarfile(output_path):
|
||||
tar_file = tarfile.open(output_path)
|
||||
tar_file.extractall(output_path_extracted)
|
||||
tar_file.close()
|
||||
else:
|
||||
raise EnvironmentError("Archive format of {} could not be identified".format(output_path))
|
||||
|
||||
return output_path_extracted
|
||||
|
||||
return output_path
|
||||
|
||||
|
||||
def split_s3_path(url):
|
||||
"""Split a full s3 path into the bucket name and path."""
|
||||
|
||||
@@ -117,7 +117,13 @@ def load_tf_weights_in_albert(model, config, tf_checkpoint_path):
|
||||
name = name.split("/")
|
||||
|
||||
# Ignore the gradients applied by the LAMB/ADAM optimizers.
|
||||
if "adam_m" in name or "adam_v" in name or "global_step" in name:
|
||||
if (
|
||||
"adam_m" in name
|
||||
or "adam_v" in name
|
||||
or "AdamWeightDecayOptimizer" in name
|
||||
or "AdamWeightDecayOptimizer_1" in name
|
||||
or "global_step" in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
continue
|
||||
|
||||
|
||||
@@ -24,6 +24,7 @@ import torch
|
||||
from torch import nn
|
||||
from torch.nn import CrossEntropyLoss, MSELoss
|
||||
|
||||
from .activations import gelu, gelu_new, swish
|
||||
from .configuration_bert import BertConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PreTrainedModel, prune_linear_layer
|
||||
@@ -86,7 +87,10 @@ def load_tf_weights_in_bert(model, config, tf_checkpoint_path):
|
||||
name = name.split("/")
|
||||
# adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
|
||||
# which are not required for using pretrained model
|
||||
if any(n in ["adam_v", "adam_m", "global_step"] for n in name):
|
||||
if any(
|
||||
n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
|
||||
for n in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
continue
|
||||
pointer = model
|
||||
@@ -126,26 +130,6 @@ def load_tf_weights_in_bert(model, config, tf_checkpoint_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
""" Original Implementation of the gelu activation function in Google Bert repo when initially created.
|
||||
For information: OpenAI GPT's gelu is slightly different (and gives slightly different results):
|
||||
0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return x * 0.5 * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
def gelu_new(x):
|
||||
""" Implementation of the gelu activation function currently in Google Bert repo (identical to OpenAI GPT).
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
def mish(x):
|
||||
return x * torch.tanh(nn.functional.softplus(x))
|
||||
|
||||
@@ -730,8 +714,8 @@ class BertModel(BertPreTrainedModel):
|
||||
seq_ids = torch.arange(seq_length, device=device)
|
||||
causal_mask = seq_ids[None, None, :].repeat(batch_size, seq_length, 1) <= seq_ids[None, :, None]
|
||||
causal_mask = causal_mask.to(
|
||||
torch.long
|
||||
) # not converting to long will cause errors with pytorch version < 1.3
|
||||
attention_mask.dtype
|
||||
) # causal and attention masks must have same type with pytorch version < 1.3
|
||||
extended_attention_mask = causal_mask[:, None, :, :] * attention_mask[:, None, None, :]
|
||||
else:
|
||||
extended_attention_mask = attention_mask[:, None, None, :]
|
||||
|
||||
@@ -27,6 +27,7 @@ import torch
|
||||
import torch.nn as nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
|
||||
from .activations import gelu
|
||||
from .configuration_distilbert import DistilBertConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PreTrainedModel, prune_linear_layer
|
||||
@@ -38,6 +39,8 @@ logger = logging.getLogger(__name__)
|
||||
DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-pytorch_model.bin",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-distilled-squad-pytorch_model.bin",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-pytorch_model.bin",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-distilled-squad-pytorch_model.bin",
|
||||
"distilbert-base-german-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-german-cased-pytorch_model.bin",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-multilingual-cased-pytorch_model.bin",
|
||||
"distilbert-base-uncased-finetuned-sst-2-english": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-finetuned-sst-2-english-pytorch_model.bin",
|
||||
@@ -45,8 +48,6 @@ DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
|
||||
|
||||
# UTILS AND BUILDING BLOCKS OF THE ARCHITECTURE #
|
||||
def gelu(x):
|
||||
return 0.5 * x * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
def create_sinusoidal_embeddings(n_pos, dim, out):
|
||||
@@ -440,8 +441,8 @@ class DistilBertModel(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertModel
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
@@ -544,8 +545,8 @@ class DistilBertForMaskedLM(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForMaskedLM
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForMaskedLM.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForMaskedLM.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
@@ -619,8 +620,8 @@ class DistilBertForSequenceClassification(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForSequenceClassification
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForSequenceClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForSequenceClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
labels = torch.tensor([1]).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, labels=labels)
|
||||
@@ -711,8 +712,8 @@ class DistilBertForQuestionAnswering(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForQuestionAnswering
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForQuestionAnswering.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForQuestionAnswering.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
start_positions = torch.tensor([1])
|
||||
end_positions = torch.tensor([3])
|
||||
@@ -798,8 +799,8 @@ class DistilBertForTokenClassification(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForTokenClassification
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForTokenClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForTokenClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0) # Batch size 1
|
||||
labels = torch.tensor([1] * input_ids.size(1)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, labels=labels)
|
||||
|
||||
@@ -231,7 +231,7 @@ class FlaubertModel(XLMModel):
|
||||
inputs_embeds = self.embeddings(input_ids)
|
||||
|
||||
tensor = inputs_embeds + self.position_embeddings(position_ids).expand_as(inputs_embeds)
|
||||
if langs is not None and self.use_lang_emb:
|
||||
if langs is not None and self.use_lang_emb and self.config.n_langs > 1:
|
||||
tensor = tensor + self.lang_embeddings(langs)
|
||||
if token_type_ids is not None:
|
||||
tensor = tensor + self.embeddings(token_type_ids)
|
||||
|
||||
@@ -24,6 +24,7 @@ import torch
|
||||
import torch.nn as nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
|
||||
from .activations import gelu_new
|
||||
from .configuration_gpt2 import GPT2Config
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import Conv1D, PreTrainedModel, SequenceSummary, prune_conv1d_layer
|
||||
@@ -95,10 +96,6 @@ def load_tf_weights_in_gpt2(model, config, gpt2_checkpoint_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
class Attention(nn.Module):
|
||||
def __init__(self, nx, n_ctx, config, scale=False):
|
||||
super().__init__()
|
||||
@@ -206,7 +203,7 @@ class MLP(nn.Module):
|
||||
nx = config.n_embd
|
||||
self.c_fc = Conv1D(n_state, nx)
|
||||
self.c_proj = Conv1D(nx, n_state)
|
||||
self.act = gelu
|
||||
self.act = gelu_new
|
||||
self.dropout = nn.Dropout(config.resid_pdrop)
|
||||
|
||||
def forward(self, x):
|
||||
|
||||
@@ -25,6 +25,7 @@ import torch
|
||||
import torch.nn as nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
|
||||
from .activations import gelu_new, swish
|
||||
from .configuration_openai import OpenAIGPTConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import Conv1D, PreTrainedModel, SequenceSummary, prune_conv1d_layer
|
||||
@@ -114,15 +115,7 @@ def load_tf_weights_in_openai_gpt(model, config, openai_checkpoint_folder_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
ACT_FNS = {"relu": nn.ReLU, "swish": swish, "gelu": gelu}
|
||||
ACT_FNS = {"relu": nn.ReLU, "swish": swish, "gelu": gelu_new}
|
||||
|
||||
|
||||
class Attention(nn.Module):
|
||||
|
||||
@@ -79,7 +79,10 @@ def load_tf_weights_in_t5(model, config, tf_checkpoint_path):
|
||||
name = txt_name.split("/")
|
||||
# adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
|
||||
# which are not required for using pretrained model
|
||||
if any(n in ["adam_v", "adam_m", "global_step"] for n in name):
|
||||
if any(
|
||||
n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
|
||||
for n in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
tf_weights.pop(txt_name, None)
|
||||
continue
|
||||
|
||||
@@ -33,6 +33,8 @@ logger = logging.getLogger(__name__)
|
||||
TF_DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-tf_model.h5",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-distilled-squad-tf_model.h5",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-tf_model.h5",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-distilled-squad-tf_model.h5",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-multilingual-cased-tf_model.h5",
|
||||
"distilbert-base-uncased-finetuned-sst-2-english": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-finetuned-sst-2-english-tf_model.h5",
|
||||
}
|
||||
@@ -78,8 +80,6 @@ class TFEmbeddings(tf.keras.layers.Layer):
|
||||
embeddings_initializer=get_initializer(config.initializer_range),
|
||||
name="position_embeddings",
|
||||
)
|
||||
if config.sinusoidal_pos_embds:
|
||||
raise NotImplementedError
|
||||
|
||||
self.LayerNorm = tf.keras.layers.LayerNormalization(epsilon=1e-12, name="LayerNorm")
|
||||
self.dropout = tf.keras.layers.Dropout(config.dropout)
|
||||
@@ -563,8 +563,8 @@ class TFDistilBertModel(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertModel
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertModel.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertModel.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
@@ -637,8 +637,8 @@ class TFDistilBertForMaskedLM(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForMaskedLM
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForMaskedLM.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForMaskedLM.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
prediction_scores = outputs[0]
|
||||
@@ -701,8 +701,8 @@ class TFDistilBertForSequenceClassification(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForSequenceClassification
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForSequenceClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForSequenceClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
logits = outputs[0]
|
||||
@@ -759,8 +759,8 @@ class TFDistilBertForTokenClassification(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForTokenClassification
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForTokenClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForTokenClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
scores = outputs[0]
|
||||
@@ -818,8 +818,8 @@ class TFDistilBertForQuestionAnswering(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForQuestionAnswering
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForQuestionAnswering.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForQuestionAnswering.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
start_scores, end_scores = outputs[:2]
|
||||
|
||||
@@ -198,7 +198,7 @@ class TFBlock(tf.keras.layers.Layer):
|
||||
|
||||
class TFGPT2MainLayer(tf.keras.layers.Layer):
|
||||
def __init__(self, config, *inputs, **kwargs):
|
||||
super().__init__(config, *inputs, **kwargs)
|
||||
super().__init__(*inputs, **kwargs)
|
||||
self.output_hidden_states = config.output_hidden_states
|
||||
self.output_attentions = config.output_attentions
|
||||
self.num_hidden_layers = config.n_layer
|
||||
|
||||
@@ -303,11 +303,9 @@ class TFPreTrainedModel(tf.keras.Model, TFModelUtilsMixin):
|
||||
elif os.path.isfile(pretrained_model_name_or_path + ".index"):
|
||||
archive_file = pretrained_model_name_or_path + ".index"
|
||||
else:
|
||||
archive_file = hf_bucket_url(pretrained_model_name_or_path, postfix=TF2_WEIGHTS_NAME)
|
||||
if from_pt:
|
||||
raise EnvironmentError(
|
||||
"Loading a TF model from a PyTorch checkpoint is not supported when using a model identifier name."
|
||||
)
|
||||
archive_file = hf_bucket_url(
|
||||
pretrained_model_name_or_path, postfix=(WEIGHTS_NAME if from_pt else TF2_WEIGHTS_NAME)
|
||||
)
|
||||
|
||||
# redirect to the cache, if necessary
|
||||
try:
|
||||
|
||||
@@ -90,9 +90,9 @@ class ProjectedAdaptiveLogSoftmax(nn.Module):
|
||||
labels :: [len*bsz]
|
||||
Return:
|
||||
if labels is None:
|
||||
out :: [len*bsz] Negative log likelihood
|
||||
else:
|
||||
out :: [len*bsz x n_tokens] log probabilities of tokens over the vocabulary
|
||||
else:
|
||||
out :: [len*bsz] Negative log likelihood
|
||||
We could replace this implementation by the native PyTorch one
|
||||
if their's had an option to set bias on all clusters in the native one.
|
||||
here: https://github.com/pytorch/pytorch/blob/dbe6a7a9ff1a364a8706bf5df58a1ca96d2fd9da/torch/nn/modules/adaptive.py#L138
|
||||
|
||||
@@ -18,12 +18,14 @@
|
||||
|
||||
import logging
|
||||
import os
|
||||
import typing
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
from torch.nn import functional as F
|
||||
|
||||
from .activations import get_activation
|
||||
from .configuration_utils import PretrainedConfig
|
||||
from .file_utils import (
|
||||
DUMMY_INPUTS,
|
||||
@@ -421,11 +423,9 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
)
|
||||
archive_file = pretrained_model_name_or_path + ".index"
|
||||
else:
|
||||
archive_file = hf_bucket_url(pretrained_model_name_or_path, postfix=WEIGHTS_NAME)
|
||||
if from_tf:
|
||||
raise EnvironmentError(
|
||||
"Loading a PyTorch model from a TF checkpoint is not supported when using a model identifier name."
|
||||
)
|
||||
archive_file = hf_bucket_url(
|
||||
pretrained_model_name_or_path, postfix=(TF2_WEIGHTS_NAME if from_tf else WEIGHTS_NAME)
|
||||
)
|
||||
|
||||
# redirect to the cache, if necessary
|
||||
try:
|
||||
@@ -1380,15 +1380,15 @@ class SequenceSummary(nn.Module):
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj: Add a projection after the vector extraction
|
||||
summary_proj_to_labels: If True, the projection outputs to config.num_labels classes (otherwise to hidden_size). Default: False.
|
||||
summary_activation: 'tanh' => add a tanh activation to the output, Other => no activation. Default
|
||||
summary_activation: 'tanh' or another string => add an activation to the output, Other => no activation. Default
|
||||
summary_first_dropout: Add a dropout before the projection and activation
|
||||
summary_last_dropout: Add a dropout after the projection and activation
|
||||
"""
|
||||
|
||||
def __init__(self, config):
|
||||
def __init__(self, config: PretrainedConfig):
|
||||
super().__init__()
|
||||
|
||||
self.summary_type = config.summary_type if hasattr(config, "summary_type") else "last"
|
||||
self.summary_type = getattr(config, "summary_type", "last")
|
||||
if self.summary_type == "attn":
|
||||
# We should use a standard multi-head attention module with absolute positional embedding for that.
|
||||
# Cf. https://github.com/zihangdai/xlnet/blob/master/modeling.py#L253-L276
|
||||
@@ -1403,9 +1403,10 @@ class SequenceSummary(nn.Module):
|
||||
num_classes = config.hidden_size
|
||||
self.summary = nn.Linear(config.hidden_size, num_classes)
|
||||
|
||||
self.activation = Identity()
|
||||
if hasattr(config, "summary_activation") and config.summary_activation == "tanh":
|
||||
self.activation = nn.Tanh()
|
||||
activation_string = getattr(config, "summary_activation", None)
|
||||
self.activation = (
|
||||
get_activation(activation_string) if activation_string else Identity()
|
||||
) # type: typing.Callable
|
||||
|
||||
self.first_dropout = Identity()
|
||||
if hasattr(config, "summary_first_dropout") and config.summary_first_dropout > 0:
|
||||
|
||||
@@ -26,6 +26,7 @@ from torch import nn
|
||||
from torch.nn import CrossEntropyLoss, MSELoss
|
||||
from torch.nn import functional as F
|
||||
|
||||
from .activations import gelu
|
||||
from .configuration_xlm import XLMConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PreTrainedModel, SequenceSummary, SQuADHead, prune_linear_layer
|
||||
@@ -55,17 +56,6 @@ def create_sinusoidal_embeddings(n_pos, dim, out):
|
||||
out.requires_grad = False
|
||||
|
||||
|
||||
def gelu(x):
|
||||
"""
|
||||
GELU activation
|
||||
https://arxiv.org/abs/1606.08415
|
||||
https://github.com/huggingface/pytorch-openai-transformer-lm/blob/master/model_pytorch.py#L14
|
||||
https://github.com/huggingface/transformers/blob/master/modeling.py
|
||||
"""
|
||||
# return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
return 0.5 * x * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
def get_masks(slen, lengths, causal, padding_mask=None):
|
||||
"""
|
||||
Generate hidden states mask, and optionally an attention mask.
|
||||
|
||||
@@ -18,13 +18,13 @@
|
||||
|
||||
|
||||
import logging
|
||||
import math
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import CrossEntropyLoss, MSELoss
|
||||
from torch.nn import functional as F
|
||||
|
||||
from .activations import gelu_new, swish
|
||||
from .configuration_xlnet import XLNetConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PoolerAnswerClass, PoolerEndLogits, PoolerStartLogits, PreTrainedModel, SequenceSummary
|
||||
@@ -183,20 +183,7 @@ def load_tf_weights_in_xlnet(model, config, tf_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
""" Implementation of the gelu activation function.
|
||||
XLNet is using OpenAI GPT's gelu (not exactly the same as BERT)
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
cdf = 0.5 * (1.0 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
return x * cdf
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
ACT2FN = {"gelu": gelu, "relu": torch.nn.functional.relu, "swish": swish}
|
||||
ACT2FN = {"gelu": gelu_new, "relu": torch.nn.functional.relu, "swish": swish}
|
||||
|
||||
|
||||
XLNetLayerNorm = nn.LayerNorm
|
||||
@@ -550,7 +537,7 @@ XLNET_INPUTS_DOCSTRING = r"""
|
||||
token_type_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Segment token indices to indicate first and second portions of the inputs.
|
||||
Indices are selected in ``[0, 1]``: ``0`` corresponds to a `sentence A` token, ``1``
|
||||
corresponds to a `sentence B` token
|
||||
corresponds to a `sentence B` token. The classifier token should be represented by a ``2``.
|
||||
|
||||
`What are token type IDs? <../glossary.html#token-type-ids>`_
|
||||
input_mask (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
|
||||
@@ -941,9 +941,9 @@ SUPPORTED_TASKS = {
|
||||
"tf": TFAutoModel if is_tf_available() else None,
|
||||
"pt": AutoModel if is_torch_available() else None,
|
||||
"default": {
|
||||
"model": {"pt": "distilbert-base-uncased", "tf": "distilbert-base-uncased"},
|
||||
"model": {"pt": "distilbert-base-cased", "tf": "distilbert-base-cased"},
|
||||
"config": None,
|
||||
"tokenizer": "distilbert-base-uncased",
|
||||
"tokenizer": "distilbert-base-cased",
|
||||
},
|
||||
},
|
||||
"sentiment-analysis": {
|
||||
@@ -977,12 +977,9 @@ SUPPORTED_TASKS = {
|
||||
"tf": TFAutoModelForQuestionAnswering if is_tf_available() else None,
|
||||
"pt": AutoModelForQuestionAnswering if is_torch_available() else None,
|
||||
"default": {
|
||||
"model": {
|
||||
"pt": "distilbert-base-uncased-distilled-squad",
|
||||
"tf": "distilbert-base-uncased-distilled-squad",
|
||||
},
|
||||
"model": {"pt": "distilbert-base-cased-distilled-squad", "tf": "distilbert-base-cased-distilled-squad"},
|
||||
"config": None,
|
||||
"tokenizer": "distilbert-base-uncased",
|
||||
"tokenizer": "distilbert-base-cased",
|
||||
},
|
||||
},
|
||||
"fill-mask": {
|
||||
@@ -1015,7 +1012,7 @@ def pipeline(
|
||||
|
||||
Examples:
|
||||
pipeline('sentiment-analysis')
|
||||
pipeline('question-answering', model='distilbert-base-uncased-distilled-squad', tokenizer='bert-base-cased')
|
||||
pipeline('question-answering', model='distilbert-base-cased-distilled-squad', tokenizer='bert-base-cased')
|
||||
pipeline('ner', model=AutoModel.from_pretrained(...), tokenizer=AutoTokenizer.from_pretrained(...)
|
||||
pipeline('ner', model='dbmdz/bert-large-cased-finetuned-conll03-english', tokenizer='bert-base-cased')
|
||||
pipeline('ner', model='https://...pytorch-model.bin', config='https://...config.json', tokenizer='bert-base-cased')
|
||||
|
||||
@@ -28,6 +28,8 @@ PRETRAINED_VOCAB_FILES_MAP = {
|
||||
"vocab_file": {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-uncased-vocab.txt",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/bert-large-uncased-vocab.txt",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-cased-vocab.txt",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/bert-large-cased-vocab.txt",
|
||||
"distilbert-base-german-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-german-cased-vocab.txt",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-multilingual-cased-vocab.txt",
|
||||
}
|
||||
@@ -36,6 +38,8 @@ PRETRAINED_VOCAB_FILES_MAP = {
|
||||
PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
"distilbert-base-uncased": 512,
|
||||
"distilbert-base-uncased-distilled-squad": 512,
|
||||
"distilbert-base-cased": 512,
|
||||
"distilbert-base-cased-distilled-squad": 512,
|
||||
"distilbert-base-german-cased": 512,
|
||||
"distilbert-base-multilingual-cased": 512,
|
||||
}
|
||||
@@ -44,6 +48,8 @@ PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES = {
|
||||
PRETRAINED_INIT_CONFIGURATION = {
|
||||
"distilbert-base-uncased": {"do_lower_case": True},
|
||||
"distilbert-base-uncased-distilled-squad": {"do_lower_case": True},
|
||||
"distilbert-base-cased": {"do_lower_case": False},
|
||||
"distilbert-base-cased-distilled-squad": {"do_lower_case": False},
|
||||
"distilbert-base-german-cased": {"do_lower_case": False},
|
||||
"distilbert-base-multilingual-cased": {"do_lower_case": False},
|
||||
}
|
||||
|
||||
@@ -159,6 +159,8 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
"""Save the tokenizer vocabulary to a directory or file."""
|
||||
if os.path.isdir(vocab_path):
|
||||
vocab_file = os.path.join(vocab_path, VOCAB_FILES_NAMES["pretrained_vocab_file"])
|
||||
else:
|
||||
vocab_file = vocab_path
|
||||
torch.save(self.__dict__, vocab_file)
|
||||
return (vocab_file,)
|
||||
|
||||
|
||||
@@ -76,7 +76,10 @@ def load_tf_weights_in_xxx(model, config, tf_checkpoint_path):
|
||||
name = name.split("/")
|
||||
# adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
|
||||
# which are not required for using pretrained model
|
||||
if any(n in ["adam_v", "adam_m", "global_step"] for n in name):
|
||||
if any(
|
||||
n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
|
||||
for n in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
continue
|
||||
pointer = model
|
||||
|
||||
@@ -0,0 +1,28 @@
|
||||
import unittest
|
||||
|
||||
from transformers import is_torch_available
|
||||
|
||||
from .utils import require_torch
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
from transformers.activations import _gelu_python, get_activation, gelu_new
|
||||
import torch
|
||||
|
||||
|
||||
@require_torch
|
||||
class TestActivations(unittest.TestCase):
|
||||
def test_gelu_versions(self):
|
||||
x = torch.Tensor([-100, -1, -0.1, 0, 0.1, 1.0, 100])
|
||||
torch_builtin = get_activation("gelu")
|
||||
self.assertTrue(torch.eq(_gelu_python(x), torch_builtin(x)).all().item())
|
||||
self.assertFalse(torch.eq(_gelu_python(x), gelu_new(x)).all().item())
|
||||
|
||||
def test_get_activation(self):
|
||||
get_activation("swish")
|
||||
get_activation("relu")
|
||||
get_activation("tanh")
|
||||
with self.assertRaises(KeyError):
|
||||
get_activation("bogus")
|
||||
with self.assertRaises(KeyError):
|
||||
get_activation(None)
|
||||
@@ -438,6 +438,34 @@ class BertModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs_for_decoder()
|
||||
self.model_tester.create_and_check_bert_model_as_decoder(*config_and_inputs)
|
||||
|
||||
def test_bert_model_as_decoder_with_default_input_mask(self):
|
||||
# This regression test was failing with PyTorch < 1.3
|
||||
(
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_mask,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
choice_labels,
|
||||
encoder_hidden_states,
|
||||
encoder_attention_mask,
|
||||
) = self.model_tester.prepare_config_and_inputs_for_decoder()
|
||||
|
||||
input_mask = None
|
||||
|
||||
self.model_tester.create_and_check_bert_model_as_decoder(
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_mask,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
choice_labels,
|
||||
encoder_hidden_states,
|
||||
encoder_attention_mask,
|
||||
)
|
||||
|
||||
def test_for_masked_lm(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_bert_for_masked_lm(*config_and_inputs)
|
||||
|
||||
@@ -0,0 +1,392 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
|
||||
import unittest
|
||||
|
||||
from transformers import is_torch_available
|
||||
|
||||
from .test_configuration_common import ConfigTester
|
||||
from .test_modeling_common import ModelTesterMixin, ids_tensor
|
||||
from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
from transformers import (
|
||||
FlaubertConfig,
|
||||
FlaubertModel,
|
||||
FlaubertWithLMHeadModel,
|
||||
FlaubertForQuestionAnswering,
|
||||
FlaubertForQuestionAnsweringSimple,
|
||||
FlaubertForSequenceClassification,
|
||||
)
|
||||
from transformers.modeling_flaubert import FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
|
||||
@require_torch
|
||||
class FlaubertModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
|
||||
all_model_classes = (
|
||||
(
|
||||
FlaubertModel,
|
||||
FlaubertWithLMHeadModel,
|
||||
FlaubertForQuestionAnswering,
|
||||
FlaubertForQuestionAnsweringSimple,
|
||||
FlaubertForSequenceClassification,
|
||||
)
|
||||
if is_torch_available()
|
||||
else ()
|
||||
)
|
||||
|
||||
class FlaubertModelTester(object):
|
||||
def __init__(
|
||||
self,
|
||||
parent,
|
||||
batch_size=13,
|
||||
seq_length=7,
|
||||
is_training=True,
|
||||
use_input_lengths=True,
|
||||
use_token_type_ids=True,
|
||||
use_labels=True,
|
||||
gelu_activation=True,
|
||||
sinusoidal_embeddings=False,
|
||||
causal=False,
|
||||
asm=False,
|
||||
n_langs=2,
|
||||
vocab_size=99,
|
||||
n_special=0,
|
||||
hidden_size=32,
|
||||
num_hidden_layers=5,
|
||||
num_attention_heads=4,
|
||||
hidden_dropout_prob=0.1,
|
||||
attention_probs_dropout_prob=0.1,
|
||||
max_position_embeddings=512,
|
||||
type_vocab_size=16,
|
||||
type_sequence_label_size=2,
|
||||
initializer_range=0.02,
|
||||
num_labels=3,
|
||||
num_choices=4,
|
||||
summary_type="last",
|
||||
use_proj=True,
|
||||
scope=None,
|
||||
):
|
||||
self.parent = parent
|
||||
self.batch_size = batch_size
|
||||
self.seq_length = seq_length
|
||||
self.is_training = is_training
|
||||
self.use_input_lengths = use_input_lengths
|
||||
self.use_token_type_ids = use_token_type_ids
|
||||
self.use_labels = use_labels
|
||||
self.gelu_activation = gelu_activation
|
||||
self.sinusoidal_embeddings = sinusoidal_embeddings
|
||||
self.asm = asm
|
||||
self.n_langs = n_langs
|
||||
self.vocab_size = vocab_size
|
||||
self.n_special = n_special
|
||||
self.summary_type = summary_type
|
||||
self.causal = causal
|
||||
self.use_proj = use_proj
|
||||
self.hidden_size = hidden_size
|
||||
self.num_hidden_layers = num_hidden_layers
|
||||
self.num_attention_heads = num_attention_heads
|
||||
self.hidden_dropout_prob = hidden_dropout_prob
|
||||
self.attention_probs_dropout_prob = attention_probs_dropout_prob
|
||||
self.max_position_embeddings = max_position_embeddings
|
||||
self.n_langs = n_langs
|
||||
self.type_sequence_label_size = type_sequence_label_size
|
||||
self.initializer_range = initializer_range
|
||||
self.summary_type = summary_type
|
||||
self.num_labels = num_labels
|
||||
self.num_choices = num_choices
|
||||
self.scope = scope
|
||||
|
||||
def prepare_config_and_inputs(self):
|
||||
input_ids = ids_tensor([self.batch_size, self.seq_length], self.vocab_size)
|
||||
input_mask = ids_tensor([self.batch_size, self.seq_length], 2).float()
|
||||
|
||||
input_lengths = None
|
||||
if self.use_input_lengths:
|
||||
input_lengths = (
|
||||
ids_tensor([self.batch_size], vocab_size=2) + self.seq_length - 2
|
||||
) # small variation of seq_length
|
||||
|
||||
token_type_ids = None
|
||||
if self.use_token_type_ids:
|
||||
token_type_ids = ids_tensor([self.batch_size, self.seq_length], self.n_langs)
|
||||
|
||||
sequence_labels = None
|
||||
token_labels = None
|
||||
is_impossible_labels = None
|
||||
if self.use_labels:
|
||||
sequence_labels = ids_tensor([self.batch_size], self.type_sequence_label_size)
|
||||
token_labels = ids_tensor([self.batch_size, self.seq_length], self.num_labels)
|
||||
is_impossible_labels = ids_tensor([self.batch_size], 2).float()
|
||||
|
||||
config = FlaubertConfig(
|
||||
vocab_size=self.vocab_size,
|
||||
n_special=self.n_special,
|
||||
emb_dim=self.hidden_size,
|
||||
n_layers=self.num_hidden_layers,
|
||||
n_heads=self.num_attention_heads,
|
||||
dropout=self.hidden_dropout_prob,
|
||||
attention_dropout=self.attention_probs_dropout_prob,
|
||||
gelu_activation=self.gelu_activation,
|
||||
sinusoidal_embeddings=self.sinusoidal_embeddings,
|
||||
asm=self.asm,
|
||||
causal=self.causal,
|
||||
n_langs=self.n_langs,
|
||||
max_position_embeddings=self.max_position_embeddings,
|
||||
initializer_range=self.initializer_range,
|
||||
summary_type=self.summary_type,
|
||||
use_proj=self.use_proj,
|
||||
)
|
||||
|
||||
return (
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
)
|
||||
|
||||
def check_loss_output(self, result):
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
|
||||
def create_and_check_flaubert_model(
|
||||
self,
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
):
|
||||
model = FlaubertModel(config=config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
outputs = model(input_ids, lengths=input_lengths, langs=token_type_ids)
|
||||
outputs = model(input_ids, langs=token_type_ids)
|
||||
outputs = model(input_ids)
|
||||
sequence_output = outputs[0]
|
||||
result = {
|
||||
"sequence_output": sequence_output,
|
||||
}
|
||||
self.parent.assertListEqual(
|
||||
list(result["sequence_output"].size()), [self.batch_size, self.seq_length, self.hidden_size]
|
||||
)
|
||||
|
||||
def create_and_check_flaubert_lm_head(
|
||||
self,
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
):
|
||||
model = FlaubertWithLMHeadModel(config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
|
||||
loss, logits = model(input_ids, token_type_ids=token_type_ids, labels=token_labels)
|
||||
|
||||
result = {
|
||||
"loss": loss,
|
||||
"logits": logits,
|
||||
}
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["logits"].size()), [self.batch_size, self.seq_length, self.vocab_size]
|
||||
)
|
||||
|
||||
def create_and_check_flaubert_simple_qa(
|
||||
self,
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
):
|
||||
model = FlaubertForQuestionAnsweringSimple(config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
|
||||
outputs = model(input_ids)
|
||||
|
||||
outputs = model(input_ids, start_positions=sequence_labels, end_positions=sequence_labels)
|
||||
loss, start_logits, end_logits = outputs
|
||||
|
||||
result = {
|
||||
"loss": loss,
|
||||
"start_logits": start_logits,
|
||||
"end_logits": end_logits,
|
||||
}
|
||||
self.parent.assertListEqual(list(result["start_logits"].size()), [self.batch_size, self.seq_length])
|
||||
self.parent.assertListEqual(list(result["end_logits"].size()), [self.batch_size, self.seq_length])
|
||||
self.check_loss_output(result)
|
||||
|
||||
def create_and_check_flaubert_qa(
|
||||
self,
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
):
|
||||
model = FlaubertForQuestionAnswering(config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
|
||||
outputs = model(input_ids)
|
||||
start_top_log_probs, start_top_index, end_top_log_probs, end_top_index, cls_logits = outputs
|
||||
|
||||
outputs = model(
|
||||
input_ids,
|
||||
start_positions=sequence_labels,
|
||||
end_positions=sequence_labels,
|
||||
cls_index=sequence_labels,
|
||||
is_impossible=is_impossible_labels,
|
||||
p_mask=input_mask,
|
||||
)
|
||||
|
||||
outputs = model(
|
||||
input_ids,
|
||||
start_positions=sequence_labels,
|
||||
end_positions=sequence_labels,
|
||||
cls_index=sequence_labels,
|
||||
is_impossible=is_impossible_labels,
|
||||
)
|
||||
|
||||
(total_loss,) = outputs
|
||||
|
||||
outputs = model(input_ids, start_positions=sequence_labels, end_positions=sequence_labels)
|
||||
|
||||
(total_loss,) = outputs
|
||||
|
||||
result = {
|
||||
"loss": total_loss,
|
||||
"start_top_log_probs": start_top_log_probs,
|
||||
"start_top_index": start_top_index,
|
||||
"end_top_log_probs": end_top_log_probs,
|
||||
"end_top_index": end_top_index,
|
||||
"cls_logits": cls_logits,
|
||||
}
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["start_top_log_probs"].size()), [self.batch_size, model.config.start_n_top]
|
||||
)
|
||||
self.parent.assertListEqual(
|
||||
list(result["start_top_index"].size()), [self.batch_size, model.config.start_n_top]
|
||||
)
|
||||
self.parent.assertListEqual(
|
||||
list(result["end_top_log_probs"].size()),
|
||||
[self.batch_size, model.config.start_n_top * model.config.end_n_top],
|
||||
)
|
||||
self.parent.assertListEqual(
|
||||
list(result["end_top_index"].size()),
|
||||
[self.batch_size, model.config.start_n_top * model.config.end_n_top],
|
||||
)
|
||||
self.parent.assertListEqual(list(result["cls_logits"].size()), [self.batch_size])
|
||||
|
||||
def create_and_check_flaubert_sequence_classif(
|
||||
self,
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
):
|
||||
model = FlaubertForSequenceClassification(config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
|
||||
(logits,) = model(input_ids)
|
||||
loss, logits = model(input_ids, labels=sequence_labels)
|
||||
|
||||
result = {
|
||||
"loss": loss,
|
||||
"logits": logits,
|
||||
}
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["logits"].size()), [self.batch_size, self.type_sequence_label_size]
|
||||
)
|
||||
|
||||
def prepare_config_and_inputs_for_common(self):
|
||||
config_and_inputs = self.prepare_config_and_inputs()
|
||||
(
|
||||
config,
|
||||
input_ids,
|
||||
token_type_ids,
|
||||
input_lengths,
|
||||
sequence_labels,
|
||||
token_labels,
|
||||
is_impossible_labels,
|
||||
input_mask,
|
||||
) = config_and_inputs
|
||||
inputs_dict = {"input_ids": input_ids, "token_type_ids": token_type_ids, "lengths": input_lengths}
|
||||
return config, inputs_dict
|
||||
|
||||
def setUp(self):
|
||||
self.model_tester = FlaubertModelTest.FlaubertModelTester(self)
|
||||
self.config_tester = ConfigTester(self, config_class=FlaubertConfig, emb_dim=37)
|
||||
|
||||
def test_config(self):
|
||||
self.config_tester.run_common_tests()
|
||||
|
||||
def test_flaubert_model(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_flaubert_model(*config_and_inputs)
|
||||
|
||||
def test_flaubert_lm_head(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_flaubert_lm_head(*config_and_inputs)
|
||||
|
||||
def test_flaubert_simple_qa(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_flaubert_simple_qa(*config_and_inputs)
|
||||
|
||||
def test_flaubert_qa(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_flaubert_qa(*config_and_inputs)
|
||||
|
||||
def test_flaubert_sequence_classif(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_flaubert_sequence_classif(*config_and_inputs)
|
||||
|
||||
@slow
|
||||
def test_model_from_pretrained(self):
|
||||
for model_name in list(FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = FlaubertModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
@@ -32,7 +32,7 @@ if is_torch_available():
|
||||
RobertaForSequenceClassification,
|
||||
RobertaForTokenClassification,
|
||||
)
|
||||
from transformers.modeling_roberta import RobertaEmbeddings
|
||||
from transformers.modeling_roberta import RobertaEmbeddings, RobertaForMultipleChoice, RobertaForQuestionAnswering
|
||||
from transformers.modeling_roberta import ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
|
||||
@@ -184,6 +184,51 @@ class RobertaModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
)
|
||||
self.check_loss_output(result)
|
||||
|
||||
def create_and_check_roberta_for_multiple_choice(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_choices = self.num_choices
|
||||
model = RobertaForMultipleChoice(config=config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
multiple_choice_inputs_ids = input_ids.unsqueeze(1).expand(-1, self.num_choices, -1).contiguous()
|
||||
multiple_choice_token_type_ids = token_type_ids.unsqueeze(1).expand(-1, self.num_choices, -1).contiguous()
|
||||
multiple_choice_input_mask = input_mask.unsqueeze(1).expand(-1, self.num_choices, -1).contiguous()
|
||||
loss, logits = model(
|
||||
multiple_choice_inputs_ids,
|
||||
attention_mask=multiple_choice_input_mask,
|
||||
token_type_ids=multiple_choice_token_type_ids,
|
||||
labels=choice_labels,
|
||||
)
|
||||
result = {
|
||||
"loss": loss,
|
||||
"logits": logits,
|
||||
}
|
||||
self.parent.assertListEqual(list(result["logits"].size()), [self.batch_size, self.num_choices])
|
||||
self.check_loss_output(result)
|
||||
|
||||
def create_and_check_roberta_for_question_answering(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
model = RobertaForQuestionAnswering(config=config)
|
||||
model.to(torch_device)
|
||||
model.eval()
|
||||
loss, start_logits, end_logits = model(
|
||||
input_ids,
|
||||
attention_mask=input_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
start_positions=sequence_labels,
|
||||
end_positions=sequence_labels,
|
||||
)
|
||||
result = {
|
||||
"loss": loss,
|
||||
"start_logits": start_logits,
|
||||
"end_logits": end_logits,
|
||||
}
|
||||
self.parent.assertListEqual(list(result["start_logits"].size()), [self.batch_size, self.seq_length])
|
||||
self.parent.assertListEqual(list(result["end_logits"].size()), [self.batch_size, self.seq_length])
|
||||
self.check_loss_output(result)
|
||||
|
||||
def prepare_config_and_inputs_for_common(self):
|
||||
config_and_inputs = self.prepare_config_and_inputs()
|
||||
(
|
||||
@@ -213,6 +258,18 @@ class RobertaModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_roberta_for_masked_lm(*config_and_inputs)
|
||||
|
||||
def test_for_token_classification(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_roberta_for_token_classification(*config_and_inputs)
|
||||
|
||||
def test_for_multiple_choice(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_roberta_for_multiple_choice(*config_and_inputs)
|
||||
|
||||
def test_for_question_answering(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_roberta_for_question_answering(*config_and_inputs)
|
||||
|
||||
@slow
|
||||
def test_model_from_pretrained(self):
|
||||
for model_name in list(ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
|
||||
@@ -200,6 +200,10 @@ class TFRobertaModelTest(TFModelTesterMixin, unittest.TestCase):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_roberta_for_masked_lm(*config_and_inputs)
|
||||
|
||||
def test_for_token_classification(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_roberta_for_token_classification(*config_and_inputs)
|
||||
|
||||
@slow
|
||||
def test_model_from_pretrained(self):
|
||||
for model_name in list(TF_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
|
||||
@@ -10,13 +10,13 @@ from .utils import require_tf, require_torch
|
||||
QA_FINETUNED_MODELS = {
|
||||
("bert-base-uncased", "bert-large-uncased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-cased", "bert-large-cased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-uncased", "distilbert-base-uncased-distilled-squad", None),
|
||||
("bert-base-cased", "distilbert-base-cased-distilled-squad", None),
|
||||
}
|
||||
|
||||
TF_QA_FINETUNED_MODELS = {
|
||||
("bert-base-uncased", "bert-large-uncased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-cased", "bert-large-cased-whole-word-masking-finetuned-squad", None),
|
||||
("bert-base-uncased", "distilbert-base-uncased-distilled-squad", None),
|
||||
("bert-base-cased", "distilbert-base-cased-distilled-squad", None),
|
||||
}
|
||||
|
||||
TF_NER_FINETUNED_MODELS = {
|
||||
@@ -38,13 +38,13 @@ NER_FINETUNED_MODELS = {
|
||||
FEATURE_EXTRACT_FINETUNED_MODELS = {
|
||||
("bert-base-cased", "bert-base-cased", None),
|
||||
# ('xlnet-base-cased', 'xlnet-base-cased', None), # Disabled for now as it crash for TF2
|
||||
("distilbert-base-uncased", "distilbert-base-uncased", None),
|
||||
("distilbert-base-cased", "distilbert-base-cased", None),
|
||||
}
|
||||
|
||||
TF_FEATURE_EXTRACT_FINETUNED_MODELS = {
|
||||
("bert-base-cased", "bert-base-cased", None),
|
||||
# ('xlnet-base-cased', 'xlnet-base-cased', None), # Disabled for now as it crash for TF2
|
||||
("distilbert-base-uncased", "distilbert-base-uncased", None),
|
||||
("distilbert-base-cased", "distilbert-base-cased", None),
|
||||
}
|
||||
|
||||
TF_TEXT_CLASSIF_FINETUNED_MODELS = {
|
||||
@@ -276,6 +276,7 @@ class MultiColumnInputTestCase(unittest.TestCase):
|
||||
self._test_multicolumn_pipeline(nlp, valid_samples, invalid_samples, mandatory_output_keys)
|
||||
|
||||
@require_tf
|
||||
@unittest.skip("This test is failing intermittently. Skipping it until we resolve.")
|
||||
def test_tf_question_answering(self):
|
||||
mandatory_output_keys = {"score", "answer", "start", "end"}
|
||||
valid_samples = [
|
||||
|
||||
Reference in new issue
Block a user