Compare commits
28
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Morgan Funtowicz |
f22083c575 | ||
|
Morgan Funtowicz
|
5b1b723e2f | ||
|
Morgan Funtowicz
|
2903c72076 | ||
|
Morgan Funtowicz
|
9fc55e44d1 | ||
|
Morgan Funtowicz
|
88f709a601 | ||
|
Morgan Funtowicz
|
0cc4c5453d | ||
|
Morgan Funtowicz
|
e0d888d3e8 | ||
|
Morgan Funtowicz
|
11269fb6de | ||
|
Morgan Funtowicz
|
39134cc9b4 | ||
|
Morgan Funtowicz
|
d6a2454995 | ||
|
Morgan Funtowicz
|
7421592037 | ||
|
Patrick von Platen
|
6a50d501ec | ||
|
Patrick von Platen
|
65d74c4965 | ||
|
Bram Vanroy
|
a143d9479e | ||
|
Manuel Romero
|
286d1ec746 | ||
|
Lysandre Debut
|
7984a70ee4 | ||
|
Lysandre Debut
|
21d8b6a33e | ||
|
Patrick von Platen
|
17c45c39ed | ||
|
Lysandre Debut
|
8194df8e0c | ||
|
Patrick von Platen
|
38f5fe9e02 | ||
|
Sam Shleifer
|
129f0604ac | ||
|
Lysandre Debut
|
0e84559d64 | ||
|
Sam Shleifer
|
92487a1dc0 | ||
|
Joe Davison
|
c36416e53c | ||
|
saippuakauppias
|
cafc4dfc7c | ||
|
Malte Pietsch
|
34b4b5a9ed | ||
|
Manuel Romero
|
7df12d7bf8 | ||
|
Joe Davison
|
197d74f988 |
No files matched your search
@@ -142,3 +142,6 @@ debug.env
|
||||
|
||||
# vim
|
||||
.*.swp
|
||||
|
||||
#ctags
|
||||
tags
|
||||
+3
-3
@@ -442,14 +442,14 @@ This example code fine-tunes XLNet on both SQuAD1.0 and SQuAD2.0 dataset. See ab
|
||||
```bash
|
||||
export SQUAD_DIR=/path/to/SQUAD
|
||||
|
||||
python /data/home/hlu/transformers/examples/run_squad.py \
|
||||
python run_squad.py \
|
||||
--model_type xlnet \
|
||||
--model_name_or_path xlnet-large-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file /data/home/hlu/notebooks/NLP/examples/question_answering/train-v1.1.json \
|
||||
--predict_file /data/home/hlu/notebooks/NLP/examples/question_answering/dev-v1.1.json \
|
||||
--train_file $SQUAD_DIR/train-v1.1.json \
|
||||
--predict_file $SQUAD_DIR/dev-v1.1.json \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
|
||||
@@ -59,7 +59,7 @@ MODEL_CLASSES = {
|
||||
# Padding text to help Transformer-XL and XLNet with short prompts as proposed by Aman Rusia
|
||||
# in https://github.com/rusiaaman/XLNet-gen#methodology
|
||||
# and https://medium.com/@amanrusia/xlnet-speaks-comparison-to-gpt-2-ea1a4e9ba39e
|
||||
PADDING_TEXT = """ In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
PADDING_TEXT = """In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
(except for Alexei and Maria) are discovered.
|
||||
The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
|
||||
remainder of the story. 1883 Western Siberia,
|
||||
@@ -214,7 +214,9 @@ def main():
|
||||
if requires_preprocessing:
|
||||
prepare_input = PREPROCESSING_FUNCTIONS.get(args.model_type)
|
||||
preprocessed_prompt_text = prepare_input(args, model, tokenizer, prompt_text)
|
||||
encoded_prompt = tokenizer.encode(preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt")
|
||||
encoded_prompt = tokenizer.encode(
|
||||
preprocessed_prompt_text, add_special_tokens=False, return_tensors="pt", add_space_before_punct_symbol=True
|
||||
)
|
||||
else:
|
||||
encoded_prompt = tokenizer.encode(prompt_text, add_special_tokens=False, return_tensors="pt")
|
||||
encoded_prompt = encoded_prompt.to(args.device)
|
||||
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
language: german
|
||||
thumbnail: https://thumb.tildacdn.com/tild3162-6462-4566-b663-376630376138/-/format/webp/Screenshot_from_2020.png
|
||||
thumbnail: https://static.tildacdn.com/tild6438-3730-4164-b266-613634323466/german_bert.png
|
||||
---
|
||||
|
||||
# German BERT
|
||||
|
||||
|
||||
## Overview
|
||||
**Language model:** bert-base-cased
|
||||
**Language:** German
|
||||
@@ -68,4 +68,4 @@ Some of our work:
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
@@ -0,0 +1,80 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# Spanish BERT (BETO) + POS
|
||||
|
||||
This model is a fine-tuned on [NER-C](https://www.kaggle.com/nltkdata/conll-corpora) Of the Spanish BERT cased [(BETO)](https://github.com/dccuchile/beto) for **POS** (Part of Speech tagging) downstream task.
|
||||
|
||||
## Details of the downstream task (POS) - Dataset
|
||||
|
||||
- [Dataset: CONLL Corpora ES](https://www.kaggle.com/nltkdata/conll-corpora) with data augmentation techniques
|
||||
|
||||
I preprocessed the dataset and splitted it as train / dev (80/20)
|
||||
|
||||
| Dataset | # Examples |
|
||||
| ---------------------- | ----- |
|
||||
| Train | 340 K |
|
||||
| Dev | 50 K |
|
||||
|
||||
|
||||
- [Fine-tune on NER script provided by Huggingface](https://github.com/huggingface/transformers/blob/master/examples/run_ner.py)
|
||||
|
||||
- Labels covered:
|
||||
|
||||
```
|
||||
AO, AQ, CC, CS, DA, DD, DE, DI, DN, DP, DT, Faa, Fat, Fc, Fd, Fe, Fg, Fh, Fia, Fit, Fp, Fpa, Fpt, Fs, Ft, Fx, Fz, I, NC, NP, P0, PD, PI, PN, PP, PR, PT, PX, RG, RN, SP, VAI, VAM, VAN, VAP, VAS, VMG, VMI, VMM, VMN, VMP, VMS, VSG, VSI, VSM, VSN, VSP, VSS, Y and Z
|
||||
```
|
||||
|
||||
|
||||
## Metrics on evaluation set:
|
||||
|
||||
| Metric | # score |
|
||||
| :------------------------------------------------------------------------------------: | :-------: |
|
||||
| F1 | **90.06**
|
||||
| Precision | **89.46** |
|
||||
| Recall | **90.67** |
|
||||
|
||||
## Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp_pos = pipeline(
|
||||
"ner",
|
||||
model="mrm8488/bert-spanish-cased-finetuned-pos",
|
||||
tokenizer=(
|
||||
'mrm8488/bert-spanish-cased-finetuned-pos',
|
||||
{"use_fast": False}
|
||||
))
|
||||
|
||||
|
||||
text = 'Mis amigos están pensando en viajar a Londres este verano'
|
||||
|
||||
nlp_pos(text)
|
||||
|
||||
#Output:
|
||||
'''
|
||||
[{'entity': 'NC', 'score': 0.7792173624038696, 'word': '[CLS]'},
|
||||
{'entity': 'DP', 'score': 0.9996283650398254, 'word': 'Mis'},
|
||||
{'entity': 'NC', 'score': 0.9999253749847412, 'word': 'amigos'},
|
||||
{'entity': 'VMI', 'score': 0.9998560547828674, 'word': 'están'},
|
||||
{'entity': 'VMG', 'score': 0.9992249011993408, 'word': 'pensando'},
|
||||
{'entity': 'SP', 'score': 0.9999602437019348, 'word': 'en'},
|
||||
{'entity': 'VMN', 'score': 0.9998666048049927, 'word': 'viajar'},
|
||||
{'entity': 'SP', 'score': 0.9999545216560364, 'word': 'a'},
|
||||
{'entity': 'VMN', 'score': 0.8722310662269592, 'word': 'Londres'},
|
||||
{'entity': 'DD', 'score': 0.9995203614234924, 'word': 'este'},
|
||||
{'entity': 'NC', 'score': 0.9999248385429382, 'word': 'verano'},
|
||||
{'entity': 'NC', 'score': 0.8802427649497986, 'word': '[SEP]'}]
|
||||
'''
|
||||
```
|
||||
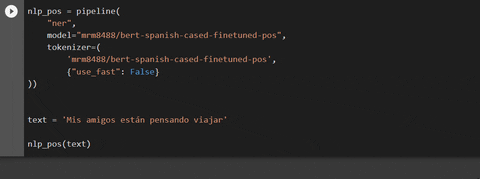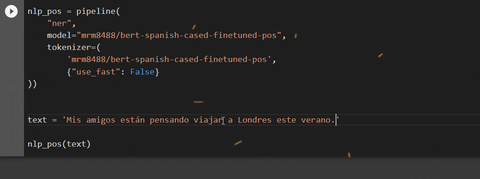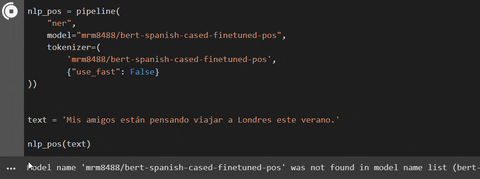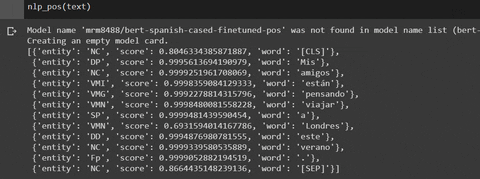
|
||||
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
+35
-6
@@ -89,7 +89,37 @@ The model was trained on a Tesla P100 GPU and 25GB of RAM with the following com
|
||||
|
||||
So, yes, this version is even more accurate.
|
||||
|
||||
### Model in action (in a Colab Notebook)
|
||||
### Model in action
|
||||
|
||||
Fast usage with **pipelines**:
|
||||
|
||||
```python
|
||||
from transformers import *
|
||||
|
||||
# Important!: By now the QA pipeline is not compatible with fast tokenizer, but they are working on it. So that pass the object to the tokenizer {"use_fast": False} as in the following example:
|
||||
|
||||
nlp = pipeline(
|
||||
'question-answering',
|
||||
model='mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es',
|
||||
tokenizer=(
|
||||
'mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es',
|
||||
{"use_fast": False}
|
||||
)
|
||||
)
|
||||
|
||||
nlp(
|
||||
{
|
||||
'question': '¿Para qué lenguaje está trabajando?',
|
||||
'context': 'Manuel Romero está colaborando activamente con huggingface/transformers ' +
|
||||
'para traer el poder de las últimas técnicas de procesamiento de lenguaje natural al idioma español'
|
||||
}
|
||||
)
|
||||
# Output: {'answer': 'español', 'end': 169, 'score': 0.67530957344621, 'start': 163}
|
||||
```
|
||||
|
||||
Play with this model and ```pipelines``` in a Colab:
|
||||
|
||||
<a href="https://colab.research.google.com/github/mrm8488/shared_colab_notebooks/blob/master/Using_Spanish_BERT_fine_tuned_for_Q%26A_pipelines.ipynb" target="_parent"><img src="https://camo.githubusercontent.com/52feade06f2fecbf006889a904d221e6a730c194/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open In Colab" data-canonical-src="https://colab.research.google.com/assets/colab-badge.svg"></a>
|
||||
|
||||
<details>
|
||||
|
||||
@@ -100,13 +130,12 @@ So, yes, this version is even more accurate.
|
||||
2. Run predictions:
|
||||
|
||||
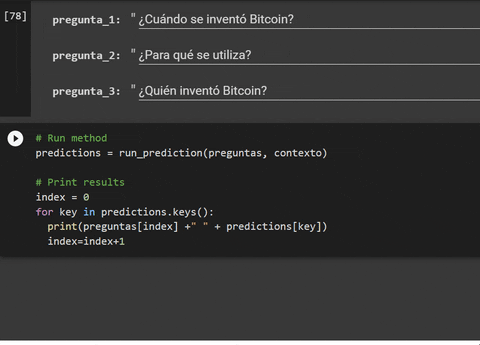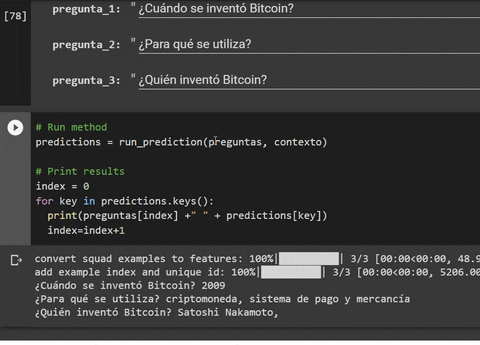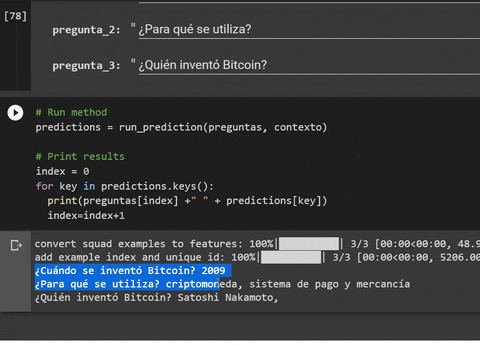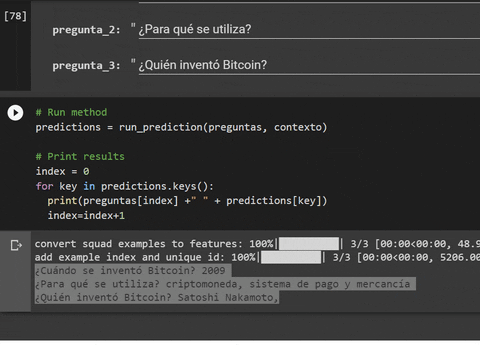
|
||||
|
||||
3. Using **Pipelines**
|
||||
|
||||
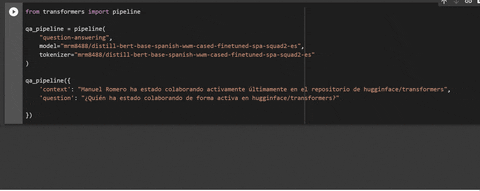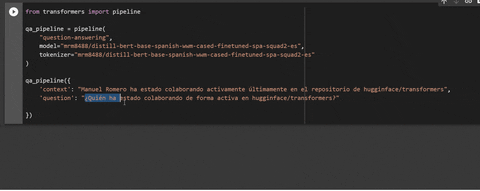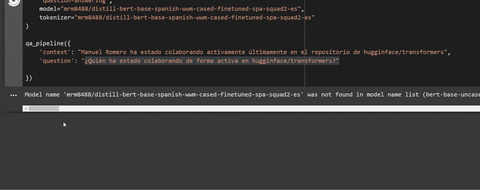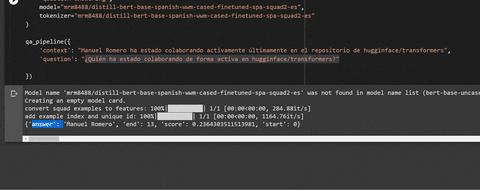
|
||||
|
||||
</details>
|
||||
|
||||
More about ``` Huggingface pipelines```? check this Colab out:
|
||||
|
||||
<a href="https://colab.research.google.com/github/mrm8488/shared_colab_notebooks/blob/master/Huggingface_pipelines_demo.ipynb" target="_parent"><img src="https://camo.githubusercontent.com/52feade06f2fecbf006889a904d221e6a730c194/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open In Colab" data-canonical-src="https://colab.research.google.com/assets/colab-badge.svg"></a>
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -92,7 +92,7 @@ setup(
|
||||
packages=find_packages("src"),
|
||||
install_requires=[
|
||||
"numpy",
|
||||
"tokenizers == 0.5.0",
|
||||
"tokenizers == 0.5.2",
|
||||
# accessing files from S3 directly
|
||||
"boto3",
|
||||
# filesystem locks e.g. to prevent parallel downloads
|
||||
|
||||
@@ -198,6 +198,7 @@ class PretrainedConfig(object):
|
||||
force_download = kwargs.pop("force_download", False)
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
if pretrained_config_archive_map is None:
|
||||
pretrained_config_archive_map = cls.pretrained_config_archive_map
|
||||
@@ -219,6 +220,7 @@ class PretrainedConfig(object):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
# Load config dict
|
||||
if resolved_config_file is None:
|
||||
|
||||
@@ -214,6 +214,7 @@ def cached_path(
|
||||
user_agent=None,
|
||||
extract_compressed_file=False,
|
||||
force_extract=False,
|
||||
local_files_only=False,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given something that might be a URL (or might be a local path),
|
||||
@@ -250,6 +251,7 @@ def cached_path(
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
user_agent=user_agent,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
elif os.path.exists(url_or_filename):
|
||||
# File, and it exists.
|
||||
@@ -378,7 +380,14 @@ def http_get(url, temp_file, proxies=None, resume_size=0, user_agent=None):
|
||||
|
||||
|
||||
def get_from_cache(
|
||||
url, cache_dir=None, force_download=False, proxies=None, etag_timeout=10, resume_download=False, user_agent=None
|
||||
url,
|
||||
cache_dir=None,
|
||||
force_download=False,
|
||||
proxies=None,
|
||||
etag_timeout=10,
|
||||
resume_download=False,
|
||||
user_agent=None,
|
||||
local_files_only=False,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given a URL, look for the corresponding file in the local cache.
|
||||
@@ -395,18 +404,19 @@ def get_from_cache(
|
||||
|
||||
os.makedirs(cache_dir, exist_ok=True)
|
||||
|
||||
# Get eTag to add to filename, if it exists.
|
||||
if url.startswith("s3://"):
|
||||
etag = s3_etag(url, proxies=proxies)
|
||||
else:
|
||||
try:
|
||||
response = requests.head(url, allow_redirects=True, proxies=proxies, timeout=etag_timeout)
|
||||
if response.status_code != 200:
|
||||
etag = None
|
||||
else:
|
||||
etag = response.headers.get("ETag")
|
||||
except (EnvironmentError, requests.exceptions.Timeout):
|
||||
etag = None
|
||||
etag = None
|
||||
if not local_files_only:
|
||||
# Get eTag to add to filename, if it exists.
|
||||
if url.startswith("s3://"):
|
||||
etag = s3_etag(url, proxies=proxies)
|
||||
else:
|
||||
try:
|
||||
response = requests.head(url, allow_redirects=True, proxies=proxies, timeout=etag_timeout)
|
||||
if response.status_code == 200:
|
||||
etag = response.headers.get("ETag")
|
||||
except (EnvironmentError, requests.exceptions.Timeout):
|
||||
# etag is already None
|
||||
pass
|
||||
|
||||
filename = url_to_filename(url, etag)
|
||||
|
||||
@@ -427,6 +437,15 @@ def get_from_cache(
|
||||
if len(matching_files) > 0:
|
||||
return os.path.join(cache_dir, matching_files[-1])
|
||||
else:
|
||||
# If files cannot be found and local_files_only=True,
|
||||
# the models might've been found if local_files_only=False
|
||||
# Notify the user about that
|
||||
if local_files_only:
|
||||
raise ValueError(
|
||||
"Cannot find the requested files in the cached path and outgoing traffic has been"
|
||||
" disabled. To enable model look-ups and downloads online, set 'local_files_only'"
|
||||
" to False."
|
||||
)
|
||||
return None
|
||||
|
||||
# From now on, etag is not None.
|
||||
|
||||
@@ -359,16 +359,12 @@ class AutoModel(object):
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
These arguments will be passed to the configuration and the model.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModel.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModel.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModel.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -503,24 +499,12 @@ class AutoModelForPreTraining(object):
|
||||
output_loading_info: (`optional`) boolean:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model.
|
||||
(e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or
|
||||
automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the
|
||||
underlying model's ``__init__`` method (we assume all relevant updates to the configuration have
|
||||
already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class
|
||||
initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of
|
||||
``kwargs`` that corresponds to a configuration attribute will be used to override said attribute
|
||||
with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration
|
||||
attribute will be passed to the underlying model's ``__init__`` function.
|
||||
These arguments will be passed to the configuration and the model.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForPreTraining.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForPreTraining.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForPreTraining.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -657,24 +641,12 @@ class AutoModelWithLMHead(object):
|
||||
output_loading_info: (`optional`) boolean:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model.
|
||||
(e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or
|
||||
automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the
|
||||
underlying model's ``__init__`` method (we assume all relevant updates to the configuration have
|
||||
already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class
|
||||
initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of
|
||||
``kwargs`` that corresponds to a configuration attribute will be used to override said attribute
|
||||
with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration
|
||||
attribute will be passed to the underlying model's ``__init__`` function.
|
||||
These arguments will be passed to the configuration and the model.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelWithLMHead.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelWithLMHead.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -814,16 +786,12 @@ class AutoModelForSequenceClassification(object):
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
These arguments will be passed to the configuration and the model.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForSequenceClassification.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForSequenceClassification.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForSequenceClassification.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -957,16 +925,12 @@ class AutoModelForQuestionAnswering(object):
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
These arguments will be passed to the configuration and the model.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
@@ -1101,16 +1065,12 @@ class AutoModelForTokenClassification:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model. (e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the underlying model's ``__init__`` method (we assume all relevant updates to the configuration have already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of ``kwargs`` that corresponds to a configuration attribute will be used to override said attribute with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration attribute will be passed to the underlying model's ``__init__`` function.
|
||||
These arguments will be passed to the configuration and the model.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForTokenClassification.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForTokenClassification.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForTokenClassification.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
|
||||
@@ -470,10 +470,6 @@ class BartDecoder(nn.Module):
|
||||
"""
|
||||
# embed positions
|
||||
positions = self.embed_positions(input_ids)
|
||||
|
||||
if decoder_cached_states is not None:
|
||||
input_ids = input_ids[:, -1:]
|
||||
positions = positions[:, -1:]
|
||||
x = self.embed_tokens(input_ids)
|
||||
|
||||
if positions is not None:
|
||||
@@ -491,7 +487,7 @@ class BartDecoder(nn.Module):
|
||||
decoder_layer # type: DecoderLayer
|
||||
# add LayerDrop (see https://arxiv.org/abs/1909.11556 for description)
|
||||
dropout_probability = random.uniform(0, 1)
|
||||
if self.training and (dropout_probability > self.layerdrop):
|
||||
if self.training and (dropout_probability < self.layerdrop):
|
||||
continue
|
||||
layer_state = decoder_cached_states[i] if decoder_cached_states is not None else None
|
||||
x, layer_self_attn, layer_past = decoder_layer.forward(
|
||||
@@ -940,7 +936,7 @@ class BartForMaskedLM(PretrainedBartModel):
|
||||
|
||||
@staticmethod
|
||||
def prepare_inputs_for_generation(input_ids, past, **kwargs):
|
||||
return {"input_ids": input_ids, "decoder_cached_states": past, "decoder_input_ids": input_ids}
|
||||
return {"input_ids": input_ids, "decoder_cached_states": past, "decoder_input_ids": input_ids[:, -1:]}
|
||||
|
||||
def get_output_embeddings(self):
|
||||
return self.lm_head
|
||||
|
||||
@@ -18,7 +18,6 @@
|
||||
import logging
|
||||
import os
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
from .modeling_auto import AutoModel, AutoModelWithLMHead
|
||||
@@ -294,21 +293,3 @@ class Model2Model(PreTrainedEncoderDecoder):
|
||||
)
|
||||
|
||||
return model
|
||||
|
||||
|
||||
class Model2LSTM(PreTrainedEncoderDecoder):
|
||||
@classmethod
|
||||
def from_pretrained(cls, *args, **kwargs):
|
||||
if kwargs.get("decoder_model", None) is None:
|
||||
# We will create a randomly initilized LSTM model as decoder
|
||||
if "decoder_config" not in kwargs:
|
||||
raise ValueError(
|
||||
"To load an LSTM in Encoder-Decoder model, please supply either: "
|
||||
" - a torch.nn.LSTM model as `decoder_model` parameter (`decoder_model=lstm_model`), or"
|
||||
" - a dictionary of configuration parameters that will be used to initialize a"
|
||||
" torch.nn.LSTM model as `decoder_config` keyword argument. "
|
||||
" E.g. `decoder_config={'input_size': 768, 'hidden_size': 768, 'num_layers': 2}`"
|
||||
)
|
||||
kwargs["decoder_model"] = torch.nn.LSTM(kwargs.pop("decoder_config"))
|
||||
model = super().from_pretrained(*args, **kwargs)
|
||||
return model
|
||||
@@ -376,6 +376,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
output_loading_info = kwargs.pop("output_loading_info", False)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
# Load config if we don't provide a configuration
|
||||
if not isinstance(config, PretrainedConfig):
|
||||
@@ -388,6 +389,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
force_download=force_download,
|
||||
resume_download=resume_download,
|
||||
proxies=proxies,
|
||||
local_files_only=local_files_only,
|
||||
**kwargs,
|
||||
)
|
||||
else:
|
||||
@@ -435,6 +437,7 @@ class PreTrainedModel(nn.Module, ModuleUtilsMixin):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
except EnvironmentError:
|
||||
if pretrained_model_name_or_path in cls.pretrained_model_archive_map:
|
||||
|
||||
@@ -512,7 +512,7 @@ class XLMModel(XLMPreTrainedModel):
|
||||
inputs_embeds = self.embeddings(input_ids)
|
||||
|
||||
tensor = inputs_embeds + self.position_embeddings(position_ids).expand_as(inputs_embeds)
|
||||
if langs is not None and self.use_lang_emb:
|
||||
if langs is not None and self.use_lang_emb and self.n_langs > 1:
|
||||
tensor = tensor + self.lang_embeddings(langs)
|
||||
if token_type_ids is not None:
|
||||
tensor = tensor + self.embeddings(token_type_ids)
|
||||
|
||||
@@ -702,8 +702,9 @@ class XLNetModel(XLNetPreTrainedModel):
|
||||
r"""
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLNetConfig`) and inputs:
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_predict, hidden_size)`):
|
||||
Sequence of hidden-states at the last layer of the model.
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
mems (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks).
|
||||
Can be used (see `mems` input) to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -728,7 +729,7 @@ class XLNetModel(XLNetPreTrainedModel):
|
||||
tokenizer = XLNetTokenizer.from_pretrained('xlnet-large-cased')
|
||||
model = XLNetModel.from_pretrained('xlnet-large-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=False)).unsqueeze(0) # Batch size 1
|
||||
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
@@ -977,19 +978,21 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
labels=None,
|
||||
):
|
||||
r"""
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for language modeling.
|
||||
Note that the labels **are shifted** inside the model, i.e. you can set ``lm_labels = input_ids``
|
||||
labels (:obj:`torch.LongTensor` of shape :obj:`(batch_size, num_predict)`, `optional`, defaults to :obj:`None`):
|
||||
Labels for masked language modeling.
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
The labels should correspond to the masked input words that should be predicted and depends on `target_mapping`. Note in order to perform standard auto-regressive language modeling a `<mask>` token has to be added to the `input_ids` (see `prepare_inputs_for_generation` fn and examples below)
|
||||
Indices are selected in ``[-100, 0, ..., config.vocab_size]``
|
||||
All labels set to ``-100`` are ignored (masked), the loss is only
|
||||
All labels set to ``-100`` are ignored, the loss is only
|
||||
computed for labels in ``[0, ..., config.vocab_size]``
|
||||
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLNetConfig`) and inputs:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when ``labels`` is provided)
|
||||
Language modeling loss.
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`):
|
||||
prediction_scores (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_predict, config.vocab_size)`):
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
`num_predict` corresponds to `target_mapping.shape[1]`. If `target_mapping` is `None`, then `num_predict` corresponds to `sequence_length`.
|
||||
mems (:obj:`List[torch.FloatTensor]` of length :obj:`config.n_layers`):
|
||||
Contains pre-computed hidden-states (key and values in the attention blocks).
|
||||
Can be used (see `past` input) to speed up sequential decoding. The token ids which have their past given to this model
|
||||
@@ -1015,7 +1018,7 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
model = XLNetLMHeadModel.from_pretrained('xlnet-large-cased')
|
||||
|
||||
# We show how to setup inputs to predict a next token using a bi-directional context.
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=True)).unsqueeze(0) # We will predict the masked token
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=False)).unsqueeze(0) # We will predict the masked token
|
||||
perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
|
||||
perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token
|
||||
target_mapping = torch.zeros((1, 1, input_ids.shape[1]), dtype=torch.float) # Shape [1, 1, seq_length] => let's predict one token
|
||||
@@ -1024,6 +1027,18 @@ class XLNetLMHeadModel(XLNetPreTrainedModel):
|
||||
outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping)
|
||||
next_token_logits = outputs[0] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
|
||||
|
||||
# The same way can the XLNetLMHeadModel be used to be trained by standard auto-regressive language modeling.
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is very <mask>", add_special_tokens=False)).unsqueeze(0) # We will predict the masked token
|
||||
labels = torch.tensor(tokenizer.encode("cute", add_special_tokens=False)).unsqueeze(0)
|
||||
assert labels.shape[0] == 1, 'only one word will be predicted'
|
||||
perm_mask = torch.zeros((1, input_ids.shape[1], input_ids.shape[1]), dtype=torch.float)
|
||||
perm_mask[:, :, -1] = 1.0 # Previous tokens don't see last token as is done in standard auto-regressive lm training
|
||||
target_mapping = torch.zeros((1, 1, input_ids.shape[1]), dtype=torch.float) # Shape [1, 1, seq_length] => let's predict one token
|
||||
target_mapping[0, 0, -1] = 1.0 # Our first (and only) prediction will be the last token of the sequence (the masked token)
|
||||
|
||||
outputs = model(input_ids, perm_mask=perm_mask, target_mapping=target_mapping, labels=labels)
|
||||
loss, next_token_logits = outputs[:2] # Output has shape [target_mapping.size(0), target_mapping.size(1), config.vocab_size]
|
||||
|
||||
"""
|
||||
transformer_outputs = self.transformer(
|
||||
input_ids,
|
||||
|
||||
@@ -114,6 +114,11 @@ class AlbertTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.sp_model)
|
||||
|
||||
def get_vocab(self):
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def __getstate__(self):
|
||||
state = self.__dict__.copy()
|
||||
state["sp_model"] = None
|
||||
|
||||
@@ -195,6 +195,9 @@ class BertTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.vocab)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.vocab, **self.added_tokens_encoder)
|
||||
|
||||
def _tokenize(self, text):
|
||||
split_tokens = []
|
||||
if self.do_basic_tokenize:
|
||||
|
||||
@@ -147,6 +147,9 @@ class CTRLTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
if token in self.cache:
|
||||
return self.cache[token]
|
||||
|
||||
@@ -149,6 +149,9 @@ class GPT2Tokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
if token in self.cache:
|
||||
return self.cache[token]
|
||||
|
||||
@@ -125,6 +125,9 @@ class OpenAIGPTTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
word = tuple(token[:-1]) + (token[-1] + "</w>",)
|
||||
if token in self.cache:
|
||||
|
||||
@@ -98,6 +98,12 @@ class T5Tokenizer(PreTrainedTokenizer):
|
||||
additional_special_tokens=additional_special_tokens,
|
||||
**kwargs,
|
||||
)
|
||||
self.max_len_single_sentence = (
|
||||
self.max_len
|
||||
) # no default special tokens - you can update this value if you add special tokens
|
||||
self.max_len_sentences_pair = (
|
||||
self.max_len
|
||||
) # no default special tokens - you can update this value if you add special tokens
|
||||
|
||||
try:
|
||||
import sentencepiece as spm
|
||||
@@ -119,6 +125,11 @@ class T5Tokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return self.sp_model.get_piece_size() + self._extra_ids
|
||||
|
||||
def get_vocab(self):
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def __getstate__(self):
|
||||
state = self.__dict__.copy()
|
||||
state["sp_model"] = None
|
||||
|
||||
@@ -22,6 +22,7 @@ import glob
|
||||
import logging
|
||||
import os
|
||||
import pickle
|
||||
import re
|
||||
from collections import Counter, OrderedDict
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
@@ -44,6 +45,7 @@ if is_torch_available():
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
VOCAB_FILES_NAMES = {"pretrained_vocab_file": "vocab.bin", "vocab_file": "vocab.txt"}
|
||||
VOCAB_FILES_NAMES_FAST = {"pretrained_vocab_file": "vocab.json", "vocab_file": "vocab.json"}
|
||||
|
||||
PRETRAINED_VOCAB_FILES_MAP = {
|
||||
"pretrained_vocab_file": {
|
||||
@@ -114,18 +116,36 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
self.delimiter = delimiter
|
||||
self.vocab_file = vocab_file
|
||||
self.never_split = never_split
|
||||
self.punctuation_symbols = '!"#$%&()*+,-./\:;<=>?@[\\]^_`{|}~' # noqa: W605
|
||||
self.punction_without_space_before_pattern = re.compile(r"[^\s][{}]".format(self.punctuation_symbols))
|
||||
self.punctuation_with_space_around_pattern = self._compile_space_around_punctuation_pattern()
|
||||
|
||||
if pretrained_vocab_file is not None:
|
||||
# Hack because, honestly this tokenizer was not made to be used
|
||||
# in a library like ours, at all.
|
||||
vocab_dict = torch.load(pretrained_vocab_file)
|
||||
for key, value in vocab_dict.items():
|
||||
if key not in self.__dict__:
|
||||
self.__dict__[key] = value
|
||||
try:
|
||||
if pretrained_vocab_file is not None:
|
||||
# Hack because, honestly this tokenizer was not made to be used
|
||||
# in a library like ours, at all.
|
||||
vocab_dict = torch.load(pretrained_vocab_file)
|
||||
for key, value in vocab_dict.items():
|
||||
if key not in self.__dict__:
|
||||
self.__dict__[key] = value
|
||||
|
||||
if vocab_file is not None:
|
||||
self.build_vocab()
|
||||
except Exception:
|
||||
raise ValueError(
|
||||
"Unable to parse file {}. Unknown format. "
|
||||
"If you tried to load a model saved through TransfoXLTokenizerFast,"
|
||||
"please note they are not compatible.".format(pretrained_vocab_file)
|
||||
)
|
||||
|
||||
if vocab_file is not None:
|
||||
self.build_vocab()
|
||||
|
||||
def _compile_space_around_punctuation_pattern(self):
|
||||
look_ahead_for_special_token = "(?=[{}])".format(self.punctuation_symbols)
|
||||
look_ahead_to_match_all_except_space = "(?=[^\s])" # noqa: W605
|
||||
return re.compile(r"" + look_ahead_for_special_token + look_ahead_to_match_all_except_space)
|
||||
|
||||
def count_file(self, path, verbose=False, add_eos=False):
|
||||
if verbose:
|
||||
logger.info("counting file {} ...".format(path))
|
||||
@@ -170,6 +190,12 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
|
||||
def save_vocabulary(self, vocab_path):
|
||||
"""Save the tokenizer vocabulary to a directory or file."""
|
||||
|
||||
logger.warning(
|
||||
"Please note you will not be able to load the save vocabulary in"
|
||||
" Rust-based TransfoXLTokenizerFast as they don't share the same structure."
|
||||
)
|
||||
|
||||
if os.path.isdir(vocab_path):
|
||||
vocab_file = os.path.join(vocab_path, VOCAB_FILES_NAMES["pretrained_vocab_file"])
|
||||
else:
|
||||
@@ -273,6 +299,9 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.idx2sym)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.sym2idx, **self.added_tokens_encoder)
|
||||
|
||||
def _tokenize(self, line, add_eos=False, add_double_eos=False):
|
||||
line = line.strip()
|
||||
# convert to lower case
|
||||
@@ -292,6 +321,19 @@ class TransfoXLTokenizer(PreTrainedTokenizer):
|
||||
else:
|
||||
return symbols
|
||||
|
||||
def prepare_for_tokenization(self, text, **kwargs):
|
||||
# add spaces before punctuation symbols as should be done in transfo-xl
|
||||
|
||||
if "add_space_before_punct_symbol" in kwargs and kwargs["add_space_before_punct_symbol"]:
|
||||
text = self.punctuation_with_space_around_pattern.sub(r" ", text)
|
||||
elif self.punction_without_space_before_pattern.search(text):
|
||||
# searches until the first occurence of a punctuation symbol without surrounding spaces
|
||||
logger.warning(
|
||||
"You might want to consider setting `add_space_before_punct_symbol=True` as an argument to the `tokenizer.encode()` to avoid tokenizing words with punctuation symbols to the `<unk>` token"
|
||||
)
|
||||
|
||||
return text
|
||||
|
||||
|
||||
class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
def __init__(
|
||||
@@ -306,8 +348,15 @@ class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
normalization: Optional[str] = None,
|
||||
):
|
||||
|
||||
tokenizer = WordLevel.from_files(vocab_file, unk_token=unk_token)
|
||||
tokenizer = Tokenizer(tokenizer)
|
||||
try:
|
||||
tokenizer = WordLevel.from_files(vocab_file, unk_token=unk_token)
|
||||
tokenizer = Tokenizer(tokenizer)
|
||||
except Exception:
|
||||
raise ValueError(
|
||||
"Unable to parse file {}. Unknown format. "
|
||||
"If you tried to load a model saved through TransfoXLTokenizer,"
|
||||
"please note they are not compatible.".format(vocab_file)
|
||||
)
|
||||
|
||||
# Create the correct normalization path
|
||||
normalizer = []
|
||||
@@ -354,7 +403,7 @@ class _TransfoXLDelimiterLookupTokenizer(BaseTokenizer):
|
||||
|
||||
class TransfoXLTokenizerFast(PreTrainedTokenizerFast):
|
||||
|
||||
vocab_files_names = VOCAB_FILES_NAMES
|
||||
vocab_files_names = VOCAB_FILES_NAMES_FAST
|
||||
pretrained_vocab_files_map = PRETRAINED_VOCAB_FILES_MAP_FAST
|
||||
max_model_input_sizes = PRETRAINED_POSITIONAL_EMBEDDINGS_SIZES
|
||||
|
||||
@@ -394,6 +443,14 @@ class TransfoXLTokenizerFast(PreTrainedTokenizerFast):
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
def save_pretrained(self, save_directory):
|
||||
logger.warning(
|
||||
"Please note you will not be able to load the vocabulary in"
|
||||
" Python-based TransfoXLTokenizer as they don't share the same structure."
|
||||
)
|
||||
|
||||
return super().save_pretrained(save_directory)
|
||||
|
||||
|
||||
class LMOrderedIterator(object):
|
||||
def __init__(self, data, bsz, bptt, device="cpu", ext_len=None):
|
||||
|
||||
@@ -14,7 +14,6 @@
|
||||
# limitations under the License.
|
||||
"""Tokenization classes for OpenAI GPT."""
|
||||
|
||||
|
||||
import copy
|
||||
import itertools
|
||||
import json
|
||||
@@ -153,6 +152,18 @@ class PreTrainedTokenizer(object):
|
||||
|
||||
padding_side = "right"
|
||||
|
||||
NO_PAD_TOKEN_FOR_BATCH_MSG = (
|
||||
"No padding token is set for this model, therefore no batch can be made with uneven "
|
||||
"sequences. Set a padding token or adjust the lengths of the sequences building the "
|
||||
"batch so that every sequence is of the same length."
|
||||
)
|
||||
|
||||
UNEVEN_SEQUENCES_FOR_BATCH_MSG = (
|
||||
"The sequences building the batch are not of the same size, no tensor "
|
||||
"can be built. Set `pad_to_max_length=True` to pad the smaller sequences"
|
||||
"up to the larger sequence's length."
|
||||
)
|
||||
|
||||
@property
|
||||
def bos_token(self):
|
||||
""" Beginning of sentence token (string). Log an error if used while not having been set. """
|
||||
@@ -286,6 +297,10 @@ class PreTrainedTokenizer(object):
|
||||
""" Ids of all the additional special tokens in the vocabulary (list of integers). Log an error if used while not having been set. """
|
||||
return self.convert_tokens_to_ids(self.additional_special_tokens)
|
||||
|
||||
def get_vocab(self):
|
||||
""" Returns the vocabulary as a dict of {token: index} pairs. `tokenizer.get_vocab()[token]` is equivalent to `tokenizer.convert_tokens_to_ids(token)` when `token` is in the vocab. """
|
||||
raise NotImplementedError()
|
||||
|
||||
def __init__(self, max_len=None, **kwargs):
|
||||
self._bos_token = None
|
||||
self._eos_token = None
|
||||
@@ -380,6 +395,7 @@ class PreTrainedTokenizer(object):
|
||||
force_download = kwargs.pop("force_download", False)
|
||||
resume_download = kwargs.pop("resume_download", False)
|
||||
proxies = kwargs.pop("proxies", None)
|
||||
local_files_only = kwargs.pop("local_files_only", False)
|
||||
|
||||
s3_models = list(cls.max_model_input_sizes.keys())
|
||||
vocab_files = {}
|
||||
@@ -447,6 +463,7 @@ class PreTrainedTokenizer(object):
|
||||
force_download=force_download,
|
||||
proxies=proxies,
|
||||
resume_download=resume_download,
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
except EnvironmentError:
|
||||
if pretrained_model_name_or_path in s3_models:
|
||||
@@ -1016,14 +1033,18 @@ class PreTrainedTokenizer(object):
|
||||
def batch_encode_plus(
|
||||
self,
|
||||
batch_text_or_text_pairs=None,
|
||||
add_special_tokens=False,
|
||||
add_special_tokens=True,
|
||||
max_length=None,
|
||||
stride=0,
|
||||
truncation_strategy="longest_first",
|
||||
pad_to_max_length=False,
|
||||
return_tensors=None,
|
||||
return_input_lengths=False,
|
||||
return_attention_masks=False,
|
||||
return_token_type_ids=True,
|
||||
return_attention_masks=True,
|
||||
return_overflowing_tokens=False,
|
||||
return_special_tokens_masks=False,
|
||||
return_offsets_mapping=False,
|
||||
return_input_lengths=False,
|
||||
**kwargs
|
||||
):
|
||||
"""
|
||||
@@ -1046,14 +1067,54 @@ class PreTrainedTokenizer(object):
|
||||
- 'only_first': Only truncate the first sequence
|
||||
- 'only_second': Only truncate the second sequence
|
||||
- 'do_not_truncate': Does not truncate (raise an error if the input sequence is longer than max_length)
|
||||
pad_to_max_length: if set to True, the returned sequences will be padded according to the model's padding side and
|
||||
padding index, up to their max length. If no max length is specified, the padding is done up to the model's max length.
|
||||
The tokenizer padding sides are handled by the class attribute `padding_side` which can be set to the following strings:
|
||||
- 'left': pads on the left of the sequences
|
||||
- 'right': pads on the right of the sequences
|
||||
Defaults to False: no padding.
|
||||
return_tensors: (optional) can be set to 'tf' or 'pt' to return respectively TensorFlow tf.constant
|
||||
or PyTorch torch.Tensor instead of a list of python integers.
|
||||
return_input_lengths: (optional) If set the resulting dictionary will include the length of each sample
|
||||
return_attention_masks: (optional) Set to True to return the attention mask (default False)
|
||||
return_offsets_mapping: (optional) Not available, should be set to False or it will throw NotImplementError
|
||||
**kwargs: passed to the `self.tokenize()` method
|
||||
|
||||
Return:
|
||||
A Dictionary of shape::
|
||||
|
||||
{
|
||||
input_ids: list[List[int]],
|
||||
token_type_ids: list[List[int]] if return_token_type_ids is True (default)
|
||||
attention_mask: list[List[int]] if return_attention_mask is True (default)
|
||||
overflowing_tokens: list[List[int]] if a ``max_length`` is specified and return_overflowing_tokens is True
|
||||
num_truncated_tokens: List[int] if a ``max_length`` is specified and return_overflowing_tokens is True
|
||||
special_tokens_mask: list[List[int]] if ``add_special_tokens`` if set to ``True`` and return_special_tokens_mask is True
|
||||
}
|
||||
|
||||
With the fields:
|
||||
``input_ids``: list of token ids to be fed to a model
|
||||
``token_type_ids``: list of token type ids to be fed to a model
|
||||
``attention_mask``: list of indices specifying which tokens should be attended to by the model
|
||||
``overflowing_tokens``: list of overflowing tokens if a max length is specified.
|
||||
``num_truncated_tokens``: number of overflowing tokens a ``max_length`` is specified
|
||||
``special_tokens_mask``: if adding special tokens, this is a list of [0, 1], with 0 specifying special added
|
||||
tokens and 1 specifying sequence tokens.
|
||||
"""
|
||||
|
||||
def get_input_ids(text):
|
||||
if isinstance(text, str):
|
||||
tokens = self.tokenize(text, add_special_tokens=add_special_tokens, **kwargs)
|
||||
return self.convert_tokens_to_ids(tokens)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], str):
|
||||
return self.convert_tokens_to_ids(text)
|
||||
elif isinstance(text, (list, tuple)) and len(text) > 0 and isinstance(text[0], int):
|
||||
return text
|
||||
else:
|
||||
raise ValueError(
|
||||
"Input is not valid. Should be a string, a list/tuple of strings or a list/tuple of integers."
|
||||
)
|
||||
|
||||
if return_offsets_mapping:
|
||||
raise NotImplementedError(
|
||||
"return_offset_mapping is not available when using Python tokenizers."
|
||||
@@ -1063,21 +1124,47 @@ class PreTrainedTokenizer(object):
|
||||
"https://github.com/huggingface/transformers/pull/2674"
|
||||
)
|
||||
|
||||
batch_outputs = {}
|
||||
input_ids = []
|
||||
for ids_or_pair_ids in batch_text_or_text_pairs:
|
||||
if isinstance(ids_or_pair_ids, (list, tuple)):
|
||||
assert len(ids_or_pair_ids) == 2
|
||||
ids, pair_ids = ids_or_pair_ids
|
||||
else:
|
||||
ids, pair_ids = ids_or_pair_ids, None
|
||||
outputs = self.encode_plus(
|
||||
ids,
|
||||
pair_ids,
|
||||
add_special_tokens=add_special_tokens,
|
||||
|
||||
first_ids = get_input_ids(ids)
|
||||
second_ids = get_input_ids(pair_ids) if pair_ids is not None else None
|
||||
input_ids.append((first_ids, second_ids))
|
||||
|
||||
if max_length is None and pad_to_max_length:
|
||||
|
||||
def total_sequence_length(input_pairs):
|
||||
first_ids, second_ids = input_pairs
|
||||
return len(first_ids) + (
|
||||
self.num_added_tokens()
|
||||
if second_ids is None
|
||||
else (len(second_ids) + self.num_added_tokens(pair=True))
|
||||
)
|
||||
|
||||
max_length = max([total_sequence_length(ids) for ids in input_ids])
|
||||
|
||||
batch_outputs = {}
|
||||
for first_ids, second_ids in input_ids:
|
||||
# Prepares a sequence of input id, or a pair of sequences of inputs ids so that it can be used by
|
||||
# the model. It adds special tokens, truncates sequences if overflowing while taking into account
|
||||
# the special tokens and manages a window stride for overflowing tokens
|
||||
outputs = self.prepare_for_model(
|
||||
first_ids,
|
||||
pair_ids=second_ids,
|
||||
max_length=max_length,
|
||||
pad_to_max_length=pad_to_max_length,
|
||||
add_special_tokens=add_special_tokens,
|
||||
stride=stride,
|
||||
truncation_strategy=truncation_strategy,
|
||||
return_tensors=None,
|
||||
return_attention_mask=return_attention_masks,
|
||||
return_token_type_ids=return_token_type_ids,
|
||||
return_overflowing_tokens=return_overflowing_tokens,
|
||||
return_special_tokens_mask=return_special_tokens_masks,
|
||||
)
|
||||
|
||||
# Append the non-padded length to the output
|
||||
@@ -1089,31 +1176,28 @@ class PreTrainedTokenizer(object):
|
||||
batch_outputs[key] = []
|
||||
batch_outputs[key].append(value)
|
||||
|
||||
# Compute longest sequence size
|
||||
max_seq_len = max(map(len, batch_outputs["input_ids"]))
|
||||
|
||||
if return_attention_masks:
|
||||
# Allow the model to not give any special attention to padded input
|
||||
batch_outputs["attention_mask"] = [[0] * len(v) for v in batch_outputs["input_ids"]]
|
||||
|
||||
if return_tensors is not None:
|
||||
|
||||
# Do the tensor conversion in batch
|
||||
for key, value in batch_outputs.items():
|
||||
|
||||
padded_value = value
|
||||
# verify that the tokenizer has a pad_token_id
|
||||
if key != "input_len" and self._pad_token is not None:
|
||||
# Padding handle
|
||||
padded_value = [
|
||||
v + [self.pad_token_id if key == "input_ids" else 1] * (max_seq_len - len(v))
|
||||
for v in padded_value
|
||||
]
|
||||
|
||||
if return_tensors == "tf" and is_tf_available():
|
||||
batch_outputs[key] = tf.constant(padded_value)
|
||||
try:
|
||||
batch_outputs[key] = tf.constant(value)
|
||||
except ValueError:
|
||||
if None in [item for sequence in value for item in sequence]:
|
||||
raise ValueError(self.NO_PAD_TOKEN_FOR_BATCH_MSG)
|
||||
else:
|
||||
raise ValueError(self.UNEVEN_SEQUENCES_FOR_BATCH_MSG)
|
||||
elif return_tensors == "pt" and is_torch_available():
|
||||
batch_outputs[key] = torch.tensor(padded_value)
|
||||
try:
|
||||
batch_outputs[key] = torch.tensor(value)
|
||||
except ValueError:
|
||||
raise ValueError(self.UNEVEN_SEQUENCES_FOR_BATCH_MSG)
|
||||
except RuntimeError:
|
||||
if None in [item for sequence in value for item in sequence]:
|
||||
raise ValueError(self.NO_PAD_TOKEN_FOR_BATCH_MSG)
|
||||
else:
|
||||
raise
|
||||
elif return_tensors is not None:
|
||||
logger.warning(
|
||||
"Unable to convert output to tensors format {}, PyTorch or TensorFlow is not available.".format(
|
||||
@@ -1121,13 +1205,6 @@ class PreTrainedTokenizer(object):
|
||||
)
|
||||
)
|
||||
|
||||
# encoder_attention_mask requires 1 for real token, 0 for padding, just invert value
|
||||
if return_attention_masks:
|
||||
if is_tf_available():
|
||||
batch_outputs["attention_mask"] = tf.abs(batch_outputs["attention_mask"] - 1)
|
||||
else:
|
||||
batch_outputs["attention_mask"] = torch.abs(batch_outputs["attention_mask"] - 1)
|
||||
|
||||
return batch_outputs
|
||||
|
||||
def prepare_for_model(
|
||||
@@ -1229,7 +1306,10 @@ class PreTrainedTokenizer(object):
|
||||
token_type_ids = [0] * len(ids) + ([1] * len(pair_ids) if pair else [])
|
||||
|
||||
if return_special_tokens_mask:
|
||||
encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(ids, pair_ids)
|
||||
if add_special_tokens:
|
||||
encoded_inputs["special_tokens_mask"] = self.get_special_tokens_mask(ids, pair_ids)
|
||||
else:
|
||||
encoded_inputs["special_tokens_mask"] = [0] * len(sequence)
|
||||
|
||||
encoded_inputs["input_ids"] = sequence
|
||||
if return_token_type_ids:
|
||||
@@ -1697,6 +1777,13 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
return_offsets_mapping=False,
|
||||
**kwargs
|
||||
):
|
||||
if not add_special_tokens:
|
||||
logger.warning(
|
||||
"Fast tokenizers add special tokens by default. To remove special tokens, please specify"
|
||||
"`add_special_tokens=False` during the initialisation rather than when calling `encode`,"
|
||||
"`encode_plus` or `batch_encode_plus`."
|
||||
)
|
||||
|
||||
# Needed if we have to return a tensor
|
||||
pad_to_max_length = pad_to_max_length or (return_tensors is not None)
|
||||
|
||||
@@ -1819,8 +1906,9 @@ class PreTrainedTokenizerFast(PreTrainedTokenizer):
|
||||
|
||||
def save_vocabulary(self, save_directory):
|
||||
if os.path.isdir(save_directory):
|
||||
folder, file = save_directory, self.vocab_files_names["vocab_file"]
|
||||
files = self._tokenizer.save(save_directory)
|
||||
else:
|
||||
folder, file = os.path.split(os.path.abspath(save_directory))
|
||||
files = self._tokenizer.save(folder, name=file)
|
||||
|
||||
return tuple(self._tokenizer.save(folder, file))
|
||||
return tuple(files)
|
||||
@@ -662,6 +662,9 @@ class XLMTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.encoder)
|
||||
|
||||
def get_vocab(self):
|
||||
return dict(self.encoder, **self.added_tokens_encoder)
|
||||
|
||||
def bpe(self, token):
|
||||
word = tuple(token[:-1]) + (token[-1] + "</w>",)
|
||||
if token in self.cache:
|
||||
|
||||
@@ -190,6 +190,11 @@ class XLMRobertaTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.sp_model) + len(self.fairseq_tokens_to_ids)
|
||||
|
||||
def get_vocab(self):
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def _tokenize(self, text):
|
||||
return self.sp_model.EncodeAsPieces(text)
|
||||
|
||||
|
||||
@@ -114,6 +114,11 @@ class XLNetTokenizer(PreTrainedTokenizer):
|
||||
def vocab_size(self):
|
||||
return len(self.sp_model)
|
||||
|
||||
def get_vocab(self):
|
||||
vocab = {self.convert_ids_to_tokens(i): i for i in range(self.vocab_size)}
|
||||
vocab.update(self.added_tokens_encoder)
|
||||
return vocab
|
||||
|
||||
def __getstate__(self):
|
||||
state = self.__dict__.copy()
|
||||
state["sp_model"] = None
|
||||
|
||||
@@ -251,6 +251,7 @@ class BartHeadTests(unittest.TestCase):
|
||||
output_past=True,
|
||||
)
|
||||
lm_model = BartForMaskedLM(config)
|
||||
lm_model.eval()
|
||||
new_input_ids = lm_model.generate(input_ids)
|
||||
self.assertEqual(new_input_ids.shape, (input_ids.shape[0], 20))
|
||||
|
||||
|
||||
@@ -641,7 +641,7 @@ global_rng = random.Random()
|
||||
|
||||
|
||||
def ids_tensor(shape, vocab_size, rng=None, name=None):
|
||||
"""Creates a random int32 tensor of the shape within the vocab size."""
|
||||
# Creates a random int32 tensor of the shape within the vocab size
|
||||
if rng is None:
|
||||
rng = global_rng
|
||||
|
||||
|
||||
@@ -23,6 +23,7 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import CTRLConfig, CTRLModel, CTRL_PRETRAINED_MODEL_ARCHIVE_MAP, CTRLLMHeadModel
|
||||
|
||||
|
||||
@@ -212,3 +213,36 @@ class CTRLModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(CTRL_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = CTRLModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
class CTRLModelLanguageGenerationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_lm_generate_ctrl(self):
|
||||
model = CTRLLMHeadModel.from_pretrained("ctrl")
|
||||
input_ids = torch.Tensor([[11859, 586, 20984, 8]]).long() # Legal My neighbor is
|
||||
expected_output_ids = [
|
||||
11859,
|
||||
586,
|
||||
20984,
|
||||
8,
|
||||
13391,
|
||||
3,
|
||||
980,
|
||||
8258,
|
||||
72,
|
||||
327,
|
||||
148,
|
||||
2,
|
||||
53,
|
||||
29,
|
||||
226,
|
||||
3,
|
||||
780,
|
||||
49,
|
||||
3,
|
||||
980,
|
||||
] # Legal My neighbor is refusing to pay rent after 2 years and we are having to force him to pay
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(input_ids)
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -24,6 +24,7 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
GPT2Config,
|
||||
GPT2Model,
|
||||
@@ -165,7 +166,7 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
"presents": presents,
|
||||
}
|
||||
self.parent.assertListEqual(
|
||||
list(result["sequence_output"].size()), [self.batch_size, self.seq_length, self.hidden_size]
|
||||
list(result["sequence_output"].size()), [self.batch_size, self.seq_length, self.hidden_size],
|
||||
)
|
||||
self.parent.assertEqual(len(result["presents"]), config.n_layer)
|
||||
|
||||
@@ -180,7 +181,7 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["lm_logits"].size()), [self.batch_size, self.seq_length, self.vocab_size]
|
||||
list(result["lm_logits"].size()), [self.batch_size, self.seq_length, self.vocab_size],
|
||||
)
|
||||
|
||||
def create_and_check_double_lm_head_model(
|
||||
@@ -208,7 +209,8 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
|
||||
self.parent.assertListEqual(list(result["loss"].size()), [])
|
||||
self.parent.assertListEqual(
|
||||
list(result["lm_logits"].size()), [self.batch_size, self.num_choices, self.seq_length, self.vocab_size]
|
||||
list(result["lm_logits"].size()),
|
||||
[self.batch_size, self.num_choices, self.seq_length, self.vocab_size],
|
||||
)
|
||||
self.parent.assertListEqual(list(result["mc_logits"].size()), [self.batch_size, self.num_choices])
|
||||
|
||||
@@ -227,7 +229,11 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
choice_labels,
|
||||
) = config_and_inputs
|
||||
|
||||
inputs_dict = {"input_ids": input_ids, "token_type_ids": token_type_ids, "head_mask": head_mask}
|
||||
inputs_dict = {
|
||||
"input_ids": input_ids,
|
||||
"token_type_ids": token_type_ids,
|
||||
"head_mask": head_mask,
|
||||
}
|
||||
|
||||
return config, inputs_dict
|
||||
|
||||
@@ -255,3 +261,84 @@ class GPT2ModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(GPT2_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = GPT2Model.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"bos_token_id": 50256, "eos_token_id": 50256}
|
||||
|
||||
|
||||
class GPT2ModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_gpt2(self):
|
||||
model = GPT2LMHeadModel.from_pretrained("gpt2")
|
||||
input_ids = torch.Tensor([[464, 3290, 318, 13779]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
464,
|
||||
3290,
|
||||
318,
|
||||
13779,
|
||||
1165,
|
||||
13,
|
||||
632,
|
||||
7832,
|
||||
284,
|
||||
6437,
|
||||
319,
|
||||
502,
|
||||
290,
|
||||
318,
|
||||
922,
|
||||
329,
|
||||
502,
|
||||
357,
|
||||
1169,
|
||||
3290,
|
||||
] # The dog is cute too. It likes to rub on me and is good for me (the dog
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
eos_token_ids=self.special_tokens["eos_token_id"],
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
|
||||
@slow
|
||||
def test_lm_generate_distilgpt2(self):
|
||||
model = GPT2LMHeadModel.from_pretrained("distilgpt2")
|
||||
input_ids = torch.Tensor([[464, 3290, 318, 13779]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
464,
|
||||
3290,
|
||||
318,
|
||||
13779,
|
||||
996,
|
||||
339,
|
||||
460,
|
||||
3360,
|
||||
655,
|
||||
2513,
|
||||
287,
|
||||
262,
|
||||
3952,
|
||||
13,
|
||||
632,
|
||||
318,
|
||||
407,
|
||||
845,
|
||||
3621,
|
||||
284,
|
||||
] # The dog is cute though he can sometimes just walk in the park. It is not very nice to
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
eos_token_ids=self.special_tokens["eos_token_id"],
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -24,6 +24,7 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
OpenAIGPTConfig,
|
||||
OpenAIGPTModel,
|
||||
@@ -208,3 +209,36 @@ class OpenAIGPTModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(OPENAI_GPT_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = OpenAIGPTModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
class OPENAIGPTModelLanguageGenerationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_lm_generate_openai_gpt(self):
|
||||
model = OpenAIGPTLMHeadModel.from_pretrained("openai-gpt")
|
||||
input_ids = torch.Tensor([[481, 2585, 544, 4957]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
481,
|
||||
2585,
|
||||
544,
|
||||
4957,
|
||||
669,
|
||||
512,
|
||||
761,
|
||||
5990,
|
||||
271,
|
||||
645,
|
||||
487,
|
||||
535,
|
||||
976,
|
||||
2479,
|
||||
240,
|
||||
487,
|
||||
804,
|
||||
1296,
|
||||
2891,
|
||||
512,
|
||||
] # the dog is cute when you're annoyed : if he's really stupid, he 'll stop fighting you
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(input_ids)
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -212,3 +212,372 @@ class TransfoXLModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(TRANSFO_XL_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = TransfoXLModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"eos_token_id": 0}
|
||||
|
||||
|
||||
class TransfoXLModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_transfo_xl_wt103(self):
|
||||
model = TransfoXLLMHeadModel.from_pretrained("transfo-xl-wt103")
|
||||
input_ids = torch.Tensor(
|
||||
[
|
||||
[
|
||||
33,
|
||||
1297,
|
||||
2,
|
||||
1,
|
||||
1009,
|
||||
4,
|
||||
1109,
|
||||
11739,
|
||||
4762,
|
||||
358,
|
||||
5,
|
||||
25,
|
||||
245,
|
||||
22,
|
||||
1706,
|
||||
17,
|
||||
20098,
|
||||
5,
|
||||
3215,
|
||||
21,
|
||||
37,
|
||||
1110,
|
||||
3,
|
||||
13,
|
||||
1041,
|
||||
4,
|
||||
24,
|
||||
603,
|
||||
490,
|
||||
2,
|
||||
71477,
|
||||
20098,
|
||||
104447,
|
||||
2,
|
||||
20961,
|
||||
1,
|
||||
2604,
|
||||
4,
|
||||
1,
|
||||
329,
|
||||
3,
|
||||
6224,
|
||||
831,
|
||||
16002,
|
||||
2,
|
||||
8,
|
||||
603,
|
||||
78967,
|
||||
29546,
|
||||
23,
|
||||
803,
|
||||
20,
|
||||
25,
|
||||
416,
|
||||
5,
|
||||
8,
|
||||
232,
|
||||
4,
|
||||
277,
|
||||
6,
|
||||
1855,
|
||||
4601,
|
||||
3,
|
||||
29546,
|
||||
54,
|
||||
8,
|
||||
3609,
|
||||
5,
|
||||
57211,
|
||||
49,
|
||||
4,
|
||||
1,
|
||||
277,
|
||||
18,
|
||||
8,
|
||||
1755,
|
||||
15691,
|
||||
3,
|
||||
341,
|
||||
25,
|
||||
416,
|
||||
693,
|
||||
42573,
|
||||
71,
|
||||
17,
|
||||
401,
|
||||
94,
|
||||
31,
|
||||
17919,
|
||||
2,
|
||||
29546,
|
||||
7873,
|
||||
18,
|
||||
1,
|
||||
435,
|
||||
23,
|
||||
11011,
|
||||
755,
|
||||
5,
|
||||
5167,
|
||||
3,
|
||||
7983,
|
||||
98,
|
||||
84,
|
||||
2,
|
||||
29546,
|
||||
3267,
|
||||
8,
|
||||
3609,
|
||||
4,
|
||||
1,
|
||||
4865,
|
||||
1075,
|
||||
2,
|
||||
6087,
|
||||
71,
|
||||
6,
|
||||
346,
|
||||
8,
|
||||
5854,
|
||||
3,
|
||||
29546,
|
||||
824,
|
||||
1400,
|
||||
1868,
|
||||
2,
|
||||
19,
|
||||
160,
|
||||
2,
|
||||
311,
|
||||
8,
|
||||
5496,
|
||||
2,
|
||||
20920,
|
||||
17,
|
||||
25,
|
||||
15097,
|
||||
3,
|
||||
24,
|
||||
24,
|
||||
0,
|
||||
]
|
||||
]
|
||||
).long()
|
||||
# In 1991 , the remains of Russian Tsar Nicholas II and his family
|
||||
# ( except for Alexei and Maria ) are discovered .
|
||||
# The voice of Nicholas's young son , Tsarevich Alexei Nikolaevich , narrates the
|
||||
# remainder of the story . 1883 Western Siberia ,
|
||||
# a young Grigori Rasputin is asked by his father and a group of men to perform magic .
|
||||
# Rasputin has a vision and denounces one of the men as a horse thief . Although his
|
||||
# father initially slaps him for making such an accusation , Rasputin watches as the
|
||||
# man is chased outside and beaten . Twenty years later , Rasputin sees a vision of
|
||||
# the Virgin Mary , prompting him to become a priest . Rasputin quickly becomes famous ,
|
||||
# with people , even a bishop , begging for his blessing . <eod> </s> <eos>
|
||||
|
||||
expected_output_ids = [
|
||||
33,
|
||||
1297,
|
||||
2,
|
||||
1,
|
||||
1009,
|
||||
4,
|
||||
1109,
|
||||
11739,
|
||||
4762,
|
||||
358,
|
||||
5,
|
||||
25,
|
||||
245,
|
||||
22,
|
||||
1706,
|
||||
17,
|
||||
20098,
|
||||
5,
|
||||
3215,
|
||||
21,
|
||||
37,
|
||||
1110,
|
||||
3,
|
||||
13,
|
||||
1041,
|
||||
4,
|
||||
24,
|
||||
603,
|
||||
490,
|
||||
2,
|
||||
71477,
|
||||
20098,
|
||||
104447,
|
||||
2,
|
||||
20961,
|
||||
1,
|
||||
2604,
|
||||
4,
|
||||
1,
|
||||
329,
|
||||
3,
|
||||
6224,
|
||||
831,
|
||||
16002,
|
||||
2,
|
||||
8,
|
||||
603,
|
||||
78967,
|
||||
29546,
|
||||
23,
|
||||
803,
|
||||
20,
|
||||
25,
|
||||
416,
|
||||
5,
|
||||
8,
|
||||
232,
|
||||
4,
|
||||
277,
|
||||
6,
|
||||
1855,
|
||||
4601,
|
||||
3,
|
||||
29546,
|
||||
54,
|
||||
8,
|
||||
3609,
|
||||
5,
|
||||
57211,
|
||||
49,
|
||||
4,
|
||||
1,
|
||||
277,
|
||||
18,
|
||||
8,
|
||||
1755,
|
||||
15691,
|
||||
3,
|
||||
341,
|
||||
25,
|
||||
416,
|
||||
693,
|
||||
42573,
|
||||
71,
|
||||
17,
|
||||
401,
|
||||
94,
|
||||
31,
|
||||
17919,
|
||||
2,
|
||||
29546,
|
||||
7873,
|
||||
18,
|
||||
1,
|
||||
435,
|
||||
23,
|
||||
11011,
|
||||
755,
|
||||
5,
|
||||
5167,
|
||||
3,
|
||||
7983,
|
||||
98,
|
||||
84,
|
||||
2,
|
||||
29546,
|
||||
3267,
|
||||
8,
|
||||
3609,
|
||||
4,
|
||||
1,
|
||||
4865,
|
||||
1075,
|
||||
2,
|
||||
6087,
|
||||
71,
|
||||
6,
|
||||
346,
|
||||
8,
|
||||
5854,
|
||||
3,
|
||||
29546,
|
||||
824,
|
||||
1400,
|
||||
1868,
|
||||
2,
|
||||
19,
|
||||
160,
|
||||
2,
|
||||
311,
|
||||
8,
|
||||
5496,
|
||||
2,
|
||||
20920,
|
||||
17,
|
||||
25,
|
||||
15097,
|
||||
3,
|
||||
24,
|
||||
24,
|
||||
0,
|
||||
29546,
|
||||
40,
|
||||
1092,
|
||||
18,
|
||||
8,
|
||||
5854,
|
||||
7,
|
||||
1143,
|
||||
2,
|
||||
7,
|
||||
1,
|
||||
159,
|
||||
99,
|
||||
16,
|
||||
1,
|
||||
1009,
|
||||
4,
|
||||
1109,
|
||||
11739,
|
||||
4762,
|
||||
358,
|
||||
5,
|
||||
25,
|
||||
245,
|
||||
28,
|
||||
1110,
|
||||
3,
|
||||
57,
|
||||
629,
|
||||
38,
|
||||
3493,
|
||||
47,
|
||||
1094,
|
||||
7,
|
||||
1297,
|
||||
3,
|
||||
0,
|
||||
]
|
||||
# In 1991, the remains of Russian Tsar Nicholas II and his family (
|
||||
# except for Alexei and Maria ) are discovered. The voice of young son,
|
||||
# Tsarevich Alexei Nikolaevich, narrates the remainder of the story.
|
||||
# 1883 Western Siberia, a young Grigori Rasputin is asked by his father
|
||||
# and a group of men to perform magic. Rasputin has a vision and
|
||||
# denounces one of the men as a horse thief. Although his father initially
|
||||
# slaps him for making such an accusation, Rasputin watches as the man
|
||||
# is chased outside and beaten. Twenty years later, Rasputin sees a vision
|
||||
# of the Virgin Mary, prompting him to become a priest.
|
||||
# Rasputin quickly becomes famous, with people, even a bishop, begging for
|
||||
# his blessing. Rasputin first appears as a priest in 1996, in the same year
|
||||
# that the remains of Russian Tsar Nicholas II and his family were discovered. H
|
||||
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(input_ids, eos_token_ids=self.special_tokens["eos_token_id"], max_length=200)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -24,6 +24,7 @@ from .utils import CACHE_DIR, require_torch, slow, torch_device
|
||||
|
||||
|
||||
if is_torch_available():
|
||||
import torch
|
||||
from transformers import (
|
||||
XLMConfig,
|
||||
XLMModel,
|
||||
@@ -396,3 +397,48 @@ class XLMModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(XLM_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = XLMModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"bos_token_id": 0, "pad_token_id": 2}
|
||||
|
||||
|
||||
class XLMModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_xlm_mlm_en_2048(self):
|
||||
model = XLMWithLMHeadModel.from_pretrained("xlm-mlm-en-2048")
|
||||
input_ids = torch.Tensor([[1, 14, 2232, 26, 1]]).long() # The dog is cute
|
||||
expected_output_ids = [
|
||||
1,
|
||||
14,
|
||||
2232,
|
||||
26,
|
||||
1,
|
||||
567,
|
||||
26,
|
||||
32,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
149,
|
||||
] # The dog is nothing is it!!!!!!!!!!!! TODO (PVP): this sentence (and others I tried) does not make much sense, there seems to be a problem with xlm language generation.
|
||||
torch.manual_seed(0)
|
||||
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
pad_token_id=self.special_tokens["pad_token_id"],
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -511,3 +511,418 @@ class XLNetModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
for model_name in list(XLNET_PRETRAINED_MODEL_ARCHIVE_MAP.keys())[:1]:
|
||||
model = XLNetModel.from_pretrained(model_name, cache_dir=CACHE_DIR)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
def prepare_generation_special_tokens():
|
||||
return {"bos_token_id": 1, "pad_token_id": 5, "eos_token_id": 2}
|
||||
|
||||
|
||||
class XLNetModelLanguageGenerationTest(unittest.TestCase):
|
||||
|
||||
special_tokens = prepare_generation_special_tokens()
|
||||
|
||||
@slow
|
||||
def test_lm_generate_xlnet_base_cased(self):
|
||||
model = XLNetLMHeadModel.from_pretrained("xlnet-base-cased")
|
||||
input_ids = torch.Tensor(
|
||||
[
|
||||
[
|
||||
67,
|
||||
2840,
|
||||
19,
|
||||
18,
|
||||
1484,
|
||||
20,
|
||||
965,
|
||||
29077,
|
||||
8719,
|
||||
1273,
|
||||
21,
|
||||
45,
|
||||
273,
|
||||
17,
|
||||
10,
|
||||
15048,
|
||||
28,
|
||||
27511,
|
||||
21,
|
||||
4185,
|
||||
11,
|
||||
41,
|
||||
2444,
|
||||
9,
|
||||
32,
|
||||
1025,
|
||||
20,
|
||||
8719,
|
||||
26,
|
||||
23,
|
||||
673,
|
||||
966,
|
||||
19,
|
||||
29077,
|
||||
20643,
|
||||
27511,
|
||||
20822,
|
||||
20643,
|
||||
19,
|
||||
17,
|
||||
6616,
|
||||
17511,
|
||||
18,
|
||||
8978,
|
||||
20,
|
||||
18,
|
||||
777,
|
||||
9,
|
||||
19233,
|
||||
1527,
|
||||
17669,
|
||||
19,
|
||||
24,
|
||||
673,
|
||||
17,
|
||||
28756,
|
||||
150,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
27,
|
||||
442,
|
||||
37,
|
||||
45,
|
||||
668,
|
||||
21,
|
||||
24,
|
||||
256,
|
||||
20,
|
||||
416,
|
||||
22,
|
||||
2771,
|
||||
4901,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
51,
|
||||
24,
|
||||
3004,
|
||||
21,
|
||||
28142,
|
||||
23,
|
||||
65,
|
||||
20,
|
||||
18,
|
||||
416,
|
||||
34,
|
||||
24,
|
||||
2958,
|
||||
22947,
|
||||
9,
|
||||
1177,
|
||||
45,
|
||||
668,
|
||||
3097,
|
||||
13768,
|
||||
23,
|
||||
103,
|
||||
28,
|
||||
441,
|
||||
148,
|
||||
48,
|
||||
20522,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
12860,
|
||||
34,
|
||||
18,
|
||||
326,
|
||||
27,
|
||||
17492,
|
||||
684,
|
||||
21,
|
||||
6709,
|
||||
9,
|
||||
8585,
|
||||
123,
|
||||
266,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
6872,
|
||||
24,
|
||||
3004,
|
||||
20,
|
||||
18,
|
||||
9225,
|
||||
2198,
|
||||
19,
|
||||
12717,
|
||||
103,
|
||||
22,
|
||||
401,
|
||||
24,
|
||||
6348,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
1068,
|
||||
2768,
|
||||
2286,
|
||||
19,
|
||||
33,
|
||||
104,
|
||||
19,
|
||||
176,
|
||||
24,
|
||||
9313,
|
||||
19,
|
||||
20086,
|
||||
28,
|
||||
45,
|
||||
10292,
|
||||
9,
|
||||
4,
|
||||
3,
|
||||
]
|
||||
]
|
||||
).long()
|
||||
# In 1991, the remains of Russian Tsar Nicholas II and his family
|
||||
# (except for Alexei and Maria) are discovered.
|
||||
# The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich, narrates the
|
||||
# remainder of the story. 1883 Western Siberia,
|
||||
# a young Grigori Rasputin is asked by his father and a group of men to perform magic.
|
||||
# Rasputin has a vision and denounces one of the men as a horse thief. Although his
|
||||
# father initially slaps him for making such an accusation, Rasputin watches as the
|
||||
# man is chased outside and beaten. Twenty years later, Rasputin sees a vision of
|
||||
# the Virgin Mary, prompting him to become a priest. Rasputin quickly becomes famous,
|
||||
# with people, even a bishop, begging for his blessing. """
|
||||
|
||||
expected_output_ids = [
|
||||
67,
|
||||
2840,
|
||||
19,
|
||||
18,
|
||||
1484,
|
||||
20,
|
||||
965,
|
||||
29077,
|
||||
8719,
|
||||
1273,
|
||||
21,
|
||||
45,
|
||||
273,
|
||||
17,
|
||||
10,
|
||||
15048,
|
||||
28,
|
||||
27511,
|
||||
21,
|
||||
4185,
|
||||
11,
|
||||
41,
|
||||
2444,
|
||||
9,
|
||||
32,
|
||||
1025,
|
||||
20,
|
||||
8719,
|
||||
26,
|
||||
23,
|
||||
673,
|
||||
966,
|
||||
19,
|
||||
29077,
|
||||
20643,
|
||||
27511,
|
||||
20822,
|
||||
20643,
|
||||
19,
|
||||
17,
|
||||
6616,
|
||||
17511,
|
||||
18,
|
||||
8978,
|
||||
20,
|
||||
18,
|
||||
777,
|
||||
9,
|
||||
19233,
|
||||
1527,
|
||||
17669,
|
||||
19,
|
||||
24,
|
||||
673,
|
||||
17,
|
||||
28756,
|
||||
150,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
27,
|
||||
442,
|
||||
37,
|
||||
45,
|
||||
668,
|
||||
21,
|
||||
24,
|
||||
256,
|
||||
20,
|
||||
416,
|
||||
22,
|
||||
2771,
|
||||
4901,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
51,
|
||||
24,
|
||||
3004,
|
||||
21,
|
||||
28142,
|
||||
23,
|
||||
65,
|
||||
20,
|
||||
18,
|
||||
416,
|
||||
34,
|
||||
24,
|
||||
2958,
|
||||
22947,
|
||||
9,
|
||||
1177,
|
||||
45,
|
||||
668,
|
||||
3097,
|
||||
13768,
|
||||
23,
|
||||
103,
|
||||
28,
|
||||
441,
|
||||
148,
|
||||
48,
|
||||
20522,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
12860,
|
||||
34,
|
||||
18,
|
||||
326,
|
||||
27,
|
||||
17492,
|
||||
684,
|
||||
21,
|
||||
6709,
|
||||
9,
|
||||
8585,
|
||||
123,
|
||||
266,
|
||||
19,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
6872,
|
||||
24,
|
||||
3004,
|
||||
20,
|
||||
18,
|
||||
9225,
|
||||
2198,
|
||||
19,
|
||||
12717,
|
||||
103,
|
||||
22,
|
||||
401,
|
||||
24,
|
||||
6348,
|
||||
9,
|
||||
12943,
|
||||
4354,
|
||||
153,
|
||||
1068,
|
||||
2768,
|
||||
2286,
|
||||
19,
|
||||
33,
|
||||
104,
|
||||
19,
|
||||
176,
|
||||
24,
|
||||
9313,
|
||||
19,
|
||||
20086,
|
||||
28,
|
||||
45,
|
||||
10292,
|
||||
9,
|
||||
4,
|
||||
3,
|
||||
1722,
|
||||
19,
|
||||
24,
|
||||
6348,
|
||||
61,
|
||||
977,
|
||||
176,
|
||||
1772,
|
||||
33,
|
||||
45,
|
||||
970,
|
||||
19,
|
||||
4185,
|
||||
19,
|
||||
27,
|
||||
442,
|
||||
22,
|
||||
2771,
|
||||
4901,
|
||||
25,
|
||||
18,
|
||||
2059,
|
||||
20,
|
||||
24,
|
||||
303,
|
||||
1775,
|
||||
691,
|
||||
9,
|
||||
1147,
|
||||
19,
|
||||
634,
|
||||
19,
|
||||
43,
|
||||
51,
|
||||
54,
|
||||
6157,
|
||||
2999,
|
||||
33,
|
||||
4185,
|
||||
]
|
||||
# In 1991, the remains of Russian Tsar Nicholas II and his family (except for Alexei and Maria)
|
||||
# are discovered. The voice of Nicholas's young son, Tsarevich Alexei Nikolaevich,
|
||||
# narrates the remainder of the story. 1883 Western Siberia, a young Grigori Rasputin
|
||||
# is asked by his father and a group of men to perform magic. Rasputin has a vision and
|
||||
# denounces one of the men as a horse thief. Although his father initially slaps
|
||||
# him for making such an accusation, Rasputin watches as the man is chased outside and beaten.
|
||||
# Twenty years later, Rasputin sees a vision of the Virgin Mary, prompting him to become a priest.
|
||||
# Rasputin quickly becomes famous, with people, even a bishop, begging for his blessing.
|
||||
# 1990, a priest who cannot even walk with his wife, Maria, is asked to perform magic
|
||||
# in the presence of a local religious leader.
|
||||
# Since, however, he has had difficulty walking with Maria
|
||||
|
||||
torch.manual_seed(0)
|
||||
output_ids = model.generate(
|
||||
input_ids,
|
||||
bos_token_id=self.special_tokens["bos_token_id"],
|
||||
pad_token_id=self.special_tokens["pad_token_id"],
|
||||
eos_token_ids=self.special_tokens["eos_token_id"],
|
||||
max_length=200,
|
||||
)
|
||||
|
||||
self.assertListEqual(output_ids[0].tolist(), expected_output_ids)
|
||||
@@ -19,6 +19,8 @@ import pickle
|
||||
import shutil
|
||||
import tempfile
|
||||
|
||||
from tests.utils import require_tf, require_torch
|
||||
|
||||
|
||||
class TokenizerTesterMixin:
|
||||
|
||||
@@ -40,6 +42,15 @@ class TokenizerTesterMixin:
|
||||
def get_input_output_texts(self):
|
||||
raise NotImplementedError
|
||||
|
||||
@staticmethod
|
||||
def convert_batch_encode_plus_format_to_encode_plus(batch_encode_plus_sequences):
|
||||
# Switch from batch_encode_plus format: {'input_ids': [[...], [...]], ...}
|
||||
# to the concatenated encode_plus format: [{'input_ids': [...], ...}, {'input_ids': [...], ...}]
|
||||
return [
|
||||
{value: batch_encode_plus_sequences[value][i] for value in batch_encode_plus_sequences.keys()}
|
||||
for i in range(len(batch_encode_plus_sequences))
|
||||
]
|
||||
|
||||
def test_tokenizers_common_properties(self):
|
||||
tokenizer = self.get_tokenizer()
|
||||
attributes_list = [
|
||||
@@ -535,10 +546,125 @@ class TokenizerTesterMixin:
|
||||
# we're loading an S3 configuration from a pre-trained identifier, and we have no way of testing those today.
|
||||
|
||||
tokenizer = self.get_tokenizer(random_argument=True)
|
||||
print(tokenizer.init_kwargs)
|
||||
assert tokenizer.init_kwargs["random_argument"] is True
|
||||
new_tokenizer = self.get_tokenizer(random_argument=False)
|
||||
print(tokenizer.init_kwargs)
|
||||
print(new_tokenizer.init_kwargs)
|
||||
assert tokenizer.init_kwargs["random_argument"] is True
|
||||
assert new_tokenizer.init_kwargs["random_argument"] is False
|
||||
|
||||
def test_get_vocab(self):
|
||||
tokenizer = self.get_tokenizer()
|
||||
vocab = tokenizer.get_vocab()
|
||||
|
||||
self.assertIsInstance(vocab, dict)
|
||||
self.assertEqual(len(vocab), len(tokenizer))
|
||||
|
||||
for word, ind in vocab.items():
|
||||
self.assertEqual(tokenizer.convert_tokens_to_ids(word), ind)
|
||||
self.assertEqual(tokenizer.convert_ids_to_tokens(ind), word)
|
||||
|
||||
tokenizer.add_tokens(["asdfasdfasdfasdf"])
|
||||
vocab = tokenizer.get_vocab()
|
||||
self.assertIsInstance(vocab, dict)
|
||||
self.assertEqual(len(vocab), len(tokenizer))
|
||||
|
||||
for word, ind in vocab.items():
|
||||
self.assertEqual(tokenizer.convert_tokens_to_ids(word), ind)
|
||||
self.assertEqual(tokenizer.convert_ids_to_tokens(ind), word)
|
||||
|
||||
def test_batch_encode_plus_batch_sequence_length(self):
|
||||
# Tests that all encoded values have the correct size
|
||||
tokenizer = self.get_tokenizer()
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
encoded_sequences = [tokenizer.encode_plus(sequence, pad_to_max_length=False) for sequence in sequences]
|
||||
encoded_sequences_batch = tokenizer.batch_encode_plus(sequences)
|
||||
self.assertListEqual(
|
||||
encoded_sequences, self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch)
|
||||
)
|
||||
|
||||
maximum_length = len(max([encoded_sequence["input_ids"] for encoded_sequence in encoded_sequences], key=len))
|
||||
|
||||
encoded_sequences_padded = [
|
||||
tokenizer.encode_plus(sequence, pad_to_max_length=True, max_length=maximum_length)
|
||||
for sequence in sequences
|
||||
]
|
||||
encoded_sequences_batch_padded = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True)
|
||||
self.assertListEqual(
|
||||
encoded_sequences_padded,
|
||||
self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch_padded),
|
||||
)
|
||||
|
||||
def test_batch_encode_plus_padding(self):
|
||||
# Test that padded sequences are equivalent between batch_encode_plus and encode_plus
|
||||
|
||||
# Right padding tests
|
||||
tokenizer = self.get_tokenizer()
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
max_length = 100
|
||||
encoded_sequences = [
|
||||
tokenizer.encode_plus(sequence, pad_to_max_length=True, max_length=max_length) for sequence in sequences
|
||||
]
|
||||
encoded_sequences_batch = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, max_length=max_length)
|
||||
self.assertListEqual(
|
||||
encoded_sequences, self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch)
|
||||
)
|
||||
|
||||
# Left padding tests
|
||||
tokenizer = self.get_tokenizer()
|
||||
tokenizer.padding_side = "left"
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
max_length = 100
|
||||
encoded_sequences = [
|
||||
tokenizer.encode_plus(sequence, pad_to_max_length=True, max_length=max_length) for sequence in sequences
|
||||
]
|
||||
encoded_sequences_batch = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, max_length=max_length)
|
||||
self.assertListEqual(
|
||||
encoded_sequences, self.convert_batch_encode_plus_format_to_encode_plus(encoded_sequences_batch)
|
||||
)
|
||||
|
||||
@require_torch
|
||||
@require_tf
|
||||
def test_batch_encode_plus_tensors(self):
|
||||
tokenizer = self.get_tokenizer()
|
||||
sequences = [
|
||||
"Testing batch encode plus",
|
||||
"Testing batch encode plus with different sequence lengths",
|
||||
"Testing batch encode plus with different sequence lengths correctly pads",
|
||||
]
|
||||
|
||||
# A Tensor cannot be build by sequences which are not the same size
|
||||
self.assertRaises(ValueError, tokenizer.batch_encode_plus, sequences, return_tensors="pt")
|
||||
self.assertRaises(ValueError, tokenizer.batch_encode_plus, sequences, return_tensors="tf")
|
||||
|
||||
if tokenizer.pad_token_id is None:
|
||||
self.assertRaises(
|
||||
ValueError, tokenizer.batch_encode_plus, sequences, pad_to_max_length=True, return_tensors="pt"
|
||||
)
|
||||
self.assertRaises(
|
||||
ValueError, tokenizer.batch_encode_plus, sequences, pad_to_max_length=True, return_tensors="tf"
|
||||
)
|
||||
else:
|
||||
pytorch_tensor = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, return_tensors="pt")
|
||||
tensorflow_tensor = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True, return_tensors="tf")
|
||||
encoded_sequences = tokenizer.batch_encode_plus(sequences, pad_to_max_length=True)
|
||||
|
||||
for key in encoded_sequences.keys():
|
||||
pytorch_value = pytorch_tensor[key].tolist()
|
||||
tensorflow_value = tensorflow_tensor[key].numpy().tolist()
|
||||
encoded_value = encoded_sequences[key]
|
||||
|
||||
self.assertEqual(pytorch_value, tensorflow_value, encoded_value)
|
||||
@@ -258,6 +258,20 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
output_p = tokenizer_p.build_inputs_with_special_tokens(input_simple, input_pair)
|
||||
self.assertEqual(output_p, output_r)
|
||||
|
||||
def assert_save_pretrained(self, tokenizer_r, tokenizer_p):
|
||||
|
||||
# Checks it save with the same files
|
||||
self.assertSequenceEqual(tokenizer_r.save_vocabulary("."), tokenizer_p.save_vocabulary("."))
|
||||
|
||||
# Checks everything loads correctly in the same way
|
||||
tokenizer_rp, tokenizer_pp = tokenizer_r.from_pretrained("."), tokenizer_p.from_pretrained(".")
|
||||
|
||||
# Check special tokens are set accordingly on Rust and Python
|
||||
for key in tokenizer_pp.special_tokens_map:
|
||||
self.assertTrue(hasattr(tokenizer_rp, key))
|
||||
# self.assertEqual(getattr(tokenizer_rp, key), getattr(tokenizer_pp, key))
|
||||
# self.assertEqual(getattr(tokenizer_rp, key + "_id"), getattr(tokenizer_pp, key + "_id"))
|
||||
|
||||
def test_bert(self):
|
||||
for tokenizer_name in BertTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = BertTokenizer.from_pretrained(tokenizer_name)
|
||||
@@ -294,7 +308,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check for padding
|
||||
self.assert_padding(tokenizer_r, tokenizer_p)
|
||||
@@ -335,12 +349,26 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
# Check alignment for build_inputs_with_special_tokens
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assertRaises(ValueError, self.assert_padding, tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
# TransfoXL tokenizers comes in a special format which is not compatible at all
|
||||
# with rust tokenizers. We ensure the errors detection at correctly raised
|
||||
tokenizer_r_files = tokenizer_r.save_pretrained(".")
|
||||
self.assertSequenceEqual(
|
||||
tokenizer_r_files, ["./vocab.json", "./special_tokens_map.json", "./added_tokens.json"]
|
||||
)
|
||||
|
||||
# Check loading Python-tokenizer save through Rust doesnt work (and the opposite)
|
||||
self.assertRaises(ValueError, tokenizer_p.from_pretrained, *tokenizer_r_files)
|
||||
self.assertRaises(ValueError, tokenizer_r.from_pretrained, *tokenizer_p.save_pretrained("."))
|
||||
|
||||
# Check loading works for Python to Python and Rust to Rust
|
||||
# Issue: https://github.com/huggingface/transformers/issues/3000
|
||||
# self.assertIsNotNone(tokenizer_p.__class__.from_pretrained('./'))
|
||||
self.assertIsNotNone(tokenizer_r.__class__.from_pretrained("./"))
|
||||
|
||||
def test_distilbert(self):
|
||||
for tokenizer_name in DistilBertTokenizer.pretrained_vocab_files_map["vocab_file"].keys():
|
||||
tokenizer_p = DistilBertTokenizer.from_pretrained(tokenizer_name)
|
||||
@@ -378,7 +406,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check for padding
|
||||
self.assert_padding(tokenizer_r, tokenizer_p)
|
||||
@@ -419,7 +447,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check for padding
|
||||
self.assertRaises(ValueError, self.assert_padding, tokenizer_r, tokenizer_p)
|
||||
@@ -460,7 +488,7 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check for padding
|
||||
# TODO: Re-enable this test as soon as Roberta align with the python tokenizer.
|
||||
@@ -501,12 +529,10 @@ class FastTokenizerMatchingTest(unittest.TestCase):
|
||||
# Check alignment for build_inputs_with_special_tokens
|
||||
self.assert_build_inputs_with_special_tokens(tokenizer_r, tokenizer_p)
|
||||
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assertEqual(len(tokenizer_r.save_vocabulary(".")), len(tokenizer_p.save_vocabulary(".")))
|
||||
|
||||
# Check for padding
|
||||
self.assertRaises(ValueError, self.assert_padding, tokenizer_r, tokenizer_p)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
# Check the number of returned files for save_vocabulary
|
||||
self.assert_save_pretrained(tokenizer_r, tokenizer_p)
|
||||
Reference in new issue
Block a user