Compare commits
162
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 thomwolf |
a40dd4ae86 | ||
|
thomwolf
|
ac8575ca5c | ||
|
thomwolf
|
ead691983b | ||
|
Julien Chaumond
|
73028c5df0 | ||
|
Timo Moeller
|
81fb8d3251 | ||
|
Julien ChaumondandIlias Chalkidis
|
4e69104a1f | ||
|
Julien ChaumondandYves Peirsman
|
73d79d42b4 | ||
|
Yves Peirsman
|
47b735f994 | ||
|
Julien Chaumond
|
7d22fefd37 | ||
|
Manuel Romero
|
61a2b7dc9d | ||
|
Ilias Chalkidis
|
6e261d3a22 | ||
|
Manuel Romero
|
4e597c8e4d | ||
|
Julien Chaumond
|
925a13ced1 | ||
|
Manuel Romero
|
575a3b7aa1 | ||
|
Julien Chaumond
|
4d36472b96 | ||
|
Ilias Chalkidis
|
8514018300 | ||
|
Ilias Chalkidis
|
1eec69a900 | ||
|
Felix MIKAELIANandJulien Chaumond
|
8744402f1e | ||
|
Severin SimmlerandJulien Chaumond
|
7f98edd7e3 | ||
|
Joe Davison
|
f1e8a51f08 | ||
|
Sam Shleifer
|
0ed630f139 | ||
|
Sam Shleifer
|
ef74b0f07a | ||
|
Lysandre
|
f54a5bd37f | ||
|
Lysandre
|
569897ce2c | ||
|
Julien Chaumond
|
21da895013 | ||
|
Julien Chaumond
|
9a70910d47 | ||
|
Julien Chaumond
|
9274734a0d | ||
|
Manuel Romero
|
69f948461f | ||
|
Julien Chaumond
|
e0b6247cf7 | ||
|
sshleifer
|
5f2dd71d1b | ||
|
sshleifer
|
31158af57c | ||
|
sshleifer
|
5dd61fb9a9 | ||
|
Oleksiy Syvokon
|
ee5de0ba44 | ||
|
jiyeon
|
bed38d3afe | ||
|
Stefan Schweter
|
498d06e914 | ||
|
Funtowicz Morgan
|
3e3a9e2c01 | ||
|
Julien Chaumond
|
1f5db9a13c | ||
|
Julien Chaumond
|
95bac8dabb | ||
|
ahotrodandJulien Chaumond
|
ba498eac38 | ||
|
Malte Pietsch
|
68ccc04ee6 | ||
|
Lysandre
|
539f601be7 | ||
|
Lysandre
|
cfb7d108bd | ||
|
Julien ChaumondandKevin Canwen Xu
|
b4691a438d | ||
|
Julien Chaumond
|
fc325e97cd | ||
|
Lysandre
|
fd639e5be3 | ||
|
Julien Chaumond
|
63a5399bc4 | ||
|
Lysandre
|
125a75a121 | ||
|
Malte Pietsch
|
9c64d1da35 | ||
|
Kevin Canwen Xu
|
bf99014c46 | ||
|
Thomas Wolf
|
92e974196f | ||
|
Morgan Funtowicz
|
6aa7973aec | ||
|
Lysandre
|
520e7f2119 | ||
|
Lysandre
|
dd28830327 | ||
|
Lysandre
|
db97930122 | ||
|
Lysandre
|
7046de2991 | ||
|
VictorSanh
|
0d3aa3c04c | ||
|
VictorSanh
|
d8b43600fd | ||
|
VictorSanh
|
ee5a6856ca | ||
|
monologg
|
73368963b2 | ||
|
Ari
|
d7dabfeff5 | ||
|
Julien Chaumond
|
42f08e596f | ||
|
Julien Chaumond
|
4f7bdb0958 | ||
|
thomwolf
|
c6c5c3fd4e | ||
|
thomwolf
|
961c69776f | ||
|
thomwolf
|
d311f87bca | ||
|
thomwolf
|
7d99e05f76 | ||
|
dchurchwell
|
2c12464a20 | ||
|
Peter Izsak
|
6fc3d34abd | ||
|
Julien Chaumond
|
7748cbbe7d | ||
|
Julien Chaumond
|
432c12521e | ||
|
Clement
|
c069932f5d | ||
|
Lysandre Debut
|
33d3072e1c | ||
|
Julien Chaumond
|
eae8ee0389 | ||
|
James Betker
|
6bb6a01765 | ||
|
Julien ChaumondandLysandre Debut
|
ada24def22 | ||
|
Lysandre
|
2184f87003 | ||
|
Lysandre
|
e615269cb8 | ||
|
Lysandre
|
5f96ebc0be | ||
|
Lysandre
|
950c6a4f09 | ||
|
Lysandre
|
d28b81dc29 | ||
|
Yuval Pinter
|
d1ab1fab1b | ||
|
sshleifer
|
9e5b549b4d | ||
|
sshleifer
|
25848a6094 | ||
|
sshleifer
|
cbcb83f21d | ||
|
Lysandre
|
3bf5417258 | ||
|
Lysandre
|
1ebfeb7946 | ||
|
Lysandre
|
9c67196b83 | ||
|
Lysandre
|
90ab15cb7a | ||
|
Julien Chaumond
|
9a50828b5c | ||
|
Lysandre
|
6c1b23554f | ||
|
Lysandre
|
239dd23f64 | ||
|
Martin Malmsten
|
522c5b5533 | ||
|
Julien Plu
|
9329e59700 | ||
|
Antonio Carlos Falcão Petri
|
2ba147ecff | ||
|
Bram Vanroy
|
9773e5e0d9 | ||
|
Julien ChaumondandStefan Schweter
|
ddb6f9476b | ||
|
Julien ChaumondandHenrykBorzymowski
|
6636826f04 | ||
|
|
98dadc98e1 | ||
|
Julien Chaumond
|
d6fc34b459 | ||
|
Lysandre
|
d426b58b9e | ||
|
Lysandre
|
1e82cd8457 | ||
|
Lysandre
|
d18d47be67 | ||
|
Lysandre
|
ff6f1492e8 | ||
|
Lysandre
|
7365f01d43 | ||
|
Arnaud
|
3a21d6da6b | ||
|
Lysandre
|
0aa40e9569 | ||
|
Lysandre
|
8036ceb7c5 | ||
|
Lysandre
|
6664ea943d | ||
|
Julien Chaumond
|
5a6b138b00 | ||
|
Julien Chaumond
|
7fe294bf07 | ||
|
Julien Chaumond
|
b85c59f997 | ||
|
Julien Chaumond
|
f9bc3f5771 | ||
|
Julien Chaumond
|
0b13fb822a | ||
|
Jared Nielsen
|
71a382319f | ||
|
Lysandre
|
01a14ebd8d | ||
|
Julien Chaumond
|
9fa836a73f | ||
|
Hang Le
|
b43cb09aaa | ||
|
Lysandre
|
df27648bd9 | ||
|
Lysandre
|
93dccf527b | ||
|
Lysandre
|
90787fed81 | ||
|
Lysandre
|
73306d028b | ||
|
Lysandre
|
ce2f4227ab | ||
|
Hang Le
|
f0a4fc6cd6 | ||
|
Peter Izsak
|
a5381495e6 | ||
|
Bram Vanroy
|
83446a88d9 | ||
|
BramVanroy
|
9fde13a3ac | ||
|
Lysandre
|
e63a81dd25 | ||
|
Lysandre
|
217349016a | ||
|
Jared Nielsen
|
adb8c93134 | ||
|
Lysandre
|
c69b082601 | ||
|
Julien Plu
|
ca1d66734d | ||
|
Julien Plu
|
5e3c72842d | ||
|
Julien Plu
|
0731fa1587 | ||
|
Julien Plu
|
a3998e76ae | ||
|
Lysandre
|
b5625f131d | ||
|
Lysandre
|
44a5b4bbe7 | ||
|
Julien Plu
|
7fc628d98e | ||
|
Julien Plu
|
64ca855617 | ||
|
BramVanroy
|
9d87eafd11 | ||
|
BramVanroy
|
a3b3638f6f | ||
|
BramVanroy
|
c96ca70f25 | ||
|
BramVanroy
|
7b5eda32bb | ||
|
BramVanroy
|
c63d91dd1c | ||
|
BramVanroy
|
b2907cd06e | ||
|
BramVanroy
|
2fec88ee02 | ||
|
BramVanroy
|
7e03d2bd7c | ||
|
Lysandre
|
335dd5e68a | ||
|
Lysandre
|
ea2600bd5f | ||
|
Wietse de Vries
|
5c3d441ee1 | ||
|
Wietse de Vries
|
f5a236c3ca | ||
|
Julien Chaumond
|
6b4c3ee234 | ||
|
Julien Chaumond
|
79815bf666 | ||
|
Julien Chaumond
|
5004d5af42 | ||
|
Lysandre
|
9ca21c838b | ||
|
thomwolf
|
e0849a66ac | ||
|
thomwolf
|
6b081f04e6 | ||
|
thomwolf
|
0e31e06a75 | ||
|
Julien Chaumond
|
ea56d305be | ||
|
Malte Pietsch
|
d440e21f5b | ||
|
Lysandre
|
875c4ae48f | ||
|
Lysandre
|
f09f42d4d3 | ||
|
Maksym Del
|
bac51fba3a |
@@ -10,7 +10,7 @@ jobs:
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[sklearn,tf,torch,testing]
|
||||
- run: sudo pip install .[sklearn,tf-cpu,torch,testing]
|
||||
- run: sudo pip install codecov pytest-cov
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/ --cov
|
||||
- run: codecov
|
||||
@@ -26,8 +26,10 @@ jobs:
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[mecab,sklearn,tf,torch,testing]
|
||||
- run: sudo pip install .[mecab,sklearn,tf-cpu,torch,testing]
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/
|
||||
- no_output_timeout: 4h
|
||||
|
||||
run_tests_torch:
|
||||
working_directory: ~/transformers
|
||||
docker:
|
||||
@@ -52,7 +54,7 @@ jobs:
|
||||
parallelism: 1
|
||||
steps:
|
||||
- checkout
|
||||
- run: sudo pip install .[sklearn,tf,testing]
|
||||
- run: sudo pip install .[sklearn,tf-cpu,testing]
|
||||
- run: sudo pip install codecov pytest-cov
|
||||
- run: python -m pytest -n 8 --dist=loadfile -s -v ./tests/ --cov
|
||||
- run: codecov
|
||||
|
||||
+3
-2
@@ -3,7 +3,7 @@ cd docs
|
||||
function deploy_doc(){
|
||||
echo "Creating doc at commit $1 and pushing to folder $2"
|
||||
git checkout $1
|
||||
if [ ! -z "$2" ]
|
||||
if [ ! -z "$2" ]
|
||||
then
|
||||
if [ -d "$dir/$2" ]; then
|
||||
echo "Directory" $2 "already exists"
|
||||
@@ -17,7 +17,7 @@ function deploy_doc(){
|
||||
fi
|
||||
}
|
||||
|
||||
deploy_doc "master"
|
||||
deploy_doc "master"
|
||||
deploy_doc "b33a385" v1.0.0
|
||||
deploy_doc "fe02e45" v1.1.0
|
||||
deploy_doc "89fd345" v1.2.0
|
||||
@@ -25,3 +25,4 @@ deploy_doc "fc9faa8" v2.0.0
|
||||
deploy_doc "3ddce1d" v2.1.1
|
||||
deploy_doc "3616209" v2.2.0
|
||||
deploy_doc "d0f8b9a" v2.3.0
|
||||
deploy_doc "6664ea9" v2.4.0
|
||||
@@ -1,17 +1,17 @@
|
||||
---
|
||||
name: "\U0001F5A5 New Benchmark"
|
||||
about: You benchmark a part of this library and would like to share your results
|
||||
name: "\U0001F5A5 New benchmark"
|
||||
about: Benchmark a part of this library and share your results
|
||||
title: "[Benchmark]"
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
# Benchmarking Transformers
|
||||
# 🖥 Benchmarking `transformers`
|
||||
|
||||
## Benchmark
|
||||
|
||||
Which part of Transformers did you benchmark?
|
||||
Which part of `transformers` did you benchmark?
|
||||
|
||||
## Set-up
|
||||
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
---
|
||||
name: "\U0001F31FNew model addition"
|
||||
name: "\U0001F31F New model addition"
|
||||
about: Submit a proposal/request to implement a new Transformer-based model
|
||||
title: ''
|
||||
labels: ''
|
||||
@@ -7,18 +7,14 @@ assignees: ''
|
||||
|
||||
---
|
||||
|
||||
# 🌟New model addition
|
||||
# 🌟 New model addition
|
||||
|
||||
## Model description
|
||||
|
||||
<!-- Important information -->
|
||||
|
||||
## Open Source status
|
||||
## Open source status
|
||||
|
||||
* [ ] the model implementation is available: (give details)
|
||||
* [ ] the model weights are available: (give details)
|
||||
* [ ] who are the authors: (mention them)
|
||||
|
||||
## Additional context
|
||||
|
||||
<!-- Add any other context about the problem here. -->
|
||||
* [ ] who are the authors: (mention them, if possible by @gh-username)
|
||||
|
||||
@@ -1,29 +1,29 @@
|
||||
---
|
||||
name: "\U0001F41B Bug Report"
|
||||
about: Submit a bug report to help us improve PyTorch Transformers
|
||||
about: Submit a bug report to help us improve transformers
|
||||
title: ''
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
## 🐛 Bug
|
||||
# 🐛 Bug
|
||||
|
||||
<!-- Important information -->
|
||||
## Information
|
||||
|
||||
Model I am using (Bert, XLNet....):
|
||||
Model I am using (Bert, XLNet ...):
|
||||
|
||||
Language I am using the model on (English, Chinese....):
|
||||
Language I am using the model on (English, Chinese ...):
|
||||
|
||||
The problem arise when using:
|
||||
* [ ] the official example scripts: (give details)
|
||||
* [ ] my own modified scripts: (give details)
|
||||
The problem arises when using:
|
||||
* [ ] the official example scripts: (give details below)
|
||||
* [ ] my own modified scripts: (give details below)
|
||||
|
||||
The tasks I am working on is:
|
||||
* [ ] an official GLUE/SQUaD task: (give the name)
|
||||
* [ ] my own task or dataset: (give details)
|
||||
* [ ] my own task or dataset: (give details below)
|
||||
|
||||
## To Reproduce
|
||||
## To reproduce
|
||||
|
||||
Steps to reproduce the behavior:
|
||||
|
||||
@@ -31,22 +31,22 @@ Steps to reproduce the behavior:
|
||||
2.
|
||||
3.
|
||||
|
||||
<!-- If you have a code sample, error messages, stack traces, please provide it here as well. -->
|
||||
<!-- If you have code snippets, error messages, stack traces please provide them here as well.
|
||||
Important! Use code tags to correctly format your code. See https://help.github.com/en/github/writing-on-github/creating-and-highlighting-code-blocks#syntax-highlighting
|
||||
Do not use screenshots, as they are hard to read and (more importantly) don't allow others to copy-and-paste your code.-->
|
||||
|
||||
## Expected behavior
|
||||
|
||||
<!-- A clear and concise description of what you expected to happen. -->
|
||||
<!-- A clear and concise description of what you would expect to happen. -->
|
||||
|
||||
## Environment
|
||||
|
||||
* OS:
|
||||
* Python version:
|
||||
* PyTorch version:
|
||||
* PyTorch Transformers version (or branch):
|
||||
* Using GPU ?
|
||||
* Distributed or parallel setup ?
|
||||
* Any other relevant information:
|
||||
|
||||
## Additional context
|
||||
|
||||
<!-- Add any other context about the problem here. -->
|
||||
## Environment info
|
||||
<!-- You can run the command `python transformers-cli env` and copy-and-paste its output below.
|
||||
Don't forget to fill out the missing fields in that output! -->
|
||||
|
||||
- `transformers` version:
|
||||
- Platform:
|
||||
- Python version:
|
||||
- PyTorch version (GPU?):
|
||||
- Tensorflow version (GPU?):
|
||||
- Using GPU in script?:
|
||||
- Using distributed or parallel set-up in script?:
|
||||
|
||||
@@ -1,20 +1,25 @@
|
||||
---
|
||||
name: "\U0001F680 Feature Request"
|
||||
about: Submit a proposal/request for a new PyTorch Transformers feature
|
||||
name: "\U0001F680 Feature request"
|
||||
about: Submit a proposal/request for a new transformers feature
|
||||
title: ''
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
## 🚀 Feature
|
||||
# 🚀 Feature request
|
||||
|
||||
<!-- A clear and concise description of the feature proposal. Please provide a link to the paper and code in case they exist. -->
|
||||
<!-- A clear and concise description of the feature proposal.
|
||||
Please provide a link to the paper and code in case they exist. -->
|
||||
|
||||
## Motivation
|
||||
|
||||
<!-- Please outline the motivation for the proposal. Is your feature request related to a problem? e.g., I'm always frustrated when [...]. If this is related to another GitHub issue, please link here too. -->
|
||||
<!-- Please outline the motivation for the proposal. Is your feature request
|
||||
related to a problem? e.g., I'm always frustrated when [...]. If this is related
|
||||
to another GitHub issue, please link here too. -->
|
||||
|
||||
## Additional context
|
||||
## Your contribution
|
||||
|
||||
<!-- Add any other context or screenshots about the feature request here. -->
|
||||
<!-- Is there any way that you could help, e.g. by submitting a PR?
|
||||
Make sure to read the CONTRIBUTING.MD readme:
|
||||
https://github.com/huggingface/transformers/blob/master/CONTRIBUTING.md -->
|
||||
|
||||
@@ -1,47 +1,57 @@
|
||||
---
|
||||
name: "\U0001F4DA Migration from PyTorch-pretrained-Bert"
|
||||
about: Report a problem when migrating from PyTorch-pretrained-Bert to Transformers
|
||||
name: "\U0001F4DA Migration from pytorch-pretrained-bert or pytorch-transformers"
|
||||
about: Report a problem when migrating from pytorch-pretrained-bert or pytorch-transformers to transformers
|
||||
title: ''
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
## 📚 Migration
|
||||
# 📚 Migration
|
||||
|
||||
## Information
|
||||
|
||||
<!-- Important information -->
|
||||
|
||||
Model I am using (Bert, XLNet....):
|
||||
Model I am using (Bert, XLNet ...):
|
||||
|
||||
Language I am using the model on (English, Chinese....):
|
||||
Language I am using the model on (English, Chinese ...):
|
||||
|
||||
The problem arise when using:
|
||||
* [ ] the official example scripts: (give details)
|
||||
* [ ] my own modified scripts: (give details)
|
||||
The problem arises when using:
|
||||
* [ ] the official example scripts: (give details below)
|
||||
* [ ] my own modified scripts: (give details below)
|
||||
|
||||
The tasks I am working on is:
|
||||
* [ ] an official GLUE/SQUaD task: (give the name)
|
||||
* [ ] my own task or dataset: (give details)
|
||||
* [ ] my own task or dataset: (give details below)
|
||||
|
||||
Details of the issue:
|
||||
## Details
|
||||
|
||||
<!-- A clear and concise description of the migration issue. If you have code snippets, please provide it here as well. -->
|
||||
<!-- A clear and concise description of the migration issue.
|
||||
If you have code snippets, please provide it here as well.
|
||||
Important! Use code tags to correctly format your code. See https://help.github.com/en/github/writing-on-github/creating-and-highlighting-code-blocks#syntax-highlighting
|
||||
Do not use screenshots, as they are hard to read and (more importantly) don't allow others to copy-and-paste your code.
|
||||
-->
|
||||
|
||||
## Environment
|
||||
## Environment info
|
||||
<!-- You can run the command `python transformers-cli env` and copy-and-paste its output below.
|
||||
Don't forget to fill out the missing fields in that output! -->
|
||||
|
||||
- `transformers` version:
|
||||
- Platform:
|
||||
- Python version:
|
||||
- PyTorch version (GPU?):
|
||||
- Tensorflow version (GPU?):
|
||||
- Using GPU in script?:
|
||||
- Using distributed or parallel set-up in script?:
|
||||
|
||||
<!-- IMPORTANT: which version of the former library do you use? -->
|
||||
* `pytorch-transformers` or `pytorch-pretrained-bert` version (or branch):
|
||||
|
||||
* OS:
|
||||
* Python version:
|
||||
* PyTorch version:
|
||||
* PyTorch Transformers version (or branch):
|
||||
* Using GPU ?
|
||||
* Distributed or parallel setup ?
|
||||
* Any other relevant information:
|
||||
|
||||
## Checklist
|
||||
|
||||
- [ ] I have read the migration guide in the readme.
|
||||
([pytorch-transformers](https://github.com/huggingface/transformers#migrating-from-pytorch-transformers-to-transformers);
|
||||
[pytorch-pretrained-bert](https://github.com/huggingface/transformers#migrating-from-pytorch-pretrained-bert-to-transformers))
|
||||
- [ ] I checked if a related official extension example runs on my machine.
|
||||
|
||||
## Additional context
|
||||
|
||||
<!-- Add any other context about the problem here. -->
|
||||
|
||||
@@ -1,12 +1,29 @@
|
||||
---
|
||||
name: "❓Questions & Help"
|
||||
about: Start a general discussion related to PyTorch Transformers
|
||||
name: "❓ Questions & Help"
|
||||
about: Post your general questions on Stack Overflow tagged huggingface-transformers
|
||||
title: ''
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
## ❓ Questions & Help
|
||||
# ❓ Questions & Help
|
||||
|
||||
<!-- A clear and concise description of the question. -->
|
||||
<!-- The GitHub issue tracker is primarly intended for bugs, feature requests,
|
||||
new models and benchmarks, and migration questions. For all other questions,
|
||||
we direct you to Stack Overflow (SO) where a whole community of PyTorch and
|
||||
Tensorflow enthusiast can help you out. Make sure to tag your question with the
|
||||
right deep learning framework as well as the huggingface-transformers tag:
|
||||
https://stackoverflow.com/questions/tagged/huggingface-transformers
|
||||
|
||||
If your question wasn't answered after a period of time on Stack Overflow, you
|
||||
can always open a question on GitHub. You should then link to the SO question
|
||||
that you posted.
|
||||
-->
|
||||
|
||||
## Details
|
||||
<!-- Description of your issue -->
|
||||
|
||||
<!-- You should first ask your question on SO, and only if
|
||||
you didn't get an answer ask it here on GitHub. -->
|
||||
**A link to original question on Stack Overflow**:
|
||||
+8
-10
@@ -41,14 +41,10 @@ Did not find it? :( So we can act quickly on it, please follow these steps:
|
||||
less than 30s;
|
||||
* Provide the *full* traceback if an exception is raised.
|
||||
|
||||
To get the OS and software versions, execute the following code and copy-paste
|
||||
the output:
|
||||
To get the OS and software versions automatically, you can run the following command:
|
||||
|
||||
```
|
||||
import platform; print("Platform", platform.platform())
|
||||
import sys; print("Python", sys.version)
|
||||
import torch; print("PyTorch", torch.__version__)
|
||||
import tensorflow; print("Tensorflow", tensorflow.__version__)
|
||||
```bash
|
||||
python transformers-cli env
|
||||
```
|
||||
|
||||
### Do you want to implement a new model?
|
||||
@@ -202,11 +198,13 @@ Follow these steps to start contributing:
|
||||
3. To indicate a work in progress please prefix the title with `[WIP]`. These
|
||||
are useful to avoid duplicated work, and to differentiate it from PRs ready
|
||||
to be merged;
|
||||
4. Make sure pre-existing tests still pass;
|
||||
5. Add high-coverage tests. No quality test, no merge;
|
||||
4. Make sure existing tests pass;
|
||||
5. Add high-coverage tests. No quality test, no merge.
|
||||
- If you are adding a new model, make sure that you use `ModelTester.all_model_classes = (MyModel, MyModelWithLMHead,...)`, which triggers the common tests.
|
||||
- If you are adding new `@slow` tests, make sure they pass using `RUN_SLOW=1 python -m pytest tests/test_my_new_model.py`.
|
||||
CircleCI does not run them.
|
||||
6. All public methods must have informative docstrings;
|
||||
|
||||
|
||||
### Tests
|
||||
|
||||
You can run 🤗 Transformers tests with `unittest` or `pytest`.
|
||||
|
||||
@@ -24,6 +24,8 @@
|
||||
|
||||
🤗 Transformers (formerly known as `pytorch-transformers` and `pytorch-pretrained-bert`) provides state-of-the-art general-purpose architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet, CTRL...) for Natural Language Understanding (NLU) and Natural Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between TensorFlow 2.0 and PyTorch.
|
||||
|
||||
[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/0)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/1)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/2)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/3)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/4)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/5)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/6)[](https://sourcerer.io/fame/clmnt/huggingface/transformers/links/7)
|
||||
|
||||
### Features
|
||||
|
||||
- As easy to use as pytorch-transformers
|
||||
@@ -60,7 +62,7 @@ Choose the right framework for every part of a model's lifetime
|
||||
| [Quick tour: Share your models ](#Quick-tour-of-model-sharing) | Upload and share your fine-tuned models with the community |
|
||||
| [Migrating from pytorch-transformers to transformers](#Migrating-from-pytorch-transformers-to-transformers) | Migrating your code from pytorch-transformers to transformers |
|
||||
| [Migrating from pytorch-pretrained-bert to pytorch-transformers](#Migrating-from-pytorch-pretrained-bert-to-transformers) | Migrating your code from pytorch-pretrained-bert to transformers |
|
||||
| [Documentation][(v2.3.0)](https://huggingface.co/transformers/v2.3.0)[(v2.2.0/v2.2.1/v2.2.2)](https://huggingface.co/transformers/v2.2.0) [(v2.1.1)](https://huggingface.co/transformers/v2.1.1) [(v2.0.0)](https://huggingface.co/transformers/v2.0.0) [(v1.2.0)](https://huggingface.co/transformers/v1.2.0) [(v1.1.0)](https://huggingface.co/transformers/v1.1.0) [(v1.0.0)](https://huggingface.co/transformers/v1.0.0) [(master)](https://huggingface.co/transformers) | Full API documentation and more |
|
||||
| [Documentation][(v2.4.0)](https://huggingface.co/transformers/v2.4.0)[(v2.3.0)](https://huggingface.co/transformers/v2.3.0)[(v2.2.0/v2.2.1/v2.2.2)](https://huggingface.co/transformers/v2.2.0) [(v2.1.1)](https://huggingface.co/transformers/v2.1.1) [(v2.0.0)](https://huggingface.co/transformers/v2.0.0) [(v1.2.0)](https://huggingface.co/transformers/v1.2.0) [(v1.1.0)](https://huggingface.co/transformers/v1.1.0) [(v1.0.0)](https://huggingface.co/transformers/v1.0.0) [(master)](https://huggingface.co/transformers) | Full API documentation and more |
|
||||
|
||||
## Installation
|
||||
|
||||
@@ -160,8 +162,9 @@ At some point in the future, you'll be able to seamlessly move from pre-training
|
||||
12. **[T5](https://github.com/google-research/text-to-text-transfer-transformer)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
|
||||
13. **[XLM-RoBERTa](https://github.com/pytorch/fairseq/tree/master/examples/xlmr)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
|
||||
14. **[MMBT](https://github.com/facebookresearch/mmbt/)** (from Facebook), released together with the paper a [Supervised Multimodal Bitransformers for Classifying Images and Text](https://arxiv.org/pdf/1909.02950.pdf) by Douwe Kiela, Suvrat Bhooshan, Hamed Firooz, Davide Testuggine.
|
||||
15. **[Other community models](https://huggingface.co/models)**, contributed by the [community](https://huggingface.co/users).
|
||||
16. Want to contribute a new model? We have added a **detailed guide and templates** to guide you in the process of adding a new model. You can find them in the [`templates`](./templates) folder of the repository. Be sure to check the [contributing guidelines](./CONTRIBUTING.md) and contact the maintainers or open an issue to collect feedbacks before starting your PR.
|
||||
15. **[FlauBERT](https://github.com/getalp/Flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
|
||||
16. **[Other community models](https://huggingface.co/models)**, contributed by the [community](https://huggingface.co/users).
|
||||
17. Want to contribute a new model? We have added a **detailed guide and templates** to guide you in the process of adding a new model. You can find them in the [`templates`](./templates) folder of the repository. Be sure to check the [contributing guidelines](./CONTRIBUTING.md) and contact the maintainers or open an issue to collect feedbacks before starting your PR.
|
||||
|
||||
These implementations have been tested on several datasets (see the example scripts) and should match the performances of the original implementations (e.g. ~93 F1 on SQuAD for BERT Whole-Word-Masking, ~88 F1 on RocStories for OpenAI GPT, ~18.3 perplexity on WikiText 103 for Transformer-XL, ~0.916 Peason R coefficient on STS-B for XLNet). You can find more details on the performances in the Examples section of the [documentation](https://huggingface.co/transformers/examples.html).
|
||||
|
||||
@@ -192,7 +195,7 @@ MODELS = [(BertModel, BertTokenizer, 'bert-base-uncased'),
|
||||
(TransfoXLModel, TransfoXLTokenizer, 'transfo-xl-wt103'),
|
||||
(XLNetModel, XLNetTokenizer, 'xlnet-base-cased'),
|
||||
(XLMModel, XLMTokenizer, 'xlm-mlm-enfr-1024'),
|
||||
(DistilBertModel, DistilBertTokenizer, 'distilbert-base-uncased'),
|
||||
(DistilBertModel, DistilBertTokenizer, 'distilbert-base-cased'),
|
||||
(RobertaModel, RobertaTokenizer, 'roberta-base'),
|
||||
(XLMRobertaModel, XLMRobertaTokenizer, 'xlm-roberta-base'),
|
||||
]
|
||||
@@ -492,19 +495,22 @@ Your model will then be accessible through its identifier, a concatenation of yo
|
||||
"username/pretrained_model"
|
||||
```
|
||||
|
||||
**Please add a README.md model card** to the repo under `model_cards/` with: model description, training params (dataset, preprocessing, hyperparameters), evaluation results, intended uses & limitations, etc.
|
||||
|
||||
Your model now has a page on huggingface.co/models 🔥
|
||||
|
||||
Anyone can load it from code:
|
||||
```python
|
||||
tokenizer = AutoTokenizer.from_pretrained("username/pretrained_model")
|
||||
model = AutoModel.from_pretrained("username/pretrained_model")
|
||||
```
|
||||
|
||||
Finally, list all your files on S3:
|
||||
List all your files on S3:
|
||||
```shell
|
||||
transformers-cli s3 ls
|
||||
# List all your S3 objects.
|
||||
```
|
||||
|
||||
You can also delete files:
|
||||
You can also delete unneeded files:
|
||||
|
||||
```shell
|
||||
transformers-cli s3 rm …
|
||||
@@ -520,8 +526,9 @@ You can create `Pipeline` objects for the following down-stream tasks:
|
||||
- `feature-extraction`: Generates a tensor representation for the input sequence
|
||||
- `ner`: Generates named entity mapping for each word in the input sequence.
|
||||
- `sentiment-analysis`: Gives the polarity (positive / negative) of the whole input sequence.
|
||||
- `question-answering`: Provided some context and a question refering to the context, it will extract the answer to the question
|
||||
in the context.
|
||||
- `text-classification`: Initialize a `TextClassificationPipeline` directly, or see `sentiment-analysis` for an example.
|
||||
- `question-answering`: Provided some context and a question refering to the context, it will extract the answer to the question in the context.
|
||||
- `fill-mask`: Takes an input sequence containing a masked token (e.g. `<mask>`) and return list of most probable filled sequences, with their probabilities.
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
@@ -194,3 +194,41 @@ h2, .rst-content .toctree-wrapper p.caption, h3, h4, h5, h6, legend{
|
||||
src: url(./Calibre-Thin.otf);
|
||||
font-weight:400;
|
||||
}
|
||||
|
||||
|
||||
/**
|
||||
* Nav Links to other parts of huggingface.co
|
||||
*/
|
||||
div.menu {
|
||||
position: absolute;
|
||||
top: 0;
|
||||
right: 0;
|
||||
padding-top: 20px;
|
||||
padding-right: 20px;
|
||||
z-index: 1000;
|
||||
}
|
||||
div.menu a {
|
||||
font-size: 14px;
|
||||
letter-spacing: 0.3px;
|
||||
text-transform: uppercase;
|
||||
color: white;
|
||||
-webkit-font-smoothing: antialiased;
|
||||
background: linear-gradient(0deg, #6671ffb8, #9a66ffb8 50%);
|
||||
padding: 10px 16px 6px 16px;
|
||||
border-radius: 3px;
|
||||
margin-left: 12px;
|
||||
position: relative;
|
||||
}
|
||||
div.menu a:active {
|
||||
top: 1px;
|
||||
}
|
||||
@media (min-width: 768px) and (max-width: 1750px) {
|
||||
.wy-breadcrumbs {
|
||||
margin-top: 32px;
|
||||
}
|
||||
}
|
||||
@media (max-width: 768px) {
|
||||
div.menu {
|
||||
display: none;
|
||||
}
|
||||
}
|
||||
|
||||
@@ -58,6 +58,16 @@ function addGithubButton() {
|
||||
document.querySelector(".wy-side-nav-search .icon-home").insertAdjacentHTML('afterend', div);
|
||||
}
|
||||
|
||||
function addHfMenu() {
|
||||
const div = `
|
||||
<div class="menu">
|
||||
<a href="/welcome">🔥 Sign in</a>
|
||||
<a href="/models">🚀 Models</a>
|
||||
</div>
|
||||
`;
|
||||
document.body.insertAdjacentHTML('afterbegin', div);
|
||||
}
|
||||
|
||||
/*!
|
||||
* github-buttons v2.2.10
|
||||
* (c) 2019 なつき
|
||||
@@ -74,6 +84,7 @@ function onLoad() {
|
||||
addCustomFooter();
|
||||
addGithubButton();
|
||||
parseGithubButtons();
|
||||
addHfMenu();
|
||||
}
|
||||
|
||||
window.addEventListener("load", onLoad);
|
||||
|
||||
+1
-1
@@ -26,7 +26,7 @@ author = u'huggingface'
|
||||
# The short X.Y version
|
||||
version = u''
|
||||
# The full version, including alpha/beta/rc tags
|
||||
release = u'2.3.0'
|
||||
release = u'2.4.1'
|
||||
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
|
||||
@@ -51,6 +51,7 @@ The library currently contains PyTorch and Tensorflow implementations, pre-train
|
||||
10. `CamemBERT <https://huggingface.co/transformers/model_doc/camembert.html>`_ (from FAIR, Inria, Sorbonne Université) released together with the paper `CamemBERT: a Tasty French Language Model <https://arxiv.org/abs/1911.03894>`_ by Louis Martin, Benjamin Muller, Pedro Javier Ortiz Suarez, Yoann Dupont, Laurent Romary, Eric Villemonte de la Clergerie, Djame Seddah, and Benoît Sagot.
|
||||
11. `ALBERT <https://github.com/google-research/ALBERT>`_ (from Google Research), released together with the paper a `ALBERT: A Lite BERT for Self-supervised Learning of Language Representations <https://arxiv.org/abs/1909.11942>`_ by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
|
||||
12. `XLM-RoBERTa <https://github.com/pytorch/fairseq/tree/master/examples/xlmr>`_ (from Facebook AI), released together with the paper `Unsupervised Cross-lingual Representation Learning at Scale <https://arxiv.org/abs/1911.02116>`_ by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
|
||||
13. `FlauBERT <https://github.com/getalp/Flaubert>`_ (from CNRS) released with the paper `FlauBERT: Unsupervised Language Model Pre-training for French <https://arxiv.org/abs/1912.05372>`_ by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
|
||||
|
||||
.. toctree::
|
||||
:maxdepth: 2
|
||||
@@ -97,4 +98,5 @@ The library currently contains PyTorch and Tensorflow implementations, pre-train
|
||||
model_doc/ctrl
|
||||
model_doc/camembert
|
||||
model_doc/albert
|
||||
model_doc/xlmroberta
|
||||
model_doc/xlmroberta
|
||||
model_doc/flaubert
|
||||
@@ -63,7 +63,7 @@ XNLI
|
||||
`The Cross-Lingual NLI Corpus (XNLI) <https://www.nyu.edu/projects/bowman/xnli/>`__ is a benchmark that evaluates
|
||||
the quality of cross-lingual text representations.
|
||||
XNLI is crowd-sourced dataset based on `MultiNLI <http://www.nyu.edu/projects/bowman/multinli/>`: pairs of text are labeled with textual entailment
|
||||
annotations for 15 different languages (including both high-ressource language such as English and low-ressource languages such as Swahili).
|
||||
annotations for 15 different languages (including both high-resource language such as English and low-resource languages such as Swahili).
|
||||
|
||||
It was released together with the paper
|
||||
`XNLI: Evaluating Cross-lingual Sentence Representations <https://arxiv.org/abs/1809.05053>`__
|
||||
|
||||
@@ -29,6 +29,13 @@ Instantiating one of ``AutoModel``, ``AutoConfig`` and ``AutoTokenizer`` will di
|
||||
:members:
|
||||
|
||||
|
||||
``AutoModelForPreTraining``
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.AutoModelForPreTraining
|
||||
:members:
|
||||
|
||||
|
||||
``AutoModelWithLMHead``
|
||||
~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
|
||||
@@ -69,3 +69,31 @@ CamembertForTokenClassification
|
||||
|
||||
.. autoclass:: transformers.CamembertForTokenClassification
|
||||
:members:
|
||||
|
||||
|
||||
TFCamembertModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFCamembertModel
|
||||
:members:
|
||||
|
||||
|
||||
TFCamembertForMaskedLM
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFCamembertForMaskedLM
|
||||
:members:
|
||||
|
||||
|
||||
TFCamembertForSequenceClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFCamembertForSequenceClassification
|
||||
:members:
|
||||
|
||||
|
||||
TFCamembertForTokenClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFCamembertForTokenClassification
|
||||
:members:
|
||||
|
||||
@@ -0,0 +1,72 @@
|
||||
FlauBERT
|
||||
----------------------------------------------------
|
||||
|
||||
The FlauBERT model was proposed in the paper
|
||||
`FlauBERT: Unsupervised Language Model Pre-training for French <https://arxiv.org/abs/1912.05372>`__ by Hang Le et al.
|
||||
It's a transformer pre-trained using a masked language modeling (MLM) objective (BERT-like).
|
||||
|
||||
The abstract from the paper is the following:
|
||||
|
||||
*Language models have become a key step to achieve state-of-the art results in many different Natural Language
|
||||
Processing (NLP) tasks. Leveraging the huge amount of unlabeled texts nowadays available, they provide an efficient
|
||||
way to pre-train continuous word representations that can be fine-tuned for a downstream task, along with their
|
||||
contextualization at the sentence level. This has been widely demonstrated for English using contextualized
|
||||
representations (Dai and Le, 2015; Peters et al., 2018; Howard and Ruder, 2018; Radford et al., 2018; Devlin et
|
||||
al., 2019; Yang et al., 2019b). In this paper, we introduce and share FlauBERT, a model learned on a very large
|
||||
and heterogeneous French corpus. Models of different sizes are trained using the new CNRS (French National Centre
|
||||
for Scientific Research) Jean Zay supercomputer. We apply our French language models to diverse NLP tasks (text
|
||||
classification, paraphrasing, natural language inference, parsing, word sense disambiguation) and show that most
|
||||
of the time they outperform other pre-training approaches. Different versions of FlauBERT as well as a unified
|
||||
evaluation protocol for the downstream tasks, called FLUE (French Language Understanding Evaluation), are shared
|
||||
to the research community for further reproducible experiments in French NLP.*
|
||||
|
||||
|
||||
FlaubertConfig
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertConfig
|
||||
:members:
|
||||
|
||||
|
||||
FlaubertTokenizer
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertTokenizer
|
||||
:members:
|
||||
|
||||
|
||||
FlaubertModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertModel
|
||||
:members:
|
||||
|
||||
|
||||
FlaubertWithLMHeadModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertWithLMHeadModel
|
||||
:members:
|
||||
|
||||
|
||||
FlaubertForSequenceClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertForSequenceClassification
|
||||
:members:
|
||||
|
||||
|
||||
FlaubertForQuestionAnsweringSimple
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertForQuestionAnsweringSimple
|
||||
:members:
|
||||
|
||||
|
||||
FlaubertForQuestionAnswering
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.FlaubertForQuestionAnswering
|
||||
:members:
|
||||
|
||||
|
||||
@@ -23,6 +23,9 @@ Tips:
|
||||
|
||||
- This implementation is the same as :class:`~transformers.BertModel` with a tiny embeddings tweak as well as a
|
||||
setup for Roberta pretrained models.
|
||||
- RoBERTa has the same architecture as BERT, but uses a byte-level BPE as a tokenizer (same as GPT-2) and uses a
|
||||
different pre-training scheme.
|
||||
- RoBERTa doesn't have `token_type_ids`, you don't need to indicate which token belongs to which segment. Just separate your segments with the separation token `tokenizer.sep_token` (or `</s>`)
|
||||
- `Camembert <./camembert.html>`__ is a wrapper around RoBERTa. Refer to this page for usage examples.
|
||||
|
||||
RobertaConfig
|
||||
|
||||
@@ -22,6 +22,9 @@ and XNLI benchmarks. We will make XLM-R code, data, and models publicly availabl
|
||||
|
||||
Tips:
|
||||
|
||||
- XLM-R is a multilingual model trained on 100 different languages. Unlike some XLM multilingual models, it does
|
||||
not require `lang` tensors to understand which language is used, and should be able to determine the correct
|
||||
language from the input ids.
|
||||
- This implementation is the same as RoBERTa. Refer to the `documentation of RoBERTa <./roberta.html>`__ for usage
|
||||
examples as well as the information relative to the inputs and outputs.
|
||||
|
||||
@@ -73,3 +76,30 @@ XLMRobertaForTokenClassification
|
||||
.. autoclass:: transformers.XLMRobertaForTokenClassification
|
||||
:members:
|
||||
|
||||
|
||||
TFXLMRobertaModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFXLMRobertaModel
|
||||
:members:
|
||||
|
||||
|
||||
TFXLMRobertaForMaskedLM
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFXLMRobertaForMaskedLM
|
||||
:members:
|
||||
|
||||
|
||||
TFXLMRobertaForSequenceClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFXLMRobertaForSequenceClassification
|
||||
:members:
|
||||
|
||||
|
||||
TFXLMRobertaForTokenClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFXLMRobertaForTokenClassification
|
||||
:members:
|
||||
|
||||
@@ -26,19 +26,22 @@ Your model will then be accessible through its identifier, a concatenation of yo
|
||||
"username/pretrained_model"
|
||||
```
|
||||
|
||||
**Please add a README.md model card** to the repo under `model_cards/` with: model description, training params (dataset, preprocessing, hyperparameters), evaluation results, intended uses & limitations, etc.
|
||||
|
||||
Your model now has a page on huggingface.co/models 🔥
|
||||
|
||||
Anyone can load it from code:
|
||||
```python
|
||||
tokenizer = AutoTokenizer.from_pretrained("username/pretrained_model")
|
||||
model = AutoModel.from_pretrained("username/pretrained_model")
|
||||
```
|
||||
|
||||
Finally, list all your files on S3:
|
||||
List all your files on S3:
|
||||
```shell
|
||||
transformers-cli s3 ls
|
||||
# List all your S3 objects.
|
||||
```
|
||||
|
||||
You can also delete files:
|
||||
You can also delete unneeded files:
|
||||
|
||||
```shell
|
||||
transformers-cli s3 rm …
|
||||
|
||||
@@ -88,6 +88,10 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | ``bert-base-finnish-uncased-v1`` | | 12-layer, 768-hidden, 12-heads, 110M parameters. |
|
||||
| | | | Trained on uncased Finnish text. |
|
||||
| | | (see `details on turkunlp.org <http://turkunlp.org/FinBERT/>`__). |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``bert-base-dutch-cased`` | | 12-layer, 768-hidden, 12-heads, 110M parameters. |
|
||||
| | | | Trained on cased Dutch text. |
|
||||
| | | (see `details on wietsedv repository <https://github.com/wietsedv/bertje/>`__). |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| GPT | ``openai-gpt`` | | 12-layer, 768-hidden, 12-heads, 110M parameters. |
|
||||
| | | | OpenAI GPT English model |
|
||||
@@ -175,6 +179,14 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | | | The DistilBERT model distilled from the BERT model `bert-base-uncased` checkpoint, with an additional linear layer. |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``distilbert-base-cased`` | | 6-layer, 768-hidden, 12-heads, 65M parameters |
|
||||
| | | | The DistilBERT model distilled from the BERT model `bert-base-cased` checkpoint |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``distilbert-base-cased-distilled-squad`` | | 6-layer, 768-hidden, 12-heads, 65M parameters |
|
||||
| | | | The DistilBERT model distilled from the BERT model `bert-base-cased` checkpoint, with an additional question answering layer. |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``distilgpt2`` | | 6-layer, 768-hidden, 12-heads, 82M parameters |
|
||||
| | | | The DistilGPT2 model distilled from the GPT2 model `gpt2` checkpoint. |
|
||||
| | | (see `details <https://github.com/huggingface/transformers/tree/master/examples/distillation>`__) |
|
||||
@@ -247,6 +259,22 @@ For a list that includes community-uploaded models, refer to `https://huggingfac
|
||||
| | ``xlm-roberta-large`` | | ~355M parameters with 24-layers, 1027-hidden-state, 4096 feed-forward hidden-state, 16-heads, |
|
||||
| | | | Trained on 2.5 TB of newly created clean CommonCrawl data in 100 languages |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| FlauBERT | ``flaubert-small-cased`` | | 6-layer, 512-hidden, 8-heads, 54M parameters |
|
||||
| | | | FlauBERT small architecture |
|
||||
| | | (see `details <https://github.com/getalp/Flaubert>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``flaubert-base-uncased`` | | 12-layer, 768-hidden, 12-heads, 137M parameters |
|
||||
| | | | FlauBERT base architecture with uncased vocabulary |
|
||||
| | | (see `details <https://github.com/getalp/Flaubert>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``flaubert-base-cased`` | | 12-layer, 768-hidden, 12-heads, 138M parameters |
|
||||
| | | | FlauBERT base architecture with cased vocabulary |
|
||||
| | | (see `details <https://github.com/getalp/Flaubert>`__) |
|
||||
| +------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
| | ``flaubert-large-cased`` | | 24-layer, 1024-hidden, 16-heads, 373M parameters |
|
||||
| | | | FlauBERT large architecture |
|
||||
| | | (see `details <https://github.com/getalp/Flaubert>`__) |
|
||||
+-------------------+------------------------------------------------------------+---------------------------------------------------------------------------------------------------------------------------------------+
|
||||
|
||||
|
||||
.. <https://huggingface.co/transformers/examples.html>`__
|
||||
|
||||
@@ -209,7 +209,7 @@ past = None
|
||||
for i in range(100):
|
||||
print(i)
|
||||
output, past = model(context, past=past)
|
||||
token = torch.argmax(output[0, :])
|
||||
token = torch.argmax(output[..., -1, :])
|
||||
|
||||
generated += [token.tolist()]
|
||||
context = token.unsqueeze(0)
|
||||
@@ -299,8 +299,8 @@ model = Model2Model.from_pretrained('fine-tuned-weights')
|
||||
model.eval()
|
||||
|
||||
# If you have a GPU, put everything on cuda
|
||||
question_tensor = encoded_question.to('cuda')
|
||||
answer_tensor = encoded_answer.to('cuda')
|
||||
question_tensor = question_tensor.to('cuda')
|
||||
answer_tensor = answer_tensor.to('cuda')
|
||||
model.to('cuda')
|
||||
|
||||
# Predict all tokens
|
||||
|
||||
+22
-23
@@ -17,15 +17,14 @@ pip install -r ./examples/requirements.txt
|
||||
| Section | Description |
|
||||
|----------------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| [TensorFlow 2.0 models on GLUE](#TensorFlow-2.0-Bert-models-on-GLUE) | Examples running BERT TensorFlow 2.0 model on the GLUE tasks.
|
||||
| [Language Model fine-tuning](#language-model-fine-tuning) | Fine-tuning the library models for language modeling on a text dataset. Causal language modeling for GPT/GPT-2, masked language modeling for BERT/RoBERTa. |
|
||||
| [Language Generation](#language-generation) | Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, Transformer-XL and XLNet. |
|
||||
| [GLUE](#glue) | Examples running BERT/XLM/XLNet/RoBERTa on the 9 GLUE tasks. Examples feature distributed training as well as half-precision. |
|
||||
| [SQuAD](#squad) | Using BERT/RoBERTa/XLNet/XLM for question answering, examples with distributed training. |
|
||||
| [Multiple Choice](#multiple-choice) | Examples running BERT/XLNet/RoBERTa on the SWAG/RACE/ARC tasks.
|
||||
| [Named Entity Recognition](#named-entity-recognition) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [Language Model training](#language-model-training) | Fine-tuning (or training from scratch) the library models for language modeling on a text dataset. Causal language modeling for GPT/GPT-2, masked language modeling for BERT/RoBERTa. |
|
||||
| [Language Generation](#language-generation) | Conditional text generation using the auto-regressive models of the library: GPT, GPT-2, Transformer-XL and XLNet. |
|
||||
| [GLUE](#glue) | Examples running BERT/XLM/XLNet/RoBERTa on the 9 GLUE tasks. Examples feature distributed training as well as half-precision. |
|
||||
| [SQuAD](#squad) | Using BERT/RoBERTa/XLNet/XLM for question answering, examples with distributed training. |
|
||||
| [Multiple Choice](#multiple-choice) | Examples running BERT/XLNet/RoBERTa on the SWAG/RACE/ARC tasks. |
|
||||
| [Named Entity Recognition](#named-entity-recognition) | Using BERT for Named Entity Recognition (NER) on the CoNLL 2003 dataset, examples with distributed training. |
|
||||
| [XNLI](#xnli) | Examples running BERT/XLM on the XNLI benchmark. |
|
||||
| [Adversarial evaluation of model performances](#adversarial-evaluation-of-model-performances) | Testing a model with adversarial evaluation of natural language
|
||||
inference on the Heuristic Analysis for NLI Systems (HANS) dataset (McCoy et al., 2019.) |
|
||||
| [Adversarial evaluation of model performances](#adversarial-evaluation-of-model-performances) | Testing a model with adversarial evaluation of natural language inference on the Heuristic Analysis for NLI Systems (HANS) dataset (McCoy et al., 2019.) |
|
||||
|
||||
## TensorFlow 2.0 Bert models on GLUE
|
||||
|
||||
@@ -49,16 +48,16 @@ Quick benchmarks from the script (no other modifications):
|
||||
|
||||
Mixed precision (AMP) reduces the training time considerably for the same hardware and hyper-parameters (same batch size was used).
|
||||
|
||||
## Language model fine-tuning
|
||||
## Language model training
|
||||
|
||||
Based on the script [`run_lm_finetuning.py`](https://github.com/huggingface/transformers/blob/master/examples/run_lm_finetuning.py).
|
||||
Based on the script [`run_language_modeling.py`](https://github.com/huggingface/transformers/blob/master/examples/run_language_modeling.py).
|
||||
|
||||
Fine-tuning the library models for language modeling on a text dataset for GPT, GPT-2, BERT and RoBERTa (DistilBERT
|
||||
Fine-tuning (or training from scratch) the library models for language modeling on a text dataset for GPT, GPT-2, BERT and RoBERTa (DistilBERT
|
||||
to be added soon). GPT and GPT-2 are fine-tuned using a causal language modeling (CLM) loss while BERT and RoBERTa
|
||||
are fine-tuned using a masked language modeling (MLM) loss.
|
||||
|
||||
Before running the following example, you should get a file that contains text on which the language model will be
|
||||
fine-tuned. A good example of such text is the [WikiText-2 dataset](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/).
|
||||
trained or fine-tuned. A good example of such text is the [WikiText-2 dataset](https://blog.einstein.ai/the-wikitext-long-term-dependency-language-modeling-dataset/).
|
||||
|
||||
We will refer to two different files: `$TRAIN_FILE`, which contains text for training, and `$TEST_FILE`, which contains
|
||||
text that will be used for evaluation.
|
||||
@@ -72,7 +71,7 @@ the tokenization). The loss here is that of causal language modeling.
|
||||
export TRAIN_FILE=/path/to/dataset/wiki.train.raw
|
||||
export TEST_FILE=/path/to/dataset/wiki.test.raw
|
||||
|
||||
python run_lm_finetuning.py \
|
||||
python run_language_modeling.py \
|
||||
--output_dir=output \
|
||||
--model_type=gpt2 \
|
||||
--model_name_or_path=gpt2 \
|
||||
@@ -100,7 +99,7 @@ We use the `--mlm` flag so that the script may change its loss function.
|
||||
export TRAIN_FILE=/path/to/dataset/wiki.train.raw
|
||||
export TEST_FILE=/path/to/dataset/wiki.test.raw
|
||||
|
||||
python run_lm_finetuning.py \
|
||||
python run_language_modeling.py \
|
||||
--output_dir=output \
|
||||
--model_type=roberta \
|
||||
--model_name_or_path=roberta-base \
|
||||
@@ -154,7 +153,7 @@ between different runs. We report the median on 5 runs (with different seeds) fo
|
||||
Some of these results are significantly different from the ones reported on the test set
|
||||
of GLUE benchmark on the website. For QQP and WNLI, please refer to [FAQ #12](https://gluebenchmark.com/faq) on the webite.
|
||||
|
||||
Before running anyone of these GLUE tasks you should download the
|
||||
Before running any one of these GLUE tasks you should download the
|
||||
[GLUE data](https://gluebenchmark.com/tasks) by running
|
||||
[this script](https://gist.github.com/W4ngatang/60c2bdb54d156a41194446737ce03e2e)
|
||||
and unpack it to some directory `$GLUE_DIR`.
|
||||
@@ -196,7 +195,7 @@ since the data processor for each task inherits from the base class DataProcesso
|
||||
The following examples fine-tune BERT on the Microsoft Research Paraphrase Corpus (MRPC) corpus and runs in less
|
||||
than 10 minutes on a single K-80 and in 27 seconds (!) on single tesla V100 16GB with apex installed.
|
||||
|
||||
Before running anyone of these GLUE tasks you should download the
|
||||
Before running any one of these GLUE tasks you should download the
|
||||
[GLUE data](https://gluebenchmark.com/tasks) by running
|
||||
[this script](https://gist.github.com/W4ngatang/60c2bdb54d156a41194446737ce03e2e)
|
||||
and unpack it to some directory `$GLUE_DIR`.
|
||||
@@ -404,12 +403,12 @@ exact_match = 81.22
|
||||
#### Distributed training
|
||||
|
||||
|
||||
Here is an example using distributed training on 8 V100 GPUs and Bert Whole Word Masking uncased model to reach a F1 > 93 on SQuAD1.0:
|
||||
Here is an example using distributed training on 8 V100 GPUs and Bert Whole Word Masking uncased model to reach a F1 > 93 on SQuAD1.1:
|
||||
|
||||
```bash
|
||||
python -m torch.distributed.launch --nproc_per_node=8 run_squad.py \
|
||||
python -m torch.distributed.launch --nproc_per_node=8 ./examples/run_squad.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path bert-base-cased \
|
||||
--model_name_or_path bert-large-uncased-whole-word-masking \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
@@ -419,9 +418,9 @@ python -m torch.distributed.launch --nproc_per_node=8 run_squad.py \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir ../models/wwm_uncased_finetuned_squad/ \
|
||||
--per_gpu_train_batch_size 24 \
|
||||
--gradient_accumulation_steps 12
|
||||
--output_dir ./examples/models/wwm_uncased_finetuned_squad/ \
|
||||
--per_gpu_eval_batch_size=3 \
|
||||
--per_gpu_train_batch_size=3 \
|
||||
```
|
||||
|
||||
Training with the previously defined hyper-parameters yields the following results:
|
||||
@@ -701,7 +700,7 @@ macro avg 0.8712 0.8774 0.8740 13869
|
||||
|
||||
Based on the script [`run_xnli.py`](https://github.com/huggingface/transformers/blob/master/examples/run_xnli.py).
|
||||
|
||||
[XNLI](https://www.nyu.edu/projects/bowman/xnli/) is crowd-sourced dataset based on [MultiNLI](http://www.nyu.edu/projects/bowman/multinli/). It is an evaluation benchmark for cross-lingual text representations. Pairs of text are labeled with textual entailment annotations for 15 different languages (including both high-ressource language such as English and low-ressource languages such as Swahili).
|
||||
[XNLI](https://www.nyu.edu/projects/bowman/xnli/) is crowd-sourced dataset based on [MultiNLI](http://www.nyu.edu/projects/bowman/multinli/). It is an evaluation benchmark for cross-lingual text representations. Pairs of text are labeled with textual entailment annotations for 15 different languages (including both high-resource language such as English and low-resource languages such as Swahili).
|
||||
|
||||
#### Fine-tuning on XNLI
|
||||
|
||||
|
||||
@@ -31,8 +31,10 @@ Here are the results on the dev sets of GLUE:
|
||||
|
||||
| Model | Macro-score | CoLA | MNLI | MRPC | QNLI | QQP | RTE | SST-2| STS-B| WNLI |
|
||||
| :---: | :---: | :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---:| :---: |
|
||||
| BERT-base-uncased | **77.6** | 49.2 | 80.8 | 87.4 | 87.5 | 86.4 | 61.7 | 92.0 | 83.8 | 45.1 |
|
||||
| DistilBERT-base-uncased | **76.8** | 43.6 | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 | 56.3 |
|
||||
| BERT-base-uncased | **74.9** | 49.2 | 80.8 | 87.4 | 87.5 | 86.4 | 61.7 | 92.0 | 83.8 | 45.1 |
|
||||
| DistilBERT-base-uncased | **74.3** | 43.6 | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 | 56.3 |
|
||||
| BERT-base-cased | **78.2** | 58.2 | 83.9 | 87.8 | 91.0 | 89.2 | 66.1 | 91.7 | 89.2 | 46.5 |
|
||||
| DistilBERT-base-cased | **75.9** | 47.2 | 81.5 | 85.6 | 88.2 | 87.8 | 60.6 | 90.4 | 85.5 | 56.3 |
|
||||
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
||||
| RoBERTa-base (reported) | **83.2**/**86.4**<sup>2</sup> | 63.6 | 87.6 | 90.2 | 92.8 | 91.9 | 78.7 | 94.8 | 91.2 | 57.7<sup>3</sup> |
|
||||
| DistilRoBERTa<sup>1</sup> | **79.0**/**82.3**<sup>2</sup> | 59.3 | 84.0 | 86.6 | 90.8 | 89.4 | 67.9 | 92.5 | 88.3 | 52.1 |
|
||||
@@ -63,7 +65,9 @@ This part of the library has only be tested with Python3.6+. There are few speci
|
||||
Transformers includes five pre-trained Distil* models, currently only provided for English and German (we are investigating the possibility to train and release a multilingual version of DistilBERT):
|
||||
|
||||
- `distilbert-base-uncased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-uncased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 66M parameters.
|
||||
- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 86.9 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 88.5 F1 score).
|
||||
- `distilbert-base-uncased-distilled-squad`: A finetuned version of `distilbert-base-uncased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 79.8 on the dev set (for comparison, Bert `bert-base-uncased` version reaches a 82.3 F1 score).
|
||||
- `distilbert-base-cased`: DistilBERT English language model pretrained on the same data used to pretrain Bert (concatenation of the Toronto Book Corpus and full English Wikipedia) using distillation with the supervision of the `bert-base-cased` version of Bert. The model has 6 layers, 768 dimension and 12 heads, totalizing 65M parameters.
|
||||
- `distilbert-base-cased-distilled-squad`: A finetuned version of `distilbert-base-cased` finetuned using (a second step of) knwoledge distillation on SQuAD 1.0. This model reaches a F1 score of 87.1 on the dev set (for comparison, Bert `bert-base-cased` version reaches a 88.7 F1 score).
|
||||
- `distilbert-base-german-cased`: DistilBERT German language model pretrained on 1/2 of the data used to pretrain Bert using distillation with the supervision of the `bert-base-german-dbmdz-cased` version of German DBMDZ Bert. For NER tasks the model reaches a F1 score of 83.49 on the CoNLL-2003 test set (for comparison, `bert-base-german-dbmdz-cased` reaches a 84.52 F1 score), and a F1 score of 85.23 on the GermEval 2014 test set (`bert-base-german-dbmdz-cased` reaches a 86.89 F1 score).
|
||||
- `distilgpt2`: DistilGPT2 English language model pretrained with the supervision of `gpt2` (the smallest version of GPT2) on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset. The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 124M parameters for GPT2). On average, DistilGPT2 is two times faster than GPT2.
|
||||
- `distilroberta-base`: DistilRoBERTa English language model pretrained with the supervision of `roberta-base` solely on [OpenWebTextCorpus](https://skylion007.github.io/OpenWebTextCorpus/), a reproduction of OpenAI's WebText dataset (it is ~4 times less training data than the teacher RoBERTa). The model has 6 layers, 768 dimension and 12 heads, totalizing 82M parameters (compared to 125M parameters for RoBERTa-base). On average DistilRoBERTa is twice as fast as Roberta-base.
|
||||
@@ -72,8 +76,8 @@ Transformers includes five pre-trained Distil* models, currently only provided f
|
||||
Using DistilBERT is very similar to using BERT. DistilBERT share the same tokenizer as BERT's `bert-base-uncased` even though we provide a link to this tokenizer under the `DistilBertTokenizer` name to have a consistent naming between the library models.
|
||||
|
||||
```python
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0)
|
||||
outputs = model(input_ids)
|
||||
@@ -81,6 +85,7 @@ last_hidden_states = outputs[0] # The last hidden-state is the first element of
|
||||
```
|
||||
|
||||
Similarly, using the other Distil* models simply consists in calling the base classes with a different pretrained checkpoint:
|
||||
- DistilBERT uncased: `model = DistilBertModel.from_pretrained('distilbert-base-uncased')`
|
||||
- DistilGPT2: `model = GPT2Model.from_pretrained('distilgpt2')`
|
||||
- DistilRoBERTa: `model = RobertaModel.from_pretrained('distilroberta-base')`
|
||||
- DistilmBERT: `model = DistilBertModel.from_pretrained('distilbert-base-multilingual-cased')`
|
||||
@@ -174,7 +179,7 @@ Happy distillation!
|
||||
|
||||
## Citation
|
||||
|
||||
If you find the ressource useful, you should cite the following paper:
|
||||
If you find the resource useful, you should cite the following paper:
|
||||
|
||||
```
|
||||
@inproceedings{sanh2019distilbert,
|
||||
|
||||
@@ -0,0 +1,15 @@
|
||||
{
|
||||
"activation": "gelu",
|
||||
"attention_dropout": 0.1,
|
||||
"dim": 768,
|
||||
"dropout": 0.1,
|
||||
"hidden_dim": 3072,
|
||||
"initializer_range": 0.02,
|
||||
"max_position_embeddings": 512,
|
||||
"n_heads": 12,
|
||||
"n_layers": 6,
|
||||
"sinusoidal_pos_embds": true,
|
||||
"tie_weights_": true,
|
||||
"vocab_size": 28996
|
||||
}
|
||||
|
||||
@@ -221,6 +221,7 @@ def main():
|
||||
top_k=args.k,
|
||||
top_p=args.p,
|
||||
repetition_penalty=args.repetition_penalty,
|
||||
do_sample=True,
|
||||
)
|
||||
|
||||
# Batch size == 1. to add more examples please use num_return_sequences > 1
|
||||
|
||||
@@ -41,6 +41,9 @@ from transformers import (
|
||||
DistilBertConfig,
|
||||
DistilBertForSequenceClassification,
|
||||
DistilBertTokenizer,
|
||||
FlaubertConfig,
|
||||
FlaubertForSequenceClassification,
|
||||
FlaubertTokenizer,
|
||||
RobertaConfig,
|
||||
RobertaForSequenceClassification,
|
||||
RobertaTokenizer,
|
||||
@@ -80,6 +83,7 @@ ALL_MODELS = sum(
|
||||
DistilBertConfig,
|
||||
AlbertConfig,
|
||||
XLMRobertaConfig,
|
||||
FlaubertConfig,
|
||||
)
|
||||
),
|
||||
(),
|
||||
@@ -93,6 +97,7 @@ MODEL_CLASSES = {
|
||||
"distilbert": (DistilBertConfig, DistilBertForSequenceClassification, DistilBertTokenizer),
|
||||
"albert": (AlbertConfig, AlbertForSequenceClassification, AlbertTokenizer),
|
||||
"xlmroberta": (XLMRobertaConfig, XLMRobertaForSequenceClassification, XLMRobertaTokenizer),
|
||||
"flaubert": (FlaubertConfig, FlaubertForSequenceClassification, FlaubertTokenizer),
|
||||
}
|
||||
|
||||
|
||||
@@ -305,7 +310,7 @@ def evaluate(args, model, tokenizer, prefix=""):
|
||||
eval_dataloader = DataLoader(eval_dataset, sampler=eval_sampler, batch_size=args.eval_batch_size)
|
||||
|
||||
# multi-gpu eval
|
||||
if args.n_gpu > 1:
|
||||
if args.n_gpu > 1 and not isinstance(model, torch.nn.DataParallel):
|
||||
model = torch.nn.DataParallel(model)
|
||||
|
||||
# Eval!
|
||||
@@ -480,7 +485,7 @@ def main():
|
||||
parser.add_argument("--do_train", action="store_true", help="Whether to run training.")
|
||||
parser.add_argument("--do_eval", action="store_true", help="Whether to run eval on the dev set.")
|
||||
parser.add_argument(
|
||||
"--evaluate_during_training", action="store_true", help="Rul evaluation during training at each logging step.",
|
||||
"--evaluate_during_training", action="store_true", help="Run evaluation during training at each logging step.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--do_lower_case", action="store_true", help="Set this flag if you are using an uncased model.",
|
||||
@@ -513,8 +518,8 @@ def main():
|
||||
)
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
|
||||
parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument(
|
||||
"--eval_all_checkpoints",
|
||||
action="store_true",
|
||||
|
||||
@@ -86,6 +86,9 @@ MODEL_CLASSES = {
|
||||
class TextDataset(Dataset):
|
||||
def __init__(self, tokenizer: PreTrainedTokenizer, args, file_path: str, block_size=512):
|
||||
assert os.path.isfile(file_path)
|
||||
|
||||
block_size = block_size - (tokenizer.max_len - tokenizer.max_len_single_sentence)
|
||||
|
||||
directory, filename = os.path.split(file_path)
|
||||
cached_features_file = os.path.join(
|
||||
directory, args.model_type + "_cached_lm_" + str(block_size) + "_" + filename
|
||||
@@ -118,7 +121,7 @@ class TextDataset(Dataset):
|
||||
return len(self.examples)
|
||||
|
||||
def __getitem__(self, item):
|
||||
return torch.tensor(self.examples[item])
|
||||
return torch.tensor(self.examples[item], dtype=torch.long)
|
||||
|
||||
|
||||
class LineByLineTextDataset(Dataset):
|
||||
@@ -130,15 +133,15 @@ class LineByLineTextDataset(Dataset):
|
||||
logger.info("Creating features from dataset file at %s", file_path)
|
||||
|
||||
with open(file_path, encoding="utf-8") as f:
|
||||
lines = [line for line in f.read().splitlines() if len(line) > 0]
|
||||
lines = [line for line in f.read().splitlines() if (len(line) > 0 and not line.isspace())]
|
||||
|
||||
self.examples = tokenizer.batch_encode_plus(lines, max_length=block_size)["input_ids"]
|
||||
self.examples = tokenizer.batch_encode_plus(lines, add_special_tokens=True, max_length=block_size)["input_ids"]
|
||||
|
||||
def __len__(self):
|
||||
return len(self.examples)
|
||||
|
||||
def __getitem__(self, i):
|
||||
return torch.tensor(self.examples[i])
|
||||
return torch.tensor(self.examples[i], dtype=torch.long)
|
||||
|
||||
|
||||
def load_and_cache_examples(args, tokenizer, evaluate=False):
|
||||
@@ -195,6 +198,12 @@ def _rotate_checkpoints(args, checkpoint_prefix="checkpoint", use_mtime=False) -
|
||||
|
||||
def mask_tokens(inputs: torch.Tensor, tokenizer: PreTrainedTokenizer, args) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
""" Prepare masked tokens inputs/labels for masked language modeling: 80% MASK, 10% random, 10% original. """
|
||||
|
||||
if tokenizer.mask_token is None:
|
||||
raise ValueError(
|
||||
"This tokenizer does not have a mask token which is necessary for masked language modeling. Remove the --mlm flag if you want to use this tokenizer."
|
||||
)
|
||||
|
||||
labels = inputs.clone()
|
||||
# We sample a few tokens in each sequence for masked-LM training (with probability args.mlm_probability defaults to 0.15 in Bert/RoBERTa)
|
||||
probability_matrix = torch.full(labels.shape, args.mlm_probability)
|
||||
@@ -202,8 +211,9 @@ def mask_tokens(inputs: torch.Tensor, tokenizer: PreTrainedTokenizer, args) -> T
|
||||
tokenizer.get_special_tokens_mask(val, already_has_special_tokens=True) for val in labels.tolist()
|
||||
]
|
||||
probability_matrix.masked_fill_(torch.tensor(special_tokens_mask, dtype=torch.bool), value=0.0)
|
||||
padding_mask = labels.eq(tokenizer.pad_token_id)
|
||||
probability_matrix.masked_fill_(padding_mask, value=0.0)
|
||||
if tokenizer._pad_token is not None:
|
||||
padding_mask = labels.eq(tokenizer.pad_token_id)
|
||||
probability_matrix.masked_fill_(padding_mask, value=0.0)
|
||||
masked_indices = torch.bernoulli(probability_matrix).bool()
|
||||
labels[~masked_indices] = -100 # We only compute loss on masked tokens
|
||||
|
||||
@@ -228,6 +238,8 @@ def train(args, train_dataset, model: PreTrainedModel, tokenizer: PreTrainedToke
|
||||
args.train_batch_size = args.per_gpu_train_batch_size * max(1, args.n_gpu)
|
||||
|
||||
def collate(examples: List[torch.Tensor]):
|
||||
if tokenizer._pad_token is None:
|
||||
return pad_sequence(examples, batch_first=True)
|
||||
return pad_sequence(examples, batch_first=True, padding_value=tokenizer.pad_token_id)
|
||||
|
||||
train_sampler = RandomSampler(train_dataset) if args.local_rank == -1 else DistributedSampler(train_dataset)
|
||||
@@ -421,6 +433,8 @@ def evaluate(args, model: PreTrainedModel, tokenizer: PreTrainedTokenizer, prefi
|
||||
# Note that DistributedSampler samples randomly
|
||||
|
||||
def collate(examples: List[torch.Tensor]):
|
||||
if tokenizer._pad_token is None:
|
||||
return pad_sequence(examples, batch_first=True)
|
||||
return pad_sequence(examples, batch_first=True, padding_value=tokenizer.pad_token_id)
|
||||
|
||||
eval_sampler = SequentialSampler(eval_dataset)
|
||||
@@ -569,8 +583,8 @@ def main():
|
||||
)
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
|
||||
parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument(
|
||||
"--save_total_limit",
|
||||
type=int,
|
||||
@@ -699,10 +713,10 @@ def main():
|
||||
)
|
||||
|
||||
if args.block_size <= 0:
|
||||
args.block_size = tokenizer.max_len_single_sentence
|
||||
args.block_size = tokenizer.max_len
|
||||
# Our input block size will be the max possible for the model
|
||||
else:
|
||||
args.block_size = min(args.block_size, tokenizer.max_len_single_sentence)
|
||||
args.block_size = min(args.block_size, tokenizer.max_len)
|
||||
|
||||
if args.model_name_or_path:
|
||||
model = model_class.from_pretrained(
|
||||
@@ -478,8 +478,8 @@ def main():
|
||||
)
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
|
||||
parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument(
|
||||
"--eval_all_checkpoints",
|
||||
action="store_true",
|
||||
|
||||
+6
-3
@@ -160,7 +160,10 @@ def train(args, train_dataset, model, tokenizer, labels, pad_token_label_id):
|
||||
# Check if continuing training from a checkpoint
|
||||
if os.path.exists(args.model_name_or_path):
|
||||
# set global_step to gobal_step of last saved checkpoint from model path
|
||||
global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
|
||||
try:
|
||||
global_step = int(args.model_name_or_path.split("-")[-1].split("/")[0])
|
||||
except ValueError:
|
||||
global_step = 0
|
||||
epochs_trained = global_step // (len(train_dataloader) // args.gradient_accumulation_steps)
|
||||
steps_trained_in_current_epoch = global_step % (len(train_dataloader) // args.gradient_accumulation_steps)
|
||||
|
||||
@@ -485,8 +488,8 @@ def main():
|
||||
)
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
|
||||
parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument(
|
||||
"--eval_all_checkpoints",
|
||||
action="store_true",
|
||||
|
||||
+18
-2
@@ -219,6 +219,11 @@ def train(args, train_dataset, model, tokenizer):
|
||||
inputs.update({"cls_index": batch[5], "p_mask": batch[6]})
|
||||
if args.version_2_with_negative:
|
||||
inputs.update({"is_impossible": batch[7]})
|
||||
if hasattr(model, "config") and hasattr(model.config, "lang2id"):
|
||||
inputs.update(
|
||||
{"langs": (torch.ones(batch[0].shape, dtype=torch.int64) * args.lang_id).to(args.device)}
|
||||
)
|
||||
|
||||
outputs = model(**inputs)
|
||||
# model outputs are always tuple in transformers (see doc)
|
||||
loss = outputs[0]
|
||||
@@ -330,6 +335,11 @@ def evaluate(args, model, tokenizer, prefix=""):
|
||||
# XLNet and XLM use more arguments for their predictions
|
||||
if args.model_type in ["xlnet", "xlm"]:
|
||||
inputs.update({"cls_index": batch[4], "p_mask": batch[5]})
|
||||
# for lang_id-sensitive xlm models
|
||||
if hasattr(model, "config") and hasattr(model.config, "lang2id"):
|
||||
inputs.update(
|
||||
{"langs": (torch.ones(batch[0].shape, dtype=torch.int64) * args.lang_id).to(args.device)}
|
||||
)
|
||||
|
||||
outputs = model(**inputs)
|
||||
|
||||
@@ -635,9 +645,15 @@ def main():
|
||||
help="If true, all of the warnings related to data processing will be printed. "
|
||||
"A number of warnings are expected for a normal SQuAD evaluation.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--lang_id",
|
||||
default=0,
|
||||
type=int,
|
||||
help="language id of input for language-specific xlm models (see tokenization_xlm.PRETRAINED_INIT_CONFIGURATION)",
|
||||
)
|
||||
|
||||
parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument(
|
||||
"--eval_all_checkpoints",
|
||||
action="store_true",
|
||||
|
||||
@@ -99,9 +99,6 @@ if TASK == "mrpc":
|
||||
inputs_1 = tokenizer.encode_plus(sentence_0, sentence_1, add_special_tokens=True, return_tensors="pt")
|
||||
inputs_2 = tokenizer.encode_plus(sentence_0, sentence_2, add_special_tokens=True, return_tensors="pt")
|
||||
|
||||
del inputs_1["special_tokens_mask"]
|
||||
del inputs_2["special_tokens_mask"]
|
||||
|
||||
pred_1 = pytorch_model(**inputs_1)[0].argmax().item()
|
||||
pred_2 = pytorch_model(**inputs_2)[0].argmax().item()
|
||||
print("sentence_1 is", "a paraphrase" if pred_1 else "not a paraphrase", "of sentence_0")
|
||||
|
||||
@@ -459,7 +459,7 @@ def main():
|
||||
help="Number of updates steps to accumulate before performing a backward/update pass.",
|
||||
)
|
||||
parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight deay if we apply some.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
|
||||
parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
|
||||
parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
|
||||
parser.add_argument(
|
||||
@@ -473,8 +473,8 @@ def main():
|
||||
)
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
|
||||
parser.add_argument("--logging_steps", type=int, default=50, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--logging_steps", type=int, default=500, help="Log every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=500, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument(
|
||||
"--eval_all_checkpoints",
|
||||
action="store_true",
|
||||
|
||||
@@ -73,7 +73,7 @@ def read_examples_from_file(data_dir, mode):
|
||||
# Examples could have no label for mode = "test"
|
||||
labels.append("O")
|
||||
if words:
|
||||
examples.append(InputExample(guid="%s-%d".format(mode, guid_index), words=words, labels=labels))
|
||||
examples.append(InputExample(guid="{}-{}".format(mode, guid_index), words=words, labels=labels))
|
||||
return examples
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,121 @@
|
||||
---
|
||||
language: swedish
|
||||
---
|
||||
|
||||
# Swedish BERT Models
|
||||
|
||||
The National Library of Sweden / KBLab releases three pretrained language models based on BERT and ALBERT. The models are trained on aproximately 15-20GB of text (200M sentences, 3000M tokens) from various sources (books, news, government publications, swedish wikipedia and internet forums) aiming to provide a representative BERT model for Swedish text. A more complete description will be published later on.
|
||||
|
||||
The following three models are currently available:
|
||||
|
||||
- **bert-base-swedish-cased** (*v1*) - A BERT trained with the same hyperparameters as first published by Google.
|
||||
- **bert-base-swedish-cased-ner** (*experimental*) - a BERT fine-tuned for NER using SUC 3.0.
|
||||
- **albert-base-swedish-cased-alpha** (*alpha*) - A first attempt at an ALBERT for Swedish.
|
||||
|
||||
All models are cased and trained with whole word masking.
|
||||
|
||||
## Files
|
||||
|
||||
| **name** | **files** |
|
||||
|---------------------------------|-----------|
|
||||
| bert-base-swedish-cased | [config](https://s3.amazonaws.com/models.huggingface.co/bert/KB/bert-base-swedish-cased/config.json), [vocab](https://s3.amazonaws.com/models.huggingface.co/bert/KB/bert-base-swedish-cased/vocab.txt), [pytorch_model.bin](https://s3.amazonaws.com/models.huggingface.co/bert/KB/bert-base-swedish-cased/pytorch_model.bin) |
|
||||
| bert-base-swedish-cased-ner | [config](https://s3.amazonaws.com/models.huggingface.co/bert/KB/bert-base-swedish-cased-ner/config.json), [vocab](https://s3.amazonaws.com/models.huggingface.co/bert/KB/bert-base-swedish-cased-ner/vocab.txt) [pytorch_model.bin](https://s3.amazonaws.com/models.huggingface.co/bert/KB/bert-base-swedish-cased-ner/pytorch_model.bin) |
|
||||
| albert-base-swedish-cased-alpha | [config](https://s3.amazonaws.com/models.huggingface.co/bert/KB/albert-base-swedish-cased-alpha/config.json), [sentencepiece model](https://s3.amazonaws.com/models.huggingface.co/bert/KB/albert-base-swedish-cased-alpha/spiece.model), [pytorch_model.bin](https://s3.amazonaws.com/models.huggingface.co/bert/KB/albert-base-swedish-cased-alpha/pytorch_model.bin) |
|
||||
|
||||
TensorFlow model weights will be released soon.
|
||||
|
||||
## Usage requirements / installation instructions
|
||||
|
||||
The examples below require Huggingface Transformers 2.4.1 and Pytorch 1.3.1 or greater. For Transformers<2.4.0 the tokenizer must be instantiated manually and the `do_lower_case` flag parameter set to `False` and `keep_accents` to `True` (for ALBERT).
|
||||
|
||||
To create an environment where the examples can be run, run the following in an terminal on your OS of choice.
|
||||
|
||||
```
|
||||
# git clone https://github.com/Kungbib/swedish-bert-models
|
||||
# cd swedish-bert-models
|
||||
# python3 -m venv venv
|
||||
# source venv/bin/activate
|
||||
# pip install --upgrade pip
|
||||
# pip install -r requirements.txt
|
||||
```
|
||||
|
||||
### BERT Base Swedish
|
||||
|
||||
A standard BERT base for Swedish trained on a variety of sources. Vocabulary size is ~50k. Using Huggingface Transformers the model can be loaded in Python as follows:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel,AutoTokenizer
|
||||
|
||||
tok = AutoTokenizer.from_pretrained('KB/bert-base-swedish-cased')
|
||||
model = AutoModel.from_pretrained('KB/bert-base-swedish-cased')
|
||||
```
|
||||
|
||||
|
||||
### BERT base fine-tuned for Swedish NER
|
||||
|
||||
This model is fine-tuned on the SUC 3.0 dataset. Using the Huggingface pipeline the model can be easily instantiated. For Transformer<2.4.1 it seems the tokenizer must be loaded separately to disable lower-casing of input strings:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline('ner', model='KB/bert-base-swedish-cased-ner', tokenizer='KB/bert-base-swedish-cased-ner')
|
||||
|
||||
nlp('Idag släpper KB tre språkmodeller.')
|
||||
```
|
||||
|
||||
Running the Python code above should produce in something like the result below. Entity types used are `TME` for time, `PRS` for personal names, `LOC` for locations, `EVN` for events and `ORG` for organisations. These labels are subject to change.
|
||||
|
||||
```python
|
||||
[ { 'word': 'Idag', 'score': 0.9998126029968262, 'entity': 'TME' },
|
||||
{ 'word': 'KB', 'score': 0.9814832210540771, 'entity': 'ORG' } ]
|
||||
```
|
||||
|
||||
The BERT tokenizer often splits words into multiple tokens, with the subparts starting with `##`, for example the string `Engelbert kör Volvo till Herrängens fotbollsklubb` gets tokenized as `Engel ##bert kör Volvo till Herr ##ängens fotbolls ##klubb`. To glue parts back together one can use something like this:
|
||||
|
||||
```python
|
||||
text = 'Engelbert tar Volvon till Tele2 Arena för att titta på Djurgården IF ' +\
|
||||
'som spelar fotboll i VM klockan två på kvällen.'
|
||||
|
||||
l = []
|
||||
for token in nlp(text):
|
||||
if token['word'].startswith('##'):
|
||||
l[-1]['word'] += token['word'][2:]
|
||||
else:
|
||||
l += [ token ]
|
||||
|
||||
print(l)
|
||||
```
|
||||
|
||||
Which should result in the following (though less cleanly formated):
|
||||
|
||||
```python
|
||||
[ { 'word': 'Engelbert', 'score': 0.99..., 'entity': 'PRS'},
|
||||
{ 'word': 'Volvon', 'score': 0.99..., 'entity': 'OBJ'},
|
||||
{ 'word': 'Tele2', 'score': 0.99..., 'entity': 'LOC'},
|
||||
{ 'word': 'Arena', 'score': 0.99..., 'entity': 'LOC'},
|
||||
{ 'word': 'Djurgården', 'score': 0.99..., 'entity': 'ORG'},
|
||||
{ 'word': 'IF', 'score': 0.99..., 'entity': 'ORG'},
|
||||
{ 'word': 'VM', 'score': 0.99..., 'entity': 'EVN'},
|
||||
{ 'word': 'klockan', 'score': 0.99..., 'entity': 'TME'},
|
||||
{ 'word': 'två', 'score': 0.99..., 'entity': 'TME'},
|
||||
{ 'word': 'på', 'score': 0.99..., 'entity': 'TME'},
|
||||
{ 'word': 'kvällen', 'score': 0.54..., 'entity': 'TME'} ]
|
||||
```
|
||||
|
||||
### ALBERT base
|
||||
|
||||
The easisest way to do this is, again, using Huggingface Transformers:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel,AutoTokenizer
|
||||
|
||||
tok = AutoTokenizer.from_pretrained('KB/albert-base-swedish-cased-alpha'),
|
||||
model = AutoModel.from_pretrained('KB/albert-base-swedish-cased-alpha')
|
||||
```
|
||||
|
||||
## Acknowledgements ❤️
|
||||
|
||||
- Resources from Stockholms University, Umeå University and Swedish Language Bank at Gothenburg University were used when fine-tuning BERT for NER.
|
||||
- Model pretraining was made partly in-house at the KBLab and partly (for material without active copyright) with the support of Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
- Models are hosted on S3 by Huggingface 🤗
|
||||
|
||||
@@ -0,0 +1,118 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# UmBERTo Commoncrawl Cased
|
||||
|
||||
[UmBERTo](https://github.com/musixmatchresearch/umberto) is a Roberta-based Language Model trained on large Italian Corpora and uses two innovative approaches: SentencePiece and Whole Word Masking. Now available at [github.com/huggingface/transformers](https://huggingface.co/Musixmatch/umberto-commoncrawl-cased-v1)
|
||||
|
||||
<p align="center">
|
||||
<img src="https://user-images.githubusercontent.com/7140210/72913702-d55a8480-3d3d-11ea-99fc-f2ef29af4e72.jpg" width="700"> </br>
|
||||
Marco Lodola, Monument to Umberto Eco, Alessandria 2019
|
||||
</p>
|
||||
|
||||
## Dataset
|
||||
UmBERTo-Commoncrawl-Cased utilizes the Italian subcorpus of [OSCAR](https://traces1.inria.fr/oscar/) as training set of the language model. We used deduplicated version of the Italian corpus that consists in 70 GB of plain text data, 210M sentences with 11B words where the sentences have been filtered and shuffled at line level in order to be used for NLP research.
|
||||
|
||||
## Pre-trained model
|
||||
|
||||
| Model | WWM | Cased | Tokenizer | Vocab Size | Train Steps | Download |
|
||||
| ------ | ------ | ------ | ------ | ------ |------ | ------ |
|
||||
| `umberto-commoncrawl-cased-v1` | YES | YES | SPM | 32K | 125k | [Link](http://bit.ly/35zO7GH) |
|
||||
|
||||
This model was trained with [SentencePiece](https://github.com/google/sentencepiece) and Whole Word Masking.
|
||||
|
||||
## Downstream Tasks
|
||||
These results refers to umberto-commoncrawl-cased model. All details are at [Umberto](https://github.com/musixmatchresearch/umberto) Official Page.
|
||||
|
||||
#### Named Entity Recognition (NER)
|
||||
|
||||
| Dataset | F1 | Precision | Recall | Accuracy |
|
||||
| ------ | ------ | ------ | ------ | ------ |
|
||||
| **ICAB-EvalITA07** | **87.565** | 86.596 | 88.556 | 98.690 |
|
||||
| **WikiNER-ITA** | **92.531** | 92.509 | 92.553 | 99.136 |
|
||||
|
||||
#### Part of Speech (POS)
|
||||
|
||||
| Dataset | F1 | Precision | Recall | Accuracy |
|
||||
| ------ | ------ | ------ | ------ | ------ |
|
||||
| **UD_Italian-ISDT** | 98.870 | 98.861 | 98.879 | **98.977** |
|
||||
| **UD_Italian-ParTUT** | 98.786 | 98.812 | 98.760 | **98.903** |
|
||||
|
||||
|
||||
|
||||
## Usage
|
||||
|
||||
##### Load UmBERTo with AutoModel, Autotokenizer:
|
||||
|
||||
```python
|
||||
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Musixmatch/umberto-commoncrawl-cased-v1")
|
||||
umberto = AutoModel.from_pretrained("Musixmatch/umberto-commoncrawl-cased-v1")
|
||||
|
||||
encoded_input = tokenizer.encode("Umberto Eco è stato un grande scrittore")
|
||||
input_ids = torch.tensor(encoded_input).unsqueeze(0) # Batch size 1
|
||||
outputs = umberto(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output
|
||||
```
|
||||
|
||||
##### Predict masked token:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
fill_mask = pipeline(
|
||||
"fill-mask",
|
||||
model="Musixmatch/umberto-commoncrawl-cased-v1",
|
||||
tokenizer="Musixmatch/umberto-commoncrawl-cased-v1"
|
||||
)
|
||||
|
||||
result = fill_mask("Umberto Eco è <mask> un grande scrittore")
|
||||
# {'sequence': '<s> Umberto Eco è considerato un grande scrittore</s>', 'score': 0.18599839508533478, 'token': 5032}
|
||||
# {'sequence': '<s> Umberto Eco è stato un grande scrittore</s>', 'score': 0.17816807329654694, 'token': 471}
|
||||
# {'sequence': '<s> Umberto Eco è sicuramente un grande scrittore</s>', 'score': 0.16565583646297455, 'token': 2654}
|
||||
# {'sequence': '<s> Umberto Eco è indubbiamente un grande scrittore</s>', 'score': 0.0932890921831131, 'token': 17908}
|
||||
# {'sequence': '<s> Umberto Eco è certamente un grande scrittore</s>', 'score': 0.054701317101716995, 'token': 5269}
|
||||
```
|
||||
|
||||
|
||||
## Citation
|
||||
All of the original datasets are publicly available or were released with the owners' grant. The datasets are all released under a CC0 or CCBY license.
|
||||
|
||||
* UD Italian-ISDT Dataset [Github](https://github.com/UniversalDependencies/UD_Italian-ISDT)
|
||||
* UD Italian-ParTUT Dataset [Github](https://github.com/UniversalDependencies/UD_Italian-ParTUT)
|
||||
* I-CAB (Italian Content Annotation Bank), EvalITA [Page](http://www.evalita.it/)
|
||||
* WIKINER [Page](https://figshare.com/articles/Learning_multilingual_named_entity_recognition_from_Wikipedia/5462500) , [Paper](https://www.sciencedirect.com/science/article/pii/S0004370212000276?via%3Dihub)
|
||||
|
||||
```
|
||||
@inproceedings {magnini2006annotazione,
|
||||
title = {Annotazione di contenuti concettuali in un corpus italiano: I - CAB},
|
||||
author = {Magnini,Bernardo and Cappelli,Amedeo and Pianta,Emanuele and Speranza,Manuela and Bartalesi Lenzi,V and Sprugnoli,Rachele and Romano,Lorenza and Girardi,Christian and Negri,Matteo},
|
||||
booktitle = {Proc.of SILFI 2006},
|
||||
year = {2006}
|
||||
}
|
||||
@inproceedings {magnini2006cab,
|
||||
title = {I - CAB: the Italian Content Annotation Bank.},
|
||||
author = {Magnini,Bernardo and Pianta,Emanuele and Girardi,Christian and Negri,Matteo and Romano,Lorenza and Speranza,Manuela and Lenzi,Valentina Bartalesi and Sprugnoli,Rachele},
|
||||
booktitle = {LREC},
|
||||
pages = {963--968},
|
||||
year = {2006},
|
||||
organization = {Citeseer}
|
||||
}
|
||||
```
|
||||
|
||||
## Authors
|
||||
|
||||
**Loreto Parisi**: `loreto at musixmatch dot com`, [loretoparisi](https://github.com/loretoparisi)
|
||||
**Simone Francia**: `simone.francia at musixmatch dot com`, [simonefrancia](https://github.com/simonefrancia)
|
||||
**Paolo Magnani**: `paul.magnani95 at gmail dot com`, [paulthemagno](https://github.com/paulthemagno)
|
||||
|
||||
## About Musixmatch AI
|
||||
|
||||
We do Machine Learning and Artificial Intelligence @[musixmatch](https://twitter.com/Musixmatch)
|
||||
Follow us on [Twitter](https://twitter.com/musixmatchai) [Github](https://github.com/musixmatchresearch)
|
||||
|
||||
|
||||
@@ -0,0 +1,117 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# UmBERTo Wikipedia Uncased
|
||||
|
||||
[UmBERTo](https://github.com/musixmatchresearch/umberto) is a Roberta-based Language Model trained on large Italian Corpora and uses two innovative approaches: SentencePiece and Whole Word Masking. Now available at [github.com/huggingface/transformers](https://huggingface.co/Musixmatch/umberto-commoncrawl-cased-v1)
|
||||
|
||||
<p align="center">
|
||||
<img src="https://user-images.githubusercontent.com/7140210/72913702-d55a8480-3d3d-11ea-99fc-f2ef29af4e72.jpg" width="700"> </br>
|
||||
Marco Lodola, Monument to Umberto Eco, Alessandria 2019
|
||||
</p>
|
||||
|
||||
## Dataset
|
||||
UmBERTo-Wikipedia-Uncased Training is trained on a relative small corpus (~7GB) extracted from [Wikipedia-ITA](https://linguatools.org/tools/corpora/wikipedia-monolingual-corpora/).
|
||||
|
||||
## Pre-trained model
|
||||
|
||||
| Model | WWM | Cased | Tokenizer | Vocab Size | Train Steps | Download |
|
||||
| ------ | ------ | ------ | ------ | ------ |------ | ------ |
|
||||
| `umberto-wikipedia-uncased-v1` | YES | YES | SPM | 32K | 100k | [Link](http://bit.ly/35wbSj6) |
|
||||
|
||||
This model was trained with [SentencePiece](https://github.com/google/sentencepiece) and Whole Word Masking.
|
||||
|
||||
## Downstream Tasks
|
||||
These results refers to umberto-wikipedia-uncased model. All details are at [Umberto](https://github.com/musixmatchresearch/umberto) Official Page.
|
||||
|
||||
#### Named Entity Recognition (NER)
|
||||
|
||||
| Dataset | F1 | Precision | Recall | Accuracy |
|
||||
| ------ | ------ | ------ | ------ | ----- |
|
||||
| **ICAB-EvalITA07** | **86.240** | 85.939 | 86.544 | 98.534 |
|
||||
| **WikiNER-ITA** | **90.483** | 90.328 | 90.638 | 98.661 |
|
||||
|
||||
#### Part of Speech (POS)
|
||||
|
||||
| Dataset | F1 | Precision | Recall | Accuracy |
|
||||
| ------ | ------ | ------ | ------ | ------ |
|
||||
| **UD_Italian-ISDT** | 98.563 | 98.508 | 98.618 | **98.717** |
|
||||
| **UD_Italian-ParTUT** | 97.810 | 97.835 | 97.784 | **98.060** |
|
||||
|
||||
|
||||
|
||||
## Usage
|
||||
|
||||
##### Load UmBERTo Wikipedia Uncased with AutoModel, Autotokenizer:
|
||||
|
||||
```python
|
||||
|
||||
import torch
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Musixmatch/umberto-wikipedia-uncased-v1")
|
||||
umberto = AutoModel.from_pretrained("Musixmatch/umberto-wikipedia-uncased-v1")
|
||||
|
||||
encoded_input = tokenizer.encode("Umberto Eco è stato un grande scrittore")
|
||||
input_ids = torch.tensor(encoded_input).unsqueeze(0) # Batch size 1
|
||||
outputs = umberto(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output
|
||||
```
|
||||
|
||||
##### Predict masked token:
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
fill_mask = pipeline(
|
||||
"fill-mask",
|
||||
model="Musixmatch/umberto-wikipedia-uncased-v1",
|
||||
tokenizer="Musixmatch/umberto-wikipedia-uncased-v1"
|
||||
)
|
||||
|
||||
result = fill_mask("Umberto Eco è <mask> un grande scrittore")
|
||||
# {'sequence': '<s> umberto eco è stato un grande scrittore</s>', 'score': 0.5784581303596497, 'token': 361}
|
||||
# {'sequence': '<s> umberto eco è anche un grande scrittore</s>', 'score': 0.33813193440437317, 'token': 269}
|
||||
# {'sequence': '<s> umberto eco è considerato un grande scrittore</s>', 'score': 0.027196012437343597, 'token': 3236}
|
||||
# {'sequence': '<s> umberto eco è diventato un grande scrittore</s>', 'score': 0.013716378249228, 'token': 5742}
|
||||
# {'sequence': '<s> umberto eco è inoltre un grande scrittore</s>', 'score': 0.010662357322871685, 'token': 1030}
|
||||
```
|
||||
|
||||
|
||||
## Citation
|
||||
All of the original datasets are publicly available or were released with the owners' grant. The datasets are all released under a CC0 or CCBY license.
|
||||
|
||||
* UD Italian-ISDT Dataset [Github](https://github.com/UniversalDependencies/UD_Italian-ISDT)
|
||||
* UD Italian-ParTUT Dataset [Github](https://github.com/UniversalDependencies/UD_Italian-ParTUT)
|
||||
* I-CAB (Italian Content Annotation Bank), EvalITA [Page](http://www.evalita.it/)
|
||||
* WIKINER [Page](https://figshare.com/articles/Learning_multilingual_named_entity_recognition_from_Wikipedia/5462500) , [Paper](https://www.sciencedirect.com/science/article/pii/S0004370212000276?via%3Dihub)
|
||||
|
||||
```
|
||||
@inproceedings {magnini2006annotazione,
|
||||
title = {Annotazione di contenuti concettuali in un corpus italiano: I - CAB},
|
||||
author = {Magnini,Bernardo and Cappelli,Amedeo and Pianta,Emanuele and Speranza,Manuela and Bartalesi Lenzi,V and Sprugnoli,Rachele and Romano,Lorenza and Girardi,Christian and Negri,Matteo},
|
||||
booktitle = {Proc.of SILFI 2006},
|
||||
year = {2006}
|
||||
}
|
||||
@inproceedings {magnini2006cab,
|
||||
title = {I - CAB: the Italian Content Annotation Bank.},
|
||||
author = {Magnini,Bernardo and Pianta,Emanuele and Girardi,Christian and Negri,Matteo and Romano,Lorenza and Speranza,Manuela and Lenzi,Valentina Bartalesi and Sprugnoli,Rachele},
|
||||
booktitle = {LREC},
|
||||
pages = {963--968},
|
||||
year = {2006},
|
||||
organization = {Citeseer}
|
||||
}
|
||||
```
|
||||
|
||||
## Authors
|
||||
|
||||
**Loreto Parisi**: `loreto at musixmatch dot com`, [loretoparisi](https://github.com/loretoparisi)
|
||||
**Simone Francia**: `simone.francia at musixmatch dot com`, [simonefrancia](https://github.com/simonefrancia)
|
||||
**Paolo Magnani**: `paul.magnani95 at gmail dot com`, [paulthemagno](https://github.com/paulthemagno)
|
||||
|
||||
## About Musixmatch AI
|
||||

|
||||
We do Machine Learning and Artificial Intelligence @[musixmatch](https://twitter.com/Musixmatch)
|
||||
Follow us on [Twitter](https://twitter.com/musixmatchai) [Github](https://github.com/musixmatchresearch)
|
||||
|
||||
@@ -0,0 +1,90 @@
|
||||
## Albert xxlarge version 1 language model fine-tuned on SQuAD2.0
|
||||
|
||||
### with the following results:
|
||||
|
||||
```
|
||||
exact: 85.65653162637918
|
||||
f1: 89.260458954177
|
||||
total': 11873
|
||||
HasAns_exact': 82.6417004048583
|
||||
HasAns_f1': 89.8598902096736
|
||||
HasAns_total': 5928
|
||||
NoAns_exact': 88.66274179983179
|
||||
NoAns_f1': 88.66274179983179
|
||||
NoAns_total': 5945
|
||||
best_exact': 85.65653162637918
|
||||
best_exact_thresh': 0.0
|
||||
best_f1': 89.2604589541768
|
||||
best_f1_thresh': 0.0
|
||||
```
|
||||
|
||||
### from script:
|
||||
|
||||
```
|
||||
python -m torch.distributed.launch --nproc_per_node=2 ${RUN_SQUAD_DIR}/run_squad.py \
|
||||
--model_type albert \
|
||||
--model_name_or_path albert-xxlarge-v1 \
|
||||
--do_train \
|
||||
--train_file ${SQUAD_DIR}/train-v2.0.json \
|
||||
--predict_file ${SQUAD_DIR}/dev-v2.0.json \
|
||||
--version_2_with_negative \
|
||||
--num_train_epochs 3 \
|
||||
--max_steps 8144 \
|
||||
--warmup_steps 814 \
|
||||
--do_lower_case \
|
||||
--learning_rate 3e-5 \
|
||||
--max_seq_length 512 \
|
||||
--doc_stride 128 \
|
||||
--save_steps 2000 \
|
||||
--per_gpu_train_batch_size 1 \
|
||||
--gradient_accumulation_steps 24 \
|
||||
--output_dir ${MODEL_PATH}
|
||||
|
||||
CUDA_VISIBLE_DEVICES=0 python ${RUN_SQUAD_DIR}/run_squad.py \
|
||||
--model_type albert \
|
||||
--model_name_or_path ${MODEL_PATH} \
|
||||
--do_eval \
|
||||
--train_file ${SQUAD_DIR}/train-v2.0.json \
|
||||
--predict_file ${SQUAD_DIR}/dev-v2.0.json \
|
||||
--version_2_with_negative \
|
||||
--do_lower_case \
|
||||
--max_seq_length 512 \
|
||||
--per_gpu_eval_batch_size 48 \
|
||||
--output_dir ${MODEL_PATH}
|
||||
```
|
||||
|
||||
### using the following system & software:
|
||||
|
||||
```
|
||||
OS/Platform: Linux-4.15.0-76-generic-x86_64-with-debian-buster-sid
|
||||
GPU/CPU: 2 x NVIDIA 1080Ti / Intel i7-8700
|
||||
Transformers: 2.3.0
|
||||
PyTorch: 1.4.0
|
||||
TensorFlow: 2.1.0
|
||||
Python: 3.7.6
|
||||
```
|
||||
|
||||
### Inferencing / prediction works with the current Transformers v2.4.1
|
||||
|
||||
### Access this albert_xxlargev1_sqd2_512 fine-tuned model with "tried & true" code:
|
||||
|
||||
```python
|
||||
config_class, model_class, tokenizer_class = \
|
||||
AlbertConfig, AlbertForQuestionAnswering, AlbertTokenizer
|
||||
|
||||
model_name_or_path = "ahotrod/albert_xxlargev1_squad2_512"
|
||||
config = config_class.from_pretrained(model_name_or_path)
|
||||
tokenizer = tokenizer_class.from_pretrained(model_name_or_path, do_lower_case=True)
|
||||
model = model_class.from_pretrained(model_name_or_path, config=config)
|
||||
```
|
||||
|
||||
### or the AutoModels (AutoConfig, AutoTokenizer & AutoModel) should also work, however I have yet to use them in my app & confirm:
|
||||
|
||||
```python
|
||||
from transformers import AutoConfig, AutoTokenizer, AutoModel
|
||||
|
||||
model_name_or_path = "ahotrod/albert_xxlargev1_squad2_512"
|
||||
config = AutoConfig.from_pretrained(model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path, do_lower_case=True)
|
||||
model = AutoModel.from_pretrained(model_name_or_path, config=config)
|
||||
```
|
||||
@@ -0,0 +1,71 @@
|
||||
---
|
||||
language: german
|
||||
thumbnail: https://thumb.tildacdn.com/tild3162-6462-4566-b663-376630376138/-/format/webp/Screenshot_from_2020.png
|
||||
---
|
||||
|
||||
# German BERT
|
||||
|
||||
## Overview
|
||||
**Language model:** bert-base-cased
|
||||
**Language:** German
|
||||
**Training data:** Wiki, OpenLegalData, News (~ 12GB)
|
||||
**Eval data:** Conll03 (NER), GermEval14 (NER), GermEval18 (Classification), GNAD (Classification)
|
||||
**Infrastructure**: 1x TPU v2
|
||||
**Published**: Jun 14th, 2019
|
||||
|
||||
## Details
|
||||
- We trained using Google's Tensorflow code on a single cloud TPU v2 with standard settings.
|
||||
- We trained 810k steps with a batch size of 1024 for sequence length 128 and 30k steps with sequence length 512. Training took about 9 days.
|
||||
- As training data we used the latest German Wikipedia dump (6GB of raw txt files), the OpenLegalData dump (2.4 GB) and news articles (3.6 GB).
|
||||
- We cleaned the data dumps with tailored scripts and segmented sentences with spacy v2.1. To create tensorflow records we used the recommended sentencepiece library for creating the word piece vocabulary and tensorflow scripts to convert the text to data usable by BERT.
|
||||
|
||||
See https://deepset.ai/german-bert for more details
|
||||
|
||||
## Hyperparameters
|
||||
|
||||
```
|
||||
batch_size = 1024
|
||||
n_steps = 810_000
|
||||
max_seq_len = 128 (and 512 later)
|
||||
learning_rate = 1e-4
|
||||
lr_schedule = LinearWarmup
|
||||
num_warmup_steps = 10_000
|
||||
```
|
||||
|
||||
## Performance
|
||||
|
||||
During training we monitored the loss and evaluated different model checkpoints on the following German datasets:
|
||||
|
||||
- germEval18Fine: Macro f1 score for multiclass sentiment classification
|
||||
- germEval18coarse: Macro f1 score for binary sentiment classification
|
||||
- germEval14: Seq f1 score for NER (file names deuutf.\*)
|
||||
- CONLL03: Seq f1 score for NER
|
||||
- 10kGNAD: Accuracy for document classification
|
||||
|
||||
Even without thorough hyperparameter tuning, we observed quite stable learning especially for our German model. Multiple restarts with different seeds produced quite similar results.
|
||||
|
||||
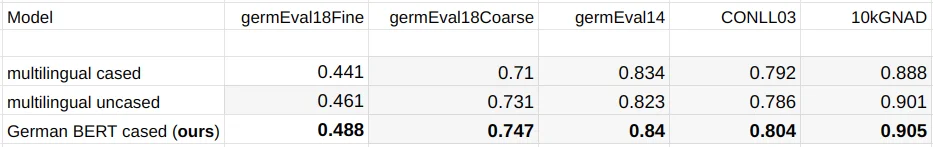
|
||||
|
||||
We further evaluated different points during the 9 days of pre-training and were astonished how fast the model converges to the maximally reachable performance. We ran all 5 downstream tasks on 7 different model checkpoints - taken at 0 up to 840k training steps (x-axis in figure below). Most checkpoints are taken from early training where we expected most performance changes. Surprisingly, even a randomly initialized BERT can be trained only on labeled downstream datasets and reach good performance (blue line, GermEval 2018 Coarse task, 795 kB trainset size).
|
||||
|
||||
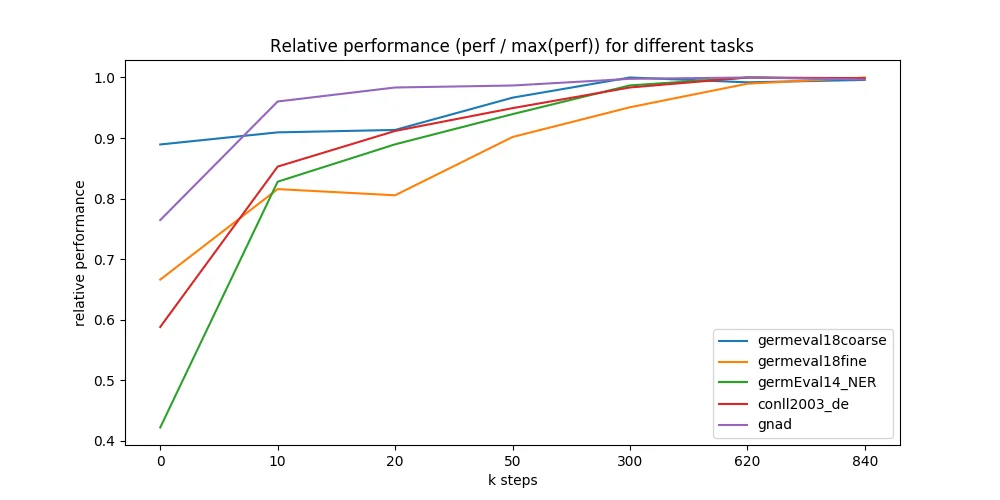
|
||||
|
||||
## Authors
|
||||
Branden Chan: `branden.chan [at] deepset.ai`
|
||||
Timo Möller: `timo.moeller [at] deepset.ai`
|
||||
Malte Pietsch: `malte.pietsch [at] deepset.ai`
|
||||
Tanay Soni: `tanay.soni [at] deepset.ai`
|
||||
|
||||
## About us
|
||||
|
||||
|
||||
We bring NLP to the industry via open source!
|
||||
Our focus: Industry specific language models & large scale QA systems.
|
||||
|
||||
Some of our work:
|
||||
- [German BERT (aka "bert-base-german-cased")](https://deepset.ai/german-bert)
|
||||
- [FARM](https://github.com/deepset-ai/FARM)
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
@@ -0,0 +1,20 @@
|
||||
---
|
||||
thumbnail: https://raw.githubusercontent.com/JetRunner/BERT-of-Theseus/master/bert-of-theseus.png
|
||||
---
|
||||
|
||||
# BERT-of-Theseus
|
||||
See our paper ["BERT-of-Theseus: Compressing BERT by Progressive Module Replacing"](http://arxiv.org/abs/2002.02925).
|
||||
|
||||
BERT-of-Theseus is a new compressed BERT by progressively replacing the components of the original BERT.
|
||||
|
||||
|
||||
|
||||
## Load Pretrained Model on MNLI
|
||||
|
||||
We provide a 6-layer pretrained model on MNLI as a general-purpose model, which can transfer to other sentence classification tasks, outperforming DistillBERT (with the same 6-layer structure) on six tasks of GLUE (dev set).
|
||||
|
||||
| Method | MNLI | MRPC | QNLI | QQP | RTE | SST-2 | STS-B |
|
||||
|-----------------|------|------|------|------|------|-------|-------|
|
||||
| BERT-base | 83.5 | 89.5 | 91.2 | 89.8 | 71.1 | 91.5 | 88.9 |
|
||||
| DistillBERT | 79.0 | 87.5 | 85.3 | 84.9 | 59.9 | 90.7 | 81.2 |
|
||||
| BERT-of-Theseus | 82.1 | 87.5 | 88.8 | 88.8 | 70.1 | 91.8 | 87.8 |
|
||||
@@ -0,0 +1,70 @@
|
||||
---
|
||||
language: german
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz German BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources another German BERT models 🎉
|
||||
|
||||
# German BERT
|
||||
|
||||
## Stats
|
||||
|
||||
In addition to the recently released [German BERT](https://deepset.ai/german-bert)
|
||||
model by [deepset](https://deepset.ai/) we provide another German-language model.
|
||||
|
||||
The source data for the model consists of a recent Wikipedia dump, EU Bookshop corpus,
|
||||
Open Subtitles, CommonCrawl, ParaCrawl and News Crawl. This results in a dataset with
|
||||
a size of 16GB and 2,350,234,427 tokens.
|
||||
|
||||
For sentence splitting, we use [spacy](https://spacy.io/). Our preprocessing steps
|
||||
(sentence piece model for vocab generation) follow those used for training
|
||||
[SciBERT](https://github.com/allenai/scibert). The model is trained with an initial
|
||||
sequence length of 512 subwords and was performed for 1.5M steps.
|
||||
|
||||
This release includes both cased and uncased models.
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| -------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `bert-base-german-dbmdz-cased` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-cased-config.json) • [`pytorch_model.bin`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-cased-pytorch_model.bin) • [`vocab.txt`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-cased-vocab.txt)
|
||||
| `bert-base-german-dbmdz-uncased` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-uncased-config.json) • [`pytorch_model.bin`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-uncased-pytorch_model.bin) • [`vocab.txt`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-uncased-vocab.txt)
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our German BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-german-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-german-cased")
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
For results on downstream tasks like NER or PoS tagging, please refer to
|
||||
[this repository](https://github.com/stefan-it/fine-tuned-berts-seq).
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
language: german
|
||||
tags:
|
||||
- "historic german"
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources German Europeana BERT models 🎉
|
||||
|
||||
# German Europeana BERT
|
||||
|
||||
We use the open source [Europeana newspapers](http://www.europeana-newspapers.eu/)
|
||||
that were provided by *The European Library*. The final
|
||||
training corpus has a size of 51GB and consists of 8,035,986,369 tokens.
|
||||
|
||||
Detailed information about the data and pretraining steps can be found in
|
||||
[this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| ------------------------------------------ | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-german-europeana-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-cased/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on Historic NER, please refer to [this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our German Europeana BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-german-europeana-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-german-europeana-cased")
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,61 @@
|
||||
---
|
||||
language: german
|
||||
tags:
|
||||
- "historic german"
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources German Europeana BERT models 🎉
|
||||
|
||||
# German Europeana BERT
|
||||
|
||||
We use the open source [Europeana newspapers](http://www.europeana-newspapers.eu/)
|
||||
that were provided by *The European Library*. The final
|
||||
training corpus has a size of 51GB and consists of 8,035,986,369 tokens.
|
||||
|
||||
Detailed information about the data and pretraining steps can be found in
|
||||
[this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| ------------------------------------------ | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-german-europeana-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-german-europeana-uncased/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on Historic NER, please refer to [this repository](https://github.com/stefan-it/europeana-bert).
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our German Europeana BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-german-europeana-uncased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-german-europeana-uncased")
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,70 @@
|
||||
---
|
||||
language: german
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz German BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources another German BERT models 🎉
|
||||
|
||||
# German BERT
|
||||
|
||||
## Stats
|
||||
|
||||
In addition to the recently released [German BERT](https://deepset.ai/german-bert)
|
||||
model by [deepset](https://deepset.ai/) we provide another German-language model.
|
||||
|
||||
The source data for the model consists of a recent Wikipedia dump, EU Bookshop corpus,
|
||||
Open Subtitles, CommonCrawl, ParaCrawl and News Crawl. This results in a dataset with
|
||||
a size of 16GB and 2,350,234,427 tokens.
|
||||
|
||||
For sentence splitting, we use [spacy](https://spacy.io/). Our preprocessing steps
|
||||
(sentence piece model for vocab generation) follow those used for training
|
||||
[SciBERT](https://github.com/allenai/scibert). The model is trained with an initial
|
||||
sequence length of 512 subwords and was performed for 1.5M steps.
|
||||
|
||||
This release includes both cased and uncased models.
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| -------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `bert-base-german-dbmdz-cased` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-cased-config.json) • [`pytorch_model.bin`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-cased-pytorch_model.bin) • [`vocab.txt`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-cased-vocab.txt)
|
||||
| `bert-base-german-dbmdz-uncased` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-uncased-config.json) • [`pytorch_model.bin`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-uncased-pytorch_model.bin) • [`vocab.txt`](https://s3.amazonaws.com/models.huggingface.co/bert/bert-base-german-dbmdz-uncased-vocab.txt)
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our German BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-german-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-german-cased")
|
||||
```
|
||||
|
||||
## Results
|
||||
|
||||
For results on downstream tasks like NER or PoS tagging, please refer to
|
||||
[this repository](https://github.com/stefan-it/fine-tuned-berts-seq).
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,77 @@
|
||||
---
|
||||
language: italian
|
||||
---
|
||||
|
||||
# 🤗 + 📚 dbmdz BERT models
|
||||
|
||||
In this repository the MDZ Digital Library team (dbmdz) at the Bavarian State
|
||||
Library open sources Italian BERT models 🎉
|
||||
|
||||
# Italian BERT
|
||||
|
||||
The source data for the Italian BERT model consists of a recent Wikipedia dump and
|
||||
various texts from the [OPUS corpora](http://opus.nlpl.eu/) collection. The final
|
||||
training corpus has a size of 13GB and 2,050,057,573 tokens.
|
||||
|
||||
For sentence splitting, we use NLTK (faster compared to spacy).
|
||||
Our cased and uncased models are training with an initial sequence length of 512
|
||||
subwords for ~2-3M steps.
|
||||
|
||||
For the XXL Italian models, we use the same training data from OPUS and extend
|
||||
it with data from the Italian part of the [OSCAR corpus](https://traces1.inria.fr/oscar/).
|
||||
Thus, the final training corpus has a size of 81GB and 13,138,379,147 tokens.
|
||||
|
||||
## Model weights
|
||||
|
||||
Currently only PyTorch-[Transformers](https://github.com/huggingface/transformers)
|
||||
compatible weights are available. If you need access to TensorFlow checkpoints,
|
||||
please raise an issue!
|
||||
|
||||
| Model | Downloads
|
||||
| --------------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `dbmdz/bert-base-italian-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-uncased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-cased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-cased/vocab.txt)
|
||||
| `dbmdz/bert-base-italian-xxl-uncased` | [`config.json`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/config.json) • [`pytorch_model.bin`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/pytorch_model.bin) • [`vocab.txt`](https://cdn.huggingface.co/dbmdz/bert-base-italian-xxl-uncased/vocab.txt)
|
||||
|
||||
## Results
|
||||
|
||||
For results on downstream tasks like NER or PoS tagging, please refer to
|
||||
[this repository](https://github.com/stefan-it/fine-tuned-berts-seq).
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.3 our Italian BERT models can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-italian-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-italian-cased")
|
||||
```
|
||||
|
||||
To load the (recommended) Italian XXL BERT models, just use:
|
||||
|
||||
```python
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("dbmdz/bert-base-italian-xxl-cased")
|
||||
model = AutoModel.from_pretrained("dbmdz/bert-base-italian-xxl-cased")
|
||||
```
|
||||
|
||||
# Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/dbmdz).
|
||||
|
||||
# Contact (Bugs, Feedback, Contribution and more)
|
||||
|
||||
For questions about our BERT models just open an issue
|
||||
[here](https://github.com/dbmdz/berts/issues/new) 🤗
|
||||
|
||||
# Acknowledgments
|
||||
|
||||
Research supported with Cloud TPUs from Google's TensorFlow Research Cloud (TFRC).
|
||||
Thanks for providing access to the TFRC ❤️
|
||||
|
||||
Thanks to the generous support from the [Hugging Face](https://huggingface.co/) team,
|
||||
it is possible to download both cased and uncased models from their S3 storage 🤗
|
||||
@@ -0,0 +1,104 @@
|
||||
# roberta-base for QA
|
||||
|
||||
## Overview
|
||||
**Language model:** roberta-base
|
||||
**Language:** English
|
||||
**Downstream-task:** Extractive QA
|
||||
**Training data:** SQuAD 2.0
|
||||
**Eval data:** SQuAD 2.0
|
||||
**Code:** See [example](https://github.com/deepset-ai/FARM/blob/master/examples/question_answering.py) in [FARM](https://github.com/deepset-ai/FARM/blob/master/examples/question_answering.py)
|
||||
**Infrastructure**: 4x Tesla v100
|
||||
|
||||
## Hyperparameters
|
||||
|
||||
```
|
||||
batch_size = 50
|
||||
n_epochs = 3
|
||||
base_LM_model = "roberta-base"
|
||||
max_seq_len = 384
|
||||
learning_rate = 3e-5
|
||||
lr_schedule = LinearWarmup
|
||||
warmup_proportion = 0.2
|
||||
doc_stride=128
|
||||
max_query_length=64
|
||||
```
|
||||
|
||||
## Performance
|
||||
Evaluated on the SQuAD 2.0 dev set with the [official eval script](https://worksheets.codalab.org/rest/bundles/0x6b567e1cf2e041ec80d7098f031c5c9e/contents/blob/).
|
||||
```
|
||||
"exact": 78.49743114629833,
|
||||
"f1": 81.73092721240889
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### In Transformers
|
||||
```python
|
||||
from transformers.pipelines import pipeline
|
||||
from transformers.modeling_auto import AutoModelForQuestionAnswering
|
||||
from transformers.tokenization_auto import AutoTokenizer
|
||||
|
||||
model_name = "deepset/roberta-base-squad2"
|
||||
|
||||
# a) Get predictions
|
||||
nlp = pipeline('question-answering', model=model_name, tokenizer=model_name)
|
||||
QA_input = {
|
||||
'question': 'Why is model conversion important?',
|
||||
'context': 'The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks.'
|
||||
}
|
||||
res = nlp(QA_input)
|
||||
|
||||
# b) Load model & tokenizer
|
||||
model = AutoModelForQuestionAnswering.from_pretrained(model_name)
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
||||
```
|
||||
|
||||
### In FARM
|
||||
|
||||
```python
|
||||
from farm.modeling.adaptive_model import AdaptiveModel
|
||||
from farm.modeling.tokenization import Tokenizer
|
||||
from farm.infer import Inferencer
|
||||
|
||||
model_name = "deepset/roberta-base-squad2"
|
||||
|
||||
# a) Get predictions
|
||||
nlp = Inferencer.load(model_name, task_type="question_answering")
|
||||
QA_input = [{"questions": ["Why is model conversion important?"],
|
||||
"text": "The option to convert models between FARM and transformers gives freedom to the user and let people easily switch between frameworks."}]
|
||||
res = nlp.inference_from_dicts(dicts=QA_input, rest_api_schema=True)
|
||||
|
||||
# b) Load model & tokenizer
|
||||
model = AdaptiveModel.convert_from_transformers(model_name, device="cpu", task_type="question_answering")
|
||||
tokenizer = Tokenizer.load(model_name)
|
||||
```
|
||||
|
||||
### In haystack
|
||||
For doing QA at scale (i.e. many docs instead of single paragraph), you can load the model also in [haystack](https://github.com/deepset-ai/haystack/):
|
||||
```python
|
||||
reader = FARMReader(model_name_or_path="deepset/roberta-base-squad2")
|
||||
# or
|
||||
reader = TransformersReader(model="deepset/roberta-base-squad2",tokenizer="deepset/roberta-base-squad2")
|
||||
```
|
||||
|
||||
|
||||
## Authors
|
||||
Branden Chan: `branden.chan [at] deepset.ai`
|
||||
Timo Möller: `timo.moeller [at] deepset.ai`
|
||||
Malte Pietsch: `malte.pietsch [at] deepset.ai`
|
||||
Tanay Soni: `tanay.soni [at] deepset.ai`
|
||||
|
||||
## About us
|
||||

|
||||
|
||||
We bring NLP to the industry via open source!
|
||||
Our focus: Industry specific language models & large scale QA systems.
|
||||
|
||||
Some of our work:
|
||||
- [German BERT (aka "bert-base-german-cased")](https://deepset.ai/german-bert)
|
||||
- [FARM](https://github.com/deepset-ai/FARM)
|
||||
- [Haystack](https://github.com/deepset-ai/haystack/)
|
||||
|
||||
Get in touch:
|
||||
[Twitter](https://twitter.com/deepset_ai) | [LinkedIn](https://www.linkedin.com/company/deepset-ai/) | [Website](https://deepset.ai)
|
||||
|
||||
@@ -0,0 +1,48 @@
|
||||
---
|
||||
language: french
|
||||
---
|
||||
|
||||
# flaubert-base-uncased-squad
|
||||
|
||||
## Description
|
||||
|
||||
A baseline model for question-answering in french ([flaubert](https://github.com/getalp/Flaubert) model fine-tuned on [french-translated SQuAD 1.1 dataset](https://github.com/Alikabbadj/French-SQuAD))
|
||||
|
||||
## Training hyperparameters
|
||||
|
||||
```shell
|
||||
python3 ./examples/run_squad.py \
|
||||
--model_type flaubert \
|
||||
--model_name_or_path flaubert-base-uncased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file SQuAD-v1.1-train_fr_ss999_awstart2_net.json \
|
||||
--predict_file SQuAD-v1.1-dev_fr_ss999_awstart2_net.json \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir output \
|
||||
--per_gpu_eval_batch_size=3 \
|
||||
--per_gpu_train_batch_size=3
|
||||
```
|
||||
|
||||
## Evaluation results
|
||||
|
||||
```shell
|
||||
{"f1": 68.66174806561969, "exact_match": 49.299692063176714}
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
nlp = pipeline('question-answering', model='fmikaelian/flaubert-base-uncased-squad', tokenizer='fmikaelian/flaubert-base-uncased-squad')
|
||||
|
||||
nlp({
|
||||
'question': "Qui est Claude Monet?",
|
||||
'context': "Claude Monet, né le 14 novembre 1840 à Paris et mort le 5 décembre 1926 à Giverny, est un peintre français et l’un des fondateurs de l'impressionnisme."
|
||||
})
|
||||
```
|
||||
@@ -0,0 +1,50 @@
|
||||
---
|
||||
language: dutch
|
||||
---
|
||||
|
||||
# Multilingual + Dutch SQuAD2.0
|
||||
|
||||
This model is the multilingual model provided by the Google research team with a fine-tuned dutch Q&A downstream task.
|
||||
|
||||
## Details of the language model(bert-base-multilingual-cased)
|
||||
|
||||
Language model ([**bert-base-multilingual-cased**](https://github.com/google-research/bert/blob/master/multilingual.md)):
|
||||
12-layer, 768-hidden, 12-heads, 110M parameters.
|
||||
Trained on cased text in the top 104 languages with the largest Wikipedias.
|
||||
|
||||
## Details of the downstream task - Dataset
|
||||
Using the `mtranslate` Python module, [**SQuAD2.0**](https://rajpurkar.github.io/SQuAD-explorer/) was machine-translated. In order to find the start tokens the direct translations of the answers were searched in the corresponding paragraphs. Since the answer could not always be found in the text, due to the different translations depending on the context (missing context in the pure answer), a loss of question-answer examples occurred. This is a potential problem where errors can occur in the data set (but in the end it was a quick and dirty solution that worked well enough for my task).
|
||||
|
||||
| Dataset | # Q&A |
|
||||
| ---------------------- | ----- |
|
||||
| SQuAD2.0 Train | 130 K |
|
||||
| Dutch SQuAD2.0 Train | 99 K |
|
||||
| SQuAD2.0 Dev | 12 K |
|
||||
| Dutch SQuAD2.0 Dev | 10 K |
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla V100 GPU with the following command:
|
||||
|
||||
```python
|
||||
export SQUAD_DIR=path/to/nl_squad
|
||||
|
||||
python run_squad.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path bert-base-multilingual-cased \
|
||||
--version_2_with_negative \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--train_file $SQUAD_DIR/train_nl-v2.0.json \
|
||||
--predict_file $SQUAD_DIR/dev_nl-v2.0.json \
|
||||
--per_gpu_train_batch_size 12 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2.0 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /tmp/output_dir/
|
||||
```
|
||||
|
||||
**Results**:
|
||||
|
||||
{'exact': **67.38**, 'f1': **71.36**}
|
||||
@@ -0,0 +1,31 @@
|
||||
# Tensorflow CamemBERT
|
||||
|
||||
In this repository you will find different versions of the CamemBERT model for Tensorflow.
|
||||
|
||||
## CamemBERT
|
||||
|
||||
[CamemBERT](https://camembert-model.fr/) is a state-of-the-art language model for French based on the RoBERTa architecture pretrained on the French subcorpus of the newly available multilingual corpus OSCAR.
|
||||
|
||||
## Model Weights
|
||||
|
||||
| Model | Downloads
|
||||
| -------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `jplu/tf-camembert-base` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/jplu/tf-camembert-base/config.json) • [`tf_model.h5`](https://s3.amazonaws.com/models.huggingface.co/bert/jplu/tf-camembert-base/tf_model.h5)
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.4 the Tensorflow models of CamemBERT can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import TFCamembertModel
|
||||
|
||||
model = TFCamembertModel.from_pretrained("jplu/tf-camembert-base")
|
||||
```
|
||||
|
||||
## Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/jplu).
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
Thanks to all the Huggingface team for the support and their amazing library!
|
||||
@@ -0,0 +1,36 @@
|
||||
# Tensorflow XLM-RoBERTa
|
||||
|
||||
In this repository you will find different versions of the XLM-RoBERTa model for Tensorflow.
|
||||
|
||||
## XLM-RoBERTa
|
||||
|
||||
[XLM-RoBERTa](https://ai.facebook.com/blog/-xlm-r-state-of-the-art-cross-lingual-understanding-through-self-supervision/) is a scaled cross lingual sentence encoder. It is trained on 2.5T of data across 100 languages data filtered from Common Crawl. XLM-R achieves state-of-the-arts results on multiple cross lingual benchmarks.
|
||||
|
||||
## Model Weights
|
||||
|
||||
| Model | Downloads
|
||||
| -------------------------------- | ---------------------------------------------------------------------------------------------------------------
|
||||
| `jplu/tf-xlm-roberta-base` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/jplu/tf-xlm-roberta-base/config.json) • [`tf_model.h5`](https://s3.amazonaws.com/models.huggingface.co/bert/jplu/tf-xlm-roberta-base/tf_model.h5)
|
||||
| `jplu/tf-xlm-roberta-large` | [`config.json`](https://s3.amazonaws.com/models.huggingface.co/bert/jplu/tf-xlm-roberta-large/config.json) • [`tf_model.h5`](https://s3.amazonaws.com/models.huggingface.co/bert/jplu/tf-xlm-roberta-large/tf_model.h5)
|
||||
|
||||
## Usage
|
||||
|
||||
With Transformers >= 2.4 the Tensorflow models of XLM-RoBERTa can be loaded like:
|
||||
|
||||
```python
|
||||
from transformers import TFXLMRobertaModel
|
||||
|
||||
model = TFXLMRobertaModel.from_pretrained("jplu/tf-xlm-roberta-base")
|
||||
```
|
||||
Or
|
||||
```
|
||||
model = TFXLMRobertaModel.from_pretrained("jplu/tf-xlm-roberta-large")
|
||||
```
|
||||
|
||||
## Huggingface model hub
|
||||
|
||||
All models are available on the [Huggingface model hub](https://huggingface.co/jplu).
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
Thanks to all the Huggingface team for the support and their amazing library!
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: esperanto
|
||||
thumbnail: https://huggingface.co/blog/assets/EsperBERTo-thumbnail-v2.png
|
||||
---
|
||||
|
||||
# EsperBERTo: RoBERTa-like Language model trained on Esperanto
|
||||
|
||||
**Companion model to blog post https://huggingface.co/blog/how-to-train** 🔥
|
||||
|
||||
## Training Details
|
||||
|
||||
- current checkpoint: 566000
|
||||
- machine name: `galinette`
|
||||
|
||||
|
||||

|
||||
|
||||
## Example pipeline
|
||||
|
||||
```python
|
||||
from transformers import TokenClassificationPipeline, pipeline
|
||||
|
||||
|
||||
MODEL_PATH = "./models/EsperBERTo-small-pos/"
|
||||
|
||||
nlp = pipeline(
|
||||
"ner",
|
||||
model=MODEL_PATH,
|
||||
tokenizer=MODEL_PATH,
|
||||
)
|
||||
# or instantiate a TokenClassificationPipeline directly.
|
||||
|
||||
nlp("Mi estas viro kej estas tago varma.")
|
||||
|
||||
# {'entity': 'PRON', 'score': 0.9979867339134216, 'word': ' Mi'}
|
||||
# {'entity': 'VERB', 'score': 0.9683094620704651, 'word': ' estas'}
|
||||
# {'entity': 'VERB', 'score': 0.9797462821006775, 'word': ' estas'}
|
||||
# {'entity': 'NOUN', 'score': 0.8509314060211182, 'word': ' tago'}
|
||||
# {'entity': 'ADJ', 'score': 0.9996201395988464, 'word': ' varma'}
|
||||
```
|
||||
@@ -0,0 +1,59 @@
|
||||
---
|
||||
language: esperanto
|
||||
thumbnail: https://huggingface.co/blog/assets/EsperBERTo-thumbnail-v2.png
|
||||
---
|
||||
|
||||
# EsperBERTo: RoBERTa-like Language model trained on Esperanto
|
||||
|
||||
**Companion model to blog post https://huggingface.co/blog/how-to-train** 🔥
|
||||
|
||||
## Training Details
|
||||
|
||||
- current checkpoint: 566000
|
||||
- machine name: `galinette`
|
||||
|
||||
|
||||

|
||||
|
||||
## Example pipeline
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
|
||||
fill_mask = pipeline(
|
||||
"fill-mask",
|
||||
model="julien-c/EspertBERTo-small",
|
||||
tokenizer="julien-c/EspertBERTo-small"
|
||||
)
|
||||
|
||||
fill_mask("Jen la komenco de bela <mask>.")
|
||||
|
||||
# This is the beginning of a beautiful <mask>.
|
||||
# =>
|
||||
|
||||
# {
|
||||
# 'score':0.06502299010753632
|
||||
# 'sequence':'<s> Jen la komenco de bela vivo.</s>'
|
||||
# 'token':1099
|
||||
# }
|
||||
# {
|
||||
# 'score':0.0421181358397007
|
||||
# 'sequence':'<s> Jen la komenco de bela vespero.</s>'
|
||||
# 'token':5100
|
||||
# }
|
||||
# {
|
||||
# 'score':0.024884626269340515
|
||||
# 'sequence':'<s> Jen la komenco de bela laboro.</s>'
|
||||
# 'token':1570
|
||||
# }
|
||||
# {
|
||||
# 'score':0.02324388362467289
|
||||
# 'sequence':'<s> Jen la komenco de bela tago.</s>'
|
||||
# 'token':1688
|
||||
# }
|
||||
# {
|
||||
# 'score':0.020378097891807556
|
||||
# 'sequence':'<s> Jen la komenco de bela festo.</s>'
|
||||
# 'token':4580
|
||||
# }
|
||||
```
|
||||
@@ -0,0 +1,25 @@
|
||||
## How to build a dummy model
|
||||
|
||||
|
||||
```python
|
||||
from transformers.configuration_bert import BertConfig
|
||||
from transformers.modeling_bert import BertForMaskedLM
|
||||
from transformers.modeling_tf_bert import TFBertForMaskedLM
|
||||
from transformers.tokenization_bert import BertTokenizer
|
||||
|
||||
|
||||
SMALL_MODEL_IDENTIFIER = "julien-c/bert-xsmall-dummy"
|
||||
DIRNAME = "./bert-xsmall-dummy"
|
||||
|
||||
config = BertConfig(10, 20, 1, 1, 40)
|
||||
|
||||
model = BertForMaskedLM(config)
|
||||
model.save_pretrained(DIRNAME)
|
||||
|
||||
tf_model = TFBertForMaskedLM.from_pretrained(DIRNAME, from_pt=True)
|
||||
tf_model.save_pretrained(DIRNAME)
|
||||
|
||||
# Slightly different for tokenizer.
|
||||
# tokenizer = BertTokenizer.from_pretrained(DIRNAME)
|
||||
# tokenizer.save_pretrained()
|
||||
```
|
||||
@@ -0,0 +1,59 @@
|
||||
---
|
||||
tags:
|
||||
- ci
|
||||
---
|
||||
|
||||
## Dummy model used for unit testing and CI
|
||||
|
||||
|
||||
```python
|
||||
import json
|
||||
import os
|
||||
from transformers.configuration_roberta import RobertaConfig
|
||||
from transformers import RobertaForMaskedLM, TFRobertaForMaskedLM
|
||||
|
||||
DIRNAME = "./dummy-unknown"
|
||||
|
||||
|
||||
config = RobertaConfig(10, 20, 1, 1, 40)
|
||||
|
||||
model = RobertaForMaskedLM(config)
|
||||
model.save_pretrained(DIRNAME)
|
||||
|
||||
tf_model = TFRobertaForMaskedLM.from_pretrained(DIRNAME, from_pt=True)
|
||||
tf_model.save_pretrained(DIRNAME)
|
||||
|
||||
# Tokenizer:
|
||||
|
||||
vocab = [
|
||||
"l",
|
||||
"o",
|
||||
"w",
|
||||
"e",
|
||||
"r",
|
||||
"s",
|
||||
"t",
|
||||
"i",
|
||||
"d",
|
||||
"n",
|
||||
"\u0120",
|
||||
"\u0120l",
|
||||
"\u0120n",
|
||||
"\u0120lo",
|
||||
"\u0120low",
|
||||
"er",
|
||||
"\u0120lowest",
|
||||
"\u0120newer",
|
||||
"\u0120wider",
|
||||
"<unk>",
|
||||
]
|
||||
vocab_tokens = dict(zip(vocab, range(len(vocab))))
|
||||
merges = ["#version: 0.2", "\u0120 l", "\u0120l o", "\u0120lo w", "e r", ""]
|
||||
|
||||
vocab_file = os.path.join(DIRNAME, "vocab.json")
|
||||
merges_file = os.path.join(DIRNAME, "merges.txt")
|
||||
with open(vocab_file, "w", encoding="utf-8") as fp:
|
||||
fp.write(json.dumps(vocab_tokens) + "\n")
|
||||
with open(merges_file, "w", encoding="utf-8") as fp:
|
||||
fp.write("\n".join(merges))
|
||||
```
|
||||
@@ -0,0 +1,7 @@
|
||||
# ArXiv-NLP GPT-2 checkpoint
|
||||
|
||||
This is a GPT-2 small checkpoint for PyTorch. It is the official `gpt2-small` fine-tuned to ArXiv paper on the computational linguistics field.
|
||||
|
||||
## Training data
|
||||
|
||||
This model was trained on a subset of ArXiv papers that were parsed from PDF to txt. The resulting data is made of 80MB of text from the computational linguistics (cs.CL) field.
|
||||
@@ -0,0 +1,7 @@
|
||||
# ArXiv GPT-2 checkpoint
|
||||
|
||||
This is a GPT-2 small checkpoint for PyTorch. It is the official `gpt2-small` finetuned to ArXiv paper on physics fields.
|
||||
|
||||
## Training data
|
||||
|
||||
This model was trained on a subset of ArXiv papers that were parsed from PDF to txt. The resulting data is made of 130MB of text, mostly from quantum physics (quant-ph) and other physics sub-fields.
|
||||
@@ -0,0 +1,91 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# BETO (Spanish BERT) + Spanish SQuAD2.0
|
||||
|
||||
This model is provided by [BETO team](https://github.com/dccuchile/beto) and fine-tuned on [SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve) for **Q&A** downstream task.
|
||||
|
||||
## Details of the language model('dccuchile/bert-base-spanish-wwm-cased')
|
||||
|
||||
Language model ([**'dccuchile/bert-base-spanish-wwm-cased'**](https://github.com/dccuchile/beto/blob/master/README.md)):
|
||||
|
||||
BETO is a [BERT model](https://github.com/google-research/bert) trained on a [big Spanish corpus](https://github.com/josecannete/spanish-corpora). BETO is of size similar to a BERT-Base and was trained with the Whole Word Masking technique. Below you find Tensorflow and Pytorch checkpoints for the uncased and cased versions, as well as some results for Spanish benchmarks comparing BETO with [Multilingual BERT](https://github.com/google-research/bert/blob/master/multilingual.md) as well as other (not BERT-based) models.
|
||||
|
||||
## Details of the downstream task (Q&A) - Dataset
|
||||
[SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve)
|
||||
|
||||
| Dataset | # Q&A |
|
||||
| ---------------------- | ----- |
|
||||
| SQuAD2.0 Train | 130 K |
|
||||
| SQuAD2.0-es-v2.0 | 111 K |
|
||||
| SQuAD2.0 Dev | 12 K |
|
||||
| SQuAD-es-v2.0-small Dev| 69 K |
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||
|
||||
```bash
|
||||
export SQUAD_DIR=path/to/nl_squad
|
||||
python transformers/examples/run_squad.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file $SQUAD_DIR/train_nl-v2.0.json \
|
||||
--predict_file $SQUAD_DIR/dev_nl-v2.0.json \
|
||||
--per_gpu_train_batch_size 12 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 2.0 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
--threads 4 \
|
||||
--version_2_with_negative
|
||||
```
|
||||
|
||||
## Results:
|
||||
|
||||
|
||||
| Metric | # Value |
|
||||
| ---------------------- | ----- |
|
||||
| **Exact** | **76.50**50 |
|
||||
| **F1** | **86.07**81 |
|
||||
|
||||
```json
|
||||
{
|
||||
"exact": 76.50501430594491,
|
||||
"f1": 86.07818773108252,
|
||||
"total": 69202,
|
||||
"HasAns_exact": 67.93020719738277,
|
||||
"HasAns_f1": 82.37912207996466,
|
||||
"HasAns_total": 45850,
|
||||
"NoAns_exact": 93.34104145255225,
|
||||
"NoAns_f1": 93.34104145255225,
|
||||
"NoAns_total": 23352,
|
||||
"best_exact": 76.51223953064941,
|
||||
"best_exact_thresh": 0.0,
|
||||
"best_f1": 86.08541295578848,
|
||||
"best_f1_thresh": 0.0
|
||||
}
|
||||
```
|
||||
|
||||
### Model in action (in a Colab Notebook)
|
||||
<details>
|
||||
|
||||
1. Set the context and ask some questions:
|
||||
|
||||
|
||||
|
||||
2. Run predictions:
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
+108
@@ -0,0 +1,108 @@
|
||||
---
|
||||
language: spanish
|
||||
thumbnail: https://i.imgur.com/jgBdimh.png
|
||||
---
|
||||
|
||||
# BETO (Spanish BERT) + Spanish SQuAD2.0 + distillation using 'bert-base-multilingual-cased' as teacher
|
||||
|
||||
This model is a fine-tuned on [SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve) and **distilled** version of [BETO](https://github.com/dccuchile/beto) for **Q&A**.
|
||||
|
||||
Distillation makes the model **smaller, faster, cheaper and lighter** than [bert-base-spanish-wwm-cased-finetuned-spa-squad2-es](https://github.com/huggingface/transformers/blob/master/model_cards/mrm8488/bert-base-spanish-wwm-cased-finetuned-spa-squad2-es/README.md)
|
||||
|
||||
This model was fine-tuned on the same dataset but using **distillation** during the process as mentioned above (and one more train epoch).
|
||||
|
||||
The **teacher model** for the distillation was `bert-base-multilingual-cased`. It is the same teacher used for `distilbert-base-multilingual-cased` AKA [**DistilmBERT**](https://github.com/huggingface/transformers/tree/master/examples/distillation) (on average is twice as fast as **mBERT-base**).
|
||||
|
||||
## Details of the downstream task (Q&A) - Dataset
|
||||
|
||||
<details>
|
||||
|
||||
[SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve)
|
||||
|
||||
| Dataset | # Q&A |
|
||||
| ----------------------- | ----- |
|
||||
| SQuAD2.0 Train | 130 K |
|
||||
| SQuAD2.0-es-v2.0 | 111 K |
|
||||
| SQuAD2.0 Dev | 12 K |
|
||||
| SQuAD-es-v2.0-small Dev | 69 K |
|
||||
|
||||
</details>
|
||||
|
||||
## Model training
|
||||
|
||||
The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
|
||||
|
||||
```bash
|
||||
!export SQUAD_DIR=/path/to/squad-v2_spanish \
|
||||
&& python transformers/examples/distillation/run_squad_w_distillation.py \
|
||||
--model_type bert \
|
||||
--model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
|
||||
--teacher_type bert \
|
||||
--teacher_name_or_path bert-base-multilingual-cased \
|
||||
--do_train \
|
||||
--do_eval \
|
||||
--do_lower_case \
|
||||
--train_file $SQUAD_DIR/train-v2.json \
|
||||
--predict_file $SQUAD_DIR/dev-v2.json \
|
||||
--per_gpu_train_batch_size 12 \
|
||||
--learning_rate 3e-5 \
|
||||
--num_train_epochs 3.0 \
|
||||
--max_seq_length 384 \
|
||||
--doc_stride 128 \
|
||||
--output_dir /content/model_output \
|
||||
--save_steps 5000 \
|
||||
--threads 4 \
|
||||
--version_2_with_negative
|
||||
```
|
||||
|
||||
## Results:
|
||||
|
||||
| Metric | # Value |
|
||||
| --------- | ----------- |
|
||||
| **Exact** | **82.40**65 |
|
||||
| **F1** | **90.50**36 |
|
||||
|
||||
```json
|
||||
{
|
||||
"exact": 82.40657784457096,
|
||||
"f1": 90.50369643376753,
|
||||
"total": 69202,
|
||||
"HasAns_exact": 75.13413304253,
|
||||
"HasAns_f1": 87.35521920631561,
|
||||
"HasAns_total": 45850,
|
||||
"NoAns_exact": 96.68550873586845,
|
||||
"NoAns_f1": 96.68550873586845,
|
||||
"NoAns_total": 23352,
|
||||
"best_exact": 82.40657784457096,
|
||||
"best_exact_thresh": 0.0,
|
||||
"best_f1": 90.50369643376902,
|
||||
"best_f1_thresh": 0.0
|
||||
}
|
||||
```
|
||||
|
||||
## Comparison:
|
||||
|
||||
| Model | f1 score |
|
||||
| :-------------------------------------------------------------: | :-------: |
|
||||
| bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | 86.07 |
|
||||
| **distill**-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | **90.50** |
|
||||
|
||||
So, yes, this version is even more accurate.
|
||||
|
||||
### Model in action (in a Colab Notebook)
|
||||
|
||||
<details>
|
||||
|
||||
1. Set the context and ask some questions:
|
||||
|
||||

|
||||
|
||||
2. Run predictions:
|
||||
|
||||

|
||||
|
||||
</details>
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -0,0 +1,93 @@
|
||||
---
|
||||
language: greek
|
||||
thumbnail: https://github.com/nlpaueb/GreekBERT/raw/master/greek-bert-logo.png
|
||||
---
|
||||
|
||||
# GreekBERT
|
||||
|
||||
A Greek version of BERT pre-trained language model.
|
||||
|
||||
<img src="https://github.com/nlpaueb/GreekBERT/raw/master/greek-bert-logo.png" width="600"/>
|
||||
|
||||
|
||||
## Pre-training corpora
|
||||
|
||||
The pre-training corpora of `bert-base-greek-uncased-v1` include:
|
||||
|
||||
* The Greek part of [Wikipedia](https://el.wikipedia.org/wiki/Βικιπαίδεια:Αντίγραφα_της_βάσης_δεδομένων),
|
||||
* The Greek part of [European Parliament Proceedings Parallel Corpus](https://www.statmt.org/europarl/), and
|
||||
* The Greek part of [OSCAR](https://traces1.inria.fr/oscar/), a cleansed version of [Common Crawl](https://commoncrawl.org).
|
||||
|
||||
Future release will also include:
|
||||
|
||||
* The entire corpus of Greek legislation, as published by the [National Publication Office](http://www.et.gr),
|
||||
* The entire corpus of EU legislation (Greek translation), as published in [Eur-Lex](https://eur-lex.europa.eu/homepage.html?locale=en).
|
||||
|
||||
## Pre-training details
|
||||
|
||||
* We trained BERT using the official code provided in Google BERT's github repository (https://github.com/google-research/bert). We then used [Hugging Face](https://huggingface.co)'s [Transformers](https://github.com/huggingface/transformers) conversion script to convert the TF checkpoint and vocabulary in the desirable format in order to be able to load the model in two lines of code for both PyTorch and TF2 users.
|
||||
* We released a model similar to the English `bert-base-uncased` model (12-layer, 768-hidden, 12-heads, 110M parameters).
|
||||
* We chose to follow the same training set-up: 1 million training steps with batches of 256 sequences of length 512 with an initial learning rate 1e-4.
|
||||
* We were able to use a single Google Cloud TPU v3-8 provided for free from [TensorFlow Research Cloud (TFRC)](https://www.tensorflow.org/tfrc), while also utilizing [GCP research credits](https://edu.google.com/programs/credits/research). Huge thanks to both Google programs for supporting us!
|
||||
|
||||
|
||||
## Requirements
|
||||
|
||||
We published `bert-base-greek-uncased-v1` as part of [Hugging Face](https://huggingface.co)'s [Transformers](https://github.com/huggingface/transformers) repository. So, you need to install the transfomers library through pip along with PyTorch or Tensorflow 2.
|
||||
|
||||
```
|
||||
pip install transfomers
|
||||
pip install (torch|tensorflow)
|
||||
```
|
||||
|
||||
## Pre-process text (Deaccent - Lower)
|
||||
|
||||
In order to use `bert-base-greek-uncased-v1`, you have to pre-process texts to lowercase letters and remove all Greek diacritics.
|
||||
|
||||
```python
|
||||
|
||||
import unicodedata
|
||||
|
||||
def strip_accents_and_lowercase(s):
|
||||
return ''.join(c for c in unicodedata.normalize('NFD', s)
|
||||
if unicodedata.category(c) != 'Mn').lower()
|
||||
|
||||
accented_string = "Αυτή είναι η Ελληνική έκδοση του BERT."
|
||||
unaccented_string = strip_accents_and_lowercase(accented_string)
|
||||
|
||||
print(unaccented_string) # αυτη ειναι η ελληνικη εκδοση του bert.
|
||||
|
||||
```
|
||||
|
||||
## Load Pretrained Model
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("nlpaueb/bert-base-greek-uncased-v1")
|
||||
model = AutoModel.from_pretrained("nlpaueb/bert-base-greek-uncased-v1")
|
||||
```
|
||||
|
||||
## Evaluation on downstream tasks
|
||||
|
||||
TBA
|
||||
|
||||
## Author
|
||||
|
||||
Ilias Chalkidis on behalf of [AUEB's Natural Language Processing Group](http://nlp.cs.aueb.gr)
|
||||
|
||||
| Github: [@ilias.chalkidis](https://github.com/seolhokim) | Twitter: [@KiddoThe2B](https://twitter.com/KiddoThe2B) |
|
||||
|
||||
## About Us
|
||||
|
||||
[AUEB's Natural Language Processing Group](http://nlp.cs.aueb.gr) develops algorithms, models, and systems that allow computers to process and generate natural language texts.
|
||||
|
||||
The group's current research interests include:
|
||||
* question answering systems for databases, ontologies, document collections, and the Web, especially biomedical question answering,
|
||||
* natural language generation from databases and ontologies, especially Semantic Web ontologies,
|
||||
text classification, including filtering spam and abusive content,
|
||||
* information extraction and opinion mining, including legal text analytics and sentiment analysis,
|
||||
* natural language processing tools for Greek, for example parsers and named-entity recognizers,
|
||||
machine learning in natural language processing, especially deep learning.
|
||||
|
||||
The group is part of the Information Processing Laboratory of the Department of Informatics of the Athens University of Economics and Business.
|
||||
@@ -0,0 +1,49 @@
|
||||
---
|
||||
language:
|
||||
- english
|
||||
- dutch
|
||||
- german
|
||||
- french
|
||||
- italian
|
||||
- spanish
|
||||
---
|
||||
|
||||
# bert-base-multilingual-uncased-sentiment
|
||||
|
||||
This a bert-base-multilingual-uncased model finetuned for sentiment analysis on product reviews in six languages: English, Dutch, German, French, Spanish and Italian. It predicts the sentiment of the review as a number of stars (between 1 and 5).
|
||||
|
||||
This model is intended for direct use as a sentiment analysis model for product reviews in any of the six languages above, or for further finetuning on related sentiment analysis tasks.
|
||||
|
||||
## Training data
|
||||
|
||||
Here is the number of product reviews we used for finetuning the model:
|
||||
|
||||
| Language | Number of reviews |
|
||||
| -------- | ----------------- |
|
||||
| English | 150k |
|
||||
| Dutch | 80k |
|
||||
| German | 137k |
|
||||
| French | 140k |
|
||||
| Italian | 72k |
|
||||
| Spanish | 50k |
|
||||
|
||||
## Accuracy
|
||||
|
||||
The finetuned model obtained the following accuracy on 5,000 held-out product reviews in each of the languages:
|
||||
|
||||
- Accuracy (exact) is the exact match on the number of stars.
|
||||
- Accuracy (off-by-1) is the percentage of reviews where the number of stars the model predicts differs by a maximum of 1 from the number given by the human reviewer.
|
||||
|
||||
|
||||
| Language | Accuracy (exact) | Accuracy (off-by-1) |
|
||||
| -------- | ---------------------- | ------------------- |
|
||||
| English | 67% | 95%
|
||||
| Dutch | 57% | 93%
|
||||
| German | 61% | 94%
|
||||
| French | 59% | 94%
|
||||
| Italian | 59% | 95%
|
||||
| Spanish | 58% | 95%
|
||||
|
||||
## Contact
|
||||
|
||||
Contact [NLP Town](https://www.nlp.town) for questions, feedback and/or requests for similar models.
|
||||
@@ -0,0 +1,51 @@
|
||||
---
|
||||
language: german
|
||||
thumbnail: kfold.png
|
||||
---
|
||||
|
||||
# German BERT for literary texts
|
||||
|
||||
This German BERT is based on `bert-base-german-dbmdz-cased`, and has been adapted to the domain of literary texts by fine-tuning the language modeling task on the [Corpus of German-Language Fiction](https://figshare.com/articles/Corpus_of_German-Language_Fiction_txt_/4524680/1). Afterwards the model was fine-tuned for named entity recognition on the [DROC](https://gitlab2.informatik.uni-wuerzburg.de/kallimachos/DROC-Release) corpus, so you can use it to recognize protagonists in German novels.
|
||||
|
||||
|
||||
# Stats
|
||||
|
||||
## Language modeling
|
||||
|
||||
The [Corpus of German-Language Fiction](https://figshare.com/articles/Corpus_of_German-Language_Fiction_txt_/4524680/1) consists of 3,194 documents with 203,516,988 tokens or 1,520,855 types. The publication year of the texts ranges from the 18th to the 20th century:
|
||||
|
||||

|
||||
|
||||
|
||||
### Results
|
||||
|
||||
After one epoch:
|
||||
|
||||
| Model | Perplexity |
|
||||
| ---------------- | ---------- |
|
||||
| Vanilla BERT | 6.82 |
|
||||
| Fine-tuned BERT | 4.98 |
|
||||
|
||||
|
||||
## Named entity recognition
|
||||
|
||||
The provided model was also fine-tuned for two epochs on 10,799 sentences for training, validated on 547 and tested on 1,845 with three labels: `B-PER`, `I-PER` and `O`.
|
||||
|
||||
|
||||
## Results
|
||||
|
||||
| Dataset | Precision | Recall | F1 |
|
||||
| ------- | --------- | ------ | ---- |
|
||||
| Dev | 96.4 | 87.3 | 91.6 |
|
||||
| Test | 92.8 | 94.9 | 93.8 |
|
||||
|
||||
The model has also been evaluated using 10-fold cross validation and compared with a classic Conditional Random Field baseline described in [Jannidis et al.](https://opus.bibliothek.uni-wuerzburg.de/opus4-wuerzburg/frontdoor/deliver/index/docId/14333/file/Jannidis_Figurenerkennung_Roman.pdf) (2015):
|
||||
|
||||

|
||||
|
||||
|
||||
# References
|
||||
|
||||
Markus Krug, Lukas Weimer, Isabella Reger, Luisa Macharowsky, Stephan Feldhaus, Frank Puppe, Fotis Jannidis, [Description of a Corpus of Character References in German Novels](http://webdoc.sub.gwdg.de/pub/mon/dariah-de/dwp-2018-27.pdf), 2018.
|
||||
|
||||
Fotis Jannidis, Isabella Reger, Lukas Weimer, Markus Krug, Martin Toepfer, Frank Puppe, [Automatische Erkennung von Figuren in deutschsprachigen Romanen](https://opus.bibliothek.uni-wuerzburg.de/opus4-wuerzburg/frontdoor/deliver/index/docId/14333/file/Jannidis_Figurenerkennung_Roman.pdf), 2015.
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 5.6 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 21 KiB |
@@ -23,6 +23,8 @@ To create the package for pypi.
|
||||
|
||||
twine upload dist/* -r pypitest
|
||||
(pypi suggest using twine as other methods upload files via plaintext.)
|
||||
You may have to specify the repository url, use the following command then:
|
||||
twine upload dist/* -r pypitest --repository-url=https://test.pypi.org/legacy/
|
||||
|
||||
Check that you can install it in a virtualenv by running:
|
||||
pip install -i https://testpypi.python.org/pypi transformers
|
||||
@@ -61,9 +63,10 @@ extras = {}
|
||||
extras["mecab"] = ["mecab-python3"]
|
||||
extras["sklearn"] = ["scikit-learn"]
|
||||
extras["tf"] = ["tensorflow"]
|
||||
extras["tf-cpu"] = ["tensorflow-cpu"]
|
||||
extras["torch"] = ["torch"]
|
||||
|
||||
extras["serving"] = ["pydantic", "uvicorn", "fastapi"]
|
||||
extras["serving"] = ["pydantic", "uvicorn", "fastapi", "starlette"]
|
||||
extras["all"] = extras["serving"] + ["tensorflow", "torch"]
|
||||
|
||||
extras["testing"] = ["pytest", "pytest-xdist"]
|
||||
@@ -73,7 +76,7 @@ extras["dev"] = extras["testing"] + extras["quality"] + ["mecab-python3", "sciki
|
||||
|
||||
setup(
|
||||
name="transformers",
|
||||
version="2.3.0",
|
||||
version="2.4.1",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
author_email="thomas@huggingface.co",
|
||||
description="State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch",
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# There's no way to ignore "F401 '...' imported but unused" warnings in this
|
||||
# module, but to preserve other warnings. So, don't check this module at all.
|
||||
|
||||
__version__ = "2.3.0"
|
||||
__version__ = "2.4.1"
|
||||
|
||||
# Work around to update TensorFlow's absl.logging threshold which alters the
|
||||
# default Python logging output behavior when present.
|
||||
@@ -25,6 +25,7 @@ from .configuration_bert import BERT_PRETRAINED_CONFIG_ARCHIVE_MAP, BertConfig
|
||||
from .configuration_camembert import CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, CamembertConfig
|
||||
from .configuration_ctrl import CTRL_PRETRAINED_CONFIG_ARCHIVE_MAP, CTRLConfig
|
||||
from .configuration_distilbert import DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, DistilBertConfig
|
||||
from .configuration_flaubert import FLAUBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, FlaubertConfig
|
||||
from .configuration_gpt2 import GPT2_PRETRAINED_CONFIG_ARCHIVE_MAP, GPT2Config
|
||||
from .configuration_mmbt import MMBTConfig
|
||||
from .configuration_openai import OPENAI_GPT_PRETRAINED_CONFIG_ARCHIVE_MAP, OpenAIGPTConfig
|
||||
@@ -92,6 +93,7 @@ from .modeling_tf_pytorch_utils import (
|
||||
from .pipelines import (
|
||||
CsvPipelineDataFormat,
|
||||
FeatureExtractionPipeline,
|
||||
FillMaskPipeline,
|
||||
JsonPipelineDataFormat,
|
||||
NerPipeline,
|
||||
PipedPipelineDataFormat,
|
||||
@@ -99,6 +101,7 @@ from .pipelines import (
|
||||
PipelineDataFormat,
|
||||
QuestionAnsweringPipeline,
|
||||
TextClassificationPipeline,
|
||||
TokenClassificationPipeline,
|
||||
pipeline,
|
||||
)
|
||||
from .tokenization_albert import AlbertTokenizer
|
||||
@@ -108,6 +111,7 @@ from .tokenization_bert_japanese import BertJapaneseTokenizer, CharacterTokenize
|
||||
from .tokenization_camembert import CamembertTokenizer
|
||||
from .tokenization_ctrl import CTRLTokenizer
|
||||
from .tokenization_distilbert import DistilBertTokenizer
|
||||
from .tokenization_flaubert import FlaubertTokenizer
|
||||
from .tokenization_gpt2 import GPT2Tokenizer, GPT2TokenizerFast
|
||||
from .tokenization_openai import OpenAIGPTTokenizer
|
||||
from .tokenization_roberta import RobertaTokenizer
|
||||
@@ -133,6 +137,7 @@ if is_torch_available():
|
||||
from .modeling_utils import PreTrainedModel, prune_layer, Conv1D
|
||||
from .modeling_auto import (
|
||||
AutoModel,
|
||||
AutoModelForPreTraining,
|
||||
AutoModelForSequenceClassification,
|
||||
AutoModelForQuestionAnswering,
|
||||
AutoModelWithLMHead,
|
||||
@@ -208,6 +213,13 @@ if is_torch_available():
|
||||
RobertaForQuestionAnswering,
|
||||
ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_camembert import (
|
||||
CamembertForMaskedLM,
|
||||
CamembertModel,
|
||||
CamembertForSequenceClassification,
|
||||
CamembertForTokenClassification,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_distilbert import (
|
||||
DistilBertPreTrainedModel,
|
||||
DistilBertForMaskedLM,
|
||||
@@ -248,9 +260,19 @@ if is_torch_available():
|
||||
XLMRobertaForMultipleChoice,
|
||||
XLMRobertaForSequenceClassification,
|
||||
XLMRobertaForTokenClassification,
|
||||
XLM_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
from .modeling_mmbt import ModalEmbeddings, MMBTModel, MMBTForClassification
|
||||
|
||||
from .modeling_flaubert import (
|
||||
FlaubertModel,
|
||||
FlaubertWithLMHeadModel,
|
||||
FlaubertForSequenceClassification,
|
||||
FlaubertForQuestionAnswering,
|
||||
FlaubertForQuestionAnsweringSimple,
|
||||
FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
# Optimization
|
||||
from .optimization import (
|
||||
AdamW,
|
||||
@@ -267,6 +289,7 @@ if is_tf_available():
|
||||
from .modeling_tf_utils import TFPreTrainedModel, TFSharedEmbeddings, TFSequenceSummary, shape_list
|
||||
from .modeling_tf_auto import (
|
||||
TFAutoModel,
|
||||
TFAutoModelForPreTraining,
|
||||
TFAutoModelForSequenceClassification,
|
||||
TFAutoModelForQuestionAnswering,
|
||||
TFAutoModelWithLMHead,
|
||||
@@ -336,6 +359,14 @@ if is_tf_available():
|
||||
TF_XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
from .modeling_tf_xlm_roberta import (
|
||||
TFXLMRobertaForMaskedLM,
|
||||
TFXLMRobertaModel,
|
||||
TFXLMRobertaForSequenceClassification,
|
||||
TFXLMRobertaForTokenClassification,
|
||||
TF_XLM_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
from .modeling_tf_roberta import (
|
||||
TFRobertaPreTrainedModel,
|
||||
TFRobertaMainLayer,
|
||||
@@ -346,6 +377,14 @@ if is_tf_available():
|
||||
TF_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
from .modeling_tf_camembert import (
|
||||
TFCamembertModel,
|
||||
TFCamembertForMaskedLM,
|
||||
TFCamembertForSequenceClassification,
|
||||
TFCamembertForTokenClassification,
|
||||
TF_CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
from .modeling_tf_distilbert import (
|
||||
TFDistilBertPreTrainedModel,
|
||||
TFDistilBertMainLayer,
|
||||
@@ -372,7 +411,12 @@ if is_tf_available():
|
||||
TF_ALBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
from .modeling_tf_t5 import TFT5PreTrainedModel, TFT5Model, TFT5WithLMHeadModel, TF_T5_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
from .modeling_tf_t5 import (
|
||||
TFT5PreTrainedModel,
|
||||
TFT5Model,
|
||||
TFT5WithLMHeadModel,
|
||||
TF_T5_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
)
|
||||
|
||||
# Optimization
|
||||
from .optimization_tf import WarmUp, create_optimizer, AdamWeightDecay, GradientAccumulator
|
||||
|
||||
@@ -0,0 +1,48 @@
|
||||
import math
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
def _gelu_python(x):
|
||||
""" Original Implementation of the gelu activation function in Google Bert repo when initially created.
|
||||
For information: OpenAI GPT's gelu is slightly different (and gives slightly different results):
|
||||
0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
This is now written in C in torch.nn.functional
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return x * 0.5 * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
gelu = getattr(F, "gelu", _gelu_python)
|
||||
|
||||
|
||||
def gelu_new(x):
|
||||
""" Implementation of the gelu activation function currently in Google Bert repo (identical to OpenAI GPT).
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
ACT2FN = {
|
||||
"relu": F.relu,
|
||||
"swish": swish,
|
||||
"gelu": gelu,
|
||||
"tanh": F.tanh,
|
||||
"gelu_new": gelu_new,
|
||||
}
|
||||
|
||||
|
||||
def get_activation(activation_string):
|
||||
if activation_string in ACT2FN:
|
||||
return ACT2FN[activation_string]
|
||||
else:
|
||||
raise KeyError(
|
||||
"function {} not found in ACT2FN mapping {} or torch.nn.functional".format(
|
||||
activation_string, list(ACT2FN.keys())
|
||||
)
|
||||
)
|
||||
@@ -0,0 +1,58 @@
|
||||
import platform
|
||||
from argparse import ArgumentParser
|
||||
|
||||
from transformers import __version__ as version
|
||||
from transformers import is_tf_available, is_torch_available
|
||||
from transformers.commands import BaseTransformersCLICommand
|
||||
|
||||
|
||||
def info_command_factory(_):
|
||||
return EnvironmentCommand()
|
||||
|
||||
|
||||
class EnvironmentCommand(BaseTransformersCLICommand):
|
||||
@staticmethod
|
||||
def register_subcommand(parser: ArgumentParser):
|
||||
download_parser = parser.add_parser("env")
|
||||
download_parser.set_defaults(func=info_command_factory)
|
||||
|
||||
def run(self):
|
||||
pt_version = "not installed"
|
||||
pt_cuda_available = "NA"
|
||||
if is_torch_available():
|
||||
import torch
|
||||
|
||||
pt_version = torch.__version__
|
||||
pt_cuda_available = torch.cuda.is_available()
|
||||
|
||||
tf_version = "not installed"
|
||||
tf_cuda_available = "NA"
|
||||
if is_tf_available():
|
||||
import tensorflow as tf
|
||||
|
||||
tf_version = tf.__version__
|
||||
try:
|
||||
# deprecated in v2.1
|
||||
tf_cuda_available = tf.test.is_gpu_available()
|
||||
except AttributeError:
|
||||
# returns list of devices, convert to bool
|
||||
tf_cuda_available = bool(tf.config.list_physical_devices("GPU"))
|
||||
|
||||
info = {
|
||||
"`transformers` version": version,
|
||||
"Platform": platform.platform(),
|
||||
"Python version": platform.python_version(),
|
||||
"PyTorch version (GPU?)": "{} ({})".format(pt_version, pt_cuda_available),
|
||||
"Tensorflow version (GPU?)": "{} ({})".format(tf_version, tf_cuda_available),
|
||||
"Using GPU in script?": "<fill in>",
|
||||
"Using distributed or parallel set-up in script?": "<fill in>",
|
||||
}
|
||||
|
||||
print("\nCopy-and-paste the text below in your GitHub issue and FILL OUT the two last points.\n")
|
||||
print(self.format_dict(info))
|
||||
|
||||
return info
|
||||
|
||||
@staticmethod
|
||||
def format_dict(d):
|
||||
return "\n".join(["- {}: {}".format(prop, val) for prop, val in d.items()]) + "\n"
|
||||
@@ -2,7 +2,6 @@ import logging
|
||||
from argparse import ArgumentParser, Namespace
|
||||
from typing import Any, List, Optional
|
||||
|
||||
from starlette.responses import JSONResponse
|
||||
from transformers import Pipeline
|
||||
from transformers.commands import BaseTransformersCLICommand
|
||||
from transformers.pipelines import SUPPORTED_TASKS, pipeline
|
||||
@@ -13,15 +12,16 @@ try:
|
||||
from fastapi import FastAPI, HTTPException, Body
|
||||
from fastapi.routing import APIRoute
|
||||
from pydantic import BaseModel
|
||||
from starlette.responses import JSONResponse
|
||||
|
||||
_serve_dependancies_installed = True
|
||||
_serve_dependencies_installed = True
|
||||
except (ImportError, AttributeError):
|
||||
BaseModel = object
|
||||
|
||||
def Body(*x, **y):
|
||||
pass
|
||||
|
||||
_serve_dependancies_installed = False
|
||||
_serve_dependencies_installed = False
|
||||
|
||||
|
||||
logger = logging.getLogger("transformers-cli/serving")
|
||||
@@ -111,7 +111,7 @@ class ServeCommand(BaseTransformersCLICommand):
|
||||
self.port = port
|
||||
self.workers = workers
|
||||
|
||||
if not _serve_dependancies_installed:
|
||||
if not _serve_dependencies_installed:
|
||||
raise RuntimeError(
|
||||
"Using serve command requires FastAPI and unicorn. "
|
||||
'Please install transformers with [serving]: pip install "transformers[serving]".'
|
||||
|
||||
@@ -76,6 +76,8 @@ class AlbertConfig(PretrainedConfig):
|
||||
The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
|
||||
layer_norm_eps (:obj:`float`, optional, defaults to 1e-12):
|
||||
The epsilon used by the layer normalization layers.
|
||||
classifier_dropout_prob (:obj:`float`, optional, defaults to 0.1):
|
||||
The dropout ratio for attached classifiers.
|
||||
|
||||
Example::
|
||||
|
||||
@@ -121,6 +123,7 @@ class AlbertConfig(PretrainedConfig):
|
||||
type_vocab_size=2,
|
||||
initializer_range=0.02,
|
||||
layer_norm_eps=1e-12,
|
||||
classifier_dropout_prob=0.1,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
@@ -140,3 +143,4 @@ class AlbertConfig(PretrainedConfig):
|
||||
self.type_vocab_size = type_vocab_size
|
||||
self.initializer_range = initializer_range
|
||||
self.layer_norm_eps = layer_norm_eps
|
||||
self.classifier_dropout_prob = classifier_dropout_prob
|
||||
|
||||
@@ -23,6 +23,7 @@ from .configuration_bert import BERT_PRETRAINED_CONFIG_ARCHIVE_MAP, BertConfig
|
||||
from .configuration_camembert import CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, CamembertConfig
|
||||
from .configuration_ctrl import CTRL_PRETRAINED_CONFIG_ARCHIVE_MAP, CTRLConfig
|
||||
from .configuration_distilbert import DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, DistilBertConfig
|
||||
from .configuration_flaubert import FLAUBERT_PRETRAINED_CONFIG_ARCHIVE_MAP, FlaubertConfig
|
||||
from .configuration_gpt2 import GPT2_PRETRAINED_CONFIG_ARCHIVE_MAP, GPT2Config
|
||||
from .configuration_openai import OPENAI_GPT_PRETRAINED_CONFIG_ARCHIVE_MAP, OpenAIGPTConfig
|
||||
from .configuration_roberta import ROBERTA_PRETRAINED_CONFIG_ARCHIVE_MAP, RobertaConfig
|
||||
@@ -53,6 +54,7 @@ ALL_PRETRAINED_CONFIG_ARCHIVE_MAP = dict(
|
||||
CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
T5_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
XLM_ROBERTA_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
FLAUBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
]
|
||||
for key, value, in pretrained_map.items()
|
||||
)
|
||||
@@ -66,6 +68,7 @@ CONFIG_MAPPING = OrderedDict(
|
||||
("camembert", CamembertConfig,),
|
||||
("xlm-roberta", XLMRobertaConfig,),
|
||||
("roberta", RobertaConfig,),
|
||||
("flaubert", FlaubertConfig,),
|
||||
("bert", BertConfig,),
|
||||
("openai-gpt", OpenAIGPTConfig,),
|
||||
("gpt2", GPT2Config,),
|
||||
@@ -77,7 +80,7 @@ CONFIG_MAPPING = OrderedDict(
|
||||
)
|
||||
|
||||
|
||||
class AutoConfig(object):
|
||||
class AutoConfig:
|
||||
r"""
|
||||
:class:`~transformers.AutoConfig` is a generic configuration class
|
||||
that will be instantiated as one of the configuration classes of the library
|
||||
@@ -126,6 +129,7 @@ class AutoConfig(object):
|
||||
- contains `xlnet`: :class:`~transformers.XLNetConfig` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.XLMConfig` (XLM model)
|
||||
- contains `ctrl` : :class:`~transformers.CTRLConfig` (CTRL model)
|
||||
- contains `flaubert` : :class:`~transformers.FlaubertConfig` (Flaubert model)
|
||||
|
||||
|
||||
Args:
|
||||
|
||||
@@ -45,6 +45,7 @@ BERT_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"bert-base-japanese-char-whole-word-masking": "https://s3.amazonaws.com/models.huggingface.co/bert/cl-tohoku/bert-base-japanese-char-whole-word-masking-config.json",
|
||||
"bert-base-finnish-cased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/TurkuNLP/bert-base-finnish-cased-v1/config.json",
|
||||
"bert-base-finnish-uncased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/TurkuNLP/bert-base-finnish-uncased-v1/config.json",
|
||||
"bert-base-dutch-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/wietsedv/bert-base-dutch-cased/config.json",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -25,6 +25,8 @@ logger = logging.getLogger(__name__)
|
||||
|
||||
CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"camembert-base": "https://s3.amazonaws.com/models.huggingface.co/bert/camembert-base-config.json",
|
||||
"umberto-commoncrawl-cased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/Musixmatch/umberto-commoncrawl-cased-v1/config.json",
|
||||
"umberto-wikipedia-uncased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/Musixmatch/umberto-wikipedia-uncased-v1/config.json",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -25,6 +25,8 @@ logger = logging.getLogger(__name__)
|
||||
DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-config.json",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-distilled-squad-config.json",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-config.json",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-distilled-squad-config.json",
|
||||
"distilbert-base-german-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-german-cased-config.json",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-multilingual-cased-config.json",
|
||||
"distilbert-base-uncased-finetuned-sst-2-english": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-finetuned-sst-2-english-config.json",
|
||||
@@ -58,7 +60,7 @@ class DistilBertConfig(PretrainedConfig):
|
||||
Number of attention heads for each attention layer in the Transformer encoder.
|
||||
dim (:obj:`int`, optional, defaults to 768):
|
||||
Dimensionality of the encoder layers and the pooler layer.
|
||||
intermediate_size (:obj:`int`, optional, defaults to 3072):
|
||||
hidden_dim (:obj:`int`, optional, defaults to 3072):
|
||||
The size of the "intermediate" (i.e., feed-forward) layer in the Transformer encoder.
|
||||
dropout (:obj:`float`, optional, defaults to 0.1):
|
||||
The dropout probabilitiy for all fully connected layers in the embeddings, encoder, and pooler.
|
||||
|
||||
@@ -0,0 +1,152 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2019-present CNRS, Facebook Inc. and the HuggingFace Inc. team.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" Flaubert configuration, based on XLM. """
|
||||
|
||||
|
||||
import logging
|
||||
|
||||
from .configuration_xlm import XLMConfig
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
FLAUBERT_PRETRAINED_CONFIG_ARCHIVE_MAP = {
|
||||
"flaubert-small-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_small_cased/config.json",
|
||||
"flaubert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_base_uncased/config.json",
|
||||
"flaubert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_base_cased/config.json",
|
||||
"flaubert-large-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_large_cased/config.json",
|
||||
}
|
||||
|
||||
|
||||
class FlaubertConfig(XLMConfig):
|
||||
"""
|
||||
Configuration class to store the configuration of a `FlaubertModel`.
|
||||
This is the configuration class to store the configuration of a :class:`~transformers.XLMModel`.
|
||||
It is used to instantiate an XLM model according to the specified arguments, defining the model
|
||||
architecture. Instantiating a configuration with the defaults will yield a similar configuration to that of
|
||||
the `xlm-mlm-en-2048 <https://huggingface.co/xlm-mlm-en-2048>`__ architecture.
|
||||
|
||||
Configuration objects inherit from :class:`~transformers.PretrainedConfig` and can be used
|
||||
to control the model outputs. Read the documentation from :class:`~transformers.PretrainedConfig`
|
||||
for more information.
|
||||
|
||||
Args:
|
||||
pre_norm (:obj:`bool`, `optional`, defaults to :obj:`False`):
|
||||
Whether to apply the layer normalization before or after the feed forward layer following the
|
||||
attention in each layer (Vaswani et al., Tensor2Tensor for Neural Machine Translation. 2018)
|
||||
layerdrop (:obj:`float`, `optional`, defaults to 0.0):
|
||||
Probability to drop layers during training (Fan et al., Reducing Transformer Depth on Demand
|
||||
with Structured Dropout. ICLR 2020)
|
||||
vocab_size (:obj:`int`, optional, defaults to 30145):
|
||||
Vocabulary size of the Flaubert model. Defines the different tokens that
|
||||
can be represented by the `inputs_ids` passed to the forward method of :class:`~transformers.FlaubertModel`.
|
||||
emb_dim (:obj:`int`, optional, defaults to 2048):
|
||||
Dimensionality of the encoder layers and the pooler layer.
|
||||
n_layer (:obj:`int`, optional, defaults to 12):
|
||||
Number of hidden layers in the Transformer encoder.
|
||||
n_head (:obj:`int`, optional, defaults to 16):
|
||||
Number of attention heads for each attention layer in the Transformer encoder.
|
||||
dropout (:obj:`float`, optional, defaults to 0.1):
|
||||
The dropout probability for all fully connected
|
||||
layers in the embeddings, encoder, and pooler.
|
||||
attention_dropout (:obj:`float`, optional, defaults to 0.1):
|
||||
The dropout probability for the attention mechanism
|
||||
gelu_activation (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
The non-linear activation function (function or string) in the
|
||||
encoder and pooler. If set to `True`, "gelu" will be used instead of "relu".
|
||||
sinusoidal_embeddings (:obj:`boolean`, optional, defaults to :obj:`False`):
|
||||
Whether to use sinusoidal positional embeddings instead of absolute positional embeddings.
|
||||
causal (:obj:`boolean`, optional, defaults to :obj:`False`):
|
||||
Set this to `True` for the model to behave in a causal manner.
|
||||
Causal models use a triangular attention mask in order to only attend to the left-side context instead
|
||||
if a bidirectional context.
|
||||
asm (:obj:`boolean`, optional, defaults to :obj:`False`):
|
||||
Whether to use an adaptive log softmax projection layer instead of a linear layer for the prediction
|
||||
layer.
|
||||
n_langs (:obj:`int`, optional, defaults to 1):
|
||||
The number of languages the model handles. Set to 1 for monolingual models.
|
||||
use_lang_emb (:obj:`boolean`, optional, defaults to :obj:`True`)
|
||||
Whether to use language embeddings. Some models use additional language embeddings, see
|
||||
`the multilingual models page <http://huggingface.co/transformers/multilingual.html#xlm-language-embeddings>`__
|
||||
for information on how to use them.
|
||||
max_position_embeddings (:obj:`int`, optional, defaults to 512):
|
||||
The maximum sequence length that this model might
|
||||
ever be used with. Typically set this to something large just in case
|
||||
(e.g., 512 or 1024 or 2048).
|
||||
embed_init_std (:obj:`float`, optional, defaults to 2048^-0.5):
|
||||
The standard deviation of the truncated_normal_initializer for
|
||||
initializing the embedding matrices.
|
||||
init_std (:obj:`int`, optional, defaults to 50257):
|
||||
The standard deviation of the truncated_normal_initializer for
|
||||
initializing all weight matrices except the embedding matrices.
|
||||
layer_norm_eps (:obj:`float`, optional, defaults to 1e-12):
|
||||
The epsilon used by the layer normalization layers.
|
||||
bos_index (:obj:`int`, optional, defaults to 0):
|
||||
The index of the beginning of sentence token in the vocabulary.
|
||||
eos_index (:obj:`int`, optional, defaults to 1):
|
||||
The index of the end of sentence token in the vocabulary.
|
||||
pad_index (:obj:`int`, optional, defaults to 2):
|
||||
The index of the padding token in the vocabulary.
|
||||
unk_index (:obj:`int`, optional, defaults to 3):
|
||||
The index of the unknown token in the vocabulary.
|
||||
mask_index (:obj:`int`, optional, defaults to 5):
|
||||
The index of the masking token in the vocabulary.
|
||||
is_encoder(:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Whether the initialized model should be a transformer encoder or decoder as seen in Vaswani et al.
|
||||
summary_type (:obj:`string`, optional, defaults to "first"):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Is one of the following options:
|
||||
- 'last' => take the last token hidden state (like XLNet)
|
||||
- 'first' => take the first token hidden state (like Bert)
|
||||
- 'mean' => take the mean of all tokens hidden states
|
||||
- 'cls_index' => supply a Tensor of classification token position (GPT/GPT-2)
|
||||
- 'attn' => Not implemented now, use multi-head attention
|
||||
summary_use_proj (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Add a projection after the vector extraction
|
||||
summary_activation (:obj:`string` or :obj:`None`, optional, defaults to :obj:`None`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
'tanh' => add a tanh activation to the output, Other => no activation.
|
||||
summary_proj_to_labels (:obj:`boolean`, optional, defaults to :obj:`True`):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
If True, the projection outputs to config.num_labels classes (otherwise to hidden_size). Default: False.
|
||||
summary_first_dropout (:obj:`float`, optional, defaults to 0.1):
|
||||
Argument used when doing sequence summary. Used in for the multiple choice head in
|
||||
:class:`~transformers.XLMForSequenceClassification`.
|
||||
Add a dropout before the projection and activation
|
||||
start_n_top (:obj:`int`, optional, defaults to 5):
|
||||
Used in the SQuAD evaluation script for XLM and XLNet.
|
||||
end_n_top (:obj:`int`, optional, defaults to 5):
|
||||
Used in the SQuAD evaluation script for XLM and XLNet.
|
||||
mask_token_id (:obj:`int`, optional, defaults to 0):
|
||||
Model agnostic parameter to identify masked tokens when generating text in an MLM context.
|
||||
lang_id (:obj:`int`, optional, defaults to 1):
|
||||
The ID of the language used by the model. This parameter is used when generating
|
||||
text in a given language.
|
||||
"""
|
||||
|
||||
pretrained_config_archive_map = FLAUBERT_PRETRAINED_CONFIG_ARCHIVE_MAP
|
||||
model_type = "flaubert"
|
||||
|
||||
def __init__(self, layerdrop=0.0, pre_norm=False, **kwargs):
|
||||
"""Constructs FlaubertConfig.
|
||||
"""
|
||||
super().__init__(**kwargs)
|
||||
self.layerdrop = layerdrop
|
||||
self.pre_norm = pre_norm
|
||||
@@ -82,6 +82,7 @@ class PretrainedConfig(object):
|
||||
self.num_return_sequences = kwargs.pop("num_return_sequences", 1)
|
||||
|
||||
# Fine-tuning task arguments
|
||||
self.architectures = kwargs.pop("architectures", None)
|
||||
self.finetuning_task = kwargs.pop("finetuning_task", None)
|
||||
self.num_labels = kwargs.pop("num_labels", 2)
|
||||
self.id2label = kwargs.pop("id2label", {i: "LABEL_{}".format(i) for i in range(self.num_labels)})
|
||||
|
||||
@@ -22,6 +22,7 @@ import os
|
||||
from transformers import (
|
||||
ALBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
BERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
CTRL_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
GPT2_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
@@ -30,9 +31,11 @@ from transformers import (
|
||||
T5_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
TRANSFO_XL_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
XLM_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
XLM_ROBERTA_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
XLNET_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
AlbertConfig,
|
||||
BertConfig,
|
||||
CamembertConfig,
|
||||
CTRLConfig,
|
||||
DistilBertConfig,
|
||||
GPT2Config,
|
||||
@@ -43,6 +46,7 @@ from transformers import (
|
||||
TFBertForPreTraining,
|
||||
TFBertForQuestionAnswering,
|
||||
TFBertForSequenceClassification,
|
||||
TFCamembertForMaskedLM,
|
||||
TFCTRLLMHeadModel,
|
||||
TFDistilBertForMaskedLM,
|
||||
TFDistilBertForQuestionAnswering,
|
||||
@@ -52,10 +56,12 @@ from transformers import (
|
||||
TFRobertaForSequenceClassification,
|
||||
TFT5WithLMHeadModel,
|
||||
TFTransfoXLLMHeadModel,
|
||||
TFXLMRobertaForMaskedLM,
|
||||
TFXLMWithLMHeadModel,
|
||||
TFXLNetLMHeadModel,
|
||||
TransfoXLConfig,
|
||||
XLMConfig,
|
||||
XLMRobertaConfig,
|
||||
XLNetConfig,
|
||||
cached_path,
|
||||
is_torch_available,
|
||||
@@ -77,6 +83,8 @@ if is_torch_available():
|
||||
XLNET_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLMWithLMHeadModel,
|
||||
XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLM_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLMRobertaForMaskedLM,
|
||||
TransfoXLLMHeadModel,
|
||||
TRANSFO_XL_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
OpenAIGPTLMHeadModel,
|
||||
@@ -84,6 +92,9 @@ if is_torch_available():
|
||||
RobertaForMaskedLM,
|
||||
RobertaForSequenceClassification,
|
||||
ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
CamembertForMaskedLM,
|
||||
CamembertForSequenceClassification,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
DistilBertForMaskedLM,
|
||||
DistilBertForQuestionAnswering,
|
||||
DistilBertForSequenceClassification,
|
||||
@@ -107,6 +118,8 @@ else:
|
||||
XLNET_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLMWithLMHeadModel,
|
||||
XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLM_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLMRobertaForMaskedLM,
|
||||
TransfoXLLMHeadModel,
|
||||
TRANSFO_XL_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
OpenAIGPTLMHeadModel,
|
||||
@@ -114,6 +127,9 @@ else:
|
||||
RobertaForMaskedLM,
|
||||
RobertaForSequenceClassification,
|
||||
ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
CamembertForMaskedLM,
|
||||
CamembertForSequenceClassification,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
DistilBertForMaskedLM,
|
||||
DistilBertForSequenceClassification,
|
||||
DistilBertForQuestionAnswering,
|
||||
@@ -152,6 +168,11 @@ else:
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
)
|
||||
|
||||
|
||||
@@ -207,6 +228,13 @@ MODEL_CLASSES = {
|
||||
XLM_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLM_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"xlm-roberta": (
|
||||
XLMRobertaConfig,
|
||||
TFXLMRobertaForMaskedLM,
|
||||
XLMRobertaForMaskedLM,
|
||||
XLM_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLM_ROBERTA_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"transfo-xl": (
|
||||
TransfoXLConfig,
|
||||
TFTransfoXLLMHeadModel,
|
||||
@@ -235,6 +263,13 @@ MODEL_CLASSES = {
|
||||
ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
ROBERTA_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"camembert": (
|
||||
CamembertConfig,
|
||||
TFCamembertForMaskedLM,
|
||||
CamembertForMaskedLM,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
CAMEMBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"distilbert": (
|
||||
DistilBertConfig,
|
||||
TFDistilBertForMaskedLM,
|
||||
@@ -242,14 +277,7 @@ MODEL_CLASSES = {
|
||||
DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"distilbert-base-uncased-distilled-squad": (
|
||||
DistilBertConfig,
|
||||
TFDistilBertForQuestionAnswering,
|
||||
DistilBertForQuestionAnswering,
|
||||
DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
DISTILBERT_PRETRAINED_CONFIG_ARCHIVE_MAP,
|
||||
),
|
||||
"distilbert-base-uncased-distilled-squad": (
|
||||
"distilbert-base-distilled-squad": (
|
||||
DistilBertConfig,
|
||||
TFDistilBertForQuestionAnswering,
|
||||
DistilBertForQuestionAnswering,
|
||||
|
||||
@@ -147,7 +147,14 @@ def squad_convert_example_to_features(example, max_seq_length, doc_stride, max_q
|
||||
)
|
||||
|
||||
if tokenizer.pad_token_id in encoded_dict["input_ids"]:
|
||||
non_padded_ids = encoded_dict["input_ids"][: encoded_dict["input_ids"].index(tokenizer.pad_token_id)]
|
||||
if tokenizer.padding_side == "right":
|
||||
non_padded_ids = encoded_dict["input_ids"][: encoded_dict["input_ids"].index(tokenizer.pad_token_id)]
|
||||
else:
|
||||
last_padding_id_position = (
|
||||
len(encoded_dict["input_ids"]) - 1 - encoded_dict["input_ids"][::-1].index(tokenizer.pad_token_id)
|
||||
)
|
||||
non_padded_ids = encoded_dict["input_ids"][last_padding_id_position + 1 :]
|
||||
|
||||
else:
|
||||
non_padded_ids = encoded_dict["input_ids"]
|
||||
|
||||
@@ -621,7 +628,7 @@ class SquadExample(object):
|
||||
self.doc_tokens = doc_tokens
|
||||
self.char_to_word_offset = char_to_word_offset
|
||||
|
||||
# Start end end positions only has a value during evaluation.
|
||||
# Start and end positions only has a value during evaluation.
|
||||
if start_position_character is not None and not is_impossible:
|
||||
self.start_position = char_to_word_offset[start_position_character]
|
||||
self.end_position = char_to_word_offset[
|
||||
|
||||
@@ -8,13 +8,16 @@ import fnmatch
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import shutil
|
||||
import sys
|
||||
import tarfile
|
||||
import tempfile
|
||||
from contextlib import contextmanager
|
||||
from functools import partial, wraps
|
||||
from hashlib import sha256
|
||||
from typing import Optional
|
||||
from urllib.parse import urlparse
|
||||
from zipfile import ZipFile, is_zipfile
|
||||
|
||||
import boto3
|
||||
import requests
|
||||
@@ -203,7 +206,15 @@ def filename_to_url(filename, cache_dir=None):
|
||||
|
||||
|
||||
def cached_path(
|
||||
url_or_filename, cache_dir=None, force_download=False, proxies=None, resume_download=False, user_agent=None
|
||||
url_or_filename,
|
||||
cache_dir=None,
|
||||
force_download=False,
|
||||
proxies=None,
|
||||
resume_download=False,
|
||||
user_agent=None,
|
||||
extract_compressed_file=False,
|
||||
force_extract=False,
|
||||
extract_dir=None,
|
||||
) -> Optional[str]:
|
||||
"""
|
||||
Given something that might be a URL (or might be a local path),
|
||||
@@ -215,6 +226,11 @@ def cached_path(
|
||||
force_download: if True, re-dowload the file even if it's already cached in the cache dir.
|
||||
resume_download: if True, resume the download if incompletly recieved file is found.
|
||||
user_agent: Optional string or dict that will be appended to the user-agent on remote requests.
|
||||
extract_compressed_file: if True and the path point to a zip or tar file, extract the compressed
|
||||
file in a folder along the archive.
|
||||
force_extract: if True when extract_compressed_file is True and the archive was already extracted,
|
||||
re-extract the archive and overide the folder where it was extracted.
|
||||
extract_dir: specify a directory to extract the archive to (overwrite the default created directory).
|
||||
|
||||
Return:
|
||||
None in case of non-recoverable file (non-existent or inaccessible url + no cache on disk).
|
||||
@@ -229,7 +245,7 @@ def cached_path(
|
||||
|
||||
if is_remote_url(url_or_filename):
|
||||
# URL, so get it from the cache (downloading if necessary)
|
||||
return get_from_cache(
|
||||
output_path = get_from_cache(
|
||||
url_or_filename,
|
||||
cache_dir=cache_dir,
|
||||
force_download=force_download,
|
||||
@@ -239,7 +255,7 @@ def cached_path(
|
||||
)
|
||||
elif os.path.exists(url_or_filename):
|
||||
# File, and it exists.
|
||||
return url_or_filename
|
||||
output_path = url_or_filename
|
||||
elif urlparse(url_or_filename).scheme == "":
|
||||
# File, but it doesn't exist.
|
||||
raise EnvironmentError("file {} not found".format(url_or_filename))
|
||||
@@ -247,6 +263,37 @@ def cached_path(
|
||||
# Something unknown
|
||||
raise ValueError("unable to parse {} as a URL or as a local path".format(url_or_filename))
|
||||
|
||||
if extract_compressed_file and os.path.isfile(output_path):
|
||||
if not is_zipfile(output_path) and not tarfile.is_tarfile(output_path):
|
||||
return output_path
|
||||
|
||||
# Path where we extract compressed archives
|
||||
# We avoid '.' in dir name and add "-extracted" at the end: "./model.zip" => "./model-zip-extracted/"
|
||||
output_dir, output_file = os.path.split(output_path)
|
||||
output_extract_dir_name = output_file.replace(".", "-") + "-extracted"
|
||||
output_path_extracted = os.path.join(output_dir, output_extract_dir_name)
|
||||
|
||||
if not os.path.isdir(output_path_extracted) or force_extract:
|
||||
# Extract file with a lock to prevent parallel extractions
|
||||
lock_path = output_path + ".lock"
|
||||
with FileLock(lock_path):
|
||||
shutil.rmtree(output_path_extracted, ignore_errors=True)
|
||||
os.makedirs(output_path_extracted)
|
||||
if is_zipfile(output_path):
|
||||
with ZipFile(output_path, "r") as zip_file:
|
||||
zip_file.extractall(output_path_extracted)
|
||||
zip_file.close()
|
||||
elif tarfile.is_tarfile(output_path):
|
||||
tar_file = tarfile.open(output_path)
|
||||
tar_file.extractall(output_path_extracted)
|
||||
tar_file.close()
|
||||
else:
|
||||
raise EnvironmentError("Archive format of {} could not be identified".format(output_path))
|
||||
|
||||
return output_path_extracted
|
||||
|
||||
return output_path
|
||||
|
||||
|
||||
def split_s3_path(url):
|
||||
"""Split a full s3 path into the bucket name and path."""
|
||||
|
||||
@@ -152,6 +152,8 @@ class ModelCard(object):
|
||||
resolved_model_card_file = cached_path(
|
||||
model_card_file, cache_dir=cache_dir, force_download=True, proxies=proxies, resume_download=False
|
||||
)
|
||||
if resolved_model_card_file is None:
|
||||
raise EnvironmentError
|
||||
if resolved_model_card_file == model_card_file:
|
||||
logger.info("loading model card file {}".format(model_card_file))
|
||||
else:
|
||||
|
||||
@@ -117,7 +117,13 @@ def load_tf_weights_in_albert(model, config, tf_checkpoint_path):
|
||||
name = name.split("/")
|
||||
|
||||
# Ignore the gradients applied by the LAMB/ADAM optimizers.
|
||||
if "adam_m" in name or "adam_v" in name or "global_step" in name:
|
||||
if (
|
||||
"adam_m" in name
|
||||
or "adam_v" in name
|
||||
or "AdamWeightDecayOptimizer" in name
|
||||
or "AdamWeightDecayOptimizer_1" in name
|
||||
or "global_step" in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
continue
|
||||
|
||||
@@ -698,7 +704,7 @@ class AlbertForSequenceClassification(AlbertPreTrainedModel):
|
||||
self.num_labels = config.num_labels
|
||||
|
||||
self.albert = AlbertModel(config)
|
||||
self.dropout = nn.Dropout(config.hidden_dropout_prob)
|
||||
self.dropout = nn.Dropout(config.classifier_dropout_prob)
|
||||
self.classifier = nn.Linear(config.hidden_size, self.config.num_labels)
|
||||
|
||||
self.init_weights()
|
||||
|
||||
@@ -25,6 +25,7 @@ from .configuration_auto import (
|
||||
CamembertConfig,
|
||||
CTRLConfig,
|
||||
DistilBertConfig,
|
||||
FlaubertConfig,
|
||||
GPT2Config,
|
||||
OpenAIGPTConfig,
|
||||
RobertaConfig,
|
||||
@@ -45,6 +46,7 @@ from .modeling_albert import (
|
||||
from .modeling_bert import (
|
||||
BERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
BertForMaskedLM,
|
||||
BertForPreTraining,
|
||||
BertForQuestionAnswering,
|
||||
BertForSequenceClassification,
|
||||
BertForTokenClassification,
|
||||
@@ -66,11 +68,19 @@ from .modeling_distilbert import (
|
||||
DistilBertForTokenClassification,
|
||||
DistilBertModel,
|
||||
)
|
||||
from .modeling_flaubert import (
|
||||
FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
FlaubertForQuestionAnswering,
|
||||
FlaubertForSequenceClassification,
|
||||
FlaubertModel,
|
||||
FlaubertWithLMHeadModel,
|
||||
)
|
||||
from .modeling_gpt2 import GPT2_PRETRAINED_MODEL_ARCHIVE_MAP, GPT2LMHeadModel, GPT2Model
|
||||
from .modeling_openai import OPENAI_GPT_PRETRAINED_MODEL_ARCHIVE_MAP, OpenAIGPTLMHeadModel, OpenAIGPTModel
|
||||
from .modeling_roberta import (
|
||||
ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
RobertaForMaskedLM,
|
||||
RobertaForQuestionAnswering,
|
||||
RobertaForSequenceClassification,
|
||||
RobertaForTokenClassification,
|
||||
RobertaModel,
|
||||
@@ -119,6 +129,7 @@ ALL_PRETRAINED_MODEL_ARCHIVE_MAP = dict(
|
||||
ALBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
T5_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
XLM_ROBERTA_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
]
|
||||
for key, value, in pretrained_map.items()
|
||||
@@ -137,11 +148,31 @@ MODEL_MAPPING = OrderedDict(
|
||||
(GPT2Config, GPT2Model),
|
||||
(TransfoXLConfig, TransfoXLModel),
|
||||
(XLNetConfig, XLNetModel),
|
||||
(FlaubertConfig, FlaubertModel),
|
||||
(XLMConfig, XLMModel),
|
||||
(CTRLConfig, CTRLModel),
|
||||
]
|
||||
)
|
||||
|
||||
MODEL_FOR_PRETRAINING_MAPPING = OrderedDict(
|
||||
[
|
||||
(T5Config, T5WithLMHeadModel),
|
||||
(DistilBertConfig, DistilBertForMaskedLM),
|
||||
(AlbertConfig, AlbertForMaskedLM),
|
||||
(CamembertConfig, CamembertForMaskedLM),
|
||||
(XLMRobertaConfig, XLMRobertaForMaskedLM),
|
||||
(RobertaConfig, RobertaForMaskedLM),
|
||||
(BertConfig, BertForPreTraining),
|
||||
(OpenAIGPTConfig, OpenAIGPTLMHeadModel),
|
||||
(GPT2Config, GPT2LMHeadModel),
|
||||
(TransfoXLConfig, TransfoXLLMHeadModel),
|
||||
(XLNetConfig, XLNetLMHeadModel),
|
||||
(FlaubertConfig, FlaubertWithLMHeadModel),
|
||||
(XLMConfig, XLMWithLMHeadModel),
|
||||
(CTRLConfig, CTRLLMHeadModel),
|
||||
]
|
||||
)
|
||||
|
||||
MODEL_WITH_LM_HEAD_MAPPING = OrderedDict(
|
||||
[
|
||||
(T5Config, T5WithLMHeadModel),
|
||||
@@ -155,6 +186,7 @@ MODEL_WITH_LM_HEAD_MAPPING = OrderedDict(
|
||||
(GPT2Config, GPT2LMHeadModel),
|
||||
(TransfoXLConfig, TransfoXLLMHeadModel),
|
||||
(XLNetConfig, XLNetLMHeadModel),
|
||||
(FlaubertConfig, FlaubertWithLMHeadModel),
|
||||
(XLMConfig, XLMWithLMHeadModel),
|
||||
(CTRLConfig, CTRLLMHeadModel),
|
||||
]
|
||||
@@ -169,6 +201,7 @@ MODEL_FOR_SEQUENCE_CLASSIFICATION_MAPPING = OrderedDict(
|
||||
(RobertaConfig, RobertaForSequenceClassification),
|
||||
(BertConfig, BertForSequenceClassification),
|
||||
(XLNetConfig, XLNetForSequenceClassification),
|
||||
(FlaubertConfig, FlaubertForSequenceClassification),
|
||||
(XLMConfig, XLMForSequenceClassification),
|
||||
]
|
||||
)
|
||||
@@ -177,8 +210,10 @@ MODEL_FOR_QUESTION_ANSWERING_MAPPING = OrderedDict(
|
||||
[
|
||||
(DistilBertConfig, DistilBertForQuestionAnswering),
|
||||
(AlbertConfig, AlbertForQuestionAnswering),
|
||||
(RobertaConfig, RobertaForQuestionAnswering),
|
||||
(BertConfig, BertForQuestionAnswering),
|
||||
(XLNetConfig, XLNetForQuestionAnswering),
|
||||
(FlaubertConfig, FlaubertForQuestionAnswering),
|
||||
(XLMConfig, XLMForQuestionAnswering),
|
||||
]
|
||||
)
|
||||
@@ -230,6 +265,7 @@ class AutoModel(object):
|
||||
- isInstance of `transfo-xl` configuration class: :class:`~transformers.TransfoXLModel` (Transformer-XL model)
|
||||
- isInstance of `xlnet` configuration class: :class:`~transformers.XLNetModel` (XLNet model)
|
||||
- isInstance of `xlm` configuration class: :class:`~transformers.XLMModel` (XLM model)
|
||||
- isInstance of `flaubert` configuration class: :class:`~transformers.FlaubertModel` (XLM model)
|
||||
|
||||
Examples::
|
||||
|
||||
@@ -270,6 +306,7 @@ class AutoModel(object):
|
||||
- contains `xlnet`: :class:`~transformers.XLNetModel` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.XLMModel` (XLM model)
|
||||
- contains `ctrl`: :class:`~transformers.CTRLModel` (Salesforce CTRL model)
|
||||
- contains `flaubert`: :class:`~transformers.Flaubert` (Flaubert model)
|
||||
|
||||
The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with `model.train()`
|
||||
@@ -346,6 +383,158 @@ class AutoModel(object):
|
||||
)
|
||||
|
||||
|
||||
class AutoModelForPreTraining(object):
|
||||
r"""
|
||||
:class:`~transformers.AutoModelForPreTraining` is a generic model class
|
||||
that will be instantiated as one of the model classes of the library -with the architecture used for pretraining this model– when created with the `AutoModelForPreTraining.from_pretrained(pretrained_model_name_or_path)`
|
||||
class method.
|
||||
|
||||
This class cannot be instantiated using `__init__()` (throws an error).
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
raise EnvironmentError(
|
||||
"AutoModelForPreTraining is designed to be instantiated "
|
||||
"using the `AutoModelForPreTraining.from_pretrained(pretrained_model_name_or_path)` or "
|
||||
"`AutoModelForPreTraining.from_config(config)` methods."
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_config(cls, config):
|
||||
r""" Instantiates one of the base model classes of the library
|
||||
from a configuration.
|
||||
|
||||
Args:
|
||||
config (:class:`~transformers.PretrainedConfig`):
|
||||
The model class to instantiate is selected based on the configuration class:
|
||||
|
||||
- isInstance of `distilbert` configuration class: :class:`~transformers.DistilBertModelForMaskedLM` (DistilBERT model)
|
||||
- isInstance of `roberta` configuration class: :class:`~transformers.RobertaModelForMaskedLM` (RoBERTa model)
|
||||
- isInstance of `bert` configuration class: :class:`~transformers.BertForPreTraining` (Bert model)
|
||||
- isInstance of `openai-gpt` configuration class: :class:`~transformers.OpenAIGPTLMHeadModel` (OpenAI GPT model)
|
||||
- isInstance of `gpt2` configuration class: :class:`~transformers.GPT2ModelLMHeadModel` (OpenAI GPT-2 model)
|
||||
- isInstance of `ctrl` configuration class: :class:`~transformers.CTRLModelLMHeadModel` (Salesforce CTRL model)
|
||||
- isInstance of `transfo-xl` configuration class: :class:`~transformers.TransfoXLLMHeadModel` (Transformer-XL model)
|
||||
- isInstance of `xlnet` configuration class: :class:`~transformers.XLNetLMHeadModel` (XLNet model)
|
||||
- isInstance of `xlm` configuration class: :class:`~transformers.XLMWithLMHeadModel` (XLM model)
|
||||
- isInstance of `flaubert` configuration class: :class:`~transformers.FlaubertWithLMHeadModel` (Flaubert model)
|
||||
|
||||
Examples::
|
||||
|
||||
config = BertConfig.from_pretrained('bert-base-uncased') # Download configuration from S3 and cache.
|
||||
model = AutoModelForPreTraining.from_config(config) # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
"""
|
||||
for config_class, model_class in MODEL_FOR_PRETRAINING_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
return model_class(config)
|
||||
raise ValueError(
|
||||
"Unrecognized configuration class {} for this kind of AutoModel: {}.\n"
|
||||
"Model type should be one of {}.".format(
|
||||
config.__class__, cls.__name__, ", ".join(c.__name__ for c in MODEL_FOR_PRETRAINING_MAPPING.keys())
|
||||
)
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(cls, pretrained_model_name_or_path, *model_args, **kwargs):
|
||||
r""" Instantiates one of the model classes of the library -with the architecture used for pretraining this model– from a pre-trained model configuration.
|
||||
|
||||
The `from_pretrained()` method takes care of returning the correct model class instance
|
||||
based on the `model_type` property of the config object, or when it's missing,
|
||||
falling back to using pattern matching on the `pretrained_model_name_or_path` string.
|
||||
|
||||
The model class to instantiate is selected as the first pattern matching
|
||||
in the `pretrained_model_name_or_path` string (in the following order):
|
||||
- contains `t5`: :class:`~transformers.T5ModelWithLMHead` (T5 model)
|
||||
- contains `distilbert`: :class:`~transformers.DistilBertForMaskedLM` (DistilBERT model)
|
||||
- contains `albert`: :class:`~transformers.AlbertForMaskedLM` (ALBERT model)
|
||||
- contains `camembert`: :class:`~transformers.CamembertForMaskedLM` (CamemBERT model)
|
||||
- contains `xlm-roberta`: :class:`~transformers.XLMRobertaForMaskedLM` (XLM-RoBERTa model)
|
||||
- contains `roberta`: :class:`~transformers.RobertaForMaskedLM` (RoBERTa model)
|
||||
- contains `bert`: :class:`~transformers.BertForPreTraining` (Bert model)
|
||||
- contains `openai-gpt`: :class:`~transformers.OpenAIGPTLMHeadModel` (OpenAI GPT model)
|
||||
- contains `gpt2`: :class:`~transformers.GPT2LMHeadModel` (OpenAI GPT-2 model)
|
||||
- contains `transfo-xl`: :class:`~transformers.TransfoXLLMHeadModel` (Transformer-XL model)
|
||||
- contains `xlnet`: :class:`~transformers.XLNetLMHeadModel` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.XLMWithLMHeadModel` (XLM model)
|
||||
- contains `ctrl`: :class:`~transformers.CTRLLMHeadModel` (Salesforce CTRL model)
|
||||
- contains `flaubert`: :class:`~transformers.FlaubertWithLMHeadModel` (Flaubert model)
|
||||
|
||||
The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with `model.train()`
|
||||
|
||||
Args:
|
||||
pretrained_model_name_or_path:
|
||||
Either:
|
||||
|
||||
- a string with the `shortcut name` of a pre-trained model to load from cache or download, e.g.: ``bert-base-uncased``.
|
||||
- a string with the `identifier name` of a pre-trained model that was user-uploaded to our S3, e.g.: ``dbmdz/bert-base-german-cased``.
|
||||
- a path to a `directory` containing model weights saved using :func:`~transformers.PreTrainedModel.save_pretrained`, e.g.: ``./my_model_directory/``.
|
||||
- a path or url to a `tensorflow index checkpoint file` (e.g. `./tf_model/model.ckpt.index`). In this case, ``from_tf`` should be set to True and a configuration object should be provided as ``config`` argument. This loading path is slower than converting the TensorFlow checkpoint in a PyTorch model using the provided conversion scripts and loading the PyTorch model afterwards.
|
||||
model_args: (`optional`) Sequence of positional arguments:
|
||||
All remaning positional arguments will be passed to the underlying model's ``__init__`` method
|
||||
config: (`optional`) instance of a class derived from :class:`~transformers.PretrainedConfig`:
|
||||
Configuration for the model to use instead of an automatically loaded configuation. Configuration can be automatically loaded when:
|
||||
|
||||
- the model is a model provided by the library (loaded with the ``shortcut-name`` string of a pretrained model), or
|
||||
- the model was saved using :func:`~transformers.PreTrainedModel.save_pretrained` and is reloaded by suppling the save directory.
|
||||
- the model is loaded by suppling a local directory as ``pretrained_model_name_or_path`` and a configuration JSON file named `config.json` is found in the directory.
|
||||
|
||||
state_dict: (`optional`) dict:
|
||||
an optional state dictionnary for the model to use instead of a state dictionary loaded from saved weights file.
|
||||
This option can be used if you want to create a model from a pretrained configuration but load your own weights.
|
||||
In this case though, you should check if using :func:`~transformers.PreTrainedModel.save_pretrained` and :func:`~transformers.PreTrainedModel.from_pretrained` is not a simpler option.
|
||||
cache_dir: (`optional`) string:
|
||||
Path to a directory in which a downloaded pre-trained model
|
||||
configuration should be cached if the standard cache should not be used.
|
||||
force_download: (`optional`) boolean, default False:
|
||||
Force to (re-)download the model weights and configuration files and override the cached versions if they exists.
|
||||
resume_download: (`optional`) boolean, default False:
|
||||
Do not delete incompletely received file. Attempt to resume the download if such a file exists.
|
||||
proxies: (`optional`) dict, default None:
|
||||
A dictionary of proxy servers to use by protocol or endpoint, e.g.: {'http': 'foo.bar:3128', 'http://hostname': 'foo.bar:4012'}.
|
||||
The proxies are used on each request.
|
||||
output_loading_info: (`optional`) boolean:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model.
|
||||
(e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or
|
||||
automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the
|
||||
underlying model's ``__init__`` method (we assume all relevant updates to the configuration have
|
||||
already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class
|
||||
initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of
|
||||
``kwargs`` that corresponds to a configuration attribute will be used to override said attribute
|
||||
with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration
|
||||
attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = AutoModelForPreTraining.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = AutoModelForPreTraining.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = AutoModelForPreTraining.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
model = AutoModelForPreTraining.from_pretrained('./tf_model/bert_tf_checkpoint.ckpt.index', from_tf=True, config=config)
|
||||
|
||||
"""
|
||||
config = kwargs.pop("config", None)
|
||||
if not isinstance(config, PretrainedConfig):
|
||||
config = AutoConfig.from_pretrained(pretrained_model_name_or_path, **kwargs)
|
||||
|
||||
for config_class, model_class in MODEL_FOR_PRETRAINING_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
return model_class.from_pretrained(pretrained_model_name_or_path, *model_args, config=config, **kwargs)
|
||||
raise ValueError(
|
||||
"Unrecognized configuration class {} for this kind of AutoModel: {}.\n"
|
||||
"Model type should be one of {}.".format(
|
||||
config.__class__, cls.__name__, ", ".join(c.__name__ for c in MODEL_FOR_PRETRAINING_MAPPING.keys())
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
class AutoModelWithLMHead(object):
|
||||
r"""
|
||||
:class:`~transformers.AutoModelWithLMHead` is a generic model class
|
||||
@@ -381,6 +570,7 @@ class AutoModelWithLMHead(object):
|
||||
- isInstance of `transfo-xl` configuration class: :class:`~transformers.TransfoXLLMHeadModel` (Transformer-XL model)
|
||||
- isInstance of `xlnet` configuration class: :class:`~transformers.XLNetLMHeadModel` (XLNet model)
|
||||
- isInstance of `xlm` configuration class: :class:`~transformers.XLMWithLMHeadModel` (XLM model)
|
||||
- isInstance of `flaubert` configuration class: :class:`~transformers.FlaubertWithLMHeadModel` (Flaubert model)
|
||||
|
||||
Examples::
|
||||
|
||||
@@ -421,6 +611,7 @@ class AutoModelWithLMHead(object):
|
||||
- contains `xlnet`: :class:`~transformers.XLNetLMHeadModel` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.XLMWithLMHeadModel` (XLM model)
|
||||
- contains `ctrl`: :class:`~transformers.CTRLLMHeadModel` (Salesforce CTRL model)
|
||||
- contains `flaubert`: :class:`~transformers.FlaubertWithLMHeadModel` (Flaubert model)
|
||||
|
||||
The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with `model.train()`
|
||||
@@ -532,6 +723,7 @@ class AutoModelForSequenceClassification(object):
|
||||
- isInstance of `bert` configuration class: :class:`~transformers.BertModelForSequenceClassification` (Bert model)
|
||||
- isInstance of `xlnet` configuration class: :class:`~transformers.XLNetModelForSequenceClassification` (XLNet model)
|
||||
- isInstance of `xlm` configuration class: :class:`~transformers.XLMModelForSequenceClassification` (XLM model)
|
||||
- isInstance of `flaubert` configuration class: :class:`~transformers.FlaubertForSequenceClassification` (Flaubert model)
|
||||
|
||||
|
||||
Examples::
|
||||
@@ -569,7 +761,7 @@ class AutoModelForSequenceClassification(object):
|
||||
- contains `roberta`: :class:`~transformers.RobertaForSequenceClassification` (RoBERTa model)
|
||||
- contains `bert`: :class:`~transformers.BertForSequenceClassification` (Bert model)
|
||||
- contains `xlnet`: :class:`~transformers.XLNetForSequenceClassification` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.XLMForSequenceClassification` (XLM model)
|
||||
- contains `flaubert`: :class:`~transformers.FlaubertForSequenceClassification` (Flaubert model)
|
||||
|
||||
The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with `model.train()`
|
||||
@@ -679,6 +871,7 @@ class AutoModelForQuestionAnswering(object):
|
||||
- isInstance of `bert` configuration class: :class:`~transformers.BertModelForQuestionAnswering` (Bert model)
|
||||
- isInstance of `xlnet` configuration class: :class:`~transformers.XLNetModelForQuestionAnswering` (XLNet model)
|
||||
- isInstance of `xlm` configuration class: :class:`~transformers.XLMModelForQuestionAnswering` (XLM model)
|
||||
- isInstance of `flaubert` configuration class: :class:`~transformers.FlaubertForQuestionAnswering` (XLM model)
|
||||
|
||||
Examples::
|
||||
|
||||
@@ -714,6 +907,7 @@ class AutoModelForQuestionAnswering(object):
|
||||
- contains `bert`: :class:`~transformers.BertForQuestionAnswering` (Bert model)
|
||||
- contains `xlnet`: :class:`~transformers.XLNetForQuestionAnswering` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.XLMForQuestionAnswering` (XLM model)
|
||||
- contains `flaubert`: :class:`~transformers.FlaubertForQuestionAnswering` (XLM model)
|
||||
|
||||
The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with `model.train()`
|
||||
|
||||
@@ -24,6 +24,7 @@ import torch
|
||||
from torch import nn
|
||||
from torch.nn import CrossEntropyLoss, MSELoss
|
||||
|
||||
from .activations import gelu, gelu_new, swish
|
||||
from .configuration_bert import BertConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PreTrainedModel, prune_linear_layer
|
||||
@@ -53,6 +54,7 @@ BERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"bert-base-japanese-char-whole-word-masking": "https://s3.amazonaws.com/models.huggingface.co/bert/cl-tohoku/bert-base-japanese-char-whole-word-masking-pytorch_model.bin",
|
||||
"bert-base-finnish-cased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/TurkuNLP/bert-base-finnish-cased-v1/pytorch_model.bin",
|
||||
"bert-base-finnish-uncased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/TurkuNLP/bert-base-finnish-uncased-v1/pytorch_model.bin",
|
||||
"bert-base-dutch-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/wietsedv/bert-base-dutch-cased/pytorch_model.bin",
|
||||
}
|
||||
|
||||
|
||||
@@ -85,7 +87,10 @@ def load_tf_weights_in_bert(model, config, tf_checkpoint_path):
|
||||
name = name.split("/")
|
||||
# adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
|
||||
# which are not required for using pretrained model
|
||||
if any(n in ["adam_v", "adam_m", "global_step"] for n in name):
|
||||
if any(
|
||||
n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
|
||||
for n in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
continue
|
||||
pointer = model
|
||||
@@ -125,26 +130,6 @@ def load_tf_weights_in_bert(model, config, tf_checkpoint_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
""" Original Implementation of the gelu activation function in Google Bert repo when initially created.
|
||||
For information: OpenAI GPT's gelu is slightly different (and gives slightly different results):
|
||||
0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return x * 0.5 * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
def gelu_new(x):
|
||||
""" Implementation of the gelu activation function currently in Google Bert repo (identical to OpenAI GPT).
|
||||
Also see https://arxiv.org/abs/1606.08415
|
||||
"""
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
def mish(x):
|
||||
return x * torch.tanh(nn.functional.softplus(x))
|
||||
|
||||
@@ -729,8 +714,8 @@ class BertModel(BertPreTrainedModel):
|
||||
seq_ids = torch.arange(seq_length, device=device)
|
||||
causal_mask = seq_ids[None, None, :].repeat(batch_size, seq_length, 1) <= seq_ids[None, :, None]
|
||||
causal_mask = causal_mask.to(
|
||||
torch.long
|
||||
) # not converting to long will cause errors with pytorch version < 1.3
|
||||
attention_mask.dtype
|
||||
) # causal and attention masks must have same type with pytorch version < 1.3
|
||||
extended_attention_mask = causal_mask[:, None, :, :] * attention_mask[:, None, None, :]
|
||||
else:
|
||||
extended_attention_mask = attention_mask[:, None, None, :]
|
||||
|
||||
@@ -33,6 +33,8 @@ logger = logging.getLogger(__name__)
|
||||
|
||||
CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"camembert-base": "https://s3.amazonaws.com/models.huggingface.co/bert/camembert-base-pytorch_model.bin",
|
||||
"umberto-commoncrawl-cased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/Musixmatch/umberto-commoncrawl-cased-v1/pytorch_model.bin",
|
||||
"umberto-wikipedia-uncased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/Musixmatch/umberto-wikipedia-uncased-v1/pytorch_model.bin",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -27,6 +27,7 @@ import torch
|
||||
import torch.nn as nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
|
||||
from .activations import gelu
|
||||
from .configuration_distilbert import DistilBertConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import PreTrainedModel, prune_linear_layer
|
||||
@@ -38,6 +39,8 @@ logger = logging.getLogger(__name__)
|
||||
DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-pytorch_model.bin",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-distilled-squad-pytorch_model.bin",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-pytorch_model.bin",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-distilled-squad-pytorch_model.bin",
|
||||
"distilbert-base-german-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-german-cased-pytorch_model.bin",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-multilingual-cased-pytorch_model.bin",
|
||||
"distilbert-base-uncased-finetuned-sst-2-english": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-finetuned-sst-2-english-pytorch_model.bin",
|
||||
@@ -45,8 +48,6 @@ DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
|
||||
|
||||
# UTILS AND BUILDING BLOCKS OF THE ARCHITECTURE #
|
||||
def gelu(x):
|
||||
return 0.5 * x * (1.0 + torch.erf(x / math.sqrt(2.0)))
|
||||
|
||||
|
||||
def create_sinusoidal_embeddings(n_pos, dim, out):
|
||||
@@ -440,8 +441,8 @@ class DistilBertModel(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertModel
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertModel.from_pretrained('distilbert-base-cased')
|
||||
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
@@ -544,8 +545,8 @@ class DistilBertForMaskedLM(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForMaskedLM
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForMaskedLM.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForMaskedLM.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, masked_lm_labels=input_ids)
|
||||
loss, prediction_scores = outputs[:2]
|
||||
@@ -619,8 +620,8 @@ class DistilBertForSequenceClassification(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForSequenceClassification
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForSequenceClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForSequenceClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
labels = torch.tensor([1]).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, labels=labels)
|
||||
@@ -711,8 +712,8 @@ class DistilBertForQuestionAnswering(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForQuestionAnswering
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForQuestionAnswering.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForQuestionAnswering.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
start_positions = torch.tensor([1])
|
||||
end_positions = torch.tensor([3])
|
||||
@@ -798,8 +799,8 @@ class DistilBertForTokenClassification(DistilBertPreTrainedModel):
|
||||
from transformers import DistilBertTokenizer, DistilBertForTokenClassification
|
||||
import torch
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = DistilBertForTokenClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = DistilBertForTokenClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Hello, my dog is cute")).unsqueeze(0) # Batch size 1
|
||||
labels = torch.tensor([1] * input_ids.size(1)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids, labels=labels)
|
||||
|
||||
@@ -232,7 +232,7 @@ class PreTrainedEncoderDecoder(nn.Module):
|
||||
encoder_outputs = ()
|
||||
|
||||
kwargs_decoder["encoder_hidden_states"] = encoder_hidden_states
|
||||
decoder_outputs = self.decoder(decoder_input_ids, encoder_hidden_states, **kwargs_decoder)
|
||||
decoder_outputs = self.decoder(decoder_input_ids, **kwargs_decoder)
|
||||
|
||||
return decoder_outputs + encoder_outputs
|
||||
|
||||
|
||||
@@ -0,0 +1,385 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2019-present CNRS, Facebook Inc. and the HuggingFace Inc. team.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" PyTorch Flaubert model, based on XLM. """
|
||||
|
||||
|
||||
import logging
|
||||
import random
|
||||
|
||||
import torch
|
||||
from torch.nn import functional as F
|
||||
|
||||
from .configuration_flaubert import FlaubertConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_xlm import (
|
||||
XLMForQuestionAnswering,
|
||||
XLMForQuestionAnsweringSimple,
|
||||
XLMForSequenceClassification,
|
||||
XLMModel,
|
||||
XLMWithLMHeadModel,
|
||||
get_masks,
|
||||
)
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"flaubert-small-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_small_cased/pytorch_model.bin",
|
||||
"flaubert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_base_uncased/pytorch_model.bin",
|
||||
"flaubert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_base_cased/pytorch_model.bin",
|
||||
"flaubert-large-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/flaubert/flaubert_large_cased/pytorch_model.bin",
|
||||
}
|
||||
|
||||
|
||||
FLAUBERT_START_DOCSTRING = r"""
|
||||
|
||||
This model is a PyTorch `torch.nn.Module <https://pytorch.org/docs/stable/nn.html#torch.nn.Module>`_ sub-class.
|
||||
Use it as a regular PyTorch Module and refer to the PyTorch documentation for all matter related to general
|
||||
usage and behavior.
|
||||
|
||||
Parameters:
|
||||
config (:class:`~transformers.FlaubertConfig`): Model configuration class with all the parameters of the model.
|
||||
Initializing with a config file does not load the weights associated with the model, only the configuration.
|
||||
Check out the :meth:`~transformers.PreTrainedModel.from_pretrained` method to load the model weights.
|
||||
"""
|
||||
|
||||
FLAUBERT_INPUTS_DOCSTRING = r"""
|
||||
Args:
|
||||
input_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`):
|
||||
Indices of input sequence tokens in the vocabulary.
|
||||
|
||||
Indices can be obtained using :class:`transformers.BertTokenizer`.
|
||||
See :func:`transformers.PreTrainedTokenizer.encode` and
|
||||
:func:`transformers.PreTrainedTokenizer.encode_plus` for details.
|
||||
|
||||
`What are input IDs? <../glossary.html#input-ids>`__
|
||||
attention_mask (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to avoid performing attention on padding token indices.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
``1`` for tokens that are NOT MASKED, ``0`` for MASKED tokens.
|
||||
|
||||
`What are attention masks? <../glossary.html#attention-mask>`__
|
||||
token_type_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Segment token indices to indicate first and second portions of the inputs.
|
||||
Indices are selected in ``[0, 1]``: ``0`` corresponds to a `sentence A` token, ``1``
|
||||
corresponds to a `sentence B` token
|
||||
|
||||
`What are token type IDs? <../glossary.html#token-type-ids>`_
|
||||
position_ids (:obj:`torch.LongTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`, defaults to :obj:`None`):
|
||||
Indices of positions of each input sequence tokens in the position embeddings.
|
||||
Selected in the range ``[0, config.max_position_embeddings - 1]``.
|
||||
|
||||
`What are position IDs? <../glossary.html#position-ids>`_
|
||||
lengths (:obj:`torch.LongTensor` of shape :obj:`(batch_size,)`, `optional`, defaults to :obj:`None`):
|
||||
Length of each sentence that can be used to avoid performing attention on padding token indices.
|
||||
You can also use `attention_mask` for the same result (see above), kept here for compatbility.
|
||||
Indices selected in ``[0, ..., input_ids.size(-1)]``:
|
||||
cache (:obj:`Dict[str, torch.FloatTensor]`, `optional`, defaults to :obj:`None`):
|
||||
dictionary with ``torch.FloatTensor`` that contains pre-computed
|
||||
hidden-states (key and values in the attention blocks) as computed by the model
|
||||
(see `cache` output below). Can be used to speed up sequential decoding.
|
||||
The dictionary object will be modified in-place during the forward pass to add newly computed hidden-states.
|
||||
head_mask (:obj:`torch.FloatTensor` of shape :obj:`(num_heads,)` or :obj:`(num_layers, num_heads)`, `optional`, defaults to :obj:`None`):
|
||||
Mask to nullify selected heads of the self-attention modules.
|
||||
Mask values selected in ``[0, 1]``:
|
||||
:obj:`1` indicates the head is **not masked**, :obj:`0` indicates the head is **masked**.
|
||||
input_embeds (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`, defaults to :obj:`None`):
|
||||
Optionally, instead of passing :obj:`input_ids` you can choose to directly pass an embedded representation.
|
||||
This is useful if you want more control over how to convert `input_ids` indices into associated vectors
|
||||
than the model's internal embedding lookup matrix.
|
||||
"""
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"The bare Flaubert Model transformer outputting raw hidden-states without any specific head on top.",
|
||||
FLAUBERT_START_DOCSTRING,
|
||||
)
|
||||
class FlaubertModel(XLMModel):
|
||||
|
||||
config_class = FlaubertConfig
|
||||
pretrained_model_archive_map = FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
def __init__(self, config): # , dico, is_encoder, with_output):
|
||||
super(FlaubertModel, self).__init__(config)
|
||||
self.layerdrop = getattr(config, "layerdrop", 0.0)
|
||||
self.pre_norm = getattr(config, "pre_norm", False)
|
||||
|
||||
@add_start_docstrings_to_callable(FLAUBERT_INPUTS_DOCSTRING)
|
||||
def forward(
|
||||
self,
|
||||
input_ids=None,
|
||||
attention_mask=None,
|
||||
langs=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
lengths=None,
|
||||
cache=None,
|
||||
head_mask=None,
|
||||
inputs_embeds=None,
|
||||
):
|
||||
r"""
|
||||
Return:
|
||||
:obj:`tuple(torch.FloatTensor)` comprising various elements depending on the configuration (:class:`~transformers.XLMConfig`) and inputs:
|
||||
last_hidden_state (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`):
|
||||
Sequence of hidden-states at the output of the last layer of the model.
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape
|
||||
:obj:`(batch_size, num_heads, sequence_length, sequence_length)`.
|
||||
|
||||
Attentions weights after the attention softmax, used to compute the weighted average in the self-attention
|
||||
heads.
|
||||
|
||||
Examples::
|
||||
|
||||
tokenizer = FlaubertTokenizer.from_pretrained('flaubert-base-cased')
|
||||
model = FlaubertModel.from_pretrained('flaubert-base-cased')
|
||||
input_ids = torch.tensor(tokenizer.encode("Le chat manges une pomme.", add_special_tokens=True)).unsqueeze(0) # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
|
||||
"""
|
||||
# removed: src_enc=None, src_len=None
|
||||
if input_ids is not None:
|
||||
bs, slen = input_ids.size()
|
||||
else:
|
||||
bs, slen = inputs_embeds.size()[:-1]
|
||||
|
||||
if lengths is None:
|
||||
if input_ids is not None:
|
||||
lengths = (input_ids != self.pad_index).sum(dim=1).long()
|
||||
else:
|
||||
lengths = torch.LongTensor([slen] * bs)
|
||||
# mask = input_ids != self.pad_index
|
||||
|
||||
# check inputs
|
||||
assert lengths.size(0) == bs
|
||||
assert lengths.max().item() <= slen
|
||||
# input_ids = input_ids.transpose(0, 1) # batch size as dimension 0
|
||||
# assert (src_enc is None) == (src_len is None)
|
||||
# if src_enc is not None:
|
||||
# assert self.is_decoder
|
||||
# assert src_enc.size(0) == bs
|
||||
|
||||
# generate masks
|
||||
mask, attn_mask = get_masks(slen, lengths, self.causal, padding_mask=attention_mask)
|
||||
# if self.is_decoder and src_enc is not None:
|
||||
# src_mask = torch.arange(src_len.max(), dtype=torch.long, device=lengths.device) < src_len[:, None]
|
||||
|
||||
device = input_ids.device if input_ids is not None else inputs_embeds.device
|
||||
|
||||
# position_ids
|
||||
if position_ids is None:
|
||||
position_ids = torch.arange(slen, dtype=torch.long, device=device)
|
||||
position_ids = position_ids.unsqueeze(0).expand((bs, slen))
|
||||
else:
|
||||
assert position_ids.size() == (bs, slen) # (slen, bs)
|
||||
# position_ids = position_ids.transpose(0, 1)
|
||||
|
||||
# langs
|
||||
if langs is not None:
|
||||
assert langs.size() == (bs, slen) # (slen, bs)
|
||||
# langs = langs.transpose(0, 1)
|
||||
|
||||
# Prepare head mask if needed
|
||||
# 1.0 in head_mask indicate we keep the head
|
||||
# attention_probs has shape bsz x n_heads x N x N
|
||||
# input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
|
||||
# and head_mask is converted to shape [num_hidden_layers x batch x num_heads x qlen x klen]
|
||||
if head_mask is not None:
|
||||
if head_mask.dim() == 1:
|
||||
head_mask = head_mask.unsqueeze(0).unsqueeze(0).unsqueeze(-1).unsqueeze(-1)
|
||||
head_mask = head_mask.expand(self.n_layers, -1, -1, -1, -1)
|
||||
elif head_mask.dim() == 2:
|
||||
head_mask = (
|
||||
head_mask.unsqueeze(1).unsqueeze(-1).unsqueeze(-1)
|
||||
) # We can specify head_mask for each layer
|
||||
head_mask = head_mask.to(
|
||||
dtype=next(self.parameters()).dtype
|
||||
) # switch to fload if need + fp16 compatibility
|
||||
else:
|
||||
head_mask = [None] * self.n_layers
|
||||
|
||||
# do not recompute cached elements
|
||||
if cache is not None and input_ids is not None:
|
||||
_slen = slen - cache["slen"]
|
||||
input_ids = input_ids[:, -_slen:]
|
||||
position_ids = position_ids[:, -_slen:]
|
||||
if langs is not None:
|
||||
langs = langs[:, -_slen:]
|
||||
mask = mask[:, -_slen:]
|
||||
attn_mask = attn_mask[:, -_slen:]
|
||||
|
||||
# embeddings
|
||||
if inputs_embeds is None:
|
||||
inputs_embeds = self.embeddings(input_ids)
|
||||
|
||||
tensor = inputs_embeds + self.position_embeddings(position_ids).expand_as(inputs_embeds)
|
||||
if langs is not None and self.use_lang_emb and self.config.n_langs > 1:
|
||||
tensor = tensor + self.lang_embeddings(langs)
|
||||
if token_type_ids is not None:
|
||||
tensor = tensor + self.embeddings(token_type_ids)
|
||||
tensor = self.layer_norm_emb(tensor)
|
||||
tensor = F.dropout(tensor, p=self.dropout, training=self.training)
|
||||
tensor *= mask.unsqueeze(-1).to(tensor.dtype)
|
||||
|
||||
# transformer layers
|
||||
hidden_states = ()
|
||||
attentions = ()
|
||||
for i in range(self.n_layers):
|
||||
# LayerDrop
|
||||
dropout_probability = random.uniform(0, 1)
|
||||
if self.training and (dropout_probability < self.layerdrop):
|
||||
continue
|
||||
|
||||
if self.output_hidden_states:
|
||||
hidden_states = hidden_states + (tensor,)
|
||||
|
||||
# self attention
|
||||
if not self.pre_norm:
|
||||
attn_outputs = self.attentions[i](tensor, attn_mask, cache=cache, head_mask=head_mask[i])
|
||||
attn = attn_outputs[0]
|
||||
if self.output_attentions:
|
||||
attentions = attentions + (attn_outputs[1],)
|
||||
attn = F.dropout(attn, p=self.dropout, training=self.training)
|
||||
tensor = tensor + attn
|
||||
tensor = self.layer_norm1[i](tensor)
|
||||
else:
|
||||
tensor_normalized = self.layer_norm1[i](tensor)
|
||||
attn_outputs = self.attentions[i](tensor_normalized, attn_mask, cache=cache, head_mask=head_mask[i])
|
||||
attn = attn_outputs[0]
|
||||
if self.output_attentions:
|
||||
attentions = attentions + (attn_outputs[1],)
|
||||
attn = F.dropout(attn, p=self.dropout, training=self.training)
|
||||
tensor = tensor + attn
|
||||
|
||||
# encoder attention (for decoder only)
|
||||
# if self.is_decoder and src_enc is not None:
|
||||
# attn = self.encoder_attn[i](tensor, src_mask, kv=src_enc, cache=cache)
|
||||
# attn = F.dropout(attn, p=self.dropout, training=self.training)
|
||||
# tensor = tensor + attn
|
||||
# tensor = self.layer_norm15[i](tensor)
|
||||
|
||||
# FFN
|
||||
if not self.pre_norm:
|
||||
tensor = tensor + self.ffns[i](tensor)
|
||||
tensor = self.layer_norm2[i](tensor)
|
||||
else:
|
||||
tensor_normalized = self.layer_norm2[i](tensor)
|
||||
tensor = tensor + self.ffns[i](tensor_normalized)
|
||||
|
||||
tensor *= mask.unsqueeze(-1).to(tensor.dtype)
|
||||
|
||||
# Add last hidden state
|
||||
if self.output_hidden_states:
|
||||
hidden_states = hidden_states + (tensor,)
|
||||
|
||||
# update cache length
|
||||
if cache is not None:
|
||||
cache["slen"] += tensor.size(1)
|
||||
|
||||
# move back sequence length to dimension 0
|
||||
# tensor = tensor.transpose(0, 1)
|
||||
|
||||
outputs = (tensor,)
|
||||
if self.output_hidden_states:
|
||||
outputs = outputs + (hidden_states,)
|
||||
if self.output_attentions:
|
||||
outputs = outputs + (attentions,)
|
||||
return outputs # outputs, (hidden_states), (attentions)
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""The Flaubert Model transformer with a language modeling head on top
|
||||
(linear layer with weights tied to the input embeddings). """,
|
||||
FLAUBERT_START_DOCSTRING,
|
||||
)
|
||||
class FlaubertWithLMHeadModel(XLMWithLMHeadModel):
|
||||
"""
|
||||
This class overrides :class:`~transformers.XLMWithLMHeadModel`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = FlaubertConfig
|
||||
pretrained_model_archive_map = FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
def __init__(self, config):
|
||||
super(FlaubertWithLMHeadModel, self).__init__(config)
|
||||
self.transformer = FlaubertModel(config)
|
||||
self.init_weights()
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""Flaubert Model with a sequence classification/regression head on top (a linear layer on top of
|
||||
the pooled output) e.g. for GLUE tasks. """,
|
||||
FLAUBERT_START_DOCSTRING,
|
||||
)
|
||||
class FlaubertForSequenceClassification(XLMForSequenceClassification):
|
||||
"""
|
||||
This class overrides :class:`~transformers.XLMForSequenceClassification`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = FlaubertConfig
|
||||
pretrained_model_archive_map = FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
def __init__(self, config):
|
||||
super(FlaubertForSequenceClassification, self).__init__(config)
|
||||
self.transformer = FlaubertModel(config)
|
||||
self.init_weights()
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""Flaubert Model with a span classification head on top for extractive question-answering tasks like SQuAD (a linear layers on top of
|
||||
the hidden-states output to compute `span start logits` and `span end logits`). """,
|
||||
FLAUBERT_START_DOCSTRING,
|
||||
)
|
||||
class FlaubertForQuestionAnsweringSimple(XLMForQuestionAnsweringSimple):
|
||||
"""
|
||||
This class overrides :class:`~transformers.XLMForQuestionAnsweringSimple`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = FlaubertConfig
|
||||
pretrained_model_archive_map = FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
def __init__(self, config):
|
||||
super(FlaubertForQuestionAnsweringSimple, self).__init__(config)
|
||||
self.transformer = FlaubertModel(config)
|
||||
self.init_weights()
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""Flaubert Model with a beam-search span classification head on top for extractive question-answering tasks like SQuAD (a linear layers on top of
|
||||
the hidden-states output to compute `span start logits` and `span end logits`). """,
|
||||
FLAUBERT_START_DOCSTRING,
|
||||
)
|
||||
class FlaubertForQuestionAnswering(XLMForQuestionAnswering):
|
||||
"""
|
||||
This class overrides :class:`~transformers.XLMForQuestionAnswering`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = FlaubertConfig
|
||||
pretrained_model_archive_map = FLAUBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
def __init__(self, config):
|
||||
super(FlaubertForQuestionAnswering, self).__init__(config)
|
||||
self.transformer = FlaubertModel(config)
|
||||
self.init_weights()
|
||||
@@ -24,6 +24,7 @@ import torch
|
||||
import torch.nn as nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
|
||||
from .activations import gelu_new
|
||||
from .configuration_gpt2 import GPT2Config
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import Conv1D, PreTrainedModel, SequenceSummary, prune_conv1d_layer
|
||||
@@ -95,10 +96,6 @@ def load_tf_weights_in_gpt2(model, config, gpt2_checkpoint_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
class Attention(nn.Module):
|
||||
def __init__(self, nx, n_ctx, config, scale=False):
|
||||
super().__init__()
|
||||
@@ -206,7 +203,7 @@ class MLP(nn.Module):
|
||||
nx = config.n_embd
|
||||
self.c_fc = Conv1D(n_state, nx)
|
||||
self.c_proj = Conv1D(nx, n_state)
|
||||
self.act = gelu
|
||||
self.act = gelu_new
|
||||
self.dropout = nn.Dropout(config.resid_pdrop)
|
||||
|
||||
def forward(self, x):
|
||||
|
||||
@@ -25,6 +25,7 @@ import torch
|
||||
import torch.nn as nn
|
||||
from torch.nn import CrossEntropyLoss
|
||||
|
||||
from .activations import gelu_new, swish
|
||||
from .configuration_openai import OpenAIGPTConfig
|
||||
from .file_utils import add_start_docstrings, add_start_docstrings_to_callable
|
||||
from .modeling_utils import Conv1D, PreTrainedModel, SequenceSummary, prune_conv1d_layer
|
||||
@@ -114,15 +115,7 @@ def load_tf_weights_in_openai_gpt(model, config, openai_checkpoint_folder_path):
|
||||
return model
|
||||
|
||||
|
||||
def gelu(x):
|
||||
return 0.5 * x * (1 + torch.tanh(math.sqrt(2 / math.pi) * (x + 0.044715 * torch.pow(x, 3))))
|
||||
|
||||
|
||||
def swish(x):
|
||||
return x * torch.sigmoid(x)
|
||||
|
||||
|
||||
ACT_FNS = {"relu": nn.ReLU, "swish": swish, "gelu": gelu}
|
||||
ACT_FNS = {"relu": nn.ReLU, "swish": swish, "gelu": gelu_new}
|
||||
|
||||
|
||||
class Attention(nn.Module):
|
||||
|
||||
@@ -79,7 +79,10 @@ def load_tf_weights_in_t5(model, config, tf_checkpoint_path):
|
||||
name = txt_name.split("/")
|
||||
# adam_v and adam_m are variables used in AdamWeightDecayOptimizer to calculated m and v
|
||||
# which are not required for using pretrained model
|
||||
if any(n in ["adam_v", "adam_m", "global_step"] for n in name):
|
||||
if any(
|
||||
n in ["adam_v", "adam_m", "AdamWeightDecayOptimizer", "AdamWeightDecayOptimizer_1", "global_step"]
|
||||
for n in name
|
||||
):
|
||||
logger.info("Skipping {}".format("/".join(name)))
|
||||
tf_weights.pop(txt_name, None)
|
||||
continue
|
||||
|
||||
@@ -42,6 +42,7 @@ from .modeling_tf_albert import (
|
||||
from .modeling_tf_bert import (
|
||||
TF_BERT_PRETRAINED_MODEL_ARCHIVE_MAP,
|
||||
TFBertForMaskedLM,
|
||||
TFBertForPreTraining,
|
||||
TFBertForQuestionAnswering,
|
||||
TFBertForSequenceClassification,
|
||||
TFBertForTokenClassification,
|
||||
@@ -125,6 +126,22 @@ TF_MODEL_MAPPING = OrderedDict(
|
||||
]
|
||||
)
|
||||
|
||||
TF_MODEL_FOR_PRETRAINING_MAPPING = OrderedDict(
|
||||
[
|
||||
(T5Config, TFT5WithLMHeadModel),
|
||||
(DistilBertConfig, TFDistilBertForMaskedLM),
|
||||
(AlbertConfig, TFAlbertForMaskedLM),
|
||||
(RobertaConfig, TFRobertaForMaskedLM),
|
||||
(BertConfig, TFBertForPreTraining),
|
||||
(OpenAIGPTConfig, TFOpenAIGPTLMHeadModel),
|
||||
(GPT2Config, TFGPT2LMHeadModel),
|
||||
(TransfoXLConfig, TFTransfoXLLMHeadModel),
|
||||
(XLNetConfig, TFXLNetLMHeadModel),
|
||||
(XLMConfig, TFXLMWithLMHeadModel),
|
||||
(CTRLConfig, TFCTRLLMHeadModel),
|
||||
]
|
||||
)
|
||||
|
||||
TF_MODEL_WITH_LM_HEAD_MAPPING = OrderedDict(
|
||||
[
|
||||
(T5Config, TFT5WithLMHeadModel),
|
||||
@@ -329,6 +346,154 @@ class TFAutoModel(object):
|
||||
)
|
||||
|
||||
|
||||
class TFAutoModelForPreTraining(object):
|
||||
r"""
|
||||
:class:`~transformers.TFAutoModelForPreTraining` is a generic model class
|
||||
that will be instantiated as one of the model classes of the library -with the architecture used for pretraining this model– when created with the `TFAutoModelForPreTraining.from_pretrained(pretrained_model_name_or_path)`
|
||||
class method.
|
||||
|
||||
This class cannot be instantiated using `__init__()` (throws an error).
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
raise EnvironmentError(
|
||||
"TFAutoModelForPreTraining is designed to be instantiated "
|
||||
"using the `TFAutoModelForPreTraining.from_pretrained(pretrained_model_name_or_path)` or "
|
||||
"`TFAutoModelForPreTraining.from_config(config)` methods."
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_config(cls, config):
|
||||
r""" Instantiates one of the base model classes of the library
|
||||
from a configuration.
|
||||
|
||||
Args:
|
||||
config (:class:`~transformers.PretrainedConfig`):
|
||||
The model class to instantiate is selected based on the configuration class:
|
||||
|
||||
- isInstance of `distilbert` configuration class: :class:`~transformers.TFDistilBertModelForMaskedLM` (DistilBERT model)
|
||||
- isInstance of `roberta` configuration class: :class:`~transformers.TFRobertaModelForMaskedLM` (RoBERTa model)
|
||||
- isInstance of `bert` configuration class: :class:`~transformers.TFBertForPreTraining` (Bert model)
|
||||
- isInstance of `openai-gpt` configuration class: :class:`~transformers.TFOpenAIGPTLMHeadModel` (OpenAI GPT model)
|
||||
- isInstance of `gpt2` configuration class: :class:`~transformers.TFGPT2ModelLMHeadModel` (OpenAI GPT-2 model)
|
||||
- isInstance of `ctrl` configuration class: :class:`~transformers.TFCTRLModelLMHeadModel` (Salesforce CTRL model)
|
||||
- isInstance of `transfo-xl` configuration class: :class:`~transformers.TFTransfoXLLMHeadModel` (Transformer-XL model)
|
||||
- isInstance of `xlnet` configuration class: :class:`~transformers.TFXLNetLMHeadModel` (XLNet model)
|
||||
- isInstance of `xlm` configuration class: :class:`~transformers.TFXLMWithLMHeadModel` (XLM model)
|
||||
|
||||
Examples::
|
||||
|
||||
config = BertConfig.from_pretrained('bert-base-uncased') # Download configuration from S3 and cache.
|
||||
model = TFAutoModelForPreTraining.from_config(config) # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
"""
|
||||
for config_class, model_class in TF_MODEL_FOR_PRETRAINING_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
return model_class(config)
|
||||
raise ValueError(
|
||||
"Unrecognized configuration class {} for this kind of AutoModel: {}.\n"
|
||||
"Model type should be one of {}.".format(
|
||||
config.__class__, cls.__name__, ", ".join(c.__name__ for c in TF_MODEL_FOR_PRETRAINING_MAPPING.keys())
|
||||
)
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(cls, pretrained_model_name_or_path, *model_args, **kwargs):
|
||||
r""" Instantiates one of the model classes of the library -with the architecture used for pretraining this model– from a pre-trained model configuration.
|
||||
|
||||
The `from_pretrained()` method takes care of returning the correct model class instance
|
||||
based on the `model_type` property of the config object, or when it's missing,
|
||||
falling back to using pattern matching on the `pretrained_model_name_or_path` string.
|
||||
|
||||
The model class to instantiate is selected as the first pattern matching
|
||||
in the `pretrained_model_name_or_path` string (in the following order):
|
||||
- contains `t5`: :class:`~transformers.TFT5ModelWithLMHead` (T5 model)
|
||||
- contains `distilbert`: :class:`~transformers.TFDistilBertForMaskedLM` (DistilBERT model)
|
||||
- contains `albert`: :class:`~transformers.TFAlbertForMaskedLM` (ALBERT model)
|
||||
- contains `roberta`: :class:`~transformers.TFRobertaForMaskedLM` (RoBERTa model)
|
||||
- contains `bert`: :class:`~transformers.TFBertForPreTraining` (Bert model)
|
||||
- contains `openai-gpt`: :class:`~transformers.TFOpenAIGPTLMHeadModel` (OpenAI GPT model)
|
||||
- contains `gpt2`: :class:`~transformers.TFGPT2LMHeadModel` (OpenAI GPT-2 model)
|
||||
- contains `transfo-xl`: :class:`~transformers.TFTransfoXLLMHeadModel` (Transformer-XL model)
|
||||
- contains `xlnet`: :class:`~transformers.TFXLNetLMHeadModel` (XLNet model)
|
||||
- contains `xlm`: :class:`~transformers.TFXLMWithLMHeadModel` (XLM model)
|
||||
- contains `ctrl`: :class:`~transformers.TFCTRLLMHeadModel` (Salesforce CTRL model)
|
||||
|
||||
The model is set in evaluation mode by default using `model.eval()` (Dropout modules are deactivated)
|
||||
To train the model, you should first set it back in training mode with `model.train()`
|
||||
|
||||
Args:
|
||||
pretrained_model_name_or_path:
|
||||
Either:
|
||||
|
||||
- a string with the `shortcut name` of a pre-trained model to load from cache or download, e.g.: ``bert-base-uncased``.
|
||||
- a string with the `identifier name` of a pre-trained model that was user-uploaded to our S3, e.g.: ``dbmdz/bert-base-german-cased``.
|
||||
- a path to a `directory` containing model weights saved using :func:`~transformers.PreTrainedModel.save_pretrained`, e.g.: ``./my_model_directory/``.
|
||||
- a path or url to a `tensorflow index checkpoint file` (e.g. `./tf_model/model.ckpt.index`). In this case, ``from_tf`` should be set to True and a configuration object should be provided as ``config`` argument. This loading path is slower than converting the TensorFlow checkpoint in a PyTorch model using the provided conversion scripts and loading the PyTorch model afterwards.
|
||||
model_args: (`optional`) Sequence of positional arguments:
|
||||
All remaning positional arguments will be passed to the underlying model's ``__init__`` method
|
||||
config: (`optional`) instance of a class derived from :class:`~transformers.PretrainedConfig`:
|
||||
Configuration for the model to use instead of an automatically loaded configuation. Configuration can be automatically loaded when:
|
||||
|
||||
- the model is a model provided by the library (loaded with the ``shortcut-name`` string of a pretrained model), or
|
||||
- the model was saved using :func:`~transformers.PreTrainedModel.save_pretrained` and is reloaded by suppling the save directory.
|
||||
- the model is loaded by suppling a local directory as ``pretrained_model_name_or_path`` and a configuration JSON file named `config.json` is found in the directory.
|
||||
|
||||
state_dict: (`optional`) dict:
|
||||
an optional state dictionnary for the model to use instead of a state dictionary loaded from saved weights file.
|
||||
This option can be used if you want to create a model from a pretrained configuration but load your own weights.
|
||||
In this case though, you should check if using :func:`~transformers.PreTrainedModel.save_pretrained` and :func:`~transformers.PreTrainedModel.from_pretrained` is not a simpler option.
|
||||
cache_dir: (`optional`) string:
|
||||
Path to a directory in which a downloaded pre-trained model
|
||||
configuration should be cached if the standard cache should not be used.
|
||||
force_download: (`optional`) boolean, default False:
|
||||
Force to (re-)download the model weights and configuration files and override the cached versions if they exists.
|
||||
resume_download: (`optional`) boolean, default False:
|
||||
Do not delete incompletely received file. Attempt to resume the download if such a file exists.
|
||||
proxies: (`optional`) dict, default None:
|
||||
A dictionary of proxy servers to use by protocol or endpoint, e.g.: {'http': 'foo.bar:3128', 'http://hostname': 'foo.bar:4012'}.
|
||||
The proxies are used on each request.
|
||||
output_loading_info: (`optional`) boolean:
|
||||
Set to ``True`` to also return a dictionnary containing missing keys, unexpected keys and error messages.
|
||||
kwargs: (`optional`) Remaining dictionary of keyword arguments:
|
||||
Can be used to update the configuration object (after it being loaded) and initiate the model.
|
||||
(e.g. ``output_attention=True``). Behave differently depending on whether a `config` is provided or
|
||||
automatically loaded:
|
||||
|
||||
- If a configuration is provided with ``config``, ``**kwargs`` will be directly passed to the
|
||||
underlying model's ``__init__`` method (we assume all relevant updates to the configuration have
|
||||
already been done)
|
||||
- If a configuration is not provided, ``kwargs`` will be first passed to the configuration class
|
||||
initialization function (:func:`~transformers.PretrainedConfig.from_pretrained`). Each key of
|
||||
``kwargs`` that corresponds to a configuration attribute will be used to override said attribute
|
||||
with the supplied ``kwargs`` value. Remaining keys that do not correspond to any configuration
|
||||
attribute will be passed to the underlying model's ``__init__`` function.
|
||||
|
||||
Examples::
|
||||
|
||||
model = TFAutoModelForPreTraining.from_pretrained('bert-base-uncased') # Download model and configuration from S3 and cache.
|
||||
model = TFAutoModelForPreTraining.from_pretrained('./test/bert_model/') # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = TFAutoModelForPreTraining.from_pretrained('bert-base-uncased', output_attention=True) # Update configuration during loading
|
||||
assert model.config.output_attention == True
|
||||
# Loading from a TF checkpoint file instead of a PyTorch model (slower)
|
||||
config = AutoConfig.from_json_file('./tf_model/bert_tf_model_config.json')
|
||||
model = TFAutoModelForPreTraining.from_pretrained('./tf_model/bert_tf_checkpoint.ckpt.index', from_tf=True, config=config)
|
||||
|
||||
"""
|
||||
config = kwargs.pop("config", None)
|
||||
if not isinstance(config, PretrainedConfig):
|
||||
config = AutoConfig.from_pretrained(pretrained_model_name_or_path, **kwargs)
|
||||
|
||||
for config_class, model_class in TF_MODEL_FOR_PRETRAINING_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
return model_class.from_pretrained(pretrained_model_name_or_path, *model_args, config=config, **kwargs)
|
||||
raise ValueError(
|
||||
"Unrecognized configuration class {} for this kind of AutoModel: {}.\n"
|
||||
"Model type should be one of {}.".format(
|
||||
config.__class__, cls.__name__, ", ".join(c.__name__ for c in TF_MODEL_FOR_PRETRAINING_MAPPING.keys())
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
class TFAutoModelWithLMHead(object):
|
||||
r"""
|
||||
:class:`~transformers.TFAutoModelWithLMHead` is a generic model class
|
||||
@@ -383,7 +548,7 @@ class TFAutoModelWithLMHead(object):
|
||||
Examples::
|
||||
|
||||
config = BertConfig.from_pretrained('bert-base-uncased') # Download configuration from S3 and cache.
|
||||
model = AutoModelWithLMHead.from_config(config) # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
model = TFAutoModelWithLMHead.from_config(config) # E.g. model was saved using `save_pretrained('./test/saved_model/')`
|
||||
"""
|
||||
for config_class, model_class in TF_MODEL_WITH_LM_HEAD_MAPPING.items():
|
||||
if isinstance(config, config_class):
|
||||
|
||||
@@ -49,6 +49,7 @@ TF_BERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"bert-base-japanese-char-whole-word-masking": "https://s3.amazonaws.com/models.huggingface.co/bert/cl-tohoku/bert-base-japanese-char-whole-word-masking-tf_model.h5",
|
||||
"bert-base-finnish-cased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/TurkuNLP/bert-base-finnish-cased-v1/tf_model.h5",
|
||||
"bert-base-finnish-uncased-v1": "https://s3.amazonaws.com/models.huggingface.co/bert/TurkuNLP/bert-base-finnish-uncased-v1/tf_model.h5",
|
||||
"bert-base-dutch-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/wietsedv/bert-base-dutch-cased/tf_model.h5",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,118 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors and The HuggingFace Inc. team.
|
||||
# Copyright (c) 2018, NVIDIA CORPORATION. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
""" TF 2.0 RoBERTa model. """
|
||||
|
||||
|
||||
import logging
|
||||
|
||||
from .configuration_camembert import CamembertConfig
|
||||
from .file_utils import add_start_docstrings
|
||||
from .modeling_tf_roberta import (
|
||||
TFRobertaForMaskedLM,
|
||||
TFRobertaForSequenceClassification,
|
||||
TFRobertaForTokenClassification,
|
||||
TFRobertaModel,
|
||||
)
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
TF_CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {}
|
||||
|
||||
|
||||
CAMEMBERT_START_DOCSTRING = r"""
|
||||
|
||||
.. note::
|
||||
|
||||
TF 2.0 models accepts two formats as inputs:
|
||||
|
||||
- having all inputs as keyword arguments (like PyTorch models), or
|
||||
- having all inputs as a list, tuple or dict in the first positional arguments.
|
||||
|
||||
This second option is useful when using :obj:`tf.keras.Model.fit()` method which currently requires having
|
||||
all the tensors in the first argument of the model call function: :obj:`model(inputs)`.
|
||||
|
||||
If you choose this second option, there are three possibilities you can use to gather all the input Tensors
|
||||
in the first positional argument :
|
||||
|
||||
- a single Tensor with input_ids only and nothing else: :obj:`model(inputs_ids)`
|
||||
- a list of varying length with one or several input Tensors IN THE ORDER given in the docstring:
|
||||
:obj:`model([input_ids, attention_mask])` or :obj:`model([input_ids, attention_mask, token_type_ids])`
|
||||
- a dictionary with one or several input Tensors associated to the input names given in the docstring:
|
||||
:obj:`model({'input_ids': input_ids, 'token_type_ids': token_type_ids})`
|
||||
|
||||
Parameters:
|
||||
config (:class:`~transformers.CamembertConfig`): Model configuration class with all the parameters of the
|
||||
model. Initializing with a config file does not load the weights associated with the model, only the configuration.
|
||||
Check out the :meth:`~transformers.PreTrainedModel.from_pretrained` method to load the model weights.
|
||||
"""
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"The bare CamemBERT Model transformer outputting raw hidden-states without any specific head on top.",
|
||||
CAMEMBERT_START_DOCSTRING,
|
||||
)
|
||||
class TFCamembertModel(TFRobertaModel):
|
||||
"""
|
||||
This class overrides :class:`~transformers.TFRobertaModel`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = CamembertConfig
|
||||
pretrained_model_archive_map = TF_CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""CamemBERT Model with a `language modeling` head on top. """, CAMEMBERT_START_DOCSTRING,
|
||||
)
|
||||
class TFCamembertForMaskedLM(TFRobertaForMaskedLM):
|
||||
"""
|
||||
This class overrides :class:`~transformers.TFRobertaForMaskedLM`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = CamembertConfig
|
||||
pretrained_model_archive_map = TF_CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""CamemBERT Model transformer with a sequence classification/regression head on top (a linear layer
|
||||
on top of the pooled output) e.g. for GLUE tasks. """,
|
||||
CAMEMBERT_START_DOCSTRING,
|
||||
)
|
||||
class TFCamembertForSequenceClassification(TFRobertaForSequenceClassification):
|
||||
"""
|
||||
This class overrides :class:`~transformers.TFRobertaForSequenceClassification`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = CamembertConfig
|
||||
pretrained_model_archive_map = TF_CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""CamemBERT Model with a token classification head on top (a linear layer on top of
|
||||
the hidden-states output) e.g. for Named-Entity-Recognition (NER) tasks. """,
|
||||
CAMEMBERT_START_DOCSTRING,
|
||||
)
|
||||
class TFCamembertForTokenClassification(TFRobertaForTokenClassification):
|
||||
"""
|
||||
This class overrides :class:`~transformers.TFRobertaForTokenClassification`. Please check the
|
||||
superclass for the appropriate documentation alongside usage examples.
|
||||
"""
|
||||
|
||||
config_class = CamembertConfig
|
||||
pretrained_model_archive_map = TF_CAMEMBERT_PRETRAINED_MODEL_ARCHIVE_MAP
|
||||
@@ -33,6 +33,8 @@ logger = logging.getLogger(__name__)
|
||||
TF_DISTILBERT_PRETRAINED_MODEL_ARCHIVE_MAP = {
|
||||
"distilbert-base-uncased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-tf_model.h5",
|
||||
"distilbert-base-uncased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-distilled-squad-tf_model.h5",
|
||||
"distilbert-base-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-tf_model.h5",
|
||||
"distilbert-base-cased-distilled-squad": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-cased-distilled-squad-tf_model.h5",
|
||||
"distilbert-base-multilingual-cased": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-multilingual-cased-tf_model.h5",
|
||||
"distilbert-base-uncased-finetuned-sst-2-english": "https://s3.amazonaws.com/models.huggingface.co/bert/distilbert-base-uncased-finetuned-sst-2-english-tf_model.h5",
|
||||
}
|
||||
@@ -78,8 +80,6 @@ class TFEmbeddings(tf.keras.layers.Layer):
|
||||
embeddings_initializer=get_initializer(config.initializer_range),
|
||||
name="position_embeddings",
|
||||
)
|
||||
if config.sinusoidal_pos_embds:
|
||||
raise NotImplementedError
|
||||
|
||||
self.LayerNorm = tf.keras.layers.LayerNormalization(epsilon=1e-12, name="LayerNorm")
|
||||
self.dropout = tf.keras.layers.Dropout(config.dropout)
|
||||
@@ -563,8 +563,8 @@ class TFDistilBertModel(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertModel
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertModel.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertModel.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
last_hidden_states = outputs[0] # The last hidden-state is the first element of the output tuple
|
||||
@@ -637,8 +637,8 @@ class TFDistilBertForMaskedLM(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForMaskedLM
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForMaskedLM.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForMaskedLM.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
prediction_scores = outputs[0]
|
||||
@@ -701,8 +701,8 @@ class TFDistilBertForSequenceClassification(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForSequenceClassification
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForSequenceClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForSequenceClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
logits = outputs[0]
|
||||
@@ -759,8 +759,8 @@ class TFDistilBertForTokenClassification(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForTokenClassification
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForTokenClassification.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForTokenClassification.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
scores = outputs[0]
|
||||
@@ -818,8 +818,8 @@ class TFDistilBertForQuestionAnswering(TFDistilBertPreTrainedModel):
|
||||
import tensorflow as tf
|
||||
from transformers import DistilBertTokenizer, TFDistilBertForQuestionAnswering
|
||||
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-uncased')
|
||||
model = TFDistilBertForQuestionAnswering.from_pretrained('distilbert-base-uncased')
|
||||
tokenizer = DistilBertTokenizer.from_pretrained('distilbert-base-cased')
|
||||
model = TFDistilBertForQuestionAnswering.from_pretrained('distilbert-base-cased')
|
||||
input_ids = tf.constant(tokenizer.encode("Hello, my dog is cute"))[None, :] # Batch size 1
|
||||
outputs = model(input_ids)
|
||||
start_scores, end_scores = outputs[:2]
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user