Merge remote-tracking branch 'origin/master'
This commit is contained in:
 Sylvain Gugger
@@ -20,7 +20,7 @@ Fixes # (issue)
|
||||
- [ ] Did you read the [contributor guideline](https://github.com/huggingface/transformers/blob/master/CONTRIBUTING.md#start-contributing-pull-requests),
|
||||
Pull Request section?
|
||||
- [ ] Was this discussed/approved via a Github issue or the [forum](https://discuss.huggingface.co/)? Please add a link
|
||||
to the it if that's the case.
|
||||
to it if that's the case.
|
||||
- [ ] Did you make sure to update the documentation with your changes? Here are the
|
||||
[documentation guidelines](https://github.com/huggingface/transformers/tree/master/docs), and
|
||||
[here are tips on formatting docstrings](https://github.com/huggingface/transformers/tree/master/docs#writing-source-documentation).
|
||||
|
||||
@@ -48,7 +48,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[torch,sklearn,testing,onnxruntime]
|
||||
pip install .[torch,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
|
||||
- name: Are GPUs recognized by our DL frameworks
|
||||
@@ -117,7 +117,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[tf,sklearn,testing,onnxruntime]
|
||||
pip install .[tf,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
|
||||
- name: Are GPUs recognized by our DL frameworks
|
||||
@@ -185,7 +185,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[torch,sklearn,testing,onnxruntime]
|
||||
pip install .[torch,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
|
||||
- name: Are GPUs recognized by our DL frameworks
|
||||
@@ -244,7 +244,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[tf,sklearn,testing,onnxruntime]
|
||||
pip install .[tf,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
|
||||
- name: Are GPUs recognized by our DL frameworks
|
||||
|
||||
@@ -50,7 +50,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[torch,sklearn,testing,onnxruntime]
|
||||
pip install .[torch,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
pip list
|
||||
|
||||
@@ -144,7 +144,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[tf,sklearn,testing,onnxruntime]
|
||||
pip install .[tf,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
pip list
|
||||
|
||||
@@ -223,7 +223,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[torch,sklearn,testing,onnxruntime]
|
||||
pip install .[torch,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
pip list
|
||||
|
||||
@@ -251,11 +251,11 @@ jobs:
|
||||
RUN_SLOW: yes
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -m pytest -n 1 --dist=loadfile -s --make-reports=examples_torch_multi_gpu examples
|
||||
python -m pytest -n 1 --dist=loadfile -s --make-reports=tests_torch_examples_multi_gpu examples
|
||||
|
||||
- name: Failure short reports
|
||||
if: ${{ always() }}
|
||||
run: cat reports/examples_torch_multi_gpu_failures_short.txt
|
||||
run: cat reports/tests_torch_examples_multi_gpu_failures_short.txt
|
||||
|
||||
- name: Run all pipeline tests on multi-GPU
|
||||
if: ${{ always() }}
|
||||
@@ -314,7 +314,7 @@ jobs:
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
pip install --upgrade pip
|
||||
pip install .[tf,sklearn,testing,onnxruntime]
|
||||
pip install .[tf,sklearn,testing,onnxruntime,sentencepiece]
|
||||
pip install git+https://github.com/huggingface/datasets
|
||||
pip list
|
||||
|
||||
@@ -345,11 +345,11 @@ jobs:
|
||||
RUN_PIPELINE_TESTS: yes
|
||||
run: |
|
||||
source .env/bin/activate
|
||||
python -m pytest -n 1 --dist=loadfile -s -m is_pipeline_test --make-reports=tests_tf_pipelines_multi_gpu tests
|
||||
python -m pytest -n 1 --dist=loadfile -s -m is_pipeline_test --make-reports=tests_tf_pipeline_multi_gpu tests
|
||||
|
||||
- name: Failure short reports
|
||||
if: ${{ always() }}
|
||||
run: cat reports/tests_tf_multi_gpu_pipelines_failures_short.txt
|
||||
run: cat reports/tests_tf_pipeline_multi_gpu_failures_short.txt
|
||||
|
||||
- name: Test suite reports artifacts
|
||||
if: ${{ always() }}
|
||||
|
||||
@@ -99,21 +99,41 @@ Longformer specific outputs
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerBaseModelOutputWithPooling
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerMultipleChoiceModelOutput
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerMaskedLMOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerQuestionAnsweringModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerSequenceClassifierOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerMultipleChoiceModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_longformer.LongformerTokenClassifierOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerBaseModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerBaseModelOutputWithPooling
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerMaskedLMOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerQuestionAnsweringModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerSequenceClassifierOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerMultipleChoiceModelOutput
|
||||
:members:
|
||||
|
||||
.. autoclass:: transformers.models.longformer.modeling_tf_longformer.TFLongformerTokenClassifierOutput
|
||||
:members:
|
||||
|
||||
LongformerModel
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
@@ -177,3 +197,24 @@ TFLongformerForQuestionAnswering
|
||||
.. autoclass:: transformers.TFLongformerForQuestionAnswering
|
||||
:members: call
|
||||
|
||||
|
||||
TFLongformerForSequenceClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFLongformerForSequenceClassification
|
||||
:members: call
|
||||
|
||||
|
||||
TFLongformerForTokenClassification
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFLongformerForTokenClassification
|
||||
:members: call
|
||||
|
||||
|
||||
TFLongformerForMultipleChoice
|
||||
~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
.. autoclass:: transformers.TFLongformerForMultipleChoice
|
||||
:members: call
|
||||
|
||||
|
||||
@@ -231,7 +231,9 @@ Here is an example of question answering using a model and a tokenizer. The proc
|
||||
... input_ids = inputs["input_ids"].tolist()[0]
|
||||
...
|
||||
... text_tokens = tokenizer.convert_ids_to_tokens(input_ids)
|
||||
... answer_start_scores, answer_end_scores = model(**inputs)
|
||||
... outputs = model(**inputs)
|
||||
... answer_start_scores = outputs.start_logits
|
||||
... answer_end_scores = outputs.end_logits
|
||||
...
|
||||
... answer_start = torch.argmax(
|
||||
... answer_start_scores
|
||||
@@ -273,7 +275,9 @@ Here is an example of question answering using a model and a tokenizer. The proc
|
||||
... input_ids = inputs["input_ids"].numpy()[0]
|
||||
...
|
||||
... text_tokens = tokenizer.convert_ids_to_tokens(input_ids)
|
||||
... answer_start_scores, answer_end_scores = model(inputs)
|
||||
... outputs = model(inputs)
|
||||
... answer_start_scores = outputs.start_logits
|
||||
... answer_end_scores = outputs.end_logits
|
||||
...
|
||||
... answer_start = tf.argmax(
|
||||
... answer_start_scores, axis=1
|
||||
|
||||
@@ -1055,7 +1055,7 @@ If you need to validate the output of a logger, you can use :obj:`CaptureLogger`
|
||||
|
||||
msg = "Testing 1, 2, 3"
|
||||
logging.set_verbosity_info()
|
||||
logger = logging.get_logger("transformers.tokenization_bart")
|
||||
logger = logging.get_logger("transformers.models.bart.tokenization_bart")
|
||||
with CaptureLogger(logger) as cl:
|
||||
logger.info(msg)
|
||||
assert cl.out, msg+"\n"
|
||||
|
||||
@@ -3,7 +3,7 @@ import json
|
||||
from typing import List
|
||||
|
||||
from ltp import LTP
|
||||
from transformers.tokenization_bert import BertTokenizer
|
||||
from transformers import BertTokenizer
|
||||
|
||||
|
||||
def _is_chinese_char(cp):
|
||||
|
||||
@@ -90,7 +90,7 @@ selected tokens (which may be part of words), they mask randomly selected words
|
||||
to that word). This technique has been refined for Chinese in [this paper](https://arxiv.org/abs/1906.08101).
|
||||
|
||||
To fine-tune a model using whole word masking, use the following script:
|
||||
|
||||
```bash
|
||||
python run_mlm_wwm.py \
|
||||
--model_name_or_path roberta-base \
|
||||
--dataset_name wikitext \
|
||||
@@ -164,7 +164,7 @@ context length for permutation language modeling.
|
||||
The `--max_span_length` flag may also be used to limit the length of a span of masked tokens used
|
||||
for permutation language modeling.
|
||||
|
||||
Here is how to fine-tun XLNet on wikitext-2:
|
||||
Here is how to fine-tune XLNet on wikitext-2:
|
||||
|
||||
```bash
|
||||
python run_plm.py \
|
||||
|
||||
@@ -107,7 +107,12 @@ def make_support(question, source="wiki40b", method="dense", n_results=10):
|
||||
return question_doc, support_list
|
||||
|
||||
|
||||
@st.cache(hash_funcs={torch.Tensor: (lambda _: None), transformers.tokenization_bart.BartTokenizer: (lambda _: None)})
|
||||
@st.cache(
|
||||
hash_funcs={
|
||||
torch.Tensor: (lambda _: None),
|
||||
transformers.models.bart.tokenization_bart.BartTokenizer: (lambda _: None),
|
||||
}
|
||||
)
|
||||
def answer_question(
|
||||
question_doc, s2s_model, s2s_tokenizer, min_len=64, max_len=256, sampling=False, n_beams=2, top_p=0.95, temp=0.8
|
||||
):
|
||||
|
||||
@@ -47,7 +47,7 @@ def embed(documents: dict, ctx_encoder: DPRContextEncoder, ctx_tokenizer: DPRCon
|
||||
input_ids = ctx_tokenizer(
|
||||
documents["title"], documents["text"], truncation=True, padding="longest", return_tensors="pt"
|
||||
)["input_ids"]
|
||||
embeddings = ctx_encoder(input_ids.to(device=device)).pooler_output
|
||||
embeddings = ctx_encoder(input_ids.to(device=device), return_dict=True).pooler_output
|
||||
return {"embeddings": embeddings.detach().cpu().numpy()}
|
||||
|
||||
|
||||
|
||||
@@ -154,7 +154,7 @@ class SummarizationDistiller(SummarizationModule):
|
||||
output_attentions=False,
|
||||
use_cache=False,
|
||||
)
|
||||
lm_logits = student_outputs.logits
|
||||
lm_logits = student_outputs["logits"]
|
||||
|
||||
# Same cross entropy vs. label smoothing logic as finetune.py
|
||||
assert lm_logits.shape[-1] == self.model.config.vocab_size
|
||||
@@ -171,7 +171,9 @@ class SummarizationDistiller(SummarizationModule):
|
||||
def zero_tensor():
|
||||
return torch.tensor(0.0).type_as(student_lm_loss)
|
||||
|
||||
teacher_enc_outputs = student_outputs.encoder_last_hidden_state # use this unless self.different_base_models
|
||||
teacher_enc_outputs = student_outputs[
|
||||
"encoder_last_hidden_state"
|
||||
] # use this unless self.different_base_models
|
||||
hid_loss_enc, hid_loss_dec = zero_tensor(), zero_tensor()
|
||||
if self.different_encoder: # compute encoder hidden state loss
|
||||
all_teacher_encoder_outputs = self.teacher.get_encoder()(
|
||||
@@ -180,12 +182,12 @@ class SummarizationDistiller(SummarizationModule):
|
||||
output_hidden_states=self.do_calc_hidden_loss,
|
||||
)
|
||||
if self.different_base_models:
|
||||
teacher_enc_outputs = all_teacher_encoder_outputs.last_hidden_state
|
||||
teacher_enc_outputs = all_teacher_encoder_outputs["last_hidden_state"]
|
||||
elif self.do_calc_hidden_loss:
|
||||
hid_loss_enc = self.calc_hidden_loss(
|
||||
src_mask,
|
||||
student_outputs.encoder_hidden_states,
|
||||
all_teacher_encoder_outputs.hidden_states,
|
||||
student_outputs["encoder_hidden_states"],
|
||||
all_teacher_encoder_outputs["hidden_states"],
|
||||
self.e_matches,
|
||||
normalize_hidden=self.hparams.normalize_hidden,
|
||||
)
|
||||
@@ -199,12 +201,12 @@ class SummarizationDistiller(SummarizationModule):
|
||||
use_cache=False, # since we are not passing labels, never let this default to True
|
||||
)
|
||||
dec_mask = decoder_input_ids.ne(pad_token_id)
|
||||
loss_ce = self.calc_ce_loss(dec_mask, lm_logits, teacher_outputs.logits)
|
||||
loss_ce = self.calc_ce_loss(dec_mask, lm_logits, teacher_outputs["logits"])
|
||||
if self.do_calc_hidden_loss: # Intermediate supervision of decoder hidden states
|
||||
hid_loss_dec = self.calc_hidden_loss(
|
||||
dec_mask,
|
||||
student_outputs.decoder_hidden_states,
|
||||
teacher_outputs.decoder_hidden_states,
|
||||
student_outputs["decoder_hidden_states"],
|
||||
teacher_outputs["decoder_hidden_states"],
|
||||
self.d_matches,
|
||||
normalize_hidden=self.hparams.normalize_hidden,
|
||||
)
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
from typing import Any, Dict, Optional, Tuple, Union
|
||||
from typing import Any, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
@@ -153,7 +153,11 @@ class Seq2SeqTrainer(Trainer):
|
||||
return loss
|
||||
|
||||
def prediction_step(
|
||||
self, model: nn.Module, inputs: Dict[str, Union[torch.Tensor, Any]], prediction_loss_only: bool
|
||||
self,
|
||||
model: nn.Module,
|
||||
inputs: Dict[str, Union[torch.Tensor, Any]],
|
||||
prediction_loss_only: bool,
|
||||
ignore_keys: Optional[List[str]] = None,
|
||||
) -> Tuple[Optional[float], Optional[torch.Tensor], Optional[torch.Tensor]]:
|
||||
"""
|
||||
Perform an evaluation step on :obj:`model` using obj:`inputs`.
|
||||
|
||||
@@ -0,0 +1,49 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-15lang-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
The measurements below have been computed on a [Google Cloud n1-standard-1 machine (1 vCPU, 3.75 GB)](https://cloud.google.com/compute/docs/machine-types\#n1_machine_type):
|
||||
|
||||
| Model | Num parameters | Size | Memory | Loading time |
|
||||
| ------------------------------- | -------------- | -------- | -------- | ------------ |
|
||||
| bert-base-multilingual-cased | 178 million | 714 MB | 1400 MB | 4.2 sec |
|
||||
| Geotrend/bert-base-15lang-cased | 141 million | 564 MB | 1098 MB | 3.1 sec |
|
||||
|
||||
Handled languages: en, fr, es, de, zh, ar, ru, vi, el, bg, th, tr, hi, ur and sw.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-15lang-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-15lang-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,41 @@
|
||||
---
|
||||
language: ar
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-ar-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-ar-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-ar-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: bg
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-bg-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-bg-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-bg-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: de
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-de-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-de-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-de-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: el
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-el-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-el-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-el-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-ar-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-ar-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-ar-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-bg-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-bg-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-bg-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: en
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-de-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-de-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-de-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-el-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-el-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-el-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-es-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-es-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-es-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-fr-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-fr-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-fr-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-hi-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-hi-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-hi-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-ru-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-ru-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-ru-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-sw-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-sw-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-sw-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-th-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-th-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-th-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-tr-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-tr-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-tr-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-ur-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-ur-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-ur-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-vi-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-vi-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-vi-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: multilingual
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-en-zh-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-en-zh-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-en-zh-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: es
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-es-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-es-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-es-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: fr
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-fr-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-fr-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-fr-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: hi
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-hi-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-hi-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-hi-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: ru
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-ru-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-ru-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-ru-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: sw
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-sw-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-sw-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-sw-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: th
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-th-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-th-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-th-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: tr
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-tr-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-tr-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-tr-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: ur
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-ur-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-ur-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-ur-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: vi
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-vi-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-vi-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-vi-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
language: zh
|
||||
|
||||
datasets: wikipedia
|
||||
|
||||
license: apache-2.0
|
||||
---
|
||||
|
||||
# bert-base-zh-cased
|
||||
|
||||
We are sharing smaller versions of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) that handle a custom number of languages.
|
||||
|
||||
Unlike [distilbert-base-multilingual-cased](https://huggingface.co/distilbert-base-multilingual-cased), our versions give exactly the same representations produced by the original model which preserves the original accuracy.
|
||||
|
||||
For more information please visit our paper: [Load What You Need: Smaller Versions of Multilingual BERT](https://www.aclweb.org/anthology/2020.sustainlp-1.16.pdf).
|
||||
|
||||
## How to use
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModel
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Geotrend/bert-base-zh-cased")
|
||||
model = AutoModel.from_pretrained("Geotrend/bert-base-zh-cased")
|
||||
|
||||
```
|
||||
|
||||
### How to cite
|
||||
|
||||
```bibtex
|
||||
@inproceedings{smallermbert,
|
||||
title={Load What You Need: Smaller Versions of Mutlilingual BERT},
|
||||
author={Abdaoui, Amine and Pradel, Camille and Sigel, Grégoire},
|
||||
booktitle={SustaiNLP / EMNLP},
|
||||
year={2020}
|
||||
}
|
||||
```
|
||||
|
||||
## Contact
|
||||
|
||||
Please contact amine@geotrend.fr for any question, feedback or request.
|
||||
@@ -0,0 +1,48 @@
|
||||
---
|
||||
language:
|
||||
- ach
|
||||
- en
|
||||
tags:
|
||||
- translation
|
||||
license: cc-by-4.0
|
||||
datasets:
|
||||
- JW300
|
||||
metrics:
|
||||
- bleu
|
||||
---
|
||||
|
||||
# HEL-ACH-EN
|
||||
|
||||
## Model description
|
||||
|
||||
MT model translating Acholi to English initialized with weights from [opus-mt-luo-en](https://huggingface.co/Helsinki-NLP/opus-mt-luo-en) on HuggingFace.
|
||||
|
||||
## Intended uses & limitations
|
||||
Machine Translation experiments. Do not use for sensitive tasks.
|
||||
#### How to use
|
||||
|
||||
```python
|
||||
# You can include sample code which will be formatted
|
||||
from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("Ogayo/Hel-ach-en")
|
||||
|
||||
model = AutoModelForSeq2SeqLM.from_pretrained("Ogayo/Hel-ach-en")
|
||||
|
||||
```
|
||||
|
||||
#### Limitations and bias
|
||||
|
||||
Trained on Jehovah Witnesses data so contains theirs and Christian views.
|
||||
|
||||
## Training data
|
||||
Trained on OPUS JW300 data.
|
||||
Initialized with weights from [opus-mt-luo-en](https://huggingface.co/Helsinki-NLP/opus-mt-luo-en?text=Bed+gi+nyasi+mar+chieng%27+nyuol+mopong%27+gi+mor%21#model_card)
|
||||
|
||||
## Training procedure
|
||||
|
||||
Remove duplicates and rows with no alphabetic characters. Used GPU
|
||||
## Eval results
|
||||
testset | BLEU
|
||||
--- | ---
|
||||
JW300.luo.en| 46.1
|
||||
@@ -0,0 +1,132 @@
|
||||
---
|
||||
tags:
|
||||
- finance
|
||||
---
|
||||
# Roberta Masked Language Model Trained On Financial Phrasebank Corpus
|
||||
|
||||
|
||||
This is a Masked Language Model trained with [Roberta](https://huggingface.co/transformers/model_doc/roberta.html) on a Financial Phrasebank Corpus.
|
||||
The model is built using Huggingface transformers.
|
||||
The model can be found at :[Financial_Roberta](https://huggingface.co/abhilash1910/financial_roberta)
|
||||
|
||||
|
||||
## Specifications
|
||||
|
||||
|
||||
The corpus for training is taken from the Financial Phrasebank (Malo et al)[https://www.researchgate.net/publication/251231107_Good_Debt_or_Bad_Debt_Detecting_Semantic_Orientations_in_Economic_Texts].
|
||||
|
||||
|
||||
## Model Specification
|
||||
|
||||
|
||||
The model chosen for training is [Roberta](https://arxiv.org/abs/1907.11692) with the following specifications:
|
||||
1. vocab_size=56000
|
||||
2. max_position_embeddings=514
|
||||
3. num_attention_heads=12
|
||||
4. num_hidden_layers=6
|
||||
5. type_vocab_size=1
|
||||
|
||||
|
||||
This is trained by using RobertaConfig from transformers package.
|
||||
The model is trained for 10 epochs with a gpu batch size of 64 units.
|
||||
|
||||
|
||||
|
||||
## Usage Specifications
|
||||
|
||||
|
||||
For using this model, we have to first import AutoTokenizer and AutoModelWithLMHead Modules from transformers
|
||||
After that we have to specify, the pre-trained model,which in this case is 'abhilash1910/financial_roberta' for the tokenizers and the model.
|
||||
|
||||
|
||||
```python
|
||||
from transformers import AutoTokenizer, AutoModelWithLMHead
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("abhilash1910/financial_roberta")
|
||||
|
||||
model = AutoModelWithLMHead.from_pretrained("abhilash1910/financial_roberta")
|
||||
```
|
||||
|
||||
|
||||
After this the model will be downloaded, it will take some time to download all the model files.
|
||||
For testing the model, we have to import pipeline module from transformers and create a masked output model for inference as follows:
|
||||
|
||||
|
||||
```python
|
||||
from transformers import pipeline
|
||||
model_mask = pipeline('fill-mask', model='abhilash1910/inancial_roberta')
|
||||
model_mask("The company had a <mask> of 20% in 2020.")
|
||||
```
|
||||
|
||||
|
||||
Some of the examples are also provided with generic financial statements:
|
||||
|
||||
Example 1:
|
||||
|
||||
|
||||
```python
|
||||
model_mask("The company had a <mask> of 20% in 2020.")
|
||||
```
|
||||
|
||||
|
||||
Output:
|
||||
|
||||
|
||||
```bash
|
||||
[{'sequence': '<s>The company had a profit of 20% in 2020.</s>',
|
||||
'score': 0.023112965747714043,
|
||||
'token': 421,
|
||||
'token_str': 'Ġprofit'},
|
||||
{'sequence': '<s>The company had a loss of 20% in 2020.</s>',
|
||||
'score': 0.021379893645644188,
|
||||
'token': 616,
|
||||
'token_str': 'Ġloss'},
|
||||
{'sequence': '<s>The company had a year of 20% in 2020.</s>',
|
||||
'score': 0.0185744296759367,
|
||||
'token': 443,
|
||||
'token_str': 'Ġyear'},
|
||||
{'sequence': '<s>The company had a sales of 20% in 2020.</s>',
|
||||
'score': 0.018143286928534508,
|
||||
'token': 428,
|
||||
'token_str': 'Ġsales'},
|
||||
{'sequence': '<s>The company had a value of 20% in 2020.</s>',
|
||||
'score': 0.015319528989493847,
|
||||
'token': 776,
|
||||
'token_str': 'Ġvalue'}]
|
||||
```
|
||||
|
||||
Example 2:
|
||||
|
||||
```python
|
||||
model_mask("The <mask> is listed under NYSE")
|
||||
```
|
||||
|
||||
Output:
|
||||
|
||||
```bash
|
||||
[{'sequence': '<s>The company is listed under NYSE</s>',
|
||||
'score': 0.1566661298274994,
|
||||
'token': 359,
|
||||
'token_str': 'Ġcompany'},
|
||||
{'sequence': '<s>The total is listed under NYSE</s>',
|
||||
'score': 0.05542507395148277,
|
||||
'token': 522,
|
||||
'token_str': 'Ġtotal'},
|
||||
{'sequence': '<s>The value is listed under NYSE</s>',
|
||||
'score': 0.04729423299431801,
|
||||
'token': 776,
|
||||
'token_str': 'Ġvalue'},
|
||||
{'sequence': '<s>The order is listed under NYSE</s>',
|
||||
'score': 0.02533523552119732,
|
||||
'token': 798,
|
||||
'token_str': 'Ġorder'},
|
||||
{'sequence': '<s>The contract is listed under NYSE</s>',
|
||||
'score': 0.02087237872183323,
|
||||
'token': 635,
|
||||
'token_str': 'Ġcontract'}]
|
||||
```
|
||||
|
||||
|
||||
## Resources
|
||||
|
||||
For all resources , please look into the [HuggingFace](https://huggingface.co/) Site and the [Repositories](https://github.com/huggingface).
|
||||
@@ -0,0 +1,118 @@
|
||||
---
|
||||
language: en
|
||||
license: mit
|
||||
datasets:
|
||||
- AI4Bharat IndicNLP Corpora
|
||||
---
|
||||
|
||||
# IndicBERT
|
||||
|
||||
IndicBERT is a multilingual ALBERT model pretrained exclusively on 12 major Indian languages. It is pre-trained on our novel monolingual corpus of around 9 billion tokens and subsequently evaluated on a set of diverse tasks. IndicBERT has much fewer parameters than other multilingual models (mBERT, XLM-R etc.) while it also achieves a performance on-par or better than these models.
|
||||
|
||||
The 12 languages covered by IndicBERT are: Assamese, Bengali, English, Gujarati, Hindi, Kannada, Malayalam, Marathi, Oriya, Punjabi, Tamil, Telugu.
|
||||
|
||||
The code can be found [here](https://github.com/divkakwani/indic-bert). For more information, checkout our [project page](https://indicnlp.ai4bharat.org/) or our [paper](https://indicnlp.ai4bharat.org/papers/arxiv2020_indicnlp_corpus.pdf).
|
||||
|
||||
|
||||
|
||||
## Pretraining Corpus
|
||||
|
||||
We pre-trained indic-bert on AI4Bharat's monolingual corpus. The corpus has the following distribution of languages:
|
||||
|
||||
|
||||
| Language | as | bn | en | gu | hi | kn | |
|
||||
| ----------------- | ------ | ------ | ------ | ------ | ------ | ------ | ------- |
|
||||
| **No. of Tokens** | 36.9M | 815M | 1.34B | 724M | 1.84B | 712M | |
|
||||
| **Language** | **ml** | **mr** | **or** | **pa** | **ta** | **te** | **all** |
|
||||
| **No. of Tokens** | 767M | 560M | 104M | 814M | 549M | 671M | 8.9B |
|
||||
|
||||
|
||||
|
||||
## Evaluation Results
|
||||
|
||||
IndicBERT is evaluated on IndicGLUE and some additional tasks. The results are summarized below. For more details about the tasks, refer our [official repo](https://github.com/divkakwani/indic-bert)
|
||||
|
||||
#### IndicGLUE
|
||||
|
||||
Task | mBERT | XLM-R | IndicBERT
|
||||
-----| ----- | ----- | ------
|
||||
News Article Headline Prediction | 89.58 | 95.52 | **95.87**
|
||||
Wikipedia Section Title Prediction| **73.66** | 66.33 | 73.31
|
||||
Cloze-style multiple-choice QA | 39.16 | 27.98 | **41.87**
|
||||
Article Genre Classification | 90.63 | 97.03 | **97.34**
|
||||
Named Entity Recognition (F1-score) | **73.24** | 65.93 | 64.47
|
||||
Cross-Lingual Sentence Retrieval Task | 21.46 | 13.74 | **27.12**
|
||||
Average | 64.62 | 61.09 | **66.66**
|
||||
|
||||
#### Additional Tasks
|
||||
|
||||
|
||||
Task | Task Type | mBERT | XLM-R | IndicBERT
|
||||
-----| ----- | ----- | ------ | -----
|
||||
BBC News Classification | Genre Classification | 60.55 | **75.52** | 74.60
|
||||
IIT Product Reviews | Sentiment Analysis | 74.57 | **78.97** | 71.32
|
||||
IITP Movie Reviews | Sentiment Analaysis | 56.77 | **61.61** | 59.03
|
||||
Soham News Article | Genre Classification | 80.23 | **87.6** | 78.45
|
||||
Midas Discourse | Discourse Analysis | 71.20 | **79.94** | 78.44
|
||||
iNLTK Headlines Classification | Genre Classification | 87.95 | 93.38 | **94.52**
|
||||
ACTSA Sentiment Analysis | Sentiment Analysis | 48.53 | 59.33 | **61.18**
|
||||
Winograd NLI | Natural Language Inference | 56.34 | 55.87 | **56.34**
|
||||
Choice of Plausible Alternative (COPA) | Natural Language Inference | 54.92 | 51.13 | **58.33**
|
||||
Amrita Exact Paraphrase | Paraphrase Detection | **93.81** | 93.02 | 93.75
|
||||
Amrita Rough Paraphrase | Paraphrase Detection | 83.38 | 82.20 | **84.33**
|
||||
Average | | 69.84 | **74.42** | 73.66
|
||||
|
||||
|
||||
\* Note: all models have been restricted to a max_seq_length of 128.
|
||||
|
||||
|
||||
|
||||
## Downloads
|
||||
|
||||
The model can be downloaded [here](https://storage.googleapis.com/ai4bharat-public-indic-nlp-corpora/models/indic-bert-v1.tar.gz). Both tf checkpoints and pytorch binaries are included in the archive. Alternatively, you can also download it from [Huggingface](https://huggingface.co/ai4bharat/indic-bert).
|
||||
|
||||
|
||||
|
||||
## Citing
|
||||
|
||||
If you are using any of the resources, please cite the following article:
|
||||
|
||||
```
|
||||
@inproceedings{kakwani2020indicnlpsuite,
|
||||
title={{IndicNLPSuite: Monolingual Corpora, Evaluation Benchmarks and Pre-trained Multilingual Language Models for Indian Languages}},
|
||||
author={Divyanshu Kakwani and Anoop Kunchukuttan and Satish Golla and Gokul N.C. and Avik Bhattacharyya and Mitesh M. Khapra and Pratyush Kumar},
|
||||
year={2020},
|
||||
booktitle={Findings of EMNLP},
|
||||
}
|
||||
```
|
||||
|
||||
We would like to hear from you if:
|
||||
|
||||
- You are using our resources. Please let us know how you are putting these resources to use.
|
||||
- You have any feedback on these resources.
|
||||
|
||||
|
||||
|
||||
## License
|
||||
|
||||
The IndicBERT code (and models) are released under the MIT License.
|
||||
|
||||
## Contributors
|
||||
|
||||
- Divyanshu Kakwani
|
||||
- Anoop Kunchukuttan
|
||||
- Gokul NC
|
||||
- Satish Golla
|
||||
- Avik Bhattacharyya
|
||||
- Mitesh Khapra
|
||||
- Pratyush Kumar
|
||||
|
||||
This work is the outcome of a volunteer effort as part of [AI4Bharat initiative](https://ai4bharat.org).
|
||||
|
||||
|
||||
|
||||
## Contact
|
||||
|
||||
- Anoop Kunchukuttan ([anoop.kunchukuttan@gmail.com](mailto:anoop.kunchukuttan@gmail.com))
|
||||
- Mitesh Khapra ([miteshk@cse.iitm.ac.in](mailto:miteshk@cse.iitm.ac.in))
|
||||
- Pratyush Kumar ([pratyush@cse.iitm.ac.in](mailto:pratyush@cse.iitm.ac.in))
|
||||
@@ -0,0 +1,80 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
tags:
|
||||
- bert
|
||||
- bluebert
|
||||
license:
|
||||
- PUBLIC DOMAIN NOTICE
|
||||
datasets:
|
||||
- PubMed
|
||||
- MIMIC-III
|
||||
|
||||
---
|
||||
|
||||
# BlueBert-Base, Uncased, PubMed and MIMIC-III
|
||||
|
||||
## Model description
|
||||
|
||||
A BERT model pre-trained on PubMed abstracts and clinical notes ([MIMIC-III](https://mimic.physionet.org/)).
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
#### How to use
|
||||
|
||||
Please see https://github.com/ncbi-nlp/bluebert
|
||||
|
||||
## Training data
|
||||
|
||||
We provide [preprocessed PubMed texts](https://ftp.ncbi.nlm.nih.gov/pub/lu/Suppl/NCBI-BERT/pubmed_uncased_sentence_nltk.txt.tar.gz) that were used to pre-train the BlueBERT models.
|
||||
The corpus contains ~4000M words extracted from the [PubMed ASCII code version](https://www.ncbi.nlm.nih.gov/research/bionlp/APIs/BioC-PubMed/).
|
||||
|
||||
Pre-trained model: https://huggingface.co/bert-large-uncased
|
||||
|
||||
## Training procedure
|
||||
|
||||
* lowercasing the text
|
||||
* removing speical chars `\x00`-`\x7F`
|
||||
* tokenizing the text using the [NLTK Treebank tokenizer](https://www.nltk.org/_modules/nltk/tokenize/treebank.html)
|
||||
|
||||
Below is a code snippet for more details.
|
||||
|
||||
```python
|
||||
value = value.lower()
|
||||
value = re.sub(r'[\r\n]+', ' ', value)
|
||||
value = re.sub(r'[^\x00-\x7F]+', ' ', value)
|
||||
|
||||
tokenized = TreebankWordTokenizer().tokenize(value)
|
||||
sentence = ' '.join(tokenized)
|
||||
sentence = re.sub(r"\s's\b", "'s", sentence)
|
||||
```
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@InProceedings{peng2019transfer,
|
||||
author = {Yifan Peng and Shankai Yan and Zhiyong Lu},
|
||||
title = {Transfer Learning in Biomedical Natural Language Processing: An Evaluation of BERT and ELMo on Ten Benchmarking Datasets},
|
||||
booktitle = {Proceedings of the 2019 Workshop on Biomedical Natural Language Processing (BioNLP 2019)},
|
||||
year = {2019},
|
||||
pages = {58--65},
|
||||
}
|
||||
```
|
||||
|
||||
### Acknowledgments
|
||||
|
||||
This work was supported by the Intramural Research Programs of the National Institutes of Health, National Library of
|
||||
Medicine and Clinical Center. This work was supported by the National Library of Medicine of the National Institutes of Health under award number 4R00LM013001-01.
|
||||
|
||||
We are also grateful to the authors of BERT and ELMo to make the data and codes publicly available.
|
||||
|
||||
We would like to thank Dr Sun Kim for processing the PubMed texts.
|
||||
|
||||
### Disclaimer
|
||||
|
||||
This tool shows the results of research conducted in the Computational Biology Branch, NCBI. The information produced
|
||||
on this website is not intended for direct diagnostic use or medical decision-making without review and oversight
|
||||
by a clinical professional. Individuals should not change their health behavior solely on the basis of information
|
||||
produced on this website. NIH does not independently verify the validity or utility of the information produced
|
||||
by this tool. If you have questions about the information produced on this website, please see a health care
|
||||
professional. More information about NCBI's disclaimer policy is available.
|
||||
@@ -0,0 +1,79 @@
|
||||
---
|
||||
language:
|
||||
- en
|
||||
tags:
|
||||
- bert
|
||||
- bluebert
|
||||
license:
|
||||
- PUBLIC DOMAIN NOTICE
|
||||
datasets:
|
||||
- PubMed
|
||||
|
||||
---
|
||||
|
||||
# BlueBert-Base, Uncased, PubMed
|
||||
|
||||
## Model description
|
||||
|
||||
A BERT model pre-trained on PubMed abstracts.
|
||||
|
||||
## Intended uses & limitations
|
||||
|
||||
#### How to use
|
||||
|
||||
Please see https://github.com/ncbi-nlp/bluebert
|
||||
|
||||
## Training data
|
||||
|
||||
We provide [preprocessed PubMed texts](https://ftp.ncbi.nlm.nih.gov/pub/lu/Suppl/NCBI-BERT/pubmed_uncased_sentence_nltk.txt.tar.gz) that were used to pre-train the BlueBERT models.
|
||||
The corpus contains ~4000M words extracted from the [PubMed ASCII code version](https://www.ncbi.nlm.nih.gov/research/bionlp/APIs/BioC-PubMed/).
|
||||
|
||||
Pre-trained model: https://huggingface.co/bert-large-uncased
|
||||
|
||||
## Training procedure
|
||||
|
||||
* lowercasing the text
|
||||
* removing speical chars `\x00`-`\x7F`
|
||||
* tokenizing the text using the [NLTK Treebank tokenizer](https://www.nltk.org/_modules/nltk/tokenize/treebank.html)
|
||||
|
||||
Below is a code snippet for more details.
|
||||
|
||||
```python
|
||||
value = value.lower()
|
||||
value = re.sub(r'[\r\n]+', ' ', value)
|
||||
value = re.sub(r'[^\x00-\x7F]+', ' ', value)
|
||||
|
||||
tokenized = TreebankWordTokenizer().tokenize(value)
|
||||
sentence = ' '.join(tokenized)
|
||||
sentence = re.sub(r"\s's\b", "'s", sentence)
|
||||
```
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```bibtex
|
||||
@InProceedings{peng2019transfer,
|
||||
author = {Yifan Peng and Shankai Yan and Zhiyong Lu},
|
||||
title = {Transfer Learning in Biomedical Natural Language Processing: An Evaluation of BERT and ELMo on Ten Benchmarking Datasets},
|
||||
booktitle = {Proceedings of the 2019 Workshop on Biomedical Natural Language Processing (BioNLP 2019)},
|
||||
year = {2019},
|
||||
pages = {58--65},
|
||||
}
|
||||
```
|
||||
|
||||
### Acknowledgments
|
||||
|
||||
This work was supported by the Intramural Research Programs of the National Institutes of Health, National Library of
|
||||
Medicine and Clinical Center. This work was supported by the National Library of Medicine of the National Institutes of Health under award number 4R00LM013001-01.
|
||||
|
||||
We are also grateful to the authors of BERT and ELMo to make the data and codes publicly available.
|
||||
|
||||
We would like to thank Dr Sun Kim for processing the PubMed texts.
|
||||
|
||||
### Disclaimer
|
||||
|
||||
This tool shows the results of research conducted in the Computational Biology Branch, NCBI. The information produced
|
||||
on this website is not intended for direct diagnostic use or medical decision-making without review and oversight
|
||||
by a clinical professional. Individuals should not change their health behavior solely on the basis of information
|
||||
produced on this website. NIH does not independently verify the validity or utility of the information produced
|
||||
by this tool. If you have questions about the information produced on this website, please see a health care
|
||||
professional. More information about NCBI's disclaimer policy is available.
|
||||
@@ -1,6 +1,12 @@
|
||||
## RuDR-BERT
|
||||
---
|
||||
language:
|
||||
- ru
|
||||
- en
|
||||
---
|
||||
|
||||
EnDR-BERT - Multilingual, Cased, which pretrained on the collecting of consumer comments on drug administration from [2]. Pre-training was based on the [original BERT code](https://github.com/google-research/bert) provided by Google. In particular, Multi-BERT was for used for initialization; vocabulary of Russian subtokens and parameters are the same as in Multi-BERT. Training details are described in our paper. \
|
||||
## EnDR-BERT
|
||||
|
||||
EnDR-BERT - Multilingual, Cased, which pretrained on the english collection of consumer comments on drug administration from [2]. Pre-training was based on the [original BERT code](https://github.com/google-research/bert) provided by Google. In particular, Multi-BERT was for used for initialization and all the parameters are the same as in Multi-BERT. Training details are described in our paper. \
|
||||
link: https://yadi.sk/d/-PTn0xhk1PqvgQ
|
||||
|
||||
|
||||
|
||||
@@ -9,8 +9,7 @@ tags:
|
||||
```python
|
||||
import json
|
||||
import os
|
||||
from transformers.configuration_roberta import RobertaConfig
|
||||
from transformers import RobertaForMaskedLM, TFRobertaForMaskedLM
|
||||
from transformers import RobertaConfig, RobertaForMaskedLM, TFRobertaForMaskedLM
|
||||
|
||||
DIRNAME = "./dummy-unknown"
|
||||
|
||||
|
||||
@@ -0,0 +1,74 @@
|
||||
---
|
||||
language: en
|
||||
datasets:
|
||||
- quartz
|
||||
pipeline_tag: question-answering
|
||||
---
|
||||
|
||||
# T5-base fine-tuned on QuaRTz
|
||||
|
||||
[Google's T5](https://ai.googleblog.com/2020/02/exploring-transfer-learning-with-t5.html) fine-tuned on [QuaRTz](https://allenai.org/data/quartz) for **QA** downstream task.
|
||||
|
||||
## Details of T5
|
||||
|
||||
The **T5** model was presented in [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/pdf/1910.10683.pdf) by *Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, Peter J. Liu* in Here the abstract:
|
||||
|
||||
Transfer learning, where a model is first pre-trained on a data-rich task before being fine-tuned on a downstream task, has emerged as a powerful technique in natural language processing (NLP). The effectiveness of transfer learning has given rise to a diversity of approaches, methodology, and practice. In this paper, we explore the landscape of transfer learning techniques for NLP by introducing a unified framework that converts every language problem into a text-to-text format. Our systematic study compares pre-training objectives, architectures, unlabeled datasets, transfer approaches, and other factors on dozens of language understanding tasks. By combining the insights from our exploration with scale and our new “Colossal Clean Crawled Corpus”, we achieve state-of-the-art results on many benchmarks covering summarization, question answering, text classification, and more. To facilitate future work on transfer learning for NLP, we release our dataset, pre-trained models, and code.
|
||||
|
||||

|
||||
|
||||
|
||||
## Details of the dataset 📚
|
||||
|
||||
**QuaRTz** is a crowdsourced dataset of 3864 multiple-choice questions about open domain qualitative relationships. Each question is paired with one of 405 different background sentences (sometimes short paragraphs). The QuaRTz dataset V1 contains 3864 questions about open domain qualitative relationships. Each question is paired with one of 405 different background sentences (sometimes short paragraphs).
|
||||
The dataset is split into:
|
||||
|
||||
|Set | Samples|
|
||||
|-----|--------|
|
||||
|Train | 2696 |
|
||||
|Valid | 384 |
|
||||
|Test | 784 |
|
||||
|
||||
## Model fine-tuning 🏋️
|
||||
|
||||
The training script is a slightly modified version of [this awesome one](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) by [Suraj Patil](https://twitter.com/psuraj28). The *question*, *context* (`para` field) and *options* (`choices` field) are concatenated and passed to the **encoder**. The **decoder** receives the right *answer* (by querying `answerKey` field). More details about the dataset fields/format [here](https://huggingface.co/nlp/viewer/?dataset=quartz)
|
||||
|
||||
## Results 📋
|
||||
|
||||
|
||||
|Set | Metric | Score |
|
||||
|-----|--------|-------|
|
||||
|Validation | Accuracy (EM) | **83.59**|
|
||||
|Test | Accuracy (EM) | **81.50**|
|
||||
|
||||
|
||||
## Model in Action 🚀
|
||||
|
||||
```python
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("mrm8488/t5-base-finetuned-quartz")
|
||||
model = AutoModelWithLMHead.from_pretrained("mrm8488/t5-base-finetuned-quartz")
|
||||
|
||||
def get_response(question, fact, opts, max_length=16):
|
||||
input_text = 'question: %s context: %s options: %s' % (question, fact, opts)
|
||||
features = tokenizer([input_text], return_tensors='pt')
|
||||
|
||||
output = model.generate(input_ids=features['input_ids'],
|
||||
attention_mask=features['attention_mask'],
|
||||
max_length=max_length)
|
||||
|
||||
return tokenizer.decode(output[0])
|
||||
|
||||
fact = 'The sooner cancer is detected the easier it is to treat.'
|
||||
question = 'John was a doctor in a cancer ward and knew that early detection was key. The cancer being detected quickly makes the cancer treatment'
|
||||
opts = 'Easier, Harder'
|
||||
|
||||
get_response(question, fact, opts)
|
||||
|
||||
# output: 'Easier'
|
||||
```
|
||||
|
||||
> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488) | [LinkedIn](https://www.linkedin.com/in/manuel-romero-cs/)
|
||||
|
||||
> Made with <span style="color: #e25555;">♥</span> in Spain
|
||||
@@ -51,13 +51,13 @@ The training script is a slightly modified version of [this one](https://colab.r
|
||||
## Model in Action 🚀
|
||||
|
||||
```python
|
||||
from transformers import AutoModelWithLMHead, AutoTokenizer
|
||||
from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained("mrm8488/t5-base-finetuned-squadv2")
|
||||
model = AutoModelWithLMHead.from_pretrained("mrm8488/t5-base-finetuned-squadv2")
|
||||
model = AutoModelForSeq2SeqLM.from_pretrained("mrm8488/t5-base-finetuned-squadv2")
|
||||
|
||||
def get_answer(question, context):
|
||||
input_text = "question: %s context: %s </s>" % (question, context)
|
||||
input_text = "question: %s context: %s" % (question, context)
|
||||
features = tokenizer([input_text], return_tensors='pt')
|
||||
|
||||
output = model.generate(input_ids=features['input_ids'],
|
||||
|
||||
@@ -2,6 +2,7 @@
|
||||
language: de
|
||||
tags:
|
||||
- exbert
|
||||
- German
|
||||
---
|
||||
|
||||
<a href="https://huggingface.co/exbert/?model=smanjil/German-MedBERT">
|
||||
@@ -10,7 +11,7 @@ tags:
|
||||
|
||||
# German Medical BERT
|
||||
|
||||
This is a fine-tuned model on Medical domain for German language and based on German BERT.
|
||||
This is a fine-tuned model on Medical domain for German language and based on German BERT. This model has only been trained to improve on target task (Masked Language Model). It can later be used to perform a downstream task of your needs, while I performed it for NTS-ICD-10 text classification task.
|
||||
|
||||
## Overview
|
||||
**Language model:** bert-base-german-cased
|
||||
@@ -30,7 +31,12 @@ This is a fine-tuned model on Medical domain for German language and based on Ge
|
||||
- Although had to train for upto 25 epochs for classification.
|
||||
|
||||
## Performance (Micro precision, recall and f1 score for multilabel code classification)
|
||||
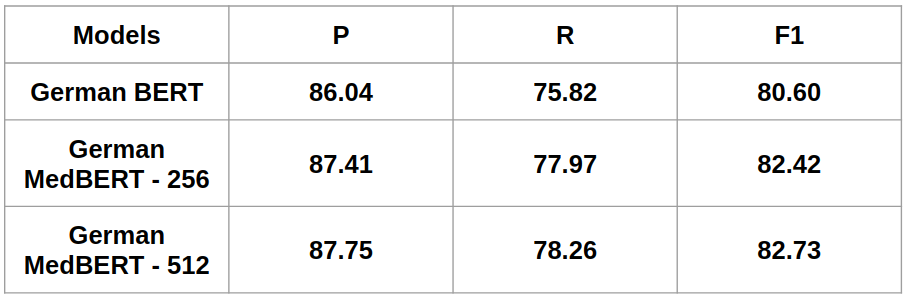
|
||||
|
||||
|Models |P |R |F1 |
|
||||
|:-------------- |:------|:------|:------|
|
||||
|German BERT |86.04 |75.82 |80.60 |
|
||||
|German MedBERT-256 |87.41 |77.97 |82.42 |
|
||||
|German MedBERT-512 |87.75 |78.26 |82.73 |
|
||||
|
||||
## Author
|
||||
Manjil Shrestha: `shresthamanjil21 [at] gmail.com`
|
||||
|
||||
@@ -0,0 +1,85 @@
|
||||
---
|
||||
language: zh
|
||||
widget:
|
||||
- text: "[CLS]国 色 天 香 , 姹 紫 嫣 红 , 碧 水 青 云 欣 共 赏 -"
|
||||
|
||||
|
||||
---
|
||||
|
||||
# Chinese Couplet GPT2 Model
|
||||
|
||||
## Model description
|
||||
|
||||
The model is used to generate Chinese couplets. You can download the model either from the [GPT2-Chinese Github page](https://github.com/Morizeyao/GPT2-Chinese), or via HuggingFace from the link [gpt2-chinese-couplet][couplet].
|
||||
|
||||
Since the parameter skip_special_tokens is used in the pipelines.py, special tokens such as [SEP], [UNK] will be deleted, and the output results may not be neat.
|
||||
|
||||
## How to use
|
||||
|
||||
You can use the model directly with a pipeline for text generation:
|
||||
|
||||
When the parameter skip_special_tokens is True:
|
||||
|
||||
```python
|
||||
>>> from transformers import BertTokenizer, GPT2LMHeadModel, TextGenerationPipeline
|
||||
>>> from transformers import TextGenerationPipeline,
|
||||
>>> tokenizer = BertTokenizer.from_pretrained("uer/gpt2-chinese-couplet")
|
||||
>>> model = GPT2LMHeadModel.from_pretrained("uer/gpt2-chinese-couplet")
|
||||
>>> text_generator = TextGenerationPipeline(model, tokenizer)
|
||||
>>> text_generator("[CLS]丹 枫 江 冷 人 初 去 -", max_length=25, do_sample=True)
|
||||
[{'generated_text': '[CLS]丹 枫 江 冷 人 初 去 - 黄 叶 声 从 天 外 来 阅 旗'}]
|
||||
```
|
||||
|
||||
When the parameter skip_special_tokens is False:
|
||||
|
||||
```python
|
||||
>>> from transformers import BertTokenizer, GPT2LMHeadModel, TextGenerationPipeline
|
||||
>>> from transformers import TextGenerationPipeline,
|
||||
>>> tokenizer = BertTokenizer.from_pretrained("uer/gpt2-chinese-poem")
|
||||
>>> model = GPT2LMHeadModel.from_pretrained("uer/gpt2-chinese-poem")
|
||||
>>> text_generator = TextGenerationPipeline(model, tokenizer)
|
||||
>>> text_generator("[CLS]丹 枫 江 冷 人 初 去 -", max_length=25, do_sample=True)
|
||||
[{'generated_text': '[CLS]丹 枫 江 冷 人 初 去 - 黄 叶 声 我 酒 不 辞 [SEP] [SEP] [SEP] [SEP] [SEP] [SEP] [SEP] [SEP] [SEP]'}]
|
||||
```
|
||||
|
||||
## Training data
|
||||
|
||||
Contains 700,000 Chinese couplets collected by [couplet-clean-dataset](https://github.com/v-zich/couplet-clean-dataset).
|
||||
|
||||
## Training procedure
|
||||
|
||||
Models are pre-trained by [UER-py](https://github.com/dbiir/UER-py/) on [Tencent Cloud TI-ONE](https://cloud.tencent.com/product/tione/). We pre-train 25,000 steps with a sequence length of 64.
|
||||
|
||||
```
|
||||
python3 preprocess.py --corpus_path corpora/couplet.txt \
|
||||
--vocab_path models/google_zh_vocab.txt \
|
||||
--dataset_path couplet.pt --processes_num 16 \
|
||||
--seq_length 64 --target lm
|
||||
```
|
||||
|
||||
```
|
||||
python3 pretrain.py --dataset_path couplet.pt \
|
||||
--vocab_path models/google_zh_vocab.txt \
|
||||
--output_model_path models/couplet_gpt_base_model.bin \
|
||||
--config_path models/bert_base_config.json --learning_rate 5e-4 \
|
||||
--tie_weight --world_size 8 --gpu_ranks 0 1 2 3 4 5 6 7 \
|
||||
--batch_size 64 --report_steps 1000 \
|
||||
--save_checkpoint_steps 5000 --total_steps 25000 \
|
||||
--embedding gpt --encoder gpt2 --target lm
|
||||
|
||||
```
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```
|
||||
@article{zhao2019uer,
|
||||
title={UER: An Open-Source Toolkit for Pre-training Models},
|
||||
author={Zhao, Zhe and Chen, Hui and Zhang, Jinbin and Zhao, Xin and Liu, Tao and Lu, Wei and Chen, Xi and Deng, Haotang and Ju, Qi and Du, Xiaoyong},
|
||||
journal={EMNLP-IJCNLP 2019},
|
||||
pages={241},
|
||||
year={2019}
|
||||
}
|
||||
```
|
||||
|
||||
[couplet]: https://huggingface.co/uer/gpt2-chinese-couplet
|
||||
|
||||
@@ -0,0 +1,85 @@
|
||||
---
|
||||
language: zh
|
||||
widget:
|
||||
- text: "[CLS] 万 叠 春 山 积 雨 晴 ,"
|
||||
- text: "[CLS] 青 山 削 芙 蓉 ,"
|
||||
|
||||
|
||||
---
|
||||
|
||||
# Chinese Poem GPT2 Model
|
||||
|
||||
## Model description
|
||||
|
||||
The model is used to generate Chinese ancient poems. You can download the model either from the [GPT2-Chinese Github page](https://github.com/Morizeyao/GPT2-Chinese), or via HuggingFace from the link [gpt2-chinese-poem][poem].
|
||||
|
||||
Since the parameter skip_special_tokens is used in the pipelines.py, special tokens such as [SEP], [UNK] will be deleted, and the output results may not be neat.
|
||||
|
||||
## How to use
|
||||
|
||||
You can use the model directly with a pipeline for text generation:
|
||||
|
||||
When the parameter skip_special_tokens is True:
|
||||
|
||||
```python
|
||||
>>> from transformers import BertTokenizer, GPT2LMHeadModel, TextGenerationPipeline
|
||||
>>> from transformers import TextGenerationPipeline,
|
||||
>>> tokenizer = BertTokenizer.from_pretrained("uer/gpt2-chinese-poem")
|
||||
>>> model = GPT2LMHeadModel.from_pretrained("uer/gpt2-chinese-poem")
|
||||
>>> text_generator = TextGenerationPipeline(model, tokenizer)
|
||||
>>> text_generator("[CLS]梅 山 如 积 翠 ,", max_length=50, do_sample=True)
|
||||
[{'generated_text': '[CLS]梅 山 如 积 翠 , 的 手 堪 捧 。 遥 遥 仙 人 尉 , 盘 盘 故 时 陇 。 丹 泉 清 可 鉴 , 石 乳 甘 于 。 行 将 解 尘 缨 , 于 焉 蹈 高 踵 。 我'}]
|
||||
```
|
||||
|
||||
When the parameter skip_special_tokens is False:
|
||||
|
||||
```python
|
||||
>>> from transformers import BertTokenizer, GPT2LMHeadModel, TextGenerationPipeline
|
||||
>>> from transformers import TextGenerationPipeline,
|
||||
>>> tokenizer = BertTokenizer.from_pretrained("uer/gpt2-chinese-poem")
|
||||
>>> model = GPT2LMHeadModel.from_pretrained("uer/gpt2-chinese-poem")
|
||||
>>> text_generator = TextGenerationPipeline(model, tokenizer)
|
||||
>>> text_generator("[CLS]梅 山 如 积 翠 ,", max_length=50, do_sample=True)
|
||||
[{'generated_text': '[CLS]梅 山 如 积 翠 , 的 [UNK] 手 堪 捧 。 遥 遥 仙 人 尉 , 盘 盘 故 时 陇 。 丹 泉 清 可 鉴 , 石 乳 甘 可 捧 。 银 汉 迟 不 来 , 槎 头 欲 谁 揽 。 何'}]
|
||||
```
|
||||
|
||||
## Training data
|
||||
|
||||
Contains 800,000 Chinese ancient poems collected by [chinese-poetry](https://github.com/chinese-poetry/chinese-poetry) and [Poetry](https://github.com/Werneror/Poetry) projects.
|
||||
|
||||
## Training procedure
|
||||
|
||||
The model is pre-trained by [UER-py](https://github.com/dbiir/UER-py/) on [Tencent Cloud TI-ONE](https://cloud.tencent.com/product/tione/). We pre-train 200,000 steps with a sequence length of 128.
|
||||
|
||||
```
|
||||
python3 preprocess.py --corpus_path corpora/poem.txt \
|
||||
--vocab_path models/google_zh_vocab.txt \
|
||||
--dataset_path poem.pt --processes_num 16 \
|
||||
--seq_length 128 --target lm
|
||||
```
|
||||
|
||||
```
|
||||
python3 pretrain.py --dataset_path poem.pt \
|
||||
--vocab_path models/google_zh_vocab.txt \
|
||||
--output_model_path models/poem_gpt_base_model.bin \
|
||||
--config_path models/bert_base_config.json --learning_rate 5e-4 \
|
||||
--tie_weight --world_size 8 --gpu_ranks 0 1 2 3 4 5 6 7 \
|
||||
--batch_size 64 --report_steps 1000 \
|
||||
--save_checkpoint_steps 50000 --total_steps 200000 \
|
||||
--embedding gpt --encoder gpt2 --target lm
|
||||
|
||||
```
|
||||
|
||||
### BibTeX entry and citation info
|
||||
|
||||
```
|
||||
@article{zhao2019uer,
|
||||
title={UER: An Open-Source Toolkit for Pre-training Models},
|
||||
author={Zhao, Zhe and Chen, Hui and Zhang, Jinbin and Zhao, Xin and Liu, Tao and Lu, Wei and Chen, Xi and Deng, Haotang and Ju, Qi and Du, Xiaoyong},
|
||||
journal={EMNLP-IJCNLP 2019},
|
||||
pages={241},
|
||||
year={2019}
|
||||
}
|
||||
```
|
||||
|
||||
[poem]: https://huggingface.co/uer/gpt2-chinese-poem
|
||||
@@ -119,7 +119,7 @@ extras["dev"] = extras["all"] + extras["testing"] + extras["quality"] + extras["
|
||||
|
||||
setup(
|
||||
name="transformers",
|
||||
version="4.0.0-dev",
|
||||
version="4.0.0-rc-1",
|
||||
author="Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Sam Shleifer, Patrick von Platen, Sylvain Gugger, Google AI Language Team Authors, Open AI team Authors, Facebook AI Authors, Carnegie Mellon University Authors",
|
||||
author_email="thomas@huggingface.co",
|
||||
description="State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch",
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# There's no way to ignore "F401 '...' imported but unused" warnings in this
|
||||
# module, but to preserve other warnings. So, don't check this module at all.
|
||||
|
||||
__version__ = "4.0.0-dev"
|
||||
__version__ = "4.0.0-rc-1"
|
||||
|
||||
# Work around to update TensorFlow's absl.logging threshold which alters the
|
||||
# default Python logging output behavior when present.
|
||||
@@ -766,7 +766,10 @@ if is_tf_available():
|
||||
from .models.longformer import (
|
||||
TF_LONGFORMER_PRETRAINED_MODEL_ARCHIVE_LIST,
|
||||
TFLongformerForMaskedLM,
|
||||
TFLongformerForMultipleChoice,
|
||||
TFLongformerForQuestionAnswering,
|
||||
TFLongformerForSequenceClassification,
|
||||
TFLongformerForTokenClassification,
|
||||
TFLongformerModel,
|
||||
TFLongformerSelfAttention,
|
||||
)
|
||||
|
||||
@@ -43,6 +43,8 @@ class PretrainedConfig(object):
|
||||
- **is_composition** (:obj:`bool`): Whether the config class is composed of multiple sub-configs. In this case
|
||||
the config has to be initialized from two or more configs of type :class:`~transformers.PretrainedConfig`
|
||||
like: :class:`~transformers.EncoderDecoderConfig` or :class:`~RagConfig`.
|
||||
- **keys_to_ignore_at_inference** (:obj:`List[str]`): A list of keys to ignore by default when looking at
|
||||
dictionary outputs of the model during inference.
|
||||
|
||||
Args:
|
||||
name_or_path (:obj:`str`, `optional`, defaults to :obj:`""`):
|
||||
|
||||
@@ -92,7 +92,10 @@ from ..funnel.modeling_tf_funnel import (
|
||||
from ..gpt2.modeling_tf_gpt2 import TFGPT2LMHeadModel, TFGPT2Model
|
||||
from ..longformer.modeling_tf_longformer import (
|
||||
TFLongformerForMaskedLM,
|
||||
TFLongformerForMultipleChoice,
|
||||
TFLongformerForQuestionAnswering,
|
||||
TFLongformerForSequenceClassification,
|
||||
TFLongformerForTokenClassification,
|
||||
TFLongformerModel,
|
||||
)
|
||||
from ..lxmert.modeling_tf_lxmert import TFLxmertForPreTraining, TFLxmertModel
|
||||
@@ -314,6 +317,7 @@ TF_MODEL_FOR_SEQUENCE_CLASSIFICATION_MAPPING = OrderedDict(
|
||||
(AlbertConfig, TFAlbertForSequenceClassification),
|
||||
(CamembertConfig, TFCamembertForSequenceClassification),
|
||||
(XLMRobertaConfig, TFXLMRobertaForSequenceClassification),
|
||||
(LongformerConfig, TFLongformerForSequenceClassification),
|
||||
(RobertaConfig, TFRobertaForSequenceClassification),
|
||||
(BertConfig, TFBertForSequenceClassification),
|
||||
(XLNetConfig, TFXLNetForSequenceClassification),
|
||||
@@ -353,6 +357,7 @@ TF_MODEL_FOR_TOKEN_CLASSIFICATION_MAPPING = OrderedDict(
|
||||
(FlaubertConfig, TFFlaubertForTokenClassification),
|
||||
(XLMConfig, TFXLMForTokenClassification),
|
||||
(XLMRobertaConfig, TFXLMRobertaForTokenClassification),
|
||||
(LongformerConfig, TFLongformerForTokenClassification),
|
||||
(RobertaConfig, TFRobertaForTokenClassification),
|
||||
(BertConfig, TFBertForTokenClassification),
|
||||
(MobileBertConfig, TFMobileBertForTokenClassification),
|
||||
@@ -368,6 +373,7 @@ TF_MODEL_FOR_MULTIPLE_CHOICE_MAPPING = OrderedDict(
|
||||
(CamembertConfig, TFCamembertForMultipleChoice),
|
||||
(XLMConfig, TFXLMForMultipleChoice),
|
||||
(XLMRobertaConfig, TFXLMRobertaForMultipleChoice),
|
||||
(LongformerConfig, TFLongformerForMultipleChoice),
|
||||
(RobertaConfig, TFRobertaForMultipleChoice),
|
||||
(BertConfig, TFBertForMultipleChoice),
|
||||
(DistilBertConfig, TFDistilBertForMultipleChoice),
|
||||
|
||||
@@ -110,6 +110,7 @@ class BartConfig(PretrainedConfig):
|
||||
:obj:`True` for `bart-large-cnn`.
|
||||
"""
|
||||
model_type = "bart"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -77,6 +77,7 @@ class CTRLConfig(PretrainedConfig):
|
||||
"""
|
||||
|
||||
model_type = "ctrl"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -82,7 +82,7 @@ class TFDPRContextEncoderOutput(ModelOutput):
|
||||
heads.
|
||||
"""
|
||||
|
||||
pooler_output: tf.Tensor
|
||||
pooler_output: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
@@ -110,7 +110,7 @@ class TFDPRQuestionEncoderOutput(ModelOutput):
|
||||
heads.
|
||||
"""
|
||||
|
||||
pooler_output: tf.Tensor
|
||||
pooler_output: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
@@ -141,7 +141,7 @@ class TFDPRReaderOutput(ModelOutput):
|
||||
heads.
|
||||
"""
|
||||
|
||||
start_logits: tf.Tensor
|
||||
start_logits: tf.Tensor = None
|
||||
end_logits: tf.Tensor = None
|
||||
relevance_logits: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
@@ -181,7 +181,7 @@ class TFDPREncoder(TFPreTrainedModel):
|
||||
return_dict = return_dict if return_dict is not None else self.bert_model.return_dict
|
||||
|
||||
outputs = self.bert_model(
|
||||
inputs=input_ids,
|
||||
input_ids,
|
||||
attention_mask=attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
inputs_embeds=inputs_embeds,
|
||||
@@ -228,7 +228,8 @@ class TFDPRSpanPredictor(TFPreTrainedModel):
|
||||
def call(
|
||||
self,
|
||||
input_ids: Tensor,
|
||||
attention_mask: Tensor,
|
||||
attention_mask: Optional[Tensor] = None,
|
||||
token_type_ids: Optional[Tensor] = None,
|
||||
inputs_embeds: Optional[Tensor] = None,
|
||||
output_attentions: bool = False,
|
||||
output_hidden_states: bool = False,
|
||||
@@ -242,6 +243,7 @@ class TFDPRSpanPredictor(TFPreTrainedModel):
|
||||
outputs = self.encoder(
|
||||
input_ids,
|
||||
attention_mask=attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
inputs_embeds=inputs_embeds,
|
||||
output_attentions=output_attentions,
|
||||
output_hidden_states=output_hidden_states,
|
||||
@@ -474,19 +476,21 @@ class TFDPRContextEncoder(TFDPRPretrainedContextEncoder):
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
inputs_embeds = inputs[2] if len(inputs) > 2 else inputs_embeds
|
||||
output_attentions = inputs[3] if len(inputs) > 3 else output_attentions
|
||||
output_hidden_states = inputs[4] if len(inputs) > 4 else output_hidden_states
|
||||
return_dict = inputs[5] if len(inputs) > 5 else return_dict
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
inputs_embeds = inputs[3] if len(inputs) > 3 else inputs_embeds
|
||||
output_attentions = inputs[4] if len(inputs) > 4 else output_attentions
|
||||
output_hidden_states = inputs[5] if len(inputs) > 5 else output_hidden_states
|
||||
return_dict = inputs[6] if len(inputs) > 6 else return_dict
|
||||
assert len(inputs) <= 7, "Too many inputs."
|
||||
elif isinstance(inputs, (dict, BatchEncoding)):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
output_attentions = inputs.get("output_attentions", output_attentions)
|
||||
output_hidden_states = inputs.get("output_hidden_states", output_hidden_states)
|
||||
return_dict = inputs.get("return_dict", return_dict)
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
assert len(inputs) <= 7, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
@@ -573,19 +577,21 @@ class TFDPRQuestionEncoder(TFDPRPretrainedQuestionEncoder):
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
inputs_embeds = inputs[2] if len(inputs) > 2 else inputs_embeds
|
||||
output_attentions = inputs[3] if len(inputs) > 3 else output_attentions
|
||||
output_hidden_states = inputs[4] if len(inputs) > 4 else output_hidden_states
|
||||
return_dict = inputs[5] if len(inputs) > 5 else return_dict
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
inputs_embeds = inputs[3] if len(inputs) > 3 else inputs_embeds
|
||||
output_attentions = inputs[4] if len(inputs) > 4 else output_attentions
|
||||
output_hidden_states = inputs[5] if len(inputs) > 5 else output_hidden_states
|
||||
return_dict = inputs[6] if len(inputs) > 6 else return_dict
|
||||
assert len(inputs) <= 7, "Too many inputs."
|
||||
elif isinstance(inputs, (dict, BatchEncoding)):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
output_attentions = inputs.get("output_attentions", output_attentions)
|
||||
output_hidden_states = inputs.get("output_hidden_states", output_hidden_states)
|
||||
return_dict = inputs.get("return_dict", return_dict)
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
assert len(inputs) <= 7, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
@@ -650,6 +656,7 @@ class TFDPRReader(TFDPRPretrainedReader):
|
||||
self,
|
||||
inputs,
|
||||
attention_mask: Optional[Tensor] = None,
|
||||
token_type_ids: Optional[Tensor] = None,
|
||||
inputs_embeds: Optional[Tensor] = None,
|
||||
output_attentions: bool = None,
|
||||
output_hidden_states: bool = None,
|
||||
@@ -679,19 +686,21 @@ class TFDPRReader(TFDPRPretrainedReader):
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
inputs_embeds = inputs[2] if len(inputs) > 2 else inputs_embeds
|
||||
output_attentions = inputs[3] if len(inputs) > 3 else output_attentions
|
||||
output_hidden_states = inputs[4] if len(inputs) > 4 else output_hidden_states
|
||||
return_dict = inputs[5] if len(inputs) > 5 else return_dict
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
inputs_embeds = inputs[3] if len(inputs) > 3 else inputs_embeds
|
||||
output_attentions = inputs[4] if len(inputs) > 4 else output_attentions
|
||||
output_hidden_states = inputs[5] if len(inputs) > 5 else output_hidden_states
|
||||
return_dict = inputs[6] if len(inputs) > 6 else return_dict
|
||||
assert len(inputs) <= 7, "Too many inputs."
|
||||
elif isinstance(inputs, (dict, BatchEncoding)):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
output_attentions = inputs.get("output_attentions", output_attentions)
|
||||
output_hidden_states = inputs.get("output_hidden_states", output_hidden_states)
|
||||
return_dict = inputs.get("return_dict", return_dict)
|
||||
assert len(inputs) <= 6, "Too many inputs."
|
||||
assert len(inputs) <= 7, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
@@ -713,9 +722,13 @@ class TFDPRReader(TFDPRPretrainedReader):
|
||||
if attention_mask is None:
|
||||
attention_mask = tf.ones(input_shape, dtype=tf.dtypes.int32)
|
||||
|
||||
if token_type_ids is None:
|
||||
token_type_ids = tf.zeros(input_shape, dtype=tf.dtypes.int32)
|
||||
|
||||
return self.span_predictor(
|
||||
input_ids,
|
||||
attention_mask,
|
||||
attention_mask=attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
inputs_embeds=inputs_embeds,
|
||||
output_attentions=output_attentions,
|
||||
output_hidden_states=output_hidden_states,
|
||||
|
||||
@@ -120,6 +120,7 @@ class GPT2Config(PretrainedConfig):
|
||||
"""
|
||||
|
||||
model_type = "gpt2"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -26,7 +26,10 @@ if is_tf_available():
|
||||
from .modeling_tf_longformer import (
|
||||
TF_LONGFORMER_PRETRAINED_MODEL_ARCHIVE_LIST,
|
||||
TFLongformerForMaskedLM,
|
||||
TFLongformerForMultipleChoice,
|
||||
TFLongformerForQuestionAnswering,
|
||||
TFLongformerForSequenceClassification,
|
||||
TFLongformerForTokenClassification,
|
||||
TFLongformerModel,
|
||||
TFLongformerSelfAttention,
|
||||
)
|
||||
|
||||
@@ -31,7 +31,6 @@ from ...file_utils import (
|
||||
add_start_docstrings_to_model_forward,
|
||||
replace_return_docstrings,
|
||||
)
|
||||
from ...modeling_outputs import MaskedLMOutput, SequenceClassifierOutput, TokenClassifierOutput
|
||||
from ...modeling_utils import (
|
||||
PreTrainedModel,
|
||||
apply_chunking_to_forward,
|
||||
@@ -151,17 +150,15 @@ class LongformerBaseModelOutputWithPooling(ModelOutput):
|
||||
|
||||
|
||||
@dataclass
|
||||
class LongformerMultipleChoiceModelOutput(ModelOutput):
|
||||
class LongformerMaskedLMOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of multiple choice Longformer models.
|
||||
Base class for masked language models outputs.
|
||||
|
||||
Args:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification loss.
|
||||
logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_choices)`):
|
||||
`num_choices` is the second dimension of the input tensors. (see `input_ids` above).
|
||||
|
||||
Classification scores (before SoftMax).
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Masked language modeling (MLM) loss.
|
||||
logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`):
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
@@ -249,6 +246,149 @@ class LongformerQuestionAnsweringModelOutput(ModelOutput):
|
||||
global_attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class LongformerSequenceClassifierOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of sentence classification models.
|
||||
|
||||
Args:
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification (or regression if config.num_labels==1) loss.
|
||||
logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, config.num_labels)`):
|
||||
Classification (or regression if config.num_labels==1) scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape :obj:`(batch_size, num_heads,
|
||||
sequence_length, x + attention_window + 1)`, where ``x`` is the number of tokens with global attention
|
||||
mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape :obj:`(batch_size, num_heads,
|
||||
sequence_length, x)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[torch.FloatTensor] = None
|
||||
logits: torch.FloatTensor = None
|
||||
hidden_states: Optional[Tuple[torch.FloatTensor]] = None
|
||||
attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
global_attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class LongformerMultipleChoiceModelOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of multiple choice Longformer models.
|
||||
|
||||
Args:
|
||||
loss (:obj:`torch.FloatTensor` of shape `(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification loss.
|
||||
logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, num_choices)`):
|
||||
`num_choices` is the second dimension of the input tensors. (see `input_ids` above).
|
||||
|
||||
Classification scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape :obj:`(batch_size, num_heads,
|
||||
sequence_length, x + attention_window + 1)`, where ``x`` is the number of tokens with global attention
|
||||
mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape :obj:`(batch_size, num_heads,
|
||||
sequence_length, x)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[torch.FloatTensor] = None
|
||||
logits: torch.FloatTensor = None
|
||||
hidden_states: Optional[Tuple[torch.FloatTensor]] = None
|
||||
attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
global_attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class LongformerTokenClassifierOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of token classification models.
|
||||
|
||||
Args:
|
||||
loss (:obj:`torch.FloatTensor` of shape :obj:`(1,)`, `optional`, returned when ``labels`` is provided) :
|
||||
Classification loss.
|
||||
logits (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, config.num_labels)`):
|
||||
Classification scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for the output of the embeddings + one for the output of each layer)
|
||||
of shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape :obj:`(batch_size, num_heads,
|
||||
sequence_length, x + attention_window + 1)`, where ``x`` is the number of tokens with global attention
|
||||
mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(torch.FloatTensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`torch.FloatTensor` (one for each layer) of shape :obj:`(batch_size, num_heads,
|
||||
sequence_length, x)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[torch.FloatTensor] = None
|
||||
logits: torch.FloatTensor = None
|
||||
hidden_states: Optional[Tuple[torch.FloatTensor]] = None
|
||||
attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
global_attentions: Optional[Tuple[torch.FloatTensor]] = None
|
||||
|
||||
|
||||
def _get_question_end_index(input_ids, sep_token_id):
|
||||
"""
|
||||
Computes the index of the first occurance of `sep_token_id`.
|
||||
@@ -1495,7 +1635,7 @@ class LongformerForMaskedLM(LongformerPreTrainedModel):
|
||||
return self.lm_head.decoder
|
||||
|
||||
@add_start_docstrings_to_model_forward(LONGFORMER_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
|
||||
@replace_return_docstrings(output_type=MaskedLMOutput, config_class=_CONFIG_FOR_DOC)
|
||||
@replace_return_docstrings(output_type=LongformerMaskedLMOutput, config_class=_CONFIG_FOR_DOC)
|
||||
def forward(
|
||||
self,
|
||||
input_ids=None,
|
||||
@@ -1561,7 +1701,7 @@ class LongformerForMaskedLM(LongformerPreTrainedModel):
|
||||
output = (prediction_scores,) + outputs[2:]
|
||||
return ((masked_lm_loss,) + output) if masked_lm_loss is not None else output
|
||||
|
||||
return MaskedLMOutput(
|
||||
return LongformerMaskedLMOutput(
|
||||
loss=masked_lm_loss,
|
||||
logits=prediction_scores,
|
||||
hidden_states=outputs.hidden_states,
|
||||
@@ -1593,7 +1733,7 @@ class LongformerForSequenceClassification(LongformerPreTrainedModel):
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-base-4096",
|
||||
output_type=SequenceClassifierOutput,
|
||||
output_type=LongformerSequenceClassifierOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def forward(
|
||||
@@ -1651,7 +1791,7 @@ class LongformerForSequenceClassification(LongformerPreTrainedModel):
|
||||
output = (logits,) + outputs[2:]
|
||||
return ((loss,) + output) if loss is not None else output
|
||||
|
||||
return SequenceClassifierOutput(
|
||||
return LongformerSequenceClassifierOutput(
|
||||
loss=loss,
|
||||
logits=logits,
|
||||
hidden_states=outputs.hidden_states,
|
||||
@@ -1837,7 +1977,7 @@ class LongformerForTokenClassification(LongformerPreTrainedModel):
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-base-4096",
|
||||
output_type=TokenClassifierOutput,
|
||||
output_type=LongformerTokenClassifierOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def forward(
|
||||
@@ -1895,7 +2035,7 @@ class LongformerForTokenClassification(LongformerPreTrainedModel):
|
||||
output = (logits,) + outputs[2:]
|
||||
return ((loss,) + output) if loss is not None else output
|
||||
|
||||
return TokenClassifierOutput(
|
||||
return LongformerTokenClassifierOutput(
|
||||
loss=loss,
|
||||
logits=logits,
|
||||
hidden_states=outputs.hidden_states,
|
||||
|
||||
@@ -19,19 +19,21 @@ from typing import Optional, Tuple
|
||||
|
||||
import tensorflow as tf
|
||||
|
||||
from transformers.activations_tf import get_tf_activation
|
||||
|
||||
from ...activations_tf import get_tf_activation
|
||||
from ...file_utils import (
|
||||
MULTIPLE_CHOICE_DUMMY_INPUTS,
|
||||
ModelOutput,
|
||||
add_code_sample_docstrings,
|
||||
add_start_docstrings,
|
||||
add_start_docstrings_to_model_forward,
|
||||
)
|
||||
from ...modeling_tf_outputs import TFMaskedLMOutput, TFQuestionAnsweringModelOutput
|
||||
from ...modeling_tf_utils import (
|
||||
TFMaskedLanguageModelingLoss,
|
||||
TFMultipleChoiceLoss,
|
||||
TFPreTrainedModel,
|
||||
TFQuestionAnsweringLoss,
|
||||
TFSequenceClassificationLoss,
|
||||
TFTokenClassificationLoss,
|
||||
get_initializer,
|
||||
keras_serializable,
|
||||
shape_list,
|
||||
@@ -147,6 +149,52 @@ class TFLongformerBaseModelOutputWithPooling(ModelOutput):
|
||||
global_attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class TFLongformerMaskedLMOutput(ModelOutput):
|
||||
"""
|
||||
Base class for masked language models outputs.
|
||||
|
||||
Args:
|
||||
loss (:obj:`tf.Tensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Masked language modeling (MLM) loss.
|
||||
logits (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, config.vocab_size)`):
|
||||
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of
|
||||
shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x +
|
||||
attention_window + 1)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x)`,
|
||||
where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[tf.Tensor] = None
|
||||
logits: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
global_attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class TFLongformerQuestionAnsweringModelOutput(ModelOutput):
|
||||
"""
|
||||
@@ -196,6 +244,146 @@ class TFLongformerQuestionAnsweringModelOutput(ModelOutput):
|
||||
global_attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class TFLongformerSequenceClassifierOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of sentence classification models.
|
||||
|
||||
Args:
|
||||
loss (:obj:`tf.Tensor` of shape :obj:`(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification (or regression if config.num_labels==1) loss.
|
||||
logits (:obj:`tf.Tensor` of shape :obj:`(batch_size, config.num_labels)`):
|
||||
Classification (or regression if config.num_labels==1) scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of
|
||||
shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x +
|
||||
attention_window + 1)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x)`,
|
||||
where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[tf.Tensor] = None
|
||||
logits: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
global_attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class TFLongformerMultipleChoiceModelOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of multiple choice models.
|
||||
|
||||
Args:
|
||||
loss (:obj:`tf.Tensor` of shape `(1,)`, `optional`, returned when :obj:`labels` is provided):
|
||||
Classification loss.
|
||||
logits (:obj:`tf.Tensor` of shape :obj:`(batch_size, num_choices)`):
|
||||
`num_choices` is the second dimension of the input tensors. (see `input_ids` above).
|
||||
|
||||
Classification scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of
|
||||
shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x +
|
||||
attention_window + 1)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x)`,
|
||||
where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[tf.Tensor] = None
|
||||
logits: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
global_attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
|
||||
@dataclass
|
||||
class TFLongformerTokenClassifierOutput(ModelOutput):
|
||||
"""
|
||||
Base class for outputs of token classification models.
|
||||
|
||||
Args:
|
||||
loss (:obj:`tf.Tensor` of shape :obj:`(1,)`, `optional`, returned when ``labels`` is provided) :
|
||||
Classification loss.
|
||||
logits (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length, config.num_labels)`):
|
||||
Classification scores (before SoftMax).
|
||||
hidden_states (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_hidden_states=True`` is passed or when ``config.output_hidden_states=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for the output of the embeddings + one for the output of each layer) of
|
||||
shape :obj:`(batch_size, sequence_length, hidden_size)`.
|
||||
|
||||
Hidden-states of the model at the output of each layer plus the initial embedding outputs.
|
||||
attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x +
|
||||
attention_window + 1)`, where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Local attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token in the sequence to every token with
|
||||
global attention (first ``x`` values) and to every token in the attention window (remaining
|
||||
``attention_window + 1`` values). Note that the first ``x`` values refer to tokens with fixed positions in
|
||||
the text, but the remaining ``attention_window + 1`` values refer to tokens with relative positions: the
|
||||
attention weight of a token to itself is located at index ``x + attention_window / 2`` and the
|
||||
``attention_window / 2`` preceding (succeeding) values are the attention weights to the ``attention_window
|
||||
/ 2`` preceding (succeeding) tokens. If the attention window contains a token with global attention, the
|
||||
attention weight at the corresponding index is set to 0; the value should be accessed from the first ``x``
|
||||
attention weights. If a token has global attention, the attention weights to all other tokens in
|
||||
:obj:`attentions` is set to 0, the values should be accessed from :obj:`global_attentions`.
|
||||
global_attentions (:obj:`tuple(tf.Tensor)`, `optional`, returned when ``output_attentions=True`` is passed or when ``config.output_attentions=True``):
|
||||
Tuple of :obj:`tf.Tensor` (one for each layer) of shape :obj:`(batch_size, num_heads, sequence_length, x)`,
|
||||
where ``x`` is the number of tokens with global attention mask.
|
||||
|
||||
Global attentions weights after the attention softmax, used to compute the weighted average in the
|
||||
self-attention heads. Those are the attention weights from every token with global attention to every token
|
||||
in the sequence.
|
||||
"""
|
||||
|
||||
loss: Optional[tf.Tensor] = None
|
||||
logits: tf.Tensor = None
|
||||
hidden_states: Optional[Tuple[tf.Tensor]] = None
|
||||
attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
global_attentions: Optional[Tuple[tf.Tensor]] = None
|
||||
|
||||
|
||||
def _compute_global_attention_mask(input_ids_shape, sep_token_indices, before_sep_token=True):
|
||||
"""
|
||||
Computes global attention mask by putting attention on all tokens before `sep_token_id` if `before_sep_token is
|
||||
@@ -249,18 +437,17 @@ class TFLongformerLMHead(tf.keras.layers.Layer):
|
||||
|
||||
super().build(input_shape)
|
||||
|
||||
def call(self, features):
|
||||
x = self.dense(features)
|
||||
x = self.act(x)
|
||||
x = self.layer_norm(x)
|
||||
def call(self, hidden_states):
|
||||
hidden_states = self.dense(hidden_states)
|
||||
hidden_states = self.act(hidden_states)
|
||||
hidden_states = self.layer_norm(hidden_states)
|
||||
|
||||
# project back to size of vocabulary with bias
|
||||
x = self.decoder(x, mode="linear") + self.bias
|
||||
hidden_states = self.decoder(hidden_states, mode="linear") + self.bias
|
||||
|
||||
return x
|
||||
return hidden_states
|
||||
|
||||
|
||||
# Copied from transformers.models.roberta.modeling_tf_roberta.TFRobertaEmbeddings
|
||||
class TFLongformerEmbeddings(tf.keras.layers.Layer):
|
||||
"""
|
||||
Same as BertEmbeddings with a tiny tweak for positional embeddings indexing.
|
||||
@@ -304,17 +491,23 @@ class TFLongformerEmbeddings(tf.keras.layers.Layer):
|
||||
|
||||
super().build(input_shape)
|
||||
|
||||
def create_position_ids_from_input_ids(self, x):
|
||||
def create_position_ids_from_input_ids(self, input_ids):
|
||||
"""
|
||||
Replace non-padding symbols with their position numbers. Position numbers begin at padding_idx+1. Padding
|
||||
symbols are ignored. This is modified from fairseq's `utils.make_positions`.
|
||||
|
||||
Args:
|
||||
x: tf.Tensor
|
||||
input_ids: tf.Tensor
|
||||
|
||||
Returns: tf.Tensor
|
||||
"""
|
||||
mask = tf.cast(tf.math.not_equal(x, self.padding_idx), dtype=tf.int32)
|
||||
input_ids_shape = shape_list(input_ids)
|
||||
|
||||
# multiple choice has 3 dimensions
|
||||
if len(input_ids_shape) == 3:
|
||||
input_ids = tf.reshape(input_ids, (input_ids_shape[0] * input_ids_shape[1], input_ids_shape[2]))
|
||||
|
||||
mask = tf.cast(tf.math.not_equal(input_ids, self.padding_idx), dtype=tf.int32)
|
||||
incremental_indices = tf.math.cumsum(mask, axis=1) * mask
|
||||
|
||||
return incremental_indices + self.padding_idx
|
||||
@@ -1783,7 +1976,7 @@ class TFLongformerForMaskedLM(TFLongformerPreTrainedModel, TFMaskedLanguageModel
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-base-4096",
|
||||
output_type=TFMaskedLMOutput,
|
||||
output_type=TFLongformerMaskedLMOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def call(
|
||||
@@ -1837,11 +2030,12 @@ class TFLongformerForMaskedLM(TFLongformerPreTrainedModel, TFMaskedLanguageModel
|
||||
|
||||
return ((loss,) + output) if loss is not None else output
|
||||
|
||||
return TFMaskedLMOutput(
|
||||
return TFLongformerMaskedLMOutput(
|
||||
loss=loss,
|
||||
logits=prediction_scores,
|
||||
hidden_states=outputs.hidden_states,
|
||||
attentions=outputs.attentions,
|
||||
global_attentions=outputs.global_attentions,
|
||||
)
|
||||
|
||||
|
||||
@@ -1871,7 +2065,7 @@ class TFLongformerForQuestionAnswering(TFLongformerPreTrainedModel, TFQuestionAn
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-large-4096-finetuned-triviaqa",
|
||||
output_type=TFQuestionAnsweringModelOutput,
|
||||
output_type=TFLongformerQuestionAnsweringModelOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def call(
|
||||
@@ -1969,3 +2163,357 @@ class TFLongformerForQuestionAnswering(TFLongformerPreTrainedModel, TFQuestionAn
|
||||
attentions=outputs.attentions,
|
||||
global_attentions=outputs.global_attentions,
|
||||
)
|
||||
|
||||
|
||||
class TFLongformerClassificationHead(tf.keras.layers.Layer):
|
||||
"""Head for sentence-level classification tasks."""
|
||||
|
||||
def __init__(self, config, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.dense = tf.keras.layers.Dense(
|
||||
config.hidden_size,
|
||||
kernel_initializer=get_initializer(config.initializer_range),
|
||||
activation="tanh",
|
||||
name="dense",
|
||||
)
|
||||
self.dropout = tf.keras.layers.Dropout(config.hidden_dropout_prob)
|
||||
self.out_proj = tf.keras.layers.Dense(
|
||||
config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="out_proj"
|
||||
)
|
||||
|
||||
def call(self, hidden_states, training=False):
|
||||
hidden_states = hidden_states[:, 0, :] # take <s> token (equiv. to [CLS])
|
||||
hidden_states = self.dropout(hidden_states, training=training)
|
||||
hidden_states = self.dense(hidden_states)
|
||||
hidden_states = self.dropout(hidden_states, training=training)
|
||||
output = self.out_proj(hidden_states)
|
||||
return output
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""
|
||||
Longformer Model transformer with a sequence classification/regression head on top (a linear layer on top of the
|
||||
pooled output) e.g. for GLUE tasks.
|
||||
""",
|
||||
LONGFORMER_START_DOCSTRING,
|
||||
)
|
||||
class TFLongformerForSequenceClassification(TFLongformerPreTrainedModel, TFSequenceClassificationLoss):
|
||||
|
||||
authorized_missing_keys = [r"pooler"]
|
||||
|
||||
def __init__(self, config, *inputs, **kwargs):
|
||||
super().__init__(config, *inputs, **kwargs)
|
||||
|
||||
self.num_labels = config.num_labels
|
||||
|
||||
self.longformer = TFLongformerMainLayer(config, name="longformer")
|
||||
self.classifier = TFLongformerClassificationHead(config, name="classifier")
|
||||
|
||||
@add_start_docstrings_to_model_forward(LONGFORMER_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-base-4096",
|
||||
output_type=TFLongformerSequenceClassifierOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def call(
|
||||
self,
|
||||
inputs=None,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
global_attention_mask=None,
|
||||
inputs_embeds=None,
|
||||
output_attentions=None,
|
||||
output_hidden_states=None,
|
||||
return_dict=None,
|
||||
labels=None,
|
||||
training=False,
|
||||
):
|
||||
return_dict = return_dict if return_dict is not None else self.config.use_return_dict
|
||||
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
position_ids = inputs[3] if len(inputs) > 3 else position_ids
|
||||
global_attention_mask = inputs[4] if len(inputs) > 4 else global_attention_mask
|
||||
inputs_embeds = inputs[5] if len(inputs) > 5 else inputs_embeds
|
||||
output_attentions = inputs[6] if len(inputs) > 6 else output_attentions
|
||||
output_hidden_states = inputs[7] if len(inputs) > 7 else output_hidden_states
|
||||
return_dict = inputs[8] if len(inputs) > 8 else return_dict
|
||||
labels = inputs[9] if len(inputs) > 9 else labels
|
||||
assert len(inputs) <= 10, "Too many inputs."
|
||||
elif isinstance(inputs, (dict, BatchEncoding)):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
global_attention_mask = inputs.get("global_attention_mask", global_attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
position_ids = inputs.get("position_ids", position_ids)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
labels = inputs.get("labels", labels)
|
||||
output_attentions = inputs.get("output_attentions", output_attentions)
|
||||
output_hidden_states = inputs.get("output_hidden_states", output_hidden_states)
|
||||
return_dict = inputs.get("return_dict", return_dict)
|
||||
assert len(inputs) <= 10, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
if global_attention_mask is None and input_ids is not None:
|
||||
logger.info("Initializing global attention on CLS token...")
|
||||
# global attention on cls token
|
||||
global_attention_mask = tf.zeros_like(input_ids)
|
||||
global_attention_mask = tf.tensor_scatter_nd_update(
|
||||
global_attention_mask,
|
||||
[[i, 0] for i in range(input_ids.shape[0])],
|
||||
[1 for _ in range(input_ids.shape[0])],
|
||||
)
|
||||
|
||||
outputs = self.longformer(
|
||||
input_ids,
|
||||
attention_mask=attention_mask,
|
||||
global_attention_mask=global_attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
position_ids=position_ids,
|
||||
inputs_embeds=inputs_embeds,
|
||||
output_attentions=output_attentions,
|
||||
output_hidden_states=output_hidden_states,
|
||||
return_dict=return_dict,
|
||||
)
|
||||
sequence_output = outputs[0]
|
||||
logits = self.classifier(sequence_output)
|
||||
|
||||
loss = None if labels is None else self.compute_loss(labels, logits)
|
||||
|
||||
if not return_dict:
|
||||
output = (logits,) + outputs[2:]
|
||||
return ((loss,) + output) if loss is not None else output
|
||||
|
||||
return TFLongformerSequenceClassifierOutput(
|
||||
loss=loss,
|
||||
logits=logits,
|
||||
hidden_states=outputs.hidden_states,
|
||||
attentions=outputs.attentions,
|
||||
global_attentions=outputs.global_attentions,
|
||||
)
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""
|
||||
Longformer Model with a multiple choice classification head on top (a linear layer on top of the pooled output and
|
||||
a softmax) e.g. for RocStories/SWAG tasks.
|
||||
""",
|
||||
LONGFORMER_START_DOCSTRING,
|
||||
)
|
||||
class TFLongformerForMultipleChoice(TFLongformerPreTrainedModel, TFMultipleChoiceLoss):
|
||||
def __init__(self, config, *inputs, **kwargs):
|
||||
super().__init__(config, *inputs, **kwargs)
|
||||
|
||||
self.longformer = TFLongformerMainLayer(config, name="longformer")
|
||||
self.dropout = tf.keras.layers.Dropout(config.hidden_dropout_prob)
|
||||
self.classifier = tf.keras.layers.Dense(
|
||||
1, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
|
||||
)
|
||||
|
||||
@property
|
||||
def dummy_inputs(self):
|
||||
input_ids = tf.constant(MULTIPLE_CHOICE_DUMMY_INPUTS)
|
||||
# make sure global layers are initialized
|
||||
global_attention_mask = tf.constant([[[0, 0, 0, 1], [0, 0, 0, 1]]] * 2)
|
||||
return {"input_ids": input_ids, "global_attention_mask": global_attention_mask}
|
||||
|
||||
@add_start_docstrings_to_model_forward(
|
||||
LONGFORMER_INPUTS_DOCSTRING.format("batch_size, num_choices, sequence_length")
|
||||
)
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-base-4096",
|
||||
output_type=TFLongformerMultipleChoiceModelOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def call(
|
||||
self,
|
||||
inputs,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
global_attention_mask=None,
|
||||
inputs_embeds=None,
|
||||
output_attentions=None,
|
||||
output_hidden_states=None,
|
||||
return_dict=None,
|
||||
labels=None,
|
||||
training=False,
|
||||
):
|
||||
r"""
|
||||
labels (:obj:`tf.Tensor` of shape :obj:`(batch_size,)`, `optional`):
|
||||
Labels for computing the multiple choice classification loss. Indices should be in ``[0, ...,
|
||||
num_choices]`` where :obj:`num_choices` is the size of the second dimension of the input tensors. (See
|
||||
:obj:`input_ids` above)
|
||||
"""
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
input_ids = inputs[0]
|
||||
attention_mask = inputs[1] if len(inputs) > 1 else attention_mask
|
||||
token_type_ids = inputs[2] if len(inputs) > 2 else token_type_ids
|
||||
position_ids = inputs[3] if len(inputs) > 3 else position_ids
|
||||
global_attention_mask = inputs[4] if len(inputs) > 4 else global_attention_mask
|
||||
inputs_embeds = inputs[5] if len(inputs) > 5 else inputs_embeds
|
||||
output_attentions = inputs[6] if len(inputs) > 6 else output_attentions
|
||||
output_hidden_states = inputs[7] if len(inputs) > 7 else output_hidden_states
|
||||
return_dict = inputs[8] if len(inputs) > 8 else return_dict
|
||||
labels = inputs[9] if len(inputs) > 9 else labels
|
||||
assert len(inputs) <= 10, "Too many inputs."
|
||||
elif isinstance(inputs, (dict, BatchEncoding)):
|
||||
input_ids = inputs.get("input_ids")
|
||||
attention_mask = inputs.get("attention_mask", attention_mask)
|
||||
global_attention_mask = inputs.get("global_attention_mask", global_attention_mask)
|
||||
token_type_ids = inputs.get("token_type_ids", token_type_ids)
|
||||
position_ids = inputs.get("position_ids", position_ids)
|
||||
inputs_embeds = inputs.get("inputs_embeds", inputs_embeds)
|
||||
labels = inputs.get("labels", labels)
|
||||
output_attentions = inputs.get("output_attentions", output_attentions)
|
||||
output_hidden_states = inputs.get("output_hidden_states", output_hidden_states)
|
||||
return_dict = inputs.get("return_dict", return_dict)
|
||||
assert len(inputs) <= 10, "Too many inputs."
|
||||
else:
|
||||
input_ids = inputs
|
||||
|
||||
return_dict = return_dict if return_dict is not None else self.config.return_dict
|
||||
|
||||
if input_ids is not None:
|
||||
num_choices = shape_list(input_ids)[1]
|
||||
seq_length = shape_list(input_ids)[2]
|
||||
else:
|
||||
num_choices = shape_list(inputs_embeds)[1]
|
||||
seq_length = shape_list(inputs_embeds)[2]
|
||||
|
||||
flat_input_ids = tf.reshape(input_ids, (-1, seq_length)) if input_ids is not None else None
|
||||
flat_attention_mask = tf.reshape(attention_mask, (-1, seq_length)) if attention_mask is not None else None
|
||||
flat_token_type_ids = tf.reshape(token_type_ids, (-1, seq_length)) if token_type_ids is not None else None
|
||||
flat_position_ids = tf.reshape(position_ids, (-1, seq_length)) if position_ids is not None else None
|
||||
flat_global_attention_mask = (
|
||||
tf.reshape(global_attention_mask, (-1, global_attention_mask.shape[-1]))
|
||||
if global_attention_mask is not None
|
||||
else None
|
||||
)
|
||||
flat_inputs_embeds = (
|
||||
tf.reshape(inputs_embeds, (-1, seq_length, shape_list(inputs_embeds)[3]))
|
||||
if inputs_embeds is not None
|
||||
else None
|
||||
)
|
||||
|
||||
outputs = self.longformer(
|
||||
flat_input_ids,
|
||||
position_ids=flat_position_ids,
|
||||
token_type_ids=flat_token_type_ids,
|
||||
attention_mask=flat_attention_mask,
|
||||
global_attention_mask=flat_global_attention_mask,
|
||||
inputs_embeds=flat_inputs_embeds,
|
||||
output_attentions=output_attentions,
|
||||
output_hidden_states=output_hidden_states,
|
||||
return_dict=return_dict,
|
||||
)
|
||||
pooled_output = outputs[1]
|
||||
|
||||
pooled_output = self.dropout(pooled_output)
|
||||
logits = self.classifier(pooled_output)
|
||||
reshaped_logits = tf.reshape(logits, (-1, num_choices))
|
||||
|
||||
loss = None if labels is None else self.compute_loss(labels, reshaped_logits)
|
||||
|
||||
if not return_dict:
|
||||
output = (reshaped_logits,) + outputs[2:]
|
||||
return ((loss,) + output) if loss is not None else output
|
||||
|
||||
return TFLongformerMultipleChoiceModelOutput(
|
||||
loss=loss,
|
||||
logits=reshaped_logits,
|
||||
hidden_states=outputs.hidden_states,
|
||||
attentions=outputs.attentions,
|
||||
global_attentions=outputs.global_attentions,
|
||||
)
|
||||
|
||||
|
||||
@add_start_docstrings(
|
||||
"""
|
||||
Longformer Model with a token classification head on top (a linear layer on top of the hidden-states output) e.g.
|
||||
for Named-Entity-Recognition (NER) tasks.
|
||||
""",
|
||||
LONGFORMER_START_DOCSTRING,
|
||||
)
|
||||
class TFLongformerForTokenClassification(TFLongformerPreTrainedModel, TFTokenClassificationLoss):
|
||||
|
||||
authorized_missing_keys = [r"pooler"]
|
||||
|
||||
def __init__(self, config, *inputs, **kwargs):
|
||||
super().__init__(config, *inputs, **kwargs)
|
||||
|
||||
self.num_labels = config.num_labels
|
||||
self.longformer = TFLongformerMainLayer(config=config, name="longformer")
|
||||
self.dropout = tf.keras.layers.Dropout(config.hidden_dropout_prob)
|
||||
self.classifier = tf.keras.layers.Dense(
|
||||
config.num_labels, kernel_initializer=get_initializer(config.initializer_range), name="classifier"
|
||||
)
|
||||
|
||||
@add_start_docstrings_to_model_forward(LONGFORMER_INPUTS_DOCSTRING.format("batch_size, sequence_length"))
|
||||
@add_code_sample_docstrings(
|
||||
tokenizer_class=_TOKENIZER_FOR_DOC,
|
||||
checkpoint="allenai/longformer-base-4096",
|
||||
output_type=TFLongformerTokenClassifierOutput,
|
||||
config_class=_CONFIG_FOR_DOC,
|
||||
)
|
||||
def call(
|
||||
self,
|
||||
inputs=None,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
global_attention_mask=None,
|
||||
inputs_embeds=None,
|
||||
output_attentions=None,
|
||||
output_hidden_states=None,
|
||||
return_dict=None,
|
||||
labels=None,
|
||||
training=False,
|
||||
):
|
||||
r"""
|
||||
labels (:obj:`tf.Tensor` of shape :obj:`(batch_size, sequence_length)`, `optional`):
|
||||
Labels for computing the token classification loss. Indices should be in ``[0, ..., config.num_labels -
|
||||
1]``.
|
||||
"""
|
||||
return_dict = return_dict if return_dict is not None else self.config.return_dict
|
||||
|
||||
if isinstance(inputs, (tuple, list)):
|
||||
labels = inputs[9] if len(inputs) > 9 else labels
|
||||
if len(inputs) > 9:
|
||||
inputs = inputs[:9]
|
||||
elif isinstance(inputs, (dict, BatchEncoding)):
|
||||
labels = inputs.pop("labels", labels)
|
||||
|
||||
outputs = self.longformer(
|
||||
inputs,
|
||||
attention_mask=attention_mask,
|
||||
global_attention_mask=global_attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
position_ids=position_ids,
|
||||
inputs_embeds=inputs_embeds,
|
||||
output_attentions=output_attentions,
|
||||
output_hidden_states=output_hidden_states,
|
||||
return_dict=return_dict,
|
||||
)
|
||||
sequence_output = outputs[0]
|
||||
sequence_output = self.dropout(sequence_output)
|
||||
logits = self.classifier(sequence_output)
|
||||
loss = None if labels is None else self.compute_loss(labels, logits)
|
||||
|
||||
if not return_dict:
|
||||
output = (logits,) + outputs[2:]
|
||||
return ((loss,) + output) if loss is not None else output
|
||||
|
||||
return TFLongformerTokenClassifierOutput(
|
||||
loss=loss,
|
||||
logits=logits,
|
||||
hidden_states=outputs.hidden_states,
|
||||
attentions=outputs.attentions,
|
||||
global_attentions=outputs.global_attentions,
|
||||
)
|
||||
|
||||
@@ -97,3 +97,4 @@ class MarianConfig(BartConfig):
|
||||
"""
|
||||
|
||||
model_type = "marian"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
@@ -102,3 +102,4 @@ class MBartConfig(BartConfig):
|
||||
"""
|
||||
|
||||
model_type = "mbart"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
@@ -62,6 +62,7 @@ class MT5Config(PretrainedConfig):
|
||||
Type of feed forward layer to be used. Should be one of :obj:`"relu"` or :obj:`"gated-gelu"`.
|
||||
"""
|
||||
model_type = "mt5"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -141,4 +141,5 @@ class PegasusConfig(BartConfig):
|
||||
"""
|
||||
|
||||
model_type = "pegasus"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
# The implementation of the config object is in BartConfig
|
||||
|
||||
@@ -92,6 +92,7 @@ class ProphetNetConfig(PretrainedConfig):
|
||||
smoothing is performed.
|
||||
"""
|
||||
model_type = "prophetnet"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -153,6 +153,7 @@ class ReformerConfig(PretrainedConfig):
|
||||
>>> configuration = model.config
|
||||
"""
|
||||
model_type = "reformer"
|
||||
keys_to_ignore_at_inference = ["past_buckets_states"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -751,15 +751,15 @@ class TFRobertaLMHead(tf.keras.layers.Layer):
|
||||
|
||||
super().build(input_shape)
|
||||
|
||||
def call(self, features):
|
||||
x = self.dense(features)
|
||||
x = self.act(x)
|
||||
x = self.layer_norm(x)
|
||||
def call(self, hidden_states):
|
||||
hidden_states = self.dense(hidden_states)
|
||||
hidden_states = self.act(hidden_states)
|
||||
hidden_states = self.layer_norm(hidden_states)
|
||||
|
||||
# project back to size of vocabulary with bias
|
||||
x = self.decoder(x, mode="linear") + self.bias
|
||||
hidden_states = self.decoder(hidden_states, mode="linear") + self.bias
|
||||
|
||||
return x
|
||||
return hidden_states
|
||||
|
||||
|
||||
@add_start_docstrings("""RoBERTa Model with a `language modeling` head on top. """, ROBERTA_START_DOCSTRING)
|
||||
|
||||
@@ -71,6 +71,7 @@ class T5Config(PretrainedConfig):
|
||||
the :obj:`"gated-gelu"` feed forward projection. Original T5 uses :obj:`"relu"`.
|
||||
"""
|
||||
model_type = "t5"
|
||||
keys_to_ignore_at_inference = ["past_key_values"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -105,6 +105,7 @@ class TransfoXLConfig(PretrainedConfig):
|
||||
"""
|
||||
|
||||
model_type = "transfo-xl"
|
||||
keys_to_ignore_at_inference = ["mems"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -128,6 +128,7 @@ class XLNetConfig(PretrainedConfig):
|
||||
"""
|
||||
|
||||
model_type = "xlnet"
|
||||
keys_to_ignore_at_inference = ["mems"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
|
||||
@@ -470,7 +470,7 @@ class CaptureLogger:
|
||||
|
||||
>>> msg = "Testing 1, 2, 3"
|
||||
>>> logging.set_verbosity_info()
|
||||
>>> logger = logging.get_logger("transformers.tokenization_bart")
|
||||
>>> logger = logging.get_logger("transformers.models.bart.tokenization_bart")
|
||||
>>> with CaptureLogger(logger) as cl:
|
||||
... logger.info(msg)
|
||||
>>> assert cl.out, msg+"\n"
|
||||
|
||||
+44
-13
@@ -1098,10 +1098,11 @@ class Trainer:
|
||||
"""
|
||||
outputs = model(**inputs)
|
||||
# Save past state if it exists
|
||||
# TODO: this needs to be fixed and made cleaner later.
|
||||
if self.args.past_index >= 0:
|
||||
self._past = outputs[self.args.past_index]
|
||||
# We don't use .loss here since the model may return tuples instead of ModelOutput.
|
||||
return outputs[0]
|
||||
return outputs["loss"] if isinstance(outputs, dict) else outputs[0]
|
||||
|
||||
def is_local_process_zero(self) -> bool:
|
||||
"""
|
||||
@@ -1220,7 +1221,9 @@ class Trainer:
|
||||
logger.info("Deleting older checkpoint [{}] due to args.save_total_limit".format(checkpoint))
|
||||
shutil.rmtree(checkpoint)
|
||||
|
||||
def evaluate(self, eval_dataset: Optional[Dataset] = None) -> Dict[str, float]:
|
||||
def evaluate(
|
||||
self, eval_dataset: Optional[Dataset] = None, ignore_keys: Optional[List[str]] = None
|
||||
) -> Dict[str, float]:
|
||||
"""
|
||||
Run evaluation and returns metrics.
|
||||
|
||||
@@ -1234,6 +1237,9 @@ class Trainer:
|
||||
Pass a dataset if you wish to override :obj:`self.eval_dataset`. If it is an :obj:`datasets.Dataset`,
|
||||
columns not accepted by the ``model.forward()`` method are automatically removed. It must implement the
|
||||
:obj:`__len__` method.
|
||||
ignore_keys (:obj:`Lst[str]`, `optional`):
|
||||
A list of keys in the output of your model (if it is a dictionary) that should be ignored when
|
||||
gathering predictions.
|
||||
|
||||
Returns:
|
||||
A dictionary containing the evaluation loss and the potential metrics computed from the predictions. The
|
||||
@@ -1250,6 +1256,7 @@ class Trainer:
|
||||
# No point gathering the predictions if there are no metrics, otherwise we defer to
|
||||
# self.args.prediction_loss_only
|
||||
prediction_loss_only=True if self.compute_metrics is None else None,
|
||||
ignore_keys=ignore_keys,
|
||||
)
|
||||
|
||||
self.log(output.metrics)
|
||||
@@ -1261,7 +1268,7 @@ class Trainer:
|
||||
self.control = self.callback_handler.on_evaluate(self.args, self.state, self.control, output.metrics)
|
||||
return output.metrics
|
||||
|
||||
def predict(self, test_dataset: Dataset) -> PredictionOutput:
|
||||
def predict(self, test_dataset: Dataset, ignore_keys: Optional[List[str]] = None) -> PredictionOutput:
|
||||
"""
|
||||
Run prediction and returns predictions and potential metrics.
|
||||
|
||||
@@ -1272,6 +1279,9 @@ class Trainer:
|
||||
test_dataset (:obj:`Dataset`):
|
||||
Dataset to run the predictions on. If it is an :obj:`datasets.Dataset`, columns not accepted by the
|
||||
``model.forward()`` method are automatically removed. Has to implement the method :obj:`__len__`
|
||||
ignore_keys (:obj:`Lst[str]`, `optional`):
|
||||
A list of keys in the output of your model (if it is a dictionary) that should be ignored when
|
||||
gathering predictions.
|
||||
|
||||
.. note::
|
||||
|
||||
@@ -1291,10 +1301,14 @@ class Trainer:
|
||||
|
||||
test_dataloader = self.get_test_dataloader(test_dataset)
|
||||
|
||||
return self.prediction_loop(test_dataloader, description="Prediction")
|
||||
return self.prediction_loop(test_dataloader, description="Prediction", ignore_keys=ignore_keys)
|
||||
|
||||
def prediction_loop(
|
||||
self, dataloader: DataLoader, description: str, prediction_loss_only: Optional[bool] = None
|
||||
self,
|
||||
dataloader: DataLoader,
|
||||
description: str,
|
||||
prediction_loss_only: Optional[bool] = None,
|
||||
ignore_keys: Optional[List[str]] = None,
|
||||
) -> PredictionOutput:
|
||||
"""
|
||||
Prediction/evaluation loop, shared by :obj:`Trainer.evaluate()` and :obj:`Trainer.predict()`.
|
||||
@@ -1346,7 +1360,7 @@ class Trainer:
|
||||
self.callback_handler.eval_dataloader = dataloader
|
||||
|
||||
for step, inputs in enumerate(dataloader):
|
||||
loss, logits, labels = self.prediction_step(model, inputs, prediction_loss_only)
|
||||
loss, logits, labels = self.prediction_step(model, inputs, prediction_loss_only, ignore_keys=ignore_keys)
|
||||
if loss is not None:
|
||||
losses = loss.repeat(batch_size)
|
||||
losses_host = losses if losses_host is None else torch.cat((losses_host, losses), dim=0)
|
||||
@@ -1410,7 +1424,11 @@ class Trainer:
|
||||
return nested_numpify(tensors)
|
||||
|
||||
def prediction_step(
|
||||
self, model: nn.Module, inputs: Dict[str, Union[torch.Tensor, Any]], prediction_loss_only: bool
|
||||
self,
|
||||
model: nn.Module,
|
||||
inputs: Dict[str, Union[torch.Tensor, Any]],
|
||||
prediction_loss_only: bool,
|
||||
ignore_keys: Optional[List[str]] = None,
|
||||
) -> Tuple[Optional[float], Optional[torch.Tensor], Optional[torch.Tensor]]:
|
||||
"""
|
||||
Perform an evaluation step on :obj:`model` using obj:`inputs`.
|
||||
@@ -1427,6 +1445,9 @@ class Trainer:
|
||||
argument :obj:`labels`. Check your model's documentation for all accepted arguments.
|
||||
prediction_loss_only (:obj:`bool`):
|
||||
Whether or not to return the loss only.
|
||||
ignore_keys (:obj:`Lst[str]`, `optional`):
|
||||
A list of keys in the output of your model (if it is a dictionary) that should be ignored when
|
||||
gathering predictions.
|
||||
|
||||
Return:
|
||||
Tuple[Optional[float], Optional[torch.Tensor], Optional[torch.Tensor]]: A tuple with the loss, logits and
|
||||
@@ -1434,6 +1455,11 @@ class Trainer:
|
||||
"""
|
||||
has_labels = all(inputs.get(k) is not None for k in self.label_names)
|
||||
inputs = self._prepare_inputs(inputs)
|
||||
if ignore_keys is None:
|
||||
if hasattr(self.model, "config"):
|
||||
ignore_keys = getattr(self.model.config, "keys_to_ignore_at_inference", [])
|
||||
else:
|
||||
ignore_keys = []
|
||||
|
||||
with torch.no_grad():
|
||||
if self.args.fp16 and _use_native_amp:
|
||||
@@ -1442,16 +1468,21 @@ class Trainer:
|
||||
else:
|
||||
outputs = model(**inputs)
|
||||
if has_labels:
|
||||
loss = outputs[0].mean().detach()
|
||||
logits = outputs[1:]
|
||||
if isinstance(outputs, dict):
|
||||
loss = outputs["loss"].mean().detach()
|
||||
logits = tuple(v for k, v in outputs.items() if k not in ignore_keys + ["loss"])
|
||||
else:
|
||||
loss = outputs[0].mean().detach()
|
||||
logits = outputs[1:]
|
||||
else:
|
||||
loss = None
|
||||
# Slicing so we get a tuple even if `outputs` is a `ModelOutput`.
|
||||
logits = outputs[:]
|
||||
if isinstance(outputs, dict):
|
||||
logits = tuple(v for k, v in outputs.items() if k not in ignore_keys)
|
||||
else:
|
||||
logits = outputs
|
||||
# TODO: this needs to be fixed and made cleaner later.
|
||||
if self.args.past_index >= 0:
|
||||
self._past = outputs[self.args.past_index if has_labels else self.args.past_index - 1]
|
||||
# Remove the past from the logits.
|
||||
logits = logits[: self.args.past_index - 1] + logits[self.args.past_index :]
|
||||
|
||||
if prediction_loss_only:
|
||||
return (loss, None, None)
|
||||
|
||||
@@ -812,6 +812,15 @@ class TFLongformerForMaskedLM:
|
||||
requires_tf(self)
|
||||
|
||||
|
||||
class TFLongformerForMultipleChoice:
|
||||
def __init__(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
|
||||
class TFLongformerForQuestionAnswering:
|
||||
def __init__(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
@@ -821,6 +830,24 @@ class TFLongformerForQuestionAnswering:
|
||||
requires_tf(self)
|
||||
|
||||
|
||||
class TFLongformerForSequenceClassification:
|
||||
def __init__(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
|
||||
class TFLongformerForTokenClassification:
|
||||
def __init__(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
|
||||
class TFLongformerModel:
|
||||
def __init__(self, *args, **kwargs):
|
||||
requires_tf(self)
|
||||
|
||||
@@ -129,7 +129,7 @@ class LongformerModelTester:
|
||||
output_without_mask = model(input_ids)["last_hidden_state"]
|
||||
self.parent.assertTrue(torch.allclose(output_with_mask[0, 0, :5], output_without_mask[0, 0, :5], atol=1e-4))
|
||||
|
||||
def create_and_check_longformer_model(
|
||||
def create_and_check_model(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
model = LongformerModel(config=config)
|
||||
@@ -141,7 +141,7 @@ class LongformerModelTester:
|
||||
self.parent.assertEqual(result.last_hidden_state.shape, (self.batch_size, self.seq_length, self.hidden_size))
|
||||
self.parent.assertEqual(result.pooler_output.shape, (self.batch_size, self.hidden_size))
|
||||
|
||||
def create_and_check_longformer_model_with_global_attention_mask(
|
||||
def create_and_check_model_with_global_attention_mask(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
model = LongformerModel(config=config)
|
||||
@@ -163,7 +163,7 @@ class LongformerModelTester:
|
||||
self.parent.assertEqual(result.last_hidden_state.shape, (self.batch_size, self.seq_length, self.hidden_size))
|
||||
self.parent.assertEqual(result.pooler_output.shape, (self.batch_size, self.hidden_size))
|
||||
|
||||
def create_and_check_longformer_for_masked_lm(
|
||||
def create_and_check_for_masked_lm(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
model = LongformerForMaskedLM(config=config)
|
||||
@@ -172,7 +172,7 @@ class LongformerModelTester:
|
||||
result = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids, labels=token_labels)
|
||||
self.parent.assertEqual(result.logits.shape, (self.batch_size, self.seq_length, self.vocab_size))
|
||||
|
||||
def create_and_check_longformer_for_question_answering(
|
||||
def create_and_check_for_question_answering(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
model = LongformerForQuestionAnswering(config=config)
|
||||
@@ -189,7 +189,7 @@ class LongformerModelTester:
|
||||
self.parent.assertEqual(result.start_logits.shape, (self.batch_size, self.seq_length))
|
||||
self.parent.assertEqual(result.end_logits.shape, (self.batch_size, self.seq_length))
|
||||
|
||||
def create_and_check_longformer_for_sequence_classification(
|
||||
def create_and_check_for_sequence_classification(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_labels = self.num_labels
|
||||
@@ -199,7 +199,7 @@ class LongformerModelTester:
|
||||
result = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids, labels=sequence_labels)
|
||||
self.parent.assertEqual(result.logits.shape, (self.batch_size, self.num_labels))
|
||||
|
||||
def create_and_check_longformer_for_token_classification(
|
||||
def create_and_check_for_token_classification(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_labels = self.num_labels
|
||||
@@ -209,7 +209,7 @@ class LongformerModelTester:
|
||||
result = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids, labels=token_labels)
|
||||
self.parent.assertEqual(result.logits.shape, (self.batch_size, self.seq_length, self.num_labels))
|
||||
|
||||
def create_and_check_longformer_for_multiple_choice(
|
||||
def create_and_check_for_multiple_choice(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_choices = self.num_choices
|
||||
@@ -296,37 +296,37 @@ class LongformerModelTest(ModelTesterMixin, unittest.TestCase):
|
||||
def test_config(self):
|
||||
self.config_tester.run_common_tests()
|
||||
|
||||
def test_longformer_model(self):
|
||||
def test_model(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_model(*config_and_inputs)
|
||||
self.model_tester.create_and_check_model(*config_and_inputs)
|
||||
|
||||
def test_longformer_model_attention_mask_determinism(self):
|
||||
def test_model_attention_mask_determinism(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_attention_mask_determinism(*config_and_inputs)
|
||||
|
||||
def test_longformer_model_global_attention_mask(self):
|
||||
def test_model_global_attention_mask(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_model_with_global_attention_mask(*config_and_inputs)
|
||||
self.model_tester.create_and_check_model_with_global_attention_mask(*config_and_inputs)
|
||||
|
||||
def test_longformer_for_masked_lm(self):
|
||||
def test_for_masked_lm(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_for_masked_lm(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_masked_lm(*config_and_inputs)
|
||||
|
||||
def test_longformer_for_question_answering(self):
|
||||
def test_for_question_answering(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs_for_question_answering()
|
||||
self.model_tester.create_and_check_longformer_for_question_answering(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_question_answering(*config_and_inputs)
|
||||
|
||||
def test_for_sequence_classification(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_for_sequence_classification(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_sequence_classification(*config_and_inputs)
|
||||
|
||||
def test_for_token_classification(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_for_token_classification(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_token_classification(*config_and_inputs)
|
||||
|
||||
def test_for_multiple_choice(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_for_multiple_choice(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_multiple_choice(*config_and_inputs)
|
||||
|
||||
|
||||
@require_torch
|
||||
@@ -691,7 +691,7 @@ class LongformerModelIntegrationTest(unittest.TestCase):
|
||||
) # long input
|
||||
input_ids = input_ids.to(torch_device)
|
||||
|
||||
loss, prediction_scores = model(input_ids, labels=input_ids)
|
||||
loss, prediction_scores = model(input_ids, labels=input_ids).to_tuple()
|
||||
|
||||
expected_loss = torch.tensor(0.0074, device=torch_device)
|
||||
expected_prediction_scores_sum = torch.tensor(-6.1048e08, device=torch_device)
|
||||
|
||||
@@ -340,6 +340,7 @@ class TFBertModelTest(TFModelTesterMixin, unittest.TestCase):
|
||||
self.assertTrue(layer.split("_")[0] in ["dropout", "classifier"])
|
||||
|
||||
|
||||
@require_tf
|
||||
class TFBertModelIntegrationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_inference_masked_lm(self):
|
||||
|
||||
@@ -12,8 +12,7 @@
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
|
||||
from transformers import is_tf_available
|
||||
@@ -124,8 +123,6 @@ class TFDPRModelTester:
|
||||
type_vocab_size=self.type_vocab_size,
|
||||
is_decoder=False,
|
||||
initializer_range=self.initializer_range,
|
||||
# MODIFY
|
||||
return_dict=False,
|
||||
)
|
||||
config = DPRConfig(projection_dim=self.projection_dim, **config.to_dict())
|
||||
|
||||
@@ -137,7 +134,7 @@ class TFDPRModelTester:
|
||||
model = TFDPRContextEncoder(config=config)
|
||||
result = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids)
|
||||
result = model(input_ids, token_type_ids=token_type_ids)
|
||||
result = model(input_ids, return_dict=True) # MODIFY
|
||||
result = model(input_ids)
|
||||
self.parent.assertEqual(result.pooler_output.shape, (self.batch_size, self.projection_dim or self.hidden_size))
|
||||
|
||||
def create_and_check_dpr_question_encoder(
|
||||
@@ -146,14 +143,14 @@ class TFDPRModelTester:
|
||||
model = TFDPRQuestionEncoder(config=config)
|
||||
result = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids)
|
||||
result = model(input_ids, token_type_ids=token_type_ids)
|
||||
result = model(input_ids, return_dict=True) # MODIFY
|
||||
result = model(input_ids)
|
||||
self.parent.assertEqual(result.pooler_output.shape, (self.batch_size, self.projection_dim or self.hidden_size))
|
||||
|
||||
def create_and_check_dpr_reader(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
model = TFDPRReader(config=config)
|
||||
result = model(input_ids, attention_mask=input_mask, return_dict=True) # MODIFY
|
||||
result = model(input_ids, attention_mask=input_mask)
|
||||
|
||||
self.parent.assertEqual(result.start_logits.shape, (self.batch_size, self.seq_length))
|
||||
self.parent.assertEqual(result.end_logits.shape, (self.batch_size, self.seq_length))
|
||||
@@ -214,27 +211,61 @@ class TFDPRModelTest(TFModelTesterMixin, unittest.TestCase):
|
||||
@slow
|
||||
def test_model_from_pretrained(self):
|
||||
for model_name in TF_DPR_CONTEXT_ENCODER_PRETRAINED_MODEL_ARCHIVE_LIST[:1]:
|
||||
model = TFDPRContextEncoder.from_pretrained(model_name, from_pt=True)
|
||||
model = TFDPRContextEncoder.from_pretrained(model_name)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
for model_name in TF_DPR_CONTEXT_ENCODER_PRETRAINED_MODEL_ARCHIVE_LIST[:1]:
|
||||
model = TFDPRContextEncoder.from_pretrained(model_name, from_pt=True)
|
||||
model = TFDPRContextEncoder.from_pretrained(model_name)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
for model_name in TF_DPR_QUESTION_ENCODER_PRETRAINED_MODEL_ARCHIVE_LIST[:1]:
|
||||
model = TFDPRQuestionEncoder.from_pretrained(model_name, from_pt=True)
|
||||
model = TFDPRQuestionEncoder.from_pretrained(model_name)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
for model_name in TF_DPR_READER_PRETRAINED_MODEL_ARCHIVE_LIST[:1]:
|
||||
model = TFDPRReader.from_pretrained(model_name, from_pt=True)
|
||||
model = TFDPRReader.from_pretrained(model_name)
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
@slow
|
||||
def test_saved_model_with_attentions_output(self):
|
||||
config, inputs_dict = self.model_tester.prepare_config_and_inputs_for_common()
|
||||
config.output_attentions = True
|
||||
|
||||
encoder_seq_length = getattr(self.model_tester, "encoder_seq_length", self.model_tester.seq_length)
|
||||
encoder_key_length = getattr(self.model_tester, "key_length", encoder_seq_length)
|
||||
|
||||
for model_class in self.all_model_classes:
|
||||
print(model_class)
|
||||
class_inputs_dict = self._prepare_for_class(inputs_dict, model_class)
|
||||
model = model_class(config)
|
||||
num_out = len(model(class_inputs_dict))
|
||||
model._saved_model_inputs_spec = None
|
||||
model._set_save_spec(class_inputs_dict)
|
||||
|
||||
with tempfile.TemporaryDirectory() as tmpdirname:
|
||||
tf.saved_model.save(model, tmpdirname)
|
||||
model = tf.keras.models.load_model(tmpdirname)
|
||||
outputs = model(class_inputs_dict)
|
||||
|
||||
if self.is_encoder_decoder:
|
||||
output = outputs["encoder_attentions"] if isinstance(outputs, dict) else outputs[-1]
|
||||
else:
|
||||
output = outputs["attentions"] if isinstance(outputs, dict) else outputs[-1]
|
||||
|
||||
attentions = [t.numpy() for t in output]
|
||||
self.assertEqual(len(outputs), num_out)
|
||||
self.assertEqual(len(attentions), self.model_tester.num_hidden_layers)
|
||||
self.assertListEqual(
|
||||
list(attentions[0].shape[-3:]),
|
||||
[self.model_tester.num_attention_heads, encoder_seq_length, encoder_key_length],
|
||||
)
|
||||
|
||||
|
||||
@require_tf
|
||||
class TFDPRModelIntegrationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_inference_no_head(self):
|
||||
model = TFDPRQuestionEncoder.from_pretrained("facebook/dpr-question_encoder-single-nq-base", return_dict=False)
|
||||
model = TFDPRQuestionEncoder.from_pretrained("facebook/dpr-question_encoder-single-nq-base")
|
||||
|
||||
input_ids = tf.constant(
|
||||
[[101, 7592, 1010, 2003, 2026, 3899, 10140, 1029, 102]]
|
||||
|
||||
@@ -249,6 +249,7 @@ class TFElectraModelTest(TFModelTesterMixin, unittest.TestCase):
|
||||
self.assertIsNotNone(model)
|
||||
|
||||
|
||||
@require_tf
|
||||
class TFElectraModelIntegrationTest(unittest.TestCase):
|
||||
@slow
|
||||
def test_inference_masked_lm(self):
|
||||
|
||||
@@ -29,7 +29,10 @@ if is_tf_available():
|
||||
from transformers import (
|
||||
LongformerConfig,
|
||||
TFLongformerForMaskedLM,
|
||||
TFLongformerForMultipleChoice,
|
||||
TFLongformerForQuestionAnswering,
|
||||
TFLongformerForSequenceClassification,
|
||||
TFLongformerForTokenClassification,
|
||||
TFLongformerModel,
|
||||
TFLongformerSelfAttention,
|
||||
)
|
||||
@@ -130,7 +133,7 @@ class TFLongformerModelTester:
|
||||
output_without_mask = model(input_ids)[0]
|
||||
tf.debugging.assert_near(output_with_mask[0, 0, :5], output_without_mask[0, 0, :5], rtol=1e-4)
|
||||
|
||||
def create_and_check_longformer_model(
|
||||
def create_and_check_model(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.return_dict = True
|
||||
@@ -144,7 +147,7 @@ class TFLongformerModelTester:
|
||||
)
|
||||
self.parent.assertListEqual(shape_list(result.pooler_output), [self.batch_size, self.hidden_size])
|
||||
|
||||
def create_and_check_longformer_model_with_global_attention_mask(
|
||||
def create_and_check_model_with_global_attention_mask(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.return_dict = True
|
||||
@@ -172,7 +175,7 @@ class TFLongformerModelTester:
|
||||
)
|
||||
self.parent.assertListEqual(shape_list(result.pooler_output), [self.batch_size, self.hidden_size])
|
||||
|
||||
def create_and_check_longformer_for_masked_lm(
|
||||
def create_and_check_for_masked_lm(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.return_dict = True
|
||||
@@ -180,7 +183,7 @@ class TFLongformerModelTester:
|
||||
result = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids, labels=token_labels)
|
||||
self.parent.assertListEqual(shape_list(result.logits), [self.batch_size, self.seq_length, self.vocab_size])
|
||||
|
||||
def create_and_check_longformer_for_question_answering(
|
||||
def create_and_check_for_question_answering(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.return_dict = True
|
||||
@@ -196,6 +199,41 @@ class TFLongformerModelTester:
|
||||
self.parent.assertListEqual(shape_list(result.start_logits), [self.batch_size, self.seq_length])
|
||||
self.parent.assertListEqual(shape_list(result.end_logits), [self.batch_size, self.seq_length])
|
||||
|
||||
def create_and_check_for_sequence_classification(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_labels = self.num_labels
|
||||
model = TFLongformerForSequenceClassification(config=config)
|
||||
output = model(
|
||||
input_ids, attention_mask=input_mask, token_type_ids=token_type_ids, labels=sequence_labels
|
||||
).logits
|
||||
self.parent.assertListEqual(shape_list(output), [self.batch_size, self.num_labels])
|
||||
|
||||
def create_and_check_for_token_classification(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_labels = self.num_labels
|
||||
model = TFLongformerForTokenClassification(config=config)
|
||||
output = model(input_ids, attention_mask=input_mask, token_type_ids=token_type_ids, labels=token_labels).logits
|
||||
self.parent.assertListEqual(shape_list(output), [self.batch_size, self.seq_length, self.num_labels])
|
||||
|
||||
def create_and_check_for_multiple_choice(
|
||||
self, config, input_ids, token_type_ids, input_mask, sequence_labels, token_labels, choice_labels
|
||||
):
|
||||
config.num_choices = self.num_choices
|
||||
model = TFLongformerForMultipleChoice(config=config)
|
||||
multiple_choice_inputs_ids = tf.tile(tf.expand_dims(input_ids, 1), (1, self.num_choices, 1))
|
||||
multiple_choice_token_type_ids = tf.tile(tf.expand_dims(token_type_ids, 1), (1, self.num_choices, 1))
|
||||
multiple_choice_input_mask = tf.tile(tf.expand_dims(input_mask, 1), (1, self.num_choices, 1))
|
||||
output = model(
|
||||
multiple_choice_inputs_ids,
|
||||
attention_mask=multiple_choice_input_mask,
|
||||
global_attention_mask=multiple_choice_input_mask,
|
||||
token_type_ids=multiple_choice_token_type_ids,
|
||||
labels=choice_labels,
|
||||
).logits
|
||||
self.parent.assertListEqual(list(output.shape), [self.batch_size, self.num_choices])
|
||||
|
||||
def prepare_config_and_inputs_for_common(self):
|
||||
config_and_inputs = self.prepare_config_and_inputs()
|
||||
(
|
||||
@@ -252,6 +290,9 @@ class TFLongformerModelTest(TFModelTesterMixin, unittest.TestCase):
|
||||
TFLongformerModel,
|
||||
TFLongformerForMaskedLM,
|
||||
TFLongformerForQuestionAnswering,
|
||||
TFLongformerForSequenceClassification,
|
||||
TFLongformerForMultipleChoice,
|
||||
TFLongformerForTokenClassification,
|
||||
)
|
||||
if is_tf_available()
|
||||
else ()
|
||||
@@ -264,25 +305,37 @@ class TFLongformerModelTest(TFModelTesterMixin, unittest.TestCase):
|
||||
def test_config(self):
|
||||
self.config_tester.run_common_tests()
|
||||
|
||||
def test_longformer_model_attention_mask_determinism(self):
|
||||
def test_model_attention_mask_determinism(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_attention_mask_determinism(*config_and_inputs)
|
||||
|
||||
def test_longformer_model(self):
|
||||
def test_model(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_model(*config_and_inputs)
|
||||
self.model_tester.create_and_check_model(*config_and_inputs)
|
||||
|
||||
def test_longformer_model_global_attention_mask(self):
|
||||
def test_model_global_attention_mask(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_model_with_global_attention_mask(*config_and_inputs)
|
||||
self.model_tester.create_and_check_model_with_global_attention_mask(*config_and_inputs)
|
||||
|
||||
def test_longformer_for_masked_lm(self):
|
||||
def test_for_masked_lm(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_longformer_for_masked_lm(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_masked_lm(*config_and_inputs)
|
||||
|
||||
def test_longformer_for_question_answering(self):
|
||||
def test_for_question_answering(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs_for_question_answering()
|
||||
self.model_tester.create_and_check_longformer_for_question_answering(*config_and_inputs)
|
||||
self.model_tester.create_and_check_for_question_answering(*config_and_inputs)
|
||||
|
||||
def test_for_sequence_classification(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_for_sequence_classification(*config_and_inputs)
|
||||
|
||||
def test_for_token_classification(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_for_token_classification(*config_and_inputs)
|
||||
|
||||
def test_for_multiple_choice(self):
|
||||
config_and_inputs = self.model_tester.prepare_config_and_inputs()
|
||||
self.model_tester.create_and_check_for_multiple_choice(*config_and_inputs)
|
||||
|
||||
@slow
|
||||
def test_saved_model_with_attentions_output(self):
|
||||
|
||||
@@ -44,6 +44,8 @@ if is_torch_available():
|
||||
DataCollatorForLanguageModeling,
|
||||
GlueDataset,
|
||||
GlueDataTrainingArguments,
|
||||
GPT2Config,
|
||||
GPT2LMHeadModel,
|
||||
LineByLineTextDataset,
|
||||
PreTrainedModel,
|
||||
TextDataset,
|
||||
@@ -73,6 +75,18 @@ class RegressionDataset:
|
||||
return result
|
||||
|
||||
|
||||
class RepeatDataset:
|
||||
def __init__(self, x, length=64):
|
||||
self.x = x
|
||||
self.length = length
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, i):
|
||||
return {"input_ids": self.x, "labels": self.x}
|
||||
|
||||
|
||||
class DynamicShapesDataset:
|
||||
def __init__(self, length=64, seed=42, batch_size=8):
|
||||
self.length = length
|
||||
@@ -136,6 +150,20 @@ if is_torch_available():
|
||||
loss = torch.nn.functional.mse_loss(y, labels)
|
||||
return (loss, y, y) if self.double_output else (loss, y)
|
||||
|
||||
class RegressionDictModel(torch.nn.Module):
|
||||
def __init__(self, a=0, b=0):
|
||||
super().__init__()
|
||||
self.a = torch.nn.Parameter(torch.tensor(a).float())
|
||||
self.b = torch.nn.Parameter(torch.tensor(b).float())
|
||||
self.config = None
|
||||
|
||||
def forward(self, input_x=None, labels=None, **kwargs):
|
||||
y = input_x * self.a + self.b
|
||||
result = {"output": y}
|
||||
if labels is not None:
|
||||
result["loss"] = torch.nn.functional.mse_loss(y, labels)
|
||||
return result
|
||||
|
||||
class RegressionPreTrainedModel(PreTrainedModel):
|
||||
config_class = RegressionModelConfig
|
||||
base_model_prefix = "regression"
|
||||
@@ -236,6 +264,33 @@ class TrainerIntegrationTest(unittest.TestCase):
|
||||
metrics = trainer.evaluate()
|
||||
self.assertEqual(metrics[metric], best_value)
|
||||
|
||||
def test_trainer_works_with_dict(self):
|
||||
# Edge case because Apex with mode O2 will change our models to return dicts. This test checks it doesn't break
|
||||
# anything.
|
||||
train_dataset = RegressionDataset()
|
||||
eval_dataset = RegressionDataset()
|
||||
model = RegressionDictModel()
|
||||
args = TrainingArguments("./regression")
|
||||
trainer = Trainer(model, args, train_dataset=train_dataset, eval_dataset=eval_dataset)
|
||||
trainer.train()
|
||||
_ = trainer.evaluate()
|
||||
_ = trainer.predict(eval_dataset)
|
||||
|
||||
def test_evaluation_with_keys_to_drop(self):
|
||||
config = GPT2Config(vocab_size=100, n_positions=128, n_ctx=128, n_embd=32, n_layer=3, n_head=4)
|
||||
tiny_gpt2 = GPT2LMHeadModel(config)
|
||||
x = torch.randint(0, 100, (128,))
|
||||
eval_dataset = RepeatDataset(x)
|
||||
args = TrainingArguments("./test")
|
||||
trainer = Trainer(tiny_gpt2, args, eval_dataset=eval_dataset)
|
||||
# By default the past_key_values are removed
|
||||
result = trainer.predict(eval_dataset)
|
||||
self.assertTrue(isinstance(result.predictions, np.ndarray))
|
||||
# We can still get them by setting ignore_keys to []
|
||||
result = trainer.predict(eval_dataset, ignore_keys=[])
|
||||
self.assertTrue(isinstance(result.predictions, tuple))
|
||||
self.assertEqual(len(result.predictions), 2)
|
||||
|
||||
def test_training_arguments_are_left_untouched(self):
|
||||
trainer = get_regression_trainer()
|
||||
trainer.train()
|
||||
|
||||
Reference in New Issue
Block a user