diff --git a/model_cards/mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es.md b/model_cards/mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es.md
new file mode 100644
index 00000000..739ef353
--- /dev/null
+++ b/model_cards/mrm8488/distill-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es.md
@@ -0,0 +1,108 @@
+---
+language: spanish
+thumbnail: https://i.imgur.com/jgBdimh.png
+---
+
+# BETO (Spanish BERT) + Spanish SQuAD2.0 + distillation using 'bert-base-multilingual-cased' as teacher
+
+This model is a fine-tuned on [SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve) and **distilled** version of [BETO](https://github.com/dccuchile/beto) for **Q&A**.
+
+Distillation makes the model smaller, fasert, cheaper and lighter than [bert-base-spanish-wwm-cased-finetuned-spa-squad2-es](https://github.com/huggingface/transformers/blob/master/model_cards/mrm8488/bert-base-spanish-wwm-cased-finetuned-spa-squad2-es/README.md)
+
+This model was fine-tuned on the same dataset but using **distillation** during the process as mentioned above (and one more train epoch).
+
+The **teacher model** for the distillation was `bert-base-multilingual-cased`. It is the same teacher used for `distilbert-base-multilingual-cased` AKA [**DistilmBERT**](https://github.com/huggingface/transformers/tree/master/examples/distillation) (on average is twice as fast as **mBERT-base**).
+
+## Details of the downstream task (Q&A) - Dataset
+
+
+
+[SQuAD-es-v2.0](https://github.com/ccasimiro88/TranslateAlignRetrieve)
+
+| Dataset | # Q&A |
+| ----------------------- | ----- |
+| SQuAD2.0 Train | 130 K |
+| SQuAD2.0-es-v2.0 | 111 K |
+| SQuAD2.0 Dev | 12 K |
+| SQuAD-es-v2.0-small Dev | 69 K |
+
+
+
+## Model training
+
+The model was trained on a Tesla P100 GPU and 25GB of RAM with the following command:
+
+```bash
+!export SQUAD_DIR=/path/to/squad-v2_spanish \
+&& python transformers/examples/distillation/run_squad_w_distillation.py \
+ --model_type bert \
+ --model_name_or_path dccuchile/bert-base-spanish-wwm-cased \
+ --teacher_type bert \
+ --teacher_name_or_path bert-base-multilingual-cased \
+ --do_train \
+ --do_eval \
+ --do_lower_case \
+ --train_file $SQUAD_DIR/train-v2.json \
+ --predict_file $SQUAD_DIR/dev-v2.json \
+ --per_gpu_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 3.0 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /content/model_output \
+ --save_steps 5000 \
+ --threads 4 \
+ --version_2_with_negative
+```
+
+## Results:
+
+| Metric | # Value |
+| --------- | ----------- |
+| **Exact** | **82.40**65 |
+| **F1** | **90.50**36 |
+
+```json
+{
+ "exact": 82.40657784457096,
+ "f1": 90.50369643376753,
+ "total": 69202,
+ "HasAns_exact": 75.13413304253,
+ "HasAns_f1": 87.35521920631561,
+ "HasAns_total": 45850,
+ "NoAns_exact": 96.68550873586845,
+ "NoAns_f1": 96.68550873586845,
+ "NoAns_total": 23352,
+ "best_exact": 82.40657784457096,
+ "best_exact_thresh": 0.0,
+ "best_f1": 90.50369643376902,
+ "best_f1_thresh": 0.0
+}
+```
+
+## Comparison:
+
+| Model | f1 score |
+| :-------------------------------------------------------------: | :-------: |
+| bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | 86.07 |
+| **distill**-bert-base-spanish-wwm-cased-finetuned-spa-squad2-es | **90.50** |
+
+So, yes, this version is even more accurate.
+
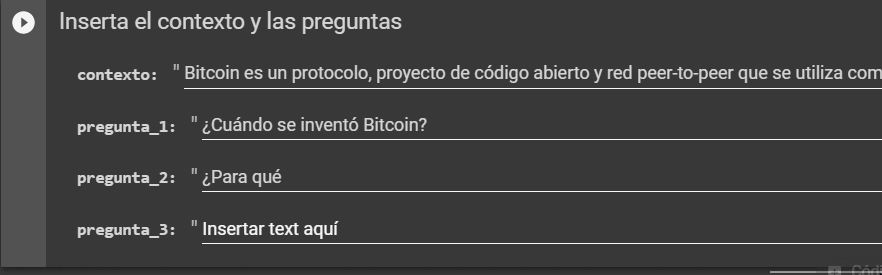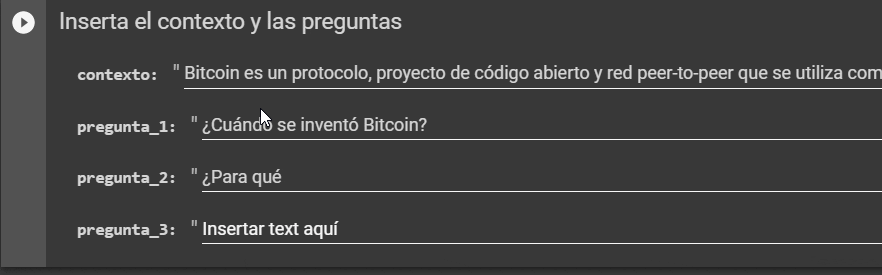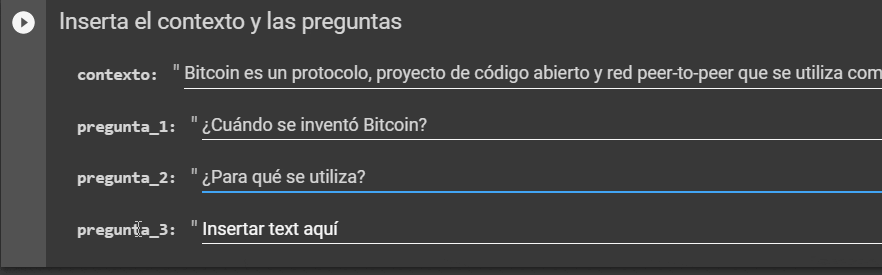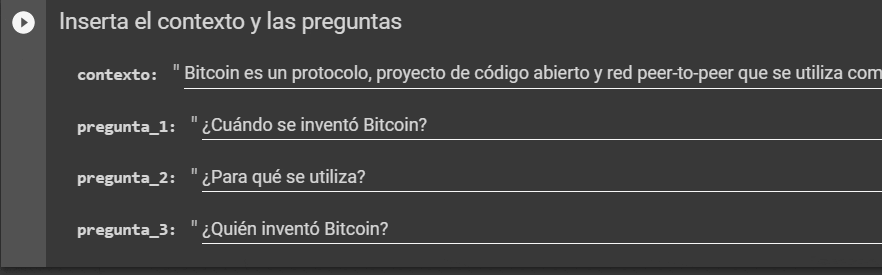
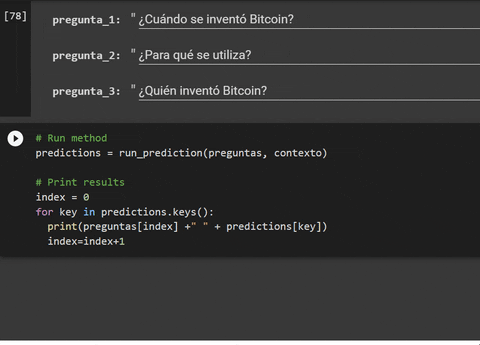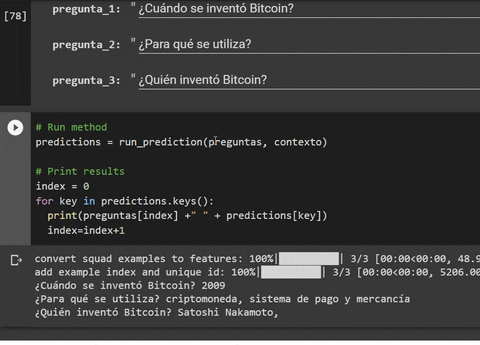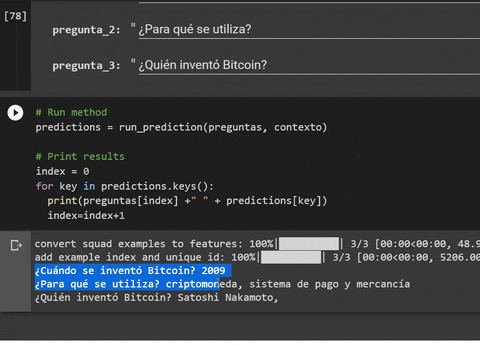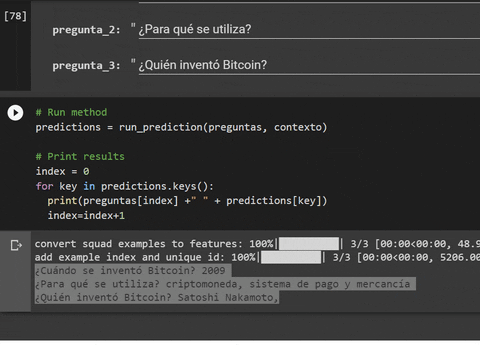
+### Model in action (in a Colab Notebook)
+
+
+
+1. Set the context and ask some questions:
+
+
+
+2. Run predictions:
+
+
+
+
+
+> Created by [Manuel Romero/@mrm8488](https://twitter.com/mrm8488)
+
+> Made with ♥ in Spain