Update notebook link and fix few working issues.
Signed-off-by: Morgan Funtowicz <morgan@huggingface.co>
This commit is contained in:
 Morgan Funtowicz committed
1 parent
189113d891
commit
1bca97ec7f
2 files changed
+4
-5
No files matched your search
@@ -32,7 +32,7 @@
|
||||
"was not well suited for the kind of hardware we're currently leveraging due to bad parallelization capabilities. \n",
|
||||
"\n",
|
||||
"Some extensions were provided by the academic community, such as Bidirectional RNN ([Schuster & Paliwal., 1997](https://www.researchgate.net/publication/3316656_Bidirectional_recurrent_neural_networks), [Graves & al., 2005](https://mediatum.ub.tum.de/doc/1290195/file.pdf)), \n",
|
||||
"which can be seen as a concatenation of two sequential process, on going forward, the other one going backward over the sequence input.\n",
|
||||
"which can be seen as a concatenation of two sequential process, one going forward, the other one going backward over the sequence input.\n",
|
||||
"\n",
|
||||
"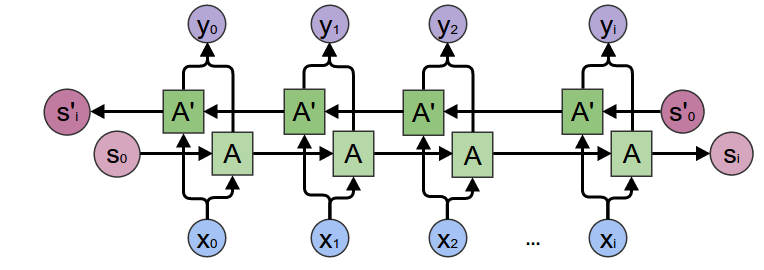\n",
|
||||
"\n",
|
||||
@@ -49,8 +49,7 @@
|
||||
"on translation tasks but it quickly extended to almost all the tasks RNNs were State-of-the-Art at that time.\n",
|
||||
"\n",
|
||||
"One advantage of Transformer over its RNN counterpart was its non sequential attention model. Remember, the RNNs had to\n",
|
||||
"iterate over each element of the input sequence one-by-one and carry an \"updatable-state\" between each hop. With Transformer\n",
|
||||
"the, the model is able to look at every position in the sequence, at the same time, in one operation.\n",
|
||||
"iterate over each element of the input sequence one-by-one and carry an \"updatable-state\" between each hop. With Transformer, the model is able to look at every position in the sequence, at the same time, in one operation.\n",
|
||||
"\n",
|
||||
"For a deep-dive into the Transformer architecture, [The Annotated Transformer](https://nlp.seas.harvard.edu/2018/04/03/attention.html#encoder-and-decoder-stacks) \n",
|
||||
"will drive you along all the details of the paper.\n",
|
||||
@@ -68,7 +67,7 @@
|
||||
"source": [
|
||||
"## Getting started with transformers\n",
|
||||
"\n",
|
||||
"For the rest of this notebook, we will use a BERT model, as it's the most simple and there are plenty of content about it\n",
|
||||
"For the rest of this notebook, we will use the [BERT (Devlin & al., 2018)](https://arxiv.org/abs/1810.04805) architecture, as it's the most simple and there are plenty of content about it\n",
|
||||
"over the internet, it will be easy to dig more over this architecture if you want to.\n",
|
||||
"\n",
|
||||
"The transformers library allows you to benefits from large, pretrained language models without requiring a huge and costly computational\n",
|
||||
|
||||
Reference in new issue
Block a user